
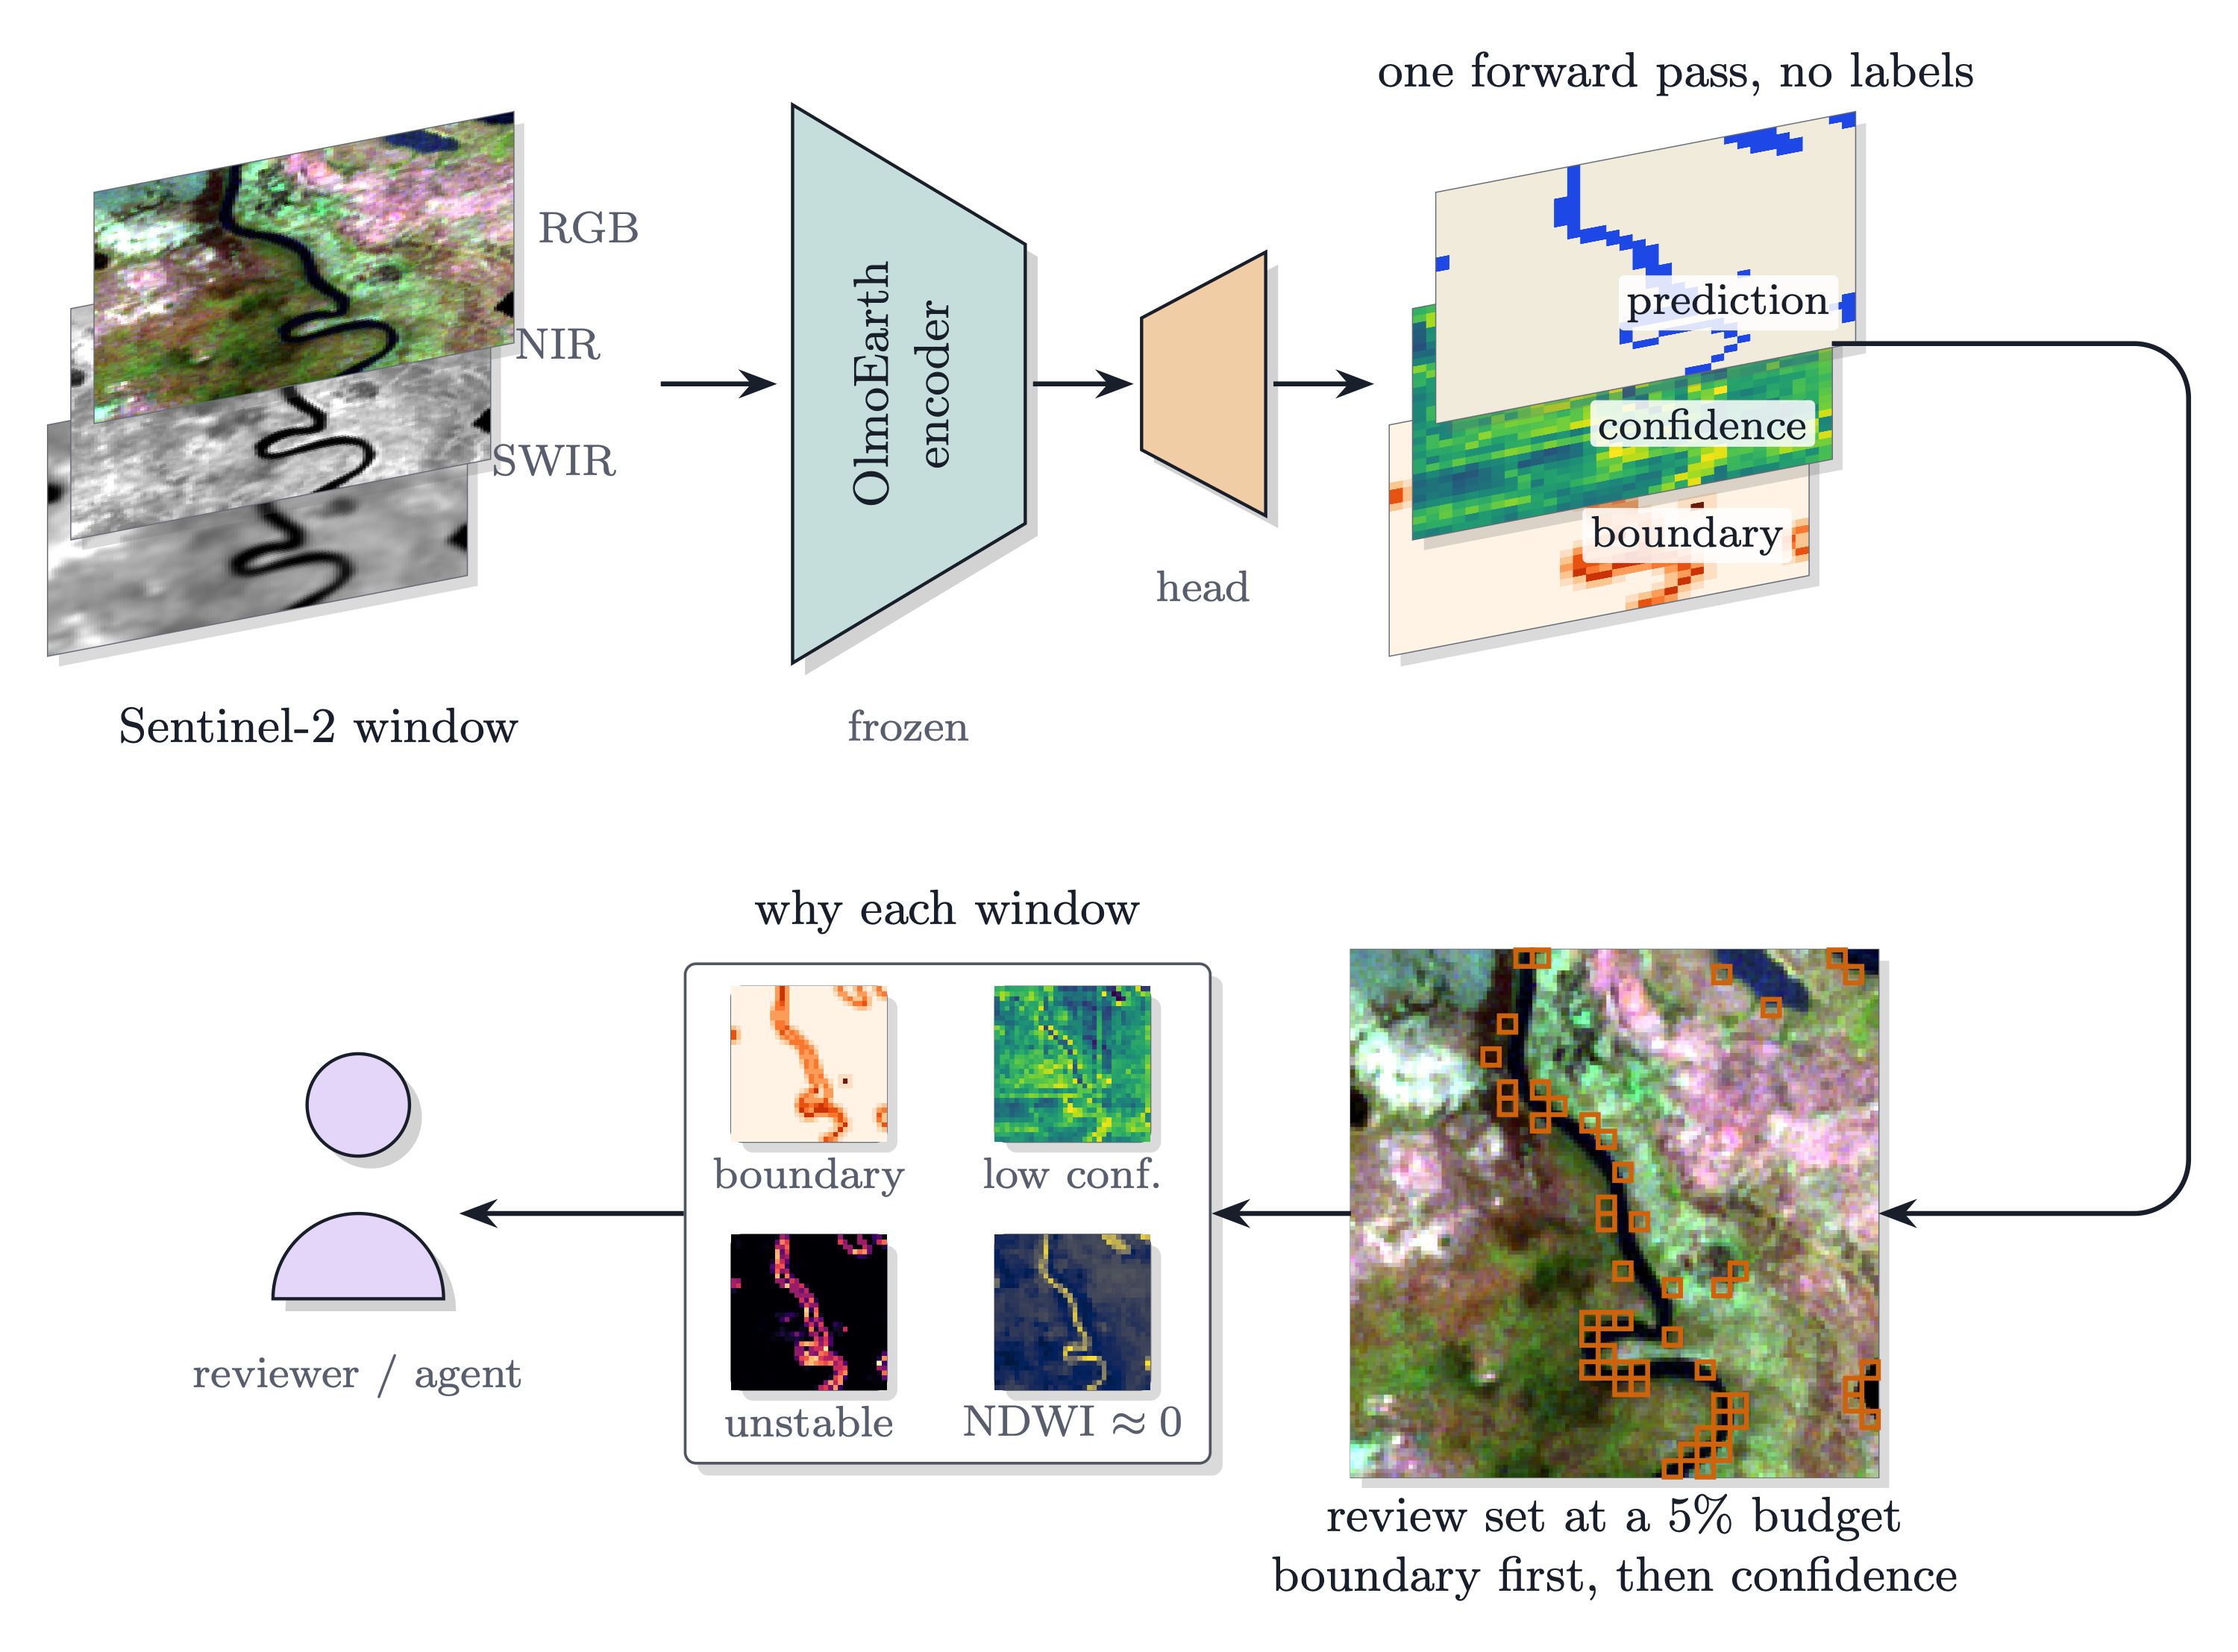
olmoearth_inferenceX measures differences between Earth-observation inferences without labels, and shows on expert-labelled testbeds which of those differences predict error. It was built around OlmoEarth and has since been run on a served global product no one here had a hand in training.
Try it in two minutes
pip install olmoearth-inferencex
oe-inferencex demo
No data, no labels and nothing but numpy. The command makes a small made-up water map the way a model would (sure in the middle of the water and the land, unsure along the shore, fooled by one cloud shadow), audits it without labels, and writes the picture below with the same files a real audit writes.
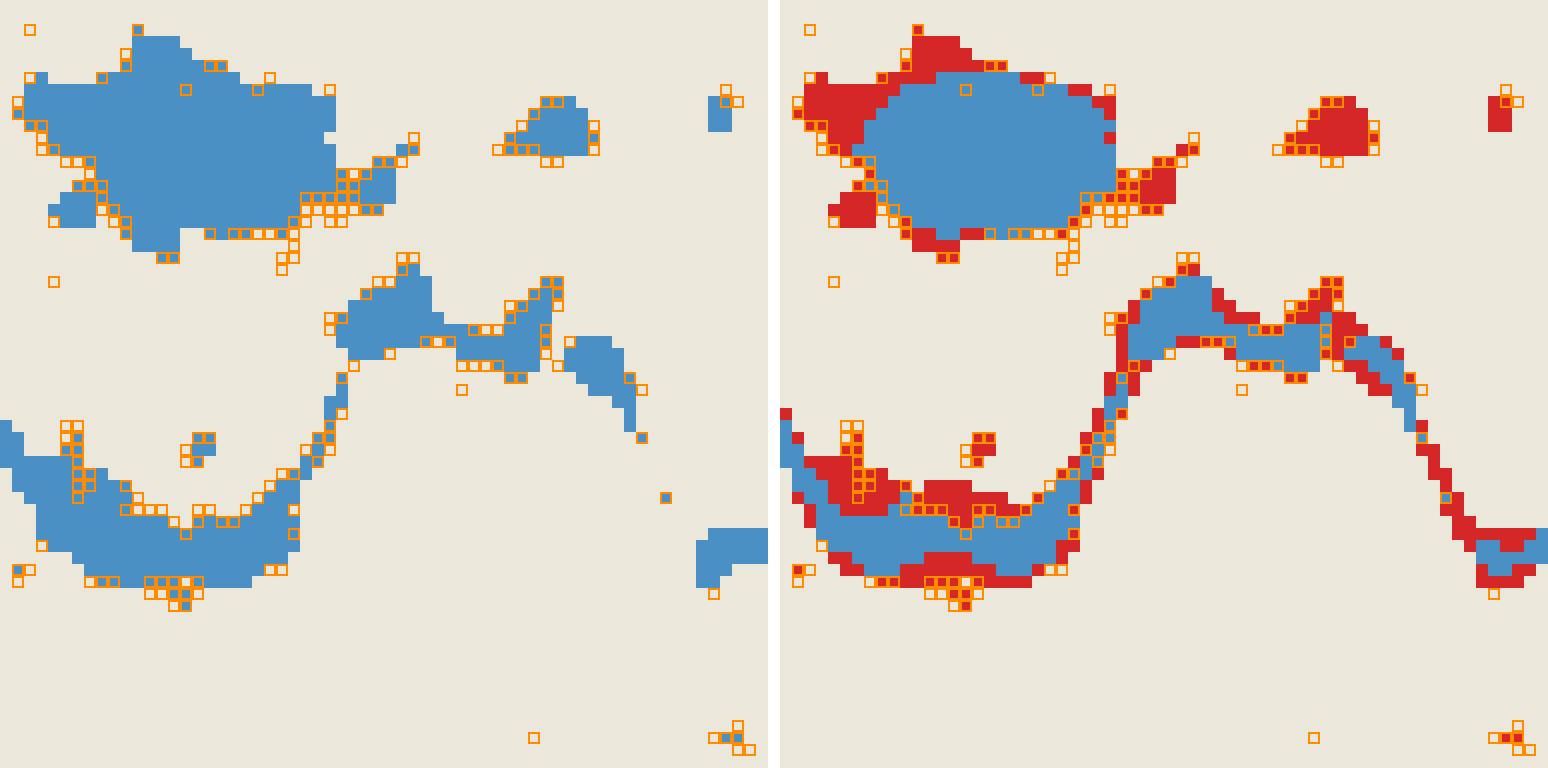
Left: the map, with the 5% of windows to check first in orange. Right: where the map is really wrong, in red, known only because the scene is made up. The flagged 5% hold about a quarter of the errors, five times what a random 5% would, which is close to what the record measures on a real flood map. The middle of the red patch at the top right is an error the model is sure about, and nothing computed without labels finds those.
Then your own map, a GeoTIFF (with pip install "olmoearth-inferencex[geo]") or a .npy array of probabilities or
logits:
oe-inferencex assess your_map.tif --out audit
What the project found, in six plain sentences: Findings, in short.
The strongest evidence
On tasks this project did not choose, the model's own margin ranks its errors better than any control that sees no model — on 24 of 24.
The tasks are the 25 of the OlmoEarth paper embedding suite by Ai2, with the splits fixed in the files. On all 24 that a top-1 minus top-2 margin is defined for, and on all 14 distinct sources behind them, the margin beats the best no-model control: 6,435,473 graded units, an accuracy range from 0.333 to 0.979, 17 of 17 classification tasks and 7 of 7 segmentation tasks, sign test p = 6e-08. Six of the tasks come from GEO-Bench 1, a third-party benchmark, and the margin wins on all six. On the same tasks it also beats the competitors the literature proposes: a five-seed ensemble on 22 of 24, nearest-neighbour typicality on 24 of 24 and a Mahalanobis distance on 24 of 24 (exp73). Nor is it a property of OlmoEarth: under the fifteen other encoders the suite is published for, eight families outside OlmoEarth (AnySat, Clay, Panopticon, Galileo, CROMA, TerraMind, Satlas, Copernicus-FM) and the OlmoEarth size series, the margin beats the control on 322 of 332 scored tasks, every encoder at 90% or better (exp74). Within the model's own confidence family the forms are close; on multi-class tasks one minus the top probability is marginally better than top-1 minus top-2 (exp76).
This is the answer to the obvious objection — that a result like this rests on testbeds the author picked. It does not. Tasks we did not choose (exp70).
What this is not: a leaderboard result. That suite measures accuracy, and no public benchmark measures label-free error ranking.
What it does
On these testbeds the model's own logit margin is the difference that predicts error; disagreement across crops, backbones or encoders does not rank errors; the sensor difference says where shared errors come from; the frozen-versus-fine-tuned difference measures how much training moved the model. Given a prediction map:
- Which windows to review first — review sets at a chosen budget, in confidence order or boundary first.
- Why each flagged window is suspect — label-free cues carrying measured evidence from expert-labelled testbeds.
- Score any candidate audit rule the same way, against the model's own confidence and a no-model control, on two references at once.
- Audit a deployed product, whoever trained it — including a served global land-cover product audited from nothing but the probabilities it publishes about itself.
- Measure the difference between two inferences of one scene: across crops, backbones, sensors, encoders, fine-tuning, and acquisition dates — how much they disagree, what the disagreeing windows share, and with labels, which side is right.
- Fuse label-free readings with labels where they exist, reported held-out and bound to the model family it was fitted on, because such rules do not transfer across families.
- Grade against a reference that is a sample, not a map — design-weighted estimators report the population quantity. Ignoring the design overstated one lead by a quarter of its size.
Both halves run from the command line without writing Python:
oe-inferencex assess and oe-inferencex compare
(Usage).
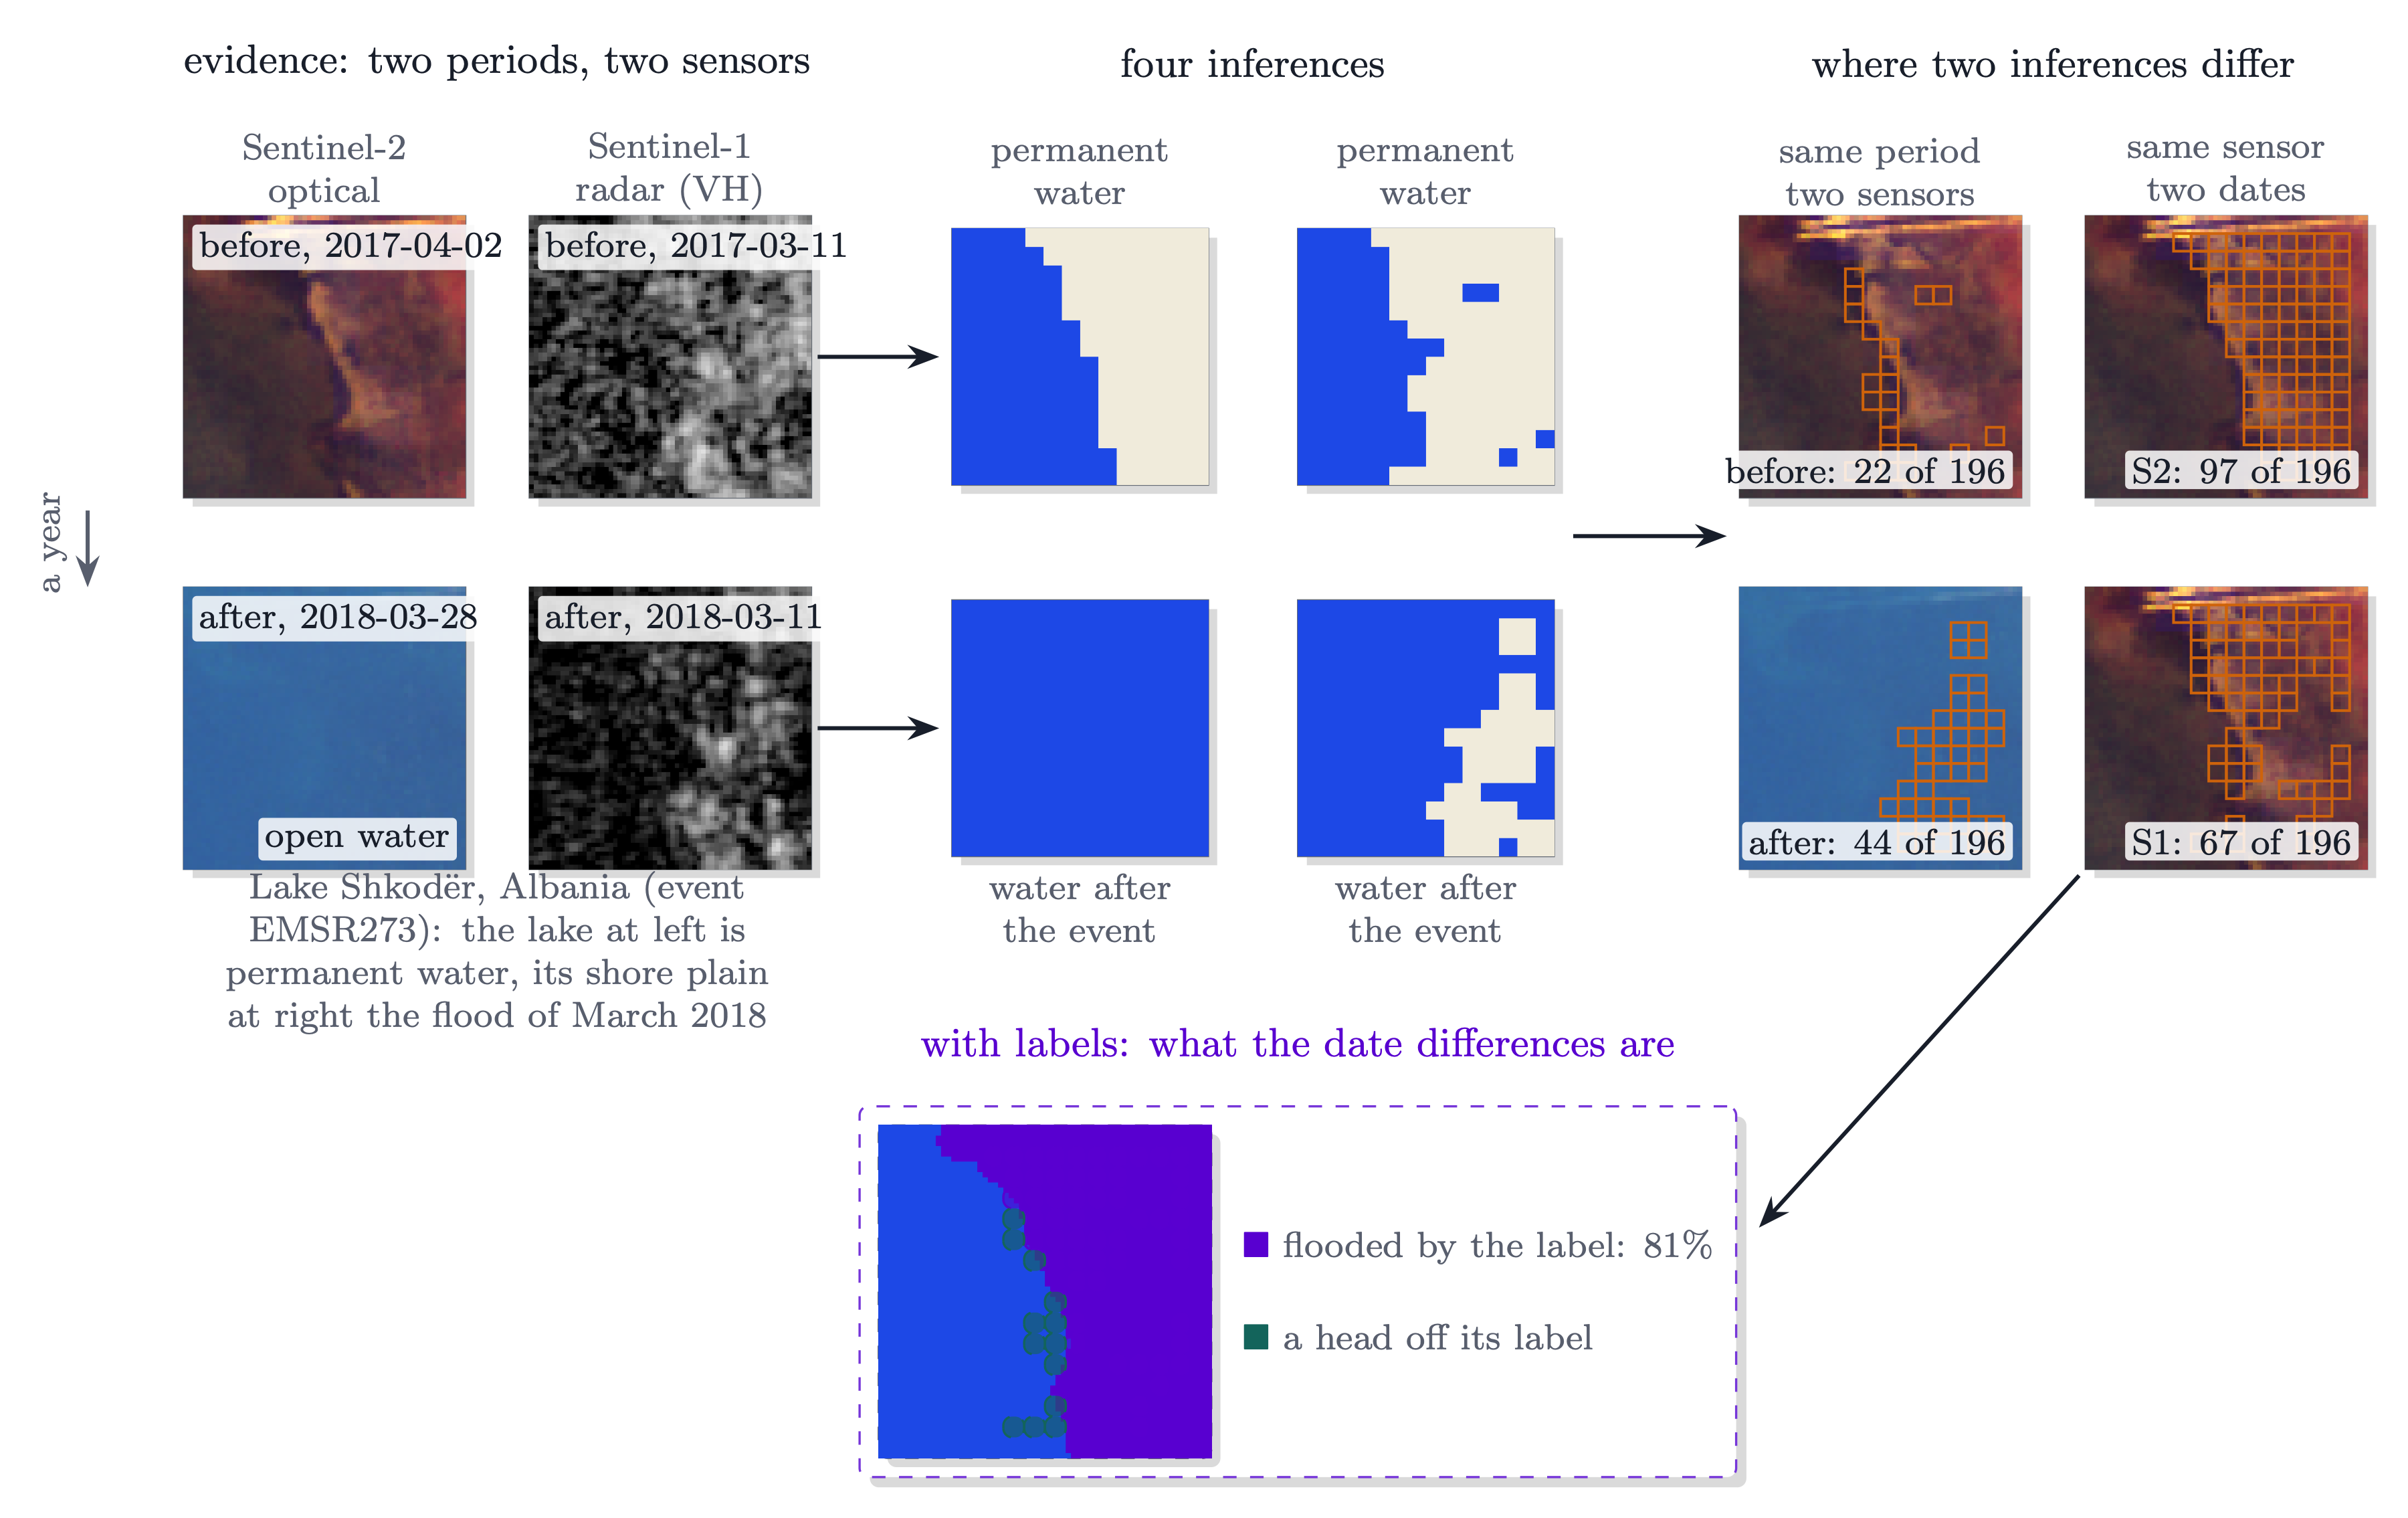
Four dated inputs of one GEOID-Flood chip (Lake Shkodër at Gruemirë, Albania), each read on identical windows. Same-period pairs differ on 22 windows before the event and 44 after; same-sensor pairs on 97 (optical) and 67 (radar). What a difference is needs labels, so that panel is boxed apart. Full numbers in Comparisons.
What the evidence spans
The ranking result rests on five kinds of reference whose errors fail in different ways, which is the part of this work hardest to argue with:
| The answer key came from | Testbeds |
|---|---|
| people reading the same imagery | Sen1Floods11 hand labels, Copernicus EMS through GEOID-Flood, WorldFloods v2 |
| another model's output | DFC2020, whose test labels are an iterated random forest, not hand-drawn |
| experts annotating a served product | Dynamic World's 409 expert tiles, audited from its own published probabilities |
| surveyors standing in the field | LUCAS Copernicus 2022, the only reference here that never saw a pixel |
| farmers' own declarations | EuroCrops, which also labels both sides of a two-date comparison |
Two warnings for practitioners
Report your readout's generalisation gap beside any ranking comparison. A small readout that has memorised its practice data reverses which confidence signal ranks best. On LUCAS the margin went from last of four model signals to the front, on the same data, purely from choosing the probe's regularisation on held-out ground.
A two-date difference needs the right floor. How often the map moves where the ground did not is 6% to 37% on crops — one to two orders of magnitude above the rate at which merely reseeding the readout moves it. Comparing a date difference against the reseed rate flatters it.
Quickstart
- Findings — what holds, the numbers, how a claim gets in, and the limits.
- Usage — assess a prediction, explain its review set, the production case, how to score a new rule.
- Recipe — what to do and not do when auditing a map.
- Technical report: the whole record in ten pages, what was done, what held, and what did not.
Also: TECHNIQUES (everything tried, one line each, with the verdict) · Protocol (how results are scored) · Explanation, Signals, Comparisons (per-cue, per-signal, per-experiment evidence) · Agent integration · Related work (where each idea comes from) · Roadmap.
Full documentation: https://olmoearth-inferencex.readthedocs.io/
Setup
Python 3.11+ and numpy; nothing else for the package. To use it:
pip install olmoearth-inferencex            # add [geo] to read and write GeoTIFFs
oe-inferencex demo                          # a first run on a made-up map
oe-inferencex assess --help
The development version installs from the repository:
pip install "olmoearth-inferencex @ git+https://github.com/2imi9/olmoearth_inferenceX".
examples/quickstart.py runs the whole surface on a
synthetic map with no data to download; the public API is what
oe_inferencex.__all__ exports, and CHANGELOG.md says what a
release contains. Rasters need the geo extra (rasterio); .npy input does
not.
To work on the repository, with the tests against the recorded numbers:
git clone https://github.com/2imi9/olmoearth_inferenceX.git
cd olmoearth_inferenceX
uv sync
uv run pytest
For the full experiment environment:
uv sync --extra encoder --extra geo
uv run python scripts/audit_one_scene.py   # one scene end to end
Licence
Apache License 2.0; see LICENSE. To cite the software or its recorded results, see CITATION.cff.
Contact
For questions and suggestions, please open an issue on GitHub.
1 maintainer

Release files for olmoearth-inferencex 1.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| olmoearth_inferencex-1.1.0.tar.gz | 70.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| olmoearth_inferencex-1.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 142.7 kB
Release files / olmoearth_inferencex-1.1.0.tar.gz
| Download URL | olmoearth_inferencex-1.1.0.tar.gz |
|---|---|
| Size | 70.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a546722eb6916bd8394fac0825fa24cc898be68dd3e55e530a6298df9690f08e
|
|
BLAKE2b-256 checksum How to use checksums |
b798e783d800a911c591ada01de59cf67a08042feca3d9b2a78b135c81c2c96d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.17 {"installer":{"name":"uv","version":"0.12.17","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|
Release files / olmoearth_inferencex-1.1.0-py3-none-any.whl
| Download URL | olmoearth_inferencex-1.1.0-py3-none-any.whl |
|---|---|
| Size | 72.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fe0a7a60ef4a3f4a540673c92d37a112064934ebaab187e0b8202a8323422ed2
|
|
BLAKE2b-256 checksum How to use checksums |
f34e814ceb03bcc7745aed401de9588fe97f80a1bf6eea9b1d0e475fa7fc37a1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
uv/0.12.17 {"installer":{"name":"uv","version":"0.12.17","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":true}
|














