
Omna


Hybrid search (semantic + keyword), enterprise-grade PII detection & masking, and schema understanding — directly on your Polars DataFrames. No vector database. No API key. Data never leaves your machine.
The problem
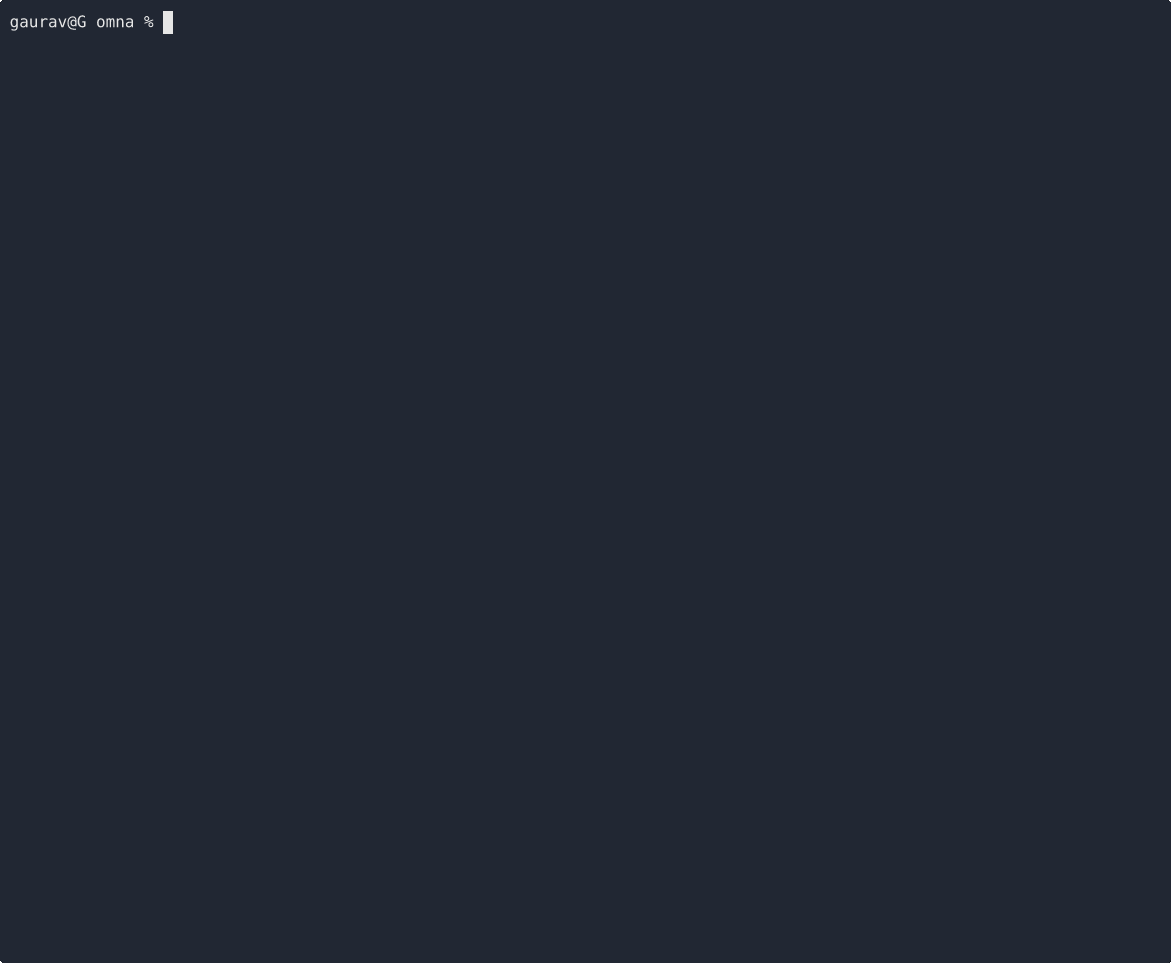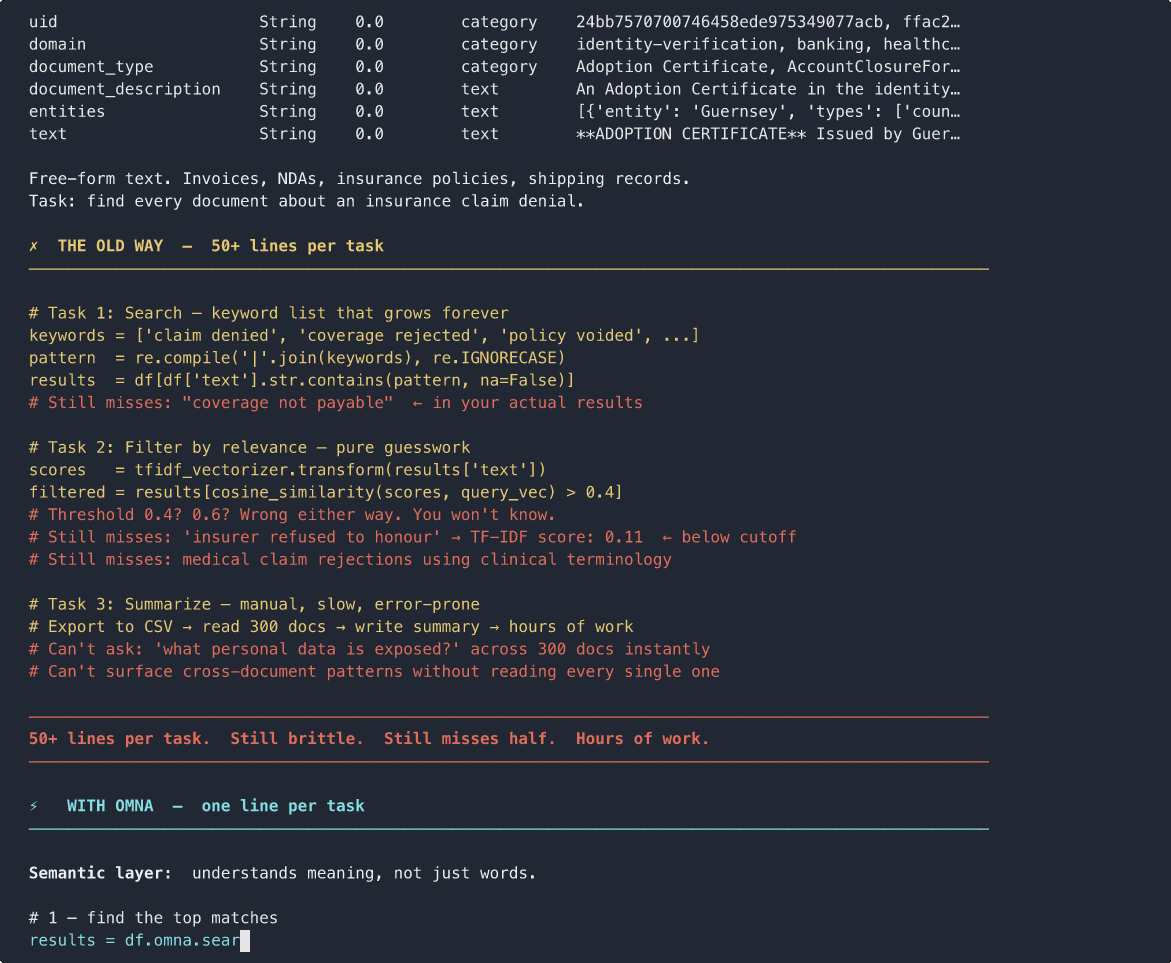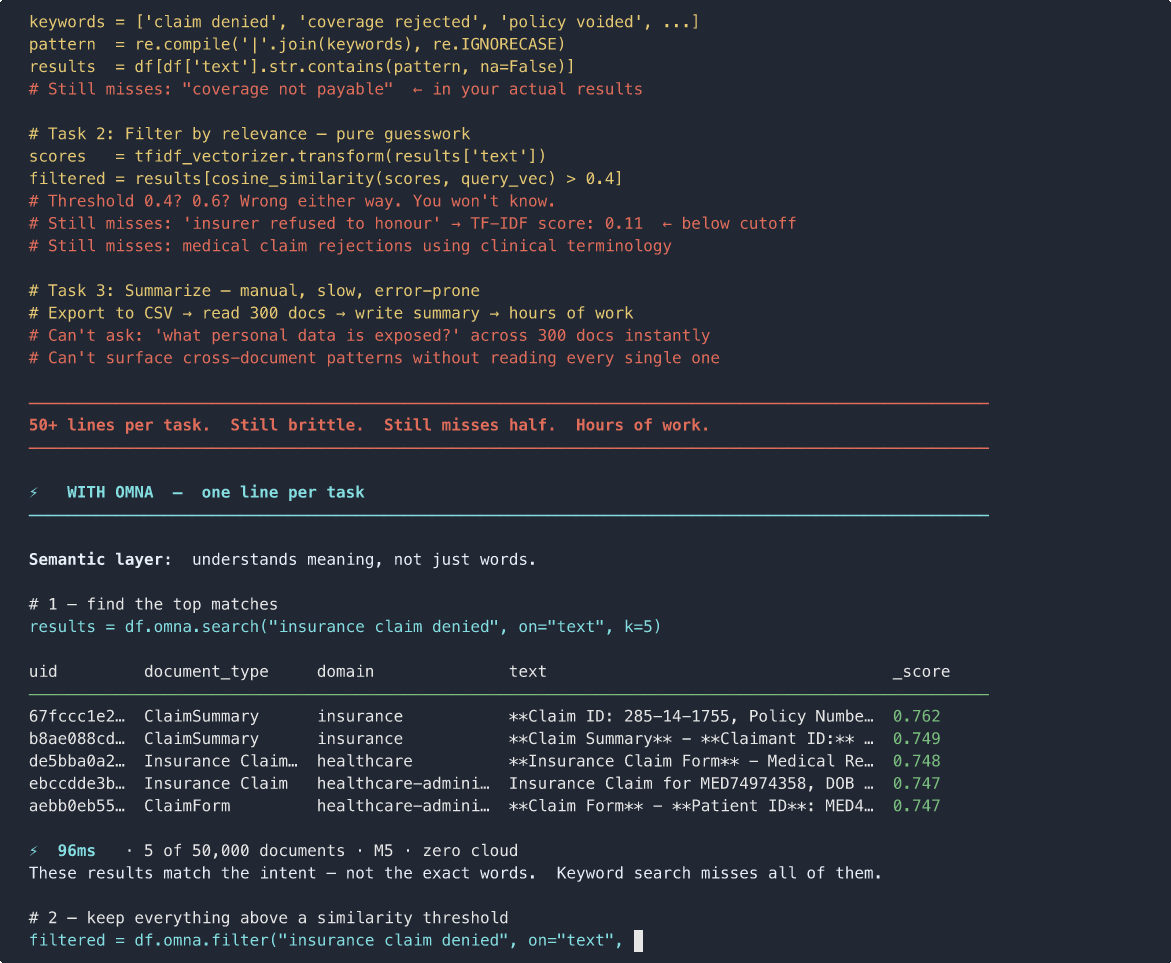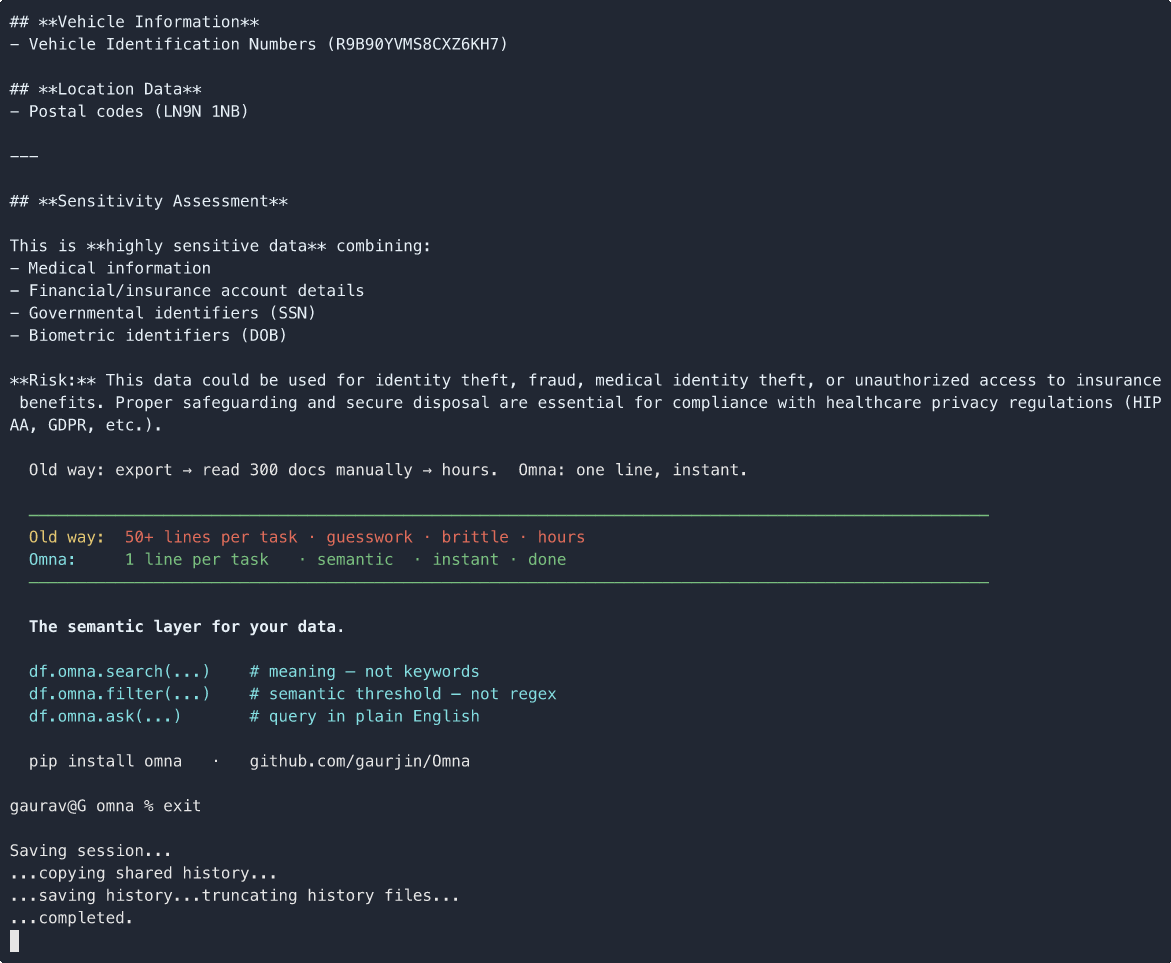
# Finding every insurance claim denial — painful
keywords = ["claim denied", "coverage rejected", "policy voided", ...]
pattern  = re.compile("|".join(keywords), re.IGNORECASE)
results  = df[df["text"].str.contains(pattern, na=False)]
# Still misses: "insurer refused to honour the policy"
# Still misses: "claim outcome: not payable"
# Still misses: medical claim rejections using clinical terminology
# ...50+ lines per task. Grows with every edge case. Still wrong.
# With Omna
results = df.omna.search("insurance claim denied", on="text", k=5)
# Finds ALL of them — including docs that never say "denied" literally.
# 9ms. 50,000 documents. Zero cloud.

filtered = df.omna.filter("insurance claim denied", on="text", threshold=0.73)
# Every semantically matching document above the threshold.
# No keyword lists. No guesswork. Pure meaning.

answer = results.omna.ask("What personal data do these documents expose?")
# → "These insurance documents expose SSNs, medical record numbers,
#    dates of birth, health plan numbers, and claimant identifiers."
# Instant. One line.
# Auditing for PII before the data ships — painful
for col in df.columns:
    for i, val in enumerate(df[col].to_list()):
        if re.search(r'\b\d{3}-\d{2}-\d{4}\b', str(val)):   # SSNs only
            print(f"row {i}, {col}: {str(val)[:60]}")
# Catches one pattern. Misses emails, phones, names, IBANs.
# No confidence score. No audit trail. No redaction.
# With Omna
df.omna.pii_report()          # audit — find every leak, every column
df.omna.mask_pii()            # redact — one line, full audit log
df.omna.mask_pii(model=True)  # + on-device AI model for contextual PII
# A six-layer engine: regex + checksum-validated IDs + 220+ secret rules +
# an on-device AI model — the SAME Rust engine as the Omna Mac app & extension.
# Reversible [PERSON_1] tokens; secrets always irreversibly redacted. Local.
# Benchmarked openly on Gretel (core-PII recall 0.84 with the model, up from
# 0.69 on the prior engine): see docs/benchmark.md.
Demo
The Sword — hybrid search (semantic + keyword), filter, and ask across 50,000 documents:
The Shield — PII audit and redaction in one line:
Dataset: Gretel PII Masking Benchmark (Gretel AI, acquired by NVIDIA) — 50,000 synthetic documents (the train split) built to test data privacy tools.
Enterprise-grade PII masking
Most "PII for DataFrames" tools are a regex or a Presidio wrapper. Omna's masking is a six-layer detection engine (pure Rust, fully on-device) — the same engine that powers the Omna Mac app and browser extension:
- L1 — patterns + checksum validators: emails, SSNs, cards (Luhn), IBANs, and 30+ international IDs verified, not just pattern-matched
- L2 — secrets: 220+ rules (AWS keys, GitHub tokens, JWTs, private keys) with entropy checks
- L3 — on-device AI model (
mask_pii(model=True)): catches contextual PII no regex can — bare names, addresses, medical context - L4–L6: entity resolution, reversible
[PERSON_1]tokens (secrets always irreversibly redacted), and a full audit trail
No cloud, no API key, no data leaves your machine.
Same Gretel benchmark, same scoring — only the engine changed:
| Gretel benchmark | Before (Presidio) | After (Omna engine) |
|---|---|---|
| Core-PII recall | 0.69 | 0.84 |
| All-types recall | 0.35 | 0.79 |
| All-types F1 | 0.50 | 0.82 |
| Types · secret rules · validated IDs | ~17 · 0 · none | 30+ · 220+ · 30+ |
df.omna.pii_report()          # audit — every PII column, with confidence
df.omna.mask_pii()            # redact (L1+L2) — instant, full audit log
df.omna.mask_pii(model=True)  # full L1–L6, model-grade
Full methodology + numbers: docs/benchmark.md.
Install
pip install "omna[all]"
Supported platforms: Python 3.10–3.12 on macOS or Linux. Windows is not supported. The PII engine (omna[pii], and mask_pii(model=True)) runs on Apple Silicon macOS and Linux — it is not available on Intel Macs, because its on-device model runtime (ONNX Runtime) ships no Intel-Mac build; Intel-Mac users can still use search, filter, and schema understanding.
Extras: omna[embed] (search/filter), omna[pii] (PII detection & masking), omna[ask] (LLM queries). A bare pip install omna (just polars + numpy + rich) gives schema understanding (understand_df()); the heavier features are opt-in. PII masking is powered by the compiled omna-pii-mask engine — a self-contained wheel with no heavy Python ML dependencies, pulled in automatically by omna[pii], omna[ask] (which masks rows before the API call), or omna[all]. No API key needed for search, filter, embed, pii_report, mask_pii, or understand. Only ask() requires ANTHROPIC_API_KEY.
Quick start
import polars as pl
import omna

df = pl.read_csv("documents.csv")

# 1 — explore the schema
omna.understand_df(df)

# 2 — audit for PII before anything touches the data
df.omna.pii_report()

# 3 — redact
clean = df.omna.mask_pii()

# 4 — build a search index once
clean.omna.embed("text")

# 5 — search by meaning
results = clean.omna.search("insurance claim denied", on="text", k=5)

# 6 — filter everything above a threshold
flagged = clean.omna.filter("insurance claim denied", on="text", threshold=0.73)

# 7 — ask a question in plain English
results.omna.ask("What personal data do these documents expose?")
What Omna does
| Method | What it does |
|---|---|
omna.understand_df(df) |
Schema inference — labels, null rates, samples. No LLM. |
df.omna.embed(column) |
Vectorize a text column once; reuse across sessions |
df.omna.search(query, on, k) |
Top-k results by hybrid relevance (semantic + keyword) |
df.omna.filter(query, on, threshold) |
Every row above a similarity threshold |
df.omna.pii_report() |
Audit every string column for PII |
df.omna.mask_pii() |
Redact PII, auto-save audit log |
df.omna.ask(question) |
Natural language queries over your DataFrame |
API reference
omna.understand_df(df) — explore before you do anything
No LLM. No API call. Analyzes column names, dtypes, null rates, and sample values.
omna.understand_df(df)
 column                dtype    null_pct   label     sample
 uid                   String     0.0%     category  24bb757...
 domain                String     0.0%     category  insurance, healthcare...
 document_type         String     0.0%     category  Invoice, ClaimForm...
 document_description  String     0.0%     text      An insurance claim...
 text                  String     0.0%     text      **Claim ID: 285-14...
Labels: email phone name id date text numeric boolean category unknown
df.omna.embed(column) — vectorize once, search forever
Converts text to 768-dimensional vectors using FastEmbed (local ONNX, no API key). Saves to .omna/{column}.parquet. Run once — search() and filter() load it automatically on every subsequent call.
df.omna.embed("text")
# → .omna/text.parquet
Model: nomic-ai/nomic-embed-text-v1.5 (768-dim, downloaded once on first use) — the same embedding model the Omna Mac app uses. Embed is a one-time cost.
| Hardware | 50k rows |
|---|---|
| MacBook Air M5 | ~45 min |
| MacBook Pro M4 Max | ~15 min |
| AWS GPU instance | ~2 min |
df.omna.search(query, on, k) — hybrid search (semantic + keyword)
Requires
df.omna.embed("column")first.
results = df.omna.search("insurance claim denied", on="text", k=5)
Search is hybrid by default: semantic (embedding) similarity and BM25 keyword
matching run together, fused with Reciprocal Rank Fusion. Semantics catch
meaning; BM25 catches rare exact tokens the embeddings blur — part codes, IDs,
surnames, acronyms. Results are ordered by fused relevance. The BM25 index is
built from the saved column on first use (no re-embedding, no change to your
index file). Pass hybrid=False for pure-semantic search.
results = df.omna.search("XJ9000", on="parts", k=5)              # exact code → BM25 nails it
results = df.omna.search("claim denied", on="text", hybrid=False) # meaning only
 uid            document_type         domain      text                               _score
 67fccc1e207…   ClaimSummary          insurance   **Claim ID: 285-14-1755, Policy…   0.762
 b8ae088cd21…   ClaimSummary          insurance   **Claim Summary**…                 0.749
 de5bba0a2cc…   Insurance Claim Form  healthcare  **Insurance Claim Form**…          0.748
 ebccdde3b42…   Insurance Claim       healthcare  Insurance Claim for MED74974358…   0.747
 aebb0eb55fb…   ClaimForm             healthcare  **Claim Form** - Patient ID…       0.747
_score is cosine similarity (0–1). None of these documents contain the phrase "insurance claim denied" — Omna finds them by meaning.
df.omna.filter(query, on, threshold) — semantic filter
Requires
df.omna.embed("column")first.
filtered = df.omna.filter("insurance claim denied", on="text", threshold=0.73)
# → N documents matched — all semantically related to claim denials
Returns every row above the threshold. Default: 0.3. Raise for precision, lower for recall.
Use search() for the top k. Use filter() for everything above a threshold.
df.omna.pii_report() — audit before you redact
df.omna.pii_report()
 column    detected types                                    hit rate   flagged
 entities  CREDIT_CARD, EMAIL_ADDRESS, PERSON, PHONE_NUMBER   85.4%    ✓ YES
 text      CREDIT_CARD, EMAIL_ADDRESS, PERSON, PHONE_NUMBER   78.1%    ✓ YES
Scans every string column. Returns hit rates, PII types, and confidence scores. Nothing is modified.
df.omna.mask_pii() — redact in one line
clean = df.omna.mask_pii()
# → Omna's own six-layer Rust engine (same kernel as the Mac app + browser
#   extension): reversible [PERSON_1]-style tokens; credentials/secrets
#   always irreversibly [REDACTED:KIND]; checksum-validated IDs; 220+ secret
#   rules. No heavy Python ML dependencies.
# → audit log saved to .omna/pii_audit.parquet automatically

clean = df.omna.mask_pii(model=True)
# → adds L3, the on-device AI model, for contextual PII regex can't catch
#   (bare prose names, addresses). Downloads the model (~809 MB) once.
# Requires the omna_pii_mask wheel (built from omna-workspace); see CHANGELOG.md.
Detects: PERSON EMAIL PHONE CREDIT_CARD US_SSN IP_ADDRESS IBAN MEDICAL_RECORD_NUMBER BANK_ACCOUNT, 220+ secret types, and 30+ international IDs — checksum-validated where applicable.
# Add the on-device AI layer (L3) for contextual PII regex can't catch —
# bare names, addresses, medical context. Downloads the model once.
clean = df.omna.mask_pii()              # L1+L2 (instant, deterministic)
df.omna.ask(question) — natural language queries
Privacy (since 2026-06-10): the sampled rows in the prompt are masked before they leave your machine (PII replaced with tokens; secrets redacted). Pass
mask_rows=Falseto send raw rows for synthetic/public data.
Sends schema + up to 20 sample rows to Claude. Requires ANTHROPIC_API_KEY.
export ANTHROPIC_API_KEY=sk-ant-...
results.omna.ask("What personal data do these documents expose?")
# → "These insurance documents expose SSNs, medical record numbers,
#    dates of birth, health plan numbers, and claimant identifiers."

# Override model
results.omna.ask("Summarise the key themes", model="claude-sonnet-4-6")
Default model: claude-haiku-4-5-20251001.
How it works
df.omna.search("insurance claim denied", on="text", k=5)
         │
         ▼
   embedder.py       FastEmbed — nomic-embed-text-v1.5, local ONNX
                     query → [0.12, -0.34, 0.87, ...]  768-dim vector
         │
         ▼
   index.py          loads .omna/text.parquet → Arrow memory, zero-copy
                     50,000 stored vectors in Polars' own allocation
         │
         ▼
   similarity.rs     Rust kernel — cosine similarity over all vectors
                     returns top-k sorted descending, no Python loop
         │
         ▼
   frame.py          slices result rows, attaches _score → pl.DataFrame
The Rust kernel is under 70 lines. Dot products and norms in machine code, no intermediate allocations. 500,000 × 768-dim vectors scored in milliseconds on a single core.
Performance
| 50k rows | 500k rows | |
|---|---|---|
| Omna search | 9ms | 27ms |
| Omna filter | 9ms | 27ms |
| Pandas + FAISS | ~25ms + index build | ~25ms + index build |
| Polars keyword regex | 1ms — exact match only | 1ms — exact match only |
Benchmarked on MacBook Air M5 with the prior 384-dim model, 10-query median, warm index. The current model (nomic-embed-text-v1.5, 768-dim) roughly doubles the per-query cosine cost — still single-digit-to-low-tens of milliseconds at these sizes.
Omna inherits Polars' Arrow columnar memory. The Rust similarity kernel operates on the same memory — no copy into NumPy, no copy into a C buffer.
FAQ
Does Omna send my data to the cloud?
No. Embedding, search, filter, PII detection, and masking all run locally. The only method that makes a network call is ask(), which sends schema metadata and sample rows to Claude via the Anthropic API — and only when you explicitly call it.
Do I need a GPU?
No. FastEmbed uses ONNX and runs on CPU. On Apple Silicon, it uses CoreML automatically. Embedding 50,000 documents takes ~45 minutes on a MacBook Air M5 — a one-time cost. After that, search() and filter() run in milliseconds from the saved index.
Why not FAISS / ChromaDB / Pinecone?
Those are vector databases. Omna is a Polars plugin. If your data already lives in a DataFrame, Omna adds hybrid search (semantic + keyword) with zero infrastructure — no separate process, no index server, no network hop. It's the difference between df.omna.search(...) and spinning up a separate service just to query your own data.
What PII types does Omna detect?
PERSON, EMAIL, PHONE, CREDIT_CARD, US_SSN, IP_ADDRESS, IBAN, MEDICAL_RECORD_NUMBER, BANK_ACCOUNT, 220+ secret types (API keys, tokens), and 30+ international IDs, and more. Detection runs on Omna's own six-layer Rust engine — fully local, no heavy Python ML dependencies.
Which Polars versions are supported?
Omna is tested on Polars 1.0+. It installs as a namespace plugin via df.omna.* — no import needed after import omna.
The embed step took 45 minutes. Do I have to redo it every time?
No. embed() saves the index to .omna/{column}.parquet. Every subsequent search() or filter() call loads it in ~300ms. You only re-run embed() if your data changes.
Roadmap
# Coming in v0.2
matched = transactions.omna.join(regulatory_categories, on="description")
# Match rows between two DataFrames by meaning, not exact key.
Star the repo to follow progress.
Help wanted — scaling toward a billion rows
Omna is fast and fully local at 50k–500k rows. How far can local-first semantic search go — a billion rows, on your own machine, no cloud? That's an open challenge, and the simplest workable idea wins. You don't need to know the internals to pitch in.
- Join the discussion: issue #3
- The three walls + idea directions: docs/scaling-to-a-billion-rows.md
- New contributors welcome — see CONTRIBUTING.md.
What's new
The PII engine was rebuilt from a Presidio + spaCy wrapper into Omna's own six-layer Rust engine (recall up ~2×, see Enterprise-grade PII masking), and the embedding model was upgraded to nomic-embed-text-v1.5. Full history in CHANGELOG.md.
License
| Layer | License |
|---|---|
Python package (omna/) |
MIT |
Rust engine (src/) |
Proprietary — ships as a compiled binary in the pip wheel |
1 maintainer

Metadata
1 maintainer
Release files for omna 0.2.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
Total release size: 3.2 MB
Release files / omna-0.2.3-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | omna-0.2.3-cp312-cp312-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 288.2 kB |
| Tags | CPython 3.12 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
a164c9dc7dbc4f40cb4ecd2001c858007a7623cdb230503c3cd677133ff19f0e
|
|
BLAKE2b-256 checksum How to use checksums |
ba87cf63fd5bf4a2d8734953ab1d23df92c96d3e6eb2122b6da98c3370983f5e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | omna-0.2.3-cp312-cp312-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 272.9 kB |
| Tags | CPython 3.12 Linux glibc 2.17+ ARM64 |
|
SHA-256 checksum How to use checksums |
9badbc2b2d20e404b83865753e123a7c2352f19def7da90518cd143977a2894f
|
|
BLAKE2b-256 checksum How to use checksums |
710077f96902f8dccd21e4cad433be918d573e049db6d6144c30d0b0b0c12890
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp312-cp312-macosx_11_0_arm64.whl
| Download URL | omna-0.2.3-cp312-cp312-macosx_11_0_arm64.whl |
|---|---|
| Size | 250.1 kB |
| Tags | CPython 3.12 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
9a3d9dd8e4eed65bd2c833f025fdf285cbbd52a003b3342fc45fd5ba3f19b544
|
|
BLAKE2b-256 checksum How to use checksums |
fc16ffc8a59b4f915ea76fe947376821509c6872faeefb3c90b12c9420cbca42
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp312-cp312-macosx_10_12_x86_64.whl
| Download URL | omna-0.2.3-cp312-cp312-macosx_10_12_x86_64.whl |
|---|---|
| Size | 260.2 kB |
| Tags | CPython 3.12 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
e900276d31cf204d222693a466872201e5db851c574cc1ff2bb4fb4f2d598a9f
|
|
BLAKE2b-256 checksum How to use checksums |
5f111eaaba7dd2a78cc790ca4f3ad89ef88d3efc0325ffb5ad52d6abd54126f6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | omna-0.2.3-cp311-cp311-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 290.8 kB |
| Tags | CPython 3.11 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
4bc65e97726b3f0d2dfabd122bfb383a4bdde5683d9d4b83bddb1823cb6e4c21
|
|
BLAKE2b-256 checksum How to use checksums |
f4f2880fc85f842bd348d48ddf583d5a034650c81de4091cae1ff3799466819a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | omna-0.2.3-cp311-cp311-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 275.7 kB |
| Tags | CPython 3.11 Linux glibc 2.17+ ARM64 |
|
SHA-256 checksum How to use checksums |
131a410e2be0702adf6f33e566da0a819799b26d92ddc0bec8805048a03522ab
|
|
BLAKE2b-256 checksum How to use checksums |
d538d424ed40fd08e5d05d124a2f8a0d69ae8d87314959388cb26eafb3e7b215
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp311-cp311-macosx_11_0_arm64.whl
| Download URL | omna-0.2.3-cp311-cp311-macosx_11_0_arm64.whl |
|---|---|
| Size | 254.6 kB |
| Tags | CPython 3.11 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
c44c1c82661c66fdf9339bddf0571f48fffc6efcb85ce035deea2e3fa6f57be4
|
|
BLAKE2b-256 checksum How to use checksums |
20e05f9fc7005998ecc26a9b673a559e4540c7004a5e2da16688cab0867104d4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp311-cp311-macosx_10_12_x86_64.whl
| Download URL | omna-0.2.3-cp311-cp311-macosx_10_12_x86_64.whl |
|---|---|
| Size | 260.8 kB |
| Tags | CPython 3.11 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
23e9ec80d4181106109096d732b38889604108f2a738df07575a5fdbc372ea75
|
|
BLAKE2b-256 checksum How to use checksums |
4346956779b66145daa858d4cae914c09479076a2d7335c1a8f358b559632214
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | omna-0.2.3-cp310-cp310-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 290.9 kB |
| Tags | CPython 3.10 Linux glibc 2.17+ x86-64 |
|
SHA-256 checksum How to use checksums |
c551aff89e9de7f250f55f10bfaa6c2d1ae61c3f3cf4d8535572a03b76a5edb1
|
|
BLAKE2b-256 checksum How to use checksums |
651e98026ef5008d58eec48084576ce58c5d6d2ff13b2444ed03b05fd6ad0e90
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | omna-0.2.3-cp310-cp310-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 275.7 kB |
| Tags | CPython 3.10 Linux glibc 2.17+ ARM64 |
|
SHA-256 checksum How to use checksums |
67933d300245df84106e784a97181027abba71aa190600ffa9a5155d15aa0f59
|
|
BLAKE2b-256 checksum How to use checksums |
c4fc238a6f00bd876dcfb07c611b1a4dad28502bf9495059cc18d9e4cde10a18
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp310-cp310-macosx_11_0_arm64.whl
| Download URL | omna-0.2.3-cp310-cp310-macosx_11_0_arm64.whl |
|---|---|
| Size | 254.7 kB |
| Tags | CPython 3.10 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
4062fcc66201a808f12d5940d9eea4824817289bf77d3e25086e7187505c3f09
|
|
BLAKE2b-256 checksum How to use checksums |
3decdfe44ed851cb3bc527582a3c718253772e665c0bcf51fd915074de8a8e4c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Release files / omna-0.2.3-cp310-cp310-macosx_10_12_x86_64.whl
| Download URL | omna-0.2.3-cp310-cp310-macosx_10_12_x86_64.whl |
|---|---|
| Size | 261.0 kB |
| Tags | CPython 3.10 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
092d997e06d30b29f1286dfcf7c9018bdea4df15af81295d0c51b096a43ab5db
|
|
BLAKE2b-256 checksum How to use checksums |
e3fa946a0d2310f25a5945057870c6d6643dd1b69c3113820b1da74257c1ade2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Security for omna 0.2.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














