
OntoSmith


An ontology-driven knowledge-graph builder: design the ontology, build the graph under it, and serve it — search, API, and app — from one pipeline.
Powered by Jev — the decision (judge) model inside OntoSmith — and built on Neo4j, the graph store underneath, with native vector search.
The stack has two named pillars: Jev judges what is true enough to write, and Neo4j stores the graph — native graph traversal, a vector index, and full-text search in one store. A build requires both.
Most knowledge-graph tooling starts from whatever a model happens to extract. OntoSmith starts from the ontology: you design the schema first — entity and relation types, definitions, boundary examples — a human approves it, and the graph is then built under that schema by a pipeline that separates proposing from judging. Models propose candidates; a fitted pair call converts enumerated pairs into candidate triples, and deterministic gates and the Jev decision model decide what is true enough to write. Every written triple carries its evidence span and provenance, and every build prices itself before it spends.
The method in one loop: cheap models propose candidate facts, the Jev decision model judges each against its evidence, and only judged facts are written, every one traceable to its span. (Proposed and rejected candidates are shown schematically; the written graph is the flagship build's.)
What the schema is — and is not
The ontology here is a flat extraction contract: a closed inventory of entity and relation types, each with a definition and boundary examples — drafted from your corpus or imported, approved by a human, and enforced type by type by the decision model. It is deliberately not a formal ontology: there is no class hierarchy, no inheritance, and no logical axioms — OntoSmith is not an OWL ontology editor, and it runs no inference or reasoning over the graph. The flatness is the point: judged per-type decisions are what make a build's quality measurable, and hierarchy would blur exactly those decisions. The job this shape is production-shaped for is narrower and concrete: turn a document corpus into a governed, evidence-carrying graph that search and agents can answer from.
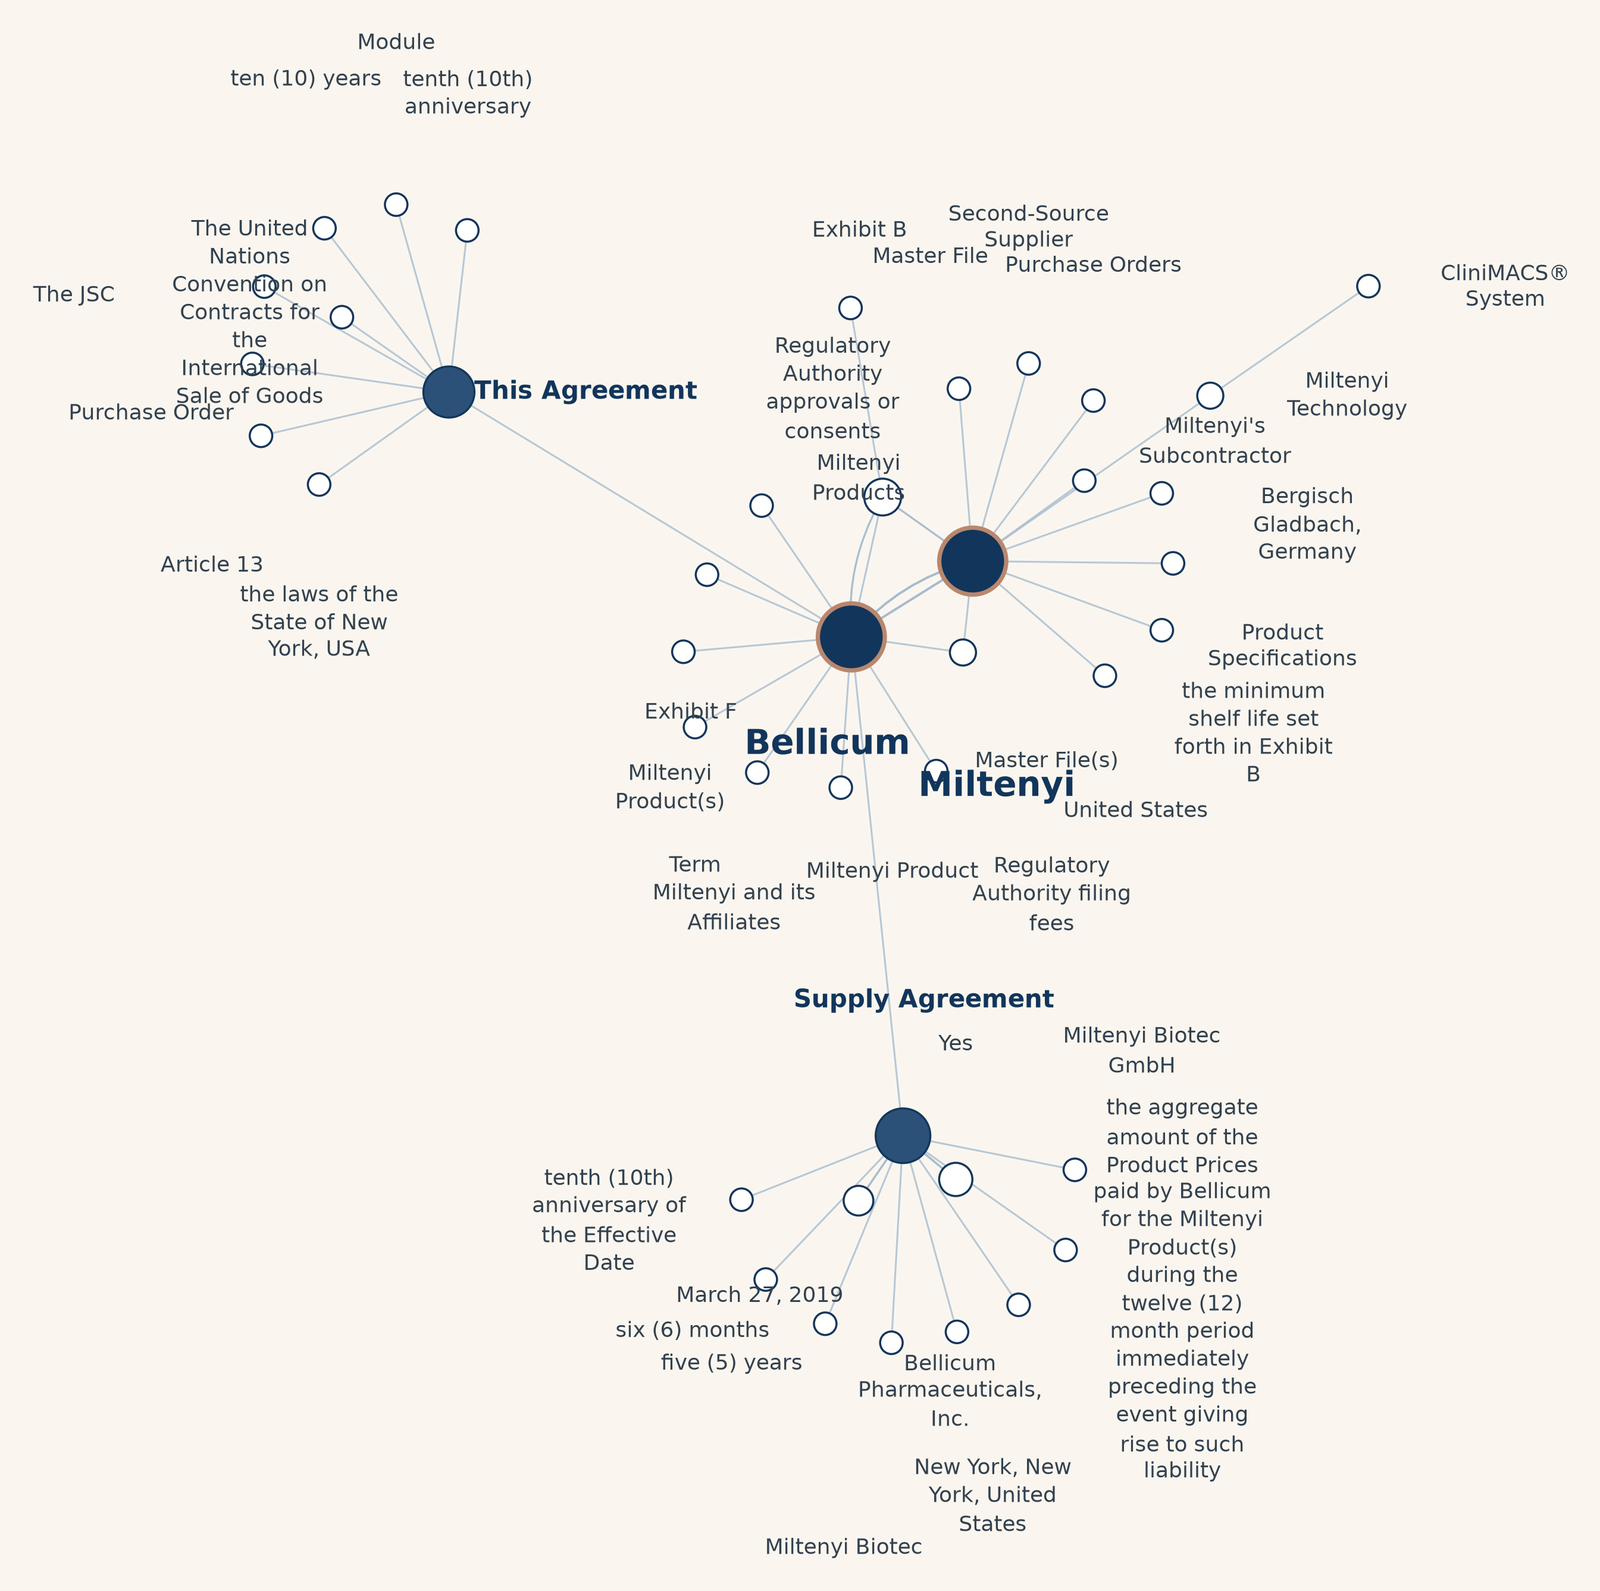
A real build, not a mock-up: the two parties' neighborhood in one CUAD supply agreement (Bellicum Pharmaceuticals × Miltenyi Biotec), built by the Legal Contract pack — 42 entities, 77 Tier-1 triples, every one carrying its evidence span and provenance. Corpus: CUAD (The Atticus Project), CC BY 4.0.
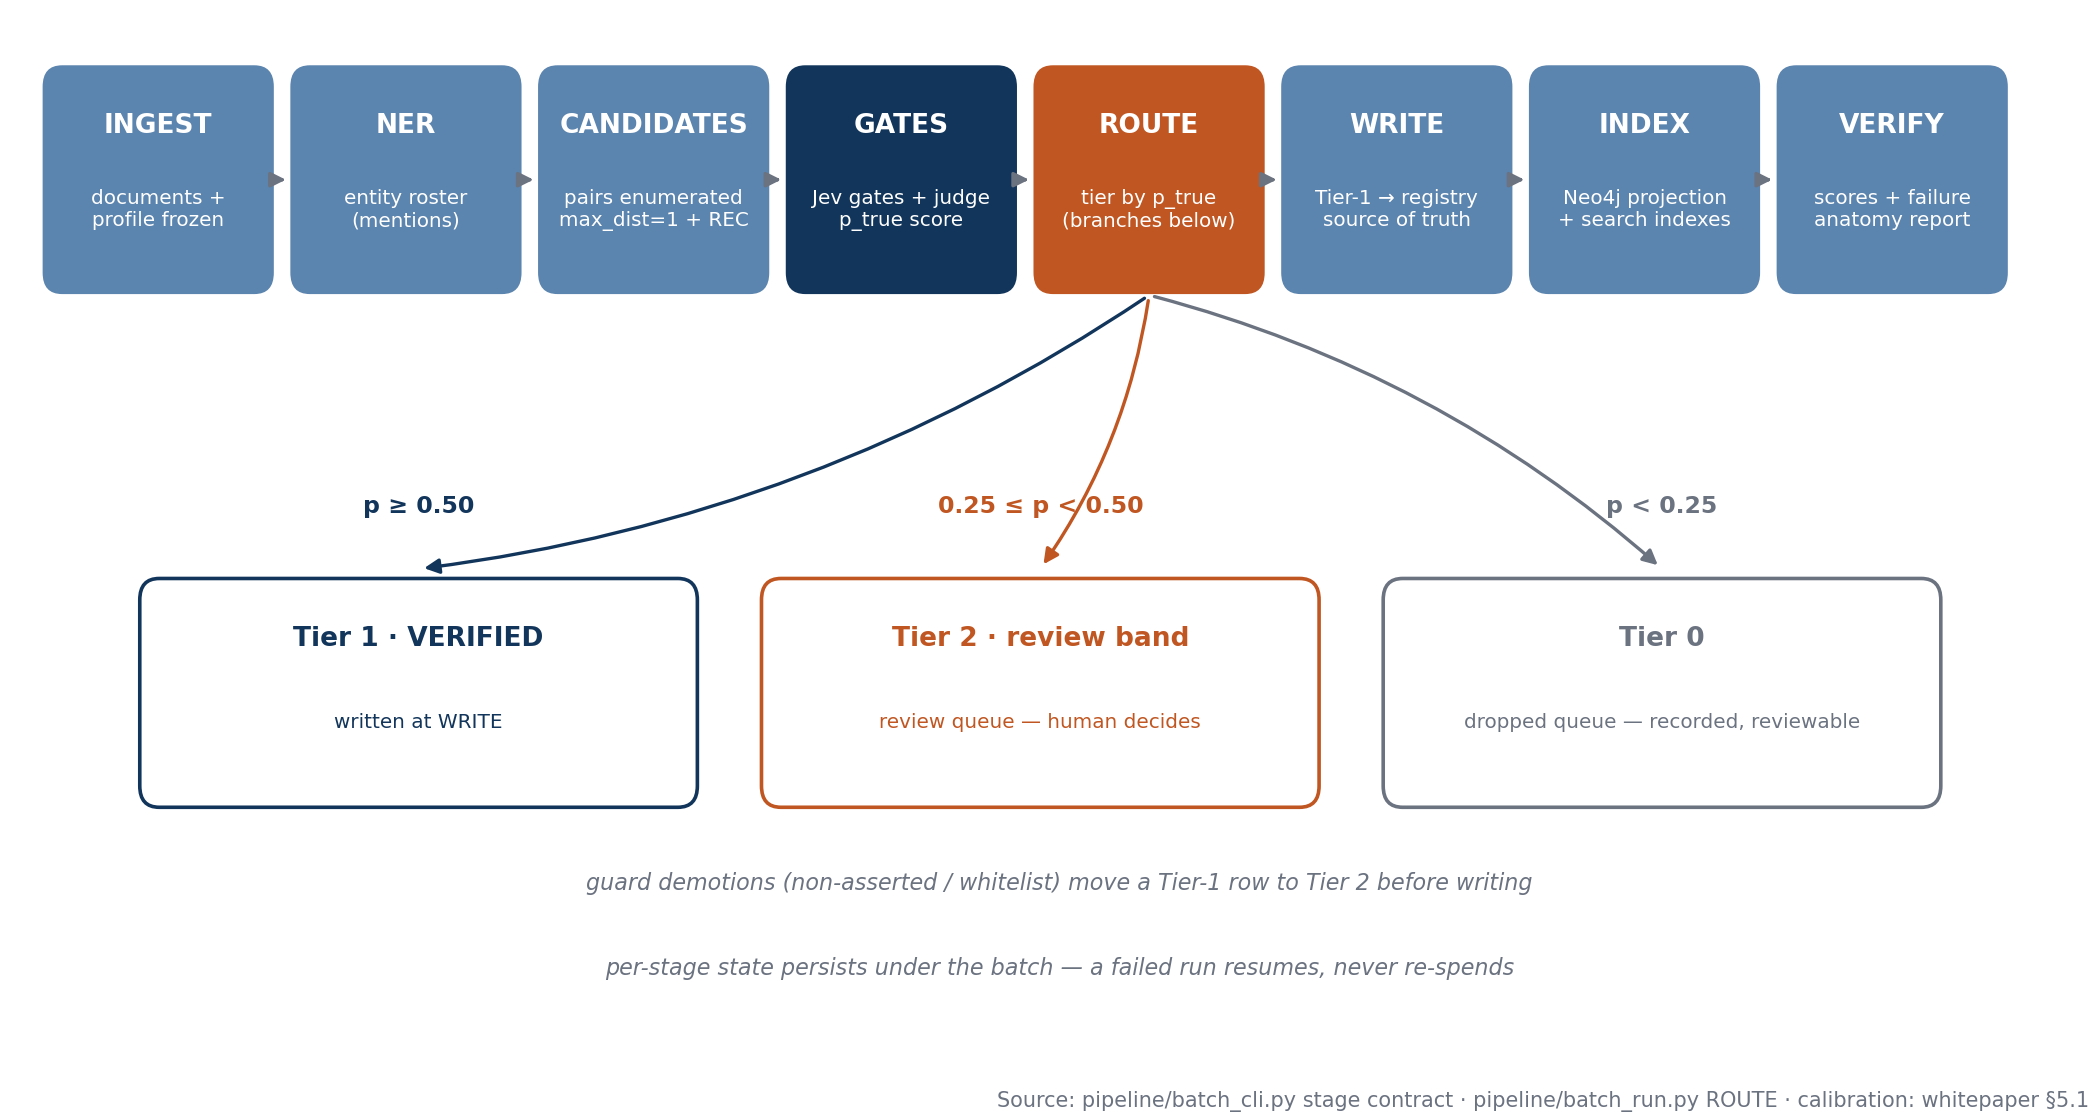
The batch stage contract and its tier branches, as coded
in pipeline/ — rendered by harness/render_charts.py.
Try it — step 1 needs no API key
Requirements
- OS — Linux (developed and tested on Linux). Windows: run under WSL2 — native Windows is not a tested platform.
- Python ≥ 3.11.
- An LLM connection — only for step 3 and live builds; steps 1–2 run keyless.
- Neo4j (5.x, Community Edition is enough) — the graph store a live build writes into; only step 3 needs it running. Setup in Connections.
Step 1 · Look around (no key, two minutes). Install from PyPI:
$ pip install ontosmith
$ ontosmith profile examples/corpus --family demo
Corpus profile
  family          demo
  status          COMPLETE
  documents       4
  claims          6
  decision points 0
  profile hash    sha256:7ae51d31fa9120ec
  spend           $0.0000
  written         profiles/demo (profile.json, setup_config.json, profile.md)

$ ontosmith inspect examples/triples.jsonl
Triple  (1 of 7 in examples/triples.jsonl)
  subject   Alder & Finch
  relation  founded by
  object    Mara Alder
Evidence
  [quote] Alder & Finch is a ceramics studio founded in 2011 by Mara Alder and Tomas Finch.
Provenance
  doc_id               alder-finch-history
  tier                 1
  p_true               0.98
p_true is the judge's ranking score for the triple —
a score to sort and threshold by, not a calibrated
probability.
The profiler is deterministic — the same corpus yields the same profile hash on every run — and the example's build output ships as a recorded artefact, so inspection runs offline too. Profiling, inspecting, validating, and the verification math all run keyless; the full list is in Connections.
Ask the shipped example build a question — retrieval over the recorded artefacts, still no key:
$ ontosmith search "Who founded Alder & Finch?"
And profile runs the same way on your own folder:
point it at any corpus directory to see whether it fits
before any build.
Step 2 · Check the evidence (no key). The flagship
build's corrected scoring replays from its shipped
adjudication appendix — no model calls, and the script
exits non-zero if any figure drifts:
python examples/demo/replay_scores.py
(appendix track). Every
headline figure maps to the command that recomputes it
in reproduce/.
Step 3 · Build with your own connection. The prerequisites, gathered in one place:
- Declare the binding —
ontosmith configurewalks the seats from the preset's values, probes the result with zero spend, and writes the bindings file. For the reference preset, accept the defaults and setOPENROUTER_API_KEY— the same key reaches every seat, the judge included (Connections explains the route and how to bind your own provider instead). One LLM connection is the only model connection a build needs; Connections covers the seats it plugs into and the recommended models. - Nothing else to install — candidates are
proposed by the proposer seat (a model call);
there is no local NLP stack. (A GLiNER+spaCy
pipeline candidate source and its
ontosmith[nlp]extra existed until 2026-10-29 and were retired — the LLM proposer is the only candidate source.) - Neo4j running — the build needs it: it is the
graph store WRITE, INDEX, and VERIFY work in.
Install it, set its password, and export
NEO4J_PASSWORD(a local default install needs nothing else; the connection variables and setup are in Connections). The run probes the store before the first stage and refuses by name if it is not serving, so a missing store costs no spend.
Cost, with its scope: the four-document demo subset prices at roughly $1–2 end to end, fixed overhead included. A full corpus prices from the counted projection before it runs (Cost guardrails, below). The flagship run's governing total prices at 3.8¢ per document over 500 documents — key-observed; the run's counted ledger reads 3.7¢ (whitepaper §5.6).
Then the hands-on guide (Track 1) walks a live build on your own documents end to end — profile, create, capped run, and the serve / search / inspect finish line. A run whose key is missing refuses before any stage starts, with the error naming the seat and the variable to set.
Optional surfaces install as extras:
pip install "ontosmith[viz]".
(The "ontosmith[neo4j]" extra installs the official
driver the export utilities use; the build itself talks
to Neo4j over HTTP and needs the server, not the extra.)
What's in the box
| Piece | What it is |
|---|---|
| Batch pipeline | The staged build: ingest → NER/roster → candidates → gates → route → write → index → verify, under a versioned pack, with a ledger-enforced spend cap |
| Corpus profiler | ontosmith profile — a deterministic census of your corpus and the decision points a human should settle first |
| Ontology builder | ontosmith ontology — drafts a domain schema from a profile, or imports an external ontology under a recorded scoping; deterministic validation; emits a hash-pinned pack only after explicit human approval |
| Four domain packs + Core baseline | Domain ontologies as data — schema, definitions, boundary examples, thresholds, measured conformance record (below) |
| Verification cores | ontosmith verify — raw and audit-corrected scoring, ceiling-adjusted recall, failure anatomy, counted cost projections |
| Evidence appendix | The flagship record's adjudication samples and verdicts, shipped for replay (benchmarks/appendix/) |
| Serving | Hybrid retrieval (vector + lexical + graph) via ontosmith search and a sample API — over the build's Neo4j store; the shipped demo's recorded artifacts also serve from files (lexical + graph arms only — no vector arm) |
| Demo + guide | A smoke corpus, a fetchable demo subset, and the hands-on guide that walks the whole loop in four tracks |
Where do I start?
| I want to… | Start here |
|---|---|
| Watch it run first | The three films, in order — Demo · Tutorial · Teardown (also collected on the project site) |
| See if my corpus fits | Step 1 above — profile it; the census names the decision points |
| Check the quality claims myself | Step 2 — the replay; the full record is the whitepaper (§5) |
| Build a graph from my documents | Hands-on, Track 1 |
| Use my own model provider | Connections — seats, recommended models, custom bindings |
| Read this project as an LLM | llms.txt — the machine-readable orientation |
| Design an ontology for my domain | ontosmith ontology — the loop below; hands-on Track 3 |
| Import an ontology my domain already has | ontosmith ontology import — BYO schema; hands-on Track 4 |
| Audit my own benchmark gold | ontosmith verify — hands-on appendix |
| Serve and query a built graph | docs/serving.md — ontosmith search / serve + the demo app at / over the build's Neo4j store (the shipped demo serves from its recorded files, no store needed) |
| Contribute | CONTRIBUTING.md |
The loop
Two artifacts carry the loop, and they are not the same
thing. A profile describes your corpus: a
deterministic census — document inventory, conventions,
decision points — that ontosmith profile produces with
no model calls, pinned by its hash. A pack carries
a domain's ontology as data: the type inventory,
definitions, and boundary examples a build runs under,
versioned and pinned by sha256, with the conformance
record of what its content measured. A batch binds one
of each.
- Profile —
ontosmith profilecensuses your corpus first (deterministic, no LLM): document inventory, conventions, and the decision points a human should settle before any build. - Design —
ontosmith ontologydrafts a domain schema from the profile, validates it deterministically, and emits it as a versioned, hash-pinned pack only after an explicit human approval. - Build —
ontosmith batchruns the staged pipeline under the pack. Measured operating points ship as defaults; the run's cost is capped by a stop-line, and countable before it starts (verify project). - Inspect —
ontosmith inspectshows any triple with its evidence span and provenance chain — and names what is missing when something is. - Verify —
ontosmith verifyships the measurement tooling with the product: audit your own gold, score your own builds raw and corrected, with the failure anatomy attached. - Serve —
ontosmith searchand the sample API (ontosmith serve) answer hybrid retrieval (vector + lexical + graph) over chunks and triples. A build is served from its Neo4j store; the shipped demo's recorded artifacts also serve from files — the keyless read-back path, lexical + graph arms only.
The method
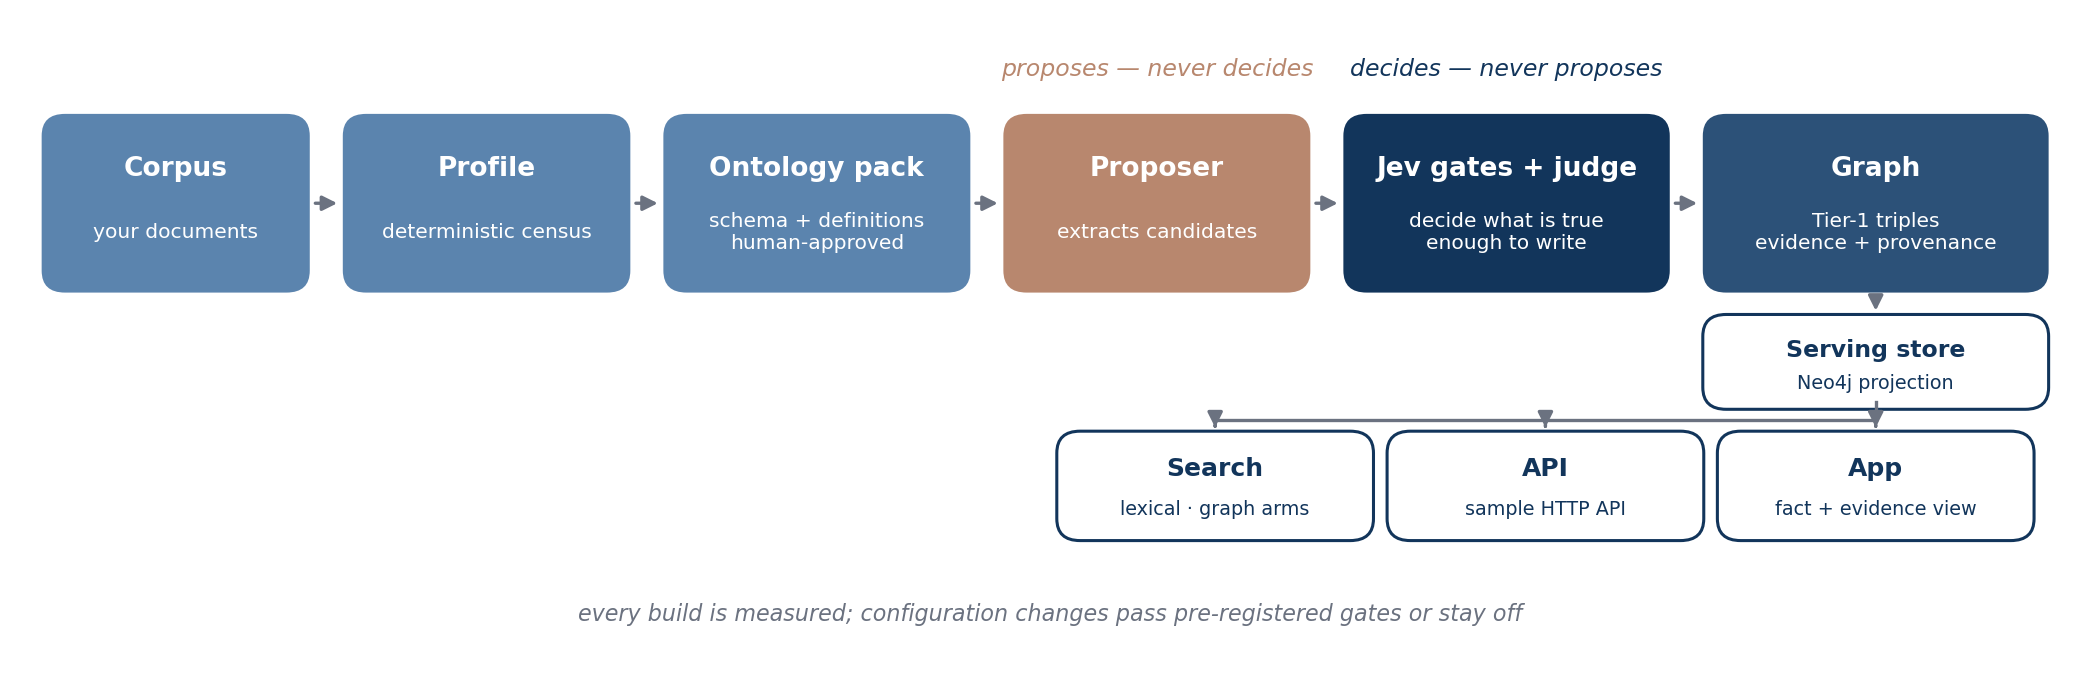
One separation runs through everything: nothing is written on the proposing seat's say-so alone. A fitted pair call converts enumerated pairs into candidate triples; deterministic gates check them; the Jev decision model decides what is written.
Operating points — thresholds, the enumeration window, the judge configuration — are chosen by pre-registered measurement gates, not by feel, and configurations that miss their gate stay off (the rejections are in the quality record). The full loop, walked end to end, is the hands-on guide.
How this differs from GraphRAG-style pipelines
GraphRAG-style pipelines typically centre the build on a single frontier-class model, and evaluate the result by its answers (or by extraction scores on someone else's benchmark), rather than by adjudicating the graph they actually built.
OntoSmith divides the job: a low-cost proposer proposes, a fitted pair call converts enumerated pairs into candidates, deterministic gates check form, and the pinned Jev model decides what is written — nothing is written on the proposer's say-so alone. Types come from an explicit, versioned ontology rather than emerging from the extraction, and the published record scores the graph itself, verdicts attached (§ Quality). If you want emergent structure and a working demo fast, the GraphRAG family gets you there sooner; this one is for when the graph has to be audited.
Three documents, three edges
A chunk store returns text and leaves the connections implicit. A graph makes each one an edge: typed, directed, carrying its evidence sentence. Three real items from this project's own records:
News — a head of government named inside somebody else's article. The article is about Abdul Jabar Sabet; one sentence in it carries a fact whose subject is a country:
Sabet was a long time aide to former Afghan Prime Minister Gulbuddin Hekmatyar.
As an edge — Afghanistan — head of government → Gulbuddin Hekmatyar — the fact answers to its own subject, evidence attached. (Appendix item B-193, judged supported.)
A novel — a character who enters by relation, not by cast list. Le Ventre de Paris never lists its cast; Quenu arrives through the plot:
He returns to his step-brother Quenu, a charcutier and his wife Lisa Quenu (formerly Macquart), with whom he finds refuge.
As an edge — Le Ventre de Paris — characters → Quenu — the character becomes a node, linked onward through the relations the sentence states. (Appendix item B-151, judged supported.)
A contract — a defined term is an identity, not a string. A CUAD agreement stipulates its vocabulary as it goes:
The term of this Agreement shall be ten (10) years (the "Term") which shall commence on the date upon which the Company delivers to Distributor the last Sample, as defined hereinafter.
The build collects stipulated terms into a
per-document registry and resolves them to their
referents, so every later "during the Term" attaches
to the same node: definition and uses are one entity,
not a scatter of string matches. (Corpus-profile
example, Legal Contract pack,
packs/legal-contract/profile/profile.json; CUAD,
CC BY 4.0.)
The appendix items are machine-adjudicated supported under the published contract (the appendix); quote spacing is normalized from the tokenized record.
Corpus packs
A pack is a domain's ontology as data: schema, definitions, boundary examples, thresholds, and its measured conformance record — hash-pinned, versioned, fail-closed on load. Domain content lives only in packs, never in code branches. The format's contract — manifest, pins, candidates, conformance — is docs/PACK_DESIGN.md.
| Pack | Contents | Measured on |
|---|---|---|
Bio Medical (bio-medical) |
Biomedical entity/relation schema, fitted qualifiers | BioRED (pilot record: whitepaper §5.7) |
Legal Contract (legal-contract) |
Contract schema: 41 label categories, role-word and defined-term rules | CUAD (promotion record: whitepaper §5.8) |
FIBO Contracts (fibo-contracts) |
Contract schema imported from FIBO (EDM Council, MIT): the FND Agreements module flattened under a recorded scoping — 15 entity + 13 relation types | CUAD, the same corpus as Legal Contract; emitted through the builder, so its record opens emitted_unmeasured — the measured account so far is the coverage record (hands-on Track 4; examples/fibo-import/) |
Open Domain (open-domain) |
Schema for general documents, with fitted direction declarations | Re-DocRED (flagship record: whitepaper §5) |
Core (core, baseline) |
The domain-neutral baseline every new corpus starts from | The cross-domain core record |
No pack fits your domain? The ontology builder (step 2) drafts one from your own corpus, for your approval — and if your domain already publishes an ontology, the builder imports it instead (hands-on Track 4).
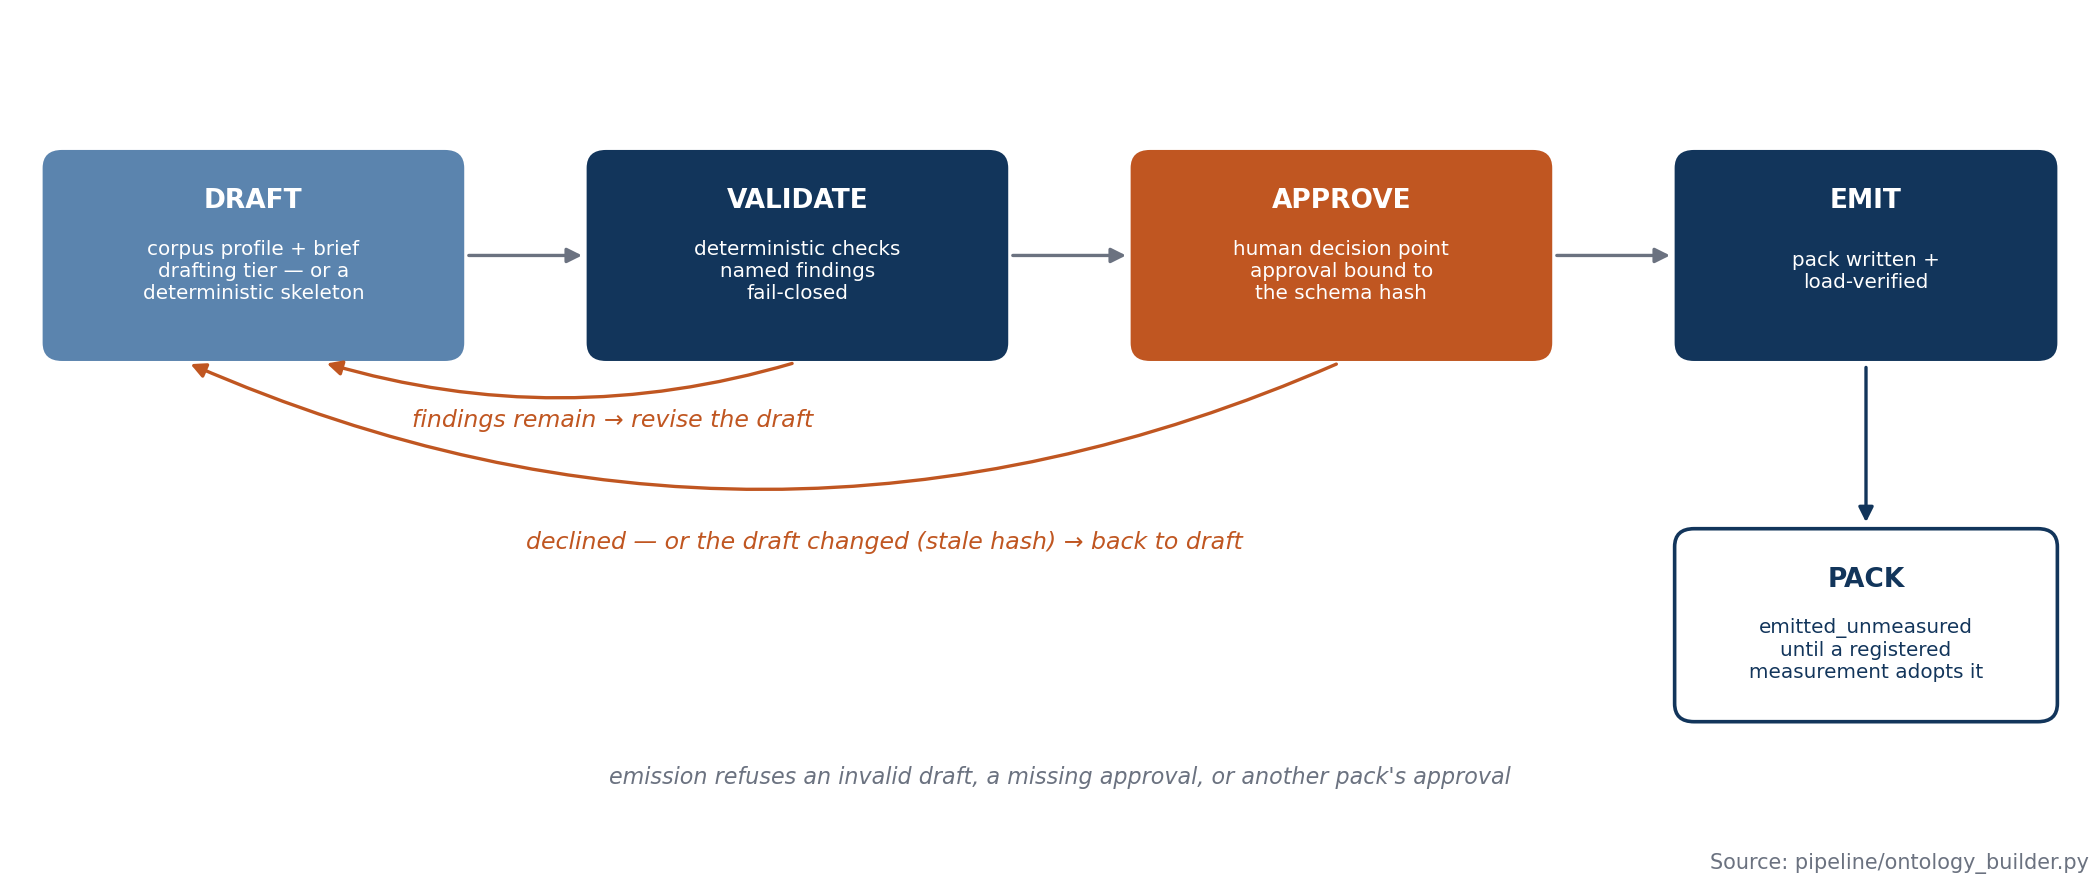
The builder loop and its refusal paths, as coded in
pipeline/ontology_builder.py — an emitted pack is
marked emitted_unmeasured until a registered
measurement adopts it.
Reference profile — measured bindings, your choice
The published measurements were made with one exact set of model bindings. That set ships as the reference profile, pre-filled in the connection layer as the default preset:
| Seat | Reference binding |
|---|---|
| Proposer — extracts candidates; never decides | anthropic/claude-haiku-5.5 |
| Judge — Jev, the decision gate; a pinned product component | typesafe/jev-1.13 |
| Escalation — adjudication escalation; in evaluation it also serves as the comparison judge — it never decides a build's triples | anthropic/claude-sonnet-5.5 |
| Drafting — schema/profile drafting; an authoring aid behind the human approve gate | — (ships unbound; bind your own) |
| Embedder — indexing and question embedding | openai/text-embedding-3-large |
Three layers, five seats: the method's judge layer is two seats in this table — the fitted pair judge, which shares the proposer's model row, and the pinned Jev gate — and drafting is an authoring seat outside the build loop.
Four models, one key: the preset reaches all four named models through a single connection key.
The names differ per seat because each measured seat's default won its job in measurement; the judge seat is the exception — a pinned component, not a bake-off winner — and you can re-point any seat (Connections).
Optimized for the Jev decision model; the other seats are yours to bind — see Optimized for Jev in Connections.
Read that table as provenance, not as a requirement: the preset is the environment the measurements were made in, so a default install runs the bindings the published numbers were measured under (the numbers themselves reproduce keyless from the appendix — step 2) — but OntoSmith needs a connection, not this one.
Domain packs declare only capability tiers (proposer / judge / escalation), never model names, so you can bind other models and endpoints in your own connection config; that is a custom binding, and run records state which binding produced a run. API keys are never settings values: config names the environment variable, the value comes from your environment. The full seat-by-seat picture — every seat, the recommended models, and the custom-binding contract — is Connections.
Cost guardrails
Spend is guarded by default. The tooling prints a
counted projection before a run (ontosmith verify project — candidate pairs counted from your data, priced
at rates you supply (--unit-cost); the tool takes
prices from the caller and never hardcodes a rate card).
Every batch enforces a stop-line: a run that would cross its cap refuses to start the unit that crosses it, and resumes from its ledger instead of re-spending.
Quality
How well does it work? The measured record — scores with
their scope and method, the failure anatomy, and the
pre-registered criterion that failed — lives in the
project whitepaper (§5); the evidence data and the replay
that recomputes it ship in benchmarks/.
What the numbers do and don't say. The corrected scores describe one measured build — the 3,902-triple sentence-window configuration — not the shipped default, which enumerates differently (whitepaper §5.6); the shipped Tier-1 set adds 186 promoted triples whose corrected precision is not recomputed. The adjudication is machine judging under a published, ruled contract — no human spot-check round has been run on the flagship sample. Retrieval is measured on one pinned 116-question set over long contracts, and at exactly zero on short abstracts. The whitepaper states each limit where the number lives (§5, §7).
When not to use it
OntoSmith is the wrong tool if you want a graph without an ontology: the schema-first step, the human approval points, and the measurement tooling are the product, not ceremony around it.
If you need a quick demo graph from a pile of text with no quality questions asked, lighter extraction tools will get you there faster — and if your domain's schema is still changing daily, settle it a little before pinning it into a pack.
Commands
| Command | What it does |
|---|---|
| Label | |
review |
interactive review-band labeling |
| Evaluate | |
evaluate · recalibrate · calibration |
|
inspect |
triple + evidence + provenance |
verify |
score / audit-sets / project / report |
| Models | |
llm · ollama |
candidate judges |
| Gates | |
triple · er · conflict · onto · cascade |
(Jev gates) |
| Connect | |
configure |
declare the seat bindings (wizard / --from-file) |
| Pipeline | |
batch |
create / run / status / rollback |
profile |
corpus profiler (deterministic, no LLM) |
ontology |
draft / validate / approve / emit a pack |
| Serve | |
search |
hybrid search over a built graph |
serve |
sample HTTP API (search / entity / neighborhood / triple-with-evidence) + the demo app at / |
The store — Neo4j
A build's graph lives in Neo4j: WRITE, INDEX, and VERIFY work in it, the graph views render through Neo4j's own tooling on the same host, and serving a build reads from it. It is a prerequisite for building, not an optional backend — setup and the connection variables are in Connections. The store holds one graph — the current build's, stamped with the identity of the ontology that produced it: a build under a different ontology replaces the previous graph (named in the run's output before it happens), never accumulates beside it, so search never needs a scope — it answers from the one graph that is there.
Asking questions of recorded artifacts needs no store: the search command and sample API also run over a file-backed store that reads a finished batch's records (or the shipped demo) directly — the demo/read-back path, whose search runs the lexical and graph arms only (docs/serving.md).
Status
Release 0.1.3, published on PyPI. The pipeline, profiler, ontology builder, inspect viewer, verification cores, packs, and the serving surface (search command + sample API) in this tree are measured, tested components, as is the minimal demo app served with the API.
License
MIT — Copyright (c) 2026 Dongbum Lee.
1 maintainer

Metadata
1 maintainer
Release files for ontosmith 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| ontosmith-0.1.3.tar.gz | 594.0 kB | With provenance | Details for ontosmith-0.1.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| ontosmith-0.1.3-py3-none-any.whl | Python 3 | none | any | Details for ontosmith-0.1.3-py3-none-any.whl |
Total release size: 1.1 MB
Release files / ontosmith-0.1.3.tar.gz
| Download URL | ontosmith-0.1.3.tar.gz |
|---|---|
| Size | 594.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3d4bce3826612774b110cd309812367b28beee10b57641abd0afc35ad2e7b9e8
|
|
BLAKE2b-256 checksum How to use checksums |
5192c3be0ad60687665dec16263b00b54649c05720b374aa3b79d5186bc89fbd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logRelease files / ontosmith-0.1.3-py3-none-any.whl
| Download URL | ontosmith-0.1.3-py3-none-any.whl |
|---|---|
| Size | 510.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7af8dca94ce7771ce5f4c75bdc0b897d80b82da6364fdac19421032bf9f569fc
|
|
BLAKE2b-256 checksum How to use checksums |
c4d4ae171a71836abfdfe5cb1772c3e6ea304ded64783761e5668868b75b0cf6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logSecurity for ontosmith 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for ontosmith-0.1.3.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 1, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














