
Open, calibrated System 1 decision models. Ask typed questions (choice, score, noul) about any state (text, email, ticket or JSON) and get a calibrated probability for every option: 17 ms on an NVIDIA GPU, 18 ms on a Mac. Distilled from open teachers, and benchmarked head to head against TypeSafe Jev, Laya, CLM-8B and frontier LLMs on the same questions with the same scorer.




Installation
pip install opendecider              # opendecider-nano
pip install "opendecider[small]"     # adds peft for opendecider-small, -small-td, -medium-td and -large-td
pip install "opendecider[mlx]"       # Apple Silicon: the MLX 4-bit / 8-bit builds of opendecider-small
pip install "opendecider[serve]"     # the HTTP server (Jev-compatible /v1/systemone)
Python 3.10 or newer. Works on Linux, Windows and macOS, on CPU, NVIDIA (CUDA) and Apple Silicon (MPS), and picks the device for you. Platform notes: Installation details. Try it without installing: live demo, or on a free NVIDIA GPU in Colab.
Quickstart
from opendecider import load

model = load("manjunathshiva/opendecider-nano")   # 0.8 GB, downloaded on first use; "…/opendecider-small" for the 4B

state = "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
questions = {
    "department": {"type": "choice", "instructions": "Which department should handle this?",
                   "criteria": {"billing": "invoices, payments, refunds",
                                "technical": "bugs, outages, system errors",
                                "other": "everything else"}},
    "urgency": {"type": "score", "instructions": "How urgent is this?",
                "criteria": ["not urgent", "soon", "blocking"]},
    "churn_risk": {"type": "noul", "instructions": "Does the user threaten to cancel or leave?"},
}

result = model.system_one(state, questions)
print(result["answers"]["department"]["choice"])   # billing        (probability 0.927)
print(result["answers"]["urgency"]["score"])       # 2 = blocking   (probability 0.604)
print(result["answers"]["churn_risk"]["noul"])     # 0.922 = probability the answer is yes
A state can be plain text or any JSON-serialisable object: a ticket with subject, body and customer fields, a log
record, an agent's tool-call trace. Questions can also be written with the helper classes Choice, Score and Noul.
Serve it: a drop-in for Jev's API
pip install "opendecider[serve]"
opendecider serve --model manjunathshiva/opendecider-nano       # http://0.0.0.0:8000
# or: docker compose up        (CPU)   |   docker compose -f compose.yaml -f compose.cuda.yaml up   (NVIDIA)
The server speaks TypeSafe Jev's /v1/systemone protocol, so existing Jev clients work by changing the base URL.
Tested with TypeSafe's own SDK (@typesafe-ai/sdk 0.6.0) and no code change:
TYPESAFE_BASE_URL=http://localhost:8000 TYPESAFE_API_KEY=<your OPENDECIDER_API_KEY> node app.js
curl -s localhost:8000/v1/systemone -H 'content-type: application/json' -d '{
  "state": "Hi, we were billed twice for March. Please refund the duplicate today.",
  "questions": {"department": {"type": "choice", "instructions": "Which department?",
                               "criteria": {"billing": "payments, refunds", "technical": "bugs, outages"}}}}'
| endpoint | what it does |
|---|---|
POST /v1/systemone |
one state, any number of typed questions (Jev's request and response shape) |
POST /v1/systemone/batch |
{"states": [...], "questions": {...}}: the same questions about many states in one call |
GET /v1/models |
the served model (as Jev's models list) |
GET /health, GET /ready |
liveness and readiness probes (model, device, version, queue depth) |
GET /metrics |
Prometheus text: requests by status, latency and batch-size histograms, in-flight, queue depth |
Production behaviour.
- Batching across requests: one inference thread merges the questions of all waiting requests into shared batches, so nano's batched speed holds under concurrent load.
- Bounded load: above
--max-in-flightrequests the server answers 503 withRetry-Afterat once instead of queueing without limit, and a request not answered within--request-timeout-sgets 504. - Validation: request size, questions per state, options per question and state length are all bounded, and invalid requests get a 4xx with a message naming the problem.
- Security and observability:
- bearer-token auth (
OPENDECIDER_API_KEY, constant-time comparison); - an
x-request-idheader on every response; - server errors never leak internals to the client.
- bearer-token auth (
- Configuration: every flag is also an environment variable (
OPENDECIDER_MODEL,OPENDECIDER_DEVICE,OPENDECIDER_MAX_BATCH,OPENDECIDER_THREADS, …); seeopendecider serve --help.
Performance under load (benchmarks/load_test.py: 100 concurrent users, 20 s ramp, 40 s hold, three questions per
request, one server process; raw results in benchmarks/results/load/):
| model and hardware | requests / s | p50 | p95 | p99 | errors |
|---|---|---|---|---|---|
nano, CPU only (8 cores, AWS c7i.4xlarge), --dtype bfloat16 |
24 | 4.4 s | 4.9 s | 5.2 s | 0 |
| nano, CPU only (same machine), default fp32 | 9 | 16.6 s | 17.2 s | 19.0 s | 0 |
| nano, 1× NVIDIA L4 | 50 | 2.1 s | 2.3 s | 2.3 s | 0 |
small (4B), 1× NVIDIA L4, --small-batch 16 |
20 | 5.8 s | 6.5 s | 6.6 s | 0 |
| small (4B), 1× NVIDIA L4, default | 9 | 14.4 s | 14.7 s | 16.1 s | 0 |
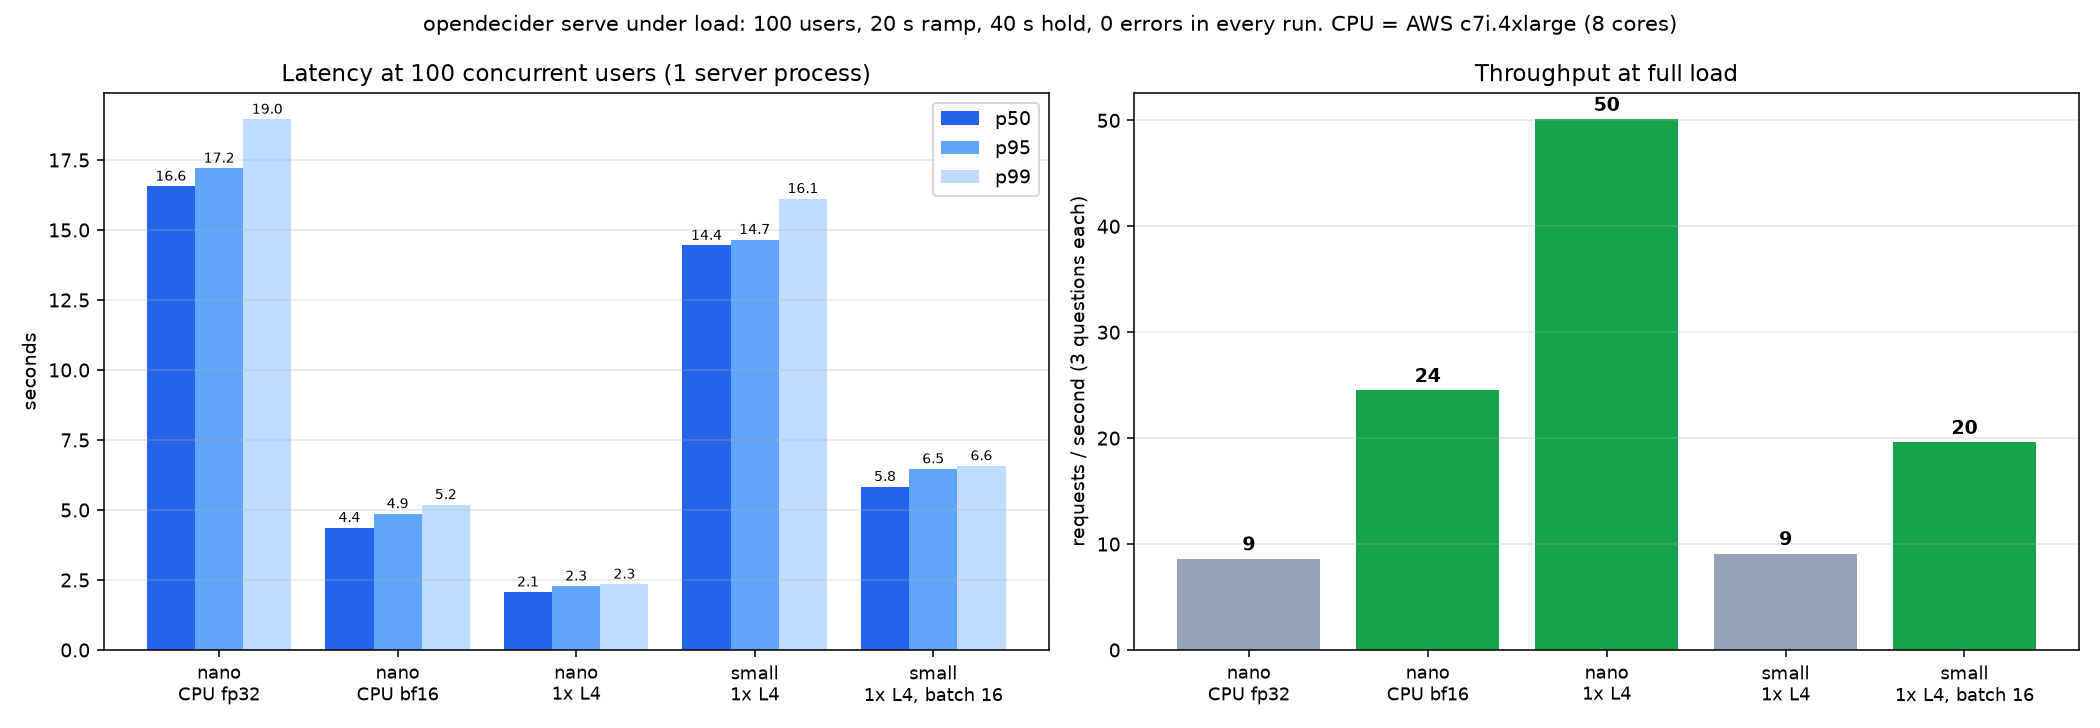
With 100 users each waiting for their answer before sending the next, latency is roughly users ÷ throughput, so a single process is at its limit here. Fewer users or more processes bring it down. To serve more traffic, run more replicas behind a load balancer (one process per GPU; on CPU, one process per 8 or so physical cores). Recommended settings:
- CPU with bf16 units (Intel Sapphire Rapids and newer, i.e. AMX):
--dtype bfloat16, 2.8× the throughput. On typed-decisions it has the same accuracy as fp32 (0.796) and the same top answer on 1,992 of 2,000 questions. On CPUs without bf16 units keep the default. - Qwen-based models on a GPU (small, small-td, medium-td, large-td):
--small-batch 16, 2.2× the throughput. The top answer changes on about 1 question in 75 (bf16 arithmetic in padded batches), so leave it off where you need exactly the published answers. --threadsat most the number of physical cores; oversubscribing hyperthreads slows CPU inference.
On the wire a score answer follows Jev: score is the expected score (it can fall between levels) and level is the
most likely level. In the Python library score is the most likely level and expected the expected score. Answers
also carry probabilities and confidence, and truncated plus a top-level warnings list when a state was cut to
fit the model's input length.
Ahead of Jev on unseen decisions, ahead of Laya like for like
On 200 general decisions none of these models trained on, opendecider-medium-td scores 0.765 against 0.730 for TypeSafe Jev, the best of any model you can run yourself; only Claude Fable 5.1 (0.840) and GPT-6 Astra (0.790) score higher, at 10–20× the latency. Its probabilities are also the closest of all tested systems to the spread of 100 human votes on ChaosNLI (JSD 0.035, against 0.148 for Jev).
On the typed-decisions benchmark (2,000 decisions across four business workflows), scored with the Jev-vs-Laya harness published by Kameshwara Pavan kumar Mantha and the Antz AI team, the like-for-like comparison is with Laya's typed-decisions checkpoint, which was also fine-tuned on the dataset's train split (the test split was never used for training or model selection): opendecider-nano 0.796 vs 0.766 (+0.030, 95% CI +0.014 to +0.044), opendecider-small-td 0.792 (+0.026, +0.008 to +0.043) and opendecider-medium-td 0.788 (+0.022, +0.005 to +0.040).
Zero-shot models are a reference there, not a head-to-head: TypeSafe Jev scores 0.754 asked one question per request (0.737 when sent the whole case in one request, the dataset's native format) and meraGPT Decider 1 0.768 (the dataset's leaderboard), and opendecider-small, which never saw the dataset, scores 0.672 (Laya's base checkpoint 0.362). The dataset's gold labels come from a ~4B teacher whose own fresh samples agree with them 73.5% of the time, and its card notes that fine-tuned and zero-shot scores are not comparable, so read fine-tuned scores near 0.8 as fitting these workflows, not as general superiority.
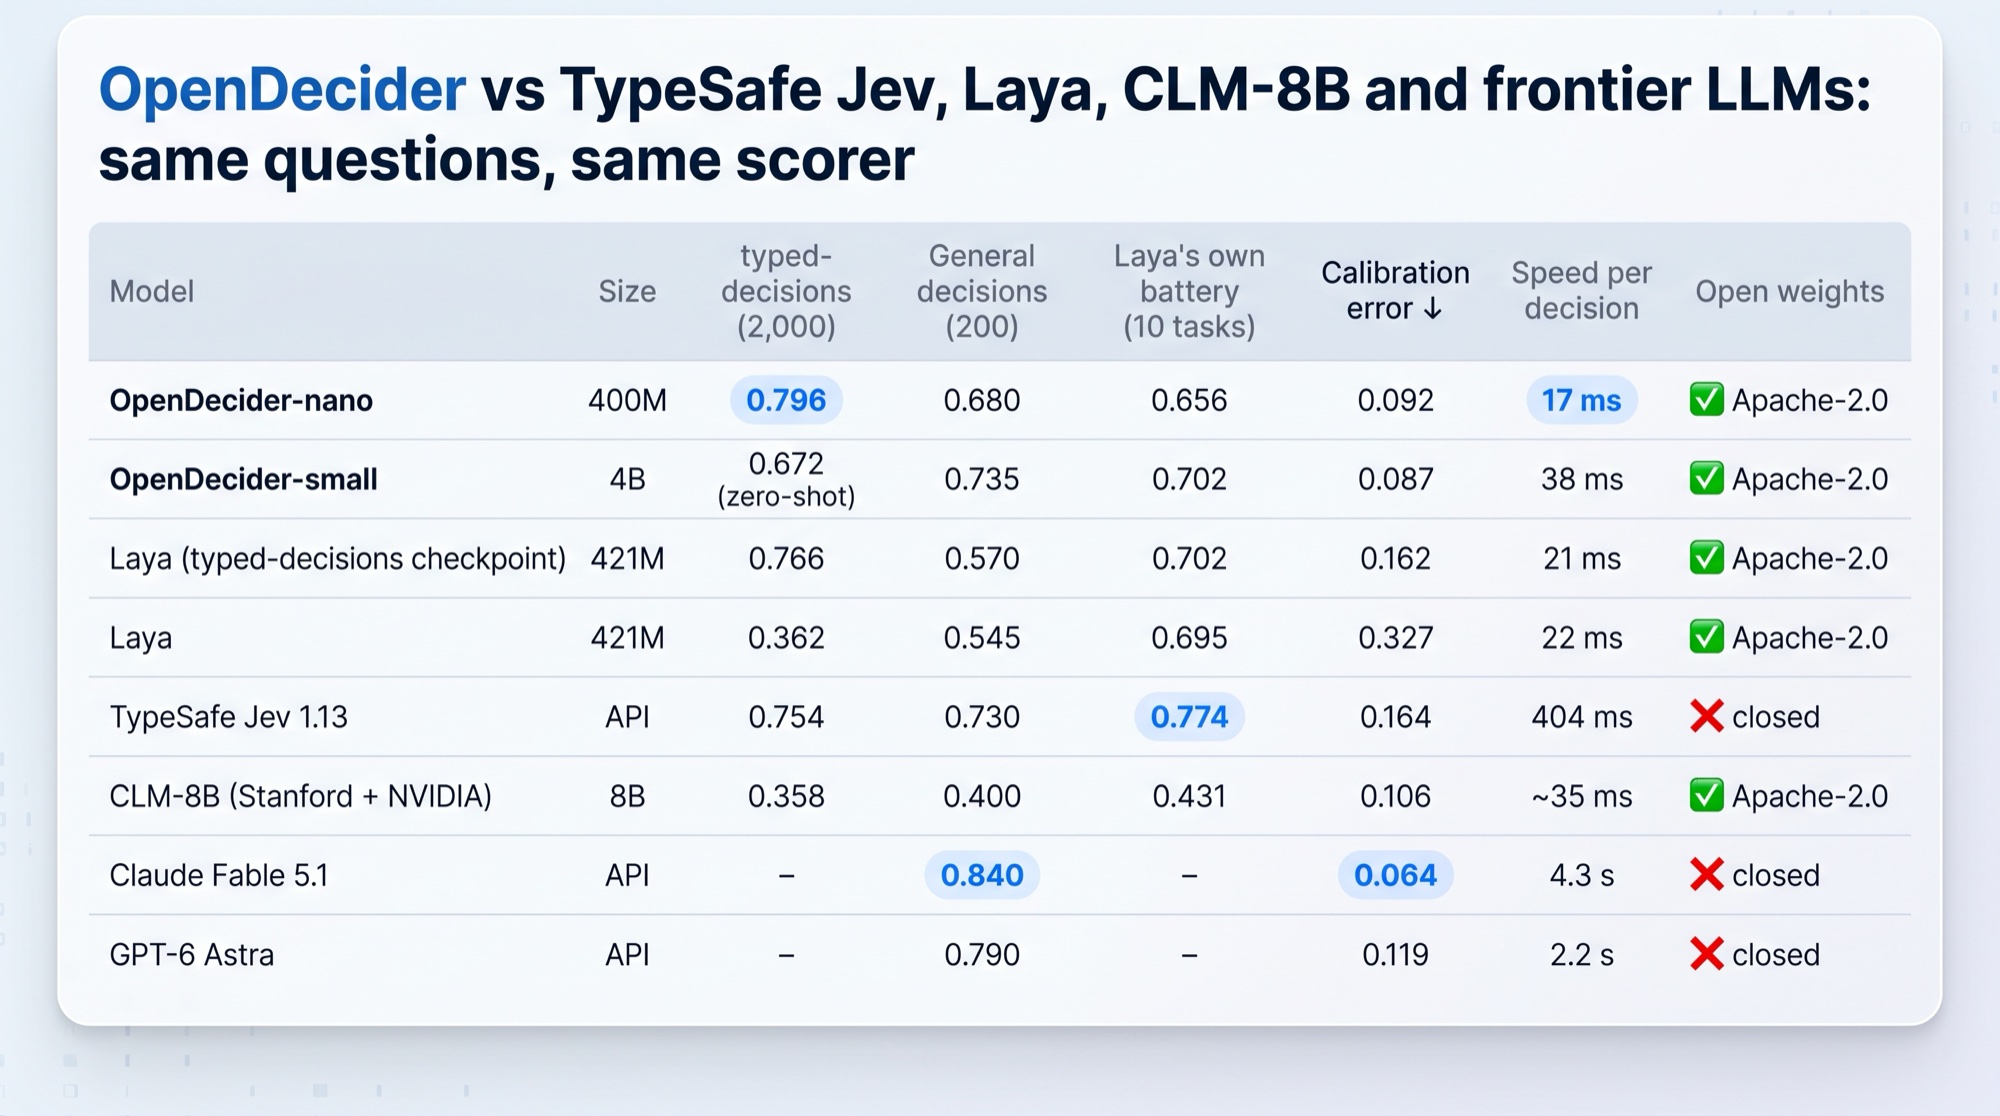
Highlighted: best in each column. typed-decisions scored with the Antz AI harness; OpenDecider-nano and Laya's typed-decisions checkpoint were fine-tuned on the train split, and the test split was never seen. Speeds: OpenDecider on an NVIDIA L40S, Laya on Apple Silicon, APIs include the network. Every number: COMPARISON.md.
What's new in 0.2.0
opendecider serve: a production server that speaks Jev's API. Existing Jev clients work by changing the base URL; tested with TypeSafe's own SDK. It adds dynamic batching, back-pressure, limits, auth, Prometheus metrics and Docker images. See Serve it.- Load-tested: 100 concurrent users with 0 errors; nano serves 50 requests/s on one NVIDIA L4 and 24 on 8 CPU cores
with
--dtype bfloat16. - Nothing silent: responses report token usage and mark truncated inputs.
- Production/Stable: a versioning policy for the API and the wire format (patch releases never break it; breaking changes only in a new minor release, after a deprecation), plus CodeQL, Dependabot and a security policy.
What's new in 0.1.2
- opendecider-medium-td (Qwen3-30B-A3B + LoRA): 0.765 on 200 general decisions, the best of any model you can run yourself and ahead of Jev (0.730); the closest of all systems to the human label spread on ChaosNLI (JSD 0.035); 0.788 on typed-decisions and 0.725 on Laya's battery. NVIDIA / Linux only.
- opendecider-large-td (Qwen3-Next-80B-A3B + LoRA), no package update needed: the best calibration of any model you can run yourself (ECE 0.083) and the closest of all 16 tested systems to human judgement (JSD 0.030); typed-decisions 0.801 (+0.035 vs Laya-td like for like); its most confident half of general decisions is 0.870 accurate vs Jev's 0.860. NVIDIA only, ~160 GB of GPU memory.
- Multi-GPU loading: models larger than one GPU are spread across all visible GPUs automatically.
What's new in 0.1.1
- opendecider-small-td: the 4B fine-tuned for business workflows, 0.792 on typed-decisions.
- Apple Silicon MLX builds of opendecider-small:
pip install "opendecider[mlx]". The 8-bit build (4.5 GB) gives the same answers as full precision on 399 of 400 general and 1,955 of 2,000 typed-decisions questions, about 2× faster than PyTorch on a Mac; the 4-bit build (2.6 GB) costs about 2 points on typed-decisions. - Colab notebook for NVIDIA (open it), tested top to bottom on an NVIDIA GPU.
- Benchmark harness in benchmarks/: rebuilds every table here from the logged answers and re-scores any model.
- T4 support: opendecider-small runs in fp16 on GPUs without bf16 (probabilities within about 0.003 of bf16).
What's new in 0.1.0
- First release:
opendecider-nano(~400M, Ettin encoder) andopendecider-small(4B, LoRA on Qwen3-4B-Instruct-2507). - Measured against TypeSafe Jev directly, through TypeSafe's own API, on every benchmark, alongside Laya, CLM-8B and five frontier LLMs.
- Same results on every platform: both models give identical benchmark scores on Apple Silicon (MPS) and Linux + NVIDIA (CUDA).
- Licence-clean data: every training dataset is listed in NOTICE. A non-commercial dataset found in our audit was removed before release, and no outputs of Claude or GPT models were used.
OpenDecider answers typed questions over any state in a single forward pass (nano) or a single next-token read (small). There's no text generation, so nothing to parse and nothing to hallucinate. Every answer carries a full, calibrated probability distribution you can threshold, route on or log.
The checkpoints:
| backbone | params | context | memory | use it for | |
|---|---|---|---|---|---|
opendecider-nano |
Ettin-encoder-400m | ~400M | 2,048 | 2.0 GiB | speed: 17–18 ms per question, ~9 ms batched; typed business decisions |
opendecider-small |
Qwen3-4B-Instruct-2507 + LoRA | 4B | 768 (training inputs) | 8.9 GiB, tested on a 16 GB Mac mini | accuracy and calibration on decisions it has never seen |
opendecider-small-td |
Qwen3-4B-Instruct-2507 + LoRA | 4B | 768 (training inputs) | 8.9 GiB | business workflows like typed-decisions' (triage, invoices, security alerts, agent traces): 0.792 |
opendecider-medium-td |
Qwen3-30B-A3B-Instruct-2507 + LoRA | 30B (3B active) | 768 (training inputs) | 61 GB bf16, across several GPUs (tested on 4× L40S) | the most accurate self-hostable model on general decisions (0.765) and the closest to human judgement; NVIDIA only |
opendecider-large-td |
Qwen3-Next-80B-A3B-Instruct + LoRA | 80B (3B active) | 768 (training inputs) | 160 GB bf16, across several GPUs (tested on 4× L40S) | probabilities you can threshold on: best calibration and agreement with people; NVIDIA only |
opendecider-small-mlx-8bit |
opendecider-small, MLX 8-bit | 4B | 768 (training inputs) | 4.5 GB | Macs: same answers as full precision (1,955/2,000 on typed-decisions), 66 ms per question |
opendecider-small-mlx-4bit |
opendecider-small, MLX 4-bit | 4B | 768 (training inputs) | 2.6 GB | Macs with little memory; about 2 points lower on typed-decisions (0.651) |
Coming next (in development)
- Rule-labelled evaluation: every model on tasksource/procedural-typed-decisions, whose answers are computed exactly from rules, so it measures correctness rather than agreement with a teacher model.
- No Mac build of medium yet: a 4-bit MLX version (before the typed-decisions fine-tune) scored 0.725 on general decisions, no better than opendecider-small-mlx-8bit (0.730) at several times the memory, so it was not released.
Installation details
# 1. a virtual environment (macOS / Linux)
python3 -m venv .venv && source .venv/bin/activate
# Windows PowerShell:  py -m venv .venv ; .venv\Scripts\Activate.ps1

# 2. PyTorch for your hardware (skip if already installed)
pip install torch                                                        # macOS (Apple Silicon uses MPS) and CPU
pip install torch --index-url https://download.pytorch.org/whl/cu128      # Linux / Windows with an NVIDIA GPU

# 3. OpenDecider
pip install "opendecider[small]"
- Device: CUDA, then MPS, then CPU, chosen automatically. Override with
load(..., device="cpu"). - Offline or air-gapped: download a model folder once (
huggingface-cli download manjunathshiva/opendecider-nano --local-dir ./nano), thenload("./nano"). - CPU only: nano runs fine on CPU for batch jobs. small needs ~17 GB of RAM in fp32 and is slow on CPU.
- Memory: nano 2.0 GiB, small 8.9 GiB of GPU or unified memory, measured on a 16 GB Mac mini (M4), where the GPU budget is 11.8 GiB.
medium-td has 61 GB and large-td 160 GB of bf16 weights, spread across all visible NVIDIA GPUs (both tested on 4× L40S,
48 GB each). large-td needs transformers 4.57 or newer;
pip install flash-linear-attentionspeeds it up.
Decision primitives
from opendecider import Choice, Score, Noul

Choice("Which team?", {"billing": "charges, refunds", "technical": "bugs"})   # pick one; descriptions optional
Choice("Which intent?", ["refund", "replacement", "information"])             # a plain list of labels
Score("How urgent?", ["not urgent", "soon", "blocking"])                      # ordered levels, lowest first
Noul("Is this spam?")                                                          # yes / no
Noul("Is this spam?", {"true": "unsolicited marketing", "false": "mail the user wants"})
Answers:
{"type": "choice", "choice": "billing", "probabilities": {"billing": 0.927, ...}, "confidence": 0.927}
{"type": "score",  "score": 2, "expected": 1.51, "probabilities": {"0": 0.091, "1": 0.305, "2": 0.604}, "confidence": 0.604}
{"type": "noul",   "noul": 0.922, "probabilities": {"true": 0.922, "false": 0.078}, "confidence": 0.922}
system_one(state, questions) takes any number of questions about one state. opendecider-nano answers all of them in
one padded batch (9.3 ms per question at 50 questions on a Mac); opendecider-small answers them in sequence.
Measure latency on your own hardware: python -m opendecider.bench_speed manjunathshiva/opendecider-nano.
Architecture
- opendecider-nano: Ettin-encoder-400m (bidirectional, fully fine-tuned) reads
question: …, [MASK] option 1, [MASK] option 2, …, input: <state>. The hidden state at each[MASK]goes through a small MLP (Linear–GELU–LayerNorm–Linear) to one logit, then a softmax across that question's options. The answer space is defined at request time, so new schemas need no retraining. There's no per-option token budget, so a 78-option question costs one forward pass. - opendecider-small: Qwen3-4B-Instruct-2507 with a LoRA adapter (r = 16, all linear projections). The options are lettered, and one forward pass gives the probability of each letter as the next token. Above 26 options it scores each option name's log-probability after the shared prompt.
- opendecider-medium-td: the same design on Qwen3-30B-A3B-Instruct-2507 (a mixture of experts, 3B active). The LoRA adapter (r = 16) is on the attention projections only; the experts are frozen.
- opendecider-large-td: the same design on Qwen3-Next-80B-A3B-Instruct, whose layers mix full attention (12) and Gated DeltaNet linear attention (36); the adapter covers the attention projections of both.
Training
Distillation from calibrated teachers. Two openly licensed teachers, Qwen3-235B-A22B-Instruct-2507 (Apache-2.0) and DeepSeek V4.1 Flash (MIT), scored every training question through token log-probabilities. Each teacher was temperature-scaled on held-out gold labels before the two were averaged, so the students learn calibrated distributions, not hard labels. Datasets that come with gold labels only use label-smoothed gold.
Data. Public classification, intent, emotion, NLI, reading-comprehension, topic, toxicity, spam, relevance and paraphrase datasets, plus synthetic business cases, emails and product reviews written for this project (full list and licences in NOTICE). opendecider-nano, -small-td, -medium-td and -large-td then had a short fine-tune on the typed-decisions train split. No benchmark dataset below, or its family, is in the training data, and every training pool was checked for text overlap with all test sets (0 overlaps).
Benchmarks
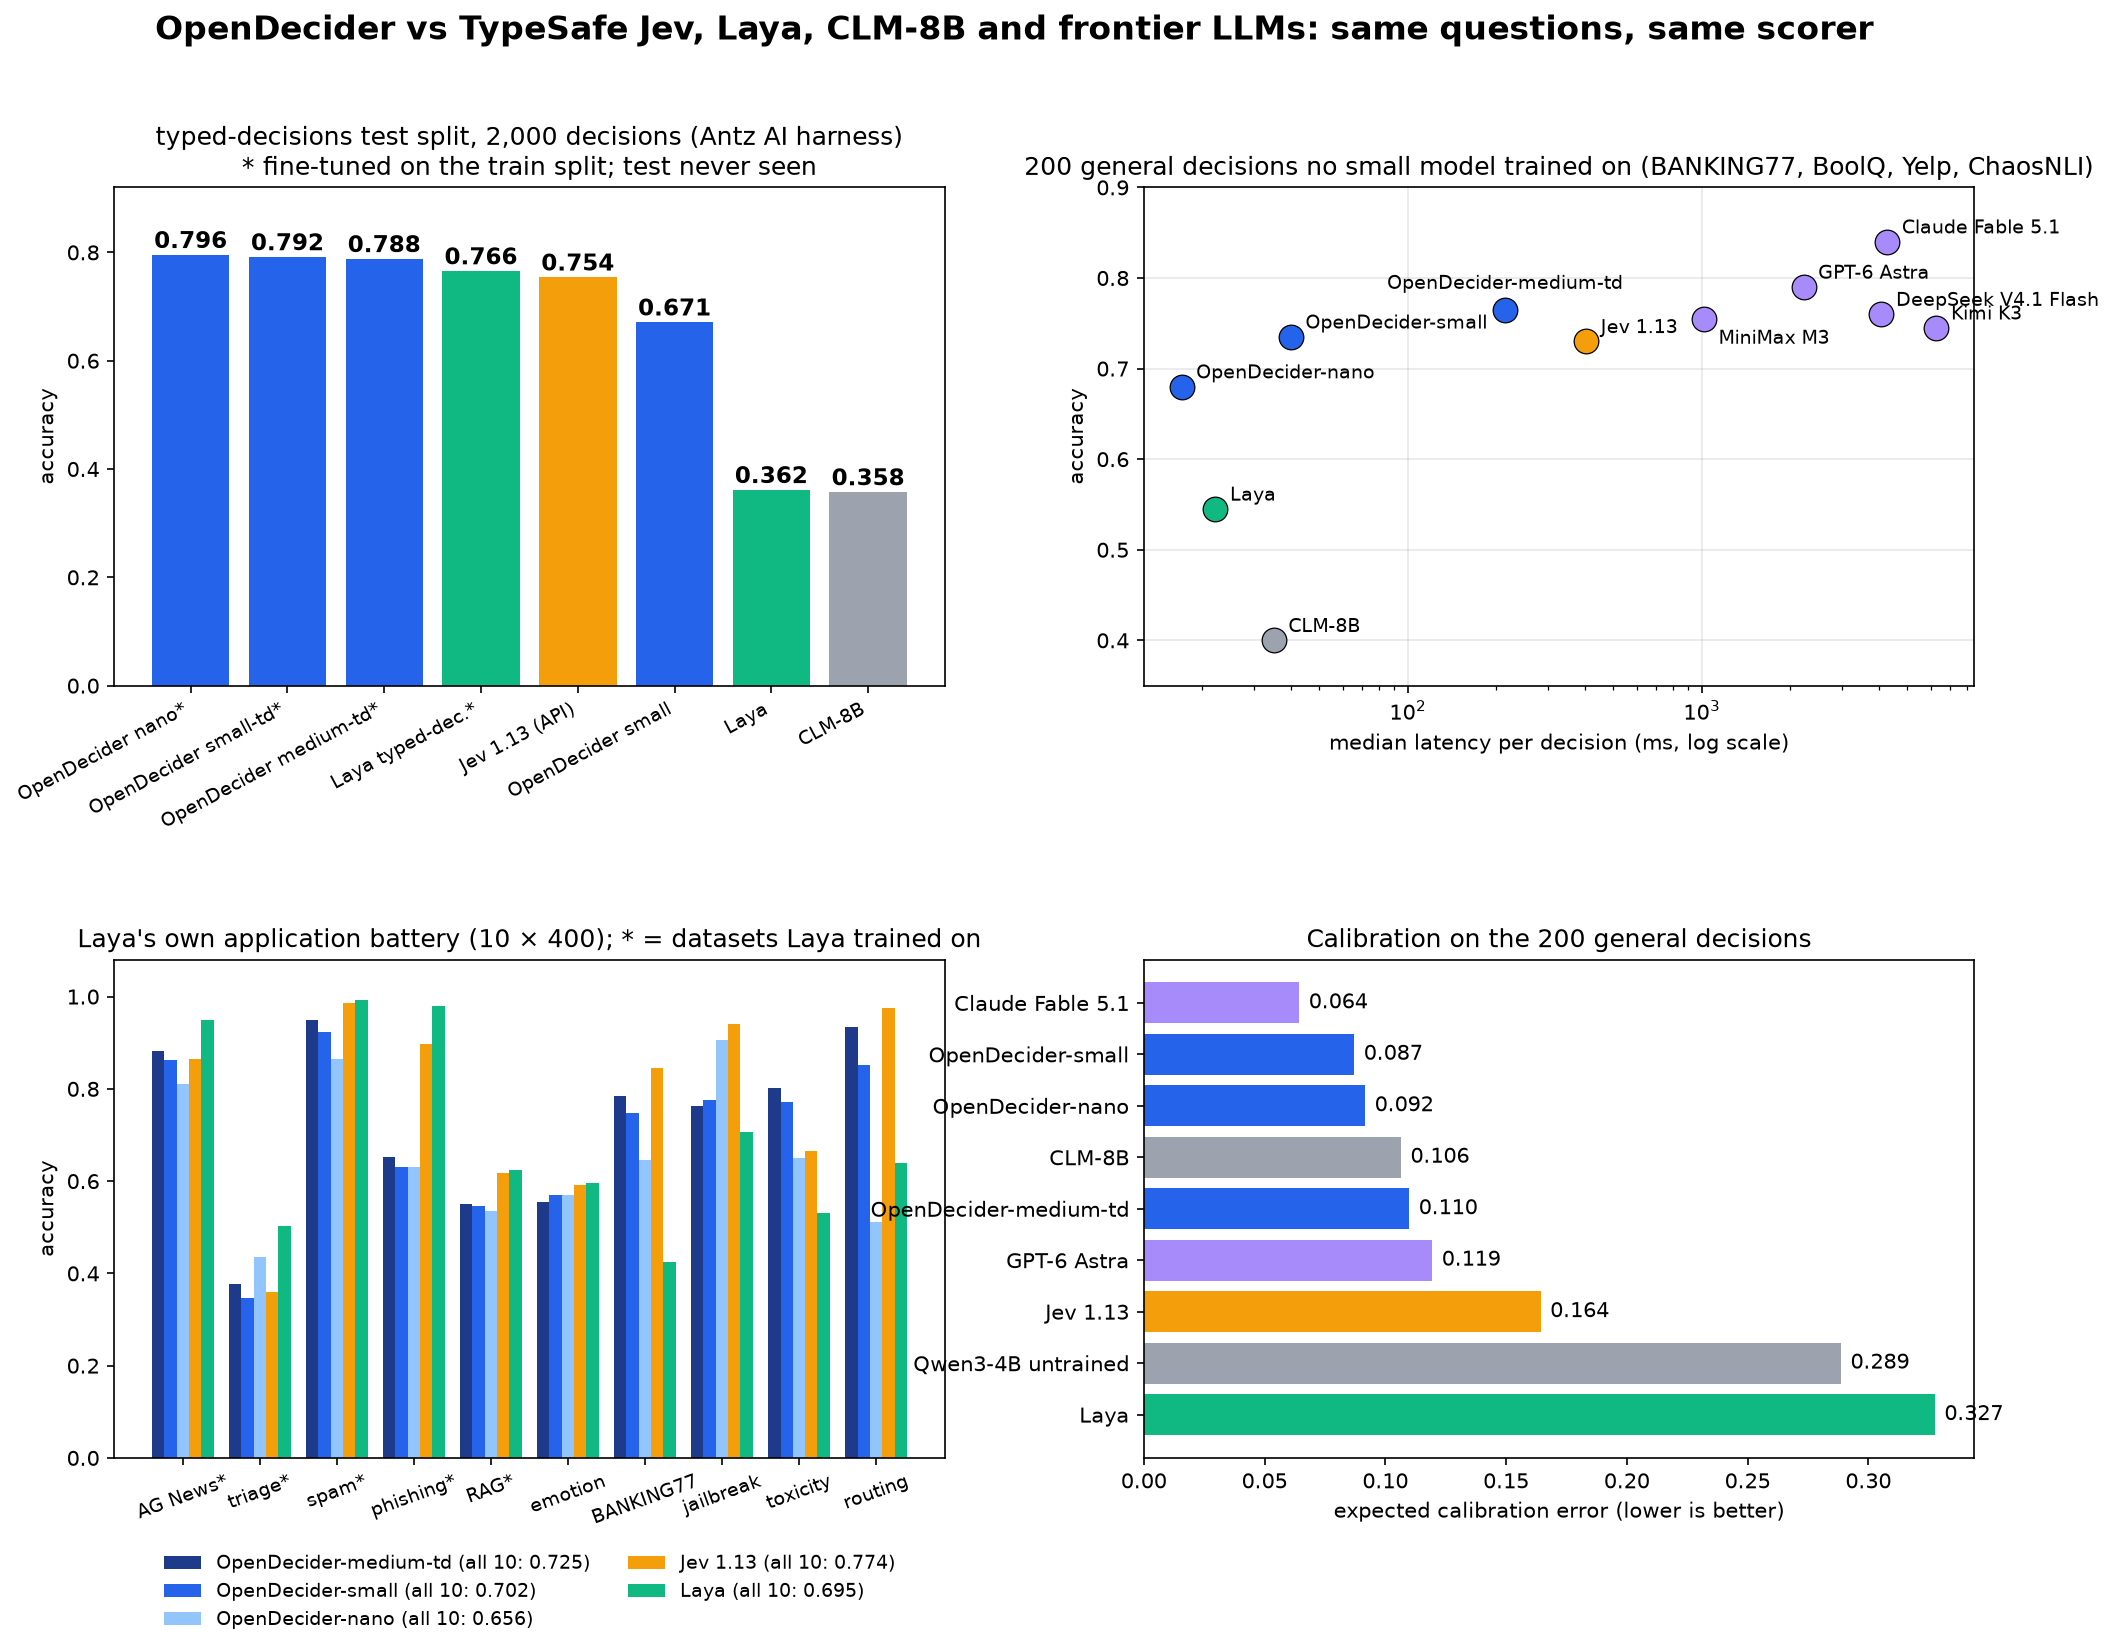
Every model answered the same questions and was scored by the same code. TypeSafe Jev was measured directly through TypeSafe's own API, not taken from published figures. Full tables, per-task results and methodology: COMPARISON.md.
Reproduce every number: python benchmarks/report.py rebuilds all the tables from the committed results, and
python benchmarks/run.py --model <name> re-scores any model. See benchmarks/.
Speed
| questions per call | nano, NVIDIA L40S | nano, Apple M4 Max | small, NVIDIA L40S | small, Apple M4 Max |
|---|---|---|---|---|
| 1 | 16.1 ms | 18.1 ms | 37.6 ms | 141 ms |
| 5 | 24.4 ms (4.9 ms/q) | 54.3 ms (10.9 ms/q) | 190.1 ms (38.0 ms/q) | 680 ms (136 ms/q) |
| 10 | 42.9 ms (4.3 ms/q) | 98.1 ms (9.8 ms/q) | 388.2 ms (38.8 ms/q) | 1.37 s (137 ms/q) |
| 50 | 189.5 ms (3.8 ms/q) | 467 ms (9.3 ms/q) | 1.94 s (38.7 ms/q) | 6.86 s (137 ms/q) |
On a 16 GB Mac mini (M4): nano 28 ms and small 280 ms per question, using 2.0 GiB and 8.9 GiB of the 11.8 GiB GPU budget, with answers identical to the 64 GB Mac to four decimals.
opendecider-medium-td answers in 214 ms and opendecider-large-td in 440 ms (median, one question) spread across 4× NVIDIA L40S. For reference, TypeSafe Jev answered at a 404 ms median per question through its API in our runs.
OpenDecider vs TypeSafe Jev (measured through TypeSafe's API)
| Benchmark / metric | TypeSafe Jev 1.13 | opendecider-nano | opendecider-small | opendecider-medium-td | opendecider-large-td |
|---|---|---|---|---|---|
| typed-decisions, 2,000 decisions (Jev zero-shot; nano, medium-td and large-td fine-tuned on its train split) | 0.754 | 0.796 | 0.672 (zero-shot) | 0.788 | 0.801 |
| 200 general decisions (BANKING77, BoolQ, Yelp, ChaosNLI) | 0.730 | 0.680 | 0.735 | 0.765 | 0.750 |
| Laya's application battery, 10 tasks | 0.774 | 0.656 | 0.702 | 0.725 | 0.718 |
| Calibration error (ECE), general decisions | 0.164 | 0.092 | 0.087 | 0.110 | 0.083 |
| Distance from the human label spread (ChaosNLI JSD) | 0.148 | 0.045 | 0.040 | 0.035 | 0.030 |
| Median latency, 1 question | 404 ms (API) | 17 ms (L40S) | 40 ms (L40S) | 214 ms (4× L40S) | 440 ms (4× L40S) |
| Weights | closed API | Apache-2.0 | Apache-2.0 | Apache-2.0 | Apache-2.0 |
| Cost | $0.025 per 1,000 decisions | self-hosted | self-hosted | self-hosted | self-hosted |
Where Jev leads
- Laya's application battery: Jev 0.774 vs 0.725 (medium-td), 0.718 (large-td), 0.702 (small) and 0.656 (nano); 0.803 on the five tasks Laya was not trained on. Jev is strongest on phishing (0.897, vs our 0.63–0.70), jailbreak detection (0.940 vs 0.76 for medium-td), spam (0.985), model routing (0.975) and 77-label BANKING77 (0.845).
- BoolQ-style yes/no reading questions (0.94, vs 0.74 nano and 0.90 small; medium-td ties at 0.94) and BANKING77 routing with 78 options on our bench (0.76, vs 0.68 nano, 0.70 small and 0.72 medium-td).
- typed-decisions without fine-tuning: Jev 0.754 vs opendecider-small 0.672. The fine-tuned nano (0.796) passes it.
Where OpenDecider leads Jev: general decisions (medium-td 0.765 and small 0.735 vs 0.730), calibration (ECE 0.083–0.110 vs 0.164), agreement with human label spread (JSD 0.030–0.045 vs 0.148), confident-half accuracy on general decisions (large-td 0.870 vs 0.860), typed-decisions after fine-tuning on its train split (0.796 vs Jev zero-shot 0.754; not like for like), toxicity moderation on Laya's battery (medium-td 0.802 vs 0.665), latency (17–440 ms vs 404 ms), open weights and self-hosting.
OpenDecider vs Laya
| Benchmark | Laya | Laya typed-decisions | opendecider-nano | opendecider-small | opendecider-medium-td | opendecider-large-td |
|---|---|---|---|---|---|---|
| typed-decisions (Antz harness) | 0.362 | 0.766 | 0.796 | 0.672 | 0.788 | 0.801 |
| 200 general decisions | 0.545 | 0.570 | 0.680 | 0.735 | 0.765 | 0.750 |
| Laya's battery, all 10 tasks | 0.695 | 0.702 | 0.656 | 0.702 | 0.725 | 0.718 |
| Laya's battery, the 5 tasks Laya was not trained on | 0.579 | 0.609 | 0.656 | 0.743 | 0.768 | 0.757 |
| BANKING77, 77 labels (Laya's battery) | 0.425 | 0.492 | 0.645 | 0.748 | 0.785 | 0.677 |
| Calibration error (ECE), general decisions | 0.327 | 0.162 | 0.092 | 0.087 | 0.110 | 0.083 |
Where Laya leads
- The five datasets Laya was trained on: AG News 0.95, Enron spam 0.99, phishing 0.98, MS MARCO relevance 0.63, support triage 0.50. OpenDecider did not train on any of them.
- Multilingual: Laya has a 100+ language checkpoint and a router. OpenDecider is evaluated in English only.
- Single-question speed on short inputs: Laya is in the same range as nano (21–33 ms).
Frontier LLMs, CLM-8B and untrained baselines (same 200 general decisions)
| Model | accuracy | ECE | median latency | $ / 1,000 decisions |
|---|---|---|---|---|
| Claude Fable 5.1 | 0.840 | 0.064 | 4.27 s | $11.81 |
| GPT-6 Astra | 0.790 | 0.119 | 2.22 s | $6.96 |
| opendecider-medium-td | 0.765 | 0.110 | 214 ms (4× L40S) | self-hosted |
| DeepSeek V4.1 Flash | 0.760 | 0.138 | 4.08 s | $0.158 |
| MiniMax M3 | 0.755 | 0.112 | 1.02 s | $0.149 |
| opendecider-large-td | 0.750 | 0.083 | 440 ms (4× L40S) | self-hosted |
| Qwen3-Next-80B-A3B-Instruct, untrained (large's base) | 0.750 | 0.230 | local | – |
| Qwen3-30B-A3B-Instruct-2507, untrained (medium's base) | 0.745 | 0.233 | local | – |
| Kimi K3 | 0.745 | 0.119 | 6.28 s | $3.64 |
| opendecider-small | 0.735 | 0.087 | 40 ms | self-hosted |
| TypeSafe Jev 1.13 | 0.730 | 0.164 | 404 ms | $0.025 |
| Qwen3-4B-Instruct-2507, untrained (small's base) | 0.700 | 0.289 | local | – |
| opendecider-nano | 0.680 | 0.092 | 17 ms | self-hosted |
| CLM-8B (Contrastive-LM) | 0.400 | 0.106 | ~35 ms | self-hosted |
Only Claude Fable 5.1 and GPT-6 Astra beat opendecider-medium-td here, at 10–20× its latency and with a per-call bill; it edges past DeepSeek V4.1 Flash (0.760), one of its own teachers, within this set's ±3-point noise. Distillation moved Qwen3-4B from 0.700 to 0.735 (calibration error 0.289 to 0.087) and Qwen3-30B-A3B from 0.745 to 0.765 (0.233 to 0.110); it left Qwen3-Next-80B's accuracy at 0.750 but cut its calibration error from 0.230 to 0.083. CLM-8B, a contrastive reranker, is near chance on classification-style decisions (0.000 on label-only BANKING77); its strongest task is passage relevance (0.603 on MS MARCO, near Laya's 0.625, which trained on it).
Automating only the confident decisions
A common way to deploy a decision model is to let it act on its most confident cases and send the rest to a person. This is the accuracy on the most confident share of decisions:
| benchmark | model | all decisions | most confident 70% | most confident 50% |
|---|---|---|---|---|
| typed-decisions | opendecider-small-td | 0.792 | 0.893 | 0.949 |
| typed-decisions | opendecider-nano | 0.796 | 0.894 | 0.943 |
| typed-decisions | opendecider-medium-td | 0.788 | 0.896 | 0.948 |
| typed-decisions | opendecider-large-td | 0.801 | 0.901 | 0.947 |
| typed-decisions | TypeSafe Jev 1.13 | 0.754 | 0.839 | 0.882 |
| general (200) | opendecider-large-td | 0.750 | 0.807 | 0.870 |
| general (200) | TypeSafe Jev 1.13 | 0.730 | 0.829 | 0.860 |
| general (200) | opendecider-small | 0.735 | 0.800 | 0.830 |
| general (200) | opendecider-medium-td | 0.765 | 0.807 | 0.820 |
| general (200) | Laya | 0.545 | 0.543 | 0.550 |
On typed-decisions, automating the confident half gives 94–95% accuracy with OpenDecider against 88% with Jev. On the general decisions Jev ranks its confidence better than the 4B and 30B (0.86 vs 0.82–0.83 on the confident half), but opendecider-large-td passes it (0.87). Laya's confidence barely separates right from wrong answers here: its accuracy stays near 0.55 at every threshold, so check it on your own data before thresholding on it.
Honest limits
- Phishing detection is the weakest task: 0.63–0.65 on Laya's battery for every OpenDecider model, against Jev's 0.90 and Laya's 0.98 (Laya trained on that dataset).
- TypeSafe Jev leads Laya's application battery (0.774 vs 0.725 medium-td, 0.702 small, 0.656 nano).
- opendecider-medium-td needs about 61 GB and -large-td about 160 GB of GPU memory across NVIDIA GPUs; neither has a Mac build.
- opendecider-large-td is not more accurate than medium-td on unseen decisions (0.750 vs 0.765); it is better calibrated.
- opendecider-nano trails Laya on Laya's battery overall (0.656 vs 0.695), because half its tasks are Laya's training data.
- opendecider-small is zero-shot on typed-decisions and trails Jev there (0.672 vs 0.754).
- English only so far. The training data includes some Spanish, German, French, Portuguese, Italian and Dutch, but no multilingual evaluation has been run.
- opendecider-small, -medium-td and -large-td answer questions one at a time (small: ~137 ms per question on a Mac, ~40 ms on an L40S). Use nano when you need many decisions per second.
- More than 26 options: the Qwen-based models switch from reading lettered options to scoring each option name, which is weaker (BANKING77's 78 options still score 0.70 for small, but on long rule-based states it can fall close to chance). A shortlist-then-letters fix is planned for 0.3, measured on every benchmark before it ships.
- Descriptions help. Very terse or cryptic option labels are harder for every model, so give options a short description when you can.
Links
- Live demo: https://huggingface.co/spaces/manjunathshiva/opendecider-demo
- PyPI: https://pypi.org/project/opendecider/
- Models: opendecider-nano · opendecider-small · opendecider-small-td · opendecider-medium-td · opendecider-large-td · collection
- Full benchmark tables: COMPARISON.md
- Related: Jev vs frontier LLMs benchmark
License
Code and weights: Apache-2.0. Base models: Ettin-encoder-400m (MIT), Qwen3-4B-Instruct-2507, Qwen3-30B-A3B-Instruct-2507 and Qwen3-Next-80B-A3B-Instruct (Apache-2.0). Training-data attributions: NOTICE.
@software{janardhan2026opendecider,
  title  = {OpenDecider: open, calibrated System 1 decision models},
  author = {Manjunath Janardhan},
  year   = {2026},
  url    = {https://github.com/manjunathshiva/opendecider}
}
1 maintainer

Metadata
1 maintainer
Release files for opendecider 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| opendecider-0.2.0.tar.gz | 60.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| opendecider-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 98.5 kB
Release files / opendecider-0.2.0.tar.gz
| Download URL | opendecider-0.2.0.tar.gz |
|---|---|
| Size | 60.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b4921fe8a0ca2cb376cc24715c005db68d8b106edb4032749ae5b533e07da620
|
|
BLAKE2b-256 checksum How to use checksums |
aca9723a9bf35361c109826995fc936adedca320400502fbda53d24311781277
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logRelease files / opendecider-0.2.0-py3-none-any.whl
| Download URL | opendecider-0.2.0-py3-none-any.whl |
|---|---|
| Size | 37.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
969f4cce8b166432c78e152fc2749b57cff46ca017e483a9a42816492ac1d444
|
|
BLAKE2b-256 checksum How to use checksums |
bb288c530b5006285ca78658f9a4f984e6e31982f28cb4887582c3268e3798d6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency log













