
OpenOmicsBench
OpenOmicsBench is a compact benchmark collection and local sequence toolkit for bioinformatics software testing, method checks and teaching. Version 2 keeps the 12 certified bulk RNA-seq objects from version 1 and adds strict FASTA and FASTQ handling, DNA, RNA and protein support, paired-read checks, preprocessing, sequence QC and five deterministic sequence benchmarks.
Version 2.1 adds benchmark suites for continuous integration. A suite can validate many bundled objects in one run or compare a directory of differential-expression results across the RNA-seq collection. Reports can be written as JSON, Markdown and JUnit XML.
The package runs offline after installation. Sequence files stay on the local computer. The built-in tools cover inspection and lightweight preprocessing; they do not claim to replace aligners, variant callers, taxonomic classifiers or assay-specific statistical workflows.
Install
OpenOmicsBench requires Python 3.11 or newer.
python -m pip install openomicsbench
omicsbench --version
List and validate the bundled benchmarks:
omicsbench list
omicsbench validate rnaseq-002
omicsbench validate sequence-004
The wheel contains the complete collection. A repository checkout and network connection are not required.
Sequence tools
Run a strict combined QC report on FASTA, FASTQ or gzip-compressed input:
omicsbench seq qc reads.fastq.gz --molecule dna --adapter AGATCGGAAGAGC
Common operations include:
omicsbench seq stats reference.fasta.gz
omicsbench seq validate proteins.fasta --molecule protein
omicsbench seq pair-check sample_R1.fastq.gz sample_R2.fastq.gz
omicsbench seq trim reads.fastq.gz trimmed.fastq.gz --quality 20 --min-length 30
omicsbench seq filter trimmed.fastq.gz clean.fastq.gz --min-length 30 --max-ambiguity 0.05 --min-mean-quality 25
omicsbench seq sample clean.fastq.gz subset.fastq.gz --count 10000 --seed 7
omicsbench seq transform transcripts.fasta proteins.fasta --operation translate --frame 1
omicsbench seq protein-stats proteins.fasta --ph 7.4
omicsbench seq digest proteins.fasta --enzyme trypsin --missed-cleavages 1
omicsbench seq motif reference.fasta ACGTRG --both-strands
omicsbench seq kmers reads.fastq.gz --k 21 --canonical --top 50
omicsbench seq compare sample-a.fasta sample-b.fasta --k 21 --size 5000
The command suite supports:
- multiline FASTA and FASTQ, including
.gzinput and output; - DNA, RNA and protein alphabets with IUPAC ambiguity symbols;
- sequence length, N50/L50, composition, GC, ambiguity and exact duplication statistics;
- FASTQ Phred+33 range checks, Q20/Q30 summaries and per-position quality;
- paired-read identity checks, interleaving and deinterleaving;
- fixed, adapter and end-quality trimming;
- filtering by length, GC, ambiguity and mean quality;
- deterministic sampling and deduplication;
- reverse complements, transcription, back-transcription and six translation frames;
- overlapping IUPAC motif searches and six-frame ORF discovery;
- canonical k-mer counts and deterministic bottom-k similarity sketches;
- amino-acid composition, molecular weight, hydropathy, charge, estimated pI, aromaticity and extinction estimates;
- trypsin, Lys-C, Arg-C and chymotrypsin digestion with missed-cleavage and peptide-length controls;
- record extraction with zero-based, half-open slices.
Commands that write files refuse to replace an existing output unless --force is supplied. Outputs are written through a temporary file and moved into place only after the operation succeeds. JSON reports go to standard output so they can be stored or checked in automated workflows.
The FASTA validator follows the nucleotide symbol expectations described by NCBI. FASTQ has no single formal specification; OpenOmicsBench accepts conventional multiline records with printable Phred+33 quality characters and requires the sequence and quality lengths to match. The GA4GH-maintained HTS specifications describe the surrounding SAM, BAM, CRAM and VCF ecosystem.
The full command reference is in docs/sequence-tools.md.
Benchmark suites
Validate the complete installed collection and save reports that can be attached to a CI run:
omicsbench suite validate --json reports/validation.json --markdown reports/validation.md --junit reports/validation.xml
The selection can be narrowed by assay or by repeating --id:
omicsbench suite validate --assay bulk_rna_seq
omicsbench suite validate --id rnaseq-002 --id sequence-005
To test a differential-expression pipeline across several biological objects, place each result in a directory under its benchmark ID. CSV and TSV are accepted, with optional gzip compression:
results/
  rnaseq-002.tsv.gz
  rnaseq-003.csv
Then run:
omicsbench suite compare results --id rnaseq-002 --id rnaseq-003 --junit reports/comparison.xml
Omit --id to require results for all 12 comparable RNA-seq objects. A completed suite exits with status 0 when every check passes, status 2 when a benchmark fails or an expected result file is missing, and status 1 for invalid input. Existing report files are protected unless --force is supplied. The suite reference describes the file convention and report fields.
Assay profiles
The assay profiles explain what the local tools can check and where a dedicated workflow becomes necessary:
omicsbench assay list
omicsbench assay info whole-genome
omicsbench assay plan whole-genome sample_R1.fastq.gz sample_R2.fastq.gz --adapter AGATCGGAAGAGC
Profiles are available for whole-genome, exome, targeted-panel, bulk RNA-seq, single-cell RNA-seq, ATAC-seq, ChIP-seq and related assays, amplicon sequencing, shotgun metagenomics, long-read DNA and RNA, genome or transcriptome references, RNA FASTA and protein FASTA. A plan contains executable validation and preprocessing commands plus a clear boundary for the downstream tools that still need a reference, database or assay-specific model.
Bundled sequence benchmarks
| ID | Content | Format | Records |
|---|---|---|---|
sequence-001 |
DNA with IUPAC ambiguity and an exact duplicate | FASTA | 4 |
sequence-002 |
coding, ambiguous and short RNA records | FASTA | 3 |
sequence-003 |
standard, ambiguous and terminating protein records | FASTA | 3 |
sequence-004 |
paired DNA reads with mixed qualities and duplication | FASTQ | 4 pairs |
sequence-005 |
paired DNA-seq reads, reference and three known SNVs | FASTQ | 20 pairs |
These five objects are project-authored synthetic fixtures. Each has an exact file inventory, checksums, format and molecule declarations, expected summary metrics and a deterministic rebuild workflow. sequence-005 also verifies that every truth-set reference allele matches the bundled reference and that every alternate allele is supported by the paired reads. The objects test software behavior and do not represent a biological cohort or sequencing instrument.
Bulk RNA-seq benchmarks
Version 2 retains the complete version 1 biological collection unchanged.
| ID | Design | Samples | Pocket genes |
|---|---|---|---|
rnaseq-002 |
SLC2A5 knockout in A549 xenografts | 10 | 2,000 |
rnaseq-003 |
AtRsgA knockout in Arabidopsis seedlings | 6 | 4,000 |
rnaseq-004 |
Klf1 knockout in mouse erythroid tissue | 6 | 4,000 |
rnaseq-005 |
Paired prostate tumour and adjacent tissue | 28 | 8,000 |
rnaseq-006 |
Arabidopsis infection adjusted for genotype | 12 | 500 |
rnaseq-007 |
ELP3 depletion in BT549 cells | 6 | 8,000 |
rnaseq-008 |
Duchenne muscular dystrophy myoblasts | 9 | 8,000 |
rnaseq-009 |
Arabidopsis genotype adjusted for infection | 12 | 500 |
rnaseq-010 |
Infection response in wild-type Arabidopsis | 6 | 500 |
rnaseq-011 |
Infection response in gsnor1 Arabidopsis | 6 | 500 |
rnaseq-012 |
Dmd-mdx myoblasts against wild type | 6 | 8,000 |
rnaseq-013 |
Dmd-mdx-beta-geo myoblasts against wild type | 6 | 8,000 |
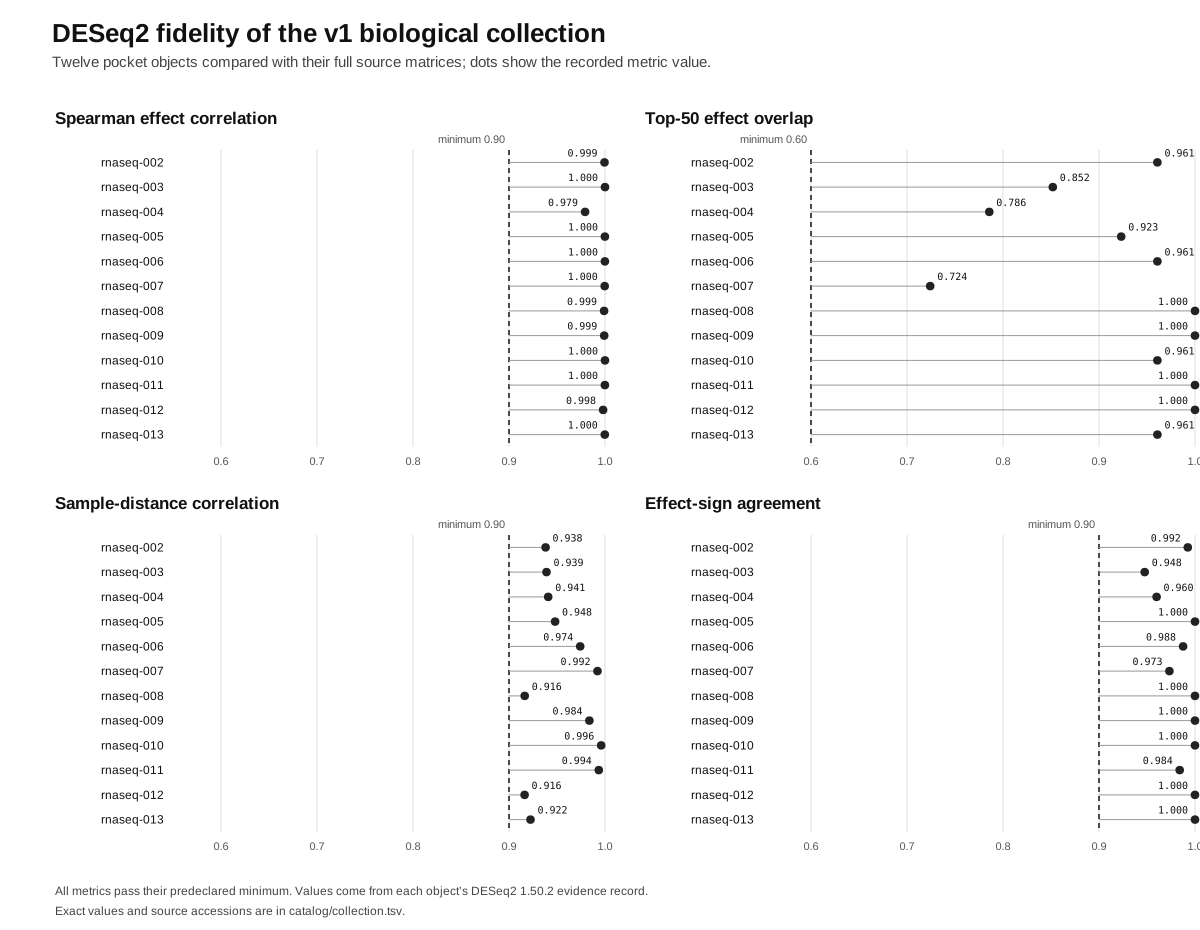
Each biological object includes the source counts for its selected samples, a smaller pocket matrix, ordered sample metadata, the declared design, source attribution, rights evidence, reference details, transformations and quantitative validation. All 12 pockets pass their predeclared DESeq2 fidelity thresholds.
Compare another tool's gene-level effects with a bundled full-source DESeq2 reference:
omicsbench compare rnaseq-002 results.csv
The input must contain unique gene_id and finite log2_fold_change columns. The report includes rank correlation, top-50 overlap, sign agreement, coverage and identifier differences. Status 0 means the declared checks passed, status 2 means a completed comparison missed a scientific threshold and status 1 means the input was invalid.
Collection records
The JSON catalog contains both benchmark families. catalog/collection.tsv lists the biological objects and catalog/sequences.tsv lists the sequence fixtures.
Expression Atlas and BioStudies supplied the biological count matrices. Their bundled material is recorded as CC BY 4.0 with provider attribution. The sequence fixtures and software are project-authored and distributed under Apache-2.0. Project-written descriptive metadata is CC BY 4.0.
The objects are research and software-test material. They are not clinical references and do not replace the complete source studies.
Development checks
python -m unittest discover -s tests -v
python workflows/build_sequence_fixtures.py
python scripts/build_catalog.py
python scripts/audit_collection.py
python scripts/check_repository.py
python scripts/certify_release.py --preflight
The repository checker validates every manifest, file inventory, byte count, SHA-256 digest and expected result. It also rejects undeclared files, schema drift, unsupported metadata and prohibited attribution traces.
Citation
Zenodo releases list Vivaan Patni as the author. GitHub development and commits use the account vxxqv. Cite the exact archived release used in an analysis. The concept DOI 10.5281/zenodo.22551734 resolves to the latest archived version.
1 maintainer

Metadata
1 maintainer
Release files for openomicsbench 2.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| openomicsbench-2.1.0.tar.gz | 10.7 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| openomicsbench-2.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 21.5 MB
Release files / openomicsbench-2.1.0.tar.gz
| Download URL | openomicsbench-2.1.0.tar.gz |
|---|---|
| Size | 10.7 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0071caea45b7461deca40f0657ab8c833f07958b8562a1bcef678e0bc2217f1a
|
|
BLAKE2b-256 checksum How to use checksums |
a717cc4d8cf768d8d78d3cbceeb62a6de7ebd83bb98913a204d4fda1877f4ee6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency logRelease files / openomicsbench-2.1.0-py3-none-any.whl
| Download URL | openomicsbench-2.1.0-py3-none-any.whl |
|---|---|
| Size | 10.8 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0d5267a5876e805f0439c74eada5674492b38f6b52f7cd1ef37d65faeadcd875
|
|
BLAKE2b-256 checksum How to use checksums |
31d24a4f103643486178ff42598f7263f07a10f3510f53b45ba455cb1f9ea3eb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 26, 2026.
Transparency log













