

ovkit
Ask a question. Get an answer. One line.
20 AI capabilities over 68 ready models — on your CPU, GPU or NPU, offline,
Apache-2.0. No AGPL, no API key, no pip install torch.


Docs · 한국어 문서 · Capabilities · Model catalog · Examples
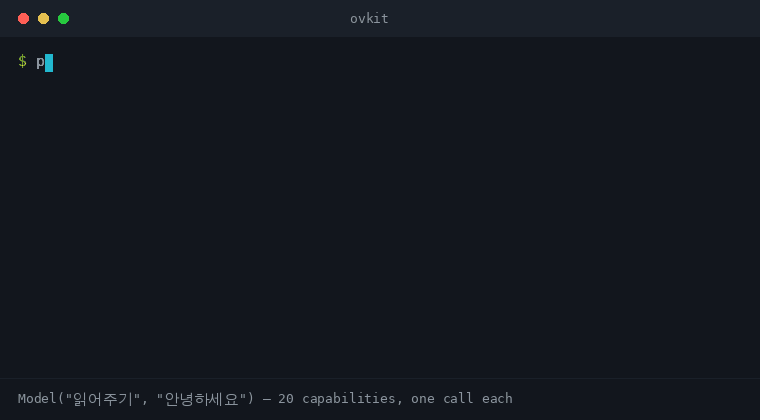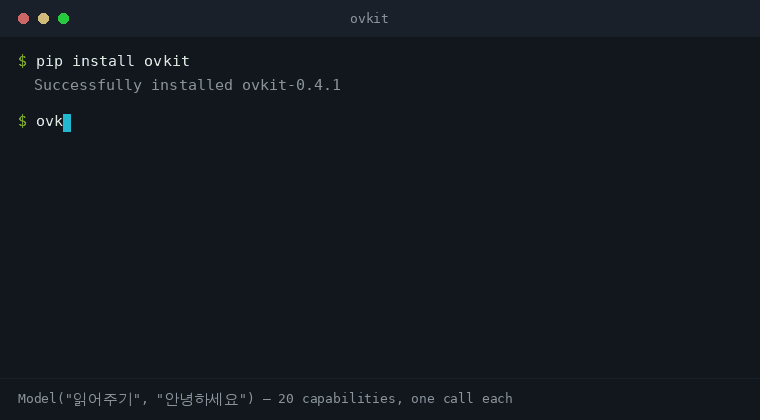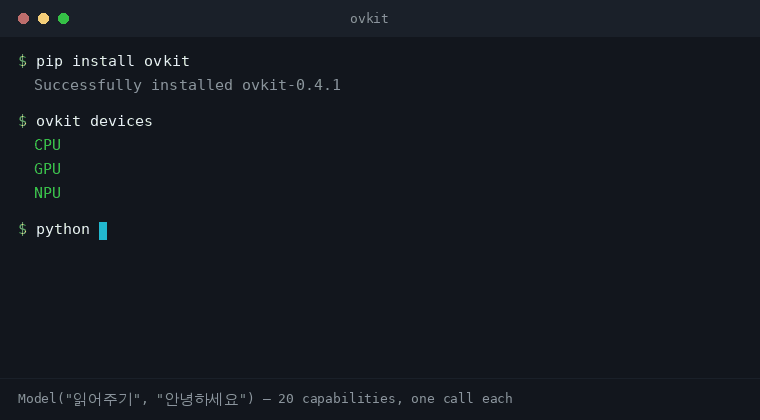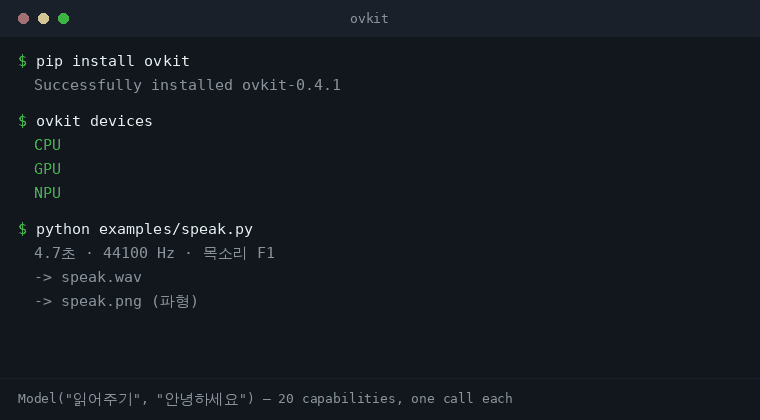
pip install ovkit
from ovkit import Model

print(Model("scene", "street.jpg"))
# 2 people (1 happy) · a laptop and a cup · floor 47%
That is the whole API. No config, no builder, no session. The model downloads itself, converts itself to OpenVINO IR, caches itself, and answers.
Model("face_analyze", "group.jpg")   # 2 faces: age 31 · male 98% · happy 92%, ...
Model("read_text",   "sign.jpg")     # 'STOP AHEAD' — every word, in reading order
Model("읽어주기",     "안녕하세요")    # text → a 44.1 kHz voice, 31 languages
Model("depth",       "room.jpg")     # nearest: bottom-left · 34% of the frame is close
Each of those chains several networks — detector, cropper, classifier, decoder — into one answer in one call. You never crop, stitch or post-process by hand.
Why people use it
Sentences, not tensors. print(r) says 2 faces: age 31 · male 98% · happy 92%. Every result also carries r.boxes, r.masks, r.keypoints, r.text,
r.to_json() when you want the numbers.
No AGPL anywhere. Detection, tracking, pose, segmentation — the whole lineup is Apache-2.0 or MIT, models and code. Including a trainable RT-DETR, so you can fine-tune a detector and ship the result commercially without a licence conversation.
It runs on the NPU. device="NPU" on an Intel® Core™ Ultra, "GPU" on Arc,
AUTO by default. Every result tells you where it actually ran and how long it
took: 2x person 14.2ms GPU.
Offline by design. One mirror
(leeyunjai/ovkit-models) holds
every model. Warm the cache once, hand it to a lab of machines, set
OVKIT_OFFLINE=1, and nothing touches the network again.
It speaks Korean. Model("얼굴분석", "사진.jpg") is the same call as
Model("face_analyze", ...), and results answer in Korean too — 47 capability
names and ~200 class names. Built for classrooms where English is the second
obstacle after the code.
60 seconds
from ovkit import Model

# a picture
r = Model("detect", "street.jpg")
print(r)                    # 2x person, car
r.save("out.jpg")           # boxes drawn on the photo

# a webcam — same call, now a stream
for r in Model("track", 0):
    print(r, r.elapsed_ms, r.device)   # 2x person (#1, #4) 14.2 GPU
    if not r.show("track"):            # q or Esc ends the loop
        break

# a sentence
Model("읽어주기", "오늘은 기계 학습을 배웁니다").save("수업.wav")
A photo answers with one Results. A folder answers with a list. A webcam
index, a video or "mic" answers with a lazy stream. You never index into a
list you did not ask for.
Or skip Python entirely:
ovkit gui                         # a window: pick a capability, point it at your webcam
ovkit run detect image.jpg        # prints results, saves image_out.jpg
ovkit capabilities                # what Model(name) can answer
ovkit devices                     # CPU / GPU / NPU
한국어
영어가 코드보다 먼저 걸림돌이 되는 교실을 위해 만들었습니다. 기능 이름도 결과도 한국어로 나옵니다.
from ovkit import Model

print(Model("얼굴분석", "단체사진.jpg"))   # 얼굴 2개: 31세 · 남성 98% · 행복 92% ...
print(Model("장면설명", "교실.jpg"))       # 사람 2명 (1명 웃는 중) · 노트북과 컵 ...
Model("읽어주기", "안녕하세요").save("인사.wav")
능력 이름 47개(물체찾기 글자읽기 따라가기 출석체크 가르치기 …)와 클래스
이름 200여 개가 번역돼 있습니다. OVKIT_LANG=en으로 영어로 바꿀 수 있고,
r.found는 한국어 이름과 영어 키를 둘 다 주므로 코드가 비교하는 값은
언어와 무관합니다.
Install
pip install ovkit
Extras: ovkit[quant] (INT8/NNCF) · ovkit[genai] (LLM/STT) · ovkit[all].
Python 3.10+. For development, install from source:
git clone https://github.com/leeyunjai82/ovkit.git && cd ovkit
python -m venv .venv && source .venv/bin/activate   # Windows: .venv\Scripts\activate
pip install -e ".[dev]"

python scripts/check.py --fix    # what CI runs: ruff, black, pytest
Capabilities
A capability name gives you the answer, not the plumbing. Each one chains a
detector with the models that describe what it found — same Model(...) call,
same Results, and it takes the same sources (path, ndarray, folder, video,
camera index).
Model(...) |
Answers | Chains |
|---|---|---|
scene |
2 people (1 happy) · a laptop and a cup · floor 47% |
detection + segmentation + faces |
face_analyze |
2 faces: age 31 · male 98% · happy 92%, ... |
face detection + age/gender + emotion (+ head pose, landmarks) |
person_analyze |
3 people: male 0.98 · long pants 0.95 · bag 0.71, ... |
person detection + attributes |
vehicle_analyze |
2 vehicles: type: car (0.98) · color: black (0.83), ... |
vehicle detection + type/colour |
read_text |
'STOP AHEAD' / '여기서 기다리세요' — every word, in reading order |
text detection + the recogniser that matches the language |
read_plate |
2 vehicles: black car — 12GA3456, ... |
plate detection + text recognition + vehicle attributes |
speak |
text in a human voice, 31 languages — r.save("hello.wav") |
duration + text encoder + flow matching + vocoder |
track |
2x person (#1, #4) — ids stable across frames |
detection + IoU association |
drowsiness |
EYES CLOSED 1.4s — drowsy |
face + landmarks + eye state + head pose, over time |
gesture |
thumb up 0.94 |
sign-language model over a rolling 8-frame clip |
gaze |
1 face: looking right and slightly up |
face detection + landmarks + head pose + gaze |
attention |
1 person looking at: laptop |
gaze + object detection (ray-cast into the boxes) |
anonymize |
the picture with every face pixelated | face (and plate) detection + redaction |
face_match |
('yunjai', 0.81) — who this is |
embedding + cosine matching against your gallery |
count |
pencil 3 · cup 1 (optionally one kind only) |
detection + per-kind tally |
posture |
neck 32° — sit up (6s) |
pose + neck angle over time |
exercise |
squat x 12 (down) |
pose + joint-angle hysteresis (squat, push-up) |
attendance |
present 24/26 + roll.csv |
face detection + roster matching |
teach |
your own classes, from example photos | embedding + cosine k-NN (5 modes) |
depth |
nearest: bottom-left · 34% of the frame is close + a colour map |
Depth Anything V2 Small |
remove_background |
the subject, saved as a transparent PNG | U2-Net |
from ovkit import Model, list_pipelines

list_pipelines()                                    # every capability, described
Model("read_text")("sign.jpg")[0].text              # 'STOP AHEAD'
Model("track")(0)                                   # webcam, ids kept across frames
Model("face_analyze", attributes=("age_gender",))   # configure what runs
Aliases: ocr, anpr, blur, driver, describe, faces, people, vehicle, tracking, reid, tts, say.
Text to speech, in one line
Model("읽어주기", "안녕하세요. 오늘은 기계 학습을 배웁니다.").save("인사.wav")
Model("speak", "Good morning, everyone.", voice="M3").save("hello.wav")
31 languages, Korean and English among them, 44.1 kHz, ten voices
(F1–F5, M1–M5). Under a second per sentence on a laptop CPU. No API
key, no network after the first download — it is four small ONNX graphs
(99M parameters total) converted to OpenVINO IR like everything else.
Model("speak", "안녕하세요", speed=1.3)   # faster
Model("speak", "안녕하세요", steps=2)     # rougher and quicker (8 by default)
Model("speak", "script.txt")             # a file works too
r.save("wave.png")                       # the waveform is just a picture
The language comes from the script you typed unless you name one (lang="en").
The same sentence sounds the same twice; pass seed=None when you want
variation.
Model: Supertonic 3, OpenRAIL-M © Supertone Inc. — commercial use and redistribution are allowed, and the same use restrictions travel with every copy.
Teach your own AI (no GPU)
A Teachable Machine in five lines — an embedding model turns examples into
vectors, new inputs match the nearest ones. Five modes: photo (default),
face (expressions), hand (needs ovkit[hand]), upper, body:
ai = Model("teach")                       # or Model("가르치기")
ai.learn("can", "photos/cans/")           # a folder per thing to recognise
ai.learn("bottle", "photos/bottles/")
print(ai.guess("new_photo.jpg"))          # ('can', 0.93)
print(ai.score("test_photos/"))           # accuracy + what it confuses
ai.save("recycling")                      # -> Documents/ovkit/recycling.json
for r in ai.predict(0, stream=True): ...  # webcam over YOUR classes
Korean method names work too: 배우기, 맞혀봐, 점수, 저장. Collect
examples with the webcam: from ovkit.pipelines.teach import collect; collect("가위", 30).
Any model on the Hugging Face Hub
The Open Model Zoo is an archive; the models people want are on the Hub.
optimum-intel converts almost any of them to OpenVINO IR, so ovkit does not
have to mirror a model to serve it:
pip install "ovkit[hf]"                      # the converter — needed once
ovkit pull google/vit-base-patch16-224
Model("google/vit-base-patch16-224", "photo.jpg") # tabby 0.94
Converting is the heavy half and happens once; what lands in the cache is a plain OpenVINO model, so running it afterwards needs nothing but ovkit — a classroom machine can be handed the cache and never see PyTorch. The pull also writes the model's own class names and the normalisation its image processor declares, so results read as answers and not as confident nonsense.
Tasks: image classification, zero-shot (CLIP) classification, feature
extraction. Detection and segmentation come from the registry instead
(detect, segment) — optimum-intel does not export those.
Train your own detector
RT-DETR, trainable, Apache-2.0 end to end — an Ultralytics-style workflow with
no AGPL code or weights anywhere (pip install "ovkit[train]"):
from ovkit import RTDETR

model = RTDETR("rtdetr-r18")                 # COCO weights, downloaded on first use
model.train(data="data.yaml", epochs=100)    # the YOLO-format labels you already have
model.val(data="data.yaml").box.map50        # mAP50 / mAP50-95
model.export(half=True)                      # -> IR + labels.txt
The three sizes are rtdetr_r18 (20M, 46.4 COCO AP — what detect uses),
rtdetr_r34 (31M, 48.9) and rtdetr_r50 (43M, 53.1), mirrored like every
other model. Running them needs nothing but ovkit; ovkit[train] adds PyTorch
for fine-tuning:
Model("detect", "street.jpg")      # r18 — keeps up with a webcam
Model("rtdetr_r50", "street.jpg")  # when you want the accuracy instead
A fine-tuned model's exported IR drops straight into Model("path/to/best.xml") — the
labels.txt written next to it means your classes answer by name. CLI:
ovkit train --data data.yaml, ovkit val, ovkit export.
Supported tasks
Every single-model task below runs end-to-end through the same 3 lines — swap the alias:
| Task | Alias | Output | Example |
|---|---|---|---|
| Object detection | detect, face_detection, person_detection, vehicle_detection, text_detection, license_plate |
r.boxes |
detect.py |
| Classification | classify, person_attributes, vehicle_attributes |
r.probs / text |
classify.py |
| Segmentation | segment, instance_segmentation |
r.masks |
segment.py |
| Pose / landmarks | pose, face_landmarks |
r.keypoints |
pose.py |
| Face analysis | age_gender, emotion, head_pose, face_reid |
r.text (e.g. "age 31 · male 98%") |
face_analysis.py |
| OCR | text_recognition |
r.text |
ocr.py |
| Tracking / matching | track, face_match |
r.track_ids · (label, score) |
track.py / face_match.py |
| Super-resolution | super_resolution |
upscaled image via r.plot() |
super_resolution.py |
| LLM / STT (GenAI) | llm, stt |
generated text | llm.py / stt.py |
| NLP / audio / time series | qa, translation, noise_suppression, time_series |
tensors via model.infer() |
denoise_audio.py |
The registry exposes one well-tested model per capability (55 OpenVINO IR + 13 GenAI); the
HF mirror hosts the full
Apache-2.0 OMZ set (other tiers, int8, sparse variants) — surfacing a
variant is a one-line edit (catalog).
ovkit list shows everything with descriptions.
Devices
| Device | How | Notes |
|---|---|---|
| AUTO (default) | Model("detect") |
OpenVINO picks the best device |
| CPU | Model("detect", device="CPU") |
works everywhere |
| GPU | device="GPU" |
Intel iGPU / Arc |
| NPU | device="NPU" |
Intel® Core™ Ultra AI accelerator |
Single images run synchronously; stream=True uses an AsyncInferQueue for
video/webcam throughput. INT8: model.quantize(calib_images) (NNCF).
Benchmarks
python scripts/benchmark.py # prints a paste-ready CPU/GPU/NPU table
| model | CPU | GPU | NPU |
|---|---|---|---|
rtdetr_r50 |
429.4 ms (2 FPS) | 36.9 ms (27 FPS) | —* |
face_detection_0205 |
11.7 ms (85 FPS) | 4.5 ms (224 FPS) | —* |
person_detection_0202 |
13.4 ms (75 FPS) | 4.7 ms (211 FPS) | 6.6 ms (151 FPS) |
resnet50_binary_0001 |
7.9 ms (126 FPS) | 5.1 ms (195 FPS) | —* |
road_segmentation_adas_0001 |
28.6 ms (35 FPS) | 13.0 ms (77 FPS) | 23.8 ms (42 FPS) |
human_pose_estimation_0007 |
82.2 ms (12 FPS) | 14.0 ms (71 FPS) | 22.7 ms (44 FPS) |
age_gender_recognition_retail_0013 |
0.5 ms (1867 FPS) | 0.5 ms (2098 FPS) | 0.6 ms (1569 FPS) |
Measured on an Intel® Core™ Ultra (Lunar Lake) laptop — CPU / integrated GPU /
NPU, median of 30 runs, 1280x720 input, OpenVINO 2026.3.
— = model not supported by the NPU compiler (dynamic shapes or unsupported ops).
Usage
Python
from ovkit import Model

model = Model("face_detection")              # alias, name, .xml, or .onnx
results = model("photo.jpg", conf=0.25)      # image / ndarray / folder / video
for r in model.predict(0, stream=True):      # webcam (lazy generator)
    annotated = r.plot()

print(Model("age_gender")("face.jpg")[0].text)   # "age 31 · male 98%"
Inputs are auto-detected: image path / ndarray / folder / video / camera
index → vision pipeline; .npy / .wav → raw inference. Grayscale models and
all-image multi-input models (super-resolution) are handled automatically. Full
control for any model: model.infer({name: tensor}) with model.inputs.
Results |
holds |
|---|---|
r.boxes |
xyxy, xywh, conf, cls |
r.masks / r.keypoints / r.probs |
masks · [x,y,conf] · top1/top5 |
r.text |
decoded text (OCR, face attributes) |
r.labels / r.track_ids |
per-box label a pipeline wrote · per-box track id |
r.tensors |
raw {name: ndarray} |
r.summary() |
the whole result as one readable line |
r.crop(i) / r.to_dict() / r.to_json() |
cut a box out · plain Python · JSON |
r.plot() / r.save(path) |
annotated image (or the model's output image) |
CLI
ovkit run detect image.jpg --save out.jpg   # one-shot inference
ovkit run age_gender face.jpg --device NPU
ovkit list                                  # aliases + models with descriptions
ovkit info face_detection                   # source / task / license
ovkit download detect                       # warm the cache
ovkit devices                               # available OpenVINO devices
GenAI (LLM / speech-to-text)
from ovkit.genai import pipeline

llm = pipeline("llm")                        # qwen25_1_5b_instruct from the mirror
print(llm.generate("Explain OpenVINO in one sentence.", max_new_tokens=64))

stt = pipeline("stt")                        # whisper_base
print(stt.generate(audio_16k_mono_float32))
Needs pip install "ovkit[genai]".
Web demo (image / webcam / audio / text)
pip install -r examples/requirements.txt
python examples/web_app.py                   # http://127.0.0.1:8000
Pick any model — the right input (upload / webcam / audio / text) appears automatically and results render with overlays.
The model mirror
Everything ovkit downloads comes from one repository, leeyunjai/ovkit-models — one copy for an offline site to take, one repository to keep alive. Models that originate elsewhere (the RT-DETR sizes, Depth Anything V2 Small, U2-Net) are copied in, and their home stays registered as the fallback.
To refresh it after adding a model, run the Sync the model mirror workflow
from the Actions tab (dry run by default; tick upload to copy). It needs an
HF_TOKEN repository secret with write access, set once. The same thing runs
locally:
export HF_TOKEN=hf_...
python scripts/sync_mirror.py            # what is missing
python scripts/sync_mirror.py --upload   # copy just that
It lists the target first and copies only what is absent, so re-running is safe.
The traffic goes the other way too. A mirror only ever added to fills up with models that left the lineup and weights uploaded under an old path — and it is the thing a school clones whole:
python scripts/audit_mirror.py           # what no manifest references
python scripts/audit_mirror.py --prune   # delete just that
A model's README.md, LICENSE and labels.txt stay as long as the model
does, and go with it when it leaves. Deletions are ordinary Hub commits, so
the history still has them.
Adding a model
Models are data, not code — one manifest entry
(src/ovkit/manifests/):
my_model:
  src: hf
  repo: leeyunjai/ovkit-models
  filename: detect/my_model/model.xml
  task: detect
  description: Shown by `ovkit list`.
  license: apache-2.0            # must be permissive — enforced at load time
Resolution: alias → local path → cache (~/.cache/ovkit) → download → convert
→ cache, with atomic writes, sha256 checks, upstream fallback, and
OVKIT_OFFLINE=1. Maintainer tooling (mirror build / verify / self-check /
benchmark) lives in scripts/ — see the
guide.
License
ovkit is Apache-2.0, and the licence of every model is checked before it loads — a manifest entry with no licence, or the wrong one, raises instead of downloading.
- Permissive (Apache-2.0 / MIT / BSD / ISC / MPL-2.0 / CC0) — loads.
- OpenRAIL-M — loads only when the entry can point at its licence, because
that licence requires every copy to pass on the same use-based restrictions.
One model uses this today: the
speakvoice. ItsLICENSEis mirrored beside the weights. - AGPL, CC-BY-NC, and anything unlabelled — refused. No exceptions, however good the model is.
That is why there is no YOLO in this repository and an Apache-2.0 RT-DETR instead: a school or a product should not need a licence conversation to run object detection.
Contributing
Adding a model is a one-line YAML edit; adding a capability is one class. The
tests never touch the network and python scripts/check.py runs exactly what CI
runs — see CONTRIBUTING.md.
Something answering "nothing found" on a picture that plainly contains the thing is the bug report this project most wants: that class of failure once hid ten broken capabilities behind a plausible answer.
Open an issue · Docs · 한국어 문서
1 maintainer

Metadata
1 maintainer
Release files for ovkit 0.4.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| ovkit-0.4.1.tar.gz | 152.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| ovkit-0.4.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 337.4 kB
Release files / ovkit-0.4.1.tar.gz
| Download URL | ovkit-0.4.1.tar.gz |
|---|---|
| Size | 152.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f421c1db9357a7bacadab6d036b6dada5120852bf3ee92ff995a1799a1e60caf
|
|
BLAKE2b-256 checksum How to use checksums |
dc9d5b55d0b729884034c163ec7b025d014a1bf8d4d2463266dd53434153be25
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 13, 2026.
Transparency logRelease files / ovkit-0.4.1-py3-none-any.whl
| Download URL | ovkit-0.4.1-py3-none-any.whl |
|---|---|
| Size | 184.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e4c616156e82f743ac702fa5cf9458201e6035caac673419c8165ac13ea83dc5
|
|
BLAKE2b-256 checksum How to use checksums |
35652f508946cea0ea2033ce6009c5a01804ba89c0586c8e531be062399b6b48
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 13, 2026.
Transparency log













