
pairsort
Sort anything with Jev. Jev judges "which of these two is better?" for a fraction of a cent. pairsort turns its answers into one ranking with honest probabilities.


pip install pairsort
export OPENROUTER_API_KEY=sk-or-...     # Jev is the default judge
import pairsort

ideas = ["A CSV-to-chart CLI", "A blockchain to-do app", "A PR-urgency ranker",
         "A local-first notes app", "A tweeting fridge magnet"]
r = pairsort.sort(ideas, "Which is most useful?")
r.best      # 'A local-first notes app'   (your own objects back, best first)
r.scores    # {id: P(best)}
uvx pairsort sort ideas.txt "Which is most useful?" # the CLI, no install needed
Several questions, one ranking
Name each question. pairsort ranks by each one separately, then blends them:
r = pairsort.sort(ideas, useful="Which is more useful?", easy="Which is easier to build?")
r.best      # 'A CSV-to-chart CLI'
print(r)
pairsort sort ideas.txt useful="Which is more useful?" easy="Which is easier to build?"
  #  P(best)  useful  easy  item
--------------------------------------------------
  1    54.3%      #2    #1  A CSV-to-chart CLI
  2    20.3%      #1    #4  A local-first notes app
  3    18.5%      #3    #3  A PR-urgency ranker
  4     5.3%      #5    #2  A tweeting fridge magnet
  5     1.6%      #4    #5  A blockchain to-do app

blend: useful 50% + easy 50%
✓ #1 is 54% likely to be the best, 34% ahead of #2
The notes app is the most useful idea but the second-hardest to build, so the blend picks the CSV CLI. To make one
question count double, write useful=("Which is more useful?", 2) in Python or useful:2="Which is more useful?" in
the CLI. That run took 40 Jev judgments and cost $0.00013. Watch a Jev run replay →
Jev: cheap and good
The same pairs, scored against ground truth, with Jev and three general LLM judges (DeepSeek V4.1 Flash, Gemma 4 31B, Nemotron 3.5 Lightning). Jev was the cheapest judge in every eval, by 1.5–20×, and landed within 2.3 points of the best judge every time.
| eval (ground truth) | Jev | best other judge | Jev cost | others |
|---|---|---|---|---|
| Same answer in 4 languages | 96% | 94% Gemma 4 31B | 5.2¢ | 15–21¢ |
| Next-day stock returns, Mon | τ +0.14 | +0.08 Gemma 4 31B | 7.3¢ | 11–17¢ |
| Exact error counts | 96.4% | 97.2% Gemma 4 31B | 2.2¢ | 6.8–9.7¢ |
| Which code runs faster | 97.3% | 97.9% DeepSeek V4.1 Flash | 1.2¢ | 3.2–6.7¢ |
| Damage ladder | 94.4% | 96.7% Gemma 4 31B | 1.6¢ | 6.3–32¢ |
| Next-day stock returns, Tue | τ +0.06 | +0.08 Gemma 4 31B | n/a (cached) | n/a |
Percentages are pairs ordered correctly (cross-lingual: identical answer in EN/ES/DE/JA). Market rows are Kendall τ against realized returns; neither day is strong evidence yet. Costs are what each judge billed for its whole eval. On the 100-model Summary Showdown, Jev's 4,800 judgments cost 11¢; the other judges cost $0.37–$1.55 for the same pairs.
Summary Showdown
100 of OpenRouter's most-used models each summarized the 1994 paper this library implements. pairsort ranked them on six questions from 400 of 4,950 possible pairs (8%) with a jury of 4 AI judges. Current top 3: GPT-6 Astra, Claude Opus 5, Nemotron 3 Ultra.
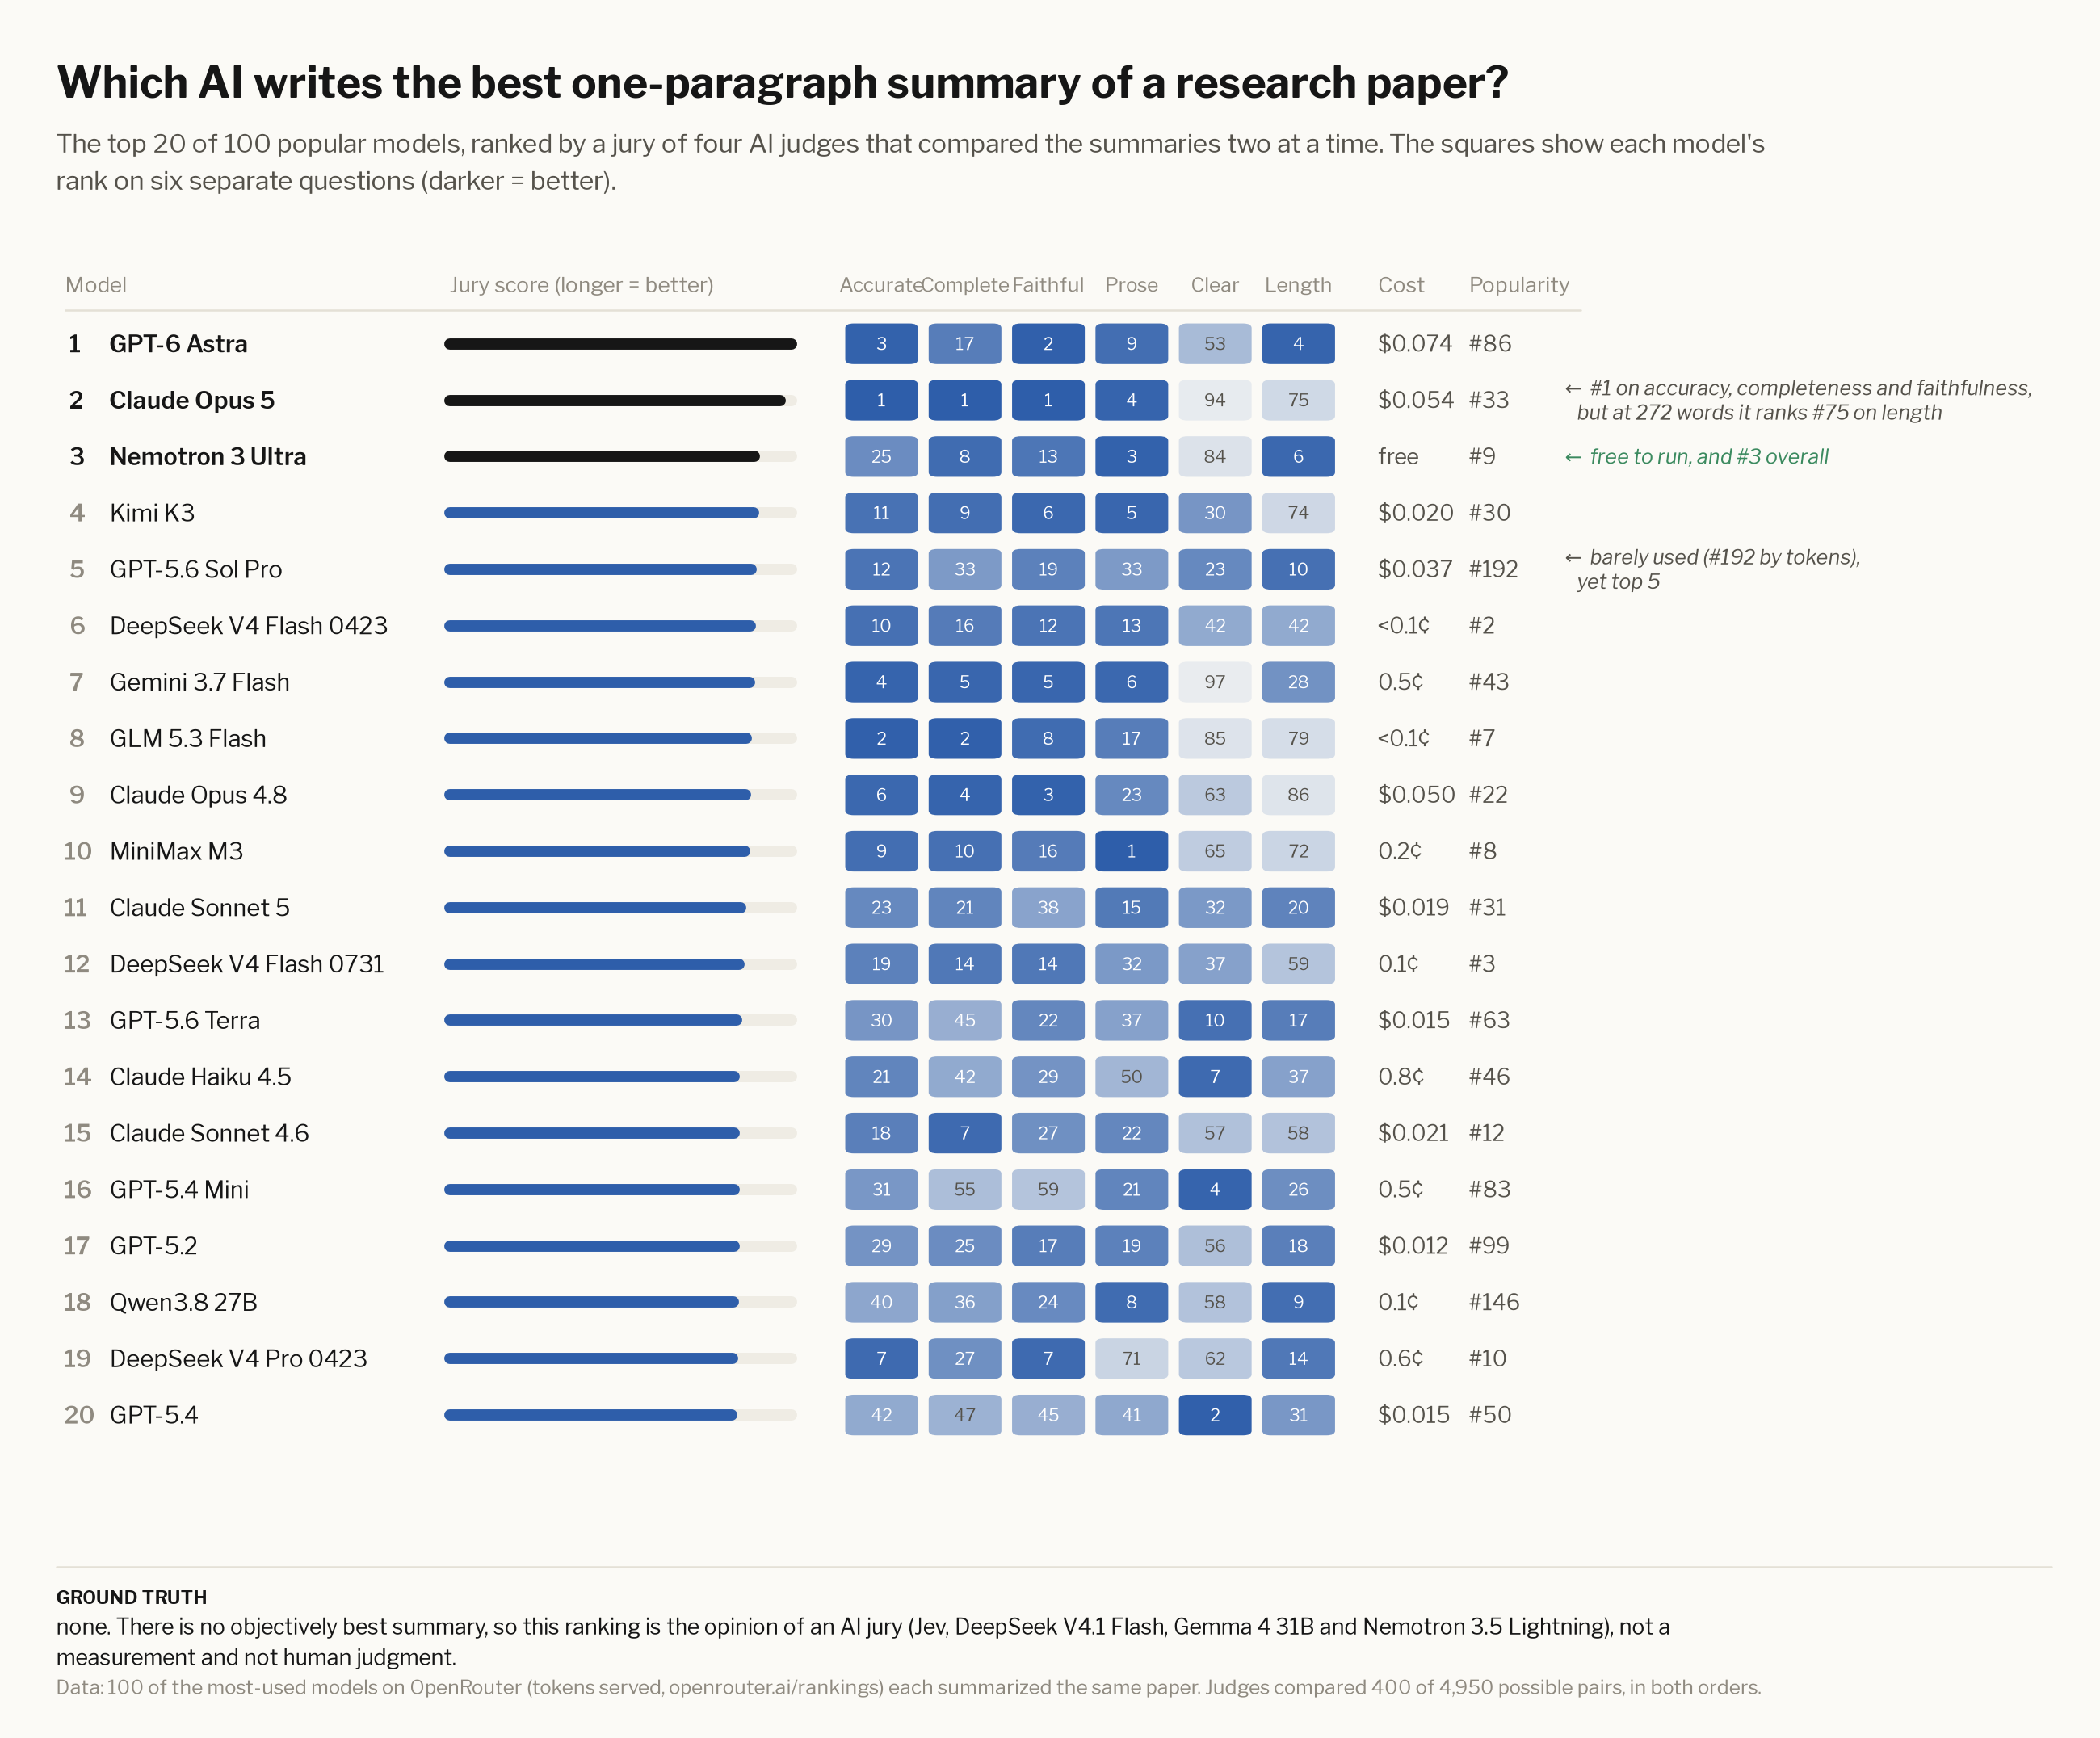
Ground truth: none — nobody can say which summary is truly best. The ranking is the AI jury's opinion; we check it against a separate LLM grader (Claude Sonnet 5 + a key-fact rubric), which the verifiable eval shows is itself accurate on exact counts. Humans can vote on the site.
Judge the summaries yourself → · full results + method · leaderboard
Does it work?
Eight evals, each with its ground truth stated up front:
| eval | what gets ranked | ground truth | result | details |
|---|---|---|---|---|
| Verifiable | 72 summaries of 6 fictional documents | exact counts of injected false statements and of facts mentioned, fixed by construction and recountable by a script | Jev: 96% of pairs right on accuracy, 94% on completeness (τ 0.82 / 0.89) for $0.02; weakest judge τ 0.42 | verifiable |
| Market | 80 + 101 stocks over 2 sessions, judged only on their pre-open SEC filings | realized next-day returns (Mon 09-21 and Tue 09-22), which didn't exist before those days | Monday: Jev τ +0.14 (p = 0.035). Tuesday: no judge beat guessing (best p = 0.12). Weak evidence so far | market |
| Degradation ladder | 60 copies of 6 real summaries, damaged one logged step at a time | rung number (each rung = previous + one planted error / deleted / swapped sentence) | Jev: 94% of pairs right, ECE 0.033 | ladder |
| Code runtime | 25 correct implementations of a new function | measured wall-clock time in a sandbox | Jev picks the faster one 97% of the time | runtime |
| Cross-lingual | the same summaries in EN/ES/DE/JA | exact counts, identical in every language by construction | Jev gives the same answer in all 4 languages 96% of the time | cross-lingual |
| Weather | 35 cities, ranked the day before | airport observations of the next day's high and rain; predictions committed first | first round resolves 2026-09-25 | weather |
| Paper sorting | 16 fictional abstracts on 3 questions | 1–5 levels assigned by construction by the dataset author (not expert ratings) | Jev: fused AUC 0.994, Kendall τ 0.86 | evaluation |
| Synthetic | simulated items, flawed simulated judge | known latent order; calibration labels sampled from it | coupling + both orders + temperature: ECE 0.158 → 0.013 | evaluation |
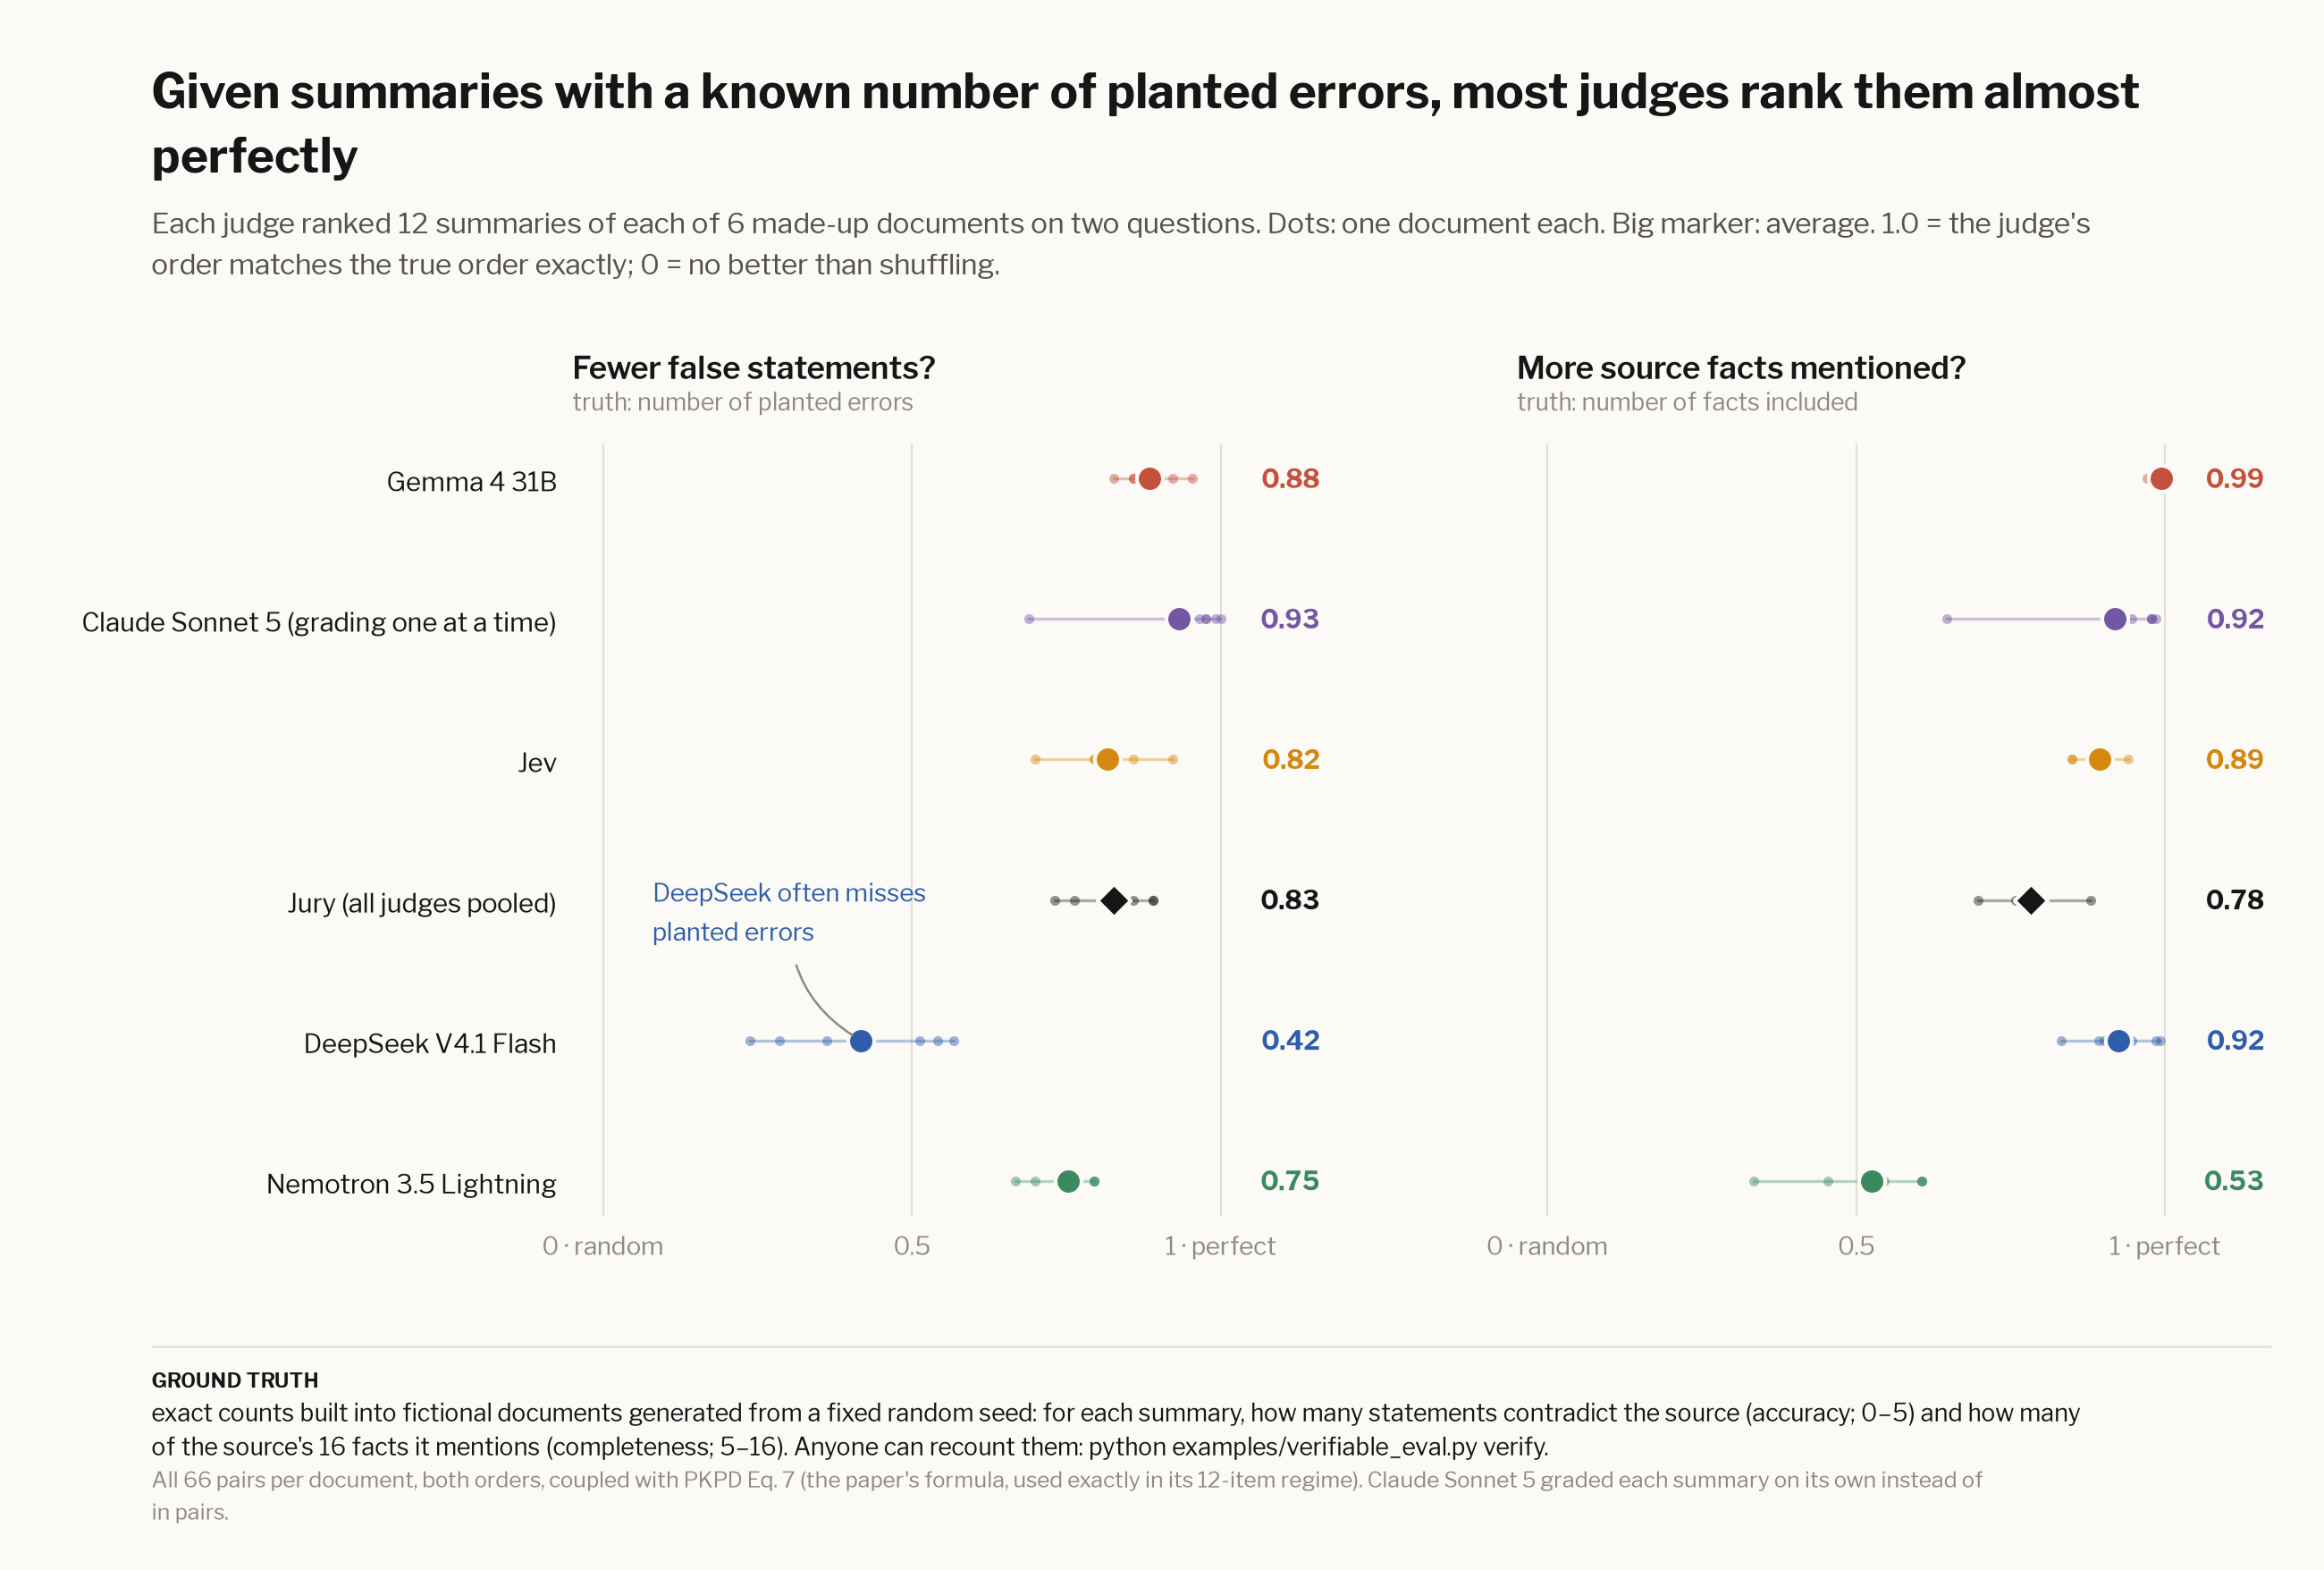
Ground truth in this figure: exact counts built into fictional documents; recount them with
python examples/verifiable_eval.py verify.
How it works
- Pick informative pairs. An active schedule asks about the pairs the ranking is least sure of and stops when it settles, so 100 items were ranked from 8% of the possible pairs.
- Ask both orders.
P_ij = (q(i,j) + 1 − q(j,i)) / 2cancels position bias exactly. - Couple into one ranking. The pairwise-coupling rule of Price, Knerr, Personnaz & Dreyfus
(NeurIPS 1994),
P_i = 1 / (Σ_{j≠i} 1/P_ij − (K − 2)), turns pairwise probabilities into one probability per item, even when the judge contradicts itself (A > B > C > A). Bradley–Terry takes over for large or sparse sets. - Blend questions, abstain when unsure. Each question is coupled separately, then fused; when the top two are too close to call, pairsort says so. Every judgment, in both orders, lands in a JSON audit log.
Beyond the one-liner
pairsort.compare("draft A", "draft B", "Which is clearer?")                                  # -> P(A is better)
pairsort.sort(ideas, "Which is shorter?", judge=lambda q, a, b: len(a) < len(b))             # any function is a judge
pairsort.sorter().by("Which is best?").judge("llm:deepseek/deepseek-v4.1-flash").budget(60).meta().sort(ideas)
cat ideas.txt | pairsort sort - "Which is funnier?" --top 3     # from stdin
pairsort compare "draft A" "draft B" "Which is clearer?"
Budgets, active and referee schedules, meta-judges, calibration profiles and every backend (Jev via OpenRouter, any
OpenRouter LLM via logprobs, open Jev models, your own function) are keywords on pairsort.sort or steps on the
builder. Quickstart · Usage & CLI ·
Judges
What's next
- Weather resolves 2026-09-25: 35 cities ranked by tomorrow's heat and rain, committed first, scored by airport sensors.
- More market sessions: two days is not evidence; each new session is added as it resolves.
- Humans vs judges: every showdown ballot grows the agreement study.
- Open Jev models locally: exercising the in-process adapters (Laya, Decider, NanoJev, Verdict) on real checkpoints.
Learn more
- How it works: pairwise questions, PKPD Eq. 7, Bradley–Terry, bias guards, blending, Jev as meta-judge and referee
- Judges & backends: Jev via OpenRouter, the LLM fallback, open Jev models, the
/v1/systemoneshim - Usage: CLI, input formats, Python API, calibration, a worked example
- Evals: verifiable · market · ladder · runtime · cross-lingual · weather · synthetic + papers · Summary Showdown · Humans vs judges
MIT licensed. Contributions welcome.
1 maintainer

Release files for pairsort 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pairsort-0.3.0.tar.gz | 78.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pairsort-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 161.2 kB
Release files / pairsort-0.3.0.tar.gz
| Download URL | pairsort-0.3.0.tar.gz |
|---|---|
| Size | 78.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
942abd9750ccc428e3590204976cb9205e8ed7aed01b1864c67306022a5dbb82
|
|
BLAKE2b-256 checksum How to use checksums |
4de2895f6c9475197a8752915bb09b24baeff367a6f683a46c5acd38a10e5f1b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 23, 2026.
Transparency logRelease files / pairsort-0.3.0-py3-none-any.whl
| Download URL | pairsort-0.3.0-py3-none-any.whl |
|---|---|
| Size | 82.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
9c162e304e1ae19db0b6a2cd323bbbc0a23d4467ec7c826790b58d0e3eab4a4b
|
|
BLAKE2b-256 checksum How to use checksums |
9eb00e000cc8323d5484a272bbf2304511aee8078fbc2b28dcf1decfc3efdaf6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 23, 2026.
Transparency log













