
blame
Cell-level "why" for pandas pipelines. No code changes.




Your report says 41,900 and it should say 38,400. Today you find that out by
adding print statements down a thirty-step pipeline until something looks wrong.
blame records the pipeline as it runs, so you can point at the number instead.
Install
pip install pandas-blame
Use
import blame, pandas as pd

with blame.trace():
    orders = pd.read_csv("orders.csv")
    customers = pd.read_csv("customers.csv")
    clean = orders[orders.qty > 0]
    joined = clean.merge(customers, on="customer_id")
    report = joined.groupby("region", as_index=False)["total"].sum()

print(blame.last_run().why(row=1, col="total"))
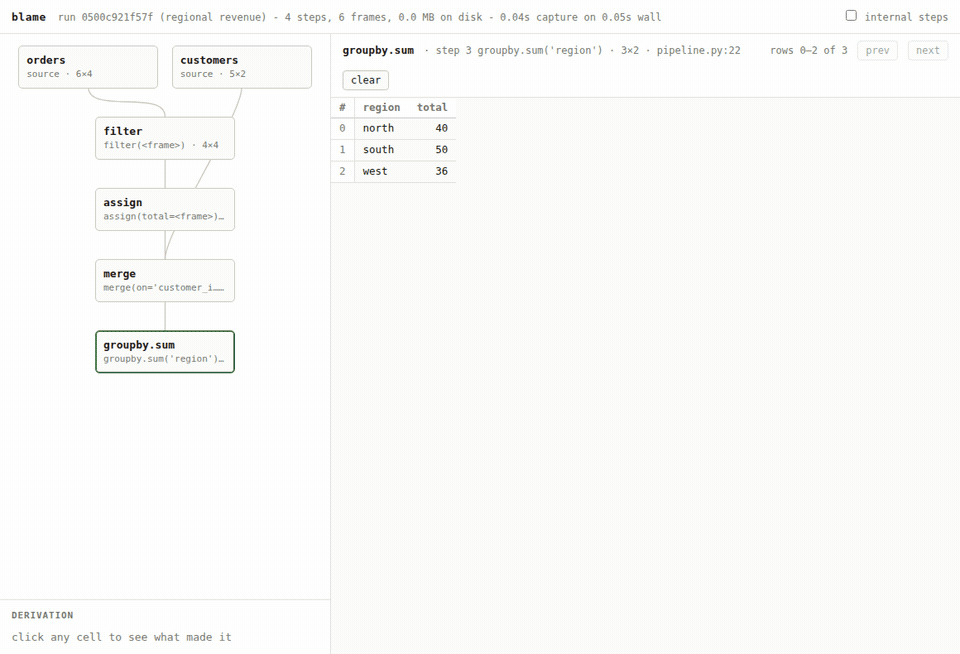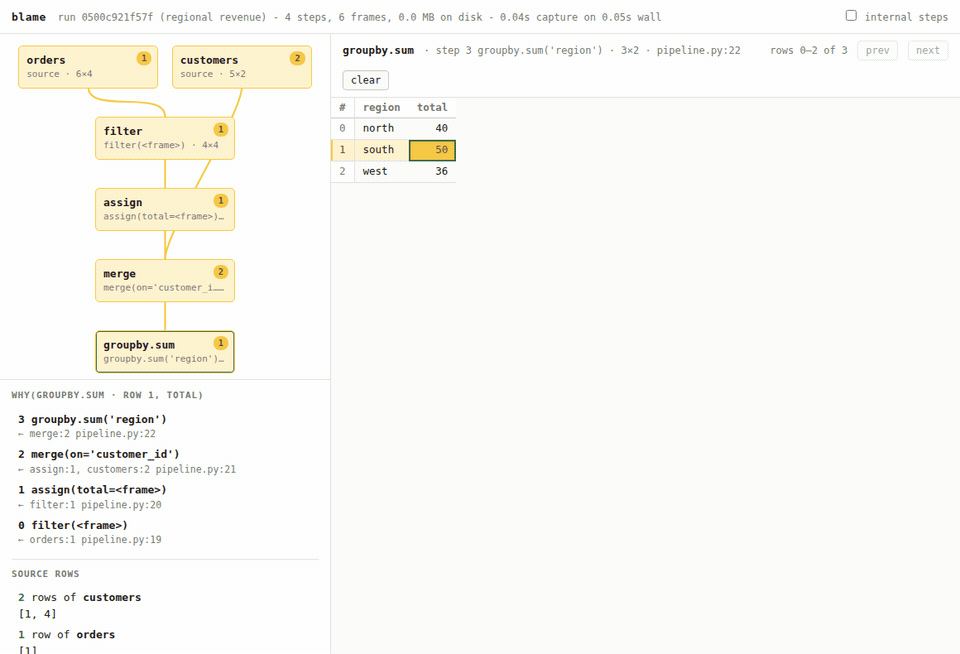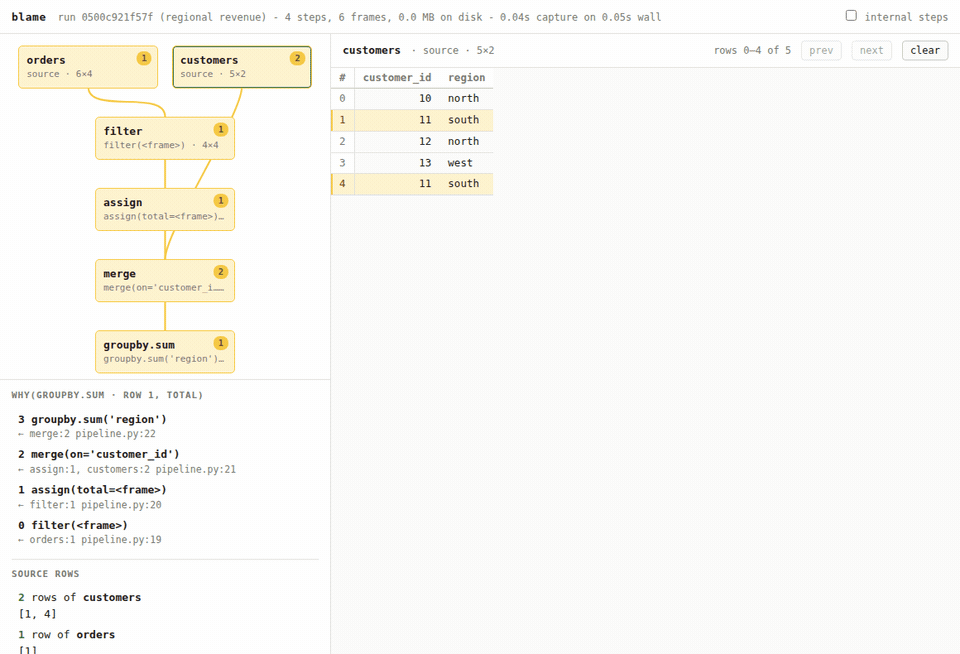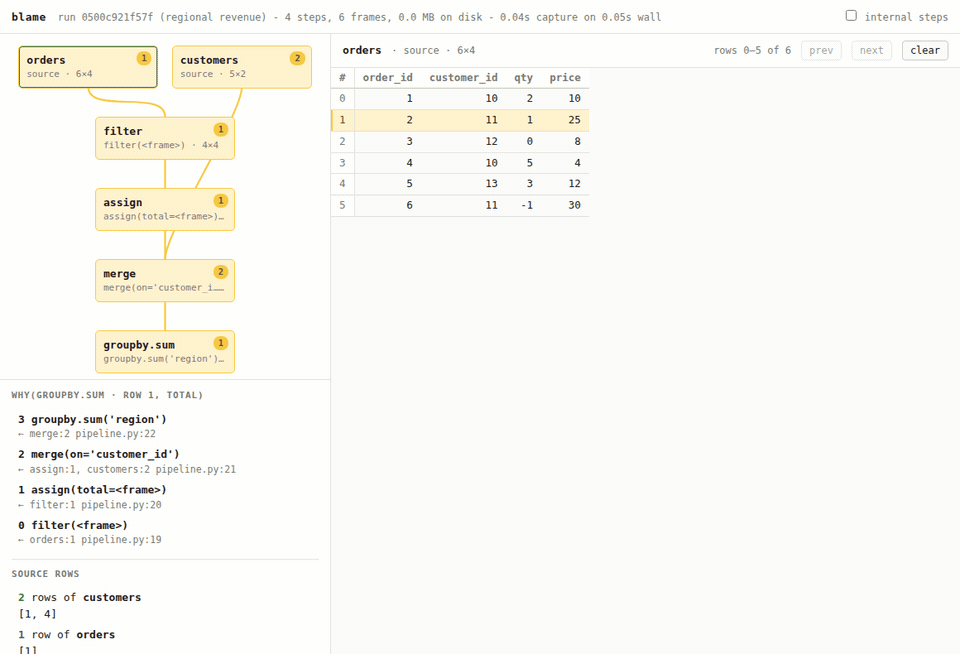
why(groupby.sum [f5] 3x2, row [1], column 'total')

  derivation:
    step   3 groupby.sum('region') [demo.py:9] <- f4:2 rows
    step   2 merge(on='customer_id') [demo.py:8] <- f3:1 row, f1:2 rows
    step   0 filter(<frame>) [demo.py:6] <- f0:1 row

  source rows:
    read_csv('customers.csv') [f1]: 2 row(s) -> [1, 4]
    read_csv('orders.csv') [f0]: 1 row(s) -> [1]
One order row, but two customer rows: customers.csv has customer_id 11
twice, so the merge duplicated that order and the group-by counted it twice.
Two row numbers in two files, not "somewhere in these steps".
blame steps    # every operation the pipeline ran, with line numbers
blame ui       # the picture above: click a cell, watch its sources light up
blame diff     # what changed since the last run, and which input row did it
blame diff is the one that earns its keep in a test suite:
with blame.trace() as before:  # yesterday's run
    report = build_report()
with blame.trace() as after:  # today's, after the data landed
    report = build_report()

assert not before.run.diff(after.run, on="order_id").unexplained_rows()
Inputs that did not move should not produce outputs that did. When they do,
blame names the input row responsible — or says plainly that none explains it,
which means the pipeline changed rather than the data.
Honest limits
Lineage is exact for filters, slices, sorts, joins, group-bys, resample,
concats, pivot, pivot_table, melt, unstack and the row-preserving
transforms. It is approximate, and says so with a ~, for apply/map with
a user function, and for operations it does not cover (transpose, stack,
explode). Approximate answers are widened to every candidate row, never
narrowed and never presented as exact — see docs/accuracy.md.
Capture costs about 2x wall time and 5 ms per step on a million rows (benchmarks). Tested on pandas 2.0.3, 2.2.3 and 3.0.5; the ten pandas documentation tutorials run under it with no exceptions, no changed results and no approximate steps, in a harness that runs on every pull request (validation).
Status
Alpha, and honest about it. It works, it is tested against ground truth, and it has never been run on your pipeline. If it gets something wrong about a real one, that is the bug report worth filing. Contributing. Roadmap.
Apache-2.0.
1 maintainer

Metadata
1 maintainer
Release files for pandas-blame 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pandas_blame-0.2.0.tar.gz | 213.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pandas_blame-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 268.3 kB
Release files / pandas_blame-0.2.0.tar.gz
| Download URL | pandas_blame-0.2.0.tar.gz |
|---|---|
| Size | 213.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
2f6ead609725076592292c3ba4d61523e3e31f617eae85bb22343fa11131b679
|
|
BLAKE2b-256 checksum How to use checksums |
6937e359e2834eff482f29aaa0ba44b20dc8ccb2517f81ac21f2cde3a8d0361c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 16, 2026.
Transparency logRelease files / pandas_blame-0.2.0-py3-none-any.whl
| Download URL | pandas_blame-0.2.0-py3-none-any.whl |
|---|---|
| Size | 55.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a1168df6e540279ade42ccf23e6901474e8fcc564f664b1520bf770ffb9cb90c
|
|
BLAKE2b-256 checksum How to use checksums |
280f33c7a2c88d4d722fb5179adfc8ba2ec61c02159672f3ef6fb28932217c78
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 16, 2026.
Transparency log













