
PAnno: A Pharmacogenomics Annotation Tool for Clinical Genomic Testing



PAnno reports prescribing recommendations and drug response phenotypes by parsing the germline variant call format (VCF) file from NGS and the population to which the individual belongs.
Installation
Prerequisite: To ensure smooth installation and usage, Python >= 3.7 (#1 and #3 below), or Miniconda/Anaconda (#2 below) are required.
- You can install PAnno from PyPI using pip as follows:
pip install panno==0.3.1
- Alternatively, you can create a environment using Conda.
conda create -n PAnno panno=0.3.1 -c lyaqing -c conda-forge -c bioconda
conda activate PAnno
- If you would like the development version instead, the command is:
pip install --upgrade --force-reinstall git+https://github.com/PreMedKB/PAnno.git
# Or download first and install later
git clone https://github.com/PreMedKB/PAnno.git; pip install PAnno
Usage
Once installed, you can use PAnno by navigating to your VCF file and entering the corresponding three-letter abbreviation of the population:
panno -s sample_id -i germline_vcf -p population -o outdir
- Required arguments
-s, --sample_id TEXT            Sample ID that will be displayed in the PAnno report.

-i, --germline_vcf TEXT         Unannotated VCF file, preferably germline variant.

-p, --population [AAC|AME|EAS|EUR|LAT|NEA|OCE|SAS|SSA]
                                The three-letter abbreviation for biogeographic groups:
                                AAC (African American/Afro-Caribbean), AME (American),
                                EAS (East Asian), EUR (European), LAT (Latino),
                                NEA (Near Eastern), OCE (Oceanian),
                                SAS (Central/South Asian), SSA (Sub-Saharan African).

-o, --outdir TEXT               Create report in the specified output path.
Input data
1. Germline VCF file
PAnno directly uses the NGS-derived germline VCF file as input and assumes it has undergone quality control. Therefore, if the VCF file is of poor quality, inaccurate diplotypes and inappropriate clinical recommendations may be reported.
PAnno requires the VCF file aligned to the GRCh38 reference genome given the increasing generality and the built-in diplotype definition dependency version.
2. Population
There are nine biogeographic groups supported by PAnno. Please use the three-letter abbreviation as input. This is to prevent errors caused by special symbols such as spaces.
AAC (African American/Afro-Caribbean), AME (American), EAS (East Asian), EUR (European), LAT (Latino), NEA (Near Eastern), OCE (Oceanian), SAS (Central/South Asian), SSA (Sub-Saharan African).
More information is available at https://www.pharmgkb.org/page/biogeographicalGroups.
Output data
The report is created in ${sample_id}.html at the outdir by default.
For more detailed instructions, run panno -h.
Examples
The demo directory contains the VCF files and PAnno reports of four Coriell samples: NA10859 (European), NA19147 (African American/Afro-Caribbean), NA19785 (Latino), and HG00436 (East Asian).
In addition, we analyzed the germline variants of 88 samples which have been characterized in the GeT-RM PGx studies.
- The VCF files are available at https://github.com/PreMedKB/PAnno-analysis/tree/main/vcf.
- The PAnno reports are available at https://github.com/PreMedKB/PAnno-analysis/tree/main/report.
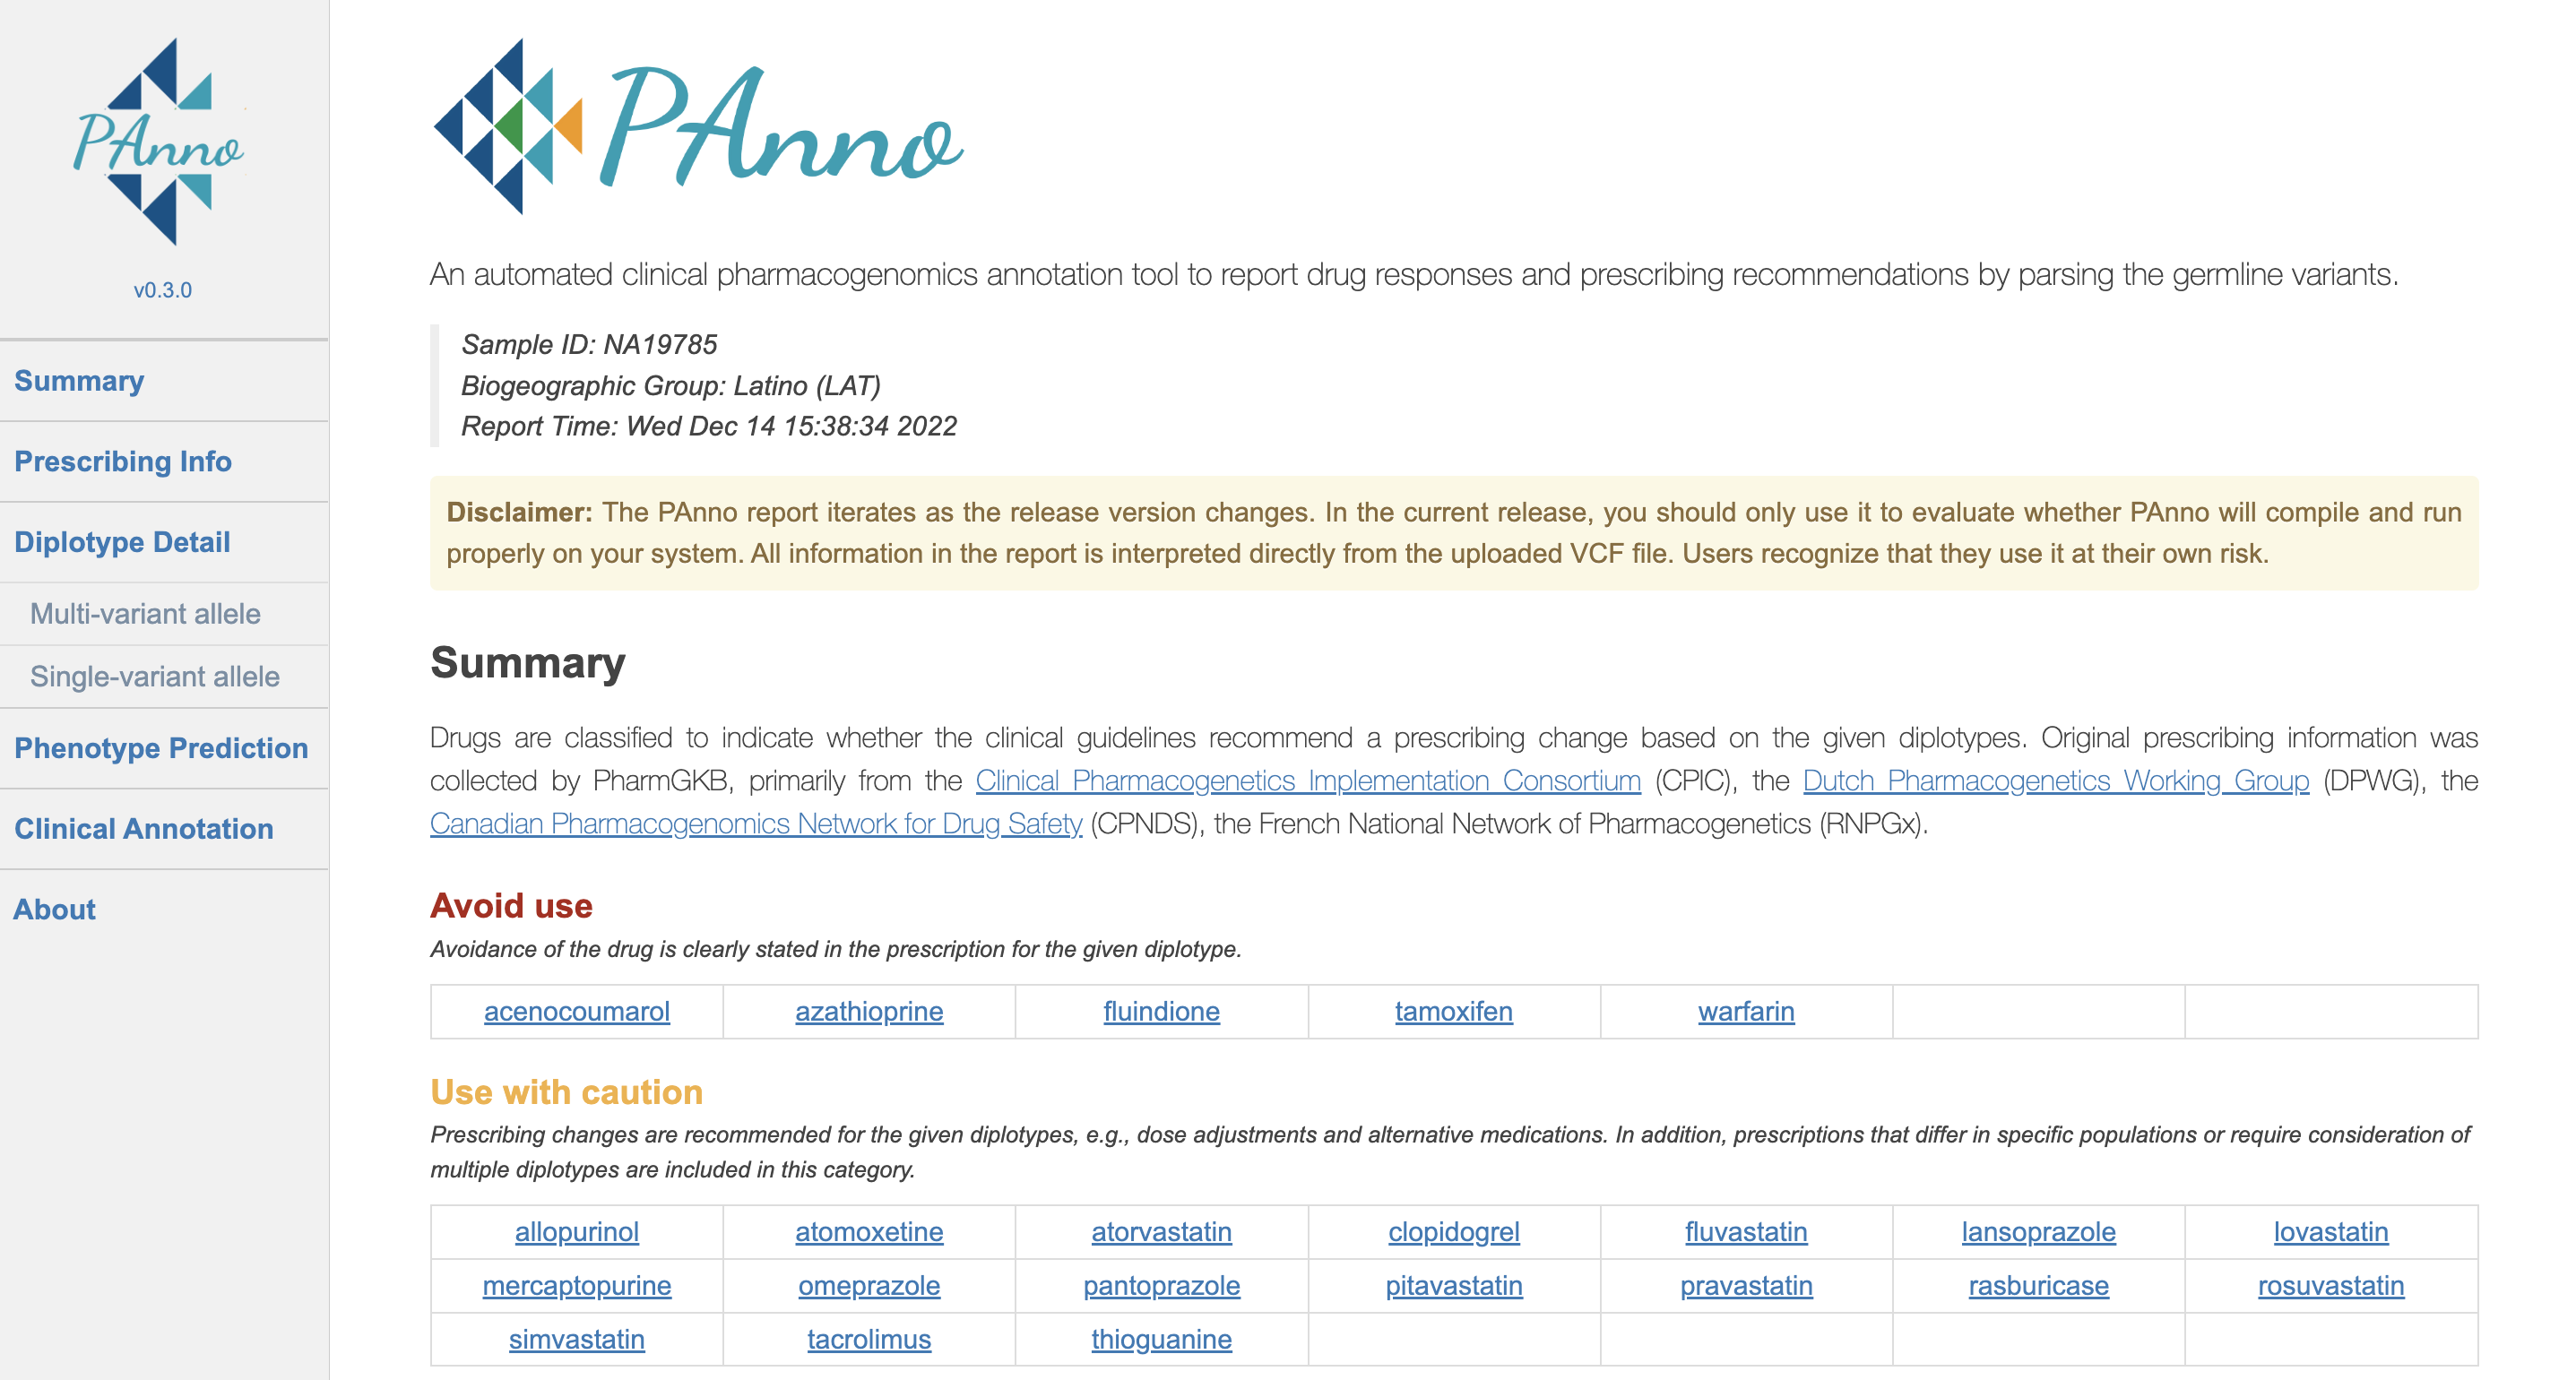
Here is a snapshot from the PAnno report:
Core Components
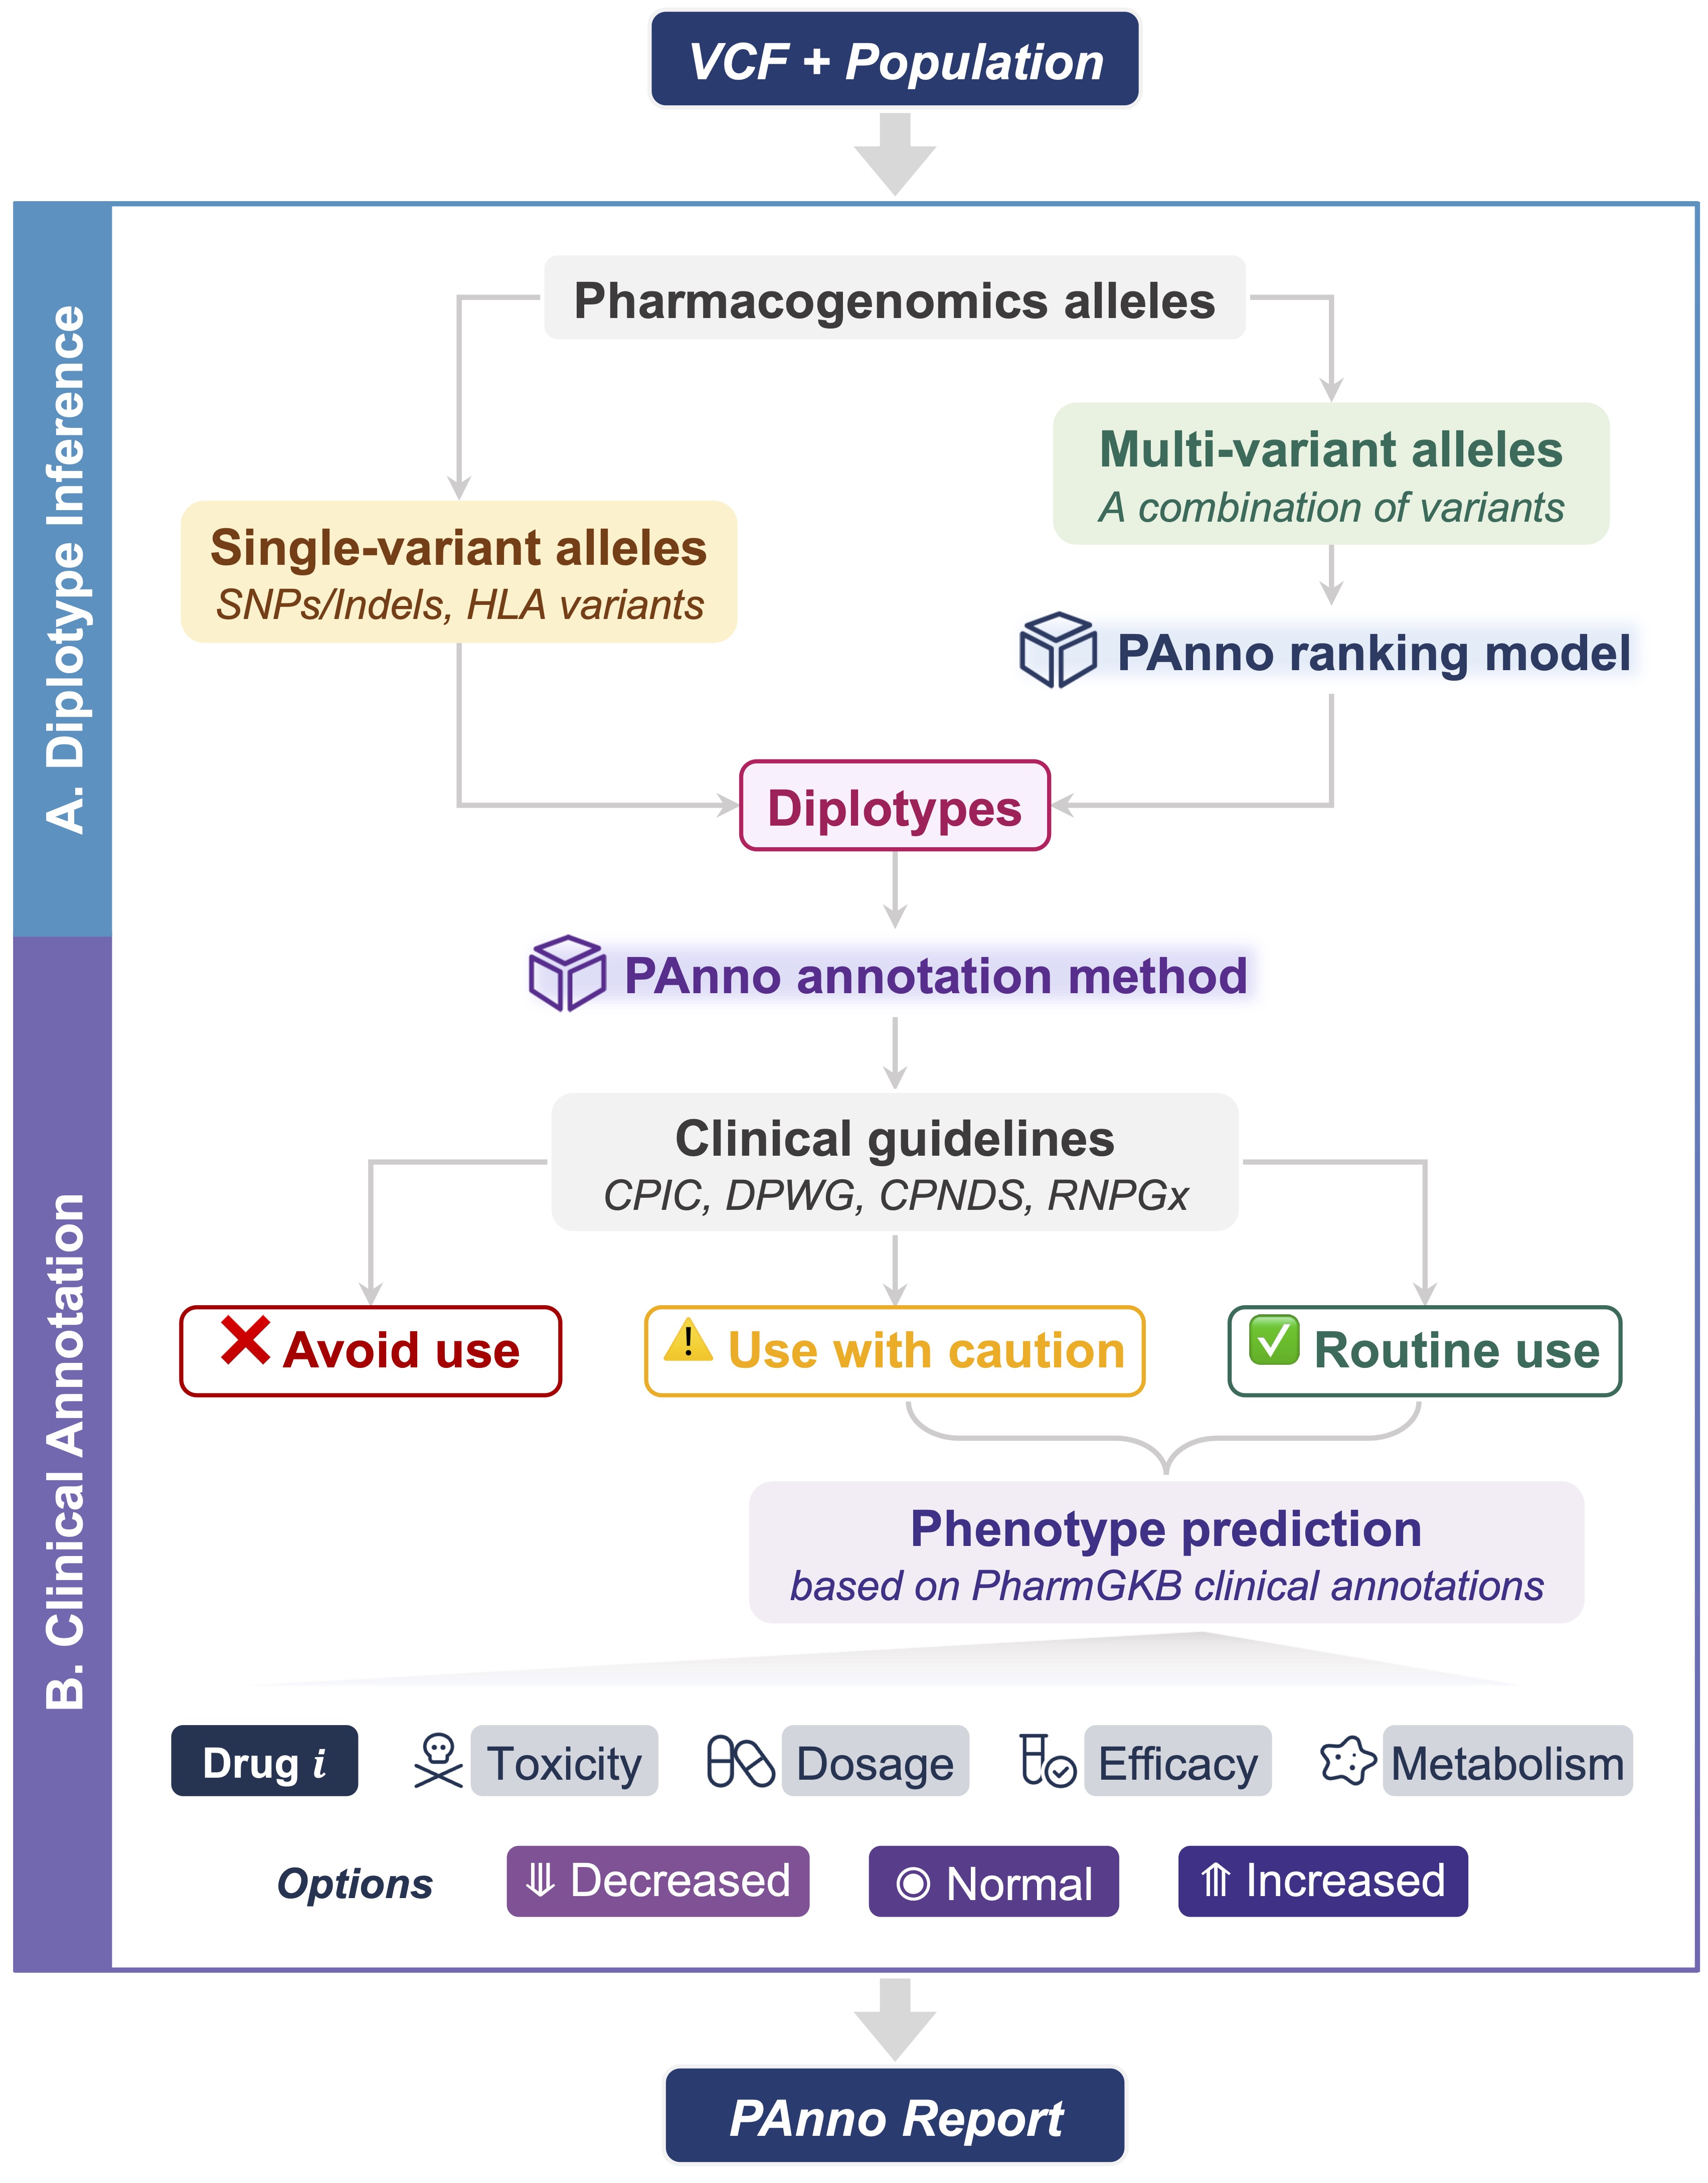
A ranking model dedicated to inferring diplotypes, developed based on the allele (haplotype) definition and population frequency, was introduced in PAnno. The predictive performance was validated in comparison with four similar tools using the consensus diplotype data of the Genetic Testing Reference Materials Coordination Program (GeT-RM) as ground truth.
An annotation method was proposed to summarize prescriptions and classify drugs into avoid use, use with caution, and routine use, following the recommendations of the Clinical Pharmacogenetics Implementation Consortium (CPIC), etc. It further predicts phenotypes of specific drugs in terms of toxicity, dosage, efficacy, and metabolism by integrating the high-confidence clinical annotations in the Pharmacogenomics Knowledgebase (PharmGKB).
1 maintainer

Metadata
1 maintainer
Release files for panno 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| panno-0.3.1.tar.gz | 9.5 MB | Without provenance | Details |
Release files / panno-0.3.1.tar.gz
| Download URL | panno-0.3.1.tar.gz |
|---|---|
| Size | 9.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c35d4e8b525a6c444bac0f7b427868bb434f4c034d5a352e00f8caabeb9ced81
|
|
BLAKE2b-256 checksum How to use checksums |
f9f53fe575624954a4302a5d2b38fea3c16661b65a930b93de4479055f1d718e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.1 CPython/3.7.7
|
Security for panno 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














