
Check every reference of a paper against real scholarly records before you submit.
No LLM guessing, no false accusations.





English · 简体中文 · Quick start · User guide · Releases · Feedback
Language models invent references, and copy-pasted BibTeX carries wrong years, wrong authors and dead DOIs. paper-preflight reads your paper (LaTeX, Word, Markdown, Typst, a PDF or a plain reference list) and asks Crossref, dblp, arXiv, DataCite, PubMed and OpenAlex about every cited work, with Semantic Scholar too if you have a free key, Open Library for books without a DOI, and GitHub, PyPI, CRAN, Hugging Face and OpenML for software, models and datasets:
- Does it exist?
- Does it match what you wrote?
- Has it been retracted?
- Has the preprint you cite been published since?
Every finding is backed by a record, or by every source that could know the work answering "no". When it cannot tell, it says "cannot determine" and why, instead of guessing. No language model takes part in a verdict.
Status: 1.0. On three weeks of real arXiv papers held out for the release: 0.79 false alarms per 100 references, against 409 real problems found (accuracy). Rule IDs, the JSON report, settings, commands and the Python API are kept through 1.x (what is stable). False positives are the bugs we most want to hear about: please open an issue.
Quick start
With uv nothing needs installing:
uvx paper-preflight check path/to/paper
path/to/paper is the project's folder, its main .tex file or a .bib file. To install it
for good (Python 3.11 or later):
pip install paper-preflight
| Extra | Adds | Install |
|---|---|---|
pdf |
Reading the reference list of a PDF | pip install "paper-preflight[pdf]" |
mcp |
The MCP server for coding agents | pip install "paper-preflight[mcp]" |
support |
The experimental evidence finder, with its local model | pip install "paper-preflight[support]" |
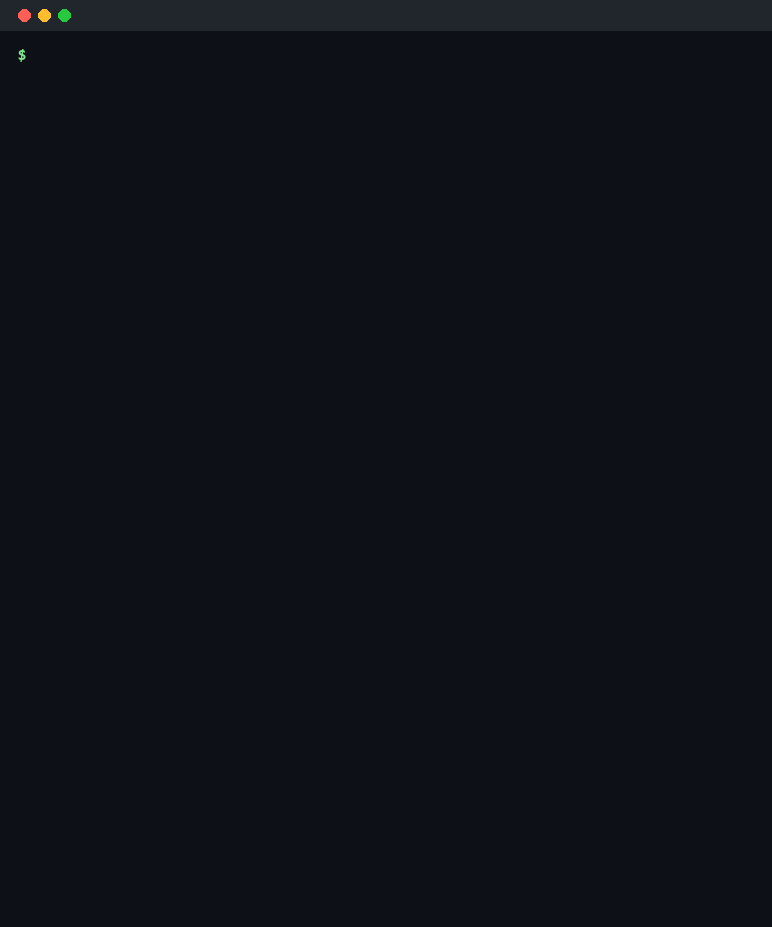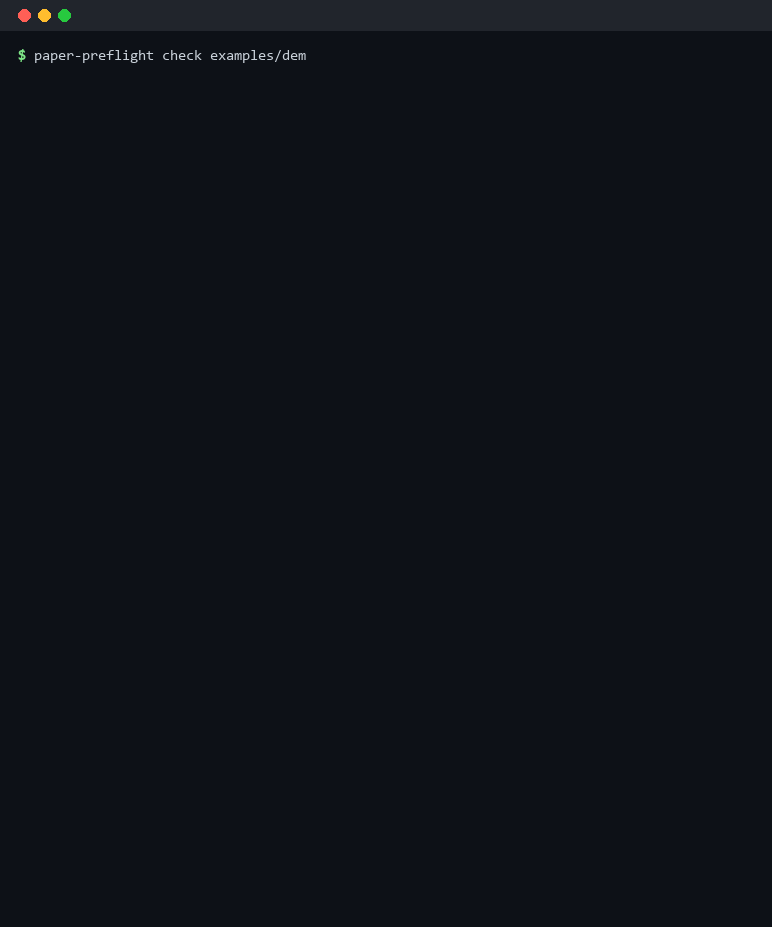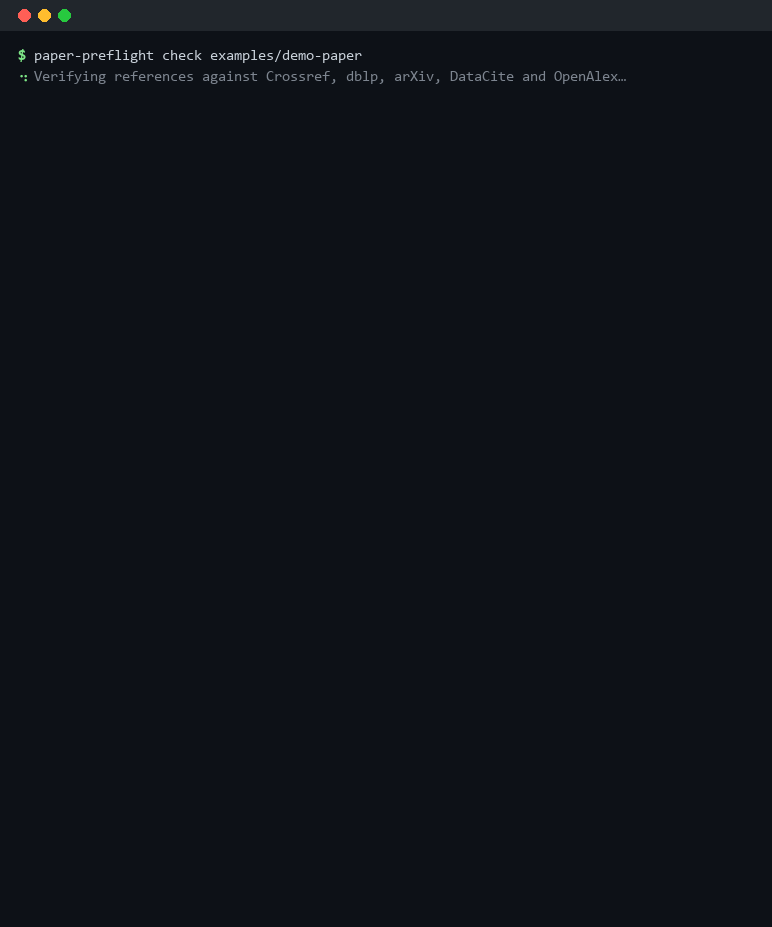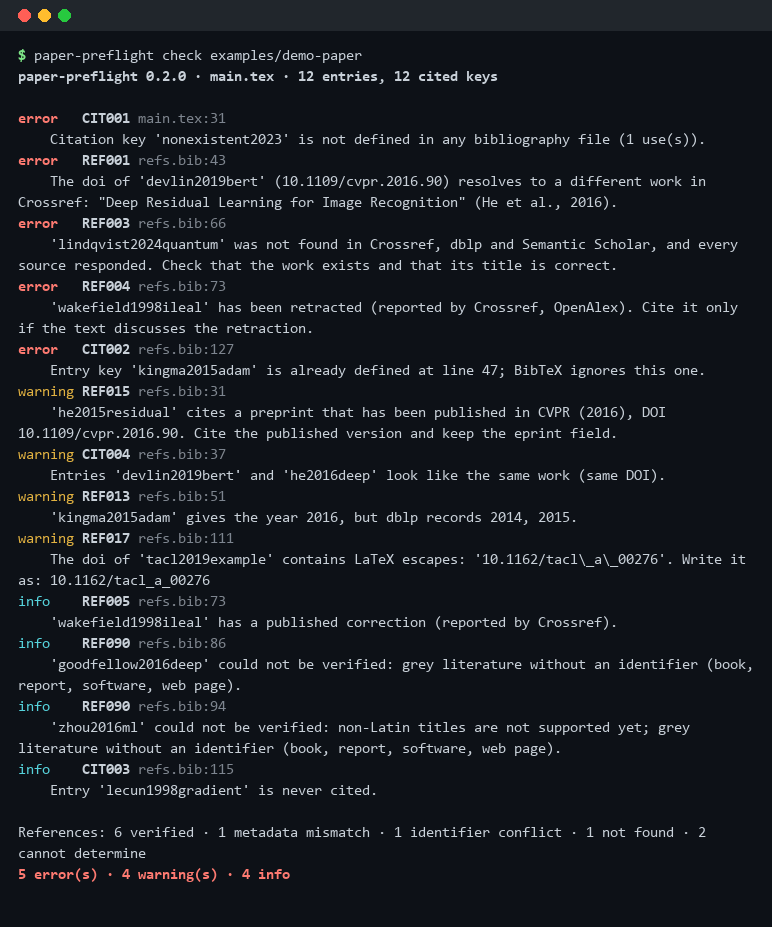
The repository's demo paper cites eleven works, several of them wrong on
purpose. The animation above is a real run of paper-preflight check examples/demo-paper
against the live sources. In it, the correct NeurIPS paper is verified through dblp although
Crossref only holds fake copies of it, the book without an identifier is confirmed by Open
Library, and the Chinese book, whose script is not supported yet, is "cannot determine", not
"not found".
The same run as text
$ paper-preflight check examples/demo-paper
paper-preflight 1.0.0 · main.tex · 12 entries, 12 cited keys

error   CIT001 main.tex:31
    Citation key 'nonexistent2023' is not defined in any bibliography file (1 use(s)).
error   REF001 refs.bib:43
    The doi of 'devlin2019bert' (10.1109/cvpr.2016.90) resolves to a different work in Crossref: "Deep Residual Learning for Image Recognition" (He et al., 2016).
error   REF003 refs.bib:66
    'lindqvist2024quantum' was not found in Crossref, dblp and Semantic Scholar, and every source responded. Check that the work exists and that its title is correct.
error   REF004 refs.bib:73
    'wakefield1998ileal' has been retracted (reported by Crossref, OpenAlex). Cite it only if the text discusses the retraction.
error   CIT002 refs.bib:128
    Entry key 'kingma2015adam' is already defined at line 47; BibTeX ignores this one.
warning REF015 refs.bib:31
    'he2015residual' cites a preprint that has been published in CVPR (2016), DOI 10.1109/cvpr.2016.90. Cite the published version and keep the eprint field.
warning CIT004 refs.bib:37
    Entries 'devlin2019bert' and 'he2016deep' look like the same work (same DOI).
warning REF013 refs.bib:51
    'kingma2015adam' gives the year 2016, but dblp records 2014, 2015.
warning REF017 refs.bib:112
    The doi of 'tacl2019example' contains LaTeX escapes: '10.1162/tacl\_a\_00276'. Write it as: 10.1162/tacl_a_00276
info    REF005 refs.bib:73
    'wakefield1998ileal' has a published correction (reported by Crossref).
info    REF090 refs.bib:95
    'zhou2016ml' could not be verified: non-Latin titles are not supported yet; grey literature without an identifier (book, report, software, web page).
info    CIT003 refs.bib:116
    Entry 'lecun1998gradient' is never cited.

References: 7 verified · 1 metadata mismatch · 1 identifier conflict · 1 not found · 1 cannot determine
5 error(s) · 4 warning(s) · 3 info
What it reads
| You have | Command |
|---|---|
A LaTeX project: its folder, main .tex or .bib; a project that ships only its compiled .bbl, as many arXiv sources do, is read from it (checked, never edited) |
paper-preflight check path/to/paper |
| A Word manuscript: citations inserted by Zotero, Mendeley or EndNote, Word's own sources, or the reference list as typed | paper-preflight check paper.docx |
Markdown, Quarto or R Markdown: [@key] against its bibliography |
paper-preflight check paper.qmd |
Typst: @key against #bibliography(...), a .bib or Hayagriva .yml |
paper-preflight check paper.typ |
A bibliography on its own: BibTeX, CSL-JSON (.json), RIS (.ris) or YAML (.yml) |
paper-preflight check refs.ris |
| A reference list as plain text, in the common styles (APA, IEEE, ACM, Nature, Vancouver, Springer, Elsevier, MDPI, GOST, Chicago, MLA) | paper-preflight check references.txt, or - for stdin |
Only the PDF (with the pdf extra) |
paper-preflight check paper.pdf |
| Any arXiv paper: its source is downloaded to a temporary folder, checked and deleted | paper-preflight check arxiv:2607.06922 |
What each input can and cannot tell, in detail: docs/inputs.md.
What it checks
Every reference gets one verdict:
| Verdict | Means |
|---|---|
| verified | A record of the work was found and agrees with the entry |
| metadata mismatch | The work was found, but the entry says something else about it: the findings name the field |
| identifier conflict | The entry's DOI or arXiv ID belongs to another work |
| not found | Every source that could know the work answered, and none has it |
| cannot determine | It could not be decided, and the report says why |
The findings say what is wrong:
| Rule | Finding |
|---|---|
| REF001 | The DOI or arXiv ID points to a different paper |
| REF002 | The DOI or arXiv ID does not exist |
| REF003 | The work was not found in any source, and every source answered |
| REF004 · REF005 | The work was retracted, or has an expression of concern or a correction |
| REF010–REF014 | Authors, title, year or venue differ from the real record |
| REF015 | A cited preprint has been formally published |
| REF016 | The registry has a DOI the entry lacks (offered as a safe fix) |
| REF017 | An identifier is written so that links break (10.1162/tacl\_a\_00276, …v1) |
| REF018 | A cited arXiv preprint was withdrawn by its authors |
| REF019 · REF021 | A linked repository, package or dataset does not exist; a linked web page is gone, with no archived copy |
| REF020 | A preprint is cited with a venue no catalogue of journals and conferences has |
| REF090 | Cannot determine, always with the reason (source unavailable, grey literature, …) |
| CIT001–CIT008 | Undefined, duplicate, unused or near-duplicate citation keys; broken .bib syntax |
| TEX001–TEX004 | Included files missing, unreadable or including each other; a remote bibliography left unchecked |
| RUN001 · RUN002 · CFG001 | A run left incomplete by a source outage; a source answered in place of another; a suppression comment that silenced nothing |
Every rule has a page: what it checks, when it can be wrong, and what to
do. paper-preflight explain REF003 prints it in the terminal.
How accurate is it?
Four measurements, all against the live sources:
| Measured on | Result |
|---|---|
| Real papers: 60 arXiv papers from three weeks held out for 1.0, 2,714 references, every flag reviewed by hand | 0.79 false alarms per 100 references (one every three papers), against 409 real problems |
| Hallucinations that passed peer review: the 151 GPTZero found in NeurIPS 2025 and ICLR 2026 papers | 142 flagged (94%), 9 cannot determine, none verified |
| HALLMARK, a public benchmark: 831 entries never used during development | Any issue: precision 98.5%, recall 93.5%, false-positive rate 1.9% |
| Next to five other tools, on 104 references labelled by hand in a published study | Precision 72.5%, against 31–51% for the others, at 87.9% recall |
Precision comes first: a reference is called fabricated only on positive evidence, and an
unanswered or ambiguous lookup is reported as "cannot determine", never as "not found". The
evaluation harness and every run's summary are in evals/.
Real papers
| arXiv papers first submitted (20 a week) | Run with | References | Flags | Real problems | False alarms | Unclear | False alarms per 100 references |
|---|---|---|---|---|---|---|---|
| 2026-10-07..13, the latest week | the first 1.0 candidate | 991 | 81 | 76 | 4 | 1 | 0.4 |
| 2026-03-25..31 | 1.0.0 | 809 | 220 | 209 | 8 | 3 | 1.0 |
| 2026-03-18..24 | 1.0.0 | 1,007 | 110 | 105 | 5 | 0 | 0.5 |
| 2026-03-11..17 | 1.0.0 | 898 | 104 | 95 | 8 | 1 | 0.9 |
| The three weeks held out for 1.0 | 1.0.0 | 2,714 | 434 | 409 | 21 | 4 | 0.79 |
Hallucinations that passed peer review
GPTZero published 151 hallucinated references it found in NeurIPS 2025 papers and ICLR 2026
submissions, each confirmed by its staff. Pasted as plain text, as the papers printed them,
142 are flagged and none is verified. The 9 left undecided are web pages and blog posts, a
workshop no source indexes, real titles given with invented authors where several works share
the title, and two references too garbled to search; each is listed with its reason in
evals/results/gptzero.md. GPTZero's own tool found these, so they
are the hallucinations a search can find; recall on every kind of hallucination is lower (see
HALLMARK).
HALLMARK
HALLMARK (v1.2.3) is a public benchmark of real and hallucinated BibTeX entries. Fabrication counts a wrong identifier, a work not found and no author in common; any issue also counts wrong authors, title, year or venue.
| Split | Mode | Precision | Recall | False-positive rate | Coverage |
|---|---|---|---|---|---|
test_public: 831 entries, never used during development |
Any issue | 98.5% | 93.5% | 1.9% | 97.7% |
| Fabrication | 99.0% | 50.2% | 0.6% | 97.7% | |
dev_public: 1,119 entries, used during development |
Any issue | 97.7% | 94.3% | 2.1% | 98.9% |
| Fabrication | 98.2% | 53.7% | 1.0% | 98.9% |
test_public was run with 1.0.0, dev_public with 0.8.0; no rule was tuned on test_public.
- Most of the false positives are disputed labels. Every flag on a
dev_publicentry labelled VALID was checked by hand: the 11 that remain are not correct citations (DOIs that belong to other papers, author lists naming people who did not write the paper, a shifted year, a truncated title). Without them, both modes reach 100% precision. The list, each with a reason one lookup confirms:evals/hallmark_disputed.toml. - What is still missed: author lists cut short at the end, or checked only against a
preprint whose later versions add people (named in an info), and invented entries that borrow
a title several real works share. Every hallucination type is broken down in
evals/results/.
Next to other tools
Badalova & Mayr (2026) checked 104 references by hand and published what five tools flagged. On the same references, with their labels:
| Tool | Precision [95% CI] | Recall | False flags per 100 correct references |
|---|---|---|---|
| CheckIfExist | 47.7% [36.0%, 59.6%] | 93.9% | 47.9 |
| HalluCiteChecker | 47.4% [32.5%, 62.7%] | 54.5% | 28.2 |
| Hallucinator | 50.9% [38.3%, 63.4%] | 87.9% | 39.4 |
| HalRef | 31.2% [21.9%, 42.2%] | 72.7% | 74.6 |
| RefChecker | 47.1% [35.7%, 58.8%] | 97.0% | 50.7 |
| paper-preflight | 72.5% [57.2%, 83.9%] | 87.9% | 15.5 |
The sample is small, so the intervals are wide. The study labels a reference correct when the
work exists, so five of paper-preflight's "false" flags point at real errors (a wrong author, a
broken DOI). Two causes of false flags found in this data were fixed before the run above (the
first run measured 62.8%); see evals/results/badalova-mayr.md.
Limits
- Titles in scripts other than Latin (Chinese, Japanese, Cyrillic, …) are "cannot determine" for now, and so is a Chinese-language work cited by a translated English title, which the open indexes rarely hold.
- Grey literature without an identifier (reports, theses, manuals, standards) is often "cannot determine": the open registries hold little of it. Books are asked of Open Library, software of GitHub, PyPI and CRAN, models and datasets of Hugging Face and OpenML.
- Web pages are never judged true or false. A linked page that is gone, with no archived copy, is reported (REF021).
- A work no open index holds is "cannot determine" when its venue is unknown to the catalogues too, but at a venue they know it can be reported as not found: read REF003's page before acting on that finding.
- Not caught: an invented reference that borrows a real title several works share, an
author list cut short at the end (an info), and a citation of a real paper for a claim it
does not make (only the experimental
supportreads the claims). - It needs the network on a first run: about 0.4 s per reference on a cold cache, so a
50-reference paper takes about 20 seconds. Answers are cached, and
--offlineworks from the cache. A source that is down, with nothing to answer in its place, makes the run incomplete (exit code 2), never "clean".
Fetch verified BibTeX
Instead of writing an entry from memory, ask for it by DOI, arXiv ID or title. Every field comes from the registry record, which a comment above the entry names:
paper-preflight bib fetch 1810.04805
% Verified with paper-preflight against dblp (conf/naacl/DevlinCLT19), 2026-10-03
@inproceedings{devlin2019bert,
  title         = {{BERT:} Pre-training of Deep Bidirectional Transformers for Language Understanding},
  author        = {Devlin, Jacob and Chang, Ming-Wei and Lee, Kenton and Toutanova, Kristina},
  booktitle     = {NAACL-HLT (1)},
  year          = {2019},
  doi           = {10.18653/v1/n19-1423},
  eprint        = {1810.04805},
  archivePrefix = {arXiv},
}
- Preprints: an arXiv preprint that has been published comes back as the published version,
with its
eprintkept (--prefer preprintfor the preprint itself). - Titles:
--title(with--author/--yearif needed) lists the candidates instead of choosing when several works match. - Retractions: a retracted work comes with a warning.
- Scripts and agents:
--format json.
Fix the bibliography
bib fix turns findings into edits of your .bib files, taken from the verified records. It
prints a diff and changes nothing until you add --apply:
paper-preflight bib fix path/to/paper --level unsafe
--- a/refs.bib
+++ b/refs.bib
@@ -48,7 +47,7 @@
   title     = {Adam: A Method for Stochastic Optimization},
   author    = {Kingma, Diederik P. and Ba, Jimmy},
   booktitle = {International Conference on Learning Representations (ICLR)},
-  year      = {2016},
+  year      = {2015},
 }
--level safe(the default) only fixes what cannot change which work is cited: identifiers written so that links break, and DOIs the registry has but the entry lacks.--level unsafealso rewrites authors, title, year and venue from the record, removes identifiers that point to another work, and cites a preprint as its published version (the entry type, venue, year, volume, pages and DOI; the eprint is kept). Review the diff first.- Only the affected fields change; comments, formatting, line endings and encoding are kept. A reference nobody could find is never "fixed": only you can say what was meant.
Options and exit codes
| Option | Effect |
|---|---|
--format json / --format sarif |
Machine-readable output (SARIF works with GitHub code scanning); -o writes it to a file |
--fail-on warning |
Make warnings fail the run too (the default is errors; never for neither) |
--offline |
Never touch the network; use only answers already in the local cache |
--refresh |
Ask every source again instead of using cached answers (after a correction, say) |
--recheck |
Search again now for references found too new to be indexed on earlier runs (otherwise once a day) |
--details |
List every finding; by default a suggestion that applies to many entries (published preprints, available DOIs) is one line |
--hide-info |
Leave out infos |
--lang zh |
Chinese messages (also chosen automatically from your locale) |
| Exit code | Meaning |
|---|---|
| 0 | Nothing at or above --fail-on was found |
| 1 | Blocking findings |
| 2 | No blocking findings, but a source was unavailable and nothing could answer in its place, so the paper cannot be called clean yet |
| 3 | Usage error |
| 4 | Internal error (please report it) |
The JSON report follows a published JSON Schema
(schema_version 1.0): fields may be added, but none is removed or changes meaning within 1.x.
Every option, the cache and its lifetimes: docs/configuration.md.
Project settings
For a whole project, put the settings in paper-preflight.toml next to the paper (or in a
folder above it, up to the repository's root), or in [tool.paper-preflight] of
pyproject.toml:
ignore-rules = ["REF016"]                  # never report these rules
ignore-keys = ["internal2024*"]            # nor anything about these entries
severity = { REF015 = "info" }             # report published preprints as infos
disable-sources = ["s2"]                   # optional sources only
fail-on = "warning"                        # as --fail-on; the command line wins
check --config <path> names the file instead. The optional sources are s2, openlibrary,
github, pypi, cran, huggingface, openml, web (links to web pages) and wayback;
the registries that judge a reference cannot be turned off. A mistake in the file (an unknown
rule or setting) is an error, never silently ignored. The JSON report names the file in
run.notes, and the MCP server reads it too.
Silence a finding you have checked
A comment directly above an entry silences rules for that entry, with an optional reason:
% preflight: ignore[REF003] reason="internal technical report, not indexed anywhere"
@techreport{lab2024internal,
  ...
}
The verdict stays in the JSON report; only the finding is dropped. A suppression that silenced nothing is reported as CFG001 (info), so stale comments do not pile up (for reference rules, only after a complete online run, since offline answers and outages may leave them unrun).
A finding you believe is wrong: where false alarms come from, and what to do.
Better results with free credentials
paper-preflight works without any account. These optional environment variables make it faster and more complete; their values are never printed or logged.
| Variable | Effect |
|---|---|
PAPER_PREFLIGHT_EMAIL |
Crossref's polite pool: faster, more reliable lookups |
OPENALEX_API_KEY |
A larger OpenAlex budget for retraction checks |
S2_API_KEY |
Semantic Scholar as a rescue source for references nobody else found |
GITHUB_TOKEN |
GitHub's larger budget (5,000 requests an hour, not 60) for references to repositories |
NCBI_API_KEY |
PubMed's larger budget (10 requests a second, not 3) for PMIDs and PMCIDs |
paper-preflight doctor shows which are set and whether each source answers right now.
Use it in your workflow
Claude Code: install the plugin. It bundles an MCP server and a skill that makes Claude check the references before calling a paper finished, fix only what is proven wrong, and never invent a reference.
claude plugin marketplace add amos689/paper-preflight
claude plugin install paper-preflight@paper-preflight
Codex, Gemini CLI, Copilot, Cursor and other agents: install the same skill
(gh skill install amos689/paper-preflight paper-preflight works too). It runs the CLI when no
MCP server is configured:
npx skills add amos689/paper-preflight
MCP clients (Codex, Cursor, VS Code, …): run paper-preflight mcp (the mcp extra). The
tools are read-only and confined to your workspace; see docs/mcp.md.
GitHub Actions: uses: amos689/paper-preflight@main checks the paper on every push, with
the report in the job summary and optional code-scanning alerts; see
docs/github-action.md.
pre-commit: check citation keys and cached verdicts on every commit in seconds; see docs/pre-commit.md.
Python:
import paper_preflight

report = paper_preflight.check_paper("paper/")
for ref in report.references:
    print(ref.key, ref.verdict, [f.rule for f in ref.findings])
The results are plain, frozen dataclasses; see docs/python-api.md.
Experimental: find the passage behind each citation
support looks in each cited work for a passage that says what the citing sentence claims. It
reads the work's text (the arXiv source, an open-access full text or PDF, or else the abstract)
and a small local model (HHEM-2.1-open, 0.4 GB) scores the passages ranked best for the claim.
It needs the support extra.
paper-preflight support path/to/paper --download-model --all
--download-model fetches the model's weights once; --all also lists the confirmed citations
with their quotes. arxiv:<id> works as a target, as it does for check.
- What it says: "confirmed", with the passage quoted word for word, or "could not confirm", with the reason (no text, only the abstract, or no passage close enough).
- It never calls a citation wrong. On a gold set of 298 citations, 93% of its
confirmations were right [95% CI 82%, 98%], but it confirms only about one real citation in
six, and a low score pointed at a mis-citation less than half the time. The gold set's labels
were made by AI models, not experts; see
evals/results/support.md. - Or let your agent judge. The MCP tool
preflight_cited_passagesreturns each claim with the cited work's best passages, for the agent to judge by the same rules, without the model. On 100 gold-set citations, a Claude agent judging from it confirmed 39% of the real ones, against HHEM's 9%, every confirmation at least partly supported (the labels come from the same model family). - What leaves your machine: only the cited works' identifiers, to fetch their text; the claims are scored locally.
How it works
- Source-first. It reads the LaTeX project as LaTeX sees it: comments,
\iffalseblocks and\includeonlyare respected,.auxfiles are used when they are fresh, and the first definition of a duplicated key wins, as in BibTeX. - Identifier-first routing. DOIs go to their registration agency (doi.org tells which: Crossref, DataCite, …). arXiv IDs go to arXiv, with DataCite as a fallback, and PMIDs and PMCIDs to PubMed, which also marks retracted articles. Entries without identifiers are searched by title in dblp and Crossref; dblp through its SPARQL endpoint, since its search API is behind a bot challenge. Which source is asked what, and how politely: docs/sources.md.
- Field-by-field matching with guards. Titles (including earlier arXiv versions'), authors (tolerating transcriptions such as Reiß/Reis), year and venue are compared. A search result is used only when enough of these agree and no other work fits as well; known fake DOI copies are skipped.
- One verdict per reference, as in What it checks. "Not found" needs every required source to answer "no".
- Cached locally. Answers are kept in a SQLite file, so re-runs are fast and
--offlineworks.
Design principles
- Positive confirmation or abstain. Rate limits, outages and unindexed works lead to "cannot determine", never to "not found".
- No LLM in the verdicts. Every verdict comes from records and fixed rules, so the same records give the same report.
- Neutral wording. Findings state observations ("not found in Crossref, dblp and Semantic Scholar, and every source responded"), never accusations.
- Local-first, no telemetry. Only the metadata of the cited works (DOIs, titles, authors) is sent to the public scholarly APIs above. Your manuscript never leaves your machine.
What it will never do
Help evade plagiarism or AI-text detection, scrape paywalled or bot-protected sites, recommend or "complete" references from memory, or name and shame authors.
Roadmap
- Next: references in Chinese script, measured on held-out papers before anything ships.
- Fewer references left undecided among grey literature (reports, theses, manuals) without an identifier.
What each release brought is in the changelog; day-to-day progress in docs/PROGRESS.md (in Chinese).
Contributing
Bug reports with a reproducible .bib entry are the most valuable contribution, especially
false positives. See CONTRIBUTING.md; security issues:
SECURITY.md.
License
MIT. See THIRD_PARTY_NOTICES.md for adapted code.
1 maintainer

Metadata
1 maintainer
Release files for paper-preflight 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| paper_preflight-1.0.0.tar.gz | 2.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| paper_preflight-1.0.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.5 MB
Release files / paper_preflight-1.0.0.tar.gz
| Download URL | paper_preflight-1.0.0.tar.gz |
|---|---|
| Size | 2.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7cd5f0485819175b7e09b1b86e59c18f55e2664206a94ad5ffe88f0994898959
|
|
BLAKE2b-256 checksum How to use checksums |
4933e5a32c5f421908d7d7e6ebcd32e321c322395e7a9db59e94b9bb3a4f1aa5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency logRelease files / paper_preflight-1.0.0-py3-none-any.whl
| Download URL | paper_preflight-1.0.0-py3-none-any.whl |
|---|---|
| Size | 297.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
61049c4f8bd62f516473036f48e61b35638266e834781846556b49b8af75a13c
|
|
BLAKE2b-256 checksum How to use checksums |
98bab8e3c4050ce79ea718b6e5babd68f1164a4ad285e13cd93896ae6292cee1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 15, 2026.
Transparency log













