
paper-repro
Point your agent at a paper's code; it gets it running and tells you whether the headline number reproduces, with the evidence.
uvx paper-repro setup --yes # register the MCP server and skill with Claude Code, Codex, Cursor
Then start a new agent session and ask:
Does karpathy/nanoGPT actually reproduce the loss of 1.88 its README claims for the small CPU Shakespeare run? I'm on a MacBook, CPU only.
No agent handy? See what it finds in a repo, in a few seconds, without installing anything:
uvx paper-repro inspect karpathy/nanoGPT
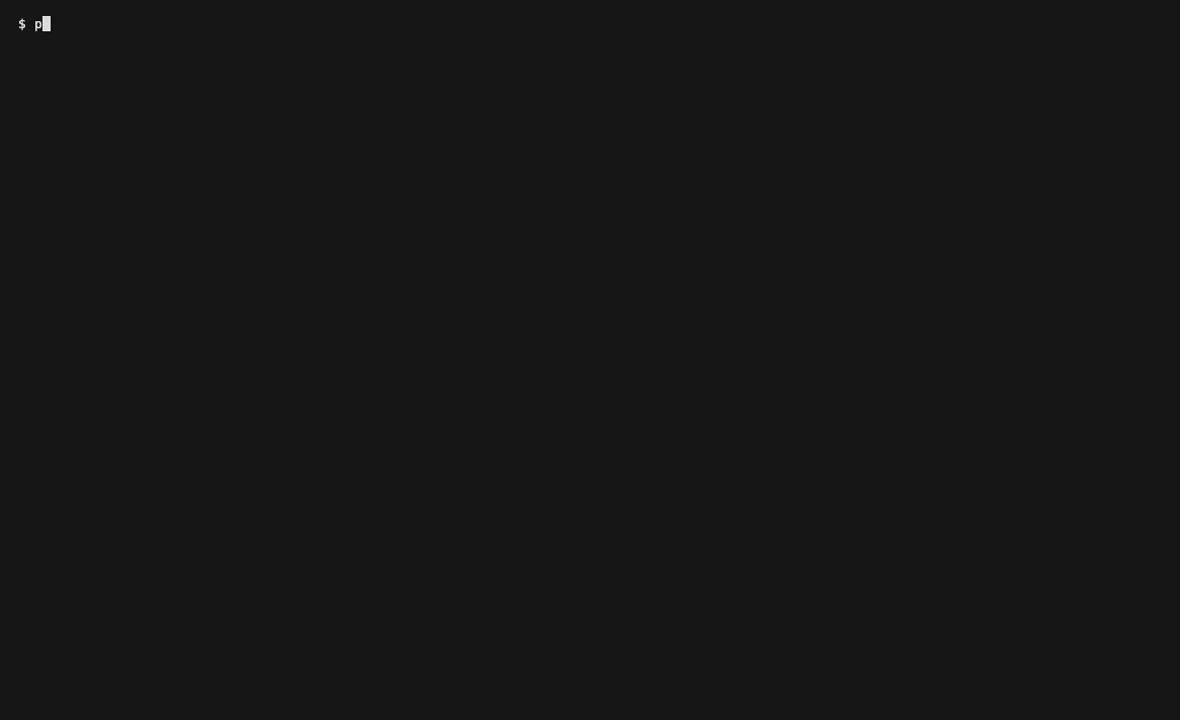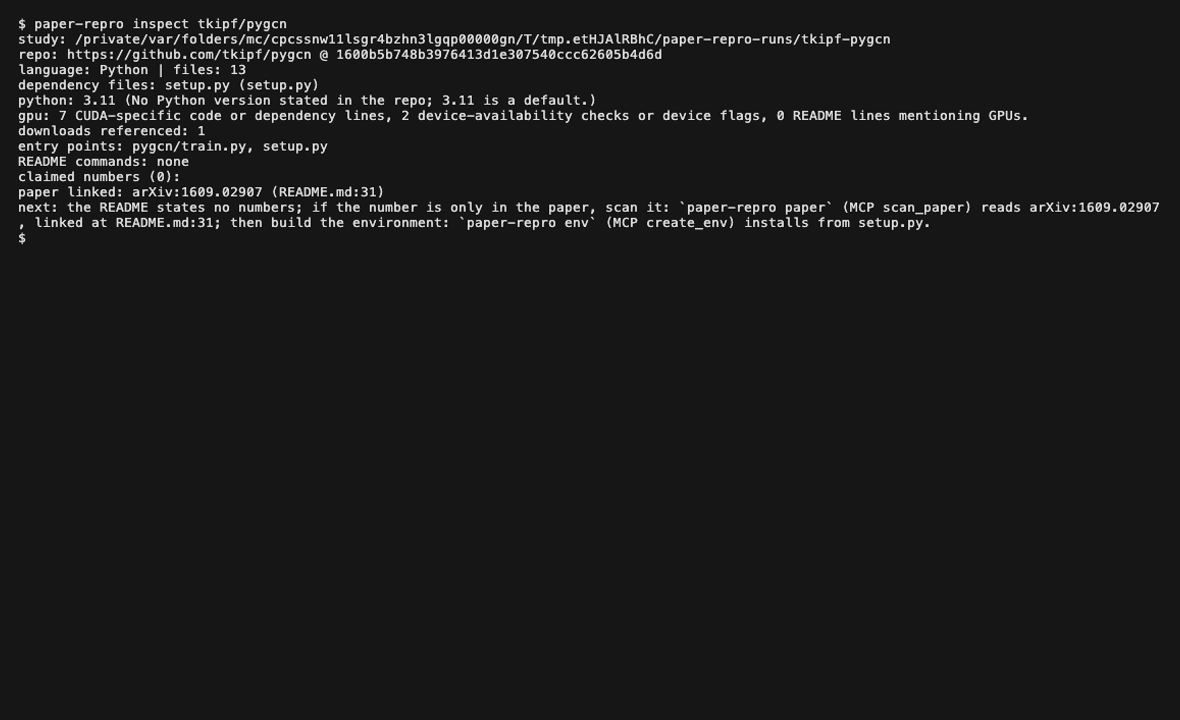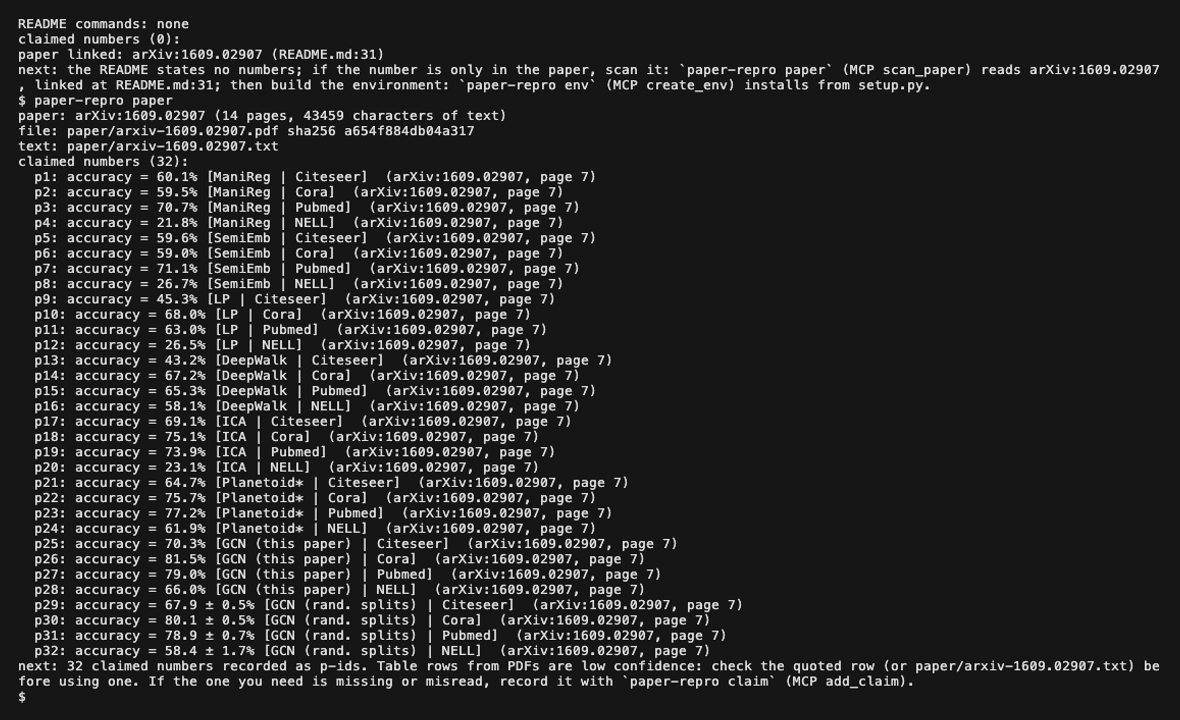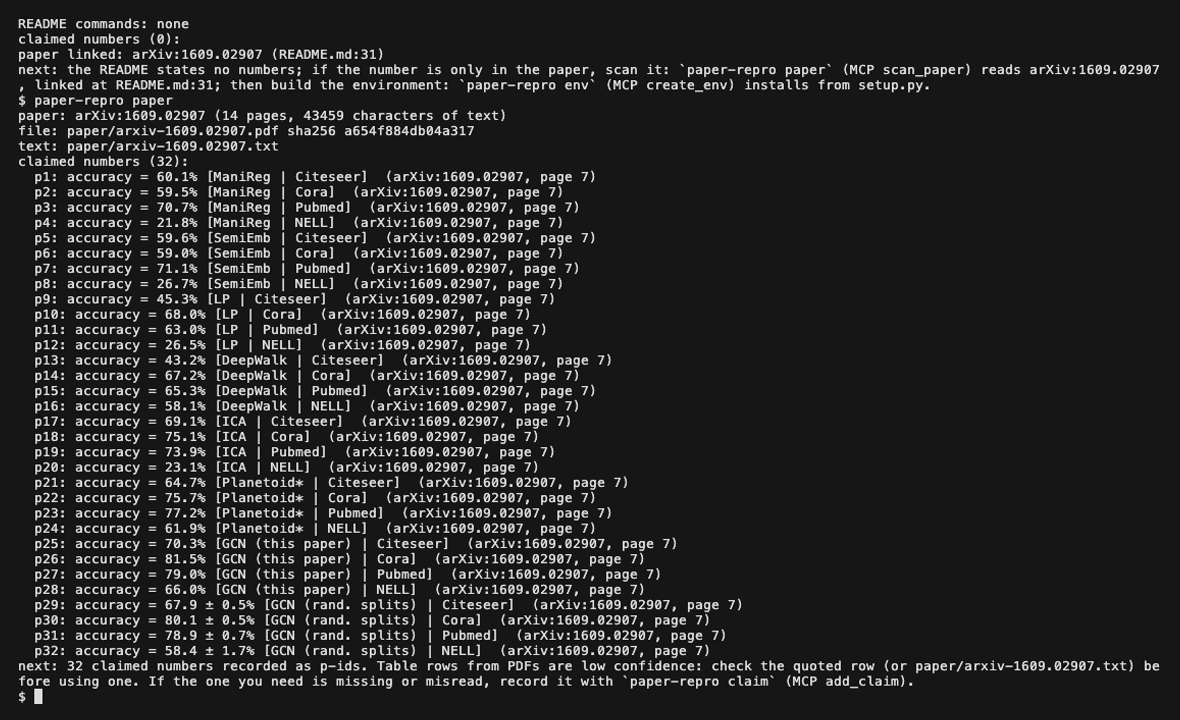
(A real recording: inspect finds no number in the pygcn README but a linked arXiv paper, and
paper pulls the results table out of it.)
Papers with Code went offline on 24 July 2025, taking its 79,817 paper-to-code links with it (shutdown record). There's no common place that tracks whether a paper's released code actually reproduces the numbers in the paper. Research benchmarks for this exist (CORE-Bench, PaperBench), but they score agents, not papers. paper-repro is the user-facing half: it gives a coding agent reliable operations to clone a repo, build its environment, run it, pull numbers out of the logs and compare them with the claim (from the README or from the paper itself), and it writes everything down so a person can check the verdict without trusting the agent.
Use it with your agent
After setup, you don't call paper-repro yourself. Ask your agent a question about a repo and a
number; the skill tells it the workflow and the MCP tools do the work. Two real headless Claude
Code sessions on this machine (Apple M4, CPU only), with nothing but the skill and the MCP server
loaded:
"Can you check whether tkipf/pygcn reproduces the Cora accuracy reported in the GCN paper? I'm on a laptop with no GPU." (paper-repro 0.1.1, 22 turns, about 15 minutes, most of it five 200-epoch training runs)
The pygcn README states no numbers, so the agent read the paper:
inspect_repo  {"source": "tkipf/pygcn"}
scan_paper    {}          -> arXiv:1609.02907 (linked at README.md:31), 32 claims from Table 2
create_env    {"python": "3.11"}
run_command   {"command": "cd pygcn && python train.py --no-cuda --epochs 2", "scope": "smoke"}
run_command   {"command": "cd pygcn && python train.py --no-cuda --seed 42", "scope": "full", ...}
              ... seeds 1, 2, 3, 4
extract_metrics {"run_ids": ["r2", "r3", "r4", "r5", "r6"], "names": ["accuracy"]}
compare_claim {"claim_id": "p26", "measured": ["m1:accuracy:last@each"], "tol": 1, "why": "..."}
  -> Close: accuracy claimed 81.5%, measured 83.34% (mean of 5 runs), 1.84 away: outside the
     tolerance of ±1 but inside the close band of ±3.
write_report  {}
From its answer to the user:
pygcn's Cora accuracy is close to the paper's number, but not a clean reproduction: it comes out about 1.8 points higher. [...] Why it doesn't match exactly: the repo isn't trying to match the paper. Its README (line 12) says it "is not intended for reproduction of the results reported in [1]." [...] it trains on the first 140 nodes in file order, validates on nodes 200-499 and tests on 500-1499 (
pygcn/utils.py:41-43). The paper uses the standard split with 20 labels per class.
"Does karpathy/nanoGPT actually reproduce the loss of 1.88 its README claims for the small CPU
Shakespeare run?" (paper-repro 0.1.0, 15 turns, 103 seconds): the agent picked claim c2,
built the environment from the README's pip install line, prepared the data, did a 5-step
smoke run, then the exact README command (47 seconds), and answered:
Yes. I ran the README's CPU command exactly as written, and the final val loss was 1.8857, against the README's claimed 1.88. [...] Train or val loss: the README says "a loss of only 1.88" without saying which. I compared against val loss, since train loss (1.76) is well below 1.88.
Both left a report.md with the commands, logs, hashes, environment and what was not checked.
Example output
A real run on this machine (Apple M4, macOS, CPU only) driven from the CLI against
karpathy/nanoGPT at commit 3adf61e. Its README says the
small CPU configuration of the Shakespeare character model "gets us a loss of only 1.88". The full
evidence bundle is in examples/nanogpt-shakespeare-char-cpu.
$ paper-repro inspect https://github.com/karpathy/nanoGPT
claimed numbers (12):
  c1: best validation loss = 1.4697  (README.md:51)
  c2: loss = 1.88  (README.md:88)
  c3: loss = 2.85  (README.md:121)
  ...
$ paper-repro env --python 3.12 --from-readme
$ paper-repro run --scope setup -- python data/shakespeare_char/prepare.py
$ paper-repro run -- "python train.py config/train_shakespeare_char.py --device=cpu --compile=False --eval_iters=20 ..."
r3: exit 0 in 236.5s, peak memory 194.6 MB, 1 files written
$ paper-repro metrics --run r3 --run r4 --name val_loss
$ paper-repro compare --claim c2 --measured 'm1:val_loss:last@each' --why '...'
k1: REPRODUCED
Reproduced: loss claimed 1.88, measured 1.8857 (mean of 2 runs), 0.0057 away, within the tolerance of ±0.0188.
  - Claim: loss 1.88 (README.md line 88).
  - Measured over 2 runs: mean 1.8857, std 0, min 1.8857, max 1.8857.
  - Distance from the claim: 0.0057 (0.3% of the claim).
  - The measured value is worse than claimed (higher, and lower is better for this metric).
  - Tolerance: ±0.0188 (1% of the claimed value, default). Close band: ±0.0564.
The runs were made with 0.1.0; the compare output above is 0.1.1 re-reading the same recorded
runs. The report also lists what was not checked: the A100 claim (1.4697), the GPT-2 numbers, the
checksums of downloaded data, and that the seed is hard-coded, so the two runs measure
determinism (identical losses at every eval step) rather than seed variance.
How it works
paper-repro is a recorder, not a brain. It never calls a model. Your agent (Claude Code, Codex, Cursor) decides what to run; paper-repro does it the same way every time and keeps the receipts.
| Step | What it does | Tools it drives |
|---|---|---|
inspect |
Shallow-clones the repo (or copies a local path), records the commit SHA, finds dependency files, Python version hints, README commands and pip install lines, entry points and their flags, data and weight downloads, GPU hints, and every number the README claims (table cells, sentences, ranges, ± values), each with file and line. |
git |
paper |
Downloads the paper from arXiv (the one the README links, or any id, URL or local PDF/text file), saves its text, and records the numbers it states as p1, p2, ... Results tables are rebuilt from word positions: each cell keeps its table, page, exact row and column labels (a two-level header becomes BLEU EN-DE) and a confidence with notes. The rebuilt tables are saved as Markdown next to the text. |
pypdf (text), pdfminer.six (word positions) |
env |
Creates an isolated virtualenv per study and installs the repo's own dependency file with pins as written. Conda environment.yml files are translated to pip. --unpin, --extra, --from-readme and a different Python are allowed but recorded as deviations. Writes lock.txt from uv pip freeze. On failure, records the exact error. |
uv venv, uv pip |
run |
Runs one shell command from the repo root inside that env. Captures stdout and stderr to files with SHA-256, exit code, wall time, CPU time, peak memory, every file created or modified, and a copy of small result files as they were when the run ended. Timeout kills the whole process tree. Each run is labeled full, shortened (needs a note saying what was cut), smoke or setup. |
your shell, POSIX rlimits |
metrics |
Extracts values like accuracy: 0.913, acc=91.3%, F1 81.2, val loss 1.8857, Accuracy: 9897/10000, plus JSON, JSON lines and CSV results, each with its source file, line and text. Select one with m1:val_loss:last, or one per run with m1:val_loss:last@each. |
|
compare |
Puts measured values next to the claim and gives one of five verdicts: reproduced, close, not reproduced, inconclusive (any value came from a smoke or shortened run), could not run. Handles percent versus fraction, ranges, ±, repeated runs (mean, std, min, max) and the rounding of the stated value. Default tolerance is 1% relative, close band 3x that; pass your own with a reason. A shortened run or a hand-typed value never counts as a reproduction. Comparing a claim again supersedes the earlier verdict, which stays in the report. |
|
report |
Writes report.md (the shareable artifact) and report.json from the evidence log only: repo URL and commit, machine, Python and key package versions, every command with exit code and duration, the claim, measured values with source lines, the reasoning, deviations, and what was not checked. |
Every step prints a next: line (a next field in JSON and MCP results) with the usual next
step, and every step appends to evidence.jsonl, a hash-chained log. paper-repro verify rechecks the
chain and the hashes of captured outputs, so an edited log or a swapped stdout file shows up.
A study directory looks like this:
paper-repro-runs/karpathy-nanoGPT/
  repo/            the checkout
  env/             the virtualenv
  runs/r3/         stdout.txt, stderr.txt, files/ (results as the run left them)
  lock.txt         resolved packages
  evidence.jsonl   the log everything else is derived from
  paper/           the paper PDF and its extracted text, if you scanned it
  report.md        the verdict and evidence, for people
  report.json      the same, for programs
paper-repro report --bundle DIR copies the shareable parts (no checkout, no env) to DIR.
CLI
The second example, examples/pygat-cora, was produced with these commands against Diego999/pyGAT, whose README says "The final accuracy is between 84.2 and 85.3 (obtained on 5 different runs)":
paper-repro inspect Diego999/pyGAT
paper-repro env                      # fails: README asks for Python 3.5, which uv does not support
paper-repro env --python 3.12        # fails: torch==0.4.1.post2 has no wheel for this machine
paper-repro env --python 3.12 --unpin
paper-repro run --scope smoke --note "2 epochs ..." -- python train.py --epochs 2
paper-repro run --seed 72 --timeout 10800 --note "..." -- "rm -f *.pkl && python train.py --seed 72"
paper-repro run --seed 1 ...  &&  paper-repro run --seed 2 ...
paper-repro metrics --run r2 --run r3 --run r4 --name accuracy
paper-repro compare --claim c1 --measured 'm1:accuracy:last@each' --tol 0.1 --close-tol 1.0 \
  --why "Cora's test split has 1000 nodes, so accuracy moves in steps of 0.1 points; ..."
paper-repro note --kind not_checked "The README's range comes from 5 runs; 3 seeds were run here ..."
paper-repro report --bundle examples/pygat-cora
Result: test accuracy 84.2, 84.7 and 84.2 over three seeds, mean 84.37, inside the claimed range, verdict reproduced. Both failed environment attempts, the Python and unpinning deviations, and the fact that only 3 of the authors' 5 runs were repeated are all in the report.
When the number is only in the paper, paper-repro paper reads it. Real output (0.1.2, trimmed)
for the Transformer paper, whose Table 2 has a two-line header (BLEU over EN-DE EN-FR):
$ paper-repro paper 1706.03762
paper: arXiv:1706.03762 (15 pages, 39496 characters of text)
file: paper/arxiv-1706.03762.pdf sha256 bdfaa68d8984f0dc
text: paper/arxiv-1706.03762.txt
tables: paper/arxiv-1706.03762.tables.md (3 rebuilt)
claimed numbers (69):
  p1: BLEU = 23.75 [ByteNet | BLEU EN-DE]  (arXiv:1706.03762, page 8, Table 2, high)
  ...
  p16: BLEU = 28.4 [Transformer (big) | BLEU EN-DE]  (arXiv:1706.03762, page 8, Table 2, high)
  p17: BLEU = 41.8 [Transformer (big) | BLEU EN-FR]  (arXiv:1706.03762, page 8, Table 2, high)
  p18: PPL = 4.92 [base | PPL (dev)]  (arXiv:1706.03762, page 9, Table 3, high)
  ...
The training-cost columns of that table are not listed (they are not results), and in 0.1.1 the same cells came out with no column name at all.
Reading tables from PDFs
pypdf's plain text loses the layout, so paper rebuilds each results table from word boxes
(pdfminer.six): it finds the Table N caption, takes the tabular lines above or below it within
its page column, places columns by the x-position of the numbers, and names each column from
every header line above it. It handles captions below the table, stacked tables, two-level
headers, section rows ("Ours", "Published"), blank cells that repeat the label above,
\multirow labels, ± spreads, a/b cells and drawn column rules. Columns that describe the
setup (depth, params, cost) are not claims; they name rows that would otherwise repeat, as in
DenseNet (k = 12) (Depth 40).
Each claim gets a confidence score from 0 to 1 (high, medium or low) with notes saying what lowered it, for example "metric named only in the caption" or "row label taken from a neighbouring row".
Measured on a regression set of 13 tables from 8 arXiv papers, with every expected cell
transcribed by hand from the rendered pages (tests/data/tables/expected.json, scored with
scripts/table_regression.py). A claim is correct only when its table, row label, column label
and value all match.
| Reader | Tables | Precision | Recall |
|---|---|---|---|
| 0.1.1 (plain text) | 9 dev tables, 212 cells | 76/119 = 0.64 | 76/212 = 0.36 |
| 0.1.2 (word positions) | the same 9 dev tables | 212/212 = 1.00 | 212/212 = 1.00 |
| 0.1.1 (plain text) | 4 held-out tables, 151 cells | 0/2 | 0/151 |
| 0.1.2, first run on held-out | the same 4 tables | 47/141 = 0.33 | 47/151 = 0.31 |
| 0.1.2, after fixing what they showed | the same 4 tables | 150/152 = 0.99 | 150/151 = 0.99 |
The dev tables (Transformer, GCN, GAT, BERT, ResNet) were used while building the reader, so 1.00 there is not an estimate of accuracy on new papers. The held-out tables (ViT, DenseNet, ELMo) were transcribed before the reader first saw them; the 0.33 is that first, honest number, and the reader was then fixed against them, so they are no longer held out either. Expect unseen papers to land somewhere in between, and check medium and low claims.
Every subcommand takes --json. paper-repro status shows what a study has recorded so far.
Setup for agents
uvx paper-repro setup          # shows what it would change, asks before applying
uvx paper-repro setup --yes    # apply without asking
It detects each agent and, for the ones present:
- Claude Code:
claude mcp add --scope user paper-repro -- uvx paper-repro mcp, and copies the skill to~/.claude/skills/paper-repro/SKILL.md. Use--project DIRto write a project.mcp.jsoninstead. - Codex: adds
[mcp_servers.paper-repro]to~/.codex/config.tomland copies the skill to~/.codex/skills/paper-repro/. - Cursor: adds
paper-reprotomcpServersin~/.cursor/mcp.json.
It backs up any file it edits (*.bak-paper-repro-<time>) and does nothing on a second run.
Start a new agent session afterwards so it picks up the server.
Manual registration is the same command everywhere: uvx paper-repro mcp over stdio.
The skill (skills/paper-repro/SKILL.md) is the workflow the agent follows: inspect, pick one claim and say why, check feasibility, set up the env with the least invasive fix, run the smallest faithful configuration first, extract, compare with a tolerance it can defend, report. It also sets the rules: never fabricate or estimate a number, never change the method to make a run succeed, and report "could not run" with the blocking error instead of pushing through.
What it can't do
- It does not judge whether the code implements the method in the paper. It checks the code's output against a stated number, nothing more.
- No GPU orchestration. On a machine without the GPU the paper used, GPU-only claims end as "could not run" or as shortened CPU runs that never count as reproductions.
- No container builds yet. A Dockerfile is detected and reported but not built; environments
are Python virtualenvs. R, Julia and other languages are detected but
envonly builds Python environments (you can stillruncommands that use a system R or Julia). - Conda environments are translated to pip, which can resolve different builds than conda would. The translation is recorded as a deviation.
- Claim detection in the README is reliable for tables and plain sentences. Reading the paper
(
paper-repro paper) needs a text PDF: scanned pages and tables embedded as images yield nothing. Tables need aTable N:orTable N.caption; rotated tables, tables split over two pages and tables whose row labels wrap onto a second line are not handled, and when a cell holds two values (88.4/88.5) only a header likeMNLI-(m/mm)or ana / bphrase in the caption names them. Sentences in the paper are only read formetric: valuestyle claims, so "a BLEU score of 28.4" in prose is not picked up; the table is. When a claim is wrong or missing, add it withpaper-repro claim --source "paper Table 2". Only arXiv is fetched automatically; for other papers pass a local PDF. - Metric extraction is pattern-based. Unusual log formats may need
--fileon a results file or a careful choice among the extracted values; the report always shows the exact source line. - Memory limits are only enforced on Linux; on macOS peak memory is recorded but not capped.
- Runs share one checkout. Runs started at the same time get separate ids and records, but their timings and written-file lists can mix, and the report says so.
- The default tolerance (1% relative) is a convention, not a statistical test. Choose one per claim and say why.
Privacy and safety
Everything runs on your machine. paper-repro sends nothing anywhere and has no telemetry. The
only network traffic is what you ask for: git clone, uv downloading packages, the paper PDF
from arxiv.org when you run paper, and whatever the repository's own scripts download.
That last part matters: running a paper's code means running a stranger's code with your user's permissions. paper-repro isolates the Python environment and can cap time and CPU, but it is not a sandbox. For code you do not trust, run it inside a VM or a disposable container.
License
MIT, see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for paper-repro 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| paper_repro-0.1.3.tar.gz | 652.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| paper_repro-0.1.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 744.8 kB
Release files / paper_repro-0.1.3.tar.gz
| Download URL | paper_repro-0.1.3.tar.gz |
|---|---|
| Size | 652.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c6a69cbca48acfba7d80f5495560a6953121b7bf059c0e0a8eba4b1678eb4f16
|
|
BLAKE2b-256 checksum How to use checksums |
d401fb7d55123d9c4e4a3eeaad15b266f02f5c03c3ecafa34feee1c7ee888aa0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency logRelease files / paper_repro-0.1.3-py3-none-any.whl
| Download URL | paper_repro-0.1.3-py3-none-any.whl |
|---|---|
| Size | 92.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7c8651fb8b28bf2fd582f92a2cefdcefe6499ec2aa136623b88c33695769c4b0
|
|
BLAKE2b-256 checksum How to use checksums |
4994fe8d1bd767ca80adf77a8afac646303ec468cad04e0207eb62c5aecae52b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 9, 2026.
Transparency log













