
lucky
hyperfine, but for pass rates. Is it better, or did you get lucky?



You tweak a prompt. You run your eval. 6/6. Before the tweak it was 2/6. Ship it!
That really happened to me. Same prompt, same model, same eval, run twice with no changes: 2/6, then 6/6. Nothing got better. I got lucky.
# lucky's verdict on those two runs (2/6 vs 6/6):
#1 vs #2: No detectable difference (p=0.061). To detect a gap this size, run ~n=10 each.
Pass rates lie at small n, and we all read them anyway: prompt tweaks, model swaps, agent configs, "is this flaky test fixed now?". lucky runs the thing enough times and tells you what you actually know.
Use it
uvx --from git+https://github.com/sandeepsirodia/lucky lucky -n 20 './eval.sh --model a' './eval.sh --model b'
#1: ./eval.sh --model a
  17/20 passed (85%, 95% CI 64–95%)   flaky (17/20 passed)

#2: ./eval.sh --model b
  12/20 passed (60%, 95% CI 39–78%)   flaky (12/20 passed)

#1 vs #2: No detectable difference (p=0.16). To detect a gap this size, run ~n=57 each.
85% vs 60% looks like a blowout. It isn't one yet. lucky tells you how many more runs it would take to know.
Any command that exits 0 on success works: tests, evals, scripts, curl health checks, agent runs.
Is my test flaky, or did I fix it?
lucky -n 50 -j 8 'pytest tests/test_checkout.py -x -q'
50/50 passed (100%, 95% CI 93–100%) stable pass
"Passed 3 times in a row" means very little. 50/50 with a 95% interval of 93–100% is a claim you can put in a PR description.
Everything it does
lucky -n 20 'cmd' |
Pass rate + 95% Wilson interval + stable pass / stable fail / flaky |
lucky 'a' 'b' 'c' |
Every pair compared with Fisher's exact test, Holm-corrected for 3+ commands |
-j 8 |
Parallel runs. Each gets $LUCKY_RUN (0, 1, 2…) |
--until-decided |
Stop early once the answer is clear, without cheating (see below) |
--timeout 60 |
Hung runs count as fails, and their whole process tree is killed |
--pass-if-stdout 'PASS' |
For commands that exit 0 but print the verdict |
--json · --export-markdown r.md |
For CI and PR descriptions |
Runs are interleaved (A, B, A, B…), so if your API gets slower at 3pm, both commands feel it equally.
Peeking is cheating, and here's the number
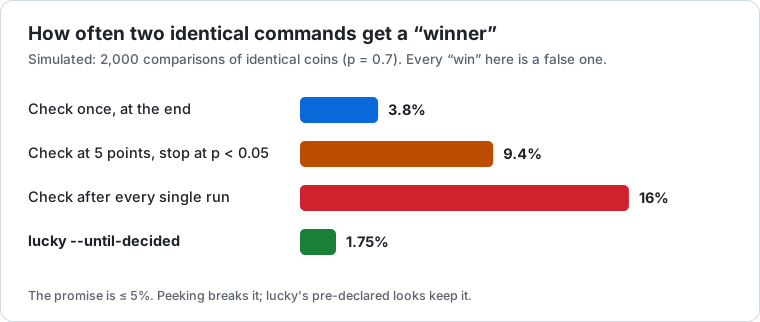
The tempting move: run a few, check, run a few more, check again, stop when it looks significant. That inflates false wins. I simulated two identical coins, checking for a "significant" difference:
| Strategy | False "B is better" rate |
|---|---|
| Check once at the end | 3.8% (Fisher's test is slightly conservative, so it stays under the promised 5%) |
| Check at 5 points, stop when p < 0.05 | 9.4% |
| Check after every single run | 16% |
--until-decided checks at 5 pre-declared points and splits the 5% error budget across them. Simulated false-positive rate: 1.75%, and it still catches real gaps (0.9 vs 0.4) over 90% of the time. The simulation is a test that runs in CI.
No magic, no dependencies
Every statistic is implemented in lucky.py with the standard library and checked in tests against independent references:
- the Wilson interval against published values
- Fisher's exact test against brute-force enumeration over 200 random tables
- Holm against a worked example
- the sample-size estimate (Fleiss continuity correction) against the formula, and by simulation: at the suggested n, a real gap is actually detected about 80% of the time
It's one file. Read it in a sitting.
Honest limits
- It answers "is there a detectable difference?", not "how big is the real difference?". Look at the two intervals for that.
- It assumes runs are independent. If your command caches results between runs, lucky can't know.
--until-decideduses a simple, conservative stopping rule (Bonferroni across looks). It's safe, but it stops later than fancier designs would.
Prior art, and what's new here
- hyperfine is the inspiration for the interface. It measures time; lucky measures pass rates.
- Flaky-test rerunners (pytest-flakefinder, flaky,
go test -count) rerun tests inside one framework. Use them if you live in that framework. - Eval statistics libraries (evalstats, evalci) are Python libraries you call on results tables, and they're more complete statistically.
lucky's niche is narrow on purpose: any command, from the shell, with a verdict, plus early stopping that doesn't cheat.
Development
python -m unittest discover -s tests -v
Tests map 1:1 to SPEC.md. Installed as a package it's called passrate (the name lucky was taken on PyPI); the command is still lucky.
MIT © Sandeep Sirodia · If lucky just saved you from shipping a coin flip, a ⭐ helps the next person find it.
1 maintainer

Release files for passrate 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| passrate-0.1.0.tar.gz | 11.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| passrate-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 21.1 kB
Release files / passrate-0.1.0.tar.gz
| Download URL | passrate-0.1.0.tar.gz |
|---|---|
| Size | 11.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
571e0c7e9bcfc03c2e7a9e2b702e022f9e00a3bfe2693640edbd97cdc28b213c
|
|
BLAKE2b-256 checksum How to use checksums |
9b42ba014f632267265204c0cc642d0503989d5226fb285c9d43a173fc1a3e0b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / passrate-0.1.0-py3-none-any.whl
| Download URL | passrate-0.1.0-py3-none-any.whl |
|---|---|
| Size | 9.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e2d2dac6ba6930c618e7969f301c9721a33271f734f91811a8a6199aec53f236
|
|
BLAKE2b-256 checksum How to use checksums |
fbb3339a5253048dd076ecc369b4f11dac41eb0dafa2bdde8bb5cc9616144174
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log












