
peasytext


Pure Python text processing toolkit — 15 tools for case conversion, slug generation, word counting, line sorting, Base64/URL/HTML encoding, find & replace, deduplication, line numbering, pattern extraction, text diffing, Lorem Ipsum generation, JSON formatting, and text reversal. Zero dependencies.
Extracted from the client-side engines at peasytext.com, where all 15 text tools run entirely in the browser. This Python package provides the same functionality for server-side and CLI usage.
Try the interactive tools at peasytext.com — Text Tools, Text Glossary, Text Formats
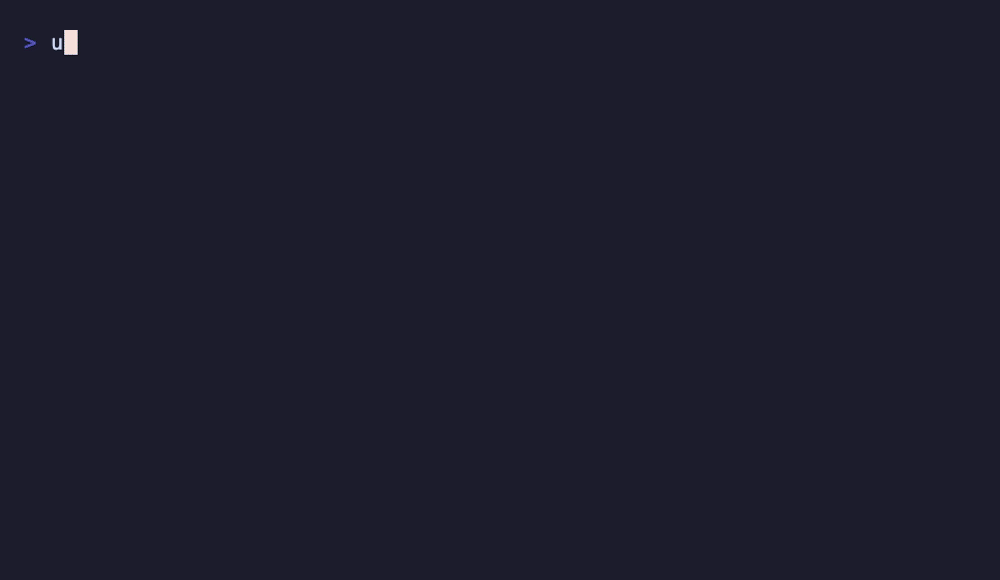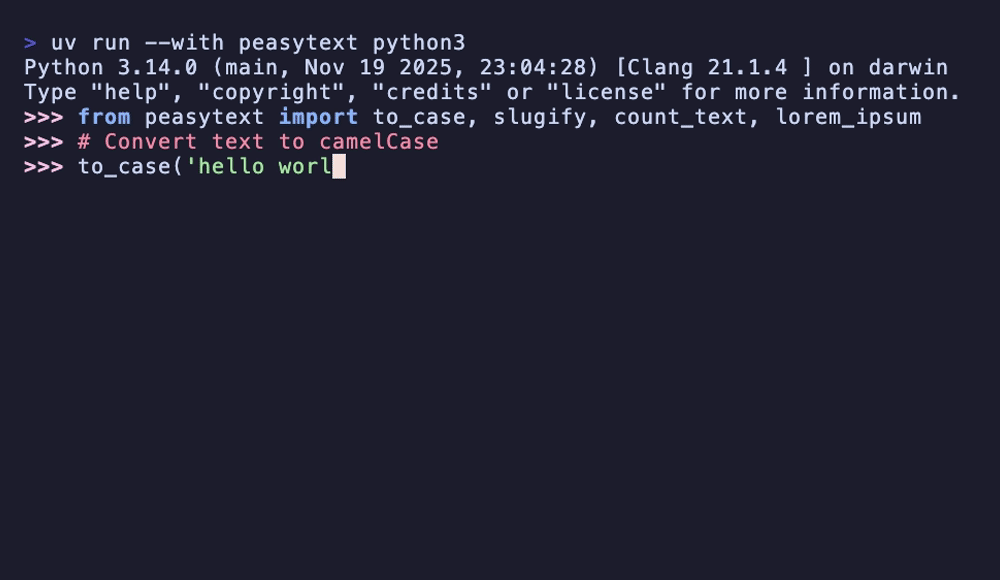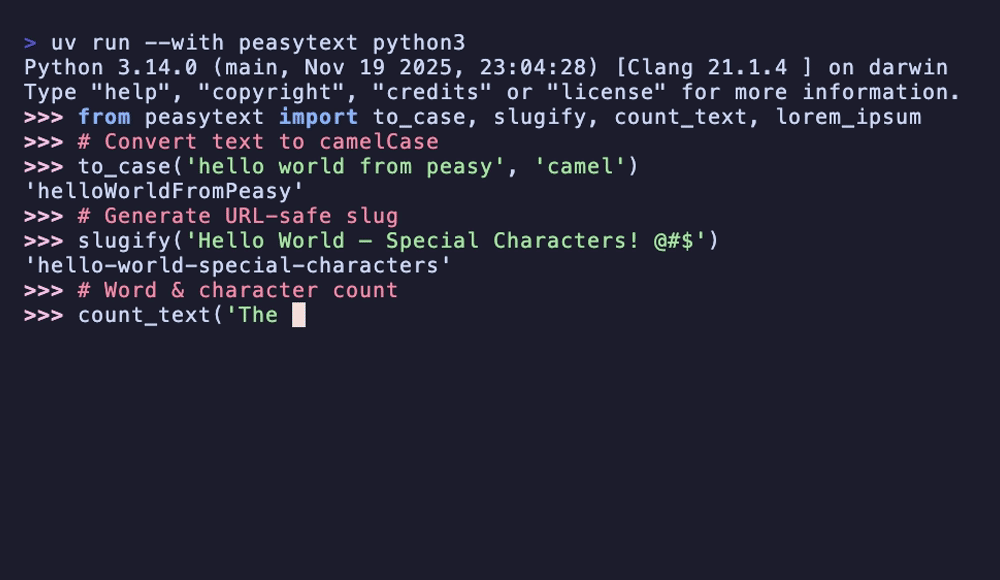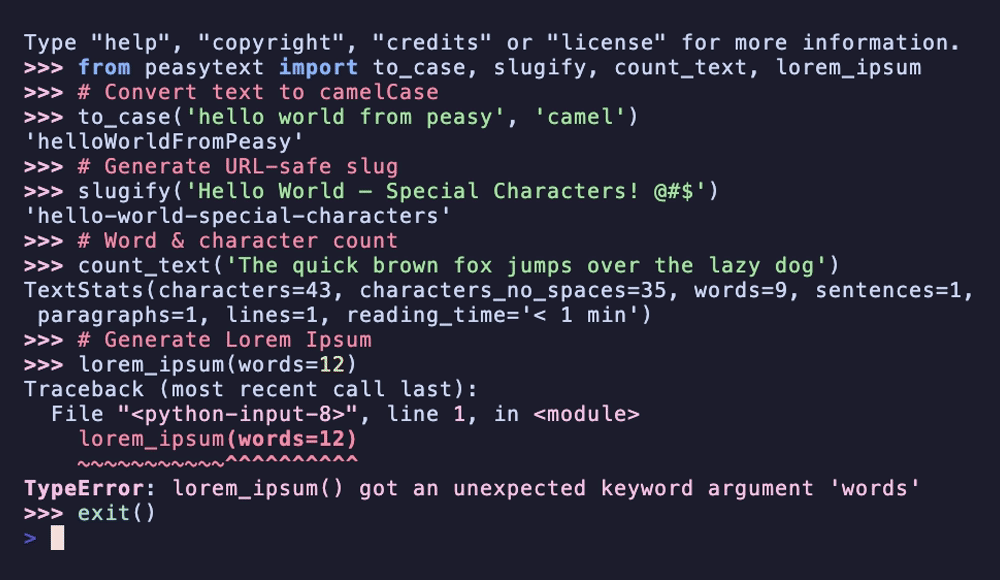
Table of Contents
- Install
- Quick Start
- What You Can Do
- Command-Line Interface
- MCP Server (Claude, Cursor, Windsurf)
- REST API Client
- API Reference
- Learn More About Text Processing
- Also Available
- Peasy Developer Tools
- License
Install
pip install peasytext              # Core (zero dependencies)
pip install "peasytext[cli]"       # + CLI (typer, rich)
pip install "peasytext[mcp]"       # + MCP server
pip install "peasytext[api]"       # + REST API client (httpx)
pip install "peasytext[all]"       # Everything
Quick Start
from peasytext import to_case, slugify, count_text, extract

# Convert text between 13 case formats
print(to_case("hello world", "pascal"))     # "HelloWorld"
print(to_case("hello world", "snake"))      # "hello_world"
print(to_case("hello world", "constant"))   # "HELLO_WORLD"

# Generate URL-friendly slugs
print(slugify("Crème brûlée recipe!"))      # "creme-brulee-recipe"

# Count words, sentences, reading time
stats = count_text("Hello world. How are you today?")
print(stats.words)          # 6
print(stats.sentences)      # 2
print(stats.reading_time)   # "< 1 min"

# Extract patterns from text
emails = extract("Contact info@example.com or admin@test.org", "emails")
print(emails)  # ["info@example.com", "admin@test.org"]
What You Can Do
Case Conversion
Convert text between 13 case formats — from basic upper/lower to programming conventions like camelCase, snake_case, and CONSTANT_CASE.
| Case | Example | Use Case |
|---|---|---|
upper |
HELLO WORLD | Constants, emphasis |
lower |
hello world | Normalization |
title |
Hello World | Headings, titles |
sentence |
Hello world | Natural text |
camel |
helloWorld | JavaScript variables |
pascal |
HelloWorld | Class names |
snake |
hello_world | Python variables |
kebab |
hello-world | CSS classes, URLs |
constant |
HELLO_WORLD | Constants, env vars |
dot |
hello.world | Package names |
path |
hello/world | File paths |
alternating |
hElLo WoRlD | Sarcasm text |
inverse |
hELLO wORLD | Inversion |
from peasytext import to_case

# Programming case conversions
print(to_case("user full name", "camel"))     # "userFullName"
print(to_case("user full name", "pascal"))    # "UserFullName"
print(to_case("user full name", "snake"))     # "user_full_name"
print(to_case("user full name", "constant"))  # "USER_FULL_NAME"
Learn more: Text Case Converter · Convert Case and Clean Text Guide · What is Case Conversion?
Slug Generation
Convert any text to a URL-friendly slug. Handles Unicode, diacritics, and special characters. Essential for SEO-friendly URLs, file naming, and database keys.
from peasytext import slugify

# Basic slugification with diacritic handling
print(slugify("Crème Brûlée — The Recipe"))  # "creme-brulee-the-recipe"
print(slugify("München Straße"))               # "munchen-strasse"

# Custom separator and length limit
print(slugify("Hello World", separator="_"))           # "hello_world"
print(slugify("A very long title here", max_length=10))  # "a-very"
Learn more: Slug Generator · Slug Generation and URL-Safe Strings · What is a Slug?
Text Statistics
Count characters, words, sentences, paragraphs, and lines. Also estimates reading time — useful for blog posts, content management, and SEO metadata.
from peasytext import count_text

stats = count_text("Hello world. This is a test.\n\nNew paragraph here.")
print(f"Words: {stats.words}")                # 9
print(f"Sentences: {stats.sentences}")        # 3
print(f"Paragraphs: {stats.paragraphs}")      # 2
print(f"Reading time: {stats.reading_time}")   # "< 1 min"
Learn more: Text Counter · Word Character Line Counting Best Practices · What is Word Count?
Line Sorting
Sort lines alphabetically, by length, numerically, or reverse order.
from peasytext import sort_lines

text = "banana\napple\ncherry"
print(sort_lines(text, "alpha"))        # apple\nbanana\ncherry
print(sort_lines(text, "length"))       # apple\nbanana\ncherry
print(sort_lines("10\n2\n30", "numeric"))  # 2\n10\n30
Learn more: Sort Lines Tool · How to Sort Text Lines · What is Line Ending?
Base64 Encoding
Encode and decode Base64 with full UTF-8 support — handles emoji, CJK characters, and all Unicode.
from peasytext import base64_encode, base64_decode

encoded = base64_encode("Hello, 世界! 🌍")
print(encoded)                    # "SGVsbG8sIOS4lueVjCEg8J+MjQ=="
print(base64_decode(encoded))     # "Hello, 世界! 🌍"
Learn more: Base64 Encode Decode Tool · Base64 Encoding Guide · How to Encode Decode Base64
URL & HTML Encoding
from peasytext import url_encode, url_decode, html_encode, html_decode
# URL encoding
print(url_encode("hello world")) # "hello%20world"
print(url_decode("hello%20world")) # "hello world"
# HTML entity encoding — prevent XSS
print(html_encode('<script>alert("xss")</script>'))
# "<script>alert("xss")</script>"
Learn more: URL Encode Decode Tool · HTML Entity Encoder · What is an Escape Character?
Find & Replace
Plain text and regex find & replace with case sensitivity options.
from peasytext import find_replace

print(find_replace("Hello World", "world", "Python", case_sensitive=False))
# "Hello Python"

# Regex mode — replace all numbers
print(find_replace("abc123def456", r"\d+", "NUM", regex=True))
# "abcNUMdefNUM"
Learn more: Find and Replace Tool · How to Find and Replace with Regex · Regex Cheat Sheet Essential Patterns
Deduplication
Remove duplicate lines while preserving original order.
from peasytext import dedupe_lines

print(dedupe_lines("apple\nbanana\napple\ncherry\nbanana"))
# "apple\nbanana\ncherry"
Learn more: Remove Duplicate Lines Tool · How to Remove Duplicate Lines
Line Numbers
Add or remove line numbers from text — useful for code snippets and documentation.
from peasytext import add_line_numbers, remove_line_numbers

print(add_line_numbers("first\nsecond\nthird"))
# "1: first\n2: second\n3: third"
Learn more: Line Numbers Tool · What is Plain Text? · What is Whitespace?
Pattern Extraction
Extract emails, URLs, phone numbers, IP addresses, hashtags, and @mentions from any text.
from peasytext import extract

text = "Contact info@example.com, visit https://example.com, call +1-555-0123"
print(extract(text, "emails"))   # ["info@example.com"]
print(extract(text, "urls"))     # ["https://example.com,"]
print(extract(text, "phones"))   # ["+1-555-0123"]
Learn more: Text Extractor Tool · How to Extract Data from Text · Regex Practical Guide
Text Diffing
Compare two texts line by line and measure similarity.
from peasytext import diff_texts

result = diff_texts("apple\nbanana\ncherry", "banana\ncherry\ndate")
print(result.added)       # ["date"]
print(result.removed)     # ["apple"]
print(result.similarity)  # 0.6667
Learn more: Text Diff Tool · What is Text Diff? · What is String Distance?
Lorem Ipsum
Generate placeholder text by words, sentences, or paragraphs.
from peasytext import lorem_ipsum

print(lorem_ipsum(10, "words"))       # 10 lorem ipsum words
print(lorem_ipsum(3, "paragraphs"))   # 3 paragraphs of text
Learn more: Lorem Ipsum Generator · Lorem Ipsum Placeholder Text Guide · What is Lorem Ipsum?
JSON Formatting
Format, minify, and validate JSON strings.
from peasytext import json_format, json_minify, json_validate

print(json_format('{"a":1,"b":2}'))   # Pretty-printed JSON
print(json_minify('{ "a": 1 }'))      # {"a":1}
print(json_validate('{"key": "ok"}')) # True
Learn more: JSON Formatter Tool · What is Text Encoding? · JSON Format Reference
Text Reversal
Reverse text by characters, words, or lines.
from peasytext import reverse_text

print(reverse_text("hello", "characters"))      # "olleh"
print(reverse_text("hello world", "words"))     # "world hello"
print(reverse_text("a\nb\nc", "lines"))         # "c\nb\na"
Learn more: Reverse Text Tool · What is ROT13? · What is Unicode?
Command-Line Interface
pip install "peasytext[cli]"

# Case conversion
peasytext case "hello world" --target pascal   # HelloWorld

# Slug generation
peasytext slug "Hello World!"                  # hello-world

# Word counter
peasytext count "Hello world. How are you?"

# Sort lines (pipe from stdin)
echo -e "banana\napple\ncherry" | peasytext sort

# Base64 encode/decode
peasytext base64 encode "Hello"                # SGVsbG8=
peasytext base64 decode "SGVsbG8="             # Hello

# Extract patterns
echo "Email me at test@example.com" | peasytext extract emails

# Generate Lorem Ipsum
peasytext lorem 3 --unit paragraphs

# JSON formatting
echo '{"a":1}' | peasytext json format
MCP Server (Claude, Cursor, Windsurf)
pip install "peasytext[mcp]"

# Run the MCP server
uvx --from "peasytext[mcp]" python -m peasytext.mcp_server
Claude Desktop (claude_desktop_config.json):
{
    "mcpServers": {
        "peasytext": {
            "command": "uvx",
            "args": ["--from", "peasytext[mcp]", "python", "-m", "peasytext.mcp_server"]
        }
    }
}
15 MCP tools available: text_case, text_slug, text_count, text_sort, text_base64, text_url_encode, text_html_entities, text_find_replace, text_dedupe, text_line_numbers, text_extract, text_lorem, text_reverse, text_json, text_diff.
REST API Client
pip install "peasytext[api]"
from peasytext.api import PeasyTextAPI

api = PeasyTextAPI()
tools = api.list_tools()
glossary = api.search("encoding")
spec = api.openapi_spec()

# Search the text processing glossary for technical terms
terms = api.search_glossary("unicode")
for term in terms:
    print(f"{term['term']}: {term['definition']}")

# Browse text processing guides and tutorials
guides = api.list_guides()
for guide in guides:
    print(f"{guide['title']}: {guide['url']}")

# Discover use cases for text operations
use_cases = api.list_use_cases()
for uc in use_cases:
    print(f"{uc['title']}: {uc['description']}")
API Reference
| Function | Description |
|---|---|
to_case(text, target) |
Convert between 13 case formats |
slugify(text, **opts) |
Generate URL-friendly slug |
count_text(text, **opts) |
Count words, chars, sentences, reading time |
sort_lines(text, mode) |
Sort lines by alpha, length, numeric, etc. |
base64_encode(text) |
Encode text to Base64 |
base64_decode(text) |
Decode Base64 to text |
url_encode(text, **opts) |
URL-encode text |
url_decode(text) |
URL-decode text |
html_encode(text) |
Encode HTML entities |
html_decode(text) |
Decode HTML entities |
find_replace(text, find, replace, **opts) |
Find and replace with regex support |
dedupe_lines(text, **opts) |
Remove duplicate lines |
add_line_numbers(text, **opts) |
Add line numbers |
remove_line_numbers(text) |
Remove line numbers |
extract(text, pattern_type) |
Extract emails, URLs, phones, etc. |
diff_texts(text_a, text_b) |
Compare two texts |
lorem_ipsum(count, unit) |
Generate Lorem Ipsum |
reverse_text(text, mode) |
Reverse by chars, words, or lines |
json_format(text, **opts) |
Pretty-print JSON |
json_minify(text) |
Minify JSON |
json_validate(text) |
Validate JSON |
Learn More About Text Processing
- Tools: Text Counter · Text Case Converter · Sort Lines · Lorem Ipsum Generator · Slug Generator · Find and Replace · Remove Duplicate Lines · Base64 Encode Decode · URL Encode Decode · JSON Formatter · HTML Entity Encoder · Reverse Text · Line Numbers · Text Diff · Text Extractor · All Tools
- Guides: Text Encoding UTF-8 ASCII · Regex Cheat Sheet Essential Patterns · Lorem Ipsum Placeholder Text Guide · Regex Practical Guide · Base64 Encoding Guide · Convert Case and Clean Text · Word Character Line Counting Best Practices · How to Find and Replace with Regex · Slug Generation URL-Safe Strings · Troubleshooting Line Endings CRLF LF · Troubleshooting Character Encoding · All Guides
- Glossary: ASCII · BOM · Case Conversion · Diacritics · Escape Character · Line Ending · Lorem Ipsum · Normalization · Plain Text · Slug · Text Encoding · Unicode · Whitespace · Word Count · All Terms
- Formats: TXT · CSV · JSON · HTML · Markdown · XML · YAML · All Formats
- API: REST API Docs · OpenAPI Spec
Also Available
| Platform | Install | Link |
|---|---|---|
| TypeScript / npm | npm install peasytext |
npm |
| Go | go get github.com/peasytools/peasytext-go |
pkg.go.dev |
| Rust | cargo add peasytext |
crates.io |
| Ruby | gem install peasytext |
RubyGems |
| MCP | uvx --from "peasytext[mcp]" python -m peasytext.mcp_server |
Config |
Peasy Developer Tools
Part of the Peasy open-source developer tools ecosystem.
| Package | PyPI | npm | Description |
|---|---|---|---|
| peasy-pdf | PyPI | npm | PDF merge, split, compress, 21 operations — peasypdf.com |
| peasy-image | PyPI | npm | Image resize, crop, convert, compress, 20 operations — peasyimage.com |
| peasytext | PyPI | npm | Text case, slugify, word count, encoding — peasytext.com |
| peasy-css | PyPI | npm | CSS gradients, shadows, flexbox, grid generators — peasycss.com |
| peasy-compress | PyPI | npm | ZIP, TAR, gzip, brotli archive operations — peasytools.com |
| peasy-document | PyPI | npm | Markdown, HTML, CSV, JSON conversions — peasyformats.com |
| peasy-audio | PyPI | npm | Audio convert, trim, merge, normalize — peasyaudio.com |
| peasy-video | PyPI | npm | Video trim, resize, GIF conversion — peasyvideo.com |
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for peasytext 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| peasytext-0.2.2.tar.gz | 625.2 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| peasytext-0.2.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 644.7 kB
Release files / peasytext-0.2.2.tar.gz
| Download URL | peasytext-0.2.2.tar.gz |
|---|---|
| Size | 625.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1b81ff10b1618be9252aa66cc2e151dc9735d6f231299c97efb405228669b445
|
|
BLAKE2b-256 checksum How to use checksums |
f846e2e29115330fec79aeb4b8d0d6fa745203ad9a1a4004a4f9bf89654e1aa7
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.10.9 {"installer":{"name":"uv","version":"0.10.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / peasytext-0.2.2-py3-none-any.whl
| Download URL | peasytext-0.2.2-py3-none-any.whl |
|---|---|
| Size | 19.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cd2cc56ebb27da46580bac8573a8292abb6099dd8ad32f5f41ad2f3e435ee31f
|
|
BLAKE2b-256 checksum How to use checksums |
ae329bea6fc77b7c7a1b8a35a4ea2af675d9f6cbec3380b47cff02fdb08f94bd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.10.9 {"installer":{"name":"uv","version":"0.10.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














