
persona-voice
Real time voice for Open Persona. LiveKit WebRTC transport, streaming STT and TTS, turn taking, and persona conditioned generation.
persona-voice is the voice layer of the Open Persona stack: a
real time, full duplex voice surface that puts sub-second audio on top of the
same persona, typed memory, and tier routed runtime the text stack uses. The
voice persona is the persona. It is never a thin prompt bypass.
What it is and where it fits
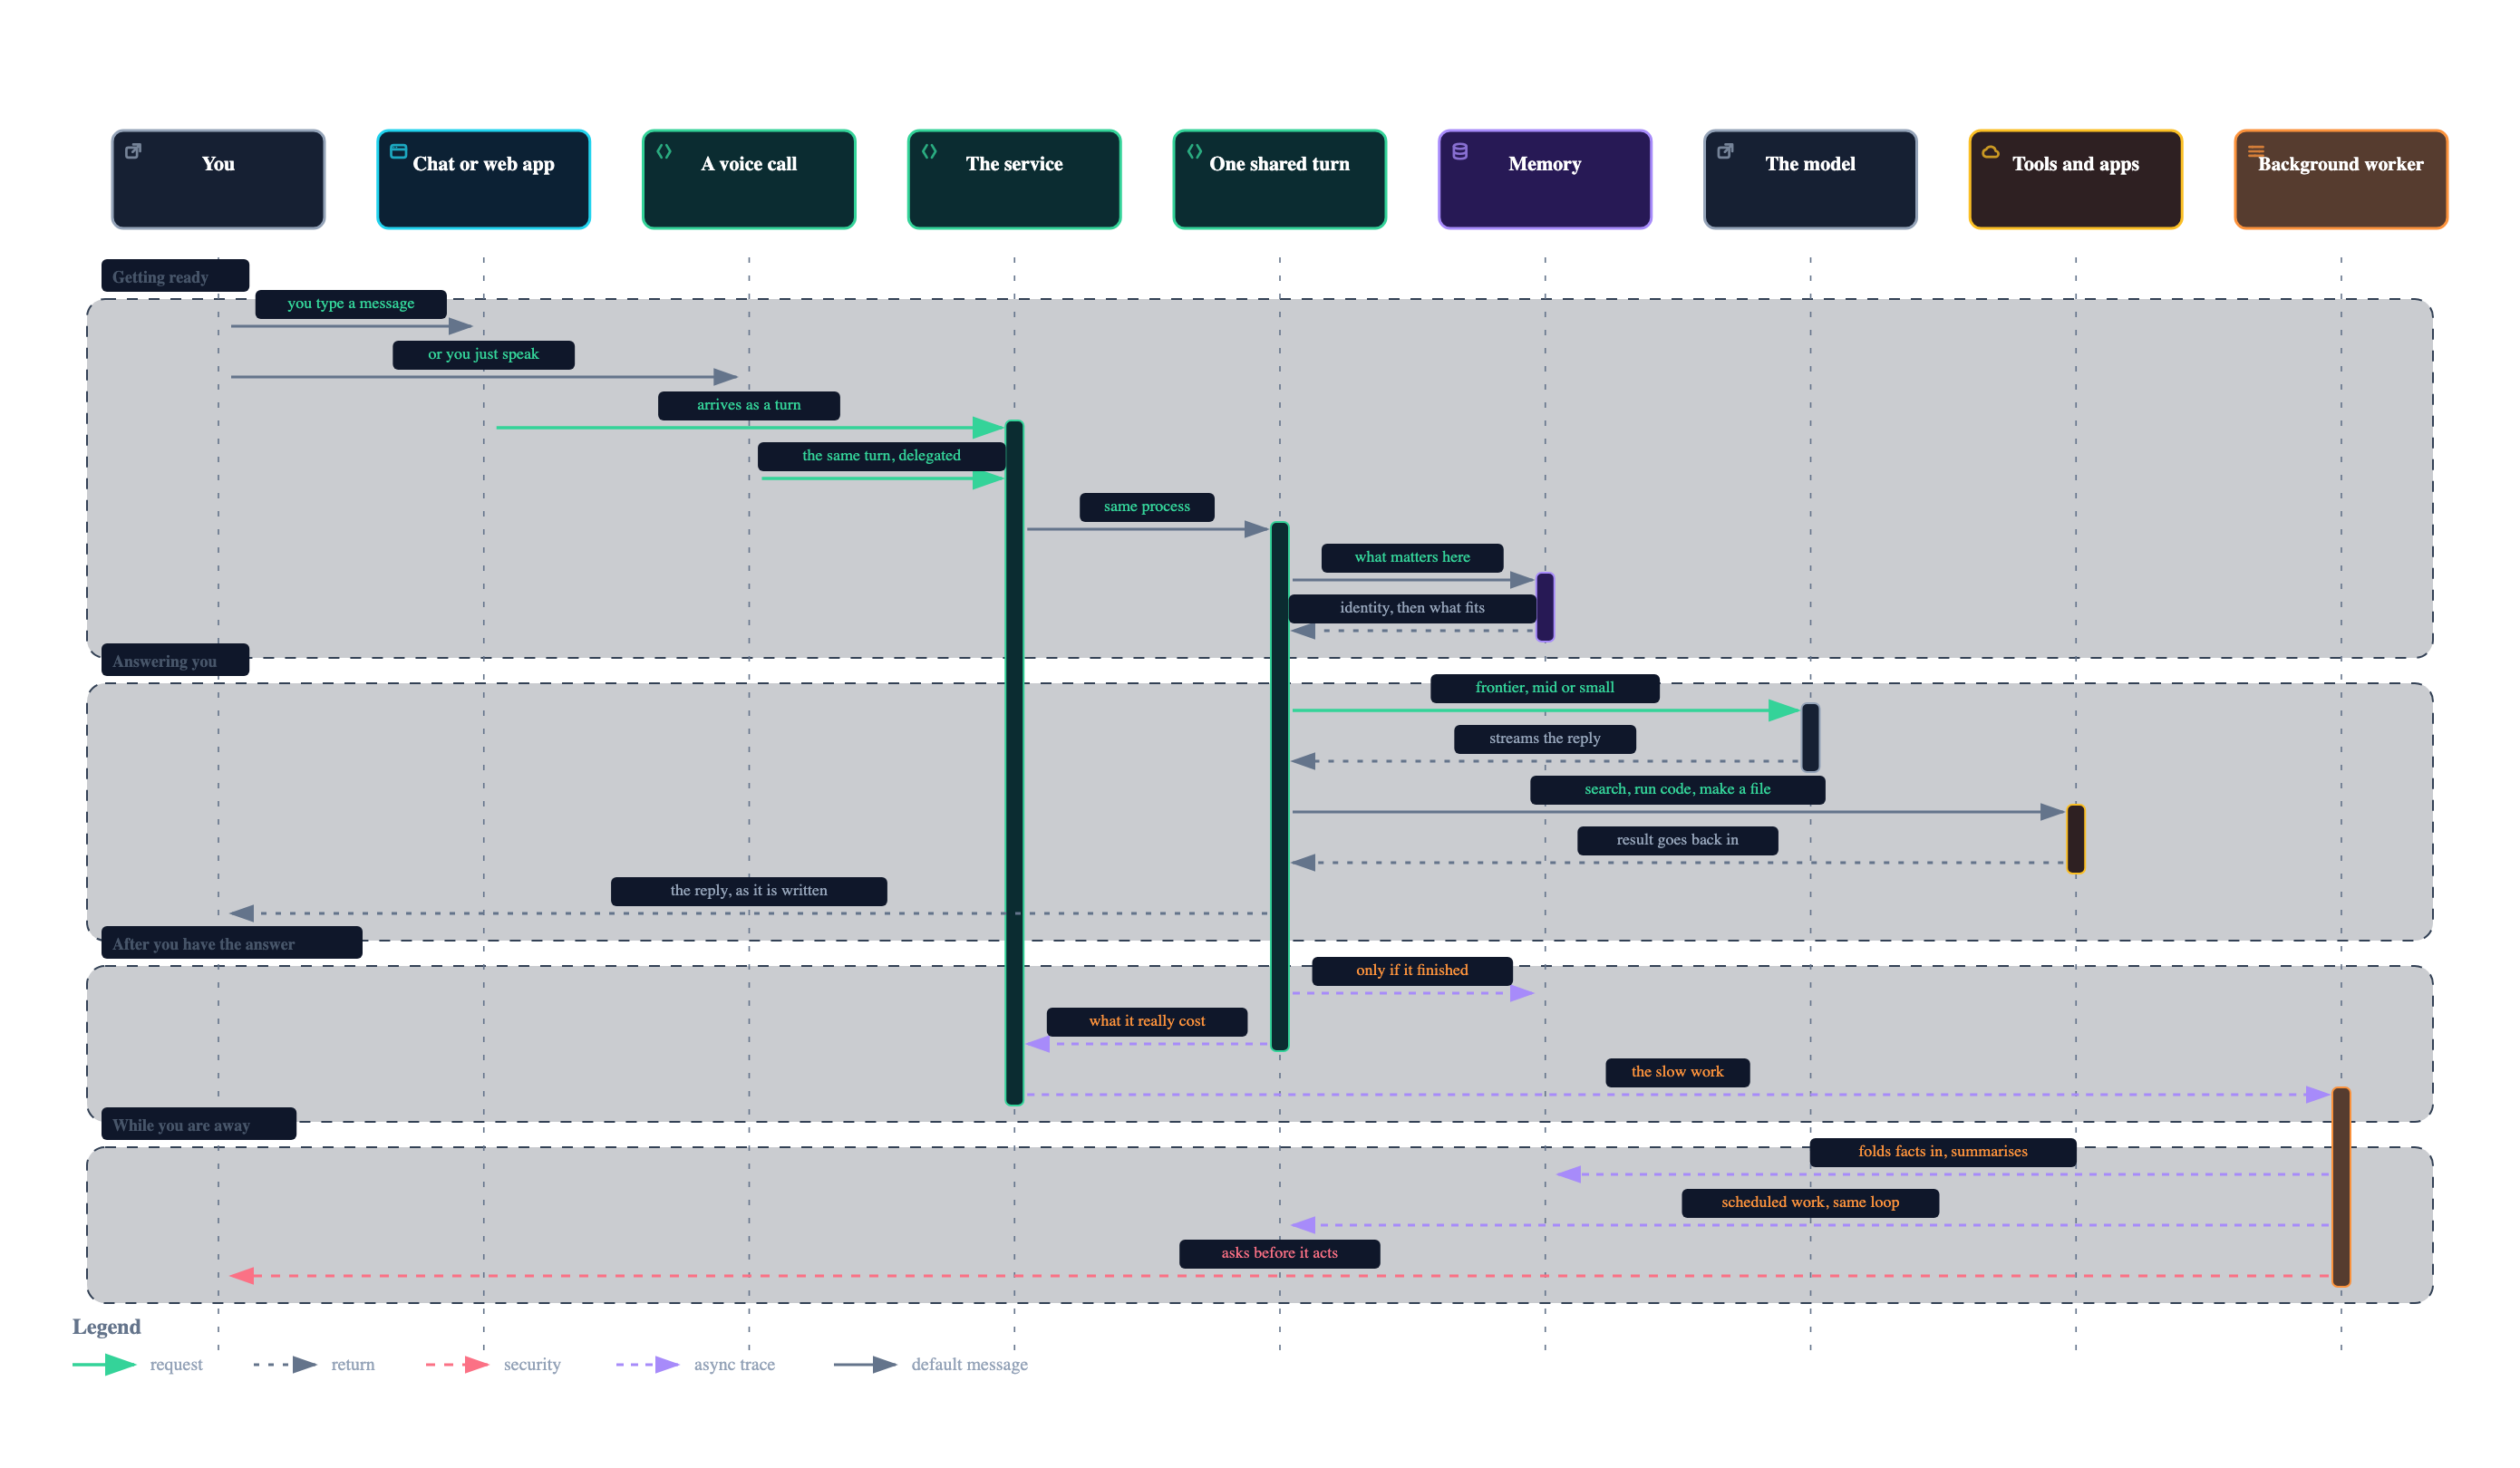
A spoken sentence and a typed message run the same turn; the call delegates anything consequential and never acts alone.
persona-voice runs in process with persona-core (no separate language, no
cross process IPC), so the typed memory stores, the audit log, and the credits
service compose directly. Since V5 it also composes
persona-runtime (prompt builder, router, shared
retrieval), so a voice turn is conditioned exactly like a text turn. The layering
stays acyclic: voice depends on runtime depends on core, and runtime never imports
voice.
WebRTC transport comes from a LiveKit OSS substrate. The browser joins a
LiveKit room, an in process agent worker joins the same room and becomes the
persona. The package's HTTP surface is a single endpoint,
POST /v1/voice/token, which mints a short lived LiveKit AccessToken after
auth, ownership, and credit pre-flights.
Like the rest of the stack, it carries an edition stance
(PERSONA_EDITION):
- cloud. The token endpoint verifies the Clerk JWT (today's deployed behavior), scopes DB access by RLS, and meters credits.
- community. No-auth local voice: a fixed local owner, no JWT, unmetered, single owner ownership.
Features
- WebRTC transport (V1). A LiveKit OSS substrate (
livekit>=1.1), thePOST /v1/voice/tokenAccessToken endpoint, aVoiceRoomfacade (inbound resample to PCM16 mono 16 kHz, outbound 24 kHz publish), aSessionstate machine, and per user voice call concurrency viapg_try_advisory_xact_lock. - Streaming STT (V2). A provider independent
StreamingSTTprotocol (mirroring the coreChatBackendadapter boundary), a Deepgram Nova-3 backend, and a Silero VAD (ONNX only) endpointing adapter. Gladia is the utterance level alternative behind the same protocol (PERSONA_STT_PROVIDER=gladia); see V14 below. - Streaming TTS (V3). A provider independent
StreamingTTSprotocol, a Cartesia Sonic backend, per persona voice as a first class identity attribute, and mid utterancecancel(), the foundation for barge-in. Emotion aware delivery (V12): the persona's emotional stance (its N5 feeling tags) drives Cartesiageneration_configexpressivity so the voice sounds its feeling, bounded by character and restrained, failing soft to a flat read, with aPERSONA_TTS_EMOTION_ENABLEDBeta kill switch. ElevenLabs is the utterance level alternative behind the same protocol (PERSONA_TTS_PROVIDER=elevenlabs); see V14 below. - Turn taking and barge-in (V4). A four state conversational machine (Listening, UserSpeaking, Processing, PersonaSpeaking), automatic endpointing, fast and discriminating interruption, a cancel watchdog, and full loop latency attribution. Pure Python decision logic on the V1, V2, and V3 seams.
- Persona, runtime, and memory integration (V5). Fills V4's reply producer seam with real persona conditioned, tier routed, streaming, cancellable generation, and writes voice turns to the same episodic store as text, so memory is unified. Plus a voice latency routing gate, off critical path history compaction, conversational voice tools, and barge-over-honest memory.
- Capability parity (V10). A call does what a chat can. The persona invokes
tools mid call and produces artifacts that render on screen in the same
FileRendererPanelchat uses. Tools partition by measured latency: search and diagram run inline, whilegenerate_imageruns on a bounded async production lane, decoupled from the audio turn, so the artifact renders the instant it's ready and the persona's "it's on screen" line is floor gated (a new agent initiatedLISTENING→PROCESSINGturn that never talks over the user). Rich output rides the sameRunEventvocabulary as chat (tool_resultplusactivity_*) over the data channel. No parallel format. - Frontend voice client (V6, in development). Browser side audio plumbing and
UI in
persona-web, with an optional dev agent launcher fired from the token endpoint. - Voice memory (V13). The persona remembers on a call in both directions.
Read: graph retrieval on voice, routed through K4's wellbeing gate (mirrored
exactly from chat: allowlist subtraction, recent window lift, care text
surfacing, recency), executed off the loop with timeout and fail soft, so a slow
turn degrades to a clean memoryless one instead of stalling. Gated by
PERSONA_VOICE_GRAPH_MEMORY_ENABLED(default OFF, which is byte identical to graph OFF; flip it ON once the operator pass ratifies latency and care). Write: completed calls enqueue post call graph synthesis through the existing background seam (source: voiceprovenance, idempotent) and write episodic chunks at chat parity. What you say on a call becomes memory the persona knows in chat, and the other way round. - Utterance level multilingual voice (V14). The incumbent providers are
language PINNED per call: Deepgram silently drops a mid utterance second
language, and Cartesia's voice is statically scoped to one language regardless of
the reply text. Strategy A swaps in Gladia STT
(
PERSONA_STT_PROVIDER=gladia, no per call language pin, code switches within a single utterance) and ElevenLabs TTS (PERSONA_TTS_PROVIDER=elevenlabs, one voice speaks whatever language the reply text is in, with nolanguage_codeever sent on the wire), behind the SAMEStreamingSTTandStreamingTTSprotocols. One env flip each way, and the same flip back restores the incumbents' original per persona voices untouched. A boot time AUTO-REMAP keeps existing personas voiced on the active provider. See.env.example's "Spec V14" blocks for every knob. - STT cost gating (V8). Bill Deepgram for the user's speech, not the whole
call. The seam adapter's tee is split: the Silero VAD is always fed, so barge-in
is never starved, while the billed backend leg is gated by conversational state.
The shipped idle gate streams only the user's turn (closed during persona
speaking and listening idle), and a shared ring buffer on reopen flushes the
run-up on every gated to open transition, so the barge-in or post idle first word
is never clipped. The actual billed audio surfaces as
VoiceLog.stt_streamed_seconds, re-basingstt_total_centsoff streamed seconds instead of wall clock. That is roughly an 85 % cost reduction on a listen heavy call. The within turn onset gate measured sub-threshold and was declined.
Install and run
persona-voice is a uv workspace package. From the repo root:
uv sync # install the workspace
persona-voice is consumed by persona-api; there is no standalone CLI. The
token issuance app boots from persona_voice.http.app:
uv run uvicorn persona_voice.http.app:create_app --factory --port 8001
You also need a running LiveKit OSS Server (docker compose up -d livekit)
and, for real STT and TTS, a Deepgram key (PERSONA_STT_API_KEY) and a Cartesia
key (PERSONA_TTS_API_KEY). Under the V14 utterance level providers that becomes
a Gladia key (PERSONA_GLADIA_API_KEY) and an ElevenLabs key
(PERSONA_ELEVENLABS_API_KEY). For local web development,
packages/api/run-local.sh boots the api (:8000) and persona-voice
(:8001) together.
Test
uv run pytest packages/voice                 # unit (default)
uv run pytest packages/voice -m integration  # live LiveKit + Postgres
uv run pytest packages/voice -m external     # live Deepgram / Cartesia
uv run mypy packages/voice/src
uv run ruff check packages/voice
Usage and key surfaces
The token flow. A client that wants a voice call calls
POST /v1/voice/token with a persona_id and an optional conversation_id:
- auth. Cloud verifies the Clerk JWT; community returns a fixed local owner with no token required.
- pre-flight. An RLS scoped persona ownership check plus a credit gate, both no-ops in community.
- mint. A short lived LiveKit AccessToken is signed with the LiveKit API secret, granting access to a per session room.
- response.
{ token, room_name, livekit_url }. The client joins the room over WebRTC; the in process agent joins the same room as the persona.
GET /v1/voices returns the provider voice catalogue, optionally filtered by
language, for the persona voice selector. It degrades to an empty list when TTS is
unconfigured.
Architecture (brief)
browser ──WebRTC──▶  LiveKit OSS Server  ◀──WebRTC──  agent worker (in-process)
   ▲                                                        │
   └── POST /v1/voice/token ──▶ persona-voice ──▶ persona-runtime ──▶ persona-core
            (auth · ownership · credits · mint)     (STT → turn-taking → reply → TTS)
The trunk owns the LiveKit substrate, audio frame plumbing, the streaming STT and
TTS protocols and their concrete backends, the session lifecycle, voice call
concurrency, the persona conditioned reply producer plus the unified memory write,
and the additive VoiceLog. Per minute billing and the V6 frontend land later.
License
persona-voice is licensed under the MIT License; see LICENSE. It
is true OSI open source: free for any use, including commercial. It is
part of the MIT licensed Open Persona engine
(persona-core / persona-runtime / persona-voice); the application layer
(persona-api / persona-web) is separately licensed
PolyForm Noncommercial 1.0.0 (source-available, noncommercial).
Links
1 maintainer

Release files for persona-voice 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| persona_voice-1.2.0.tar.gz | 824.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| persona_voice-1.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / persona_voice-1.2.0.tar.gz
| Download URL | persona_voice-1.2.0.tar.gz |
|---|---|
| Size | 824.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6f3d84db83b1a67c9fc7da2bd96d0b89a0819491202fa78d01bcee7702e5eaf7
|
|
BLAKE2b-256 checksum How to use checksums |
56e4f46aea60dadef4d88f228d74ac7fa4fd76b61256a7da408121996be95646
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.9
|
Release files / persona_voice-1.2.0-py3-none-any.whl
| Download URL | persona_voice-1.2.0-py3-none-any.whl |
|---|---|
| Size | 311.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cc478595acc884096e5bc8a718e68fe01e60e69509b795c600d343b936d2a342
|
|
BLAKE2b-256 checksum How to use checksums |
4ef145f9582208d1bb148d46fad75afb7a5b059516706ef0962936e12a05eed9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.6.9
|














