
Personal Brain
Turn your LinkedIn network into a graph you can ask questions, stored in FalkorDB, and fly through it in 3D.
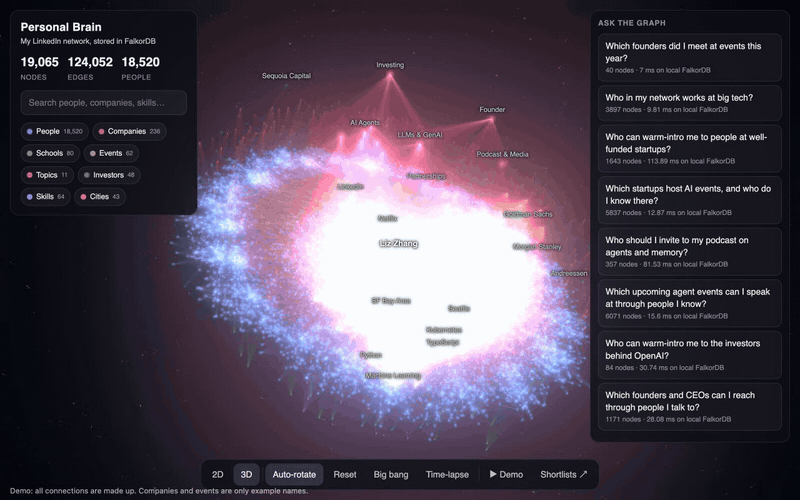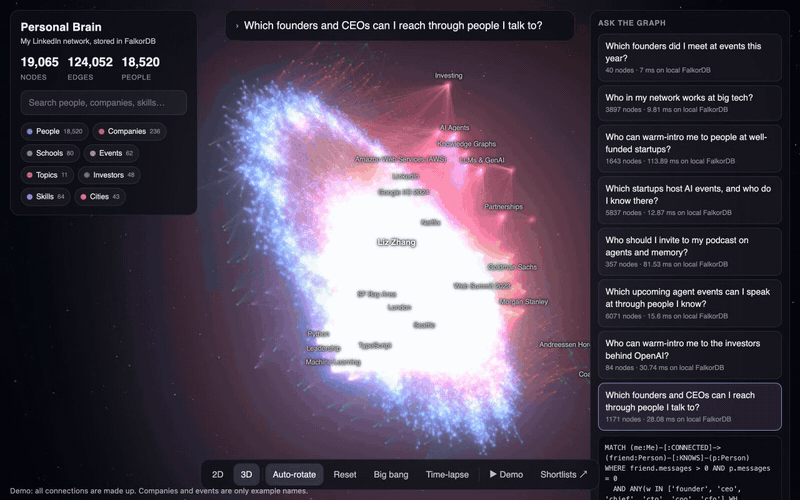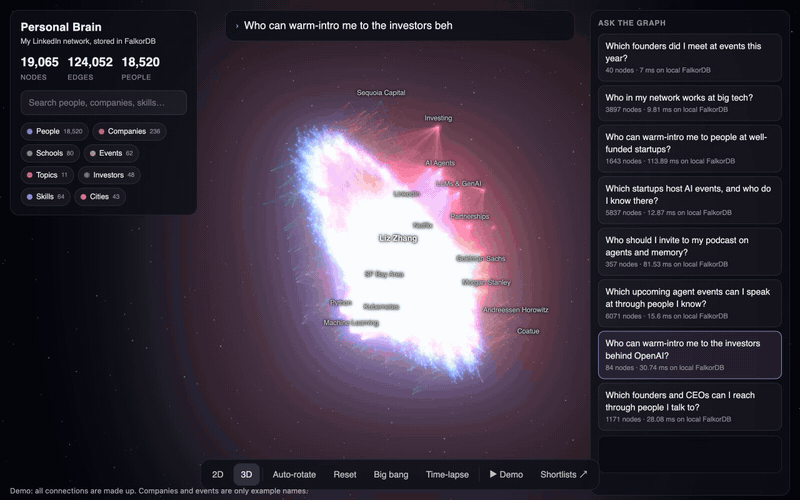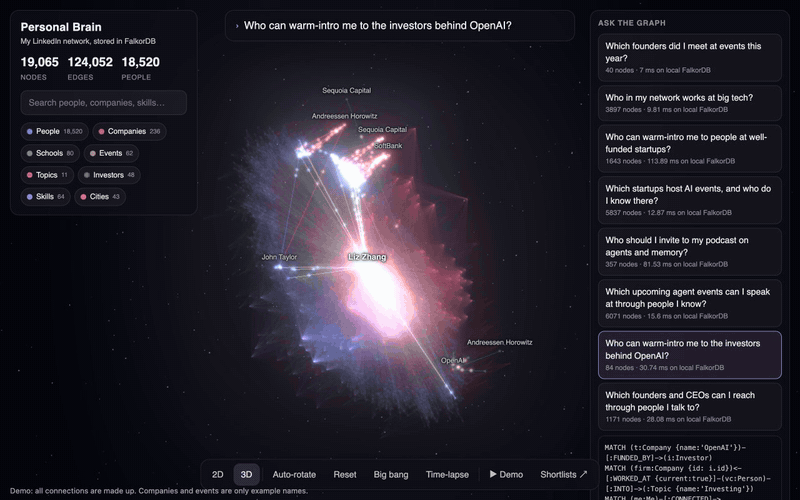
Try the live demo. All connections in it are made up, and its companies and events are only example names. To rebuild it, see scripts/build_demo.py.
After every event you meet people. Two weeks later you forget who they were, what they work on, and who could introduce you to whom. Personal Brain keeps that memory as a graph: people, companies, schools, skills, events, topics, investors and cities, plus inferred "who knows whom" links.
What the viewer does:
- Shows your whole network as a galaxy in WebGL (tested with 19k nodes and 117k edges), with a 2D / 3D toggle.
- Time-lapse: watch your network grow, connection by connection, with your events popping up.
- Ask the graph: a question types itself, then its Cypher query, then the answer lights up with light pulses along the paths. Example questions:
- Which founders did I meet at events this year?
- Who in my network works at big tech?
- Who can warm-intro me to people at well-funded startups?
- Which startups host AI events, and who do I know there?
- Who should I invite to my podcast on agents and memory?
- Which upcoming agent events can I speak at through people I know?
- Shortlists: ranked tables (and CSVs) of co-hosts & sponsors, podcast guests, upcoming events to speak at, and organizers you know. Every row says why it ranks there.
- Remember: type "Met Maya from Supabase at AI Engineer Summit, runs developer events" and it is written to FalkorDB live and appears in the galaxy.
- Demo mode: the whole show hands-free (press
D). - Agent memory (MCP): Claude Code, or any MCP client, can find people, ask the graph, remember who you met and forget on request.
Everything runs on your laptop. The viewer works offline (three.js is vendored).
Quick start: a sample network in 5 minutes
You need uv and FalkorDB. uvx downloads the right Python for you.
The made-up sample network has 241 invented people, startups and events, in the same file formats as a real LinkedIn export. You can try everything before you download your own data.
1. Start FalkorDB. Run it in Docker, or see FalkorDB Cloud:
docker run -p 6379:6379 -p 3000:3000 -it --rm falkordb/falkordb:latest
2. Load the sample, and add the server to Claude Code:
uvx personal-brain load --sample
claude mcp add personal-brain -- uvx personal-brain mcp
Try:
- "Who in my network works at Kestrel Graph?"
- "Who could introduce me to someone at a well-funded startup?"
- "I met Oskar Mensah at the Graph & RAG Meetup. He's building agent memory." (There are two Oskar Mensahs, so it asks which one.)
- "Forget that note."
Other MCP clients: use command uvx, arguments personal-brain mcp (stdio).
FalkorDB Cloud
A free FalkorDB Cloud instance works without Docker. Pass its URL to the server, and add --cloud to load and export:
export FALKORDB_URL='falkors://user:password@host:port'
uvx personal-brain load --sample --cloud
claude mcp add personal-brain -e FALKORDB_URL="$FALKORDB_URL" -- uvx personal-brain mcp
Or put FALKORDB_URL=... in ~/.personal-brain/.env.
Use it as your agent's memory (MCP)
uvx personal-brain mcp gives your agent four tools on one graph:
| Tool | What it does |
|---|---|
remember |
Saves who you met, where they work and where you met. Matches the name to people already in the graph. When it is not sure which person you mean, it saves nothing and asks. A new company ends the old job and keeps it in the history. |
find |
Finds people, companies and events by name, in any script, typos and missing accents included. |
ask |
Runs a read-only Cypher query (FalkorDB refuses writes), with a 5 second limit and at most 50 rows. The tool description carries the schema. |
forget |
Forgets one note and everything it added, one relationship, or one person. A forgotten person stays out of future rebuilds. |
Every write hangs off a Note node, so you can trace each fact to the note that made it. PB_GRAPH picks the graph (default network). If FalkorDB is not running, the server still starts, and each tool says how to start it. Windows is not tested.
How it works
LinkedIn data export ──┐
                       ├─> load_graph.py ──> FalkorDB ──┬─> mcp_server.py ──> your agent
data/enriched/ ────────┘   (graph "network")            ├─> export_graph.py ──> layout_graph.py ──> viewer
(optional)                                              ├─> export_stories.py, export_shortlists.py ──> viewer
                                                        └─> server.py (live "Remember" API) ──> viewer
- Your LinkedIn export gives connections (with the date you connected), your messages (only counts are used, never text), your posts, jobs and schools.
- Optional files in
data/enriched/add each connection's full job history, schools and skills, company funding, and upcoming events. They use the JSON format ofsample_data/enriched/. This repo has no tool to collect them; everything works without them. - load_graph.py builds the graph and infers:
KNOWSbetween two connections who worked at the same company or studied at the same school for 3+ months at the same time (at big schools, same start year only), who work at the same company now (when there is no job history), or who are in the same group chat.Eventnodes: days when you added 5+ connections are probably events. Name them inmy_brain.json.Topicinterests (AI agents, agent memory, knowledge graphs, founders, investors, podcasts…) from headlines and skills.- With enriched files only:
- Years of experience per technology from job titles and descriptions.
well_fundedstartups: private, active, at most 5,000 people, and a Series round or 8+ investors.Cityfrom each profile's location, at metro level ("Berlin Metropolitan Area" and "Berlin" are one city; Palo Alto and San Jose are "SF Bay Area").- Who hosts each upcoming event: a host who is your connection (LinkedIn match), or a company where you know people (host is the company, a host works there, or the title names it, like "Notion x Clover").
- export_graph.py + layout_graph.py export the graph to JSON and compute a 2D layout (igraph DrL). In 3D, each node type sits on its own layer.
- export_stories.py runs the "Ask the graph" Cypher queries on FalkorDB and saves the answers and timings for the viewer.
- export_shortlists.py ranks co-hosts, podcast guests and places to speak with a simple score you can read and change.
Graph schema
| Nodes | Edges |
|---|---|
Me, Person, Company, School, Skill, Topic, Event, Investor, City, Note |
(Me)-[:CONNECTED]->(Person), (Person)-[:WORKED_AT {title, start, end, current}]->(Company), (Person)-[:STUDIED_AT]->(School), (Person)-[:HAS_SKILL]->(Skill), (Person)-[:HAS_EXPERIENCE {years}]->(Skill), (Person)-[:INTO]->(Topic), (Person)-[:KNOWS {via, place}]-(Person), (Me)-[:ATTENDED]->(Event), (Person)-[:MET_AT]->(Event), (Company)-[:FUNDED_BY {lead, round}]->(Investor), (Person)-[:LIVES_IN]->(City), (Event {upcoming})-[:HOSTED_BY {via}]->(Person or Company), (Event)-[:ABOUT]->(Topic), (Event)-[:HELD_IN]->(City), (Me)-[:MET]->(Person) and (Me)-[:WROTE]->(Note)-[:ABOUT]->(Person) (from Remember) |
Build your own
1. Get your LinkedIn data. LinkedIn > Settings > Data privacy > Get a copy of your data. Two choices:
- Connections only: usually ready in about 10 minutes. You get people, their current company and title, and the day you connected. That is enough for the graph, events and the agent tools.
- Download larger data archive: ready in about a day. It adds your messages (only counts are used), posts, jobs and schools.
Unzip it into ~/.personal-brain (the folder name contains LinkedInDataExport). personal-brain --help shows your data folder. To use another folder, set PB_HOME.
Or start empty. Skip the import. The MCP server creates you in an empty graph, and the graph grows as you tell your agent who you met.
Optional: copy my_brain.example.json to ~/.personal-brain/my_brain.json to name your events and list competitors.
2. Build the graph and the viewer data. Add --cloud to both when you use FalkorDB Cloud:
uvx personal-brain load
uvx personal-brain export
3. Open it.
uvx personal-brain view
Open http://127.0.0.1:8765 (shortlists: http://127.0.0.1:8765/shortlists.html). Keys: 2 / 3 switch views, T time-lapse, B big bang, D demo, Esc reset.
To explore in the FalkorDB Browser instead, see docs/demo_queries.cypher.
Work on the code
You need Python 3.10 or newer, uv and Docker. In a clone, your data folder is the clone itself, and Claude Code reads .mcp.json from any folder inside it.
git clone https://github.com/zhang-liz/personal-brain && cd personal-brain
python3 -m venv .venv && .venv/bin/pip install -e .
docker run -p 6379:6379 -p 3000:3000 -it --rm falkordb/falkordb:latest
Then, in another terminal, run the tests. They use throwaway graphs:
.venv/bin/python tests/test_memory.py       # the memory tools (add --cloud to use FALKORDB_URL)
.venv/bin/python tests/test_mcp_server.py   # the server, started the way an agent starts it
.venv/bin/python tests/test_package.py      # the built package, used from another folder
Your data stays yours
- Your data stays in
~/.personal-brain, outside the package. Only you can open that folder. In a clone, the export,data/,.envandmy_brain.jsonare in.gitignore. Never commit them. - Message text is never read into the graph, only how many messages you exchanged with each person.
data/viewer/graph.jsonand the shortlists in your data folder hold real names. Share screenshots, not those files.- The local server listens on
127.0.0.1only and serves onlydata/viewer/.
Files
| Path | What it does |
|---|---|
src/personal_brain/cli.py |
The personal-brain command |
src/personal_brain/paths.py |
Where your data folder is |
src/personal_brain/load_graph.py |
Builds the FalkorDB graph and all inferred links |
src/personal_brain/export_graph.py |
Exports every node and edge to data/viewer/graph.json |
src/personal_brain/layout_graph.py |
Precomputes the layout |
src/personal_brain/export_stories.py |
The "Ask the graph" questions and their Cypher |
src/personal_brain/export_shortlists.py |
Ranked shortlists: co-hosts & sponsors, podcast guests, places to speak |
src/personal_brain/viewer/shortlists.html |
The shortlists page (filter, download CSV) |
src/personal_brain/server.py |
Serves the viewer and the live Remember / Forget API |
src/personal_brain/memory.py |
The memory itself: remember, find, ask, forget (used by the MCP server and the viewer) |
src/personal_brain/mcp_server.py |
The MCP server for Claude Code and other agents |
.mcp.json |
Tells Claude Code how to start the MCP server in a clone |
tests/ |
End-to-end checks of the memory tools, the MCP server and the built package, on throwaway graphs |
src/personal_brain/sample_data/ |
The made-up sample network |
scripts/make_sample_data.py |
Writes sample_data/ |
src/personal_brain/viewer/index.html |
The WebGL viewer (three.js r170, MIT, vendored) |
docs/demo_queries.cypher |
Queries to paste into the FalkorDB Browser |
This is a demo-quality build made at a hackathon, not a product.
License
MIT, see LICENSE. three.js in src/personal_brain/viewer/vendor/ is MIT too (its own LICENSE file).
1 maintainer

Metadata
1 maintainer
Release files for personal-brain 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| personal_brain-0.1.0.tar.gz | 357.3 kB | With provenance | Details for personal_brain-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| personal_brain-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for personal_brain-0.1.0-py3-none-any.whl |
Total release size: 732.7 kB
Release files / personal_brain-0.1.0.tar.gz
| Download URL | personal_brain-0.1.0.tar.gz |
|---|---|
| Size | 357.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1ec0885ef0f2d8f1c37a4686d2954861232734678791aa46512193a24230618b
|
|
BLAKE2b-256 checksum How to use checksums |
f332ec0e2370415ca0d46711c729649574e2b75b68eb3aa83f59f913a730f31c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logRelease files / personal_brain-0.1.0-py3-none-any.whl
| Download URL | personal_brain-0.1.0-py3-none-any.whl |
|---|---|
| Size | 375.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
037358aa6577430c9a22330968e3d7259db67302aa9001caaa511b328d35558e
|
|
BLAKE2b-256 checksum How to use checksums |
61db2c1d664dad8a6320787bd19dd467982f6b480b0fbca2438558fa8577b465
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logSecurity for personal-brain 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for personal_brain-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 4, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














