
pgsesame
Declarative permission management for PostgreSQL and Amazon Redshift. Define roles, users, groups and grants in YAML, then plan and apply changes like Terraform.
Status: 0.2, alpha.
validate,plan,apply, change sets andimportwork for roles, users, groups, memberships, privileges, ownership and default privileges on PostgreSQL and Redshift, along with row-level security and Redshift masking. Tested against PostgreSQL 14 to 18, Supabase, oblako's redshift-local and Redshift Serverless, on Python 3.10 to 3.13. See the roadmap.
Why
Granting access by hand leaves a trail of GRANT statements nobody can review.
pgsesame keeps the intended state in one file: changes go through pull requests,
sesame plan shows exactly which statements a change needs, and sesame apply
runs them. A second plan after apply is empty.
It is built on what went wrong with earlier tools (redtape for Redshift, pgbedrock for PostgreSQL): it reads the real catalog without crashing on what it doesn't model, issues only the difference instead of every grant on every run, and plans revokes and drops but applies them only when you ask.
Where it runs
PostgreSQL 14 to 18, Amazon Redshift (provisioned or Serverless) and Amazon Aurora DSQL. PostgreSQL services work through the same connection, as the platform's admin role: Supabase (tested, with its built-in roles and row-level security), Google's AlloyDB, Amazon RDS and Aurora, Cloud SQL, Neon.
On Amazon RDS and Aurora PostgreSQL, --rds names the instance or cluster and
pgsesame finds the rest:
sesame plan permissions.yaml --iam --rds my-cluster        # a signed IAM token, over TLS
sesame plan permissions.yaml --data-api --rds my-cluster --secret-arn arn:aws:secretsmanager:...
--iam signs an authentication token for the admin user (or --db-user), which
is the only way into an Aurora cluster made with express configuration; the
caller needs rds-db:connect on that database user, which AmazonRDSFullAccess
doesn't include. A user the spec creates signs in the same way once it is a
member of rds_iam (member_of: [rds_iam], with rds_iam: {type: builtin}). The RDS
Data API runs apply in one transaction. The admin user isn't a superuser: from
PostgreSQL 16 on it changes only the roles it has ADMIN OPTION on, so a login or
membership change it can't make is noted in the plan, not attempted.
Amazon Aurora DSQL is engine: dsql: PostgreSQL 16's roles, memberships, grants
and default privileges, plus the IAM identities that sign in as a role:
version: 1
engine: dsql
principals:
  app:
    type: user                       # a role that logs in
    iam: [arn:aws:iam::123456789012:role/app-task]   # AWS IAM GRANT app TO '...'
    privileges:
      schemas: {usage: [orders]}
      tables: {select: [orders.*]}
sesame plan permissions.yaml --dsql abc123xyz          # as admin, with an IAM token
sesame login dsql --dsql abc123xyz                     # or save it as a target
DSQL signs in with IAM only, so a spec gives it no passwords, and it has no database privileges, row-level security or ownership changes: a spec naming them is refused with the reason. It also allows one DDL statement per transaction, and a GRANT is one, so apply runs each statement in its own transaction; if one fails, apply says how many before it were applied, and the next plan shows what remains.
Install
uv tool install pgsesame               # installs the `sesame` command
uv tool install "pgsesame[redshift]"   # Redshift through IAM or the Data API
uv tool install "pgsesame[rds]"        # RDS and Aurora through IAM or the Data API (or [aurora])
uv tool install "pgsesame[dsql]"       # Aurora DSQL
uvx pgsesame --help                    # or try it without installing
pip install pgsesame                   # or into an environment
To upgrade, uv tool install --force --refresh 'pgsesame[redshift]': without
--refresh uv can reuse the version it has cached.
In CI without Python, use the image (amd64 and arm64):
docker run --rm -v "$PWD:/work" -e SESAME_DSN ghcr.io/almostly/pgsesame plan permissions.yaml
pgsesame connects the way you already do: a DSN or the standard PG* variables
with a password (PostgreSQL and Redshift), temporary credentials from IAM for a
Redshift cluster or Serverless workgroup, or the Redshift Data API when the
database isn't reachable over the network.
A spec
version: 1
engine: redshift            # or postgres

principals:
  reader:
    type: role
    privileges:
      schemas:
        usage: [analytics]
      tables:
        select: [analytics.*]

  alice:
    type: user
    password_env: ALICE_PASSWORD
    member_of: [reader]

  support:
    type: role
    privileges:
      columns:                # some columns of a table, not all of it
        select: [crm.customers.id, crm.customers.email]
        update: [crm.customers.email]
Connect once with sesame login, then plan and apply by name. The password goes
to the operating system's keychain, never to a file; a Redshift target with IAM or
the Data API keeps no secret at all:
sesame login prod --host db.example.com --user admin --database app   # asks for the password
sesame login analytics --engine redshift --iam --workgroup analytics --database dev
sesame login aurora --iam --rds my-cluster            # RDS or Aurora: an IAM token
sesame login dsql --dsql abc123xyz                    # Aurora DSQL: an IAM token
sesame login app --supabase abcdefghijklmnopqrst  # Supabase: its session pooler
sesame targets                     # the saved targets; * marks the default
sesame use prod                    # the default for plan and apply
sesame plan permissions.yaml --target analytics
sesame logout prod                 # forget it and its password
--supabase takes a project ref and connects as postgres with TLS. With a
personal access token in SUPABASE_ACCESS_TOKEN, as the Supabase CLI uses, it
asks Supabase for the project's session pooler, which takes IPv4; without one it
uses the direct connection, db.<ref>.supabase.co, which is IPv6 only.
A target can instead take its password from an environment variable when it
connects, so a .env file or a CI secret supplies it and nothing is stored:
sesame login staging --host db.staging.example.com --user admin --password-env STAGING_DB_PASSWORD
uv run --env-file .env sesame plan permissions.yaml -t staging
Targets to share go in the project, committed next to the spec: sesame login --project writes sesame.toml (or put the same tables under [tool.sesame] in
pyproject.toml). sesame looks for it from the current directory up to the
repository root; a project target wins over your own of the same name, and your
sesame use wins over the project's default. A project target takes no typed
password, only --password-env, so the file stays free of secrets:
# sesame.toml
default = "staging"

[targets.staging]
host = "db.staging.example.com"
user = "admin"
database = "app"
sslmode = "require"
password_env = "STAGING_DB_PASSWORD"
The same file then serves CI, with STAGING_DB_PASSWORD as a repository secret.
SESAME_DSN and the standard PG* variables keep working too.
sesame validate permissions.yaml
sesame plan permissions.yaml       # exit code 2 when there are changes
sesame apply permissions.yaml      # revokes, drops and owner changes need --allow-revoke / --allow-drop / --allow-owner

sesame plan permissions.yaml -o changes.json   # save the plan as a change set
sesame show changes.json                       # review it, no database needed
sesame apply changes.json                      # run exactly that, or refuse if it's stale
Where migrations change the database, as with Supabase's CLI and preview branches,
a plan can be one: --migration writes it to a directory as
<UTC time>_pgsesame.sql, for review and supabase db push. What apply runs only
with a flag (revokes, drops, owner changes) is in it commented out, with the flag,
and a plan that sets a password is refused, as the file is committed:
sesame plan permissions.yaml -t app --migration supabase/migrations
Passwords never go in the spec: name an environment variable with password_env,
use IAM, or set password: disabled.
On PostgreSQL a role's attributes are declared too: createdb, createrole,
replication and bypassrls. Once a principal lists them, it has those and no
others; taking one away needs --allow-revoke. A principal that doesn't list
them keeps whatever it has. An admin that isn't a superuser gives only the
attributes it holds itself (PostgreSQL 16+; before, CREATEDB and CREATEROLE), and
the plan notes the rest rather than failing:
principals:
  migrator:
    type: user
    attributes: [createdb, createrole]
On Redshift a role's system permissions are declared the same way, with system:
Redshift grants them to roles only, and checks the names, so any of its permissions
can be listed as GRANT writes it. Its sys: roles are built-in, joined with
member_of:
principals:
  "sys:monitor":
    type: builtin
  auditor:
    type: role
    system: [access system table, create user]
    member_of: ["sys:monitor"]
A platform's own roles (Supabase's authenticated, RDS's rds_iam) are type: builtin: granted to and joined, never created or altered, and their privileges are
managed only in the schemas the spec names for them. PUBLIC, every user, is one too,
named public: its grants are planned TO PUBLIC and revoked as drift only in
the schemas its privileges name, so its defaults elsewhere (CONNECT on the
database, USAGE on public) are left alone:
principals:
  public:
    type: builtin
    privileges:
      tables: {select: [reference.countries]}
A built-in role's memberships are the platform's too, but for the spec's own
roles it joins (member_of, and only those). Supabase's Data API signs in as
authenticator and switches to the role a request's JWT names, so a custom role
needs granting to it:
principals:
  editor:  # a JWT with "role": "editor"
    type: role
  authenticator:
    type: builtin
    member_of: [editor]
Superusers bypass every grant, so pgsesame leaves them alone, unless the spec
says who may be one. Then any other is warned about on every plan, and apply
makes the plan's changes (NOSUPERUSER for the unlisted, SUPERUSER for the
listed; Redshift's NOCREATEUSER and CREATEUSER) only with --allow-superuser,
which no other flag implies. The connected user stays one (the apply would cut
itself off), and so do the platform's own (rdsadmin, rdsdb, supabase_admin)
and PostgreSQL's bootstrap superuser. Only a superuser changes superusers: on RDS,
Aurora or Supabase, where the admin isn't one, the plan is an audit:
manage:
  superusers: [dba]
Row-level security is declared per table:
principals:
  authenticated:
    type: builtin
    privileges:
      schemas: {usage: [app]}
      tables: {select: [app.notes]}

row_level_security:
  app.notes:
    policies:
      own_notes:
        command: select          # all, select, insert, update, delete
        to: [authenticated]
        using: "auth.uid() = owner"
Policy expressions are compared in the form PostgreSQL stores them, so a re-plan
after apply is empty; dropping a policy or disabling row-level security needs
--allow-drop. examples/supabase puts it together for a
Supabase app: its built-in roles, column grants, policies on auth.uid() and a
dashboard's own login.
Only a table's owner switches its row-level security. On a table the connected
user can't act as the owner of, a change to enabled or force is warned about
and skipped, and its policies are still planned. That is how Supabase's file
storage works: storage.objects belongs to supabase_storage_admin with
row-level security on, and postgres may add policies to it:
row_level_security:
  storage.objects:
    policies:
      avatars_own_folder:  # users/<their id>/... in the avatars bucket
        command: select
        to: [authenticated]
        using: "bucket_id = 'avatars' and (select auth.uid())::text = (storage.foldername(name))[1]"
Realtime works the same way: policies on realtime.messages authorize Broadcast
and Presence. Which tables send their changes to Postgres Changes subscribers is
the supabase_realtime publication's list, which a spec can manage too
(publications, on PostgreSQL). pgsesame never creates or drops a publication;
taking a table out needs --allow-revoke:
publications:
  supabase_realtime:
    tables: [app.posts]  # or app.* for every table in app
Where Supabase's Data API reaches rows past row-level security, the plan warns,
whatever the spec says. The API signs in as authenticator and switches to one of
its roles (anon, authenticated, a custom JWT role), so anyone with the project's
anon key acts as one. Once the plan has run, a table with row-level security off,
or a view that runs with its owner's rights (no security_invoker), that such a
role can read or write is said; so are PUBLIC's grants, which every role holds. A
role that bypasses row-level security (service_role) and the platform's own
tables are left out:
! public.todos: row-level security is off, and anon (DELETE, INSERT, SELECT, UPDATE) can reach it: every row is open to them
Default privileges that give such a role the tables an owner creates are said as
well, since PostgreSQL makes a table with row-level security off. Supabase's own
defaults in public did this until October 30, 2026: a new table there now needs
a grant, in the migration that creates it. That is what a spec does, and
sesame plan --migration writes the grants into a migration. A spec imported
before then still lists those defaults, and applying it would put them back:
drop them from its default_privileges, or import it again.
On PostgreSQL, functions and procedures take EXECUTE. schema.name names every
overload, schema.name(types) one of them, with the types as PostgreSQL writes
them (integer, not int), and schema.* every function in the schema; an
extension's functions are left out:
principals:
  supabase_auth_admin:  # Supabase's Auth hook
    type: builtin
    privileges:
      schemas: {usage: [public]}
      functions: {execute: [public.custom_access_token_hook]}
A function the spec names is declared in full: whoever may execute it, declared
or not, is what the spec says. PostgreSQL lets PUBLIC execute every new function,
and Supabase grants anon and authenticated the functions made in public; on a
function the spec names, both are drift, revoked with --allow-revoke. Functions
it doesn't name keep their grants.
On Redshift, dynamic data masking is declared per column: what everyone sees, which roles see the raw value, and which see their own mask:
masking:
  policies:
    redact: {type: varchar(256), using: "'***'::varchar(256)"}
    email_domain: {type: varchar(256), using: "regexp_replace(value, '^[^@]+', '***')"}
  columns:
    crm.customers.email:
      mask: redact               # everyone else
      unmasked: [pii_reader]     # the raw value
      roles:
        support: email_domain    # their own mask; later entries win
pgsesame works out Redshift's mechanics: the mask is attached to PUBLIC at
priority 10, each role's policy at 20, 30 ... in the order written, and the
unmasked roles get a pass-through policy of pgsesame's own
(sesame_unmasked_varchar_256) at 1000. A constant needs its type ('***'::varchar(256)): Redshift
refuses an expression of ambiguous type. Expressions are compared in the form
Redshift stores them; moving a role's priority is a change, taking a role off a
column needs --allow-revoke, and a policy whose type changes is replaced only
with --allow-drop. Planning masking needs a superuser or the sys:secadmin
role, as Redshift shows policies to no one else.
Priorities are compared by order, not number: where a column's attachments
already rank everyone as the spec does (the mask below the roles, the roles in
the order written, the unmasked above), the plan keeps the database's numbers.
Expressions are compared in the form Redshift stores them, read back from probe
policies: rolled back over a direct connection; over the Data API created, read
and dropped in the same plan (never attached), which needs
redshift-data:BatchExecuteStatement.
Ownership is declared on the owner, and planned as ALTER ... OWNER TO for the
objects it lists (schema.* for every table in a schema). Objects the spec
doesn't list keep their owner; an owner's privileges on its own objects are
implied, so they're neither granted nor revoked. A change of owner takes from the
old owner everything owning gave it, so apply runs it only with --allow-owner;
without it, the plan shows it and apply skips it. A superuser's memberships and
privileges are left alone (it bypasses them), but what it owns is planned like
any other owner's. pgsesame never drops a schema,
table, view, user, group or role. On Redshift the owner is a user:
principals:
  etl:
    type: user
    owns:
      schemas: [analytics]
      tables: [analytics.*]
Default privileges give a role what an owner creates from now on, so a table made overnight is readable in the morning. The owner needn't be in the spec (it's often the ETL or admin user); pgsesame manages the entries whose grantee it does:
default_privileges:
  - owner: etl               # objects etl creates ...
    schema: analytics        # ... in this schema (leave out for every schema) ...
    grantee: analyst         # ... are readable by analyst
    tables: [select]
On Redshift an entry for one schema takes only if its owner may create there (directly, through a group or role, or as the schema's owner): Redshift refuses it otherwise, even to a superuser. The plan warns about such an entry and skips it, so the rest still applies.
Tables that are rebuilt
A grant belongs to one table, so a tool that rebuilds tables (dbt's table
materialization, Glue, a stored procedure) drops its grants with the old one.
sesame grants lists what the spec grants, from the spec alone, for such a tool
to put back right after a rebuild, without parsing the YAML itself:
sesame grants permissions.yaml --object bianalytics.loans          # JSON
sesame grants permissions.yaml --format csv > declared_grants.csv  # every grant
Each row is object_type, schema, object (* for schema.*, as the spec
writes it), column, privilege, grantee and grantee_type (on Redshift user,
group or role, which decides the GRANT syntax). --object schema.table keeps
the rows that reach that table: its own and its schema's *.
examples/dbt is the pattern for dbt: after each apply,
publish_grants.py loads sesame grants --format csv into
monitoring.declared_grants, and one shared post-hook, pgsesame_regrant(),
grants a model's rows right after it builds, in the same transaction, skipping
grantees that don't exist. dbt's own grants: config would revoke everything
else on each build; this only adds back what the spec declares.
tests/test_dbt.py runs it with dbt against redshift-local.
Adopting an existing database
sesame import writes the spec that reproduces what the database grants today,
so a first plan has nothing to do, and the spec is edited from there. On Redshift
it needs to see every grant: Redshift shows a user only its own, unless it is a
superuser or holds the ACCESS SYSTEM TABLE system permission, and a spec missing
the rest would have a plan revoke them, so import refuses rather than write it.
The permission is the least-privileged way, through a role:
CREATE ROLE sesame_reader;
GRANT ACCESS SYSTEM TABLE TO ROLE sesame_reader;
GRANT ROLE sesame_reader TO "IAM:deployer";
Plan and apply without it say so before anything else:
sesame import --target dwh --schema collections --schema risk_engine -o permissions.yaml
sesame plan permissions.yaml --target dwh        # ✓ nothing to do
It writes every role but superusers and the platform's own (or only those named
with --prefix), their memberships, grants, column grants, default privileges,
ownership and, on Redshift, masking; never passwords. Masking is written in
pgsesame's model (the PUBLIC mask, roles in priority order, unmasked roles), so
where policies were attached another way, the first plan shows the correction;
the import's notes say what changes. Without superuser or sys:secadmin it says
it couldn't see the policies, rather than writing none. A role they refer to but that wasn't selected is
written as type: builtin: referred to, never managed. So is every other role
that may execute a function the import names, PUBLIC included, with its grants in
the same schemas, since a plan takes every grant on a named function as declared.
On Supabase, the platform stays the platform's. Its roles are type: builtin:
anon, authenticated and service_role with their grants in the app's schemas, and
authenticator with the app's roles it joins (custom JWT roles). Its schemas (auth,
storage, realtime, extensions ...) and the default privileges of roles postgres
can't act as are left out, unless --schema names one. The flags become the
spec's manage: section, which also works on its own:
manage:
  schemas: [collections, risk_engine]   # grants elsewhere aren't compared (no drift)
  prefixes: [svc_]                       # undeclared svc_* roles are managed too:
                                         # what they hold is revoked with --allow-revoke
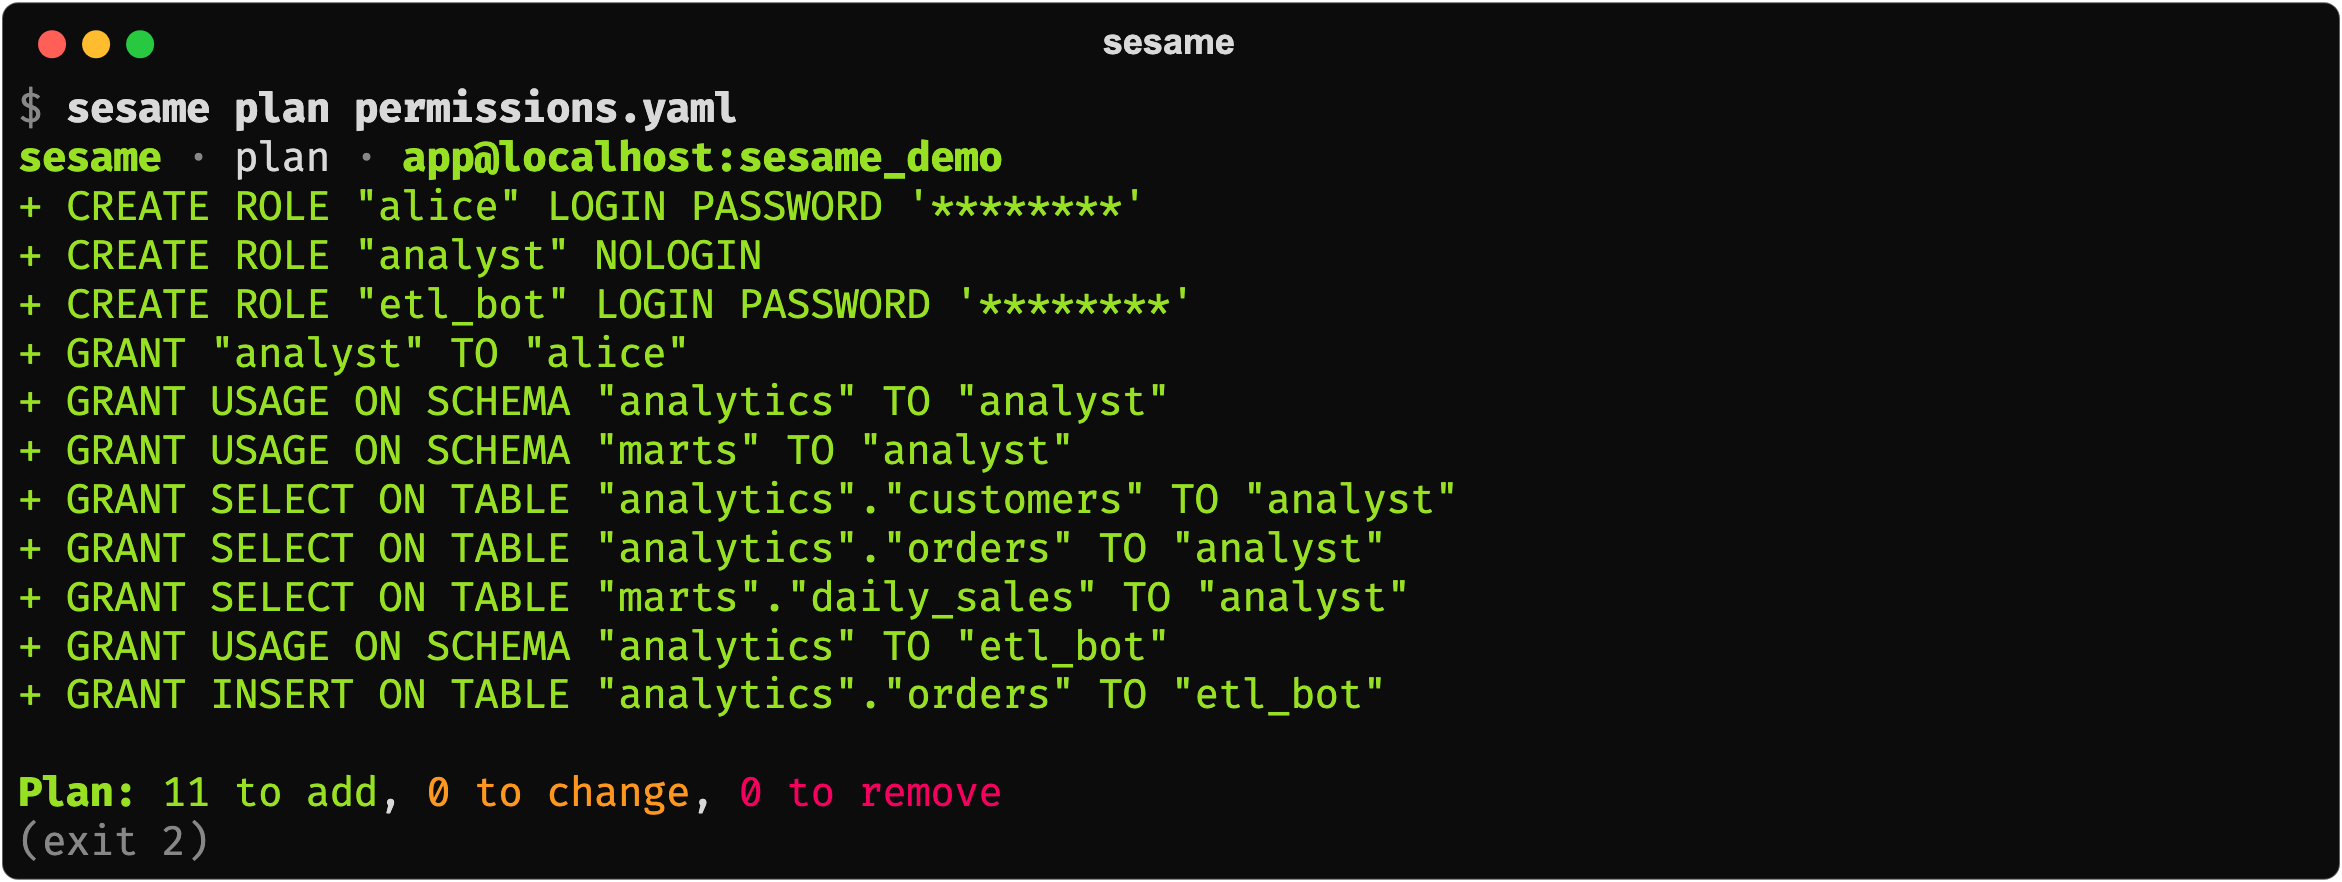
A first plan creates the roles and grants the spec declares:
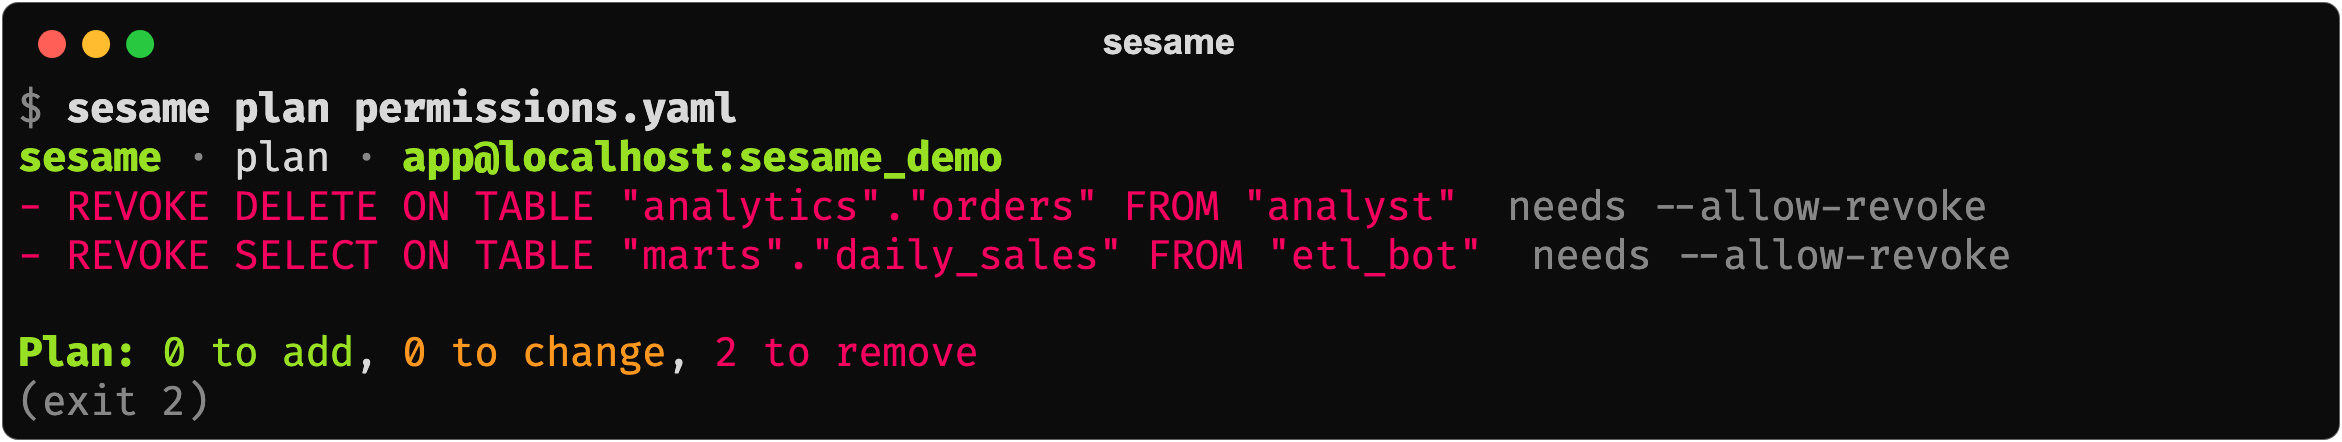
Later, two grants someone made by hand show up as drift; they are revoked only
with --allow-revoke:
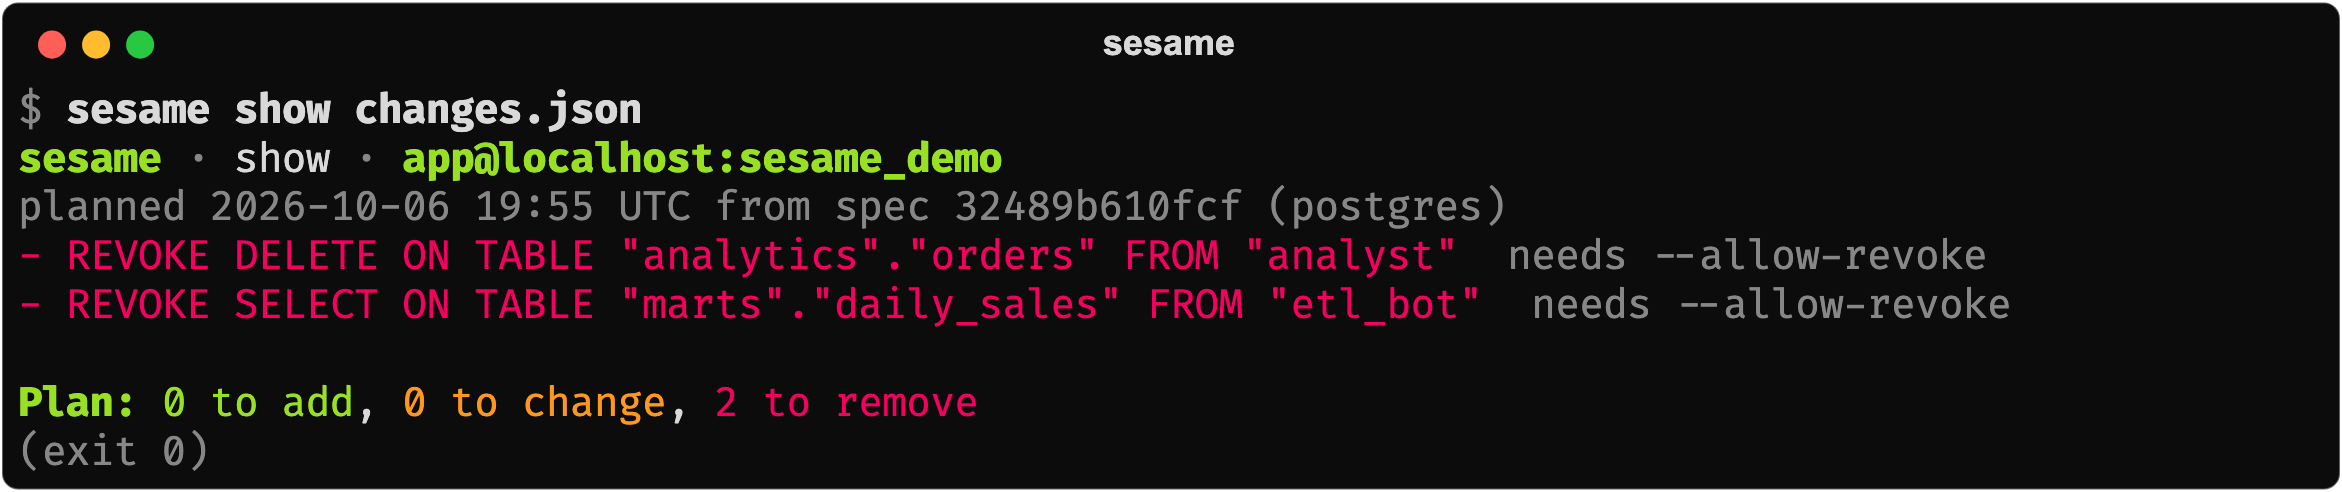
A saved change set can be reviewed without a database, then applied exactly:
In GitHub Actions
Review the plan on the pull request; apply the reviewed change set on merge. The
connection comes from a secret (SESAME_DSN), and the production environment
can require a reviewer's approval before apply runs.
on:
  pull_request:
  push:
    branches: [main]

jobs:
  plan:
    runs-on: ubuntu-latest
    permissions: {contents: read, pull-requests: write}
    env: {SESAME_DSN: "${{ secrets.SESAME_DSN }}"}
    steps:
      - uses: actions/checkout@v4
      - uses: almostly/pgsesame@v0.3.1
        with: {command: plan, spec: permissions.yaml}

  apply:
    if: github.event_name == 'push'
    needs: plan
    runs-on: ubuntu-latest
    environment: production
    env: {SESAME_DSN: "${{ secrets.SESAME_DSN }}"}
    steps:
      - uses: almostly/pgsesame@v0.3.1
        with: {command: apply}
On a pull request the plan is posted as one comment, updated on each push. On
merge, apply runs exactly the change set the plan job saved, or refuses if the
database changed since. Revokes need allow-revoke: true, owner changes
allow-owner: true. The step's outputs
(has-changes, to-add, to-change, to-remove) can drive other steps. For
Redshift with IAM, sign in with aws-actions/configure-aws-credentials and pass
args: --iam --workgroup analytics.
Outside GitHub, run uvx pgsesame or the image
(docker run --rm -v "$PWD:/work" -e SESAME_DSN ghcr.io/almostly/pgsesame plan permissions.yaml); plan exits 2 when it has changes.
Testing locally
The integration tests run against PostgreSQL in Docker and against oblako's local Redshift, so a spec can be planned and applied in CI before it touches a real cluster.
License
Apache-2.0
1 maintainer

Metadata
1 maintainer
Release files for pgsesame 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| pgsesame-0.3.1.tar.gz | 654.9 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pgsesame-0.3.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 753.3 kB
Release files / pgsesame-0.3.1.tar.gz
| Download URL | pgsesame-0.3.1.tar.gz |
|---|---|
| Size | 654.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b6e686975209dd179ca41c3a527db372b0c1524d470c617dcb2bdc4940e8cf55
|
|
BLAKE2b-256 checksum How to use checksums |
f7f2a3bf10e9cb10c2eb1e7697216304d057eb5c1162f347516f6090c30546fa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logRelease files / pgsesame-0.3.1-py3-none-any.whl
| Download URL | pgsesame-0.3.1-py3-none-any.whl |
|---|---|
| Size | 98.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
4e9dc8e5f2fe56ec2372f01aa010d7f61eb39a44e8c7e959ea9aaafe2475ff78
|
|
BLAKE2b-256 checksum How to use checksums |
14f035113d7e35b67f96408d682ac3653973e51588446a659496ca110db4b9be
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logSecurity for pgsesame 0.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for pgsesame-0.3.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 21, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














