
piiscope: PII scanner and privacy risk CLI
Find, score and remediate personal data in files and databases without sending the data to an external service.



What it does
piiscope finds personal data in your datasets and measures privacy risks across global jurisdictions. It scans tabular data or free text to locate direct identifiers and calculate k-anonymity, l-diversity and t-closeness on quasi-identifiers. It helps you remediate findings by applying strategies like hashing, generalisation or tokenisation directly to the target columns.
Install
pip install piiscope
For reading Parquet files:
pip install "piiscope[parquet]"
For spaCy-based natural language processing:
pip install "piiscope[nlp]"
Quickstart
Scan a file to identify privacy risks:
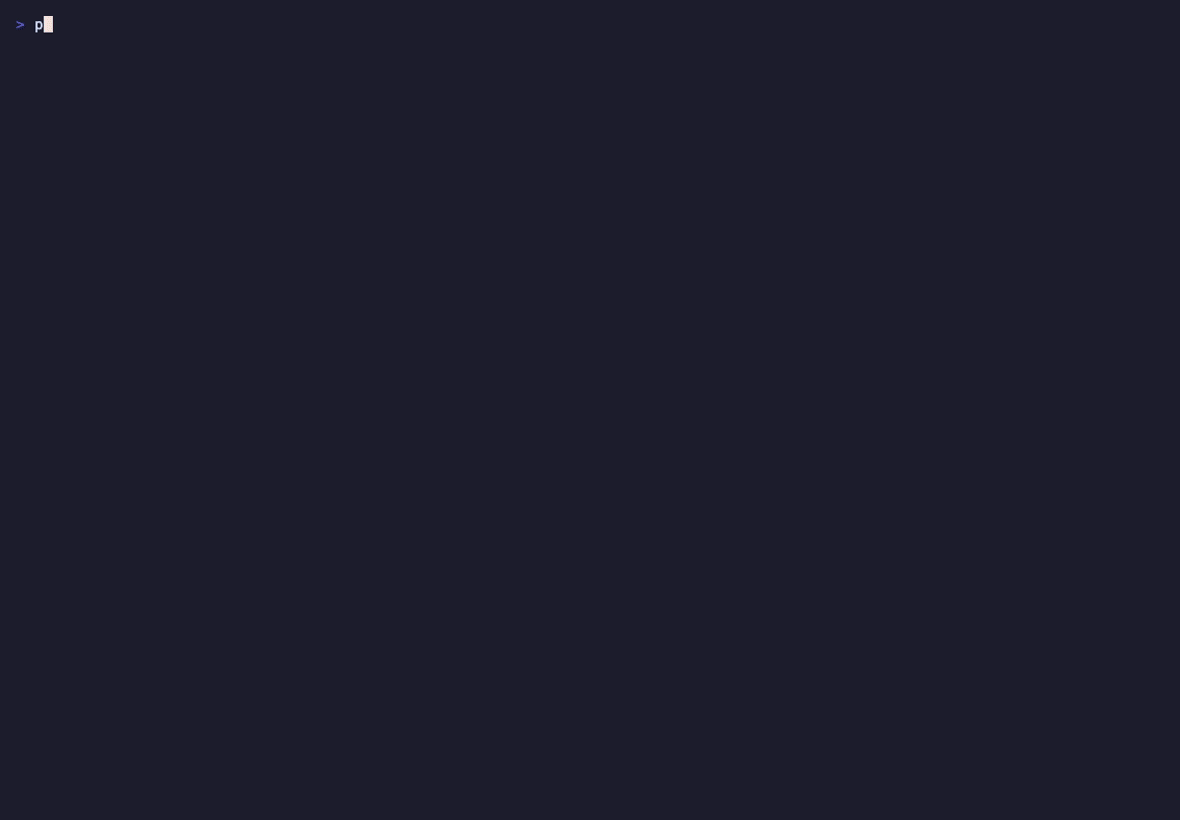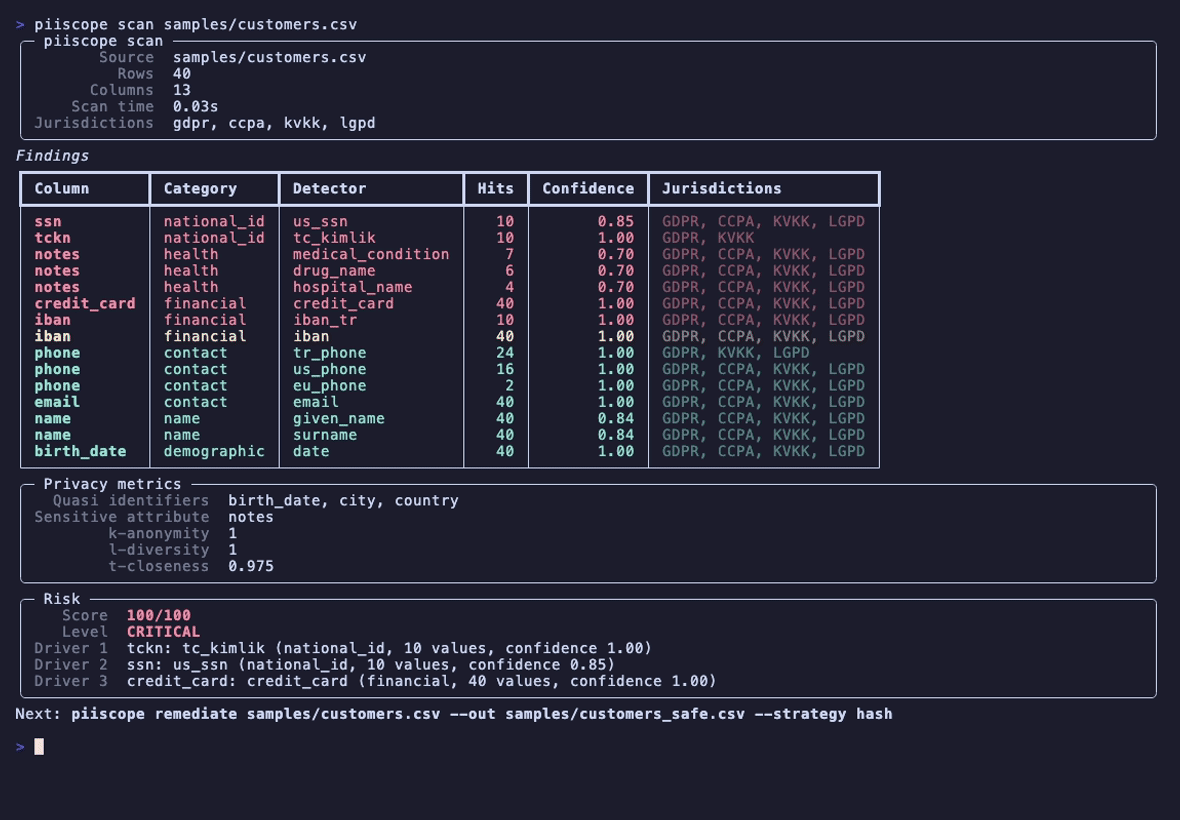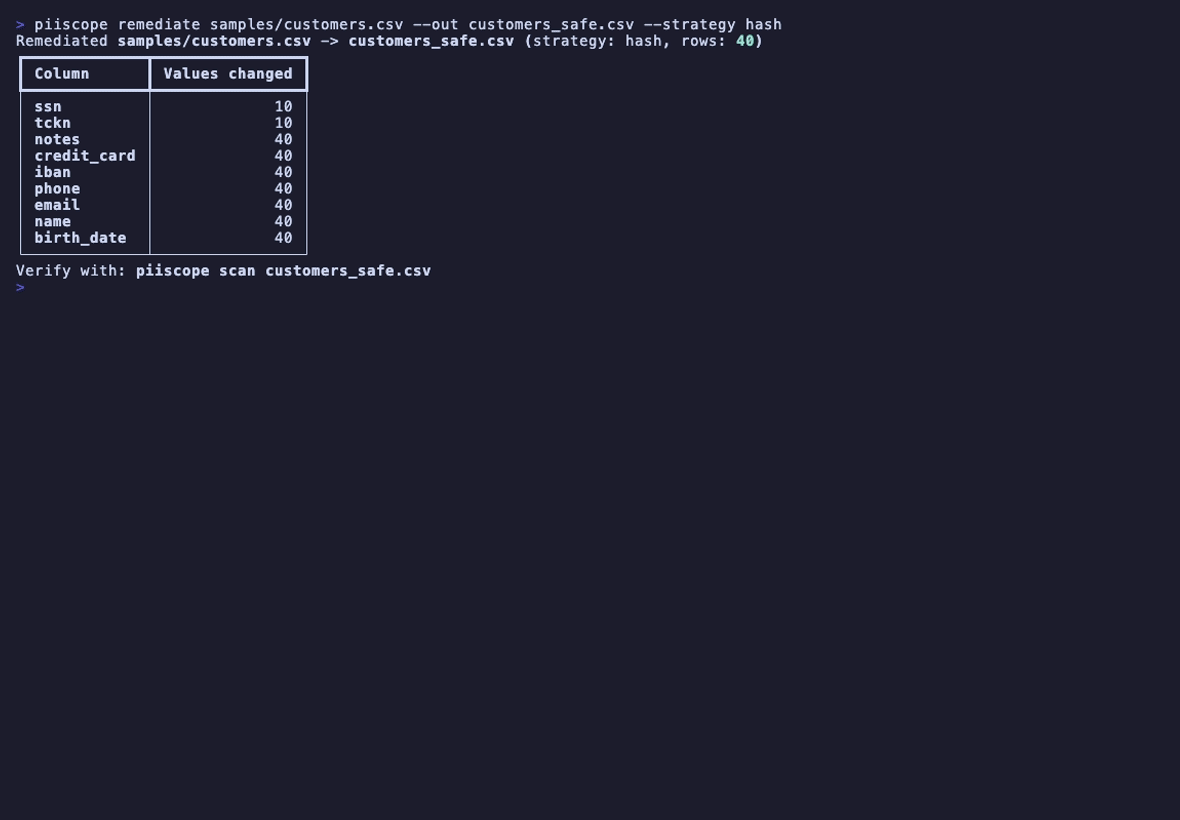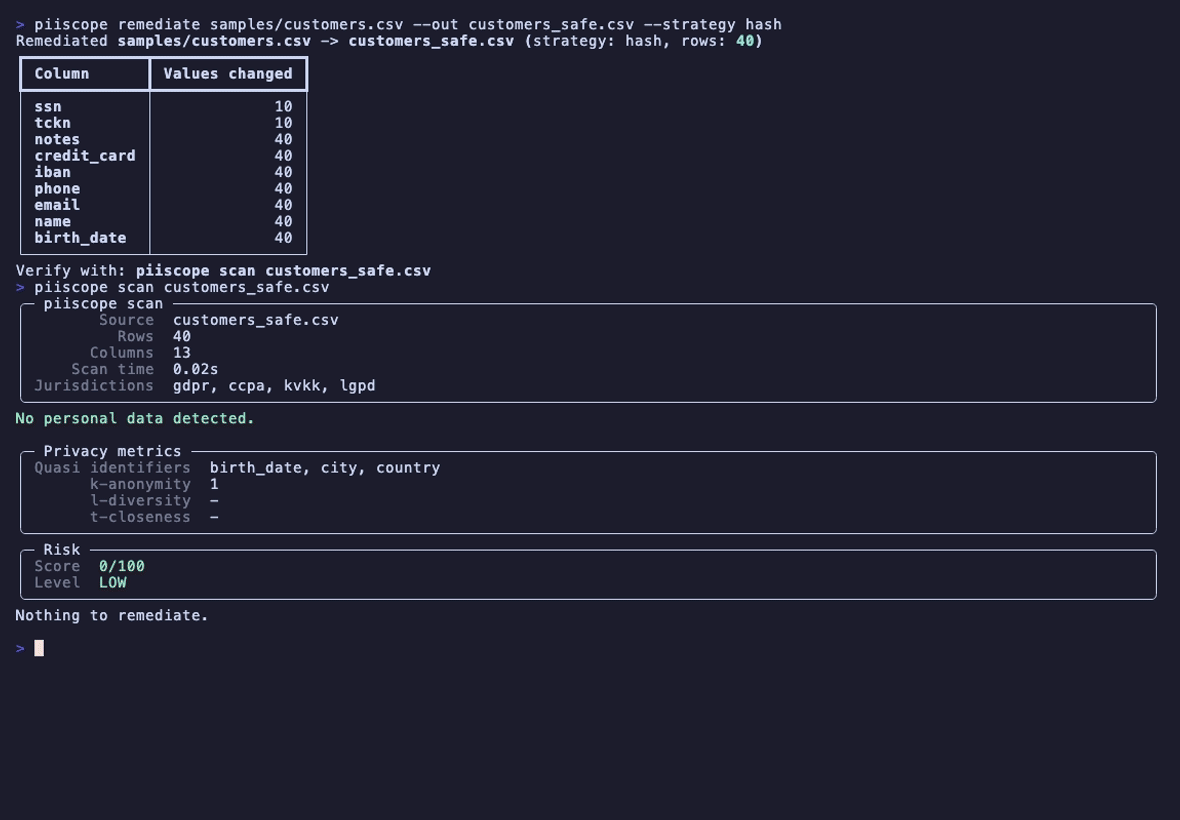
piiscope scan samples/customers.csv
╭─ piiscope scan ──────────────────────────────────────────────────────────────────────────────────╮
│        Source  samples/customers.csv                                                             │
│          Rows  40                                                                                │
│       Columns  13                                                                                │
│     Scan time  0.06s                                                                             │
│ Jurisdictions  gdpr, ccpa, kvkk, lgpd                                                            │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
Findings
┏━━━━━━━━━━━━━┳━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━┳━━━━━━┳━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━━━━━━━━━┓
┃ Column      ┃ Category    ┃ Detector          ┃ Hits ┃ Confidence ┃ Jurisdictions          ┃
┡━━━━━━━━━━━━━╇━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━╇━━━━━━╇━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━━━━━━━┩
│ ssn         │ national_id │ us_ssn            │   10 │       0.85 │ GDPR, CCPA, KVKK, LGPD │
│ tckn        │ national_id │ tc_kimlik         │   10 │       1.00 │ GDPR, KVKK             │
│ notes       │ health      │ medical_condition │    7 │       0.70 │ GDPR, CCPA, KVKK, LGPD │
│ notes       │ health      │ drug_name         │    6 │       0.70 │ GDPR, CCPA, KVKK, LGPD │
│ notes       │ health      │ hospital_name     │    4 │       0.70 │ GDPR, CCPA, KVKK, LGPD │
│ credit_card │ financial   │ credit_card       │   40 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ iban        │ financial   │ iban_tr           │   10 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ iban        │ financial   │ iban              │   40 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ phone       │ contact     │ tr_phone          │   24 │       1.00 │ GDPR, KVKK, LGPD       │
│ phone       │ contact     │ us_phone          │   16 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ phone       │ contact     │ eu_phone          │    2 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ email       │ contact     │ email             │   40 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
│ name        │ name        │ given_name        │   40 │       0.84 │ GDPR, CCPA, KVKK, LGPD │
│ name        │ name        │ surname           │   40 │       0.84 │ GDPR, CCPA, KVKK, LGPD │
│ notes       │ name        │ given_name        │    1 │       0.60 │ GDPR, CCPA, KVKK, LGPD │
│ birth_date  │ demographic │ date              │   40 │       1.00 │ GDPR, CCPA, KVKK, LGPD │
└─────────────┴─────────────┴───────────────────┴──────┴────────────┴────────────────────────┘
╭─ Privacy metrics ────────────────────────────────────────────────────────────────────────────────╮
│   Quasi identifiers  birth_date, city, country                                                   │
│ Sensitive attribute  notes                                                                       │
│         k-anonymity  1                                                                           │
│         l-diversity  1                                                                           │
│         t-closeness  0.975                                                                       │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
╭─ Risk ───────────────────────────────────────────────────────────────────────────────────────────╮
│    Score  100/100                                                                                │
│    Level  CRITICAL                                                                               │
│ Driver 1  tckn: tc_kimlik (national_id, 10 values, confidence 1.00)                              │
│ Driver 2  ssn: us_ssn (national_id, 10 values, confidence 0.85)                                  │
│ Driver 3  credit_card: credit_card (financial, 40 values, confidence 1.00)                       │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
Next: piiscope remediate samples/customers.csv --out samples/customers_safe.csv --strategy hash
Remediate the file, then prove the output is clean:
piiscope remediate samples/customers.csv --out customers_safe.csv --strategy hash
piiscope scan customers_safe.csv
Remediated samples/customers.csv -> customers_safe.csv (strategy: hash, rows: 40)
┏━━━━━━━━━━━━━┳━━━━━━━━━━━━━━━━┓
┃ Column      ┃ Values changed ┃
┡━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━┩
│ ssn         │             10 │
│ tckn        │             10 │
│ notes       │             40 │
│ credit_card │             40 │
│ iban        │             40 │
│ phone       │             40 │
│ email       │             40 │
│ name        │             40 │
│ birth_date  │             40 │
└─────────────┴────────────────┘
Verify with: piiscope scan customers_safe.csv
╭─ piiscope scan ──────────────────────────────────────────────────────────────────────────────────╮
│        Source  customers_safe.csv                                                                │
│          Rows  40                                                                                │
│       Columns  13                                                                                │
│     Scan time  0.02s                                                                             │
│ Jurisdictions  gdpr, ccpa, kvkk, lgpd                                                            │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
No personal data detected.

╭─ Privacy metrics ────────────────────────────────────────────────────────────────────────────────╮
│ Quasi identifiers  birth_date, city, country                                                     │
│       k-anonymity  1                                                                             │
│       l-diversity  -                                                                             │
│       t-closeness  -                                                                             │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
╭─ Risk ───────────────────────────────────────────────────────────────────────────────────────────╮
│ Score  0/100                                                                                     │
│ Level  LOW                                                                                       │
╰──────────────────────────────────────────────────────────────────────────────────────────────────╯
Nothing to remediate.
If this saves you time, consider starring the repository. It helps other developers find it.
Scan a file and get the risk score in JSON:
piiscope scan samples/customers.csv --format json | jq '.risk'
{
  "score": 100,
  "level": "critical",
  "drivers": [
    "tckn: tc_kimlik (national_id, 10 values, confidence 1.00)",
    "ssn: us_ssn (national_id, 10 values, confidence 0.85)",
    "credit_card: credit_card (financial, 40 values, confidence 1.00)"
  ]
}
make demo runs the first scan from a fresh clone.
Use it as a CI gate
You can fail the build based on privacy risk levels (0=low, 1=medium, 2=high, 3=critical) using --fail-on. A level at or above the threshold produces an exit code of 2.
steps:
  - run: pip install piiscope
  - run: piiscope scan data/ --fail-on high
The repository also ships a reusable GitHub Action:
name: Privacy scan

on: [pull_request]

jobs:
  piiscope:
    runs-on: ubuntu-latest
    permissions:
      contents: read
    steps:
      - uses: actions/checkout@v4
      - uses: barissozudogru/piiscope@v1.3.0
        with:
          path: data/
          fail-on: high
The action writes a SARIF artifact path to its outputs. It does not include matched or redacted sample values.
Generate SARIF directly from the CLI:
piiscope scan data/ --format sarif --output piiscope.sarif
Reproducible benchmark
The Piiscope Structured PII Pattern Benchmark contains 512 deterministic positive and hard-negative cases across English, German, Turkish, and Portuguese contexts. Every value is synthetic, reserved for documentation, or a published test credential. It contains no records collected from people.
Reproduce the checked-in evaluation:
python benchmarks/piiscope-benchmark/generate.py
python benchmarks/piiscope-benchmark/evaluate.py
Version 1.3.0 reaches 1.000 micro precision, recall, exact multi-label match, and hard-negative pass rate on this structured-pattern benchmark. Version 1.2.0 is included as a baseline. The benchmark does not measure real-world prevalence, demographic fairness, or multilingual named-entity recall.
Python API
Call the scan and remediate functions directly in Python:
from piiscope import ScanResult, remediate, scan

result: ScanResult = scan("samples/customers.csv", jurisdictions=["gdpr", "ccpa"])
print(f"Risk Score: {result.risk.score}")
for finding in result.findings:
    print(f"Found {finding.category} in {finding.column}")

if result.metrics:
    print(f"k-anonymity: {result.metrics.k_anonymity}")

print(result.to_markdown())

remediate("samples/customers.csv", "safe.csv", strategy="hash")
What it detects
Built-in detectors, grouped by category (run piiscope patterns for the full table with descriptions):
| Category | Detectors |
|---|---|
| contact | email, us_phone, eu_phone, tr_phone, tr_phone_strict |
| national_id | us_ssn, tc_kimlik, passport, passport_de, passport_tr, passport_uk, national_id |
| financial | credit_card (Luhn-checked), iban, iban_tr, swift_bic, vat, vat_de, vat_tr |
| health | medical_condition, drug_name, hospital_name, medical_record |
| name | given_name, surname |
| demographic | date |
| network | ipv4_address, ipv6_address |
| other | url |
Name detection is deliberately conservative: in free text a token must be capitalised and outside a stoplist of common-word names (will, bill, may, summer, ...), columns that describe places or organisations (city, street, company, ...) never yield person names, and a cell such as "Maria Silva Santos" counts as one given name and one surname. Throughput on a laptop is about 7,000 rows per second on a 300,000-row CSV with free text; files stream in chunks so memory stays flat.
Dictionaries
Name and health detectors use built-in lists shipped with the package: given names from Wikidata (CC0) plus curated per-country top lists, surnames from the US Census 2010 file (public domain) plus curated top lists for Germany, Turkey, Brazil, Spain, France, Italy, the Netherlands and Poland, medicine names from the FDA Drugs@FDA product file (public domain), and a curated list of condition terms in English, German and Turkish. Provenance and regeneration steps are in piiscope/detection/data/README.md (python scripts/build_dictionaries.py). Extend any list at runtime:
piiscope scan data.csv --dictionary given_name=custom_names.txt
Jurisdictions
By default every finding is tagged with the regulations that govern it (GDPR, CCPA, KVKK, LGPD) and scored with that regulation's weighting, so health data and national identifiers count as special categories. Pass --jurisdiction gdpr (repeatable) to restrict the tags and the weighting to the regulations you answer to.
Privacy metrics and risk score
piiscope computes common privacy metrics automatically:
- k-anonymity: The minimum size of groups with identical quasi-identifiers.
- l-diversity: The variety of sensitive values inside those k-anonymous groups.
- t-closeness: How the distribution of sensitive values in a group compares to the whole dataset.
Quasi-identifiers (age, birth date, postal code, gender, city) are picked from column-name hints when you do not pass --quasi-identifiers; the sensitive attribute is the highest-severity finding column. The risk score is the highest-scoring single finding (detector severity, jurisdiction weighting, confidence and how many values matched) scaled to 0-100, with levels low (below 25), medium (25-49), high (50-74) and critical (75 and above). The three strongest findings are listed as drivers so you know what to fix first.
Remediation strategies
Transform findings with one of the following methods:
hash: SHA-256 hex digest.redact: Keep the first and last characters and mask the middle.null: Empty string.generalise: Numbers become ranges, dates become years, everything else is redacted.tokenise: One-way salted hash pseudonym that stays stable when the same salt is reused.date-shift: Shift dates by a fixed number of days.
Reports
Generate compliance reports showing findings, metrics and a DPIA-style summary.
piiscope report data.csv --out scan.html
piiscope report data.csv --out scan.md
piiscope report data.csv --out scan.json
The HTML report provides a formatted summary showing the dataset risk, a breakdown of findings, k-anonymity metrics and actionable next steps.
Run the full platform
The piiscope platform provides a complete web platform including an API, worker, database and React dashboard for file uploads, RBAC, audit logs, webhooks and compliance reporting.
To run it locally:
cp deploy/env.example .env
docker compose -f deploy/docker-compose.yml --env-file .env up --build -d
Access the UI at http://localhost:3000 and API docs at http://localhost:8000/docs. See docs/architecture.md for details. You can also run make up.
Project layout
piiscope/: Core Python package and detection engine.api/: FastAPI REST API service.app/: React UI dashboard.deploy/: Docker Compose and environment configurations.docs/: Architecture and platform documentation.samples/: Example datasets for testing.tests/: Pytest suite.
Contributing, Security and License
Contributions are welcome; see CONTRIBUTING.md for the development workflow and guidelines. For reporting vulnerabilities, check SECURITY.md. Licensed under the Apache 2.0 License.
Data handling: All scans execute completely locally. No data is sent to external servers, and samples included in reports are partially redacted to prevent leakage.
Citation
If you use piiscope in academic work, please cite it. The concept DOI below always resolves to the latest version; use the version DOI to cite a specific release.
- Concept DOI (all versions): 10.5281/zenodo.22071806
- Latest archived release (v1.1.1): 10.5281/zenodo.22071807
@software{sozudogru_piiscope,
  author  = {Sozudogru, Baris},
  title   = {piiscope: find, score and remediate personal data in files and databases},
  version = {1.3.0},
  doi     = {10.5281/zenodo.22071806},
  url     = {https://github.com/barissozudogru/piiscope},
  year    = {2026}
}
1 maintainer

Metadata
1 maintainer
Release files for piiscope 1.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| piiscope-1.3.0.tar.gz | 241.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| piiscope-1.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 471.4 kB
Release files / piiscope-1.3.0.tar.gz
| Download URL | piiscope-1.3.0.tar.gz |
|---|---|
| Size | 241.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8afbd89d332a8473a3490fbfcd573c93f336e76afebebc002d3c3f162b2c5552
|
|
BLAKE2b-256 checksum How to use checksums |
b2e56d10da2bb278189de98b4af9496736b744d7f12539ede82923d6a9097aa6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 26, 2026.
Transparency logRelease files / piiscope-1.3.0-py3-none-any.whl
| Download URL | piiscope-1.3.0-py3-none-any.whl |
|---|---|
| Size | 230.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b39727934f15850bca91dee4213eb3c11fb8228b801d8b8fa386c8eec815aeb6
|
|
BLAKE2b-256 checksum How to use checksums |
2d8bb891227a9033c9c9277eb9ecd04108d9351954af58fccfe8dc0a2f41f8c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 26, 2026.
Transparency log













