
PipelineProfiler
AutoML Pipeline exploration tool compatible with Jupyter Notebooks. Supports auto-sklearn and D3M pipeline format.
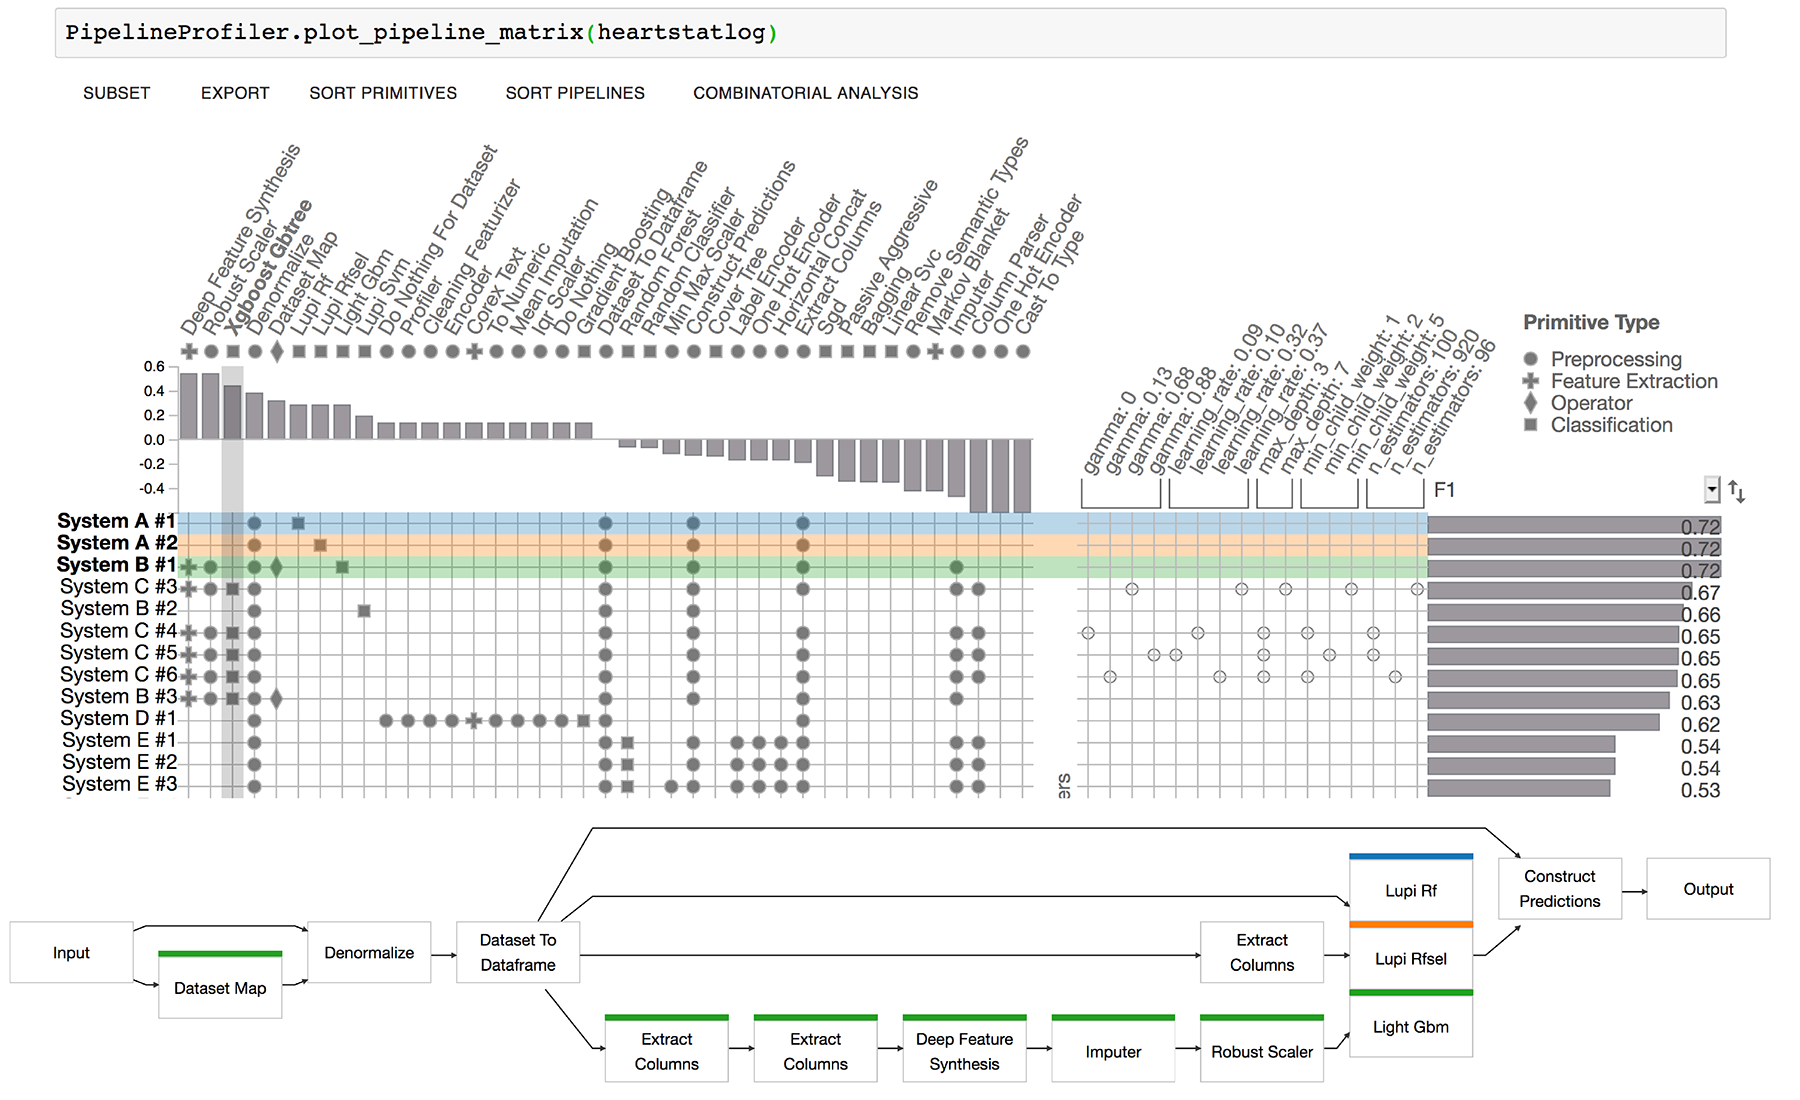
(Shift click to select multiple pipelines)
Paper: https://arxiv.org/abs/2005.00160
Video: https://youtu.be/2WSYoaxLLJ8
Blog: Medium post
Demo
Live demo (Google Colab):
In Jupyter Notebook:
import PipelineProfiler
data = PipelineProfiler.get_heartstatlog_data()
PipelineProfiler.plot_pipeline_matrix(data)
Install
Option 1: install via pip:
pip install pipelineprofiler
Option 2: Run the docker image:
docker build -t pipelineprofiler .
docker run -p 9999:8888 pipelineprofiler
Then copy the access token and log in to jupyter in the browser url:
localhost:9999
Data preprocessing
PipelineProfiler reads data from the D3M Metalearning database. You can download this data from: https://metalearning.datadrivendiscovery.org/dumps/2020/03/04/metalearningdb_dump_20200304.tar.gz
You need to merge two files in order to explore the pipelines: pipelines.json and pipeline_runs.json. To do so, run
python -m PipelineProfiler.pipeline_merge [-n NUMBER_PIPELINES] pipeline_runs_file pipelines_file output_file
Pipeline exploration
import PipelineProfiler
import json
In a jupyter notebook, load the output_file
with open("output_file.json", "r") as f:
    pipelines = json.load(f)
and then plot it using:
PipelineProfiler.plot_pipeline_matrix(pipelines[:10])
Data postprocessing
You might want to group pipelines by problem type, and select the top k pipelines from each team. To do so, use the code:
def get_top_k_pipelines_team(pipelines, k):
    team_pipelines = defaultdict(list)
    for pipeline in pipelines:
        source = pipeline['pipeline_source']['name']
        team_pipelines[source].append(pipeline)
    for team in team_pipelines.keys():
        team_pipelines[team] = sorted(team_pipelines[team], key=lambda x: x['scores'][0]['normalized'], reverse=True)
        team_pipelines[team] = team_pipelines[team][:k]
    new_pipelines = []
    for team in team_pipelines.keys():
        new_pipelines.extend(team_pipelines[team])
    return new_pipelines

def sort_pipeline_scores(pipelines):
    return sorted(pipelines, key=lambda x: x['scores'][0]['value'], reverse=True)

pipelines_problem = {}
for pipeline in pipelines:
    problem_id = pipeline['problem']['id']
    if problem_id not in pipelines_problem:
        pipelines_problem[problem_id] = []
    pipelines_problem[problem_id].append(pipeline)
for problem in pipelines_problem.keys():
    pipelines_problem[problem] = sort_pipeline_scores(get_top_k_pipelines_team(pipelines_problem[problem], k=100))
2 maintainers


Metadata
2 maintainers
Release files for pipelineprofiler 0.1.18
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| pipelineprofiler-0.1.18.tar.gz | 871.9 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pipelineprofiler-0.1.18-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / pipelineprofiler-0.1.18.tar.gz
| Download URL | pipelineprofiler-0.1.18.tar.gz |
|---|---|
| Size | 871.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1e14ed6ed8a08e0726853c4841263411a566d2dcef44624dfa02ecf6ce264432
|
|
BLAKE2b-256 checksum How to use checksums |
4639204e9f0a7fde560e178dd82d987b747d450a0521b5b4db4bf1d9792ece4d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.8.0 pkginfo/1.8.2 readme-renderer/32.0 requests/2.26.0 requests-toolbelt/0.9.1 urllib3/1.26.8 tqdm/4.49.0 importlib-metadata/4.11.1 keyring/23.5.0 rfc3986/2.0.0 colorama/0.4.4 CPython/3.8.12
|
Release files / pipelineprofiler-0.1.18-py3-none-any.whl
| Download URL | pipelineprofiler-0.1.18-py3-none-any.whl |
|---|---|
| Size | 881.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6efe8bfe0bdfbe153d34f27d9c8100c5d02a67fd825591faed5170137011d9d9
|
|
BLAKE2b-256 checksum How to use checksums |
6ec198c22e87afba0a74248632c8b93277b1069083ce580c38edc91c6ecaa30a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.8.0 pkginfo/1.8.2 readme-renderer/32.0 requests/2.26.0 requests-toolbelt/0.9.1 urllib3/1.26.8 tqdm/4.49.0 importlib-metadata/4.11.1 keyring/23.5.0 rfc3986/2.0.0 colorama/0.4.4 CPython/3.8.12
|
Security for pipelineprofiler 0.1.18
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














