
pith — output-token optimizer
Self-hosted output-token control plane for the Claude and OpenAI APIs. It fingerprints routes, records usage, and —
once a route has a pinned output profile — rewrites requests cache-safely to shorten outputs. Run it as a drop-in
proxy, or plug it into a gateway you already run: LiteLLM, Headroom, or Portkey (see Where pith runs).
Design: docs/design/specs/2026-10-07-output-token-optimizer-design.md.
How it decides: docs/methodology.md.
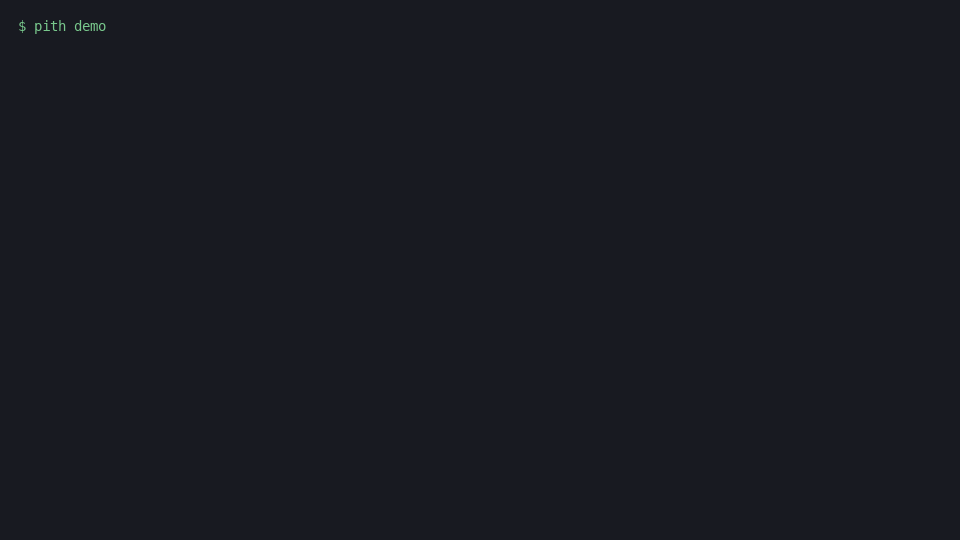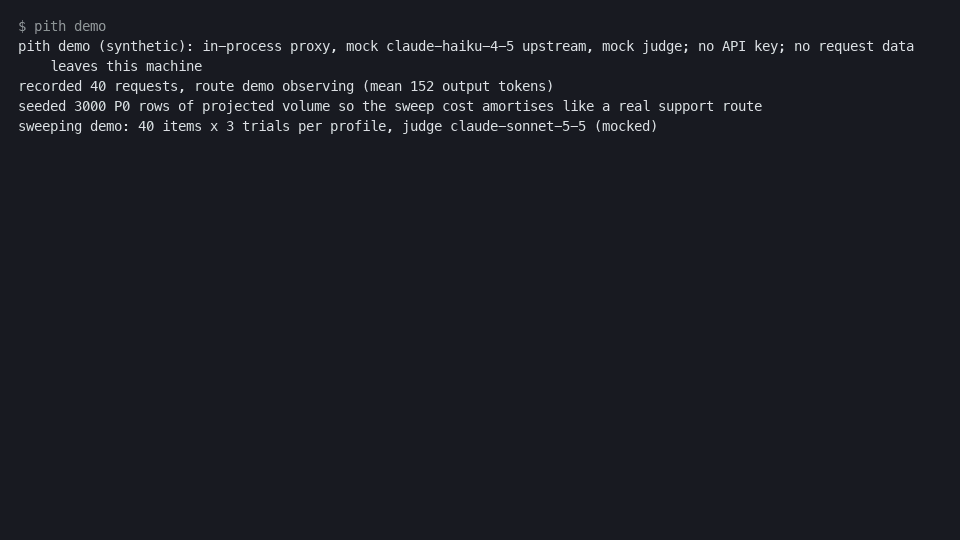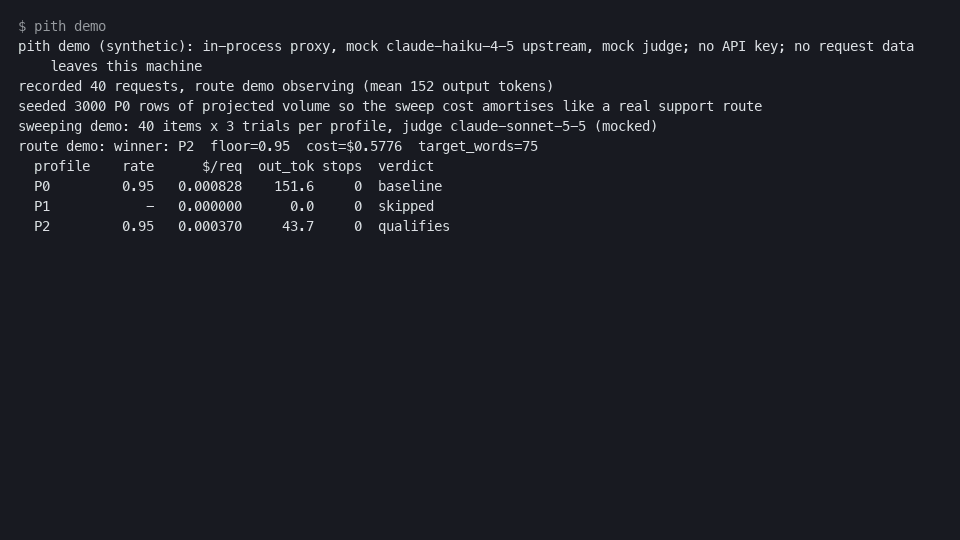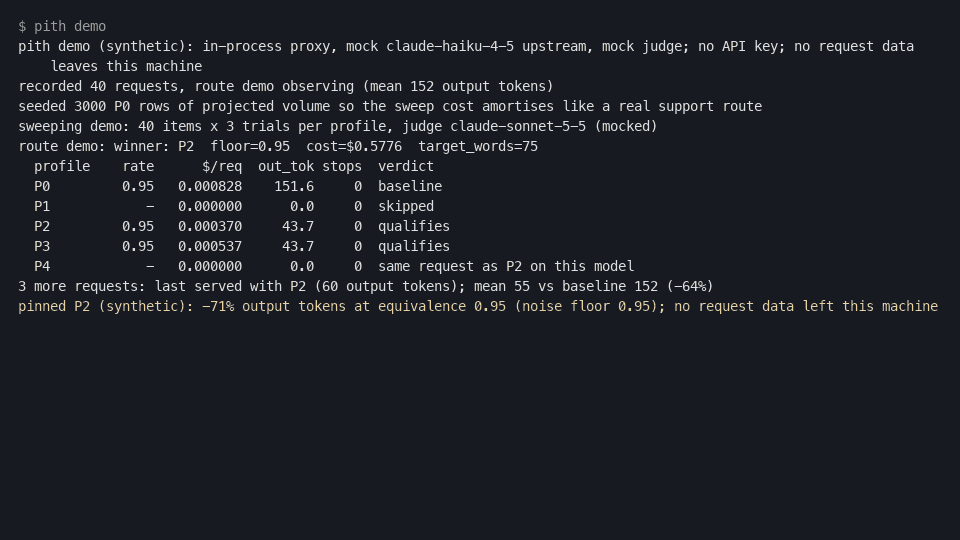
Try it in a minute, with no API key: pip install pith-optimizer && pith demo runs the whole loop in-process against
a mock upstream and a mock judge, so no request data leaves the machine: 40 requests recorded through the proxy, a
sweep, a pin, and the pinned profile served on the next requests (--items, --trials, --seed; --db keeps the
run in a scratch SQLite file, never your real pith.db). Numbers are synthetic and show the mechanics, not savings;
see Live results for measured numbers.
Live results
Measured against the real Anthropic API on 2026-10-10 with tests/live/test_sweep_demo.py: a support-ticket
classification route on claude-haiku-4-5 (30 real requests through the proxy, then a sweep at --trials 3,
judge claude-sonnet-5-5). The sweep cost about $1.3 and took 24 minutes.
| Profile | What it does | Equivalence (per-item majority) | Output tokens / request | $/request* | Verdict |
|---|---|---|---|---|---|
| P0 | unconstrained baseline | 0.933 ± 0.046 (self-consistency = noise floor) | 160 | $0.000860 | baseline |
| P1 | effort one notch down | — | — | — | skipped (no effort on this model) |
| P2 | terse-shape instruction | 0.933 ± 0.046 | 78 (−51%) | $0.000579 (−33%) | pinned |
| P3 | shape + one-shot exemplar | 0.900 ± 0.056 | 99 (−38%) | $0.000804 | qualifies, costlier than P2 |
| P4 | effort down + shape | — | — | — | same request as P2 on this model |
* Haiku 4.5 at $1/$5 per million tokens, including the sweep's own cost amortized over projected monthly volume.
The pinned instruction matches the unconstrained model's agreement with itself exactly, at 51% fewer output tokens
and 33% lower cost per request, on one 30-item run; a larger run with a holdout is the next step, and recheck
re-judges live traffic after a pin and reverts on drift. An earlier run (2026-10-08) of the same demo reported "P4
pinned at −56%": Haiku has no effort parameter, so P4's request was byte-identical to P2's and the sweep judged the
same request twice, once at 0.833 and once at 0.933, and pinned on the second. The sweep now judges identical
effective requests once and reports the duplicate as an alias, which is the P4 row above.
Two larger runs on distinct tickets with a 30% holdout requested (OPTIMIZER_DEMO_HOLDOUT=0.3) did not pin anything,
and those are the more informative results:
| Run | Profile | Equivalence on the fit set | Output tokens / request | Verdict |
|---|---|---|---|---|
| 100 tickets, fit 70 ($2.99, 55 min) | P0 | 0.871 ± 0.040 (noise floor) | 171 | baseline |
| P2 | 0.829 ± 0.045 | 80 (−53%) | rate below bar | |
| P3 | 0.786 ± 0.049 | 85 (−50%) | rate below bar | |
| 200 tickets, fit 140 ($5.99, 1 h 50 min) | P0 | 0.829 ± 0.032 (noise floor) | 175 | baseline |
| P2 | 0.779 ± 0.035 | 82 (−53%) | rate below bar | |
| P3 | 0.671 ± 0.040 | 89 (−49%) | rate below bar |
P4 was the same request as P2 in both runs and was not judged again. With diverse prompts the unconstrained model agrees with itself less often than on the ten repeated tickets (0.93 → 0.87 → 0.83 as the prompt set widens), and the terse instruction lands 0.04–0.05 below that floor each time: inside the sampling error at n=70, at the edge of it at n=140, and in the same direction both times. So on this route the shape instruction halves output tokens but is probably slightly less faithful than the baseline is to itself, and the one-shot exemplar is clearly worse. The sweep refused to pin on that evidence, which is the behaviour it should have, and the holdout never ran because nothing reached it. Read the three runs together: the 30-item pin above is what ten repeated tickets look like, and the larger runs are what a real route looks like.
A short-answer route tells the other half of the story, and the stored judgments say exactly where the loss is. Same
tickets, system prompt "Classify each ticket as one of: shipping, refund, account, product, other" with no length hint
(OPTIMIZER_DEMO_ROUTE=classify). Unprompted, Haiku answers with the label and a sentence of justification. Two runs:
| Run | Profile | Equivalence on the fit set | Output tokens / request | $/request (raw) | Verdict |
|---|---|---|---|---|---|
| 100 tickets, fit 70 ($1.30, 28 min) | P0 | 0.971 ± 0.020 (noise floor) | 38 | $0.000237 | baseline |
| P2 | 0.929 ± 0.031 | 9 (−77%) | $0.000122 (−48%) | rate below noise floor tolerance | |
| P3 | 0.957 ± 0.024 | 27 (−29%) | $0.000244 | not cheaper than P0 | |
| 200 tickets, fit 139 ($2.56, 56 min) | P0 | 0.971 ± 0.014 (noise floor) | 39 | $0.000244 | baseline |
| P2 | 0.885 ± 0.027 | 13 (−67%) | $0.000143 (−41%) | rate below bar | |
| P3 | 0.914 ± 0.024 | 23 (−43%) | $0.000215 | rate below noise floor tolerance |
Reading the first 200-item run's judgments (OPTIMIZER_DEMO_DB keeps them): of 417 P2 trials, 24 were extra-info,
19 contradiction and 10 missing-info, concentrated on 16 of 139 tickets. Replaying three of them showed the
mechanism: the shape text then began "Answer directly", and on a classification route that nudged the model to
answer the ticket (for "How do I delete my account and all my data?" the terse reply was the label followed by
invented steps) or to change the label. The shape text was changed to ask only for concision (shape text v2; pins are
tied to the text version they were validated under), and the same 200-item run was repeated ($2.49, 58 minutes):
| Profile | Equivalence on the 140-item fit set | Output tokens / request | $/request (raw) | Verdict |
|---|---|---|---|---|
| P0 | 0.942 ± 0.020 (noise floor) | 42 | $0.000256 | baseline |
| P2 | 0.906 ± 0.025 | 10 (−77%) | $0.000126 (−51%) | rate below noise floor tolerance |
| P3 | 0.942 ± 0.020 | 24 (−44%) | $0.000223 (−13%) | sweep cost not recovered at projected volume |
The wording fix removed the failure it targeted: extra-info fell from 24 to 4 and missing-info from 10 to 3. What
remains for the label-only P2 is label disagreement (28 contradiction trials, against 10 inside the baseline's own
noise pairs), and it misses the floor's tolerance by 0.004. P3, label plus a one-line justification, now matches the
baseline's self-consistency exactly at 44% fewer output tokens and qualifies on every quality condition; it is held
back only by economics: a $2.49 sweep cannot repay a $0.00003-per-request saving at the demo's simulated 13k
requests a month, and the table says so. At roughly 80k requests a month the same numbers pin P3, which is the
honest shape of the product on a cheap route: the sweep is a fixed cost, so it pays on volume.
The cache-safety check (tests/live/test_cache_safety.py) passed in the same session: a P2-pinned route on
claude-opus-5-5 still reported cache_read_input_tokens > 0 on the second request, so the rewrite does not
re-bill the customer's prompt cache.
What the earlier failing runs showed, and what changed because of them: haiku rejects the mid-conversation system
message the shape profiles inject (the sweep now falls back to the user-text form like the proxy does); the judge
reasons in prose and ends with the bare label (the parser now reads the first or last standalone line); a $1 sweep
cannot repay itself on a 30-request route (the table says so instead of "not cheaper"); and across runs the noise
floor swung 0.80–0.97 on 30 items, so the absolute equivalence_bar is capped by the floor and the comparison
tolerance follows the sampling error.
Run
pip install pith-optimizer
pith serve --config pith.toml
pith.toml starts from pith.example.toml; every scalar setting is also an OPTIMIZER_<FIELD>
environment variable. From a checkout, python -m pith is the same CLI:
python3 -m venv .venv && .venv/bin/pip install -e .
cp pith.example.toml pith.toml
.venv/bin/python -m pith serve --config pith.toml
Point your client at it and keep your own API key:
ANTHROPIC_BASE_URL=http://localhost:8787   # Anthropic SDKs
OPENAI_BASE_URL=http://localhost:8787/v1   # OpenAI SDKs
Where pith runs
One SQLite, one sweep CLI, four ways to put the data plane in front of your traffic. All of them honour
X-Optimizer: off|bypass and X-Optimizer-Route (Portkey: the equivalent metadata keys), fail open on any pith error,
and never log exception text.
| Standalone proxy | LiteLLM plugin | Headroom plugin | Portkey plugin | |
|---|---|---|---|---|
| Attaches as | pith serve, point SDKs at it |
guardrail in config.yaml |
two entry points, enabled by env | default.webhook hooks in the Portkey config |
| Code in the host | none | none | none | none |
| Profiles applied | P1–P4 (effort + shape) | P2/P3 (shape, user text) | P1–P4 (effort in the raw body, shape after compression) | P2/P3 (shape, user text) |
| Streams recorded | yes | yes | yes | no (Portkey delivers no body) |
| Provider rejections | retried with the original, counted | counted (provider-attributed 400/422) | counted for effort rewrites only | invisible to hooks |
| Routes swept via | provider APIs | the LiteLLM proxy (litellm_upstream) |
provider APIs | the Portkey gateway (portkey_upstream) |
| Keys for sweeps | ANTHROPIC_API_KEY / OPENAI_API_KEY |
LITELLM_API_KEY |
ANTHROPIC_API_KEY / OPENAI_API_KEY |
PORTKEY_API_KEY + [portkey_headers] |
| Known limits | — | chat completions only | /v1/responses passes through; keep Headroom's cache and shaper off with pins |
OpenAI-format only; no revert-on-rejection |
Pick one per route: two pith instances in one chain would shape the same request twice.
Kill switches
- Per request: header
X-Optimizer: off(forces P0).X-Optimizer: bypassalso skips recording. - Per route:
[routes."<key>"] enabled = falseinpith.toml. - Global:
OPTIMIZER_ENABLED=0.
Any proxy-side failure forwards your original request unchanged.
LiteLLM plugin
Already running a LiteLLM proxy? Register pith as a guardrail instead of
adding a second hop. Install pith into the LiteLLM proxy's environment and add to its config.yaml:
guardrails:
  - guardrail_name: pith
    litellm_params:
      guardrail: pith.guardrail.PithGuardrail
      mode: [pre_call, post_call]
      default_on: true

# in the proxy's environment
OPTIMIZER_CONFIG=/path/to/pith.toml      # optional; every scalar setting is also an OPTIMIZER_<FIELD> variable; [routes] and [prices] need the toml
pip install pith-optimizer
The guardrail fingerprints every /v1/chat/completions request, records usage into the same SQLite the CLI reads, and
applies a pinned profile by appending the shape text to the last user message. Only P2 and P3 apply through LiteLLM:
LiteLLM folds system messages into the provider's system prompt (cache-breaking), and a guardrail cannot retry a
rejected request, so effort profiles are left to the standalone proxy. The kill switches above still work: the
guardrail reads X-Optimizer and X-Optimizer-Route from the request headers LiteLLM records. Any pith error inside a
hook is logged and the request proceeds unchanged. Three provider-attributed 400/422 responses on a pinned route revert
it to P0; the count resets when the route is re-pinned. The guardrail writes to SQLite from each LiteLLM worker process;
keep the database on local disk (WAL handles concurrent workers). To see the report for guardrail-recorded routes, run
python -m pith serve --config pith.toml against the same db_path and open /optimizer/report.html.
Sweep those routes from the same host, through the LiteLLM proxy (replays carry X-Optimizer: bypass, so the guardrail
ignores them):
litellm_upstream = "http://localhost:4000"   # pith.toml
[prices."<model_name as clients send it>"]   # required: LiteLLM aliases are not in the built-in price table
input = 1.25
output = 10.0

export LITELLM_API_KEY=sk-...                 # a LiteLLM virtual key or the master key
.venv/bin/python -m pith sweep --config pith.toml
Set judge_provider = "litellm" and a judge_model LiteLLM serves to run the judge through it as well.
Headroom plugin
Running Headroom's proxy? Install pith into the same environment and enable its two extensions; no second hop and no Headroom code changes:
pip install pith-optimizer
HEADROOM_PROXY_EXTENSIONS=pith HEADROOM_PIPELINE_EXTENSIONS=pith OPTIMIZER_CONFIG=/path/to/pith.toml headroom proxy
(headroom proxy --proxy-extension pith is the flag form of the first variable; the pipeline extension has no flag.)
The proxy extension installs a middleware that fingerprints each /v1/messages and /v1/chat/completions request on
the client's original body, records usage from the response, and rewrites effort parameters for P1/P4 pins. The pipeline
extension appends the shape text for P2/P3/P4 pins at Headroom's PRE_SEND stage, after compression, as user text.
Routes recorded this way are ordinary Anthropic/OpenAI routes: the same keys as traffic through pith serve, swept with
ANTHROPIC_API_KEY/OPENAI_API_KEY and the full profile set. X-Optimizer: off|bypass and X-Optimizer-Route work
as usual. Keep Headroom's own output shaper off (HEADROOM_OUTPUT_SHAPER unset) and its learned verbosity steering off
(HEADROOM_VERBOSITY_LEVEL unset, no headroom learn --verbosity) while pith is enabled: two steering instructions
would fight. Turn Headroom's response cache off while pins are in use (HEADROOM_CACHE_ENABLED=false): its entries are
keyed before pith shapes a request, so a shaped response can be served to an unshaped one and vice versa. Cache hits
never reach the provider and are never recorded. /v1/responses passes through unrecorded. Any pith error forwards the
request unchanged. Headroom's beacon and telemetry switches are Headroom's own (HEADROOM_BEACON=off).
Portkey plugin
Behind a Portkey gateway, pith needs no gateway code: Portkey's built-in
default.webhook check calls pith before and after each request. Run pith serve where the gateway can reach it and
add two hooks to the Portkey config (x-portkey-config header or a saved config):
{
  "before_request_hooks": [{"type": "mutator", "id": "pith-before",
    "checks": [{"id": "default.webhook", "parameters": {"webhookURL": "http://pith:8787/optimizer/portkey",
                                                        "headers": {"authorization": "Bearer <webhook_token>"}}}]}],
  "after_request_hooks":  [{"type": "guardrail", "id": "pith-after", "deny": false,
    "checks": [{"id": "default.webhook", "parameters": {"webhookURL": "http://pith:8787/optimizer/portkey",
                                                        "headers": {"authorization": "Bearer <webhook_token>"}}}]}]
}
The before hook fingerprints the request and, for a pinned route, returns it with the shape text appended to the last
user message; the after hook records usage into the same SQLite the CLI reads. x-portkey-metadata keys: pith_route
(name the route), pith_bypass (skip pith entirely), pith: "off" (force P0). Set webhook_token in pith.toml
when the endpoint is reachable beyond the gateway. Limits: only OpenAI-format (chatComplete) requests are handled;
streaming responses are seen but not recorded (Portkey delivers no body for them); provider rejections are invisible
to after hooks, so recheck is the drift guard; Portkey appends hook_results to responses whenever hooks run. Only
P2/P3 apply through Portkey. Note the port clash: Portkey's gateway and pith both default to 8787, so move one.
Sweep those routes through the gateway: set portkey_upstream, put a [prices."<model>"] entry for each model name
the clients send, add any routing headers under [portkey_headers] (a saved config id, provider, virtual key), export
PORTKEY_API_KEY, and run python -m pith sweep. Replays and the judge carry x-portkey-metadata: {"pith_bypass": true}
so the webhook ignores them; judge_provider = "portkey" runs the judge through the gateway too.
Without webhook_token, anyone who can reach pith can post hook payloads that write usage rows and sweep samples, so set
the token or keep pith on a private network (pith logs a warning at startup when the endpoint is open and not bound to
loopback). Open-source gateway users: sweeps still require PORTKEY_API_KEY in the environment, but the OSS gateway
ignores it, so any dummy value works. Provider credentials go in [portkey_headers] (authorization, or an
x-portkey-config JSON with api_key), which puts a secret in pith.toml, so protect that file; saved config ids and
virtual keys exist only on the hosted product. judge_provider = "portkey" requires the gateway config to route
judge_model: with x-portkey-provider = "openai" the judge model must be an OpenAI model. Do not chain pith adapters
(for example pith serve with Portkey as its upstream while the webhook is also active): the inner adapter would strip
the outer one's shape text and misattribute it. Metadata flags accept booleans or the strings true/false, 1/0,
yes/no, on/off.
Sweeps: turning observation into pins
The proxy never holds an API key, so sweeps run from the CLI with keys in its environment:
export ANTHROPIC_API_KEY=...   # and/or OPENAI_API_KEY
.venv/bin/python -m pith sweep --config pith.toml --dry-run     # spends, prints, writes nothing
.venv/bin/python -m pith sweep --config pith.toml               # pins the cheapest profile that clears the bar
A route is swept once it has 50 sampled baseline requests (sample_rate controls sampling) and ≥80% text-ending
responses. The sweep replays the frozen sample under each profile, judges equivalence against the unconstrained
baseline (judge_model), and pins only a profile that is at least as consistent as the baseline is with itself. equivalence_bar is an absolute floor on quality, but it is capped by the route's own self-consistency: if the unconstrained model agrees with itself only 85% of the time, a profile that also reaches 85% qualifies. Routes whose self-consistency is under 50% are never pinned. Judgments are taken per item by majority across trials (use an odd --trials, default 3), every pair of baseline trials is judged for the noise floor, and the comparison tolerance widens with the sweep's sampling error.
A pin is tied to the shape-text version it was validated under; after a pith upgrade that changes the text, the route drops its pin on the next request and goes back to observing until it is swept again.
sweep_budget_usd_month = 0 (the default) refuses every sweep; set a ceiling, or pass --budget-usd per run.
Sweep flags: --route <key> (one route; also sweeps a pinned one), --trials N (replays per item, default 3),
--sample N (items per sweep, default 50), --dry-run, and --budget-usd X, a ceiling for the whole run: each
swept route draws it down and a route whose estimate no longer fits is refused. --holdout F (0 ≤ F < 0.5, default 0)
holds back a fraction of the sample; the winner is replayed and judged on it alone and pinned only if it clears the same
rule there (reason failed holdout: … otherwise). Held items whose request also appears in the fit set are dropped, so
the holdout is out-of-sample; its bar allows the same sampling-error tolerance as the noise-floor check, and a holdout
that cannot be judged (winner a no-op there, or no baseline consistency) fails rather than pins. The printed table ends
with a holdout line when a holdout was requested (not run (…) if there was no winner or no out-of-sample item), and
the stored result carries the holdout's own P0/winner table; its spend is amortized like the rest of the sweep. --dry-run and recheck spend is not
counted against sweep_budget_usd_month; only live sweeps are. recheck --route <key> --n N re-judges the last N live responses.
Exit codes: 0 done, 2 refused (budget, price, or missing key), 1 aborted.
A sweep's own cost is amortized over the route's projected monthly volume (last 7 days × 30/7, floor 1,000 requests) and
added to every candidate's $/request, so a profile is pinned only if it repays the sweep within a month. On a tiny route
the table will say sweep cost not recovered at projected volume even for a profile that is cheaper per request —
that is the honest answer, not a failure.
Drift: python -m pith recheck re-judges recent live responses on pinned routes and reverts a route to P0 when
its rolling equivalence falls below the same floor-capped bar the pin used (min(bar, noise floor), with the floor read from the route's last sweep and the current configured bar used;
the configured bar alone when no sweep with a numeric floor is on record), less the same sampling tolerance the pin allows. Run both from cron, e.g. a nightly recheck and a weekly sweep.
Audit: GET /optimizer/sweeps/<route key> returns every sweep for a route with its per-profile table.
Name a route explicitly with the request header X-Optimizer-Route: <name>.
The proxy has no authentication of its own — bind listen to a private interface. On first use of an OpenAI stream
without usage, token estimation downloads the o200k_base vocabulary once (set TIKTOKEN_CACHE_DIR to pre-seed it on
egress-filtered hosts; if the download fails the proxy falls back to a length estimate and flags the row as estimated).
Report
GET /optimizer/report (JSON) · GET /optimizer/report.html
Tests
.venv/bin/pip install -e '.[dev]' && .venv/bin/pytest
OPTIMIZER_LIVE=1 ANTHROPIC_API_KEY=... .venv/bin/pytest tests/live   # cache-safety check (~$0.02) and sweep demo (~$1.3, ~30 min)
For repeated live runs keep the key in a git-ignored .env (ANTHROPIC_API_KEY=..., chmod 600) and run
set -a; . ./.env; set +a; OPTIMIZER_LIVE=1 .venv/bin/pytest tests/live.
The sweep demo takes OPTIMIZER_DEMO_SAMPLE (items, default 30), OPTIMIZER_DEMO_HOLDOUT (fraction, default 0) and
OPTIMIZER_DEMO_BUDGET (USD ceiling, default 10), plus OPTIMIZER_DEMO_ROUTE (support, the explanatory
default, or classify) and OPTIMIZER_DEMO_DB (a SQLite path that keeps the sweep's judgments for inspection): 30 items cost about $1.3 and take about 30 minutes; 100 items with a
30% holdout are estimated at about $4, have cost about $4, take about 75 minutes, and need the budget of 10; 200 items with a 30% holdout are estimated at about $7, have cost
about $6, and need the budget of 15.
OPTIMIZER_LITELLM_LIVE=1 .venv/bin/pytest tests/live/test_litellm_mock.py boots a real LiteLLM proxy with a mock
model and the guardrail (needs pip install 'litellm[proxy]', no API key).
OPTIMIZER_HEADROOM_LIVE=1 .venv/bin/pytest tests/live/test_headroom_mock.py boots Headroom's real proxy app with the
pith extensions against a mock upstream (needs pip install headroom-ai and a re-run of pip install -e ., no API key).
OPTIMIZER_PORTKEY_LIVE=1 .venv/bin/pytest tests/live/test_portkey_mock.py runs the open-source Portkey gateway via
npx (needs Node and a free port 8787) with the webhook hooks against a mock upstream; no API key.
The three gateway live tests also run weekly in CI (the integrations workflow, also runnable by hand) against pinned
LiteLLM 1.104.2, Headroom 0.40.0 and Portkey gateway 1.15.2. The job guards pith's own changes against those pinned
versions (and unpinned transitive dependencies); a new gateway release is tested by bumping the pin in the workflow.
License
MIT — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for pith-optimizer 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pith_optimizer-0.2.0.tar.gz | 92.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pith_optimizer-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 147.4 kB
Release files / pith_optimizer-0.2.0.tar.gz
| Download URL | pith_optimizer-0.2.0.tar.gz |
|---|---|
| Size | 92.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
40dbf35af146fd7ee5a1291578a08c72f3761e7e64004c771fa487ab8d304c8a
|
|
BLAKE2b-256 checksum How to use checksums |
e1610896f06e6bfe9ec92262beba7065685d4aebaec36c17d19a9d79c8f7f597
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.4
|
Release files / pith_optimizer-0.2.0-py3-none-any.whl
| Download URL | pith_optimizer-0.2.0-py3-none-any.whl |
|---|---|
| Size | 54.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3056de3216e332dff2eadeaaeeeffda2d6c305dc0387b7d10dfc6ab28b83e084
|
|
BLAKE2b-256 checksum How to use checksums |
4091f482e0ab1a9c178e836df806f4c9a8eaddb63c8d5fac69a67bfc6e30b7f5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.4
|













