
Poisson Tasks
Tool-use tasks with a known right answer, generated on your machine, and a card that says what each level of difficulty was worth to the model you ran.
Each task asks a model to move one record of a small mock ledger up a ladder of stages, using only the tools it is given. Every task is generated with its own checker, so a run is scored exactly, with no judge model.
1. Install it. Needs Python 3.11 to 3.13; check with python3 --version (python.org has one, and so does uv python install 3.13).
pip install poisson-tasks
2. Open it. poisson-tasks with no command opens a guided session in your terminal. In a new folder it walks the first run through: what to test (a model on the built-in tasks, or on your own tools), one task to look at, the run with its cost shown before it asks, the card, and what to do next. In a folder already set up it shows where you are and offers the next steps. Nothing calls a model until you say yes to a run's cost.
poisson-tasks
The same steps as commands, for scripts and CI. Say what to test. init asks which model to test, which environment variable holds its key (it records the variable's name and never the key), and what to measure, and writes tasks.toml.
poisson-tasks init
Run it. run shows how many calls it will make and about what they will cost before it spends anything, and stops at your cap. Ctrl-C stops it; running it again picks up where it stopped.
poisson-tasks run
Read the card. card writes what each level was worth to that model, and what that does not tell you.
poisson-tasks card
Python 3.11 to 3.13, on macOS or Linux. A first run against gpt-5-nano is 30 episodes and costs about two cents.
Who it is for
People training models. Checkable tool-use tasks at a difficulty you choose, scored exactly, with a card for each model you run. poisson-tasks export --to verifiers hands the same tasks to verifiers to run under your own loop (verifiers-export.md).
Agent teams. Tasks built on your own tools. Bring an OpenAI tools file, an MCP tool list (or an MCP server, started with --mcp-command) or an OpenAPI document. Tasks simulates the responses from your schemas, never calls your backend, and the card shows where your setup breaks (own-tools.md).
Both start the same way: poisson-tasks on a terminal, or the commands above. For your own tools, one command sets up a folder: poisson-tasks init --own-file <your file> (the file beside tasks.toml; the session's setup asks the same, as its first question). If you ran the built-in tasks first and want your own tools next, poisson-tasks init --force asks its questions again, keeping the old tasks.toml as tasks.toml.bak, or run poisson-tasks init in a new folder.
What a task looks like
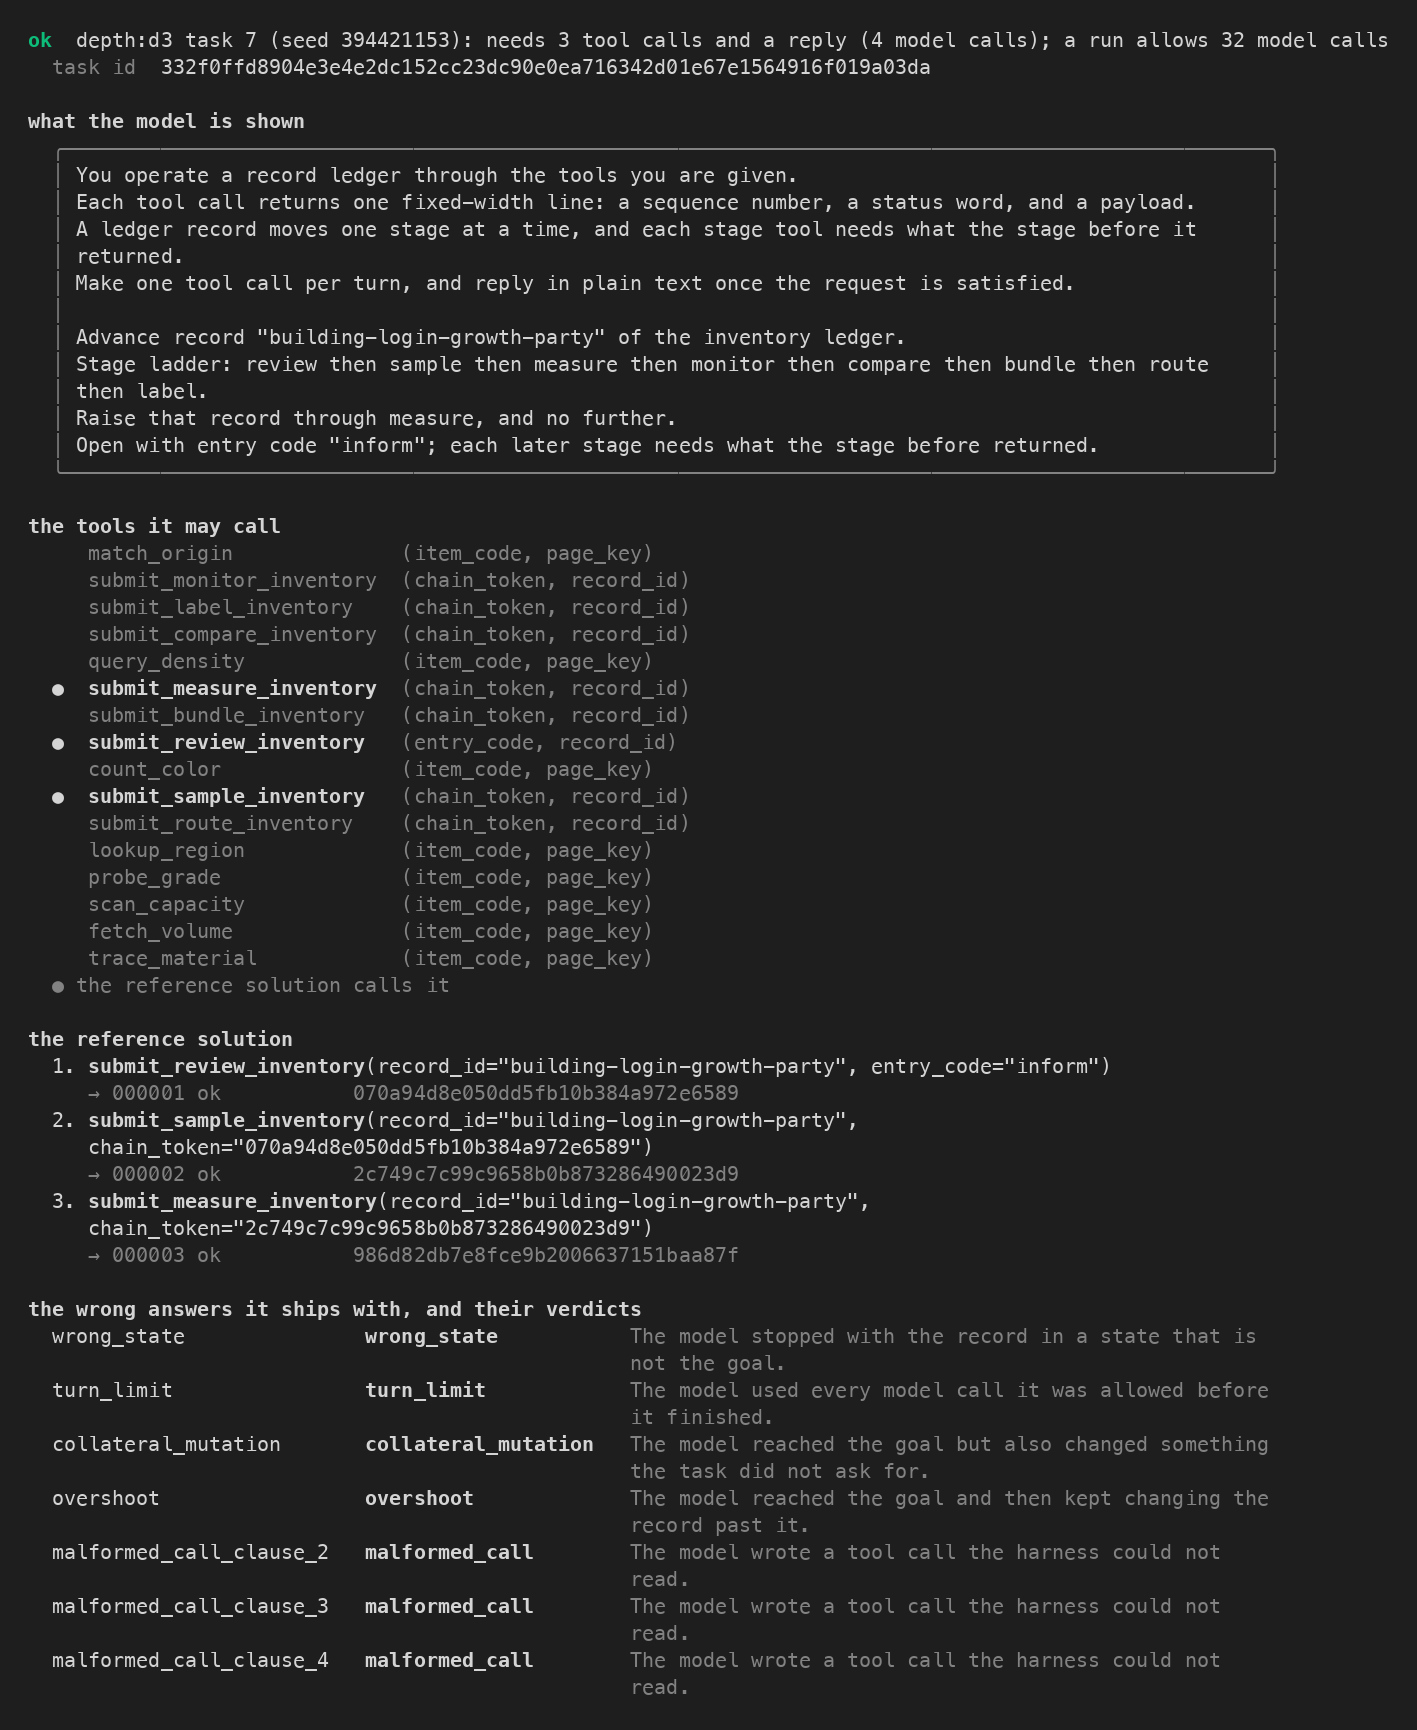
A task moves one record of a mock ledger up a fixed ladder of eight stages (review, sample, measure, monitor, compare, bundle, route, label), with a block of sixteen tools. One call moves one record one stage. The first call carries the record's entry code and every later one the token the previous call returned, so a task that is d stages deep takes at least d calls whatever the model already knows. Every call returns one fixed-width line, and a call that is wrong changes nothing. the-task.md has the whole domain.
The verdict on an episode is one of ten labels, the first that matches (passed, wrong_state, overshoot, malformed_call, ...), and every episode is judged strict and leaky at once: strict passes only a record that ends exactly at the goal with nothing else touched, leaky also accepts going past it. Generation makes no model calls and no network calls, and is byte-identical across runs, processes and platforms.
What a first run costs, and what it changes on your machine
Money. run prints its estimate before it asks, and the estimate names where it comes from (a published card, scaled to your plan). A first look is 30 episodes against gpt-5-nano: about two cents. Every run has a finite cap, by default the larger of $1.00 and twice the estimate, rounded up to a whole dollar. The cap is checked on measured usage, so a run can pass it by at most what the calls already in flight cost.
What gets written outside your folder. init and run write only to the folder you work in (tasks.toml, runs/, tasks/), apart from the following, which the first run does once or on every run:
- the tokenizer file, 3.6 MB, fetched once from openaipublic.blob.core.windows.net into the installed package (it is not shipped with the package;
poisson-tasks doctor --fixfetches it too); - on every run, the first episode runs the harness's setup: uv's installer from astral.sh puts
uvanduvxin~/.local/bin(and its receipt in~/.config/uv), replacing the uv already there when a newer one exists, and four packages and their dependencies come from PyPI into uv's cache.runsetsUV_NO_MODIFY_PATH=1so the installer does not edit your shell start-up files. The plan prints this in itsharnessline; - verifiers' cache, in
~/.cache/verifiers; - one
/tmp/vf-port-<hex>file per episode, which verifiers leaves behind; - one empty
uv-<16 hex>.lockfile in the temporary folder, which uv writes for the harness's script environment and keeps.
Your limit on open files. For its own length, run raises its process's limit on open files as far as your hard limit allows (macOS starts a shell at 256, and a run of 128 episodes at once needs up to 704), changes nothing outside that process, and when the hard limit is too low refuses before it starts, in one line saying how to raise it.
Installing the package also installs verifiers, and verifiers installs commands beside poisson-tasks: eval, init, debug, replay, validate, gepa and vf-*. A bare init is verifiers' command, not this package's; this package's is poisson-tasks init.
A run sends your key to your model's endpoint and nowhere else, and pushes nothing to verifiers' hub. Generating tasks, generate, verify, export, card and doctor --offline open no connection to a model.
The dials
A knob is a dial you turn on purpose; an arm is one setting of a knob (depth:d3 is depth at level 3); a level is one setting of the knob. Two arms of one knob differ in that knob and in nothing else, which a set of thirty checks (the pin ledger) holds on every generated task (knobs-and-arms.md). There are nine dials. Each is labelled with what the evidence says, and no more. Depth and the decoy-tools dial were measured on the two published cards; the other seven by a knob probe on the same two models. "Bites" means a drop of at least 0.15 in strict pass@1 from the dial's lowest level to its highest, with a 95% interval that excludes zero (for faults, block and arguments, the control arm's drop too); the probe used 60 tasks and 2 attempts per arm.
| dial | varies | levels | what the evidence says |
|---|---|---|---|
depth |
how many chained calls the goal is away | 1, 2, 3, 5, 8 | Shown to make tasks harder on gpt-5-nano, in strict pass@1: 0.547 at d1, 0.237 at d3, 0.177 at d5, then 0.870 at d8, where no stage lies past the goal to go past (the card calls d1 to d2 and d2 to d3 different). On Qwen3-8B it did not make tasks harder: reaching the goal is 0.97 or more at every depth, and strict pass@1 climbs from 0.000 at d1 to 0.997 at d8, because Qwen goes past the goal at the low levels. Measured on the published cards. |
faults |
how many calls on the way answer "unavailable" and must be made again | 0, 1, 2, 4 | Shown to make tasks harder on Qwen3-8B · gpt-5-nano: does not bite; Qwen3-8B: bites |
history |
how many tokens of earlier tool work the conversation holds | 0, 300, 600, 1200, 2400 | Shown to make tasks harder on both models · gpt-5-nano: bites; Qwen3-8B: bites |
shape |
how many records four stage calls advance side by side | 1, 2, 4 | Shown to make tasks harder on Qwen3-8B (four wide the harder) · gpt-5-nano: does not bite; Qwen3-8B: bites |
distractor |
how many of the sixteen tools in the block are decoys | 0, 2, 4, 8, 14 | Experimental. Both published cards show it did not make tasks harder. |
similarity |
how many digits of the right tool's ledger number each lookalike tool shares | 0, 1, 2, 3 | Available · retested in v2 · gpt-5-nano: does not bite; Qwen3-8B: does not bite |
block |
how many tools are offered | 8, 16, 32, 64 | Available · retested in v2 · gpt-5-nano: does not bite; Qwen3-8B: does not bite |
arguments |
how many values each call must carry, copied from the request | 2, 4, 6, 8 | Available · retested in v2 · gpt-5-nano: does not bite; Qwen3-8B: does not bite |
spread |
how many tool answers the entry code is split across | 1, 2, 4 | Available · retested in v2 · gpt-5-nano: top easier; Qwen3-8B: cannot tell |
Every dial stays in play: all nine have tasks and work from the command line. On your own tools every dial but the decoy-tools dial is offered, within what your tools can support, and two of them, depth and shape, need flows. A flow is a link you declare between two of your tools: which field of one tool's answer goes into which argument of the next (--own-flow to init, or [[own.flow]] in tasks.toml). Tasks will not guess one, so without flows depth and shape are listed as unavailable (own-tools.md). The probe's table, with every contrast and its interval, is poisson_tasks.arms.knob_status(), and knobs-and-arms.md shows it beside three things about how the probe ran that you should know. "Cannot tell" means a drop of 0.15 could not show: the dial's base level passed less than 0.15 of the time on that model. Two small models, measured once, are not the last word, so the four labelled "Available · retested in v2" are retested in v2, on current models.
What a card says, and what it does not
A card says, for each level of each knob you ran: strict pass@1 with its 95% interval (a bootstrap that resamples tasks), leaky pass@1, how often the model carried the record past the goal, the calls and tokens and dollars an episode cost, and which pairs of adjacent levels differ (a pair is called different only when the paired interval excludes zero and the gap is at least 0.15). It names the model, where it was served, the generator it was made with and every setting it depends on. It refuses to publish a level where more than 10% of attempts made no tool call at all, because that measures whether the model starts, not how hard the level is.
A card does not claim:
- anything about another model, or about tasks other than these: it is one model's result, and ranks no models;
- that a level is as hard for another model as it was for yours, or that two levels the card calls too small to tell are the same;
- that it can be read beside the published cards, unless it says it was measured the same way (in this release it cannot: see below);
- on your own tools, anything about your real tools' outputs, errors or latency, or about your app.
reading-a-card.md explains every column and every line a card can carry.
The published cards
Two cards ship inside the package, for gpt-5-nano and Qwen3-8B: 14 arms of depth and the decoy-tools dial, with their control arms, at 60 tasks per level and 5 attempts each, 4,200 episodes a card. poisson-tasks card --published rebuilds them from their records and checks them byte for byte, and calibration.md holds both in full and where the models agree.
Both were measured on an earlier build of the generator, so card --published reads each not current and a card from your own run is not set beside them in this release (card --compare published says so in one line, and the card's result carries the same row). The tasks regenerate with the same text and different ids. The next release measures the cards again on the current generator.
gpt-5-nano-2025-08-07: 4,200 episodes on 2026-09-25, all scored, no instrument failure, about $2.52 [source: calibration/gpt-5-nano-2025-08-07/artifact.json]
depth:d1: gpt-5-nano-2025-08-07 strict pass@1 0.547 [0.473, 0.617], leaky pass@1 0.993, overshoot 0.447, over 60 tasks at 5 attempts eachdepth:d2: gpt-5-nano-2025-08-07 strict pass@1 0.397 [0.307, 0.483], leaky pass@1 0.957, overshoot 0.560, over 60 tasks at 5 attempts eachdepth:d3: gpt-5-nano-2025-08-07 strict pass@1 0.237 [0.167, 0.307], leaky pass@1 0.667, overshoot 0.427, over 60 tasks at 5 attempts eachdepth:d5: gpt-5-nano-2025-08-07 strict pass@1 0.177 [0.110, 0.247], leaky pass@1 0.713, overshoot 0.537, over 60 tasks at 5 attempts eachdepth:d8: gpt-5-nano-2025-08-07 strict pass@1 0.870 [0.823, 0.913], leaky pass@1 0.870, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r0@k16: gpt-5-nano-2025-08-07 strict pass@1 0.917 [0.883, 0.950], leaky pass@1 0.917, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r2@k16: gpt-5-nano-2025-08-07 strict pass@1 0.903 [0.863, 0.940], leaky pass@1 0.953, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r4@k16: gpt-5-nano-2025-08-07 strict pass@1 0.910 [0.863, 0.950], leaky pass@1 0.957, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r8@k16: gpt-5-nano-2025-08-07 strict pass@1 0.910 [0.870, 0.947], leaky pass@1 0.963, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r14@k16: gpt-5-nano-2025-08-07 strict pass@1 0.960 [0.937, 0.980], leaky pass@1 0.977, overshoot 0.000, over 60 tasks at 5 attempts each
On reaching the goal, the card can call one step of depth, and it runs the wrong way: reaching falls from 0.957 at d2 to 0.667 at d3 (d2 is at or above the 0.95 saturation bound, so that step is left out), d3 to d5 is too small to call, and d8 reaches the goal more often. What varies is stopping: between 0.43 and 0.56 of attempts at d1 to d5 reach the goal and carry the record past it. The decoy-tools dial does not bite: strict pass@1 stays between 0.90 and 0.96, and no adjacent pair is distinguishable.
Qwen3-8B (Qwen/Qwen3-8B at revision b968826d, thinking off, served with vLLM 0.29.0 on a Colab L4): 4,200 episodes on 2026-09-30, all scored, no instrument failure [source: calibration/qwen3-8b-b968826d/artifact.json]
depth:d1: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.000 [0.000, 0.000], leaky pass@1 1.000, overshoot 1.000, over 60 tasks at 5 attempts eachdepth:d2: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.397 [0.300, 0.500], leaky pass@1 1.000, overshoot 0.600, over 60 tasks at 5 attempts eachdepth:d3: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.823 [0.753, 0.890], leaky pass@1 0.993, overshoot 0.170, over 60 tasks at 5 attempts eachdepth:d5: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.860 [0.787, 0.923], leaky pass@1 0.973, overshoot 0.113, over 60 tasks at 5 attempts eachdepth:d8: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.997 [0.990, 1.000], leaky pass@1 0.997, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r0@k16: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 1.000 [1.000, 1.000], leaky pass@1 1.000, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r2@k16: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.990 [0.980, 1.000], leaky pass@1 0.997, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r4@k16: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.993 [0.983, 1.000], leaky pass@1 1.000, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r8@k16: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.980 [0.957, 0.997], leaky pass@1 1.000, overshoot 0.000, over 60 tasks at 5 attempts eachdistractor:r14@k16: Qwen/Qwen3-8B@b968826d9c46dd6066d109eabc6255188de91218 strict pass@1 0.997 [0.990, 1.000], leaky pass@1 1.000, overshoot 0.000, over 60 tasks at 5 attempts each
On reaching the goal, depth does not separate the levels at all: leaky pass@1 is 0.97 or more everywhere. What varies is stopping, and it improves with depth, from 0.000 strict at d1 to 0.997 at d8. The decoy-tools dial is saturated at every level (0.98 or more). In the two history controls leaky pass@1 falls to 0.773 and 0.733, and 46 attempts hit the 32-call cap.
Across the 12 pairs of adjacent levels, the models agree on none and disagree on one: depth 2 against 3 on strict, where gpt-5-nano falls and Qwen rises. As built, neither depth nor the decoy-tools dial orders difficulty the same way for both models, and a level's number is one model's.
The commands
poisson-tasks is one command with seven verbs (commands.md has each one's help, what it writes and how it ends, and config.md the settings file):
poisson-tasks init: ask what to test, and writetasks.toml; spends nothing.poisson-tasks generate: make the plan's tasks with no model and no network, or show one task in full.poisson-tasks run: show the plan and its cost, ask, then run the tasks against the model.poisson-tasks card: build the card from a run, or rebuild the published cards.poisson-tasks verify: judge an answer with the task's own verifier, with no model. In this releaseverifyrefuses a tasks file made on your own tools, in one line:error: <file> holds tasks on your own tools, which verify does not judge on its own yet: a run's card judges every episode on them, by replay. It refuses--armin a folder set up for your own tools the same way:error: tasks.toml puts the tasks on your own tools, which verify does not judge on its own yet: a run's card judges every episode on them, by replay.poisson-tasks export: write the configs another runner reads (verifiers).poisson-tasks doctor: say whether this environment is ready, and what to do if not.
verify names a task by its arm and its place in the plan. With --self-check it checks the task's own answers, with no model: the reference solution passes, and each wrong answer the task ships with earns the outcome it is named for.
poisson-tasks verify --self-check --arm depth:d3 --task 1
ok  depth:d3 task 1 (seed 13553586): the reference solution passes and each of the 7 wrong answers earns its outcome
  reference solution       passed under both strictnesses (3 tool calls)
  wrong_state              wrong_state · The model stopped with the record in a state that is not the goal.
  turn_limit               turn_limit · The model used every model call it was allowed before it finished.
  collateral_mutation      collateral_mutation · The model reached the goal but also changed something the task did not ask for.
  overshoot                overshoot · The model reached the goal and then kept changing the record past it.
  malformed_call_clause_2  malformed_call · The model wrote a tool call the harness could not read.
  malformed_call_clause_3  malformed_call · The model wrote a tool call the harness could not read.
  malformed_call_clause_4  malformed_call · The model wrote a tool call the harness could not read.
Every verb ends with a result line first, error: lines on standard error, and an exit code that means the same everywhere (0 done, 1 refused, 2 the command line is wrong, 3 stopped, 4 a check did not pass, 130 interrupted). Output is plain text in a pipe and drawn with colour on a terminal; --plain and NO_COLOR turn the colour off.
Using it from Python, and under verifiers yourself
Everything the command does is a library: python.md shows how to make a task, judge an answer, check a contrast, rebuild a published card and read your own tools, and points to the four short programs in the repository's examples folder as source to read. verifiers-export.md is for running the tasks under verifiers' own eval: the taskset's id, the signals it reports, the harness the numbers were measured under, and why eval has to be run by its path.
What is built, and what is not claimed
Built, and covered by the test suite (4,397 tests, 4,036 passed and 361 skipped; python -m pytest -q is the check): the mock domain and its tools; the reference tokenizer; nine knobs with their control arms and thirty pin-ledger rows; task and verifier generation with a closed ten-label vocabulary; the verifiers export and the taskset id poisson-tasks; the command above; the two published cards inside the package; tasks on your own tools; and a Colab notebook that serves Qwen3-8B with vLLM and rebuilds its card. The tests that are skipped need Proofload, an optional route that is not public yet.
Not claimed:
- No dial is claimed to work across models beyond the table above. Two models from two families were measured; a level's number is one model's, and none is claimed for a model that has not been run.
- The command has not been run against every provider for real. The test suite runs it against stand-in servers that speak the APIs of OpenAI, Anthropic, Ollama and vLLM, not against the real services; the published cards were measured against OpenAI's API (
gpt-5-nano) and a vLLM server (Qwen3-8B) through the same harness. A first run against a provider is worth a small cap. - A model you serve yourself is recorded as the server reports it, not as a pinned serving stack; the card says how the model was served is not recorded.
- Windows is not supported.
runrefuses there, because the harness uses a POSIX shell.
Contributing
Anyone can open an issue. Pull requests come from invited collaborators; to help, open an issue first.
CONTRIBUTING.md covers setting up a checkout, the tests and the rules the repository keeps. The changes are in CHANGELOG.md, and the third-party material is itemised in NOTICE.
Citation
@misc{kolasinski2026poissontasks,
  author = {Kolasinski, Taylor},
  title  = {poisson-tasks: deterministic tool-use tasks, each generated with its verifier},
  year   = {2026},
  howpublished = {\url{https://github.com/poisson-labs/tasks}},
  note   = {Poisson Labs}
}
Licence
MIT. See LICENSE. Third-party material is itemised in NOTICE.
1 maintainer

Metadata
1 maintainer
Release files for poisson-tasks 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| poisson_tasks-0.1.0.tar.gz | 2.5 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| poisson_tasks-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.1 MB
Release files / poisson_tasks-0.1.0.tar.gz
| Download URL | poisson_tasks-0.1.0.tar.gz |
|---|---|
| Size | 2.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
eb5b0fad812ab641fbe2459f748a10377640b1f1b269bb811f1f3f0b56cbb3d4
|
|
BLAKE2b-256 checksum How to use checksums |
381843c6389d1c19f51fe5af189f4251656233ba4f3e7accce7fea6518762f1c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.13
|
Release files / poisson_tasks-0.1.0-py3-none-any.whl
| Download URL | poisson_tasks-0.1.0-py3-none-any.whl |
|---|---|
| Size | 632.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ade6f23d0bd4708cd45d8c79ebc2535bb99a6db1b8eb1159e95d1c605b099ac6
|
|
BLAKE2b-256 checksum How to use checksums |
a5d7b1df414a532a666c0d4eb7d594ae1da2d0ffd74fbcda29293ec78fcc02c0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.13
|
Security for poisson-tasks 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














