
pragmatiq


pragmatiq is a developer-friendly implementation of ideas described in the PRAGMA paper (arXiv:2604.08649) by Ostroukhov et al. It turns user histories made of timestamped key-value events into embeddings that downstream teams can use for probes, LoRA fine-tuning, graph-based AML experiments, and serving.
The repository includes the full stack: a deterministic synthetic banking data generator, tokenizer, padding-free PyTorch model, training pipeline, batch embedding, ONNX/Triton serving, notebooks, and a Streamlit demo. It is GPU-first and CPU-complete: every command picks a CUDA device when one is visible (bf16 at inference, bf16-mixed in training, flash-attn's varlen kernel when installed) and runs the same code in fp32 on a CPU when none is — slower, never a different result contract.
pragmatiq is an independent implementation inspired by the PRAGMA paper (arXiv 2604.08649). It is not affiliated with or endorsed by Revolut.
Contents
- Why this exists
- Quickstart
- What is included
- Architecture
- Repository map
- Workflows
- Using your own data
- Hardware
- Running on GPU
- Extending pragmatiq
- AML over the transfer graph
- Synthetic data realism
- Model sizes
- PRAGMA+Nemotron text-embedding variant
- Defaults where the paper is silent
- Serving with Triton
- Streamlit demo
- Observability
- Notebooks
- Development
- Citation
- License
Why this exists
The PRAGMA paper (arXiv:2604.08649) describes a practical foundation-model recipe for heterogeneous banking behavior: transactions, app sessions, trades, communications, profiles, and transfer relationships. The paper does not ship reference code.
pragmatiq provides an open implementation that researchers, ML engineers, and data scientists can run, inspect, adapt, and benchmark. The goal is not to claim novelty over PRAGMA. The goal is to make the implementation path concrete.
Quickstart
Requirements
| Python | 3.11 or newer |
| torch | 2.6 or newer (the ONNX exporter and weights_only checkpoint loading need it) |
| GPU (recommended) | any CUDA device; flash-attn >= 2.4.1 optional, enables the padding-free varlen attention kernel |
| CPU (supported) | everything runs in fp32; the same commands, the same outputs contract, more wall-clock |
pip install "pragmatiq[train]"
pragmatiq quickstart --n-users 2000 --max-steps 80   # the fast path: a few minutes
pragmatiq quickstart                                 # the reference run (50k users, 400 steps)
pragmatiq info                                       # what device / precision / extras this machine will use
The train extra brings in Lightning, which pretraining (and therefore
quickstart) runs on; a plain pip install pragmatiq is the slim inference
core for embedding with an already-trained run. pragmatiq info prints the
versions, the resolved device (cuda when visible, else cpu), whether
flash-attn is importable, and which extras are installed; pragmatiq --version
prints the package version.
Or from a clone of the repo (for development):
git clone https://github.com/dynamiq-ai/pragmatiq.git && cd pragmatiq
pip install -e ".[dev,full]"
quickstart runs the synthetic pipeline end to end on whatever device
pragmatiq info reports:
- generate synthetic users and event histories,
- fit the key-value-time tokenizer,
- pretrain a nano masked-language model,
- embed users,
- run a gradient-boosting credit-risk probe against a raw-count baseline.
The fast path (--n-users 2000 --max-steps 80) is the right first run on a
laptop; the default is the reference run whose timings the
Hardware table records.
The plain pip install pragmatiq is the slim inference core: validating,
tokenizing, embedding with a trained run, the gradient-boosting probe, and LoRA
fine-tuning all work without any extra. Training needs .[train] — pretraining
runs on Lightning. The other extras add focused tooling: .[serve] for slim
ONNX/Triton export and serving (no Lightning / torch-geometric / transformers),
.[aml] for the GraphSAGE transfer-graph ablation (torch-geometric),
.[text] for the frozen Nemotron text encoder, .[tracking] for Weights &
Biases and TensorBoard mirrors, .[data] for the synthetic realism report
(matplotlib), .[demo] for the Streamlit demo, and .[full] for all of them.
The same workflow is available from Python:
from pragmatiq import api

result = api.quickstart(n_users=2000, max_steps=80)
print(result["message"])
The CLI is intentionally thin. Commands parse arguments, then call public
functions in pragmatiq/api.py, so notebook and production
callers use the same library surface.
What is included
| Area | What pragmatiq ships |
|---|---|
| Synthetic data | Agent-based banking simulator with deterministic seeds, causal labels, fraud/default/AML scenarios, and realism checks. |
| Tokenization | Key-value-time tokenizer for numeric bins, categorical values, descriptor text, profiles, and unseen [UNK] fallbacks. |
| Model | PRAGMA-style profile, event, and history encoders with TimeRoPE, padding-free varlen attention, and tied MLM head. |
| Training | Pretraining on one GPU, many GPUs, or a CPU (same command), resume-safe checkpoints, probes, LoRA fine-tuning, and configurable heads/maskers/value encoders. |
| AML graph | GraphSAGE ablation over transfer graphs using isolated embeddings, pragmatiq features, and hand-crafted graph features. |
| Inference | Batch embedding (bf16 on CUDA, fp32 on CPU), PragmaModel.from_pretrained(run), notebook-friendly embed_records, ONNX, and GPU-first Triton serving. |
| Publication assets | Model card, contribution guide, citation metadata, security policy, Apache-2.0 license, and GitHub templates. |
Architecture
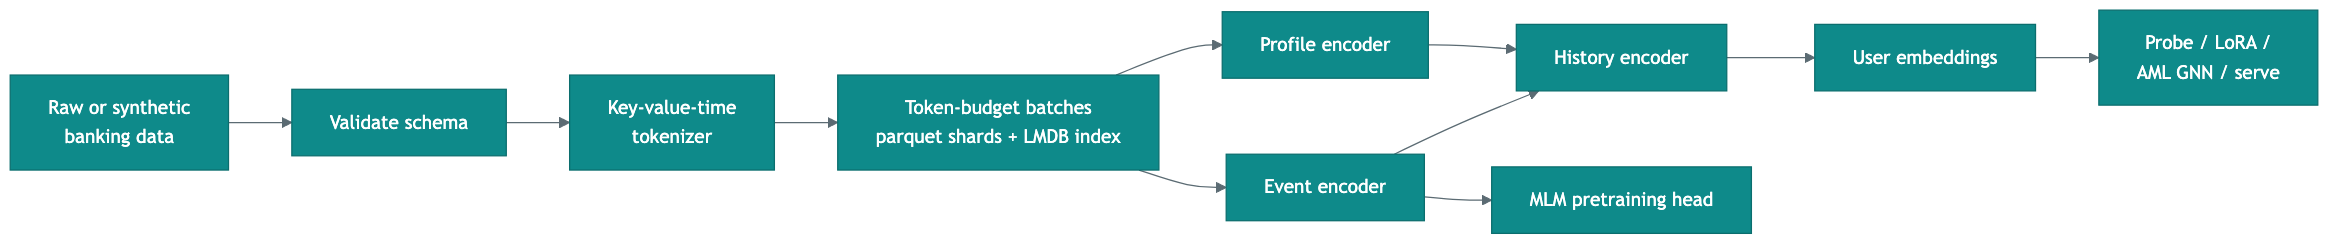
At a high level, pragmatiq follows the PRAGMA recipe:
- Key and value embeddings share one table, also reused for tied MLM logits.
- Continuous time positions use the paper's
8 * ln(1 + delta_t / 8)transform. - Events are encoded independently, then combined with profile information in a bidirectional history encoder.
- Masking combines token, whole-event, and key-level masks;
[UNK]replacements are excluded from MLM loss. - Checkpoints include model, optimizer, scheduler, sampler position, RNG states, tokenizer hash, and resolved config.
- Registries let users customize heads, maskers, and value encoders without forking the library.
See docs/architecture.md for a teaching-grade walkthrough of
the encoders, temporal encoding, and objective, and MODEL_CARD.md for the
objective and limitations write-up.
Paper fidelity
What follows the PRAGMA paper, and what pragmatiq adds on top:
| Component | In the paper | pragmatiq |
|---|---|---|
Key–value–time tokenization, 8·ln(1+Δt/8) time transform, TimeRoPE on continuous log-seconds |
✓ | faithful |
Profile / event / history encoders; 3d MLM head [ẑ_e, z_h(EVT), z_h(USR)] → tied logits + label smoothing |
✓ | faithful |
Masking 15% token / 10% event / 10% key, 10% [UNK]-as-dropout excluded from loss |
✓ | faithful |
| Model sizes 10M / 100M / 1B | ✓ | faithful S/M/L (+ a CPU nano for CI) |
| Pre-training caps (event ≤24 tokens, profile ≤200, ≤6500 most-recent events/user, applied when a batch is collated — after the eval-point cut) | ✓ | faithful |
| PRAGMA+Nemotron frozen-text-embedding variant (MSE reconstruction) | ✓ | implemented, switchable, off by default |
| Synthetic data generator | the paper uses real Revolut data | our addition — agent-based, deterministic |
| AML over the transfer graph (GraphSAGE ablation) | not in the paper | our addition, presented standalone |
| Downstream probe | LoRA + a probe across tasks | gradient boosting is our default probe head |
| Robustness to event staleness (§3.4.2) | ✓ | probe --staleness-window + scripts/benchmarks/staleness_probe.py |
Repository map
pragmatiq/
├── pragmatiq/               # the library — all logic lives here
│   ├── api.py               # public functions: synthesize / tokenize / pretrain / ... (api.__all__)
│   ├── cli.py               # Typer CLI (parses args, calls api.py, nothing else)
│   ├── registry.py          # @register_head / @register_masker / @register_value_encoder
│   ├── validate.py          # data-contract validation with actionable errors
│   ├── core/                # device + precision resolution (env.py), errors, progress bars
│   ├── data/                # schema, tokenizer, sharding, collation, synthetic generator (v2)
│   ├── models/              # encoders, varlen attention (layers.py), MLM head, LoRA, AML GNN
│   ├── training/            # pretrainer, masking, Muon+AdamW, autoconfig, probe, finetuner
│   ├── inference/           # batch embedder, ONNX export, serving runtime + contract, benchmarks
│   └── runs/                # run directories, metric logging, run comparison
├── configs/                 # pretrain / tokenizer / synthetic / finetune YAMLs
├── notebooks/               # 01–04 guided walkthroughs (see Notebooks below)
├── apps/demo/app.py         # Streamlit demo
├── deploy/                  # Triton model repo (+ config.cpu.pbtxt), docker-compose(.cpu).yaml, Prometheus
├── scripts/                 # runpod_launch.py, gpuval/ (GPU validation legs), benchmarks/, baselines/, gates/
└── tests/                   # the spec in executable form — useful usage examples
The tests/ directory doubles as living documentation: for example
tests/test_tokenizer.py shows the tokenizer
contract end to end, and tests/test_training.py
demonstrates bit-exact checkpoint resume.
Workflows
The quickstart is the best first run. Use the commands below when you want to drive each stage explicitly.
1. Generate and tokenize data
pragmatiq synth generate --out data/synth --config configs/data/synthetic.yaml
pragmatiq tokenize data/synth --out data/tokenized --n-workers 8
The generator takes --n-users, --seed, and --n-workers; the same seed
produces byte-identical output for any worker count. To fit generator priors to
aggregate statistics a bank can share (no raw data), use
pragmatiq synth calibrate --stats configs/data/aggregates.example.yaml.
2. Pretrain and embed
pragmatiq pretrain data/tokenized --name demo --model-size small --config configs/pretrain.yaml
pragmatiq embed data/tokenized --run runs/demo --out embeddings.parquet
Inspect and compare runs at any point:
pragmatiq runs list
pragmatiq runs compare demo other-run
3. Evaluate task signal
probe is the fastest check (a gradient-boosting head on frozen embeddings).
Use fine-tuning when you want supervised adapter training on a labeled task;
on a GPU the fine-tuner sizes its token budget from the device memory and
reports per-epoch epoch_stats (batches, tokens, seconds, tokens/s) so a slow
epoch is visible, not silent.
pragmatiq probe data/tokenized --run runs/demo --label data/synth/labels/default_12m.parquet
pragmatiq finetune data/tokenized --run runs/demo --label data/synth/labels/default_12m.parquet \
  --config configs/finetune/credit.yaml
The probe head is gradient boosting by default (HistGradientBoostingClassifier;
--probe-model logistic or lightgbm switch it), which captures the non-linear
structure of a learned embedding better than a linear head. Both ROC-AUC and PR-AUC
are reported — PR-AUC is the honest headline on the low-prevalence risk tasks — and
the raw-count baseline uses the same classifier, so the gap reflects the
representation, not the model family. On the default synthetic book the pragmatiq
probe beats that baseline. When a label table carries an eval_ts column, histories
are truncated at it before embedding — for both the probe and the baseline — so
metrics are forecasts, never hindcasts.
The embedding's value is not specific to credit. The multi-task probe benchmark
(scripts/benchmarks/multitask_probe.py) probes every user-level task against
the same raw-count baseline. The table below is written by that script's
--write flag, carries a provenance stamp, and is refused if it would replace a
larger-scale result.
Event-level fraud/recurring (transaction/series-level) and comm_uplift
(a treatment-effect task — see pragmatiq uplift) are evaluated by their own
paths, not this user-embedding probe.
| task | probe ROC-AUC | baseline ROC-AUC | probe PR-AUC | baseline PR-AUC | prevalence |
|---|---|---|---|---|---|
| default_12m | 0.719 | 0.487 | 0.141 | 0.028 | 0.03 |
| churn_6m | 0.692 | 0.598 | 0.302 | 0.165 | 0.12 |
| ltv_positive | 0.795 | 0.693 | 0.900 | 0.851 | 0.73 |
provenance: n_users=50000, model=small, steps=2000, seed=0, commit=cc48149
Event staleness
In production the event feed lags: the embedding you score
at 09:00 was built from events that stopped arriving some time earlier. The
paper checks that task metrics barely move when the most recent window of
history is missing (§3.4.2). pragmatiq probe --staleness-window 6h (or
api.probe(..., staleness_window="6h")) drops the last 6 hours before every
user's eval point, for the probe and the baseline alike;
scripts/benchmarks/staleness_probe.py sweeps 0 / 1h / 6h / 1d / 3d and writes
the table below with --write.
| task | stale window | probe ROC-AUC | Δ vs fresh | probe PR-AUC | Δ vs fresh | baseline ROC-AUC |
|---|---|---|---|---|---|---|
| default_12m | 0 | 0.710 | +0.000 | 0.131 | +0.000 | 0.487 |
| default_12m | 1h | 0.698 | -0.012 | 0.139 | +0.008 | 0.484 |
| default_12m | 6h | 0.713 | +0.002 | 0.142 | +0.011 | 0.489 |
| default_12m | 1d | 0.702 | -0.008 | 0.119 | -0.012 | 0.484 |
| default_12m | 3d | 0.691 | -0.019 | 0.108 | -0.024 | 0.528 |
| churn_6m | 0 | 0.695 | +0.000 | 0.315 | +0.000 | 0.598 |
| churn_6m | 1h | 0.695 | -0.000 | 0.312 | -0.004 | 0.601 |
| churn_6m | 6h | 0.695 | +0.000 | 0.308 | -0.007 | 0.602 |
| churn_6m | 1d | 0.692 | -0.003 | 0.302 | -0.014 | 0.602 |
| churn_6m | 3d | 0.687 | -0.008 | 0.298 | -0.017 | 0.598 |
provenance: n_users=50000, model=small, steps=2000, seed=0, commit=fd60311
Using your own data
pragmatiq trains on a small parquet contract — four files, strict dtypes
(enforced by pragmatiq validate, defined in
pragmatiq/data/schema.py):
| File | Required columns |
|---|---|
events.parquet |
user_id (string), ts (timestamp[us]), source (string), fields (map<string,string>) |
profiles.parquet |
user_id (string), as_of (timestamp[us]), attributes (map<string,string>), lifelong (list<struct<key: string, ts: timestamp[us]>>) |
transfers.parquet |
optional, for the AML GNN; from_user, to_user (string), ts (timestamp[us]), amount (float64) |
labels/*.parquet |
optional task tables: forecast labels use user_id (string), eval_ts (timestamp[us]), label (int8); AML membership uses user_id, observed_through (timestamp[us]), label (int8) |
The subsections below walk through producing each file from a typical bank data warehouse.
Events: one row per event, fields as a string map
Every event is (user_id, ts, source, fields). source must be one of
transaction, app, trading, communication. fields is a flat
map<string,string>: stringify everything — the tokenizer decides per key
whether a field is numeric (percentile-binned into 64 buckets + a zero
bucket), categorical (one token per value up to 1000 distinct values), or
free text (byte-level BPE). A flattening export looks like this
(Trino/Spark-flavored SQL):
-- one row per event, sorted so each user's rows are adjacent and time-ordered
CREATE TABLE export.events AS
SELECT * FROM (
    SELECT CAST(t.customer_id AS VARCHAR)        AS user_id,
           t.booked_at                           AS ts,
           'transaction'                         AS source,
           MAP(ARRAY['amount', 'currency', 'mcc', 'merchant', 'channel'],
               ARRAY[CAST(t.amount AS VARCHAR), t.currency,
                     CAST(t.mcc AS VARCHAR), t.merchant_name, t.channel]) AS fields
    FROM dwh.card_transactions t

    UNION ALL

    SELECT CAST(a.customer_id AS VARCHAR),
           a.event_time,
           'app',
           MAP(ARRAY['screen', 'action', 'os'],
               ARRAY[a.screen, a.action, a.os])
    FROM dwh.app_events a
)
ORDER BY user_id, ts;
The ORDER BY (user_id, ts) is not cosmetic: pragmatiq validate errors on
out-of-time-order events within a user and warns when one user's rows appear in
non-adjacent blocks (they would tokenize as multiple records). Different
sources can carry completely different field keys — that heterogeneity is the
point of the key-value scheme.
Profiles: static attributes plus lifelong milestones
One row per user: attributes holds static key-values (country, age band,
plan), lifelong holds dated milestones (account opened, KYC passed, first
card), and as_of is the snapshot timestamp:
CREATE TABLE export.profiles AS
SELECT CAST(c.customer_id AS VARCHAR)                      AS user_id,
       CURRENT_TIMESTAMP                                   AS as_of,
       MAP(ARRAY['country', 'age_band', 'plan'],
           ARRAY[c.country, c.age_band, c.plan])           AS attributes,
       ARRAY[ROW('account_opened', c.opened_at),
             ROW('kyc_passed',     c.kyc_at)]              AS lifelong
FROM dwh.customers c;
Transfers and labels
transfers.parquet is the directed money-flow edge list consumed by the
AML GNN — only needed for graph experiments.
Forecast label tables are (user_id, eval_ts, label):
CREATE TABLE export.labels_default_12m AS
SELECT CAST(customer_id AS VARCHAR)            AS user_id,
       observation_date                        AS eval_ts,  -- when the decision was made
       CAST(defaulted_within_12m AS TINYINT)   AS label
FROM risk.default_outcomes;
Why eval_ts matters. pragmatiq probe truncates each user's history at
their eval_ts before embedding, so the embedding only sees what the bank knew
at decision time and the reported AUC is a genuine forecast, not a hindcast on
data that already contains the outcome. The AML task is the deliberate
exception: mule detection is membership classification over observed activity,
so labels/aml.parquet uses (user_id, observed_through, label) and the full
horizon rather than a forecast cut (see MODEL_CARD.md).
Validate, tokenize, pretrain
pragmatiq validate data/mybank
pragmatiq tokenize data/mybank --out data/mybank-tokenized --n-workers 8
pragmatiq pretrain data/mybank-tokenized --name mybank-v1 --model-size small
validate catches dtype mismatches, null ids, null timestamps, unknown sources,
timestamp ordering problems, non-contiguous user rows, and cardinality
pathologies — each finding is a human-readable string with a concrete fix, and
the command exits nonzero on errors. Events must be grouped by user and ascending
in ts; sort by (user_id, ts) before tokenizing (a user whose rows are split
apart is refused rather than silently fragmented). tokenize --n-workers N
parallelizes encoding across processes with a byte-identical guarantee: shard
files are identical for any worker count.
To rehearse this path against sparse data before pointing it at a real feed,
generate synthetic data with missing_field_rate > 0 (a WorldConfig knob): that
fraction of event fields is dropped deterministically, so you can confirm the
validate → tokenize → train flow tolerates missing fields.
Time zones and the calendar features
pragmatiq derives the hour-of-day, day-of-week and day-of-month calendar features
from each event's timestamp, and by default treats timestamps as UTC. If your
data is in a local zone — so the behavioural day/night, weekend and payday
structure is local — set calendar_tz in the tokenizer config to an IANA zone:
# tokenizer.yaml passed via `pragmatiq tokenize --config`
calendar_tz: Europe/London   # default: UTC
or programmatically, api.tokenize(raw, out, config={"calendar_tz": "Europe/London"}).
Pass timezone-aware timestamps so the instant itself is correct; only the
wall-clock calendar features are localized (DST included). calendar_tz is folded
into the tokenizer content hash, so a checkpoint refuses to load against a
tokenizer fitted with a different zone.
Tokenizer knobs for real books
Two TokenizerConfig fields exist only for real-scale data and never bind on
the synthetic book:
max_counter_distinct(default1_000_000) bounds the value tablefit()keeps per key. A continuous numeric key (amounts, balances) would otherwise grow that table to one entry per distinct value; once a key that has only ever parsed as a number exceeds the bound, new values stop being inserted (its classification cannot change). A key that saturates and then stops looking numeric raises with a pointer toforce_numeric/force_categorical— silently routing it to BPE would hide the problem.max_events_per_user(default6500) is recorded in the shard manifest and applied when a batch is collated, after any eval-point truncation, so a heavy user's probe or fine-tune batch holds the most recent events before its eval point rather than a prefix of the globally most recent ones. Shards keep the full history.
[UNK] and when to refit the tokenizer
At inference time, keys and values not seen during tokenizer fitting map to
[UNK] with a logged warning instead of raising KeyError. That makes drift
visible instead of fatal — but a rising [UNK] rate is a signal, not a
feature.
- Reuse a tokenizer (
pragmatiq tokenize newdata --tokenizer-dir data/mybank-tokenized/tokenizer ...) whenever you tokenize new data for an existing trained model. This is mandatory, not just convenient: checkpoints embed the tokenizer content hash andPragmaModel.from_pretrained()refuses to load against a mismatched tokenizer. - Refit a tokenizer (the default, no
--tokenizer-dir) when you are starting a new pretraining run — new bank, new event sources, or enough drift that[UNK]warnings are frequent. A refit changes the vocabulary, so it always implies pretraining a new model with it.
Hardware
The table below is written by the GPU validation run
(scripts/gpuval/, results in docs/benchmarks/gpu-validation-1.1.0.json)
and lists, per model preset, the peak VRAM and pretraining throughput measured
on the validation hardware, plus the quickstart timings and the serving
request rate. It is the source for every performance number in this README;
where a number is missing below, it has not been measured on this build.
Hardware: NVIDIA A100-SXM4-80GB × 8, torch 2.8.0+cu128, flash-attn 2.8.3, CUDA 12.8. Data: 50000 synthetic users, 300 pretrain steps, model small. Run 1.1.0 on 2026-09-14T23:47:52.
| preset | devices | tokens/s | peak VRAM (GB) | DDP efficiency |
|---|---|---|---|---|
| small | 1 | 438,370 | 1.8 | 100% |
| small | 2 | 828,442 | 1.9 | 94% |
| small | 4 | 1,595,042 | 1.9 | 91% |
| small | 8 | 2,416,437 | 1.9 | 69% |
| fine-tune devices | epochs | wall time | best val ROC-AUC | epoch-1 → epoch-2 tok/s |
|---|---|---|---|---|
| 1 | 3 | 181 s | 0.505 | 128,247 → 637,238 |
| 8 | 3 | 543 s | 0.555 | n/a |
| serving device | concurrency | req/s | p50 ms | p99 ms |
|---|---|---|---|---|
| cpu | 1 | 103.7 | 9 | 12 |
| cpu | 4 | 120.7 | 33 | 39 |
| cpu | 16 | 68.1 | 210 | 340 |
| cpu | 64 | 94.1 | 667 | 812 |
| cuda | 1 | 129.0 | 7 | 14 |
| cuda | 4 | 113.9 | 33 | 71 |
| cuda | 16 | 102.5 | 140 | 213 |
| cuda | 64 | 103.0 | 574 | 765 |
- bf16 vs fp32: embed 127 vs 74 users/s; probe ROC-AUC 0.613 vs 0.572 (|Δ| = 0.0413); mean embedding cosine 0.999999.
- flash-attn vs SDPA max abs diff: 0.00e+00 (tolerance 1e-02).
pragmatiq quickstart --n-users 2000 --max-steps 80: 311 s.
Acceptance: 15/16 checks passed. Evidence: docs/benchmarks/gpu-validation-1.1.0.json.
Running on GPU
pragmatiq is GPU-first: every entry point defaults to device="auto", which
resolves to CUDA when a device is visible and to CPU otherwise —
PragmaModel.from_pretrained(run), api.embed, api.probe, api.finetune,
BatchEmbedder, benchmark, the Triton backend. Pin the choice with
PRAGMATIQ_DEVICE=cpu (or cuda:1) instead of threading a flag through every
call; an explicit device="cpu" argument is always honoured as given.
| What | On CUDA | On CPU |
|---|---|---|
Inference (embed, probe, embed_records, serving) |
torch.inference_mode + bf16 autocast; flash-attn varlen kernel when installed |
fp32, byte-stable, SDPA fallback |
| Pretraining | bf16-mixed (Lightning Fabric), DDP across all visible GPUs | fp32 |
| LoRA fine-tuning | bf16 autocast forward, fp32 grads; token budget sized from device memory | fp32, token_budget=16384 |
| Determinism | opt-in deterministic: true (fp32, deterministic kernels) |
byte-identical from a fixed seed |
PRAGMATIQ_INFERENCE_PRECISION=fp32 forces fp32 inference on CUDA (for an
A/B against the bf16 path); bf16 on a CPU device is downgraded to fp32.
PRAGMATIQ_DISABLE_FLASH=1 forces the SDPA path on CUDA — useful for the
deterministic run and for measuring what the kernel buys.
flash-attn is optional but recommended. When flash-attn is importable on
CUDA and the forward runs in bf16/fp16 (the default at inference and in
training), varlen attention calls flash_attn_varlen_func directly on the
packed, padding-free token stream. Everywhere else — CPU, fp32 on CUDA,
PRAGMATIQ_DISABLE_FLASH=1 — pragmatiq falls back to PyTorch SDPA over
length-bucketed padded blocks built from cu_seqlens with a deterministic
scatter (a single long history does not pad the whole batch to its width). The two paths agree to fp32 atol 1e-4 (the padding-equivalence test)
and to bf16 precision (~1e-2) against each other on CUDA (checked on every GPU
validation run). flash-attn ships CUDA-specific wheels, so install the wheel
that matches your torch and CUDA build rather than pip install flash-attn
from source; the RunPod image pragmatiq validates on pairs
runpod/pytorch 2.8 with the flash_attn-2.8.3 cu12 / torch 2.8 / cp311 wheel
(the exact URL is the constant in
scripts/runpod_launch.py).
pragmatiq info reports whether the kernel is available.
The trainer is built on Lightning Fabric and auto-detects CUDA: on GPU it
trains in bf16-mixed precision, on CPU in fp32 — no flags needed,
pragmatiq pretrain is the same command on both. pragmatiq pretrain
defaults to --config auto, which sizes the batch and schedule from the data
and the device (see Scaling hands-off);
pragmatiq pretrain ... --show-config prints the resolved plan (api.pretrain_plan)
without training. Batches are collated on a prefetch thread and pinned
(prefetch_batches, default 2) so the GPU is not waiting on the host.
Knobs that matter
All defaults live in configs/pretrain.yaml and map
1:1 onto TrainConfig in
pragmatiq/training/pretrainer.py; any
key can be overridden via --config or programmatically through
api.pretrain(..., key=value).
| Knob | Default | What it does |
|---|---|---|
max_steps |
20000 |
Optimizer steps; also the cosine-schedule horizon. |
token_budget |
16384 |
Tokens per packed forward (the per-device memory knob — config: auto sizes it from the GPU). |
grad_accum_steps |
1 |
Micro-batches per optimizer step. Effective batch = token_budget × grad_accum × world_size; raise it for a large, stable batch on a memory-bound GPU without raising token_budget. |
devices / num_nodes |
auto / 1 |
Fabric DDP: per-node device count and host count (multi-node). |
lr_muon / lr_adamw |
3e-3 / 3e-4 |
Muon drives 2-D hidden weights; AdamW drives embeddings/norms/biases. |
warmup_steps |
100 (dataclass) / 500 (pretrain.yaml) |
Linear warmup before the cosine decay. The YAML value wins when using the CLI or api.pretrain() without an override; the dataclass default applies only in unit tests and direct Python use. |
weight_decay / grad_clip |
0.01 / 1.0 |
Applied to both optimizers. |
checkpoint_every_min |
15.0 |
Wall-clock minutes between full checkpoints. |
log_every |
20 |
Steps between metric logs and the stderr heartbeat. |
verbose |
true |
One-line heartbeat (step, loss, mlm_acc, tok/s, ETA); --quiet disables it. |
wandb / wandb_project |
false / pragmatiq |
Weights & Biases mirror (or pass --wandb). |
seed / nan_skip |
0 / true |
Reproducibility; NaN/inf losses dump the batch to debug/ and skip the step. |
max_consecutive_skips |
50 |
Abort if this many steps in a row are skipped for a non-finite loss/grad — a divergence guard so a broken run fails loud instead of burning compute. |
deterministic |
false |
Opt-in reproducible CUDA path (see Determinism); forces fp32 on GPU, at a throughput cost. |
accelerator |
auto |
auto (CUDA when visible), cpu, or cuda; an explicit cpu on a GPU host trains on the CPU. |
prefetch_batches |
2 |
Batches collated ahead on a background thread (0 = synchronous). |
masker, p_token, p_event, p_key, p_unk |
pragma, 0.15, 0.10, 0.10, 0.10 |
Masking strategy (swappable via @register_masker) and its rates. |
text_loss_weight |
1.0 |
Weight λ on the text MSE term in the Nemotron variant (loss = CE + λ·MSE); inert without a text encoder. |
Scaling to 1M–26M records, hands-off
Pointing pragmatiq at a large book should not require tuning the batch or schedule.
Pass config="auto" (or --config auto) and it sizes token_budget, grad_accum_steps,
max_steps, and warmup_steps from the shard index (user count, token distribution) and
the target device, with an explainable rationale logged at startup:
pragmatiq pretrain data/tokenized --name big --model-size medium --config auto
api.pretrain("data/tokenized", "big", model_size="medium", config="auto")
Explicit overrides still win (api.pretrain(..., config="auto", grad_accum_steps=8)), and
autoconfigure is callable directly to inspect the plan.
The three levers it sets are also usable by hand:
- Gradient accumulation decouples the effective batch from device memory.
grad_accum_stepsmicro-batches accumulate before one clip + optimizer step, so a stable batch is reached on a memory-bound GPU without raisingtoken_budget. With the default1the trajectory is byte-identical to no accumulation. - Multi-node DDP is
devices(per-node) ×num_nodes. The rank sampler shards the data per global rank with a per-rank masking seed, so adding ranks trains disjoint slices in lockstep. - Truncation caps (set on the tokenizer:
max_event_tokens=24,max_profile_tokens=200at encode time;max_events_per_user=6500at collate time, after the eval-point cut) keep heavy-tailed real histories tractable; they do not bind at synthetic scale.
Resume semantics
pragmatiq pretrain data/tokenized --name demo --resume auto
--resume auto picks up runs/demo/checkpoints/last.pt if it exists.
Checkpoints capture the model, both optimizers, the LR scheduler, the
sampler position, all RNG states (torch, numpy, CUDA, and the masking
generator), the tokenizer hash, and the resolved config — so an interrupted
run resumed mid-flight reproduces the exact batch and masking stream of an
uninterrupted one (this is tested bit-exactly). Resuming with a different
tokenizer is refused with a clear error.
Determinism
From a fixed seed, CPU runs are byte-identical — weight init, dropout, the masking stream, and shard/worker output are all seeded (CI-enforced for the generator and the resume test). GPU kernels use a different reduction order, so CPU and GPU outputs are never bit-identical to each other — pick one target and compare against itself.
The opt-in deterministic: true flag makes the GPU path reproducible on
fixed hardware. It enables torch.use_deterministic_algorithms, the cuDNN
deterministic path, flash-attn's deterministic backward, and (because bf16
backward on CUDA has no deterministic implementation upstream) trains in fp32
instead of bf16-mixed. With it on:
- GPU forward / embedding is reproducible run-to-run on the same hardware.
- GPU training is bit-exact in fp32 (same seed → same loss curve).
- GPU bf16 training is not bit-exact — the SDPA/flash bf16 backward stays
nondeterministic upstream. Leaving
deterministic: falsekeeps the default bf16-mixed path; a deterministic bf16 run is run-to-run stable to ~1e-3.
The flag is off by default, so default performance and behaviour are unchanged; turn it on only when you need a reproducible GPU run and can accept the fp32 throughput cost.
Multi-GPU and renting a GPU
Fabric launches DDP across all visible CUDA devices automatically — no flag
changes, just run on a multi-GPU host. Each rank trains a disjoint, equal-sized
shard of every epoch's batches (so the gradient all-reduce covers the full epoch
once) with an independent masking stream, and only rank 0 writes checkpoints and
metrics. For multi-node jobs set num_nodes (and devices per node) in the
config; the rank sharding and per-rank masking extend across the whole world. Pair
this with grad_accum_steps and config: auto (see
Scaling to 1M–26M records) for a large, stable
effective batch without per-device OOM.
Measured pretraining throughput per preset, single-GPU and DDP scaling, is in
the Hardware table; every run also logs its own tokens/s in
runs/<name>/metrics.jsonl, so measure on your own data.
scripts/runpod_launch.py is a turnkey path for
validating on a rented A100/H100: it creates a RunPod pod via the REST API,
syncs the repo over SSH (no GitHub required), installs the matching flash-attn
wheel, and runs the GPU validation legs in scripts/gpuval/ (pretrain
throughput and memory per preset, a full fine-tune with per-epoch stats,
flash-vs-SDPA equivalence, bf16-vs-fp32 embeddings, resume, export on the GPU
image, serving request rates, an optional multi-GPU sweep), writing the JSON
the Hardware table renders:
export RUNPOD_API_KEY=...
python scripts/runpod_launch.py --gpu "NVIDIA A100 80GB PCIe" --run-name a100-smoke
python scripts/runpod_launch.py --terminate <pod_id>
Extending pragmatiq
Heads, maskers, and value encoders are resolved by name through
pragmatiq/registry.py, so you can plug in your own
without forking. Register a component with the matching decorator and reference it
by name in a config.
import torch.nn as nn
from pragmatiq.registry import register_head

@register_head("ranking")
class RankingHead(nn.Module):
    """A custom task head on the user embedding z_h[USR] -> [n_users, n_classes]."""

    def __init__(self, dim: int, n_classes: int = 2) -> None:
        super().__init__()
        self.net = nn.Sequential(nn.Linear(dim, dim), nn.GELU(), nn.Linear(dim, n_classes))

    def forward(self, user_repr):
        return self.net(user_repr)
Select it in a fine-tune config and run as usual:
# myhead.yaml
head: ranking
n_classes: 2
lora_rank: 8
pragmatiq finetune data/tokenized --run runs/mybank-v1 \
  --label data/mybank/labels/churn.parquet --config myhead.yaml
Registration is an import side effect, so import the module that defines your
component before finetune/get_head runs (keep it in a package your config or
entry point imports). @register_masker(name) and @register_value_encoder(name)
work the same way, referenced by the masker and value_encoder config keys.
AML over the transfer graph
Money laundering through mule rings is a relational problem: a mule is
defined by who they transact with (fan-in of small credits, layering inside
the ring, shared cash-out), not only by their own behavior. pragmatiq ships a
transfer-graph extension that tests exactly how much of that signal a graph
recovers. The AML GNN path needs the aml extra
(pip install "pragmatiq[aml]"), which brings in torch-geometric.
The pieces
TransferGraphBuilder(pragmatiq/models/gnn.py) turnstransfers.parquetplus frozen pragmatiq user embeddings into a PyG graph: nodes are embedded users, directed edges are money flows (kept only between users that have features), edge attributes are amount and log-recency, node features are the embeddings, and node labels mark mules.AmlGNNis a 2–3 layer GraphSAGE node classifier with two deliberate design choices. Sum aggregation: mule detection hinges on fan-in, and mean aggregation normalizes degree away — sum keeps it, so message passing can recover the structural signal regardless of which node features are used. A raw-feature skip to the head: each node's own features are projected and concatenated with the graph representation before classification (with residual conv layers), because without it the stack over-smooths and loses the per-user signal an isolated probe already has.
The four-arm ablation
pragmatiq gnn (and api.gnn) runs four setups on identical, stratified
train/val/test splits shared across arms, over multiple seeds:
| Arm | Features | Graph? | Question it answers |
|---|---|---|---|
| (a) | pragmatiq embeddings | no — logistic probe | How far does a per-user embedding get alone? |
| (b) | pragmatiq embeddings | GraphSAGE | Does the transfer graph add to rich learned features? |
| (c) | hand-crafted node stats (degree, volume) | GraphSAGE | What does a fraud analyst's baseline + a graph achieve? |
| (d) | same hand-crafted stats | no — logistic control | Is the graph effect real, or just the features? |
The synthetic mule rings are multi-hop layered laundering chains. Money mules
are modeled as ordinary recruited accounts with no distinctive individual
behavior, and their amounts and counterparty degree are drawn to match ordinary
accounts — so 1-hop degree is not a trivial oracle ((d), a degree-only
logistic baseline, reaches only 0.604). The laundering legs are written to the
transfer ledger (transfers.parquet), not the card-event stream; the
discriminative signal is the multi-hop layering chain in that ledger.
The gated claim — relational recovery. A GraphSAGE over the
transfer graph recovers money-mule rings that a probe on the isolated per-user
embedding cannot: (c) 0.622 ≫ (a) 0.480 on the current book (five seeds, full
scale), so the AML signal lives in the multi-hop transfer structure an isolated
embedding misses. This is what gate_6 gates, at both CI and full scale, by more
than the cross-seed noise.
Reported, not gated. Message passing adds over the same hand-crafted features
without a graph ((c) 0.622 > (d) 0.597), but by less than the per-seed spread
(± 0.043), so the claim is reported rather than gated. The learned per-user
embedding adds a little over the isolated probe ((b) 0.572 > (a) 0.480) and does
not beat hand-crafted features ((b) 0.572 < (c) 0.622). The isolated
embedding sits near chance, so the model does not capture the multi-hop laundering
signal in the per-user representation; recovering it in a learned representation
is the open challenge. This is consistent with the PRAGMA paper's own
observation that AML is a setting where the model underperforms because it
processes user histories in isolation — the GNN here is pragmatiq's honest
extension that probes that gap, not a "the learned embedding wins" result. See
MODEL_CARD.md and
notebooks/04_aml_gnn.ipynb.
Running it
pip install -e ".[aml]"
pragmatiq gnn data/tokenized --run runs/demo \
  --transfers data/synth/transfers.parquet \
  --aml-label data/synth/labels/aml.parquet \
  --seeds 0,1,2 --epochs 150
The command embeds users with the trained run, builds the graph, fits each
arm per seed, and prints per-arm mean ± std ROC-AUC plus a verdict dict.
notebooks/04_aml_gnn.ipynb is the interactive
version of the same experiment.
Latest results
The table below is auto-written by write_aml_report in
pragmatiq/models/gnn.py on a passing full run
(opt-in via PRAGMATIQ_WRITE_RESULTS=1). Generated tables carry a provenance
stamp (node/edge/mule counts, seeds, epochs, git commit), and the writer
refuses to overwrite a larger-scale result with a smaller-scale one — a
CI-scale run can never masquerade as a full-scale result.
| setup | ROC-AUC (mean ± std over seeds) |
|---|---|
| (a) probe on isolated pragmatiq embeddings | 0.480 ± 0.021 |
| (b) GraphSAGE over transfers + pragmatiq features | 0.572 ± 0.020 |
| (c) GraphSAGE + hand-crafted node features | 0.622 ± 0.043 |
| (d) control: logistic regression on the same hand-crafted features, no graph | 0.597 ± 0.011 |
Relational recovery (gated): True — a GraphSAGE over the transfer graph recovers money-mule rings that a probe on isolated pragmatiq embeddings cannot ((c) > (a) = True, by more than the cross-seed noise), so the AML signal lives in the multi-hop transfer structure an isolated per-user embedding misses. Money mules are degree- and volume-matched to ordinary accounts, so the signal is the multi-hop layering chain, not 1-hop degree.
Reported, not gated: message passing over the same hand-crafted features beats the no-graph control by more than the cross-seed noise ((c) > (d) = False); the learned per-user embedding adds a little over the isolated probe ((b) > (a) = True) but does not beat hand-crafted features ((b) > (c) = False). The isolated embedding sits near chance, so on this synthetic book the model does not capture the multi-hop laundering signal on its own — recovering it in a learned per-user representation is the open challenge (see MODEL_CARD.md).
provenance: n_nodes=12000, n_edges=344388, n_mules=607, seeds=[0, 1, 2, 3, 4], epochs=150, commit=cbe83c6
Synthetic data realism
The generator (pragmatiq/data/synthetic/) is an agent-based simulator, and
its output is what every gate and result table in this README is measured on,
so its realism is a first-class concern. Beyond the persona / lifecycle /
episode machinery described in MODEL_CARD.md, the book has
these properties; the constants are # GUESS values, held in
pragmatiq/data/synthetic/config.py and simulator.py:
| Property | How it is modelled | # GUESS constants |
|---|---|---|
| Amounts in the transaction currency | Internal accounting (income, budgets, balances, the LTV profit model) is in GBP; emitted amount strings are converted with fixed mid-rates, so a PLN user's grocery amounts are ~5× a GB user's and an FX purchase abroad is in the merchant's currency |
FX_PER_GBP = {GBP 1.0, EUR 1.17, PLN 5.05, USD 1.27} (mid-2023 spot, held flat) |
| Card-only interchange | The ltv_positive profit model earns interchange on card payments and crypto top-ups only — rent (standing order), subscriptions (direct debit) and ATM withdrawals earn none |
0.7 % of card spend |
| Bank holidays | England & Wales bank holidays computed per year: Good Friday / Easter Monday from the Gregorian Easter algorithm, the May and August Mondays, substitute weekdays when Christmas or New Year fall on a weekend; paydays and holiday spend follow them | one calendar for the whole book |
| Payday schedules | Each monthly-paid user draws a rule: last business day, the 25th, the 28th (rolled back to a business day), or a four-weekly cycle (13 credits a year, some months with two); payday spend bumps follow the user's own dates | mix 0.55 / 0.20 / 0.15 / 0.10 |
| Market hours | Equity orders only on trading days, concentrated in the LSE session and the US overlap (UK time); crypto trades around the clock with an evening tilt and on weekends | the two 24-hour intensity curves in simulator.py |
| Overdraft feedback | Overdraft fees are debited from the balance (one pass over the pre-fee trajectory), so a long overdraft compounds toward the insolvency that drives default_12m |
5.00 GBP per overdrawn day, ≤ 60 fee days |
| Merchant geography | Everyday spend lands on home-country merchants (Zipf popularity kept per country); a trip draws a destination country and its merchants; a slice of online orders is cross-border | p = 0.10 of online orders go to the global pool |
| Mule windows | Ring windows are clamped to the simulated horizon, so laundering behaviour never lands past the last day | — |
Every seed still produces byte-identical output for any worker count (CI-enforced); the fingerprint differs from 1.0.x for the same seed, so result tables regenerated on this generator are not comparable to earlier ones.
Model sizes
| Size | d | Heads | Depths (profile / event / history) | Nominal | Actual params at ~28k vocab |
|---|---|---|---|---|---|
small |
192 | 3 | 1 / 5 / 2 | 10M | ~9.1M |
medium |
512 | 8 | 3 / 16 / 6 | 100M | ~94M |
large |
1024 | 16 | 9 / 45 / 18 | 1B | ~940M |
These sizes are the presets in ModelConfig.preset
(pragmatiq/models/pragmatiq.py), selected with --model-size. Any architecture field (e.g. rope_base, dropout) can be
overridden by passing it in the pretrain config. The test suite checks the
model and MLM head parameter counts against the nominal sizes.
PRAGMA+Nemotron text-embedding variant
The paper describes a variant in which high-cardinality text fields (merchant names, device ids, free-text memos) are not split into BPE pieces. Instead a frozen text model maps each value's full string to a single vector, and the MLM objective reconstructs that continuous vector with MSE rather than predicting sub-word ids. On its text-heavy tasks the paper reports a meaningful credit lift at a modest latency cost, so pragmatiq ships it as a switchable option — off by default, so the BPE path is byte-identical to a build without it.
It is switchable from the data step alone. Tokenize in embed mode and pretrain
auto-builds the matching frozen encoder and MSE reconstruction head — no model flags:
pip install -e ".[text]"     # adds transformers (the frozen embedder)
pragmatiq tokenize data/synth --out data/tokenized --config configs/data/tokenizer_nemotron.yaml
pragmatiq pretrain data/tokenized --name nemo --model-size medium   # text branch auto-wired
- Encoders are resolved by name from the registry (
@register_text_encoder): the productionnemotronembedder (frozen, mean-pooled,no_grad), and a deterministic, dependency-freehashstand-in so the whole path — embed-mode tokenization, the text input projection, the MSE branch, and masking that routes text to reconstruction — is exercised on CPU in CI without downloading a multi-GB model. - Objective: masked text tokens are reconstructed by a
Linear(3d → text_dim)head against the frozen vector; the loss isCE + λ·MSE(text_loss_weight, default 1.0). Ordinary tokens keep the cross-entropy MLM objective. - Serving handles both variants — build the Triton image with
PRAGMATIQ_TRITON_EXTRAS=nemotron(see Serving with Triton).
Paper-silent (# GUESS) hyperparameters
The paper leaves some engineering details unspecified. pragmatiq treats these
as documented defaults, exposes every one in config, and marks source-level
choices with # GUESS. Defaults are written into each run's run.yaml /
meta.json at training time, so shipped checkpoints embed their values
reproducibly regardless of future default changes. Changing a default is a
MINOR (not breaking) change per the stability policy;
the checkpoint-format and tokenizer-hash guards ensure already-shipped
checkpoints always load identically.
The table below lists all 13 # GUESS source markers, resolved to 9 unique
hyperparameters (some values appear in both the dataclass and the optimizer or
masker call-site).
| # | Parameter | File(s) | Default | Config key | Rationale |
|---|---|---|---|---|---|
| 1 | lr_muon — Muon LR for 2-D hidden weights |
training/pretrainer.py, training/optim.py |
3e-3 |
configs/pretrain.yaml · lr_muon |
Paper-silent; matches Keller Jordan's Muon reference, known to work for MLM at this scale |
| 2 | lr_adamw — AdamW LR for embeddings/norms/biases |
training/pretrainer.py, training/optim.py |
3e-4 |
configs/pretrain.yaml · lr_adamw |
Paper-silent; standard AdamW default one decade below Muon LR; stable for embedding tables |
| 3 | warmup_steps — cosine-schedule warmup length |
training/pretrainer.py |
100 (dataclass); 500 (pretrain.yaml) |
configs/pretrain.yaml · warmup_steps |
Paper-silent; ~2–5% of default max_steps; short warm-up avoids early instability on small runs |
| 4 | token_budget — per-forward token cap |
training/pretrainer.py |
16384 |
configs/pretrain.yaml · token_budget |
Paper-silent; a conservative fixed default — config: auto replaces it with a budget sized from the device memory (see the Hardware table for what each preset needs) |
| 5 | p_unk — [UNK] fraction of selected masked positions |
training/masking.py, training/pretrainer.py |
0.10 (10 %) |
TrainConfig.p_unk / configs/pretrain.yaml |
Paper-silent; keeps the model robust to unseen tokens; excluded from CE loss like the BERT sentinel |
| 6 | n_buckets — percentile buckets per numeric key |
data/tokenizer.py |
64 |
configs/data/tokenizer.yaml · n_buckets |
Paper-silent; 64 uniform-mass bins give ~1.5% resolution per bucket, balancing vocab size vs precision |
| 7 | target_vocab — target total vocabulary size |
data/tokenizer.py |
28000 |
configs/data/tokenizer.yaml · target_vocab |
Paper-silent; in the range of standard NLP sub-word vocabs; BPE fills the remainder after categoricals |
| 8 | numeric_min_cardinality — distinct-value floor for numeric routing |
data/tokenizer.py |
None (= 4 × n_buckets) |
configs/data/tokenizer.yaml · numeric_min_cardinality |
Paper-silent; separates low-cardinality identifier codes (MCC, ZIP) from continuous magnitudes |
| 9 | rope_base — geometric frequency ladder base for TimeRoPE |
models/pragmatiq.py |
10000.0 |
pretrain config override rope_base |
Paper-silent; inherited from LLaMA/GPT-NeoX RoPE; appropriate for log-seconds positions |
| 10 | max_counter_distinct — value-table bound for numeric keys |
data/tokenizer.py |
1_000_000 |
configs/data/tokenizer.yaml · max_counter_distinct |
Paper-silent; keeps fit() memory bounded on continuous keys without touching classification |
The synthetic generator carries its own # GUESS constants (FX rates, payday
mix, market-hours curves); they are listed in
Synthetic data realism.
Serving with Triton
The production serving path is a Triton python backend that runs the native
varlen PyTorch model — the exact no-padding forward used in training, not an
approximation. The model repository lives at
deploy/triton/model_repository/pragmatiq_embedder/:
config.pbtxt
declares the interface and
1/model.py
loads PragmaModel.from_pretrained(run_dir) once at startup and serves
embed_records for every request.
One-command deploy + smoke
scripts/deploy_serving.sh is the turnkey path: it
builds the serving image, boots tritonserver with your run mounted, waits for
readiness, then sends a real embedding request and verifies the [n_users, dim]
response. With nvidia-smi on the host it serves on CUDA in bf16; without it,
the script overlays deploy/triton/config.cpu.pbtxt
(KIND_CPU) and sets PRAGMATIQ_SERVE_CPU=1 so the same image boots CPU-only.
pragmatiq pretrain data/tokenized --name demo            # any trained run works
bash scripts/deploy_serving.sh --run runs/demo           # default model
bash scripts/deploy_serving.sh --run runs/nemo --variant nemotron   # Nemotron variant
Bring the full stack up
deploy/docker-compose.yaml starts four services:
Triton, Prometheus, Grafana, and the Streamlit demo. The Triton service builds
from deploy/triton/Dockerfile, which installs pragmatiq
into Triton's Python (the python backend imports it; the stock image cannot run the
model) while leaving the image's CUDA build of torch untouched. Point PRAGMATIQ_RUN
at a trained run directory — the one with checkpoints/ and tokenizer/ — mounted
read-only at /models/run:
export PRAGMATIQ_RUN=$PWD/runs/demo
docker compose -f deploy/docker-compose.yaml up -d --build
# Nemotron variant serving: PRAGMATIQ_TRITON_EXTRAS=nemotron docker compose ... up -d --build
The Triton service has a readiness healthcheck (/v2/health/ready) and
reserves the host's GPUs (NVIDIA container toolkit). On a CPU-only host use
deploy/docker-compose.cpu.yaml
instead — same services, the KIND_CPU config mounted over the default and
PRAGMATIQ_SERVE_CPU=1:
docker compose -f deploy/docker-compose.cpu.yaml up -d --build
The serving image installs pragmatiq into the NGC Triton 25.06 image (torch 2.8)
with every runtime dependency read from pyproject.toml, so the image cannot
drift from the package.
Device policy inside the backend (pragmatiq.inference.serve.resolve_serve_device):
PRAGMATIQ_SERVE_CPU=1 wins, else a Triton KIND_GPU instance pins its assigned
GPU, else CUDA when visible, else CPU. Requests are validated (each record needs a
string user_id and an events list) and capped: PRAGMATIQ_SERVE_MAX_RECORDS
(default 1024 users per request) rejects oversized payloads with a clear error, and
PRAGMATIQ_SERVE_TOKEN_BUDGET (default 16384) splits a request into forward passes
of at most that many tokens. PRAGMATIQ_INFERENCE_PRECISION=fp32 pins fp32 serving.
| Service | Port | What it is |
|---|---|---|
| Triton HTTP / gRPC | 8000 / 8001 | Inference endpoints |
| Triton metrics | 8002 | Prometheus scrape target (5s interval, see deploy/prometheus/prometheus.yml) |
| Prometheus | 9090 | Metrics store |
| Grafana | 3000 | Dashboards (anonymous admin enabled; Prometheus at http://prometheus:9090) |
| Streamlit demo | 8501 | See Streamlit demo |
Request format
One request carries a JSON array of plain user records — the same dicts
PragmaModel.embed_records accepts (user_id, events as
{ts, source, fields} objects with ts in microseconds since epoch, optional
attributes and lifelong). The response is the [n_users, dim] fp32
embedding matrix. Batching happens inside the model: the varlen forward
packs all users in the request with no padding, which is why config.pbtxt
sets max_batch_size: 0 and uses a 2-instance group for request-level
concurrency instead of Triton dynamic batching (the trade-off is documented in
the config file).
curl -s localhost:8000/v2/models/pragmatiq_embedder/infer \
  -H 'Content-Type: application/json' \
  -d @- <<'JSON'
{
  "inputs": [{
    "name": "records_json",
    "shape": [1],
    "datatype": "BYTES",
    "data": ["[{\"user_id\": \"u1\", \"events\": [{\"ts\": 1718200000000000, \"source\": \"transaction\", \"fields\": {\"amount\": \"42.50\", \"currency\": \"GBP\", \"merchant\": \"TESCO\"}}], \"attributes\": {\"country\": \"GB\"}, \"lifelong\": []}]"]
  }]
}
JSON
Unseen keys or values in a request map to [UNK] with a logged warning —
serving never raises KeyError on vocabulary drift.
Benchmarking
pragmatiq benchmark data/tokenized --run runs/demo --device cuda
benchmark measures local batch-embedding throughput (users/s, tokens/s, the
precision used, and a USD-per-million-users estimate) and writes
benchmark_results.md in the current directory (--out to move it;
--precision fp32 for the fp32 A/B),
which also includes the ready-to-run perf_analyzer command for sweeping
p50/p95/p99 latency vs concurrency against the live Triton endpoint (latency
percentiles need a real endpoint, so that half is emitted as a command rather
than executed).
The ONNX export
pragmatiq export (requires the serve extra) writes a dense reformulation
of the model: the same weights run over padded tensors, so the exported graph
reproduces the native embeddings (validated against onnxruntime on export and
shape-dynamic in the user/event/token axes). The Triton python backend stays the
high-throughput path because it runs the native varlen model and skips the
padding the dense graph materializes — a deployment choice, not a fidelity gap.
Pick Triton for throughput, ONNX for portability.
Streamlit demo
apps/demo/app.py is a small Streamlit app over a trained run and a
generated dataset: pick a synthetic user in the sidebar and see their event
timeline (recent transactions with amount/merchant), their embedding
computed live via embed_records (the raw embedding and its norm — attach
fine-tuned heads for calibrated fraud/credit/churn scores), and their ego
transfer graph (all transfers in and out of the selected user).
pip install -e ".[demo]"
pragmatiq quickstart          # writes runs/quickstart/{raw,tok,runs/quickstart}
PRAGMATIQ_OUT=runs/quickstart streamlit run apps/demo/app.py
PRAGMATIQ_OUT (default runs/quickstart) is a quickstart output directory;
the demo derives the raw data (<out>/raw), the tokenized shards (<out>/tok)
and the trained run (<out>/runs/quickstart) from it. The demo also runs as
the demo service in
deploy/docker-compose.yaml on port 8501.
Observability
Every training run always writes runs/<name>/metrics.jsonl — one JSON object
per logged step (total and per-masking-type losses, MLM accuracy, grad norm,
LR factor, tokens/sec, GPU memory) — plus run.yaml, meta.json, and a copy
of the tokenizer. On top of that:
- Console: long phases (synth, tokenize, embed) show tqdm progress bars in
terminals and notebooks, and rate-limited log lines when output is piped
(CI,
nohup). Pretraining prints a one-line heartbeat everylog_everysteps (step, loss, mlm_acc, tokens/sec, ETA); disable withverbose: falsein the pretrain config orpragmatiq --quiet .... Progress and logs go to stderr — stdout stays a single parseable JSON document. - Parallelism without nondeterminism:
synth generate --n-workersandtokenize --n-workersfan out across processes but produce byte-identical output for any worker count (CI-enforced), so you can scale CPU phases freely without losing reproducibility. - TensorBoard:
pip install -e ".[tracking]", thentensorboard --logdir runs/<name>/tb. The mirror is on whenever thetensorboardpackage is installed; otherwise it is a silent no-op. - Weights & Biases:
pip install -e ".[tracking]", then setwandb: true(and optionallywandb_project) in the pretrain config, or pass--wandbtopragmatiq pretrain.
Notebooks
The notebooks are the guided tour; each one runs top to bottom on a laptop CPU and picks up a GPU automatically when one is visible.
| Notebook | One line |
|---|---|
01_quickstart_and_data.ipynb |
Generate a synthetic banking book with the causal agent-based simulator and explore why its labels are learnable without leakage. |
02_tokenize_and_embed.ipynb |
Fit the key-value-time tokenizer, shard the book, and embed users from shards or from plain Python dicts. |
03_finetune_and_probe.ipynb |
Turn embeddings into task models two ways: a fast linear probe and a LoRA fine-tune. |
04_aml_gnn.ipynb |
Run the AML transfer-graph ablation and unpack the relational-recovery result, including its limitations. |
Development
pip install -e ".[dev,full]"
CI installs .[dev,full], and the full test suite exercises the optional
extras (Lightning, torch-geometric, transformers, matplotlib, …) — install the
same combination for a green local run. Run the fast local checks before
opening a PR:
ruff check .
mypy pragmatiq
pytest tests/ -x -q
Every change is gated in CI: lint, types, the full suite on Python 3.11 and
3.12, a slim-install serving boundary, packaging smoke, the supply-chain scan,
and every acceptance gate in scripts/gates/:
| Gate | Checks |
|---|---|
gate_1 |
synthetic data: determinism, realism metrics, credit GBDT baseline in the realistic band |
gate_2 |
tokenizer: golden hash, [UNK] handling, caps |
gate_3 |
sharding, collation, padding-equivalence, prefetch loader |
gate_4 |
model: parameter counts, varlen attention backends |
gate_5 |
training: resume bit-exact, probe > baseline, fine-tune |
gate_6 |
AML GNN four-arm ablation (relational recovery) |
gate_7 |
inference / serving request path / deploy manifests / demo |
gate_8 |
nano end-to-end, validate, packaging + attribution |
gate_9_contract |
public-API / CLI / serving contract tests |
gate_serve_slim |
the [serve] install imports without training extras |
gate_storage |
fsspec staging in/out, remote roots |
gate_integrations |
SageMaker / Databricks adapters offline |
gate_10_byoc |
no-phone-home, offline hardening |
bash scripts/gates/run_full_validation.sh runs them all; set
PRAGMATIQ_GATE_FULL=1 for full-scale runs. GPU validation
(scripts/gpuval/, launched through scripts/runpod_launch.py) is run before
each release and its JSON is committed under docs/benchmarks/. See
CONTRIBUTING.md for the development workflow.
Citation
If you use pragmatiq, cite this repository and the PRAGMA paper that inspired it:
- Software citation metadata:
CITATION.cff - Reference paper: PRAGMA: Revolut Foundation Model, arXiv:2604.08649
License
1 maintainer

Metadata
1 maintainer
Release files for pragmatiq 1.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| pragmatiq-1.1.0.tar.gz | 267.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| pragmatiq-1.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 532.2 kB
Release files / pragmatiq-1.1.0.tar.gz
| Download URL | pragmatiq-1.1.0.tar.gz |
|---|---|
| Size | 267.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
d731242c6f7806330e2367a8c4a966f1f627fedc879da3649b22366d53303573
|
|
BLAKE2b-256 checksum How to use checksums |
9e051c543f42c1a323cd7d604fbcbfb8f3fbbf2e28f7d6a4bcf3f23253fbfc22
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 15, 2026.
Transparency logRelease files / pragmatiq-1.1.0-py3-none-any.whl
| Download URL | pragmatiq-1.1.0-py3-none-any.whl |
|---|---|
| Size | 264.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a06933d2cf284064efc5b342951a6dd9c71385743a27d0836643eb1abe4d76d8
|
|
BLAKE2b-256 checksum How to use checksums |
17f313b379f4956fcbe1b6b3c84e1151608e4c14f437b5c0e2667aace4cf6e55
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 15, 2026.
Transparency log













