
PromptQuery
Natural-language SQL for production-scale Postgres schemas.


PromptQuery is an open-source CLI that lets you query Postgres in plain English — engineered for real production schemas with hundreds of tables, not toy demos. It introspects your schema, generates SQL, shows it for confirmation, and runs it read-only.
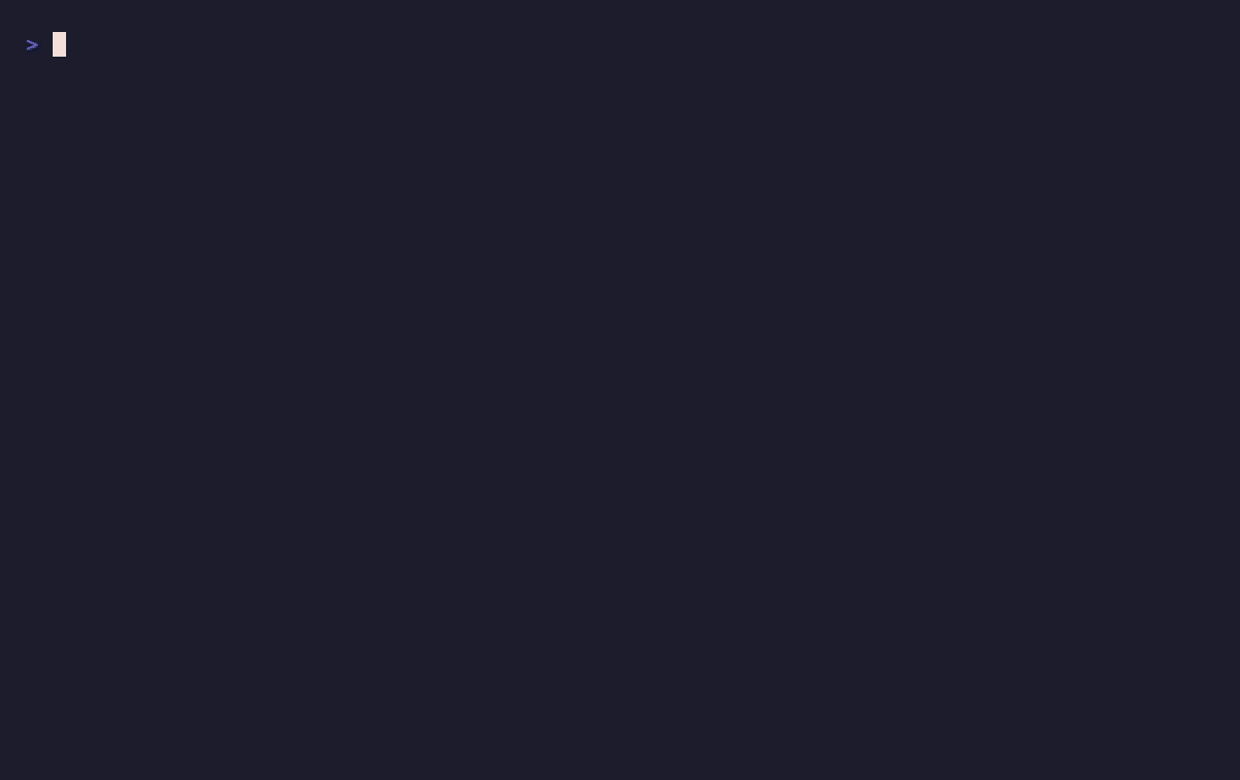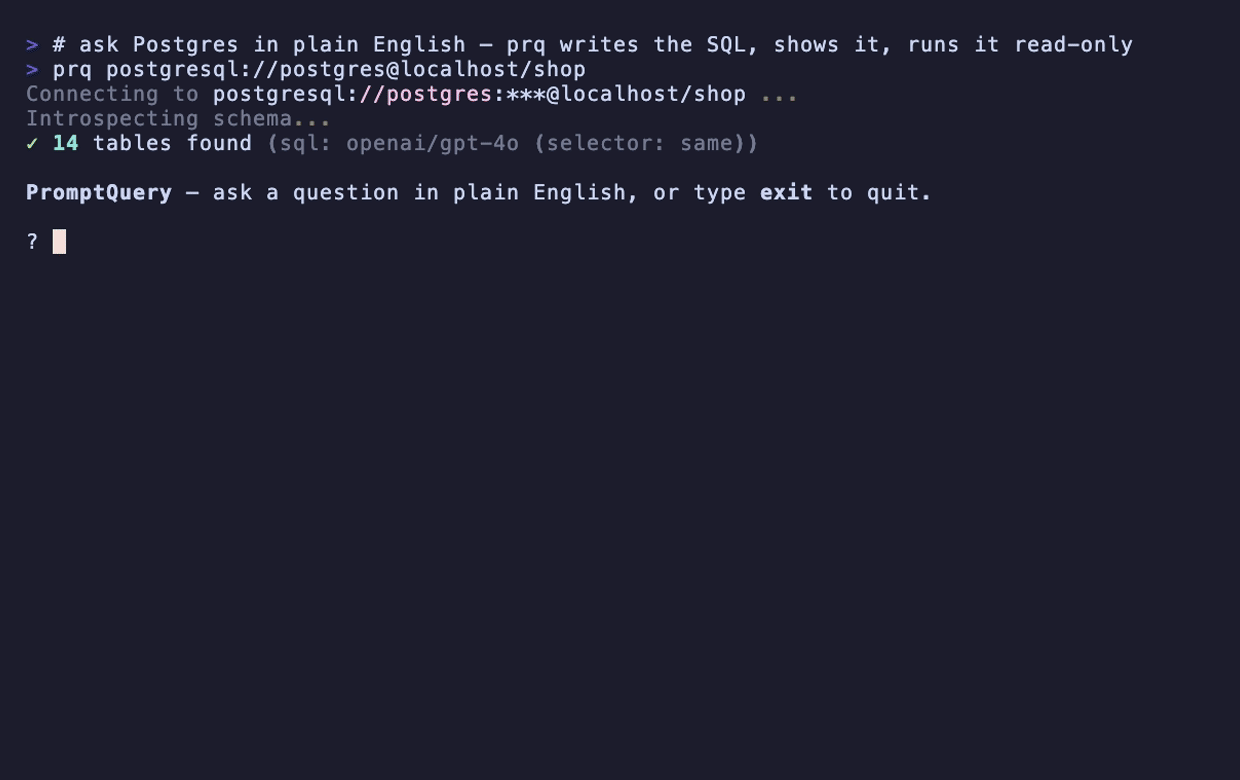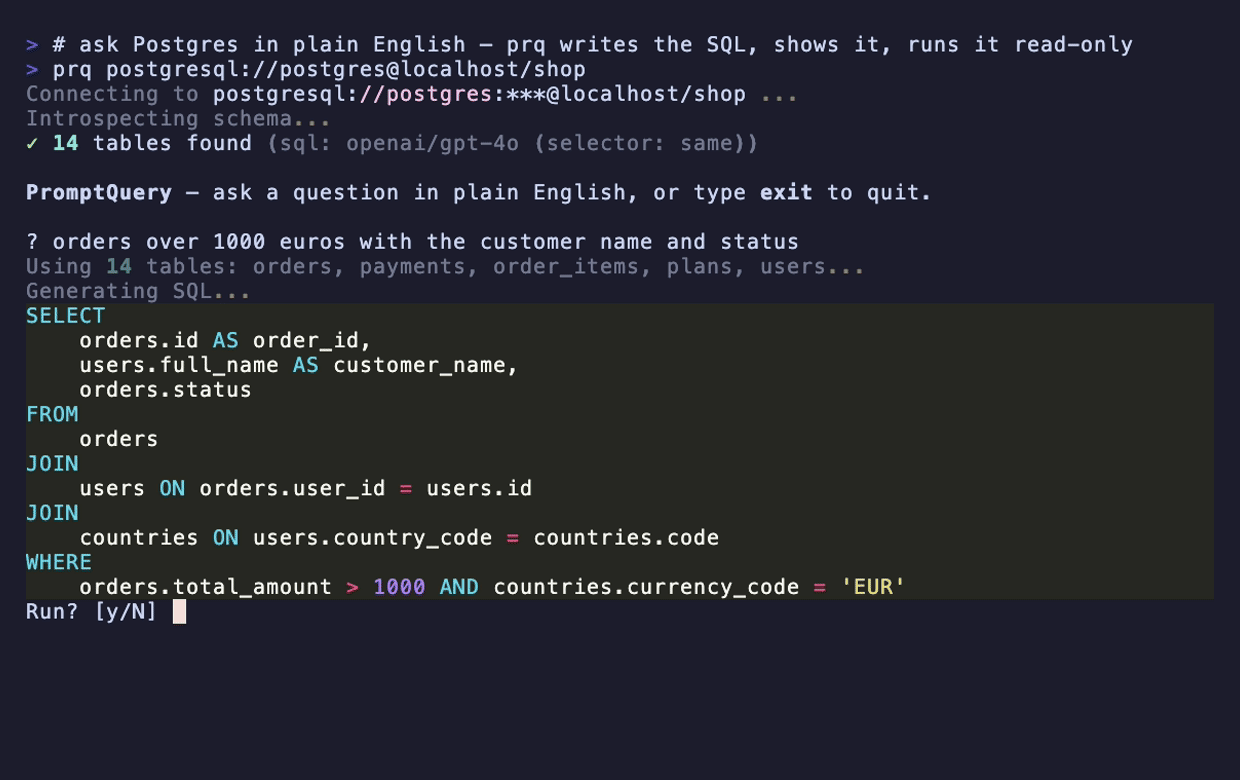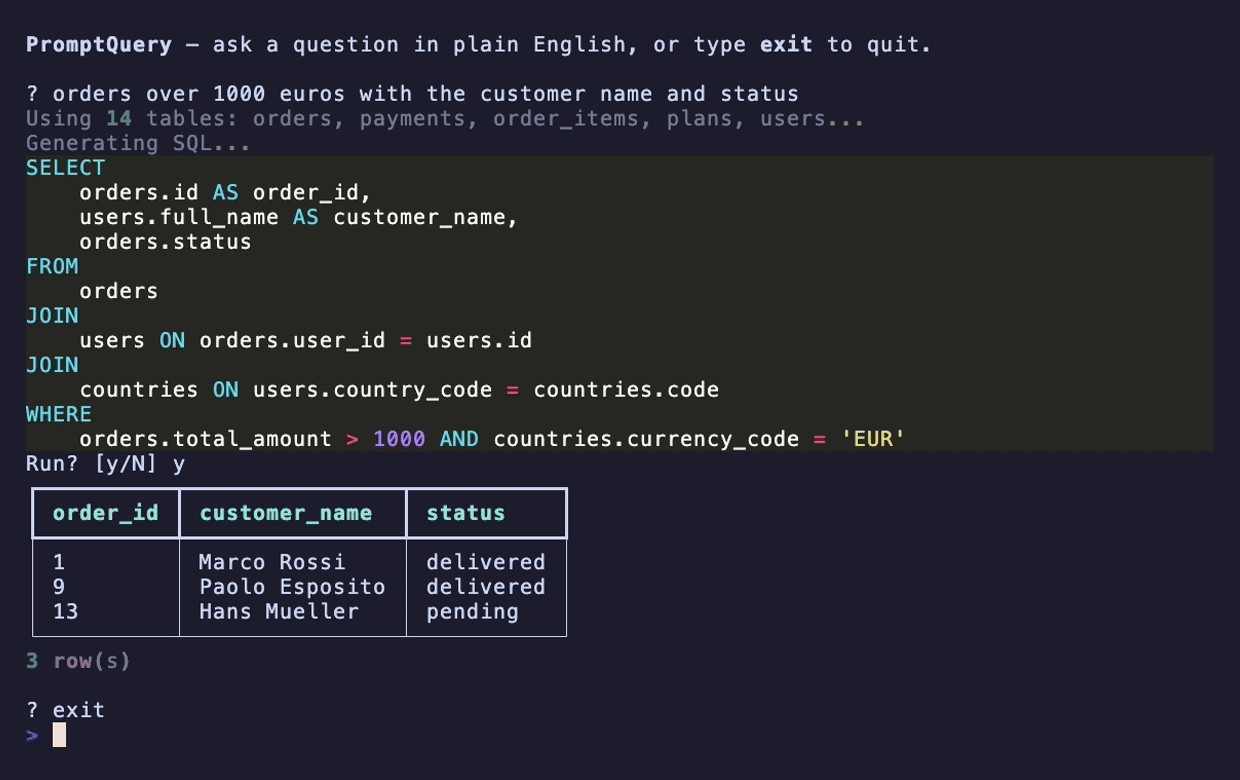
Plain English in → the SQL it's about to run → your rows. Read-only, with a confirmation step. Here it even reads "euros" as a currency join across three tables. Try it yourself on a live 216-table database, no setup ↓
The numbers
Two independent production-scale schemas. SQL generation: gpt-4o. Table selection: gpt-4o-mini.
What "accuracy" means here: a question passes only if the generated SQL references every table the question needs and invents none (parsed with sqlglot). These two schemas ship without seeded data, so queries are parsed, not executed — execution-equality is measured separately on the seeded shop fixture (see Benchmark). Finding the right handful of tables out of hundreds is the hard part, and this measures exactly that. "Tokens / query" is the SQL-generator prompt size, measured with tiktoken.
Odoo 18 ERP — 675 tables (eval/fixtures/odoo.schema.json)
| Pipeline | Accuracy | Tokens / query | Latency |
|---|---|---|---|
| Naive (full schema in prompt) | 84.0 % | ~85,600 | 3.4 s |
| PromptQuery v0.1 (TF-IDF only) | 76.0 % | ~4,500 | 2.0 s |
| PromptQuery v0.2 (TF-IDF + LLM selector) | 100.0 % | ~7,100 | 5.6 s |
EMBL-EBI RNAcentral — 216 tables, biology domain, public read-only DB
| Pipeline | Accuracy | Tokens / query | Latency |
|---|---|---|---|
| Naive (full schema in prompt) | 82.0 % | ~28,200 | 3.0 s |
| PromptQuery v0.1 (TF-IDF only) | 74.0 % | ~2,600 | 1.9 s |
| PromptQuery v0.2 (TF-IDF + LLM selector) | 94.0 % | ~1,600 | 4.8 s |
Pattern across both benchmarks: PromptQuery v0.2 wins by +12 to +16 percentage-points over the naive "stuff the whole schema into a prompt" baseline, at ~12–17× lower per-query token cost (12.1× on Odoo, 17.4× on RNAcentral), validated independently on two different production schemas and domains.
Accuracy receipts: eval/results_odoo_v2.json, eval/results_rnacentral.json. Token receipts: eval/results_odoo_tokens.json, eval/results_rnacentral_tokens.json — measured with eval/token_bench.py. Reproduce everything with one command each — see Benchmark below.
Quick start
pip install promptquery

# Set ONE of these (PromptQuery auto-detects):
export OPENAI_API_KEY=...
export ANTHROPIC_API_KEY=...

# Connect and start asking:
prq postgresql://localhost/mydb
prq and pquery are short aliases for promptquery. All three commands work identically.
One-shot mode (scripting / CI)
--query skips the REPL and returns machine-readable output. Progress messages go to stderr, results to stdout — pipe-friendly:
prq --query "how many users in Italy" postgresql://localhost/mydb         # JSON to stdout
prq --query "top 10 orders by total" --out csv postgresql://... > out.csv
prq --query "..." --out table postgresql://...                            # rich-formatted table
Exit codes: 0 success · 1 LLM/connection error · 2 safety-guard rejection · 3 execution error.
Try it without setting up a database
EMBL-EBI publishes a public read-only Postgres with real biological RNA-sequence data (216 tables). Install PromptQuery and try it in under a minute:
pip install promptquery
export OPENAI_API_KEY=...

prq --query "for each Rfam clan, show the clan name and how many Rfam models belong to it, top 10" \
  --selector-model gpt-4o-mini --model gpt-4o --out table \
  postgresql://reader:NWDMCE5xdipIjRrp@hh-pgsql-public.ebi.ac.uk:5432/pfmegrnargs
That's the exact query in the demo above — a real JOIN + GROUP BY across a 216-table schema you've never seen. (Credentials above are EMBL-EBI's public read-only — published for tutorial use.)
More to try — swap the --query string for any of these. Same database, no schema knowledge required, each a different query shape — and each one verified to return real rows:
which 10 source databases contribute the most RNA sequences          # GROUP BY over millions of rows (ENA, SILVA, Rfam …)
how many Rfam families are there in total                            # a one-number COUNT
list the 10 Rfam families with the longest consensus sequences, with their length
How it works
question
   │
   ▼
┌───────────────────┐
│ TF-IDF (stemmed)  │  Microseconds. Free. Surfaces ~50 candidate tables
│ retriever         │  by lexical match on names, columns, and comments.
└────────┬──────────┘
         │
         ▼
┌───────────────────┐
│ LLM table         │  One small LLM call. Handles semantic mismatches
│ selector          │  TF-IDF cannot: "invoice" → `account_move`,
│ (cheap model)     │  "shipment" → `stock_picking`. Picks ~15 tables.
└────────┬──────────┘
         │
         ▼
┌───────────────────┐
│ FK-graph          │  One hop outward + inward to pick up join targets
│ expansion         │  the question didn't name explicitly. Cap at 25.
└────────┬──────────┘
         │
         ▼
┌───────────────────┐
│ SQL generator     │  Your real LLM call. Receives ~25 tables, not 675 —
│ (frontier model)  │  with column comments and every enum's legal values,
│                   │  so it filters on real states instead of guessing them.
└────────┬──────────┘
         │
         ▼
┌───────────────────┐
│ Safety guard      │  sqlglot validator: rejects anything that isn't a
│ (sqlglot)         │  pure SELECT/CTE/UNION. Catches CTEs that hide DML.
└────────┬──────────┘
         │
         ▼
   "Run? [y/N]" → execute against a read-only Postgres session
         │
         ▼
┌───────────────────┐
│ Self-repair       │  If the database rejects the query, the error message
│ (on error only)   │  goes back to the model for one corrected attempt
│                   │  (--max-repair). Repaired SQL is re-validated and
│                   │  re-confirmed before it runs. Empty results are never
│                   │  "repaired" — empty is often the right answer.
└───────────────────┘
See ARCHITECTURE.md for the deep dive (file inventory, design bets, the patent-landmine non-goals).
Configuration
| Flag | Default | Description |
|---|---|---|
--model |
auto-detect | LLM for SQL generation (e.g. gpt-4o, claude-sonnet-4-6, anthropic/claude-opus-4-7) |
--selector-model |
same as --model |
LLM for the table-selector step. A cheaper model is recommended (e.g. gpt-4o-mini) |
--top-k |
50 | TF-IDF candidates passed to the LLM selector |
--select |
15 | Tables the LLM selector picks from those candidates |
--max-tables |
25 | Cap after FK expansion — what the SQL generator actually sees |
--max-repair |
1 | Repair rounds when the database rejects a query (0 disables) |
--no-selector |
— | Skip the LLM selector (v0.1 behaviour: TF-IDF + FK only) |
-y, --yes |
— | Skip the confirmation prompt before running |
Environment
| Variable | Purpose |
|---|---|
OPENAI_API_KEY |
Use OpenAI as the LLM provider |
ANTHROPIC_API_KEY |
Use Anthropic as the LLM provider |
If both are set, Anthropic is preferred. Override either with --model anthropic/<name> or --model openai/<name>.
Safety
PromptQuery has two independent layers so a write is impossible, even if one layer fails:
- Session-level: every Postgres session opens with
default_transaction_read_only = onand a 60-secondstatement_timeout. The database itself refuses non-SELECT operations. - Pre-execution: every generated query is parsed with
sqlglotand rejected unless it's a singleSELECT/WITH/UNION/INTERSECT/EXCEPT. The validator also catches CTEs that hide DML (WITH x AS (DELETE …) SELECT * FROM x) and dangerous-function calls (pg_terminate_backend,set_config,lo_export,dblink_exec).
Every query is also shown to you before it runs. Confirm with y.
How it compares
PromptQuery is deliberately narrow. Vanna and WrenAI are mature, popular, and good at what they do — a trainable chat library and a governed BI layer respectively. PromptQuery isn't trying to be either. It's for engineers who live in psql and want one correct, read-only query from the terminal, right now, without setting anything up.
| PromptQuery | Vanna | WrenAI | |
|---|---|---|---|
| Interface | CLI / REPL | Python library | Web app |
| Setup | connect & go — live schema introspection | train on your DDL/docs/SQL (vector store) | model a semantic layer (MDL) |
| Scale approach | FK-graph retrieval over 100s of tables | RAG over example SQL | semantic layer |
| Determinism | temperature 0 by default | model default | model default |
| Writes | refused — two read-only layers | your responsibility | your responsibility |
| Sweet spot | a correct read-only query from the terminal | embedding NL→SQL in an app | self-serve BI for analysts |
| License | Apache-2.0 | MIT | Apache-2.0 |
It's also not an IDE assistant (DataGrip AI and friends) — those live in your editor and write freely; PromptQuery lives in your terminal and won't write at all. Details as of June 2026; corrections welcome via an issue.
Benchmark
The eval suite is part of the repo and reproducible:
# End-to-end (real Postgres + execution-equality scoring on the shop schema):
docker compose -f eval/docker-compose.yml up -d
PGPASSWORD=promptquery psql -h 127.0.0.1 -p 55432 -U promptquery -d shop \
    -f eval/fixtures/shop.sql \
    -f eval/fixtures/shop_seed.sql
python -m eval.end_to_end --model gpt-4o --pad 0 --pad 200

# Parsing-mode on Odoo 18 (675 tables):
python -m eval.parsing_bench \
    --fixture eval/fixtures/odoo.schema.json \
    --questions eval.questions.odoo \
    --model gpt-4o --selector-model gpt-4o-mini

# Parsing-mode on EMBL-EBI's public RNAcentral (216 tables, real biology data):
python -m eval.parsing_bench \
    --fixture eval/fixtures/rnacentral.schema.json \
    --questions eval.questions.rnacentral \
    --model gpt-4o --selector-model gpt-4o-mini
The committed eval/results_*.json files are receipts of every bench we've run — including unfavourable ones, on purpose.
See eval/END_TO_END.md for the harness internals.
What PromptQuery does NOT do (yet)
- No writes.
SELECTonly, by design and by belt-and-suspenders. - Postgres only. MySQL and SQLite are on the v0.4 roadmap.
- One database at a time. No multi-DB sessions.
- No data visualisation. Rows out, that's it. Pipe to
csv/jq/ your tool of choice.
Roadmap
- v0.2 (shipped) — LLM-assisted table selector, stemmed TF-IDF.
- v0.3 — local LLMs (Ollama), schema anonymisation (GDPR-by-default), query-history-as-few-shot.
- v0.4 — MySQL + SQLite adapters, MCP server mode, public competitor benchmark.
Development
git clone https://github.com/Cyberfilo/promptquery
cd promptquery
python3.12 -m venv .venv
.venv/bin/pip install -e ".[dev,openai]"

# Run the unit tests:
.venv/bin/pytest

# Run the retrieval eval (no API key needed, no DB needed):
.venv/bin/python -m eval.retrieval
66 tests, all pure-Python — no live database or API key required for the core suite.
License
Apache-2.0. Apache-2.0 was chosen over MIT specifically for its explicit patent grant and automatic termination clauses, which matter for a tool that operates in an active NL-to-SQL patent landscape.
1 maintainer

Metadata
1 maintainer
Release files for promptquery 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| promptquery-0.3.0.tar.gz | 838.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| promptquery-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 867.8 kB
Release files / promptquery-0.3.0.tar.gz
| Download URL | promptquery-0.3.0.tar.gz |
|---|---|
| Size | 838.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9627bd4ffafd12ab56ce45a02ddb21753d451e4e98bdda17705cdd91a7198579
|
|
BLAKE2b-256 checksum How to use checksums |
1a36790dfdc61f4fbcec404fa02a9d8258c75bc89e82dc2507084d424cf59650
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 10, 2026.
Transparency logRelease files / promptquery-0.3.0-py3-none-any.whl
| Download URL | promptquery-0.3.0-py3-none-any.whl |
|---|---|
| Size | 28.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8071411d4d1020af8d9fb5eed0795e0c4eaad0887f01d4453065ea64740e6edd
|
|
BLAKE2b-256 checksum How to use checksums |
dbe6ee886c3cb556cfddca728a19d3def9186d6246453b5f403b4b6c29862083
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 10, 2026.
Transparency log













