




English · 简体中文 · Español · Deutsch · Русский · Português (Brasil) · Français
Install · Live list · For AI agents · Proxy server · How it works · Recipes · Options · FAQ
Proxy checks you can inspect: what passed, what failed, and when. proxy-scraper collects public HTTP, SOCKS4 and SOCKS5 proxies from hundreds of lists, runs up to four checks on each one and keeps the outcome of each check for the proxies it lists (for the rest it counts how each check ended), so "working" is something you can look at instead of a label you have to trust.
https://github.com/user-attachments/assets/b99c1d8f-5bce-4a52-a8a9-b9c2c726301b
21 seconds · real interface, example numbers, documentation IPs · mp4
Try it – no install needed, uvx comes with uv (pipx run does the same):
uvx proxy-scraper-cli --pick 3 --verify               # up to 3 proxies from the hourly list that pass right now, from your network
uvx proxy-scraper-cli --diagnose socks5://HOST:PORT   # one proxy, check by check: what it did and what it didn't
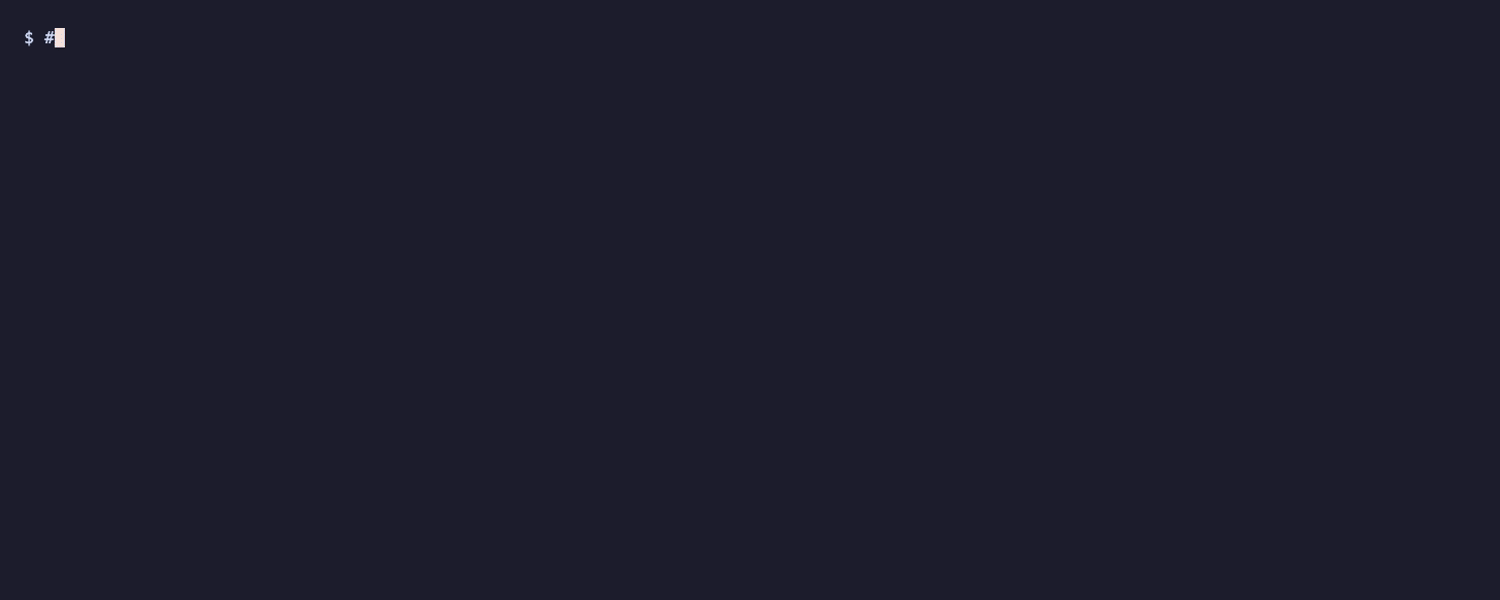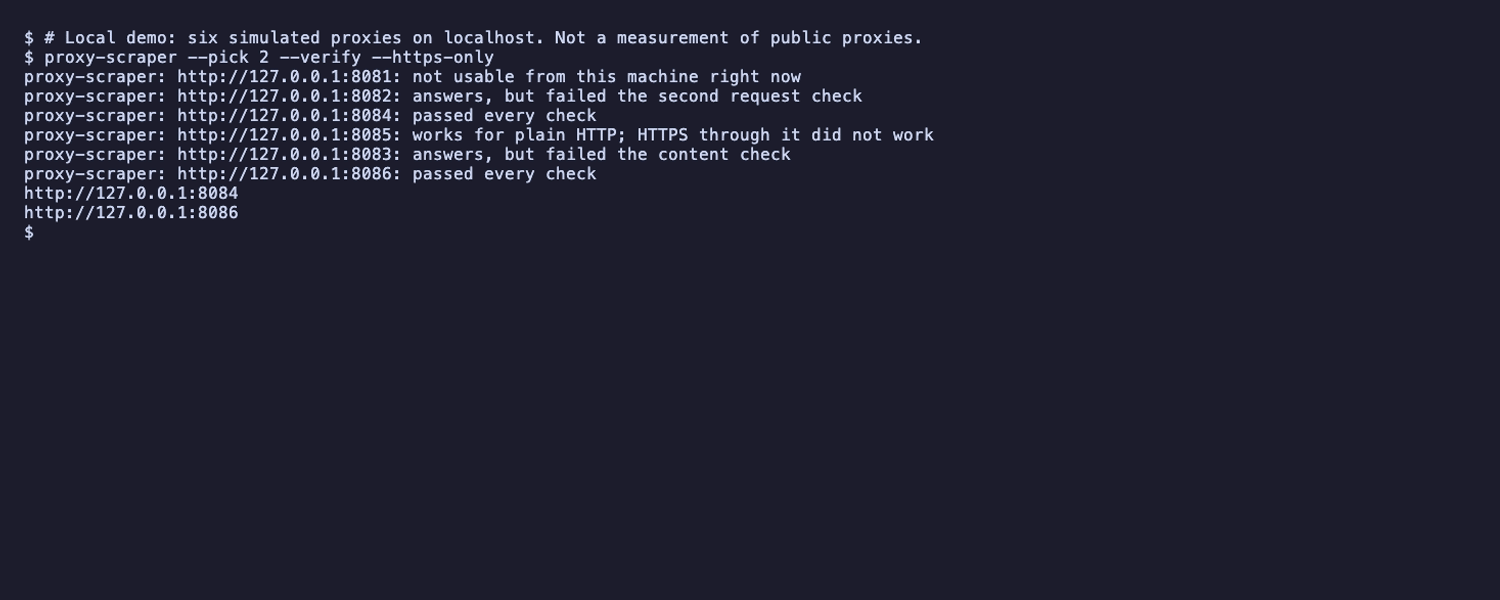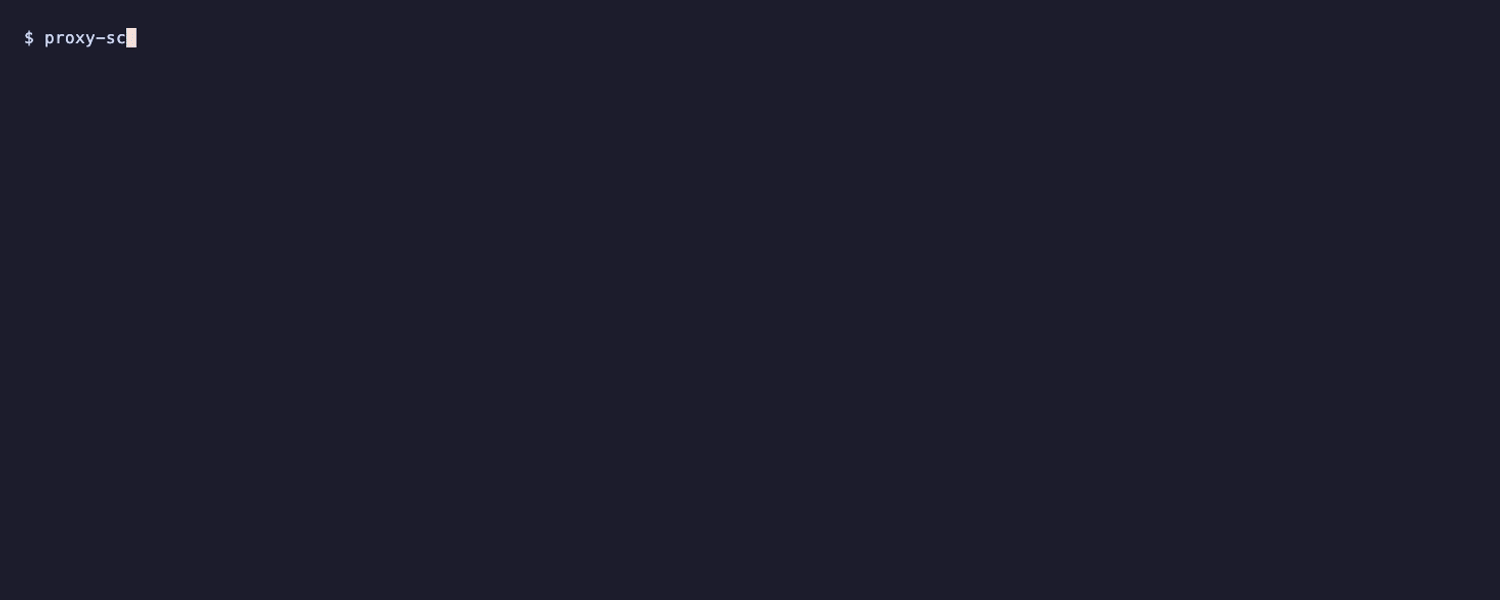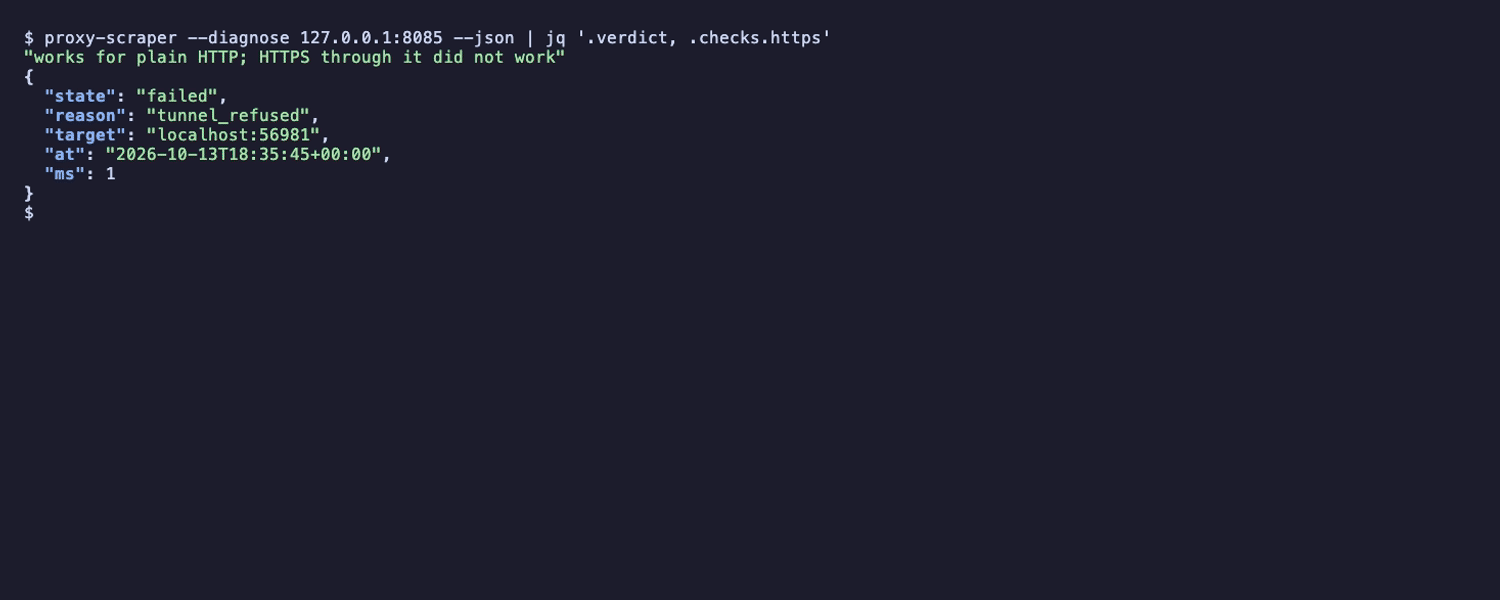
A real terminal recording, made against six simulated proxies on localhost (reproduce it). It shows how results are reported. It measures nothing about public proxies.
The package is proxy-scraper-cli on PyPI (the plain name is taken). Once installed, the command is proxy-scraper. --verify and --diagnose need version 1.30 or newer.
Three ways to get proxies, and what "checked" means for each:
| Command | Where the proxies come from | Checked | Takes |
|---|---|---|---|
proxy-scraper --pick 5 |
the published list | from GitHub's servers when the list was built, about every hour | under a second |
proxy-scraper --pick 5 --verify |
the published list | now, from your network | seconds to a minute and a half at most |
proxy-scraper -y |
every list the tool knows | now, from your network | minutes (about three in the hourly runs) |
What you get
- Every check has an outcome you can read.
passed,failed,unavailableorskipped, with a reason code, the target and the time, in the terminal, in JSON and from Python. A check that didn't run is never shown as passed, and a check target that is down doesn't turn the proxies checked against it into failures. → Check states - Fresh when it matters.
--pick --verifychecks a few proxies from your own network, usually in seconds.--recheckdoes the same for a list of your own, and--diagnosetells you why one proxy doesn't work. - More than a list. A rotating local proxy server, a Python API, an MCP server for AI agents, Docker, and exports for curl, proxychains, Clash and sing-box.
What it can't do. Free proxies are run by strangers, and of one hour's list only about a quarter is on the list again a day later. A pass is one measurement, from one network, against test targets: it is not a promise for the next hour or for the site you care about. The HTTPS check is a verified TLS connection to one test host, not a security rating. Use free proxies for public data and testing, never for logins, payments or anything personal. → What the numbers show and what they don't · How it compares · Who runs free proxies
Only want the lists? You don't need this tool: free-proxy-list has them as plain files per protocol and country, rebuilt about every hour. Or straight from here: all.txt · http.txt · socks4.txt · socks5.txt · proxies.json · more formats
Used by: the hourly list is a built-in source of monosans/proxy-scraper-checker and gfpcom/free-proxy-list.
Table of contents
Install
With pipx (recommended – gives you a proxy-scraper command in its own environment):
pipx install proxy-scraper-cli
proxy-scraper
The package is called proxy-scraper-cli on PyPI (the plain name is taken), the command is proxy-scraper.
With Homebrew on macOS and Linux:
brew install maximilianfeix/tap/proxy-scraper
The formula follows each release within about a day.
Other ways: Docker, pip, a faster event loop, or straight from the repo
# Docker – learned state and results stay in two folders next to you
mkdir -p proxy-data results
docker run --rm --user "$(id -u):$(id -g)" -v "$PWD/proxy-data:/data" -v "$PWD/results:/work/results" \
  ghcr.io/maximilianfeix/proxy-scraper --want 50 --https-only

# pip into the current environment
pip install proxy-scraper-cli

# optional: faster event loop on macOS/Linux
pipx install "proxy-scraper-cli[fast]"

# the latest main instead of the latest release
pipx install git+https://github.com/maximilianfeix/proxy-scraper.git

# no install at all
git clone https://github.com/maximilianfeix/proxy-scraper.git
cd proxy-scraper
pip install -r requirements.txt
python3 proxy_scraper.py
Every release also ships a wheel you can install with pip install <file>.whl, and a multi-arch image (amd64/arm64) on ghcr.io. In the container the wizard never shows up, it runs straight away. For the proxy server use --serve --serve-host 0.0.0.0 --serve-open with -p 127.0.0.1:8899:8899, so the port is only open on your own machine – or set -e PROXY_SCRAPER_SERVE_PASSWORD=… instead of --serve-open.
Tab completion for bash, zsh, fish and PowerShell:
eval "$(proxy-scraper --completion zsh)"     # in ~/.zshrc (after compinit), same for bash in ~/.bashrc
proxy-scraper --completion fish > ~/.config/fish/completions/proxy-scraper.fish
proxy-scraper --completion powershell | Out-String | Invoke-Expression   # in $PROFILE
Installed, the learned state lives in your user data folder (~/Library/Application Support/proxy-scraper, %LOCALAPPDATA%\proxy-scraper or ~/.local/share/proxy-scraper; override with PROXY_SCRAPER_HOME) and results go to ./results. Run from a clone, both stay inside the project. After the second run that finds proxies it asks once for a GitHub star; PROXY_SCRAPER_NO_STAR_HINT=1 turns that off (it never shows in CI).
Started without arguments, a wizard asks what you are looking for:
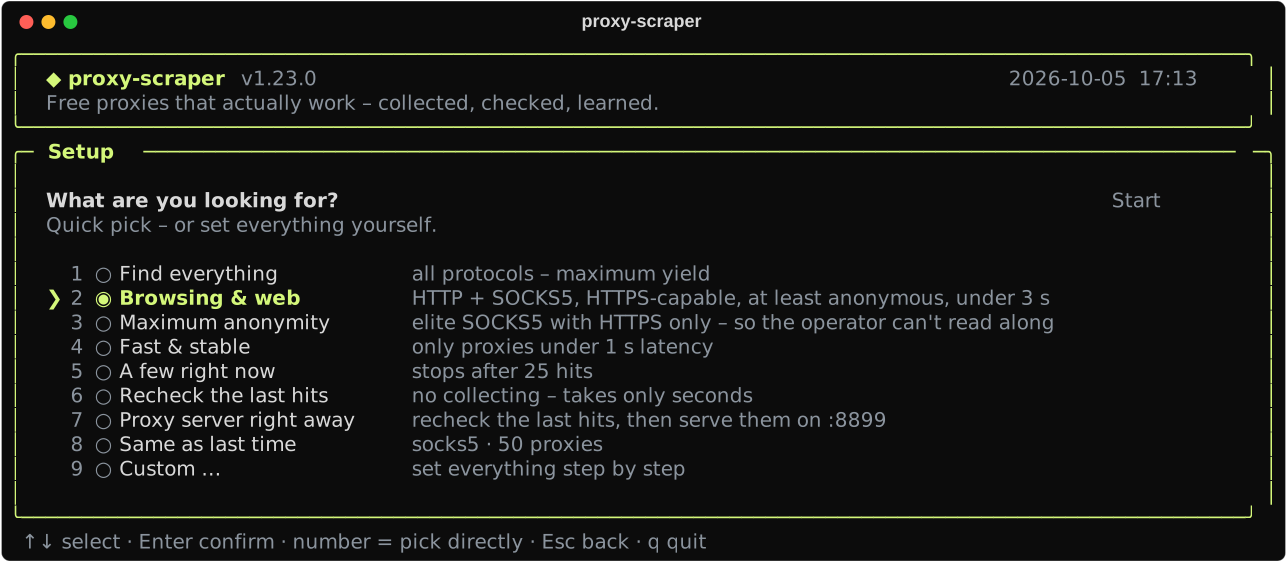 Illustration: the real interface, rendered with sample data by docs/make_demo.py. The numbers in it are made up.
| Preset | What it does |
|---|---|
| Find everything | all protocols, maximum yield |
| Browsing & web | HTTP + SOCKS5, HTTPS-capable, at least anonymous, under 3 s |
| Maximum anonymity | elite SOCKS5 with HTTPS only |
| Fast & stable | proxies under 1 s only |
| A few right now | stops after 25 hits |
| Recheck the last hits | no collecting, takes seconds |
| Proxy server right away | recheck the last hits, then serve them on :8899 |
| Same as last time | your previous choice |
| Custom … | protocols, countries, anonymity, HTTPS, target site, latency, amount, check mode |
Keys: ↑↓ select · Space toggle · 1–9 jump · Enter next · Esc back · q quit. In scripts and cron jobs the wizard never shows up – pass options or -y.
Live proxy list
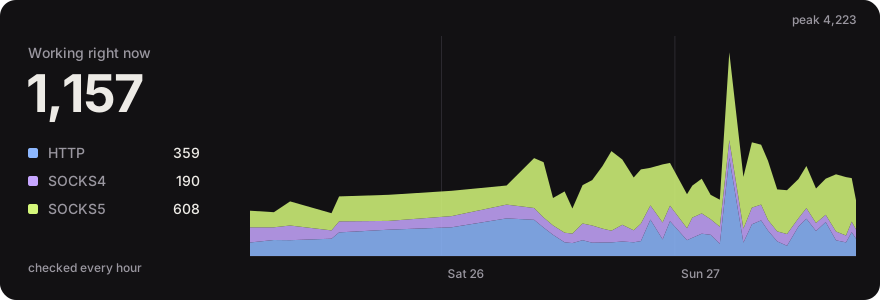
Don't want to scan yourself? About every hour GitHub Actions runs the tool and publishes the hits to the proxy-list branch – every entry passed the first request, the second request and the content check in the last run (the HTTPS test is recorded per entry, not required), best first: fast ones that are likely to still be up come on top.
Just want the lists? They also live in a repository of their own, maximilianfeix/free-proxy-list – one list per protocol, per country and per site, updated every hour, with the numbers of the last run on the front page. Watch or star it to keep it at hand. Other tools pull it too: monosans/proxy-scraper-checker and gfpcom/free-proxy-list use it as a built-in source.
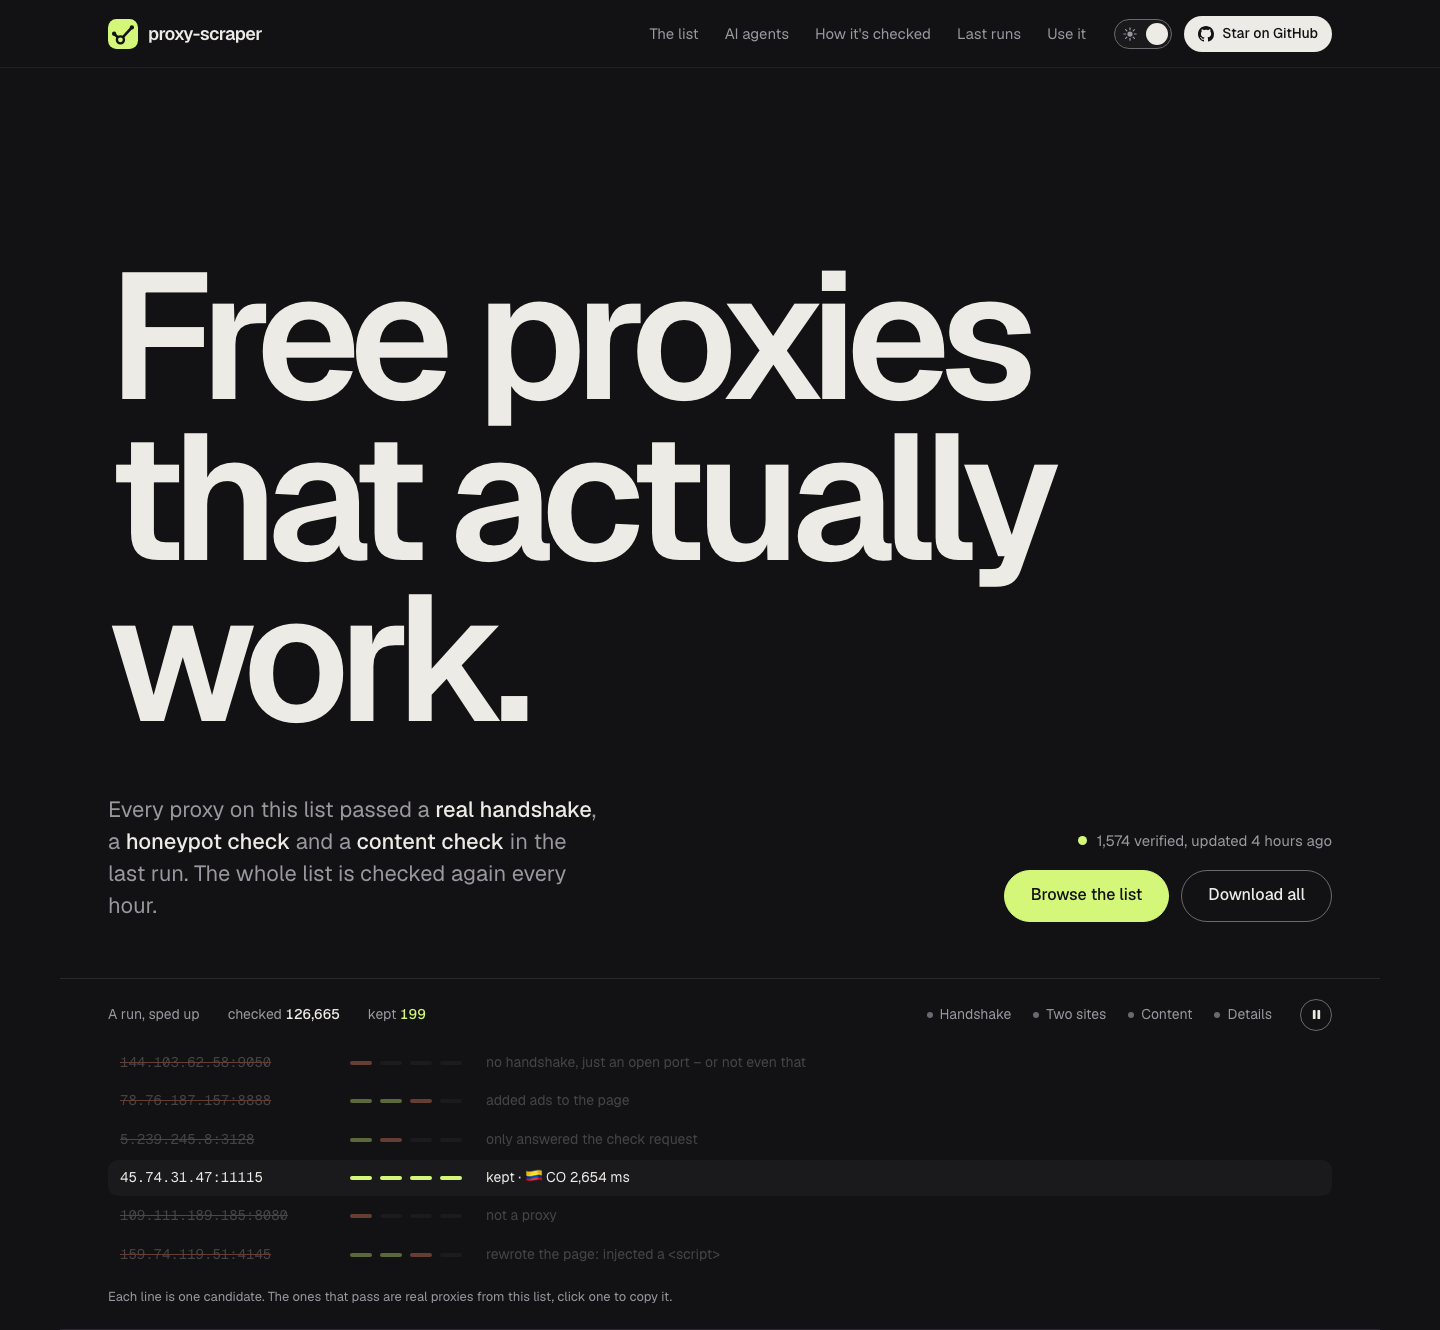
→ Browse it on the website – search, filter by type, country, HTTPS, provider and latency, see how long each proxy has been on the list and in how many of the week's runs, copy or download exactly the proxies you need.
Every protocol and country also has its own page with a plain download, e.g. SOCKS5 or Germany (country/de/proxies.txt).
| List | Format | Link |
|---|---|---|
| All | socks5://1.2.3.4:1080 |
all.txt |
| HTTP · SOCKS4 · SOCKS5 | 1.2.3.4:8080 |
http.txt · socks4.txt · socks5.txt |
| HTTPS-capable only | type://ip:port |
https.txt |
| Elite only | type://ip:port |
elite.txt |
| Gets through to Google · Reddit · Amazon · Instagram · TikTok · Discord (one test request got a normal page in the last run) | type://ip:port |
google.txt · reddit.txt · amazon.txt · instagram.txt · tiktok.txt · discord.txt |
| Stable, on the list in 90 %+ of this week's runs | type://ip:port |
stable.txt |
| With all details | latency, country, HTTPS, anonymity, exit IP, uptime, sites | proxies.json · proxies.csv |
curl -s https://raw.githubusercontent.com/maximilianfeix/proxy-scraper/proxy-list/socks5.txt | head
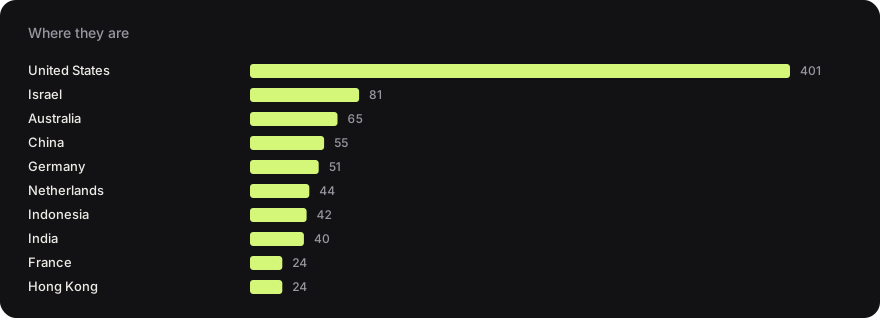
Where they come from: which free proxy lists actually work ranks every source of the hourly runs – how many proxies each one lists, how many passed every check and the share. The same as data: sources.json.
Over time: every day the first run's proxies.json is kept for good as a gzipped asset of the release of that year, like snapshots-2026 – proxies-2026-09-28.json.gz and so on, for anyone who wants to look at free proxies over weeks and months.
Every file is also on GitHub Pages, which sits behind a CDN, isn't rate limited like raw.githubusercontent and sends CORS headers, so it works straight from the browser: https://maximilianfeix.github.io/proxy-scraper/socks5.txt. jsDelivr works too, but can lag behind by a few hours.
Or let the tool start from it: proxy-scraper --recheck live downloads the list and checks it again from your network – well under a minute instead of a full scan. How many still work from your network differs a lot from the list's own count, which is the point of checking again. Add --serve and the result is a rotating proxy.
For AI agents (MCP)
proxy-scraper-mcp is an MCP server: Claude Code, Claude Desktop, Cursor, VS Code, Codex and any other MCP client can ask for working proxies and load pages through them.
| Tool | What it does |
|---|---|
get_proxies |
proxies from the hourly list, as checked in its last run – filter by protocol, country, HTTPS, elite, no datacenter, not blocklisted, stable, uptime, latency, gets through to Google/Reddit/Amazon |
check_proxies |
checks proxies from your own network, so they work from where your code runs (30–90 s, reports progress) |
fetch_url |
loads a page through a proxy from the checked list, switches proxies by itself when one fails, returns readable text – HTTPS only through proxies that passed the TLS test |
Things to ask your agent: "Load bbc.com/news as seen from the UK", "Give me 5 SOCKS5 proxies from Germany that aren't in a datacenter", "Check which of these sites block free proxies".
Needs uv – it fetches a suitable Python by itself if yours is older than 3.10. Claude Code:
claude mcp add proxy-scraper -- uvx --python ">=3.10" --from "proxy-scraper-cli[mcp]" proxy-scraper-mcp
Claude Desktop, Cursor and most other clients – add this to the MCP config (Claude Desktop: Settings → Developer → Edit Config, Cursor: ~/.cursor/mcp.json):
{
  "mcpServers": {
    "proxy-scraper": {
      "command": "uvx",
      "args": ["--python", ">=3.10", "--from", "proxy-scraper-cli[mcp]", "proxy-scraper-mcp"]
    }
  }
}
VS Code, Codex, Docker, or without uv
VS Code – .vscode/mcp.json:
{
  "servers": {
    "proxy-scraper": {
      "type": "stdio",
      "command": "uvx",
      "args": ["--python", ">=3.10", "--from", "proxy-scraper-cli[mcp]", "proxy-scraper-mcp"]
    }
  }
}
Codex – ~/.codex/config.toml:
[mcp_servers.proxy-scraper]
command = "uvx"
args = ["--python", ">=3.10", "--from", "proxy-scraper-cli[mcp]", "proxy-scraper-mcp"]
Without uv: pipx install --python python3.12 "proxy-scraper-cli[mcp]" (any Python 3.10+), then use proxy-scraper-mcp as the command.
Docker – no Python needed, the image has everything:
{
  "mcpServers": {
    "proxy-scraper": {
      "command": "docker",
      "args": ["run", "-i", "--rm", "ghcr.io/maximilianfeix/proxy-scraper", "--mcp"]
    }
  }
}
It's also in the official MCP registry as io.github.maximilianfeix/proxy-scraper, so clients that browse the registry can install it from there.
The server tells agents what it tells you: free proxies are run by strangers, so no logins, cookies or personal data through them. Local and private addresses are refused, and results go to proxy-scraper's data folder, not into the project you're working in.
Features
|
Setup wizard |
Fast |
|
Real verification |
Learns with every run |
|
Finds new sources by itself |
Filters & target sites |
|
Live dashboard |
Rotating proxy server |
|
Runs everywhere |
Thoroughly tested |
Why not just download a list?
A list tells you what worked for its author when it was built. This is what the tool adds; what other projects document about their own checks is in the comparison, no other list was measured for it.
| proxy-scraper | |
|---|---|
| Checked right before you use them, from your network | --pick --verify, --recheck, or a scan |
| The outcome of every check, with reason and time | checks in JSON, --diagnose |
| A second request that has to show the same exit IP | always attempted; if its target is down, your own run keeps the proxy as unavailable, the hourly list and --verify don't |
| A test page that has to arrive byte for byte | the same |
| HTTPS tested with a certificate that verifies (one test host) | unless --fast |
| Anonymity level and country per proxy | yes |
| Only proxies that reach your target site | --target |
| Learns which sources are worth it | yes |
| Usable as a single rotating proxy | --serve |
| API to fetch a proxy (same paths as proxy_pool) | /get |
| Ready-made list without running anything | live list |
Named and dated: how it compares to other tools and lists, task by task.
Examples
# 50 proxies that can do HTTPS – then stop
proxy-scraper --want 50 --https-only

# only Germany, Austria and Switzerland, the 20,000 most promising candidates
proxy-scraper --country DE,AT,CH -l 20000

# fast elite SOCKS5 proxies
proxy-scraper --types socks5 --anonymity elite --max-latency 1500

# 20 proxies that really reach Google AND Discord
proxy-scraper --target google.com --target discord.com --want 20

# only recheck the last hits (plus history) – takes seconds
proxy-scraper --recheck

# wizard with defaults – it keeps what you already passed
proxy-scraper -i --country DE

# which sources deliver the most?
proxy-scraper --list-sources
Running from a clone? Replace proxy-scraper with python3 proxy_scraper.py.
From Python
from proxyscraper import check_proxies, find_proxies

if __name__ == "__main__":  # needed on macOS/Windows, the parser uses a process pool
    for p in find_proxies(want=20, https=True, countries=["DE", "NL"], no_datacenter=True):
        print(p.url, p.latency, p.country, p.org)

    alive = check_proxies(["socks5://1.2.3.4:1080", "5.6.7.8:3128"])  # your own list
Same run as the command line – sources, learning, every check, result files – just without terminal output. Each result has url, latency, exit_ip, https, anonymity, country, asn, org and hosting. There's an async version of both (find_proxies_async, check_proxies_async).
Don't need a fresh scan? live_proxies takes the live list instead – no checks, one download, done in about a second:
import itertools, requests
from proxyscraper import live_proxies

proxies = live_proxies(types=["socks5"], https=True, min_uptime=90)  # the reliable ones this week
pool = itertools.cycle(p.url for p in proxies)
r = requests.get("https://api.ipify.org", proxies={"https": next(pool)}, timeout=15)  # pip install "requests[socks]"
Same filters as find_proxies, plus min_uptime, works_on (["google"], "reddit", "amazon", "instagram", "tiktok", "discord") and limit. Every result also has uptime_24h, uptime_7d, first_seen, up_for_hours and sites.
Or let the library do the retrying: ProxyRotator loads a URL through the list and moves on to the next proxy when one fails – HTTPS only through proxies with verified TLS.
from proxyscraper import ProxyRotator

with ProxyRotator(country="DE") as rotator:
    r = rotator.get("https://httpbin.org/ip")
    print(r.status, r.text, "via", r.via)
Usually a few seconds; when many proxies in a row are down it can take a minute (timeout= is per attempt). There's aget() with async with for asyncio code.
Already using requests, httpx, Playwright or Scrapy? proxy_url() gives you one local proxy address that rotates behind the scenes – every connection goes out through another proxy from the list, best first, dead ones skipped:
import requests
from proxyscraper import ProxyRotator

with ProxyRotator(country="DE") as rotator:
    proxy = rotator.proxy_url()          # http://country-de:…@127.0.0.1:…
    requests.get("https://api.ipify.org", proxies={"http": proxy, "https": proxy})
    # httpx.Client(proxy=proxy) · scrapy: meta={"proxy": proxy} · curl -x "$proxy"
    # Playwright wants the login apart: chromium.launch(proxy=rotator.playwright_proxy())
It runs on 127.0.0.1 with a random password, takes over each new hourly list by itself and stops with the with block.
Rotating proxy server
A list is nice – but usually you just want to enter one proxy address and have something behind it that keeps trying:
proxy-scraper --recheck --serve # recheck the last hits, then go – takes seconds
curl -x http://127.0.0.1:8899 https://api.ipify.org              # a different IP every time
curl -x socks5h://127.0.0.1:8899 https://api.ipify.org           # SOCKS5 on the same port
curl -x http://country-de:x@127.0.0.1:8899 https://api.ipify.org # only German exits
curl -x http://session-cart42:x@127.0.0.1:8899 https://shop.example  # same proxy for this session
curl http://127.0.0.1:8899/__proxy-scraper/status                # pool and counters as JSON
curl http://127.0.0.1:8899/__proxy-scraper/metrics               # the same for Prometheus/Grafana
Like commercial rotating proxies, the username carries what you want: country-XX, type-http|socks4|socks5 and session-NAME, combinable (country-us-type-socks5-session-a). It works for HTTP (Proxy-Authorization) and SOCKS5 (username/password auth). By default the password is ignored and the server only listens on 127.0.0.1.
To reach it from other machines, give it a password – every client then has to send it, over HTTP and SOCKS5 alike, and the status page wants it as Basic auth:
export PROXY_SCRAPER_SERVE_PASSWORD=$(openssl rand -hex 16)   # the env var keeps it out of `ps`
proxy-scraper --recheck --serve --serve-host 0.0.0.0
curl -x "http://country-de:$PROXY_SCRAPER_SERVE_PASSWORD@your-server:8899" https://api.ipify.org
Without a password the server refuses to start on any address but 127.0.0.1: that would be an open proxy for anyone who reaches the port (Docker publishes ports past host firewalls like ufw). If a firewall or -p 127.0.0.1:… already keeps others out, say so with --serve-open. The ready-made compose.yaml starts the server in Docker from the live list, with a password, a health check and learned state in a volume: put PROXY_PASSWORD=… into .env, then docker compose up -d.
| Option | What it does |
|---|---|
--rotate weighted |
default: fast and proven proxies more often, everyone gets a chance |
--rotate random / round-robin |
evenly, at random or in turn |
--rotate fastest |
always the fastest one that isn't busy |
--sticky 300 |
the same site keeps its proxy for 5 minutes (logins, carts) |
- every connection goes through a different proxy (unless sticky); fast and proven ones are preferred
CONNECTfor HTTPS and plain HTTP requests; HTTP, SOCKS4 and SOCKS5 proxies can sit behind it (SOCKS5 with DNS through the proxy)- HTTPS prefers proxies that passed the test with verified TLS; when no such proxy fits right now – none matches a wish like
country-de, or they have all dropped out – it uses the others – your client's own certificate check still catches a proxy that breaks the encryption, so leave it on - if a proxy stays silent inside the tunnel or returns an error page instead of TLS, the same first packet quietly goes to the next one
- three failures in a row and a proxy leaves the rotation – every 5 minutes those get re-checked and come back if they work again
--serve-refill 6checks fresh proxies every 6 hours in the background (the live list with--recheck live, otherwise the last run + history) with the same checks and filters, and adds the hits – a server that runs for days doesn't run dry- listens on
127.0.0.1only (unless--serve-hostsays otherwise), optionally with a password; live view with requests, success rate, pool and the latest connections
In the wizard this is Proxy server right away.
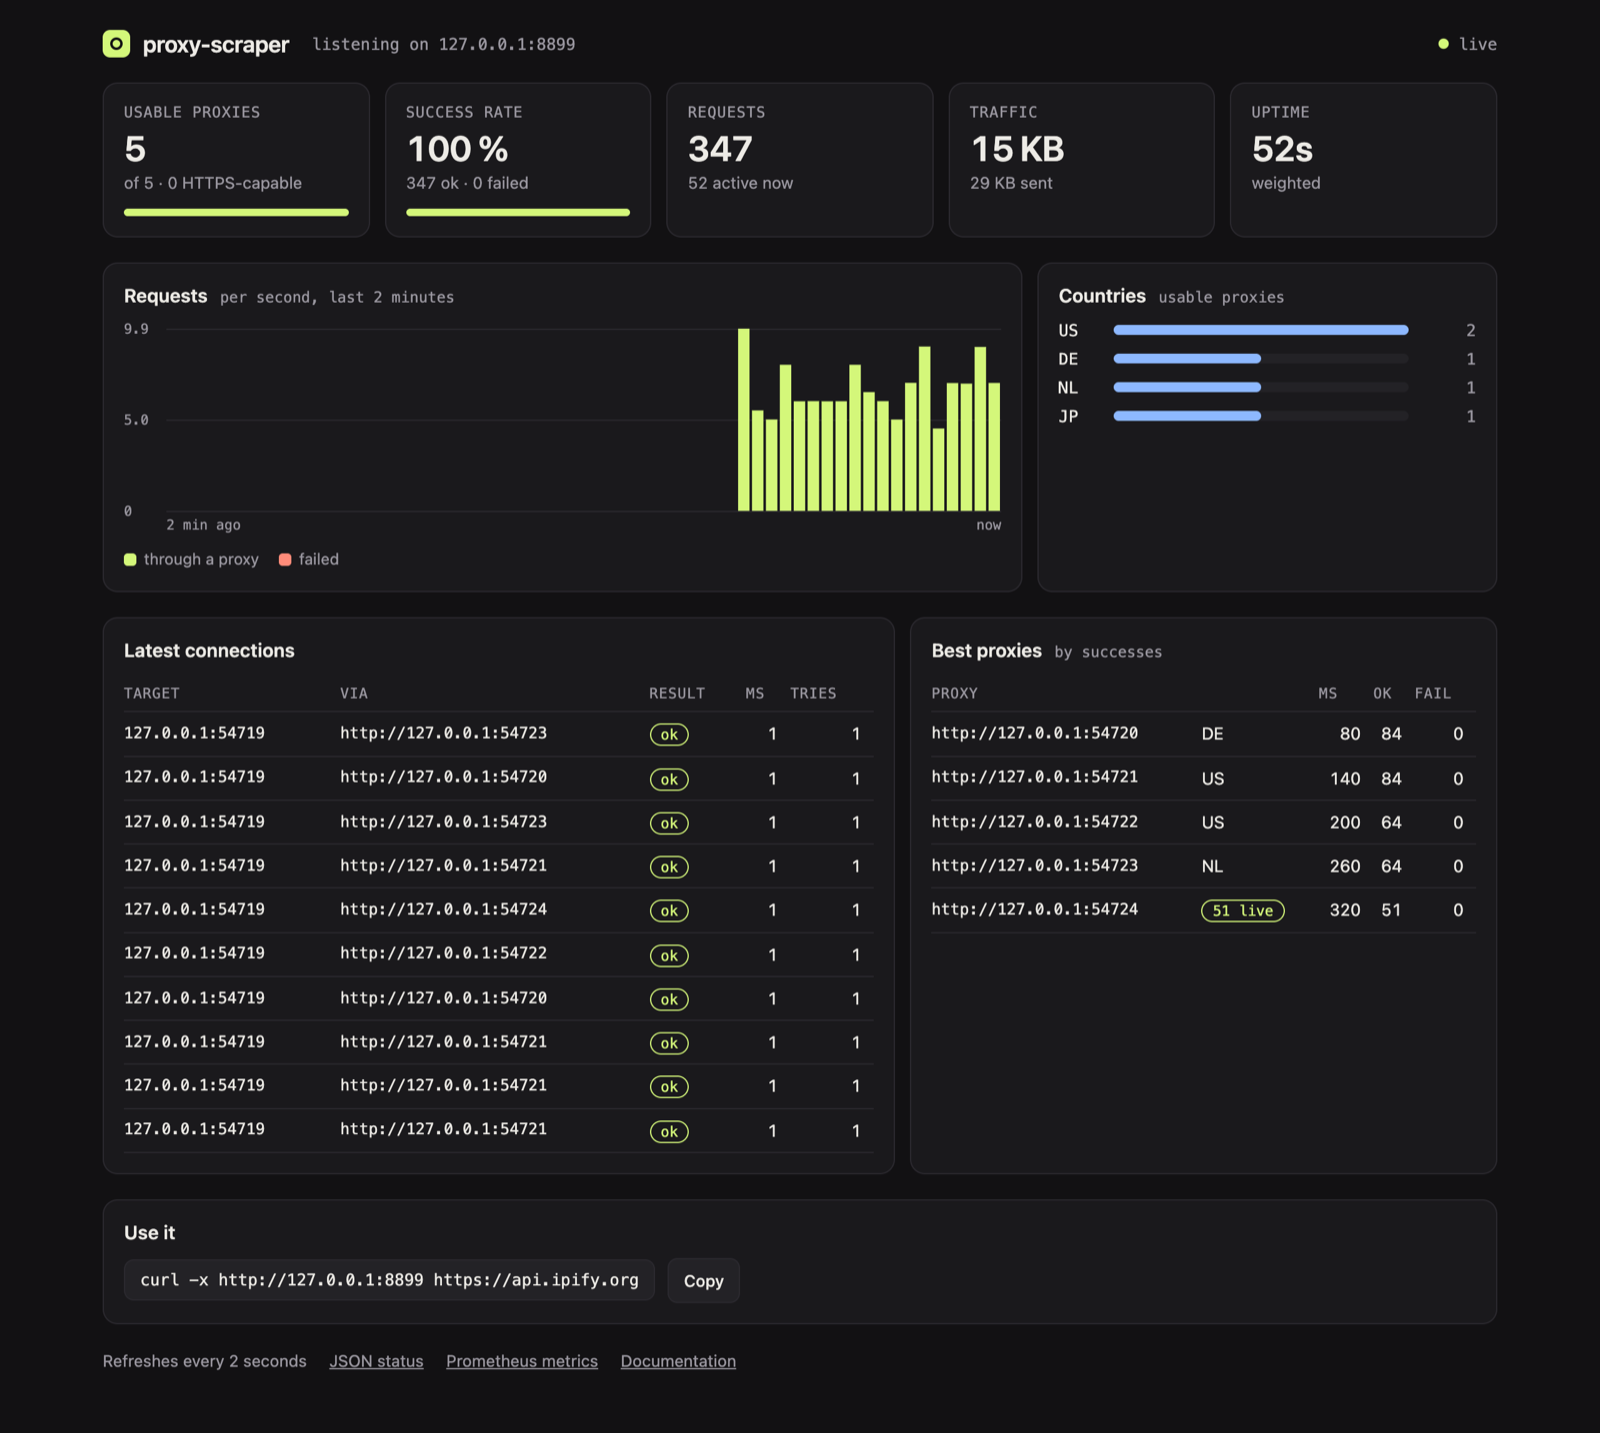
Live dashboard: open http://127.0.0.1:8899/__proxy-scraper/ in a browser – the pool, success rate, traffic, a live chart of requests, countries, the best proxies and the latest connections, refreshed every two seconds. It needs nothing from the internet, and --serve-password protects it like the rest.
Proxy pool API
Some programs want a proxy address, not a proxy – to hand it to a browser, a worker or a queue. The same port answers plain HTTP requests with one:
curl http://127.0.0.1:8899/get                          # one proxy as JSON, chosen like a connection would be
curl "http://127.0.0.1:8899/get?country=DE&https=1&format=txt"   # → http://203.0.113.7:8080
curl "http://127.0.0.1:8899/all?protocol=socks5&limit=20"        # the 20 best SOCKS5 proxies
curl "http://127.0.0.1:8899/report?proxy=203.0.113.7:8080&ok=0"  # it failed you – three times and it's out
| Endpoint | What it does |
|---|---|
/get |
one proxy, picked by the --rotate strategy |
/pop |
like /get, and the proxy leaves the pool |
/all |
every usable proxy, best first (limit=N) |
/count |
totals by type and country |
/delete?proxy=IP:PORT |
take a proxy out |
/report?proxy=IP:PORT&ok=0 |
feedback from your own requests |
Filters work on /get, /pop and /all: country=DE,AT, protocol=socks5, https=1, anonymity=elite, max_latency=1500, and format=txt for plain URLs. With --serve-password the API wants it as Basic auth, like the status page.
Coming from jhao104/proxy_pool? The endpoints, type=https and most JSON fields (proxy, https, region, check_count, fail_count, …) are the same, so point your code at port 8899 and most of it keeps working (three differences: there is no last_time, anonymous is true/false, not a string, and source is always proxy-scraper) – without Redis, and with proxies that passed the second-request, content and TLS checks:
import requests
proxy = requests.get("http://127.0.0.1:8899/get?type=https").json()["url"]   # e.g. socks5://…, type included
requests.get("https://example.com", proxies={"http": proxy, "https": proxy})
Discord and Telegram bot
The live list can also come to you: bot/ is a Discord bot that posts every run into a server – a summary with the fastest proxies, the full lists per protocol as files, and slash commands like /proxies type:socks5 country:DE https:true. It sets up its own read-only channels when you invite it, and a GitHub Action deploys it to a server as a systemd service. The same process answers on Telegram too: /proxy de socks5 for one proxy with a curl line, /proxies 10 us https for a short list. Setup in bot/README.md.
How it works
flowchart LR
    A[sources.json<br/>meta lists<br/>GitHub discovery] --> B[Fetch & parse<br/>in parallel on all cores]
    B --> C[Prioritize<br/>history → good sources → rest]
    C --> D[Check<br/>HTTP · SOCKS4 · SOCKS5]
    D --> E[Details<br/>HTTPS · anonymity · country]
    E --> F[results/]
    D -. hit rate per source .-> G[(learned state)]
    G -. next run .-> C
- Sources – the curated list in
sources.json, meta sources (other projects that maintain lists of proxy sources) and, once a day, a GitHub search for actively maintained repos. Every search adds to what earlier ones found; a list the search hasn't seen for three weeks drops out. - Collect – plain text, HTML tables, JSON APIs and
type://ip:portlines are recognized; private and reserved address ranges are dropped. Lists that haven't changed since the last run answer304and come from a local cache – a second run right after the first loads only what changed (in one logged hourly run 52 MB, with 431 of 746 lists unchanged). - Prioritize – known working proxies first, then by the learned hit rate of their sources.
- Check – every proxy has to fetch its exit IP from a check target (
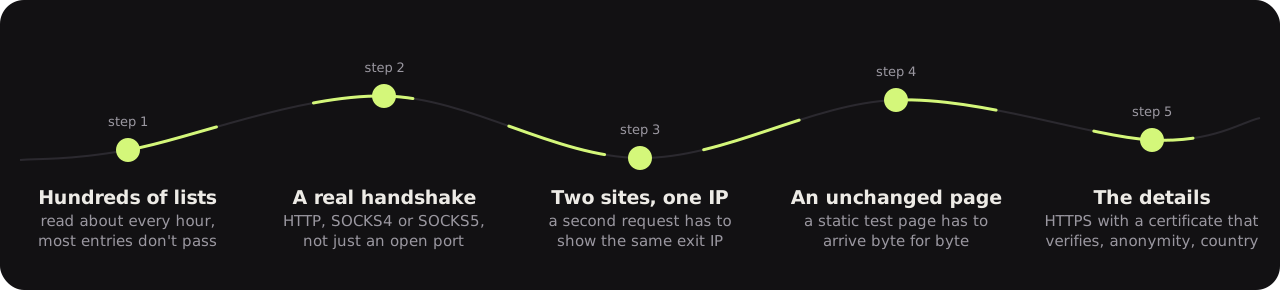
checkip.amazonaws.com, withifconfig.me,ipinfo.io,wtfismyip.comandident.meas reserves – none of them behind Cloudflare) and return a valid, foreign IP. If the target goes down mid-run, the tool switches and re-checks the proxies that were affected, so the statistics don't learn from an outage. The targets of the later checks are asked directly when a check against them fails; if they don't answer either, the proxy's check isunavailable, notfailed. Anyone passing your own IP through is out. Then comes the second request viahttpbin.org, which has to see the same exit IP: proxies that only answer the first check with “200 + IP” fail here, and so do unstable ones and exits that rotate. Finally a static HTML page has to arrive byte for byte as it does without a proxy. Each of these leaves its outcome on the result. - Countries and providers – looked up offline in the free DB-IP databases, including the provider (ASN) and whether the provider's name looks like a hosting company (between 45 % and 65 % of the entries in the lists we looked at) (downloaded once a month, ~2 µs per lookup); ip-api.com is only asked for the few addresses it doesn't know.
- Blocklists – one DNS lookup per exit IP against SpamCop, cached for the run: between 28 % and 43 % of the entries exited from a listed IP in the lists we looked at, and sites that use the list show those captchas or block them.
--no-blocklisteddrops them. If your DNS resolver is refused by SpamCop (large public resolvers are), the lookup is skipped instead of guessing. - Learn – hit rates and history are stored. Sources without hits, with content unchanged for a week or permanently unreachable are skipped.
📸 See the live dashboard and final report
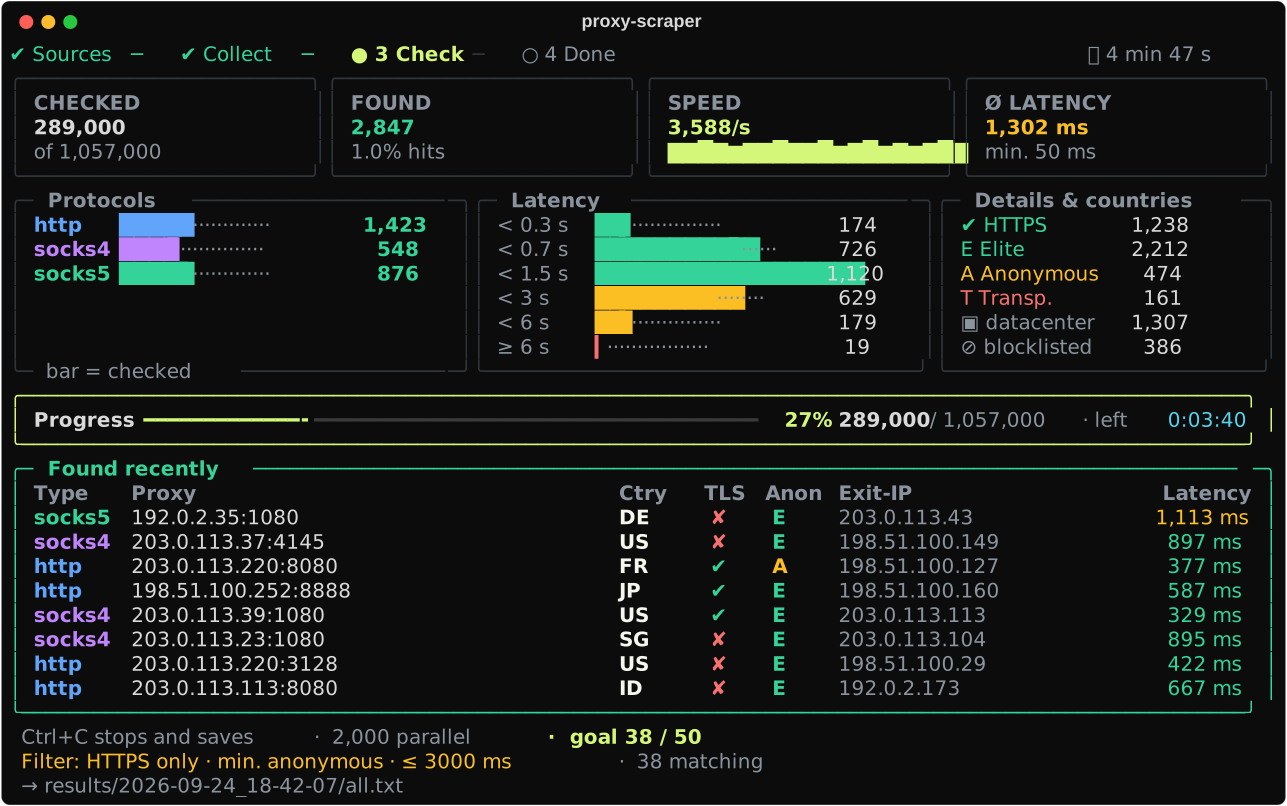
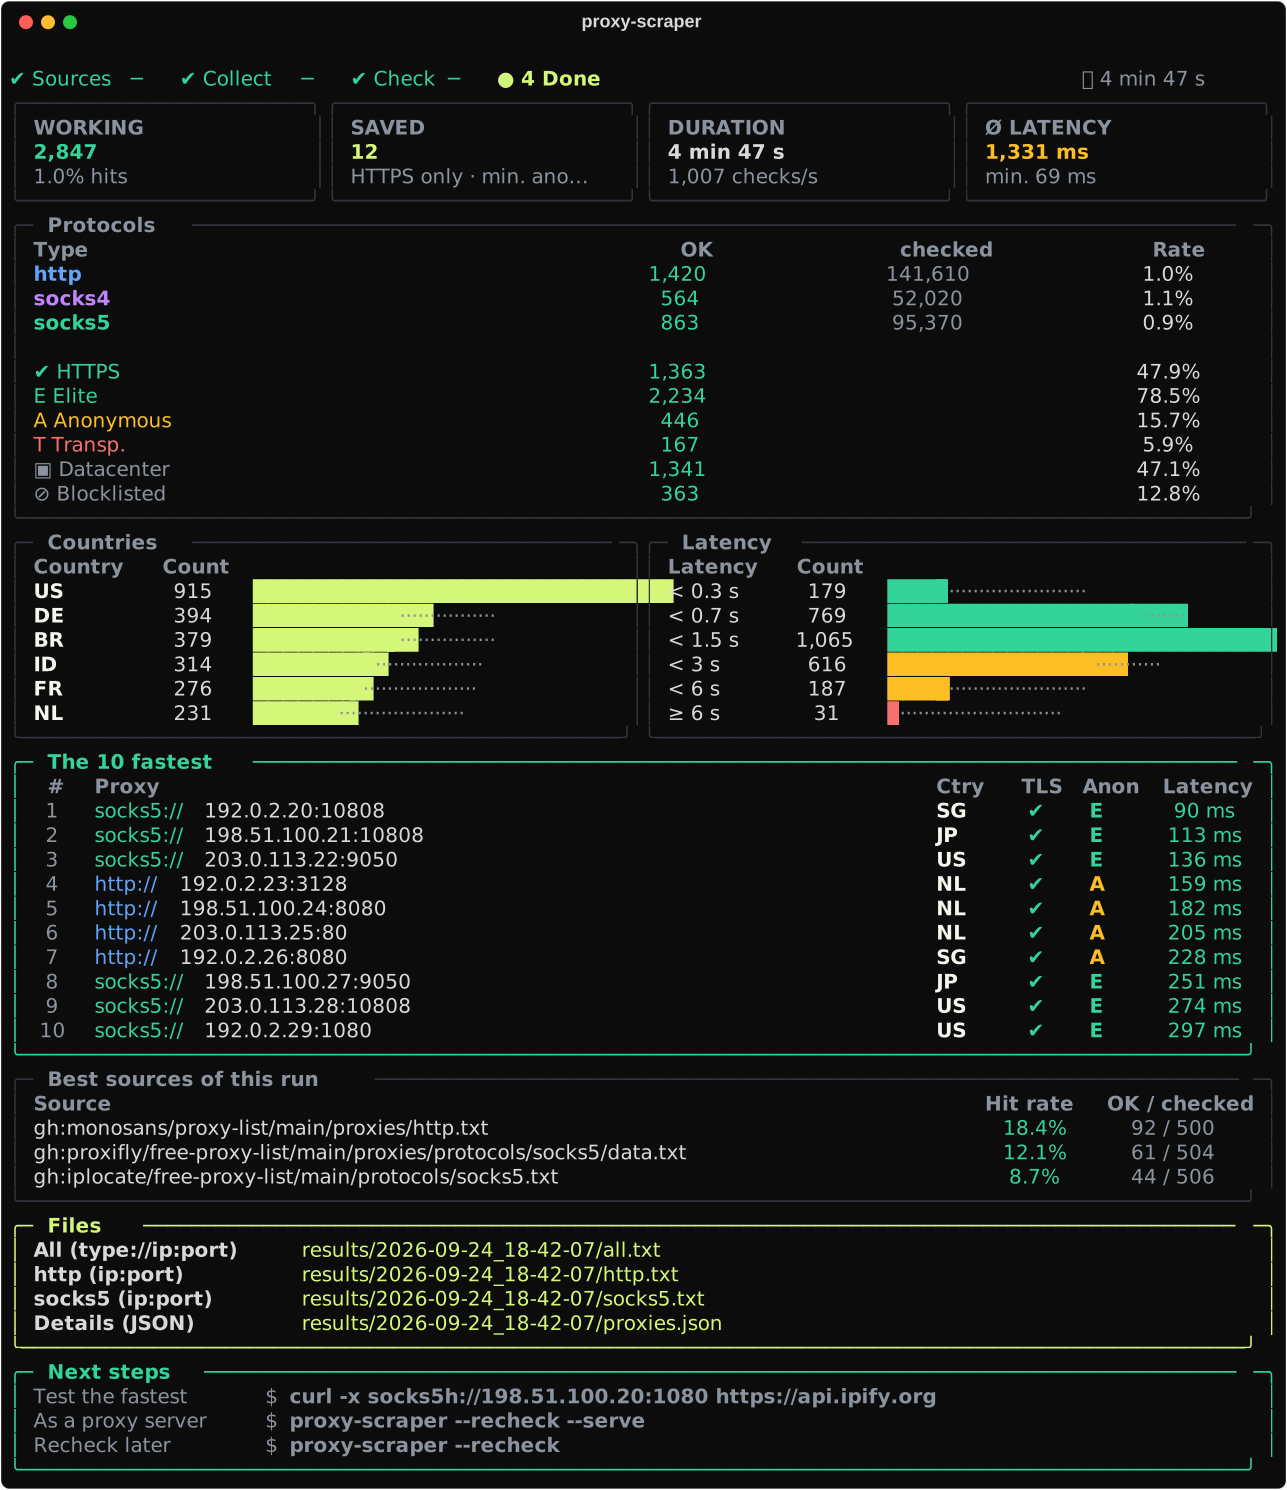 Illustration: the real interface, rendered with sample data by docs/make_demo.py. The numbers in it are made up.
Your own lists
proxy-scraper --source https://example.com/my-list.txt --source socks5=./socks.txt   # on top of the built-in sources
proxy-scraper --only-sources --source bought.txt --want 50                            # only yours
Any text with ip:port works; lines like socks5://user:pass@host:port keep their type, bare ones are tried as HTTP and SOCKS5 unless you write http=…. For logins written the way many paid lists export them, ip:port:user:pass, use --recheck bought.txt, --recheck https://example.com/proxies.txt for a list on the web, or pipe the list into --recheck - – sources leave that form alone, since lists like ip:port:US:elite look the same.
Output
Every run gets its own folder; results/latest.txt always names the newest one (on macOS/Linux there is also the symlink results/latest):
results/2026-09-24_18-42-07/
├── all.txt        socks5://203.0.113.10:1080   (fastest first)
├── http.txt       203.0.113.20:8080            (plain ip:port lists per type)
├── socks4.txt
├── socks5.txt
├── proxies.json   latency, country, HTTPS, anonymity, exit IP
└── proxies.csv
Recipes
Use the fastest proxy from the last run – free proxies die quickly, so --recheck first if the run is older than a few minutes
proxy-scraper --recheck -y
curl -x "$(head -1 results/latest/all.txt)" http://api.ipify.org
For HTTPS, pick a proxy with "https": true from proxies.json – like the Python example below does.
Python requests (pip install "requests[socks]" for SOCKS)
import json
from pathlib import Path

import requests

run = Path("results") / Path("results/latest.txt").read_text().strip()   # works on every OS
proxies = json.loads((run / "proxies.json").read_text())   # fastest first

for p in proxies:
    if not p["https"]:
        continue
    try:
        r = requests.get("https://api.ipify.org", proxies={"http": p["url"], "https": p["url"]}, timeout=8)
        print(p["url"], "→", r.text)
        break
    except requests.RequestException:
        continue  # free proxies come and go – just take the next one
httpx (pip install "httpx[socks]") – straight from the hourly list, no scan
import httpx
from proxyscraper import live_proxies

for p in live_proxies(types=["http", "socks5"], https=True, min_uptime=90, limit=10):  # httpx can't do SOCKS4
    try:
        with httpx.Client(proxy=p.url, timeout=10) as client:
            print(p.url, "→", client.get("https://api.ipify.org").text)
        break
    except httpx.HTTPError:
        continue  # next one
aiohttp (pip install aiohttp aiohttp-socks – aiohttp alone can't do SOCKS)
import asyncio

import aiohttp
from aiohttp_socks import ProxyConnector, ProxyError
from proxyscraper import live_proxies_async


async def main():
    for p in await live_proxies_async(https=True, min_uptime=90, limit=10):
        try:
            async with aiohttp.ClientSession(connector=ProxyConnector.from_url(p.url)) as session:
                async with session.get("https://api.ipify.org", timeout=aiohttp.ClientTimeout(total=10)) as r:
                    print(p.url, "→", await r.text())
                    return
        except (aiohttp.ClientError, ProxyError, asyncio.TimeoutError, OSError):
            continue  # free proxies come and go – just take the next one

asyncio.run(main())
Scrapy – a downloader middleware that sends every request, retries included, through the next proxy. Scrapy only speaks HTTP proxies, https=True picks the ones that can tunnel https:// pages
import itertools

import scrapy
from scrapy.crawler import CrawlerProcess
from proxyscraper import live_proxies

PROXIES = [p.url for p in live_proxies(types="http", https=True, min_uptime=50)]
if not PROXIES:
    raise SystemExit("No proxy matches right now – loosen the filters (e.g. min_uptime)")
POOL = itertools.cycle(PROXIES)


class RotatingProxy:
    def process_request(self, request, spider=None):  # newer Scrapy leaves out spider
        request.meta["proxy"] = next(POOL)


class IpSpider(scrapy.Spider):
    name = "ip"
    start_urls = [f"https://api.ipify.org/?n={i}" for i in range(3)]
    custom_settings = {
        "DOWNLOADER_MIDDLEWARES": {f"{__name__}.RotatingProxy": 350},
        "RETRY_TIMES": 5, "DOWNLOAD_TIMEOUT": 15,
    }

    def parse(self, response):
        print(response.meta["proxy"], "→", response.text)


if __name__ == "__main__":
    process = CrawlerProcess()
    process.crawl(IpSpider)
    process.start()
In a Scrapy project, put RotatingProxy in middlewares.py and add it to DOWNLOADER_MIDDLEWARES in settings.py. For long crawls, reload the pool now and then – the list changes every hour.
Selenium – Chrome and Firefox can't send a proxy login, so point them at the local rotating server instead: every page load goes out through another checked proxy, and dead ones are skipped for you
proxy-scraper --recheck live --serve --https-only # 127.0.0.1:8899, ready in about 30 s
from selenium import webdriver

options = webdriver.ChromeOptions()
options.add_argument("--proxy-server=http://127.0.0.1:8899")
driver = webdriver.Chrome(options=options)
driver.get("https://api.ipify.org")
print(driver.find_element("tag name", "body").text)     # a different IP on each start
driver.quit()
Firefox takes the proxy as preferences: options = webdriver.FirefoxOptions(), then options.set_preference("network.proxy.type", 1), "network.proxy.http" / "network.proxy.ssl" to "127.0.0.1" and "network.proxy.http_port" / "network.proxy.ssl_port" to 8899. Keep the server without --serve-host, so only your own machine can use it, and start it with --https-only when the pages are https:// – then only proxies that passed the HTTPS test with verified TLS serve them. One browser session keeps its connections, so for a new IP per page use session-NAME in the proxy login (not possible in Selenium) or restart the driver.
proxychains, Clash / Mihomo, sing-box – ready-made configs with --export
proxy-scraper --want 30 -y --export proxychains,clash,singbox
proxychains4 -f results/latest/proxychains.conf curl https://api.ipify.org
clash.yaml has all HTTP and SOCKS5 proxies plus a url-test group that always picks the fastest. singbox.json does the same for sing-box, SOCKS4 included, and opens a local proxy: sing-box run -c results/latest/singbox.json, then use 127.0.0.1:2080 as HTTP or SOCKS5 proxy. All three leave out HTTP proxies that can't tunnel (CONNECT), because these tools tunnel everything.
Browsers and the OS – --export pac writes proxy.pac: point Firefox, Chrome (via the system settings), FoxyProxy or macOS/Windows proxy settings at it and every request goes through the best 30 HTTP and SOCKS5 proxies in order, the browser moving on by itself when one fails. Local names and private IP addresses stay direct (a host name like 10.example.com doesn't count as private). The file itself has no DIRECT fallback and resolves no host names, and SOCKS4 is left out because it would make the browser resolve names with your own DNS. Two Firefox settings matter: turn on Proxy DNS when using SOCKS v5, and set network.proxy.failover_direct to false in about:config – otherwise Firefox goes direct once every proxy has failed. No install at all: the live list publishes one every hour at https://maximilianfeix.github.io/proxy-scraper/proxy.pac.
Proxifier (Windows, macOS) sends any program through a proxy, even ones without proxy settings. --export proxifier writes proxifier.ppx: import it via File → Import Profile, and every connection goes through a redundancy chain of the best 50 proxies – Proxifier tries them in order and takes the first that answers. localhost stays direct. HTTP proxies are included only when they can tunnel (CONNECT), SOCKS4 only without a login. Needs Proxifier 4; add --https-only for proxies that passed the HTTPS test.
Burp Suite, OWASP ZAP, mitmproxy – put the rotating server behind your intercepting proxy, so a scan or a brute-force test comes from many IPs while you still see every request. Start it with proxy-scraper --recheck live --serve, then:
| Tool | Where | Set |
|---|---|---|
| Burp Suite | Settings → Network → Connections → Upstream proxy servers | a rule for destination host *, proxy host 127.0.0.1, port 8899; with --serve-password add Basic auth (user any or a wish like country-de, the password) |
| OWASP ZAP | Options → Network → Connection → HTTP Proxy | host 127.0.0.1, port 8899, and under its authentication the user (any or a wish) and the password – use the HTTP setting, not SOCKS: ZAP never sends loopback addresses through its SOCKS proxy |
| mitmproxy | command line | mitmproxy --mode upstream:http://127.0.0.1:8899 --upstream-auth country-us:x |
Username wishes – country-us sends everything out through US proxies, session-NAME keeps one exit IP for a login flow – reach the server as the proxy login. mitmproxy sends it right away; Burp and ZAP may wait to be asked, so start the server with --serve-password when you rely on a wish there. Keep your tool's upstream certificate checks on (no --ssl-insecure in mitmproxy, no "ignore certificate errors" upstream in Burp or ZAP): free proxies are strangers, and that check is what stops one from reading or changing your HTTPS traffic. Tested end to end with mitmproxy 12, certificate checks on: HTTP and HTTPS through mitmproxy and the rotating server, every request out through a US proxy, and a site with an expired certificate refused. Only test what you're allowed to.
In a pipe – -o - prints the hits to stdout, the interface moves to stderr
proxy-scraper --recheck live --want 20 -y -o - | grep '^socks5://' > socks.txt
Check a list you already have – --recheck - reads it from stdin: plain ip:port lines, type://ip:port, logins (user:pass@ip:port or ip:port:user:pass), JSON, a CSV export or a table pasted from a website (HTML or Markdown), in the order it came in. Only what works from your network comes out:
curl -s https://example.com/proxies.txt | proxy-scraper --recheck - -o - > working.txt
Proxies without a type are tried as HTTP and as SOCKS5 – or as SOCKS4 with --types socks4 alone. A password with a comma, quote, | or bracket can't be told apart from the text around it in a paste; put such proxies in a file, one per line, and use --recheck file.txt.
Any tool, through the rotating server
proxy-scraper --recheck --serve &
export HTTPS_PROXY=http://127.0.0.1:8899 HTTP_PROXY=http://127.0.0.1:8899
pip download requests   # git, pip, npm & co. now go through the pool
In a GitHub workflow – the action picks working proxies for the next steps
Marketplace · Complete workflow, inputs and outputs
- id: proxies
  uses: maximilianfeix/proxy-scraper@v1
  with:
    types: socks5
    https: true
    min-uptime: 90        # on the list for 90 %+ of the week
    min-speed: 100        # optional: downloaded 100+ KB/s in the last check
    works-on: google      # optional: google, reddit, amazon
    recheck: true         # optional: check them again from the runner
- run: curl -x "${{ steps.proxies.outputs.proxy }}" https://api.ipify.org
proxy is the fastest one, file a text file with all of them (up to limit, default 20), count how many. Without a match the step fails, unless fail-if-empty: false.
In the shell, without a scan – --pick takes proxies from the hourly list in about half a second
curl -x "$(proxy-scraper --pick --https-only --min-uptime 90)" https://api.ipify.org
proxy-scraper --pick 10 --country DE --works-on google > de.txt
proxy-scraper --pick 5 --min-speed 200     # only ones that downloaded 200+ KB/s
"Fastest first" means the first answer plus the download speed measured in the last check – in a test with real pages, the 25 fastest by download loaded four times as many pages as the 25 quickest to answer a tiny request.
Without installing anything – straight from the live list
curl -s https://raw.githubusercontent.com/maximilianfeix/proxy-scraper/proxy-list/https.txt | head -5
The shell snippets are for macOS and Linux, where results/latest points to the newest run. On Windows, results/latest.txt holds the folder name instead – in PowerShell:
$run = "results\$(Get-Content results\latest.txt)"
curl.exe -x (Get-Content "$run\all.txt" -TotalCount 1) http://api.ipify.org
Options
Show all options
| Option | Description |
|---|---|
-i, --interactive |
setup wizard (shown automatically without arguments) |
-y, --yes |
start right away without the wizard |
--types http socks5 |
only these protocols |
-l, --limit N |
only check the N most promising proxies |
--want N |
stop as soon as N matching proxies are found |
--country DE,AT |
only these countries |
--https-only |
only proxies that can tunnel HTTPS |
--anonymity elite |
minimum anonymity (anonymous or elite) |
--max-latency MS |
maximum latency |
--no-datacenter |
skip proxies whose exit is (probably) in a datacenter – those get blocked sooner |
--no-blocklisted |
skip proxies whose exit IP is on the SpamCop blocklist – those often get captchas |
--no-dnsbl |
skip the blocklist lookup |
--target URL |
only proxies that reach this site (repeatable) |
--recheck [FILE|URL|-|live] |
only check proxies from a file, a URL, stdin (-), the last run, or the public live list |
--fast |
skip the HTTPS test (confirmation and anonymity still run) |
--no-geo |
skip the country lookup |
-c, --concurrency N |
simultaneous checks (default: 2000) |
-t, --timeout S |
timeout per proxy (default: 8 s) |
--discover |
search GitHub for new sources right now |
--no-cache |
download every list again (unchanged ones are normally skipped via ETag) |
--list-sources [N] |
show the source ranking (add --json for scripts: url, status, hit rate, checks, last change) |
--pick [N] |
print N proxies (default 1) from the hourly checked list and exit – no scan, same filters, plus --min-uptime PERCENT, --min-speed KBPS and --works-on google,reddit,… |
--verify |
with --pick: check the candidates from your machine first and print only those that pass now – 5 candidates per proxy asked for (10 to 60), up to 8 at a time, 90 s at most; exit code 3 if fewer than N passed |
--diagnose PROXY |
check one proxy and show what each check found, state by state; exit code 0 nothing failed, 1 a check failed, 3 a check could not run |
--json |
with --pick or --diagnose (and --list-sources): the result as JSON on stdout |
--serve-host ADDR |
where the proxy server listens (default 127.0.0.1; any other address needs a password or --serve-open) |
--serve-password SECRET |
clients must send this password in the proxy login; better set PROXY_SCRAPER_SERVE_PASSWORD |
--serve-open |
allow --serve-host without a password – only behind a firewall or with docker -p 127.0.0.1:… |
--rotate STRATEGY · --sticky SEC |
how the proxy server picks proxies, see above |
--serve-refill HOURS |
while serving, check fresh proxies every HOURS and add the hits to the pool |
--serve [PORT] |
afterwards serve as a rotating proxy on 127.0.0.1:PORT (default: 8899) |
-o FILE |
also write all hits to this file; -o - prints them to stdout |
--export FORMATS |
extra files for other tools: proxychains, clash, singbox, curl, pac, proxifier or all |
-V, --version |
print the version |
--completion SHELL |
print the tab completion script for bash, zsh, fish or PowerShell |
Everything else: proxy-scraper --help
GitHub Actions
The repo does part of the work itself:
| Workflow | What it does |
|---|---|
| tests | 3 operating systems × 4 Python versions, plus a built and installed package – on every push and pull request |
| lint | ruff with a pinned version – same rules locally and in CI |
| codeql | security analysis on every push and once a week |
| proxy list | about every hour: collect, check, publish to proxy-list. The learned statistics live in the Actions cache, so the tool keeps getting better in the cloud too |
| docker | builds the image on every change and runs a real scan inside it; on a version tag it publishes linux/amd64 + linux/arm64 to ghcr.io |
| release | on a version tag: test, build, smoke-test and publish a GitHub release with the wheel |
| discord bot | tests the bot and deploys it to the server on every change in bot/ |
| Dependabot | keeps the action versions up to date |
FAQ
Who runs free proxies – and should you use them?
Almost nobody runs a free proxy for you. What ends up on public lists is usually one of these:
- Misconfigured servers – a Squid, a router or an app with a proxy port that was meant to stay internal.
- Deliberately open proxies – a few volunteers and research projects, and services that give some away to sell the rest.
- Infected machines – computers and IoT devices whose owners don't know they relay traffic. Many residential exits are like this.
- Traps – honeypots that log what goes through them, and proxies that rewrite pages to inject ads or scripts.
That is general background, not something this project measured: a check can't see who runs a proxy or why.
proxy-scraper can't tell an infected home router from an open office proxy, but it filters what it can measure: a proxy has to answer two independent requests with the same exit IP, deliver a known page byte for byte, and HTTPS counts only with a certificate that verifies for the test host. Each hit says whether its exit is in a datacenter.
Good uses: public data, checking how a site looks from another country, testing your own blocking and rate limits, research. Never send passwords, cookies, payment or personal data through a free proxy, and keep HTTPS certificate checks on. Use them only where you're allowed to.
Almost nothing gets through.
Many company, school and university networks block proxy connections. The tool notices a hit rate below 0.2 % and warns you – a different network such as a phone hotspot helps. The learned statistics are not downgraded in such a run.
Does it work on Windows?
Yes, in PowerShell and Windows Terminal. uvloop doesn't exist there and is skipped automatically. In the old cmd.exe window some symbols may be missing depending on the font.
Why does it find fewer proxies than other lists claim to have?
Because only proxies that pass every check are kept: two independent requests that show the same foreign exit IP, and a test page that arrives unchanged. In the hourly runs that is about 1 % of the 150,000 candidates checked. They passed from the network that checked them, at that moment.
What about proxies with a username and password?
Lines like socks5://user:pass@1.2.3.4:1080 keep their login: HTTP proxies get a Proxy-Authorization header, SOCKS5 uses username/password auth (RFC 1929), SOCKS4 the user ID. The same works for --recheck with your own list. The result files keep the credentials, the terminal only shows user:•••.
How fresh is the live list?
It's rebuilt about every hour; the “updated” badge shows the last run. Free proxies come and go quickly, so for anything important run proxy-scraper --recheck right before use.
Is it safe to use free proxies?
Only for things that don't matter. Public proxies are run by strangers who can read everything that isn't encrypted. Never send passwords or personal data through them, and only use them for legal purposes.
Roadmap
What's next is in the open issues – ideas and wishes are welcome as an issue. During Hacktoberfest there are beginner-friendly issues with pointers on where to start.
Shipped in v1.24 to v1.26: --recheck - for lists you pipe in, which proxies get through to Discord, a README you can try in five seconds, the MCP server in the Docker image, logins written as ip:port:user:pass, and a Hugging Face dataset that loads in one line.
Shipped in v1.22 and v1.23: a live dashboard for the rotating server, --export pac and an hourly proxy.pac, "best first" that counts how likely a proxy is still up, the lists in a repository of their own (free-proxy-list), daily snapshots on Hugging Face, brew install, a Chinese README, Python 3.14, and a recipe for Burp Suite, ZAP and mitmproxy.
Shipped in v1.10 to v1.21: download speed per proxy and "best first" everywhere, daily snapshots, a rotating proxy URL for requests, httpx and Playwright, --pick for working proxies without a scan, a proxy pool API compatible with jhao104/proxy_pool, your own lists with --source, a GitHub Action, a Telegram bot and an Atom feed for the weekly report.
Shipped in v1.8 and v1.9: uptime per proxy and stable.txt, which proxies get through to Google, Reddit and Amazon, live_proxies() in Python, a page per proxy with its week of checks, a weekly report, live charts in this README, shareable filters on the website, sources mined from other scrapers' lists, untyped lists tried as HTTP and SOCKS5, --export singbox, PowerShell completion and recipes for httpx, aiohttp and Scrapy.
Shipped in v1.7: an MCP server so AI agents get working proxies and can load pages through them, 28 new sources and a GitHub search that runs daily and keeps what it found, and a cleaner website.
Shipped in v1.6: spam blocklist check for every exit IP, a live list refreshed every hour, pages per protocol and country, an optional password for the proxy server and a pool that refills itself while it runs, compose.yaml, -o - for pipes, a Discord bot, and a new website and README – everything in English now.
Shipped in v1.5: content tampering check, live list website with trend and stable proxies, provider/datacenter info, a much bigger proxy server (rotation strategies, sticky sessions, SOCKS5 inbound, status and Prometheus metrics), --recheck live, Python API, shell completion. Measured and dropped earlier: protocol detection with an extra connection (#3) and IPv6 (#1).
Contributing
Bug reports, new sources and pull requests are very welcome – see CONTRIBUTING.md, and docs/ARCHITECTURE.md for how the pieces fit together. The short version:
pip install -e ".[dev]"
python3 -m pytest          # runs offline – fake proxies on localhost
ruff check .
python3 docs/make_demo.py  # regenerate the images in this README
Project structure
proxy_scraper.py        entry point when run from a clone
bot/                    Discord bot for the live list (own requirements, deployed by GitHub Actions)
proxyscraper/
├── cli.py              arguments, wizard or direct start
├── app.py              one run in phases: network → jobs → check → learn & report
├── options.py          RunOptions + Filters – all settings in one place
├── pipeline.py         collect sources, prioritize, check loop
├── checker.py          the checks: basic, second request, content, HTTPS
├── handshake.py        HTTP/SOCKS4/SOCKS5 handshakes incl. login
├── judges.py           check targets, Cloudflare filter, failover
├── sources.py          source lists, meta sources, GitHub discovery, statistics
├── sources.json        curated sources
├── fetchcache.py       ETag cache for unchanged lists
├── parsing.py          find proxies in text, HTML and JSON
├── history.py          history of working proxies
├── geo.py              countries: offline first, ip-api.com as fallback
├── asndb.py            DB-IP provider database, datacenter heuristic
├── geodb.py            DB-IP country database (monthly, binary search)
├── targets.py          target sites for --target
├── output.py           result files
├── exporters.py        proxychains, Clash, sing-box, curl, PAC and Proxifier formats (--export)
├── server/             rotating proxy server (--serve): pool · http · upstream · socks · status · api · core
├── api.py              find_proxies() / check_proxies() for Python
├── agent.py            MCP tools without the SDK: live list, filters, fetch through proxies
├── mcp_server.py       MCP server (proxy-scraper-mcp) for AI agents
├── publish.py          live list for GitHub Actions
├── sourcepages.py      the ranking of the sources on the website
├── mirror.py           the same lists in their own repo (free-proxy-list)
├── paths.py            where state and results are stored
├── compat.py           differences between Unix and Windows
├── netio.py            small HTTP client on asyncio
└── ui/                 widgets · dashboard · report · wizard · serve · keys
Community
Questions, ideas and things you built with it go to Discussions – bugs to the issues. If proxy-scraper saves you time, a ⭐ helps others find it.
Thanks to everyone who helped build it – new sources, countries, Python 3.14, examples and more:
Want to join? Beginner-friendly issues say where to start.
From the same author: dejabuilt, an agent skill that checks GitHub before you build – it tells you whether a project idea already exists, with the numbers.
Acknowledgements
proxy-scraper stands on the work of the people who publish free proxy lists. Thanks to everyone listed in sources.json, and especially to
- monosans/proxy-scraper-checker and gfpcom/free-proxy-list, whose curated source collections are read as meta sources
- Textualize/rich, which draws the whole terminal UI
- IP Geolocation by DB-IP – the free country database (CC BY 4.0) used for offline country lookups
- httpbin, checkip.amazonaws.com, ifconfig.me, ipinfo.io, wtfismyip.com, ident.me and ip-api.com, used as check targets and for country lookups
Disclaimer
This tool only collects publicly listed proxies and checks whether they work. You are responsible for how you use them – respect the terms of the sites you visit and the laws where you live.
Made in Germany by @maximilianfeix · MIT License · Changelog · Security · Contributing
If proxy-scraper saves you time, a ⭐ helps others find it.
1 maintainer

Metadata
1 maintainer
Release files for proxy-scraper-cli 1.30.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| proxy_scraper_cli-1.30.0.tar.gz | 531.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| proxy_scraper_cli-1.30.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 917.3 kB
Release files / proxy_scraper_cli-1.30.0.tar.gz
| Download URL | proxy_scraper_cli-1.30.0.tar.gz |
|---|---|
| Size | 531.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8959b7be3da9da5ecb0259c618c66992688735568a3996093ab435b7eac1baab
|
|
BLAKE2b-256 checksum How to use checksums |
4a3aeecbb27c06ed6afda85ed7a7515b580967fba8d0e8ecb2c09078623f9ee3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency logRelease files / proxy_scraper_cli-1.30.0-py3-none-any.whl
| Download URL | proxy_scraper_cli-1.30.0-py3-none-any.whl |
|---|---|
| Size | 385.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ec9ed2513d2d0e36bca911a141ad1c516b5068ca7ce5211783cbe8fd52e7a326
|
|
BLAKE2b-256 checksum How to use checksums |
35e1ca02c3344d91604d0ca71326619461c70428bb3ee636d655869fd5a02ce2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 16, 2026.
Transparency log













