
Psycholing Metrics


Extract word-level linguistic metrics from text: surprisal (primary focus), frequency, word length, and parsing features (POS, NER, morphology, dependencies via spaCy).
Installation
pip install psycholing-metrics
python -m spacy download en_core_web_sm
Or install directly from GitHub:
pip install git+https://github.com/lacclab/psycholing-metrics.git
Quick Start
import spacy
from psycholing_metrics import get_metrics, create_surprisal_extractor, SurprisalExtractorType

text = "Many of us know we don't get enough sleep."

extractor = create_surprisal_extractor(
    extractor_type=SurprisalExtractorType.CAT_CTX_LEFT,
    model_name="gpt2",
)
parsing_model = spacy.load("en_core_web_sm")

metrics = get_metrics(
    target_text=text,
    surp_extractor=extractor,
    parsing_model=parsing_model,
    parsing_mode="re-tokenize",
    add_parsing_features=True,
)
Output (one row per word):
| Word | Length | Wordfreq_Frequency | subtlex_Frequency | gpt2_Surprisal | Word_idx | Token | POS | TAG | Token_idx | Relationship | Morph | Entity | Is_Content_Word | Reduced_POS | Head_word_idx | n_Lefts | n_Rights | AbsDistance2Head | Distance2Head | Head_Direction | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | Many | 4 | 10.2645 | 11.4053 | 7.2296 | 1 | Many | ADJ | JJ | 0 | nsubj | ['Degree=Pos'] | True | ADJ | 4 | 0 | 1 | 3 | 3 | RIGHT | |
| 1 | of | 2 | 5.31617 | 6.39588 | 1.76724 | 2 | of | ADP | IN | 1 | prep | [] | False | FUNC | 1 | 0 | 1 | 1 | -1 | LEFT | |
| 2 | us | 2 | 9.82828 | 9.16726 | 1.56595 | 3 | us | PRON | PRP | 2 | pobj | ['Case=Acc', 'Number=Plur', 'Person=1', 'PronType=Prs'] | False | FUNC | 2 | 0 | 0 | 1 | -1 | LEFT | |
| 3 | know | 4 | 9.63236 | 7.41279 | 3.44459 | 4 | know | VERB | VBP | 3 | parataxis | ['Tense=Pres', 'VerbForm=Fin'] | True | VERB | 7 | 1 | 0 | 3 | 3 | RIGHT | |
| 4 | we | 2 | 8.17085 | 6.75727 | 5.35026 | 5 | we | PRON | PRP | 4 | nsubj | ['Case=Nom', 'Number=Plur', 'Person=1', 'PronType=Prs'] | False | FUNC | 7 | 0 | 0 | 2 | 2 | RIGHT |
You can also call individual functions:
from psycholing_metrics import get_surprisal, get_frequency, get_word_length

surprisal_df = get_surprisal(text, surp_extractor=extractor)
frequency_df = get_frequency(text, language="en")
length_df = get_word_length(text, disregard_punctuation=True)
Multi-Model Extraction
Extract surprisal from multiple models at once using extract_metrics_for_multiple_models:
import pandas as pd
from psycholing_metrics import SurprisalExtractorType
from psycholing_metrics.eye_tracking import extract_metrics_for_multiple_models

text_df = pd.DataFrame({
    "Phrase": [1, 2, 1, 2],
    "Line": [1, 1, 2, 2],
    "Target_Text": [
        "Is this the real life?",
        "Is this just fantasy?",
        "Caught in a landslide,",
        "no escape from reality",
    ],
    "Prefix": ["pre 11", "pre 12", "pre 21", "pre 22"],
})

metrics_df = extract_metrics_for_multiple_models(
    text_df=text_df,
    text_col_name="Target_Text",
    text_key_cols=["Line", "Phrase"],
    surprisal_extraction_model_names=["gpt2", "EleutherAI/pythia-70m"],
    surp_extractor_types=SurprisalExtractorType.CAT_CTX_LEFT,
    add_parsing_features=False,
    model_target_device="cuda",
    extract_metrics_kwargs={
        "ordered_prefix_col_names": ["Prefix"],
    },
)
To extract surprisal using multiple extractor types, pass a list to surp_extractor_types.
This produces a separate column for each (model, type) combination:
metrics_df = extract_metrics_for_multiple_models(
    text_df=text_df,
    text_col_name="Target_Text",
    text_key_cols=["Line", "Phrase"],
    surprisal_extraction_model_names=["gpt2"],
    surp_extractor_types=[
        SurprisalExtractorType.CAT_CTX_LEFT,
        SurprisalExtractorType.PIMENTEL_CTX_LEFT,
    ],
    add_parsing_features=False,
    model_target_device="cuda",
)
# Result columns: gpt2_cat_Surprisal, gpt2_pimentel_Surprisal, ...
Eye-Tracking Integration
Add word-level metrics to an SR interest area report:
import pandas as pd
from psycholing_metrics import SurprisalExtractorType
from psycholing_metrics.eye_tracking import add_metrics_to_eye_tracking_report

df = pd.read_csv("path/to/interest_area_report.csv")

enriched_df = add_metrics_to_eye_tracking_report(
    eye_tracking_data=df,
    textual_item_key_cols=["paragraph_id", "batch", "article_id", "level"],
    surprisal_extraction_model_names=["gpt2"],
    spacy_model_name="en_core_web_sm",
    parsing_mode="re-tokenize",
    model_target_device="cuda",
    surp_extractor_types=SurprisalExtractorType.CAT_CTX_LEFT,
)
Surprisal Extractors
| Type | Column Suffix | Description |
|---|---|---|
CAT_CTX_LEFT |
cat |
Standard text-level concatenation. The "buggy" version per Pimentel & Meister (2024). |
PIMENTEL_CTX_LEFT |
pimentel |
Corrected surprisal computation per Pimentel & Meister (2024). |
SOFT_CAT_WHOLE_CTX_LEFT |
softwhole |
Embedding-level: aggregates entire left context into one vector. |
SOFT_CAT_SENTENCES |
softsent |
Embedding-level: aggregates left context per-sentence. |
INV_EFFECT_EXTRACTOR |
inveffect |
Measures how much context reduces surprisal. |
The surprisal column name follows the pattern {model_name}_{suffix}_Surprisal (e.g., gpt2_cat_Surprisal). When using multiple extractor types, each produces its own column.
Supported Models
GPT-2:    gpt2, gpt2-medium, gpt2-large, gpt2-xl
GPT-Neo:  EleutherAI/gpt-neo-125M, EleutherAI/gpt-neo-1.3B, EleutherAI/gpt-neo-2.7B,
          EleutherAI/gpt-j-6B, EleutherAI/gpt-neox-20b
OPT:      facebook/opt-125m, facebook/opt-350m, ..., facebook/opt-66b
Pythia:   EleutherAI/pythia-70m, ..., EleutherAI/pythia-12b
Llama:    meta-llama/Llama-2-7b-hf, meta-llama/Llama-2-13b-hf, meta-llama/Llama-2-70b-hf
Gemma:    google/gemma-2b, google/gemma-7b (also *-it versions)
Mamba:    state-spaces/mamba-130m-hf, ..., state-spaces/mamba-2.8b-hf
Mistral:  mistralai/Mistral-7B-Instruct-v0.*
Llama, Gemma, and Mistral require a HuggingFace access token via the
hf_access_tokenparameter.
Prefix-Conditioned Surprisal
Condition surprisal on a left context prefix:
metrics = get_metrics(
    target_text=text,
    surp_extractor=extractor,
    parsing_model=None,
    add_parsing_features=False,
    left_context_text="What university is Dr. Kelley from?",
)
Without Left Context
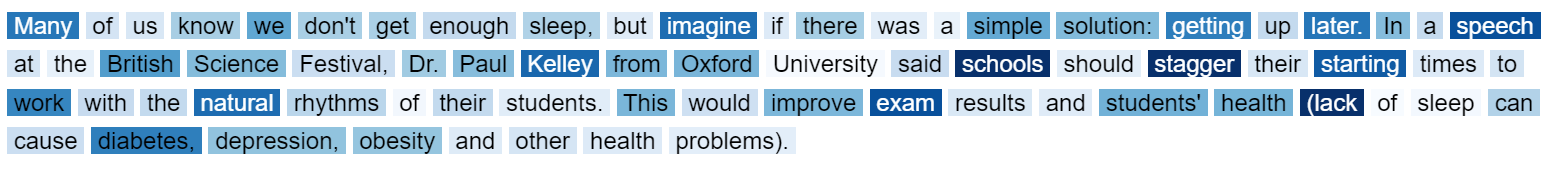
With Left Context
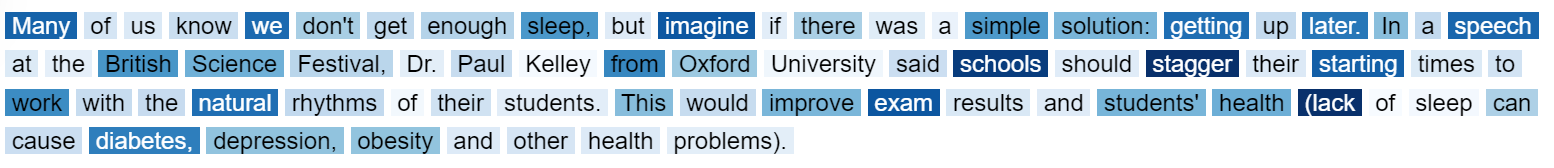
The SOFT_CAT_WHOLE_CTX_LEFT and SOFT_CAT_SENTENCES extractors provide embedding-level context concatenation for more nuanced control over how the prefix affects surprisal.
Notes
- Words are split by whitespace and include adjacent punctuation.
- A word's surprisal is the sum of its sub-word token surprisals.
- BOS representation is used when available (e.g., GPT-2), following Pimentel & Meister (2024).
Parsing Features
get_parsing_features (from psycholing_metrics.text_processing) extracts word-level linguistic features using spaCy. It can also be used standalone, without surprisal extraction:
import spacy
from psycholing_metrics.text_processing import get_parsing_features

nlp = spacy.load("en_core_web_sm")
features = get_parsing_features("The cat sat on the mat.", nlp, mode="re-tokenize")
Output columns:
| Column | Description |
|---|---|
Word_idx |
1-indexed word position |
Token |
The word token |
POS |
Universal POS tag (NOUN, VERB, ADJ, ...) |
TAG |
Fine-grained POS tag (NN, VBD, JJ, ...) |
Relationship |
Dependency relation to head (nsubj, dobj, prep, ...) |
Morph |
Morphological features (tense, number, case, ...) |
Entity |
Named entity type (PERSON, ORG, ...) or None |
Is_Content_Word |
True for nouns, verbs, adjectives, adverbs |
Reduced_POS |
Simplified POS: NOUN, VERB, ADJ, or FUNC |
Head_word_idx |
Index of the dependency head word |
n_Lefts |
Number of left dependents |
n_Rights |
Number of right dependents |
AbsDistance2Head |
Absolute distance to head word |
Distance2Head |
Signed distance to head word |
Head_Direction |
Direction to head: LEFT, RIGHT, or SELF |
Tokenization Modes
The mode parameter controls how spaCy's tokenization aligns with whitespace-delimited words:
re-tokenize(default): Merges spaCy sub-tokens (e.g., "don't" → "don" + "'t") back into single words matching whitespace splits. Best for most use cases.keep-first: Keeps only the first sub-token's features for compressed words (e.g., "don't" uses features of "don").keep-all: Returns all sub-token features as lists for compressed words.
Frequency
Frequency is computed via wordfreq and the SUBTLEX-US corpus:
- Reported as negative log2 frequency.
- Punctuation is stripped before lookup.
- Compound words use half harmonic mean of parts.
Package Structure
psycholing_metrics/
├── __init__.py           # Public API exports
├── metrics.py            # get_metrics, get_surprisal, get_frequency, get_word_length
├── text_processing.py    # Text cleaning, parsing features, token aggregation
├── model_loader.py       # HuggingFace model/tokenizer initialization
├── eye_tracking.py       # Eye-tracking data integration
├── tabular.py            # Tabular text processing
├── surprisal/            # Surprisal extraction strategies
│   ├── types.py          # SurprisalExtractorType enum
│   ├── base.py           # BaseSurprisalExtractor
│   ├── factory.py        # create_surprisal_extractor()
│   ├── concatenated.py   # ConcatenatedSurprisalExtractor (text-level)
│   ├── pimentel.py       # PimentelSurprisalExtractor (corrected)
│   ├── soft_concatenated.py  # Embedding-level extractors
│   └── inverse_effect.py # InverseEffectExtractor
└── pimentel_word_prob/   # Pimentel & Meister (2024) implementation
Dependencies
pandas>=2.1.0numpy>=1.20.3torch>=2.0.0transformers>=4.40.1acceleratewordfreq>=3.0.3spacy>=3.0.0tqdmsentence-splitter
1 maintainer

Metadata
1 maintainer
Release files for psycholing-metrics 2.2.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| psycholing_metrics-2.2.4.tar.gz | 393.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| psycholing_metrics-2.2.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 791.9 kB
Release files / psycholing_metrics-2.2.4.tar.gz
| Download URL | psycholing_metrics-2.2.4.tar.gz |
|---|---|
| Size | 393.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b03faf67c0d65d3f22eef6264f87eca5cd6f1af2305bfc41f805cd90e5790707
|
|
BLAKE2b-256 checksum How to use checksums |
723884b408a30c81b6d959e4232f134e7d6251feac555caaba9596f1f3f67400
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.5
|
Release files / psycholing_metrics-2.2.4-py3-none-any.whl
| Download URL | psycholing_metrics-2.2.4-py3-none-any.whl |
|---|---|
| Size | 398.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ea1f5bf264a0a3274ce3928036de5687ae6bb2fe6a5f8da5ef0d47efb0b36ca2
|
|
BLAKE2b-256 checksum How to use checksums |
a5dd64a1da34627556526364ab82e0897b390c4aaa074f1cfd6d1a7bb5896542
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.12.5
|














