
mddspls is the python light package of the data-driven sparse PLS algorithm
In the high dimensional settings (large number of variables), one objective is to select the relevant variables and thus to reduce the dimension. That subspace selection is often managed with supervised tools. However, some data can be missing, compromising the validity of the sub-space selection. We propose a PLS, Partial Least Square, based method, called dd-sPLS for data-driven-sparse PLS, allowing jointly variable selection and subspace estimation while training and testing missing data imputation through a new algorithm called Koh-Lanta.
It contains one main class mddspls and one associated important method denote predict permitting to predict from a new dataset. The function called perf_mddsPLS permits to compute cross-validation.
Data simulation
One might be interested to simulate data and test the package through regression and classification. Here a spiked model is used:
#!/usr/bin/env python

import py_ddspls
import numpy as np
import sklearn.metrics as sklm

n = 100
R_model = 10
R_X_Y = 2
T = 10
L = np.array(np.random.normal(0,1,n*R_model)).reshape((n,R_model))

p_t = 20
q = 5

Xs = {}

for t in range(T):
        Omega_1_2 = np.diag(np.random.uniform(0,1,R_model))
        u,s,vh = np.linalg.svd(np.array(np.random.normal(0,1,p_t*p_t)).reshape((p_t,p_t)))
        U_mod_T = vh[0:R_model,:]
        Xs[t] = L@Omega_1_2@U_mod_T

Omega_y_1_2 = np.diag(np.concatenate((np.ones(R_X_Y),np.zeros(R_model-R_X_Y))))
u,s,vh = np.linalg.svd(np.array(np.random.normal(0,1,R_model*R_model)).reshape((R_model,R_model)))
U_mod_T = vh[:,0:q]
Y = L@Omega_y_1_2@U_mod_T

k_groups = 2
Y_transfor = Y[:,0]
lolo = np.linspace(np.min(Y_transfor),np.max(Y_transfor),k_groups+1)
Y_bin = np.zeros(n)
for ii in range(n):
        for k_i in range(k_groups):
                if (Y_transfor[ii]>=lolo[k_i])&(Y_transfor[ii]<lolo[k_i+1]):
                        Y_bin[ii] = k_i
                if Y_transfor[ii]==lolo[k_groups]:
                        Y_bin[ii] = k_groups-1

pos_0 = np.where(Y_bin==0)[0]
pos_1 = np.where(Y_bin==1)[0]
Y_classif = np.repeat("Class 2",n)
Y_classif[pos_1] = "Class 1"

# Missing values are introduced in blocks 1, 2 and 3
Xs[0][0,:] = None
Xs[1][1:3,:] = None
Xs[2][2:10,:] = None
The dd-sPLS regularization parameter is fixed to 0.6:
lambd=0.6
A train/test dataset is defined for the sack of the example:
id_train = range(30,100)
id_test = range(30)
Xtrain = {}
Ytrain = Y[id_train,:]
Xtest = {}
Regression analysis
Let us produce 2 axes:
R=2
Start model building and check results with sklearn tools:
mod_0=py_ddspls.model.ddspls(Xtrain,Ytrain,lambd=lambd,R=R,mode="reg",verbose=True)
Y_est_reg = mod_0.predict(Xtest)
print(sklm.mean_squared_error(Y[id_test,:],Y_est_reg))
- Leave-one-out cross validation can be performed with built tools, the parameter
NCORES permits to fix the number of cores to be used in the process
perf_model_reg = py_ddspls.model.perf_ddspls(Xs,Y,R=R,kfolds="loo",n_lambd=10,NCORES=4,mode="reg")
print(perf_model_reg)

fig = plt.figure()
ax = fig.add_subplot(1, 1, 1)
cols = ['r','g','b','y','black','brown']
for jj in range(q):
        ax.plot(perf_model_reg[:,1],perf_model_reg[:,jj+2],cols[jj])

ax.plot(perf_model_reg[:,1],
        np.sqrt((perf_model_reg[:,2:(2+q)]**2).mean(axis=1)),"brown",linewidth=2,ls="--")
plt.legend(np.concatenate((1+np.arange(q),np.array("RMSE of RMSE errors").reshape((1,)))),loc='upper')
plt.title('Leave-One-Out Cross-validation error against $\lambda$')
plt.xlabel('$\lambda$')
plt.ylabel('RMSE')
plt.show()
Which returns this kind of graphics
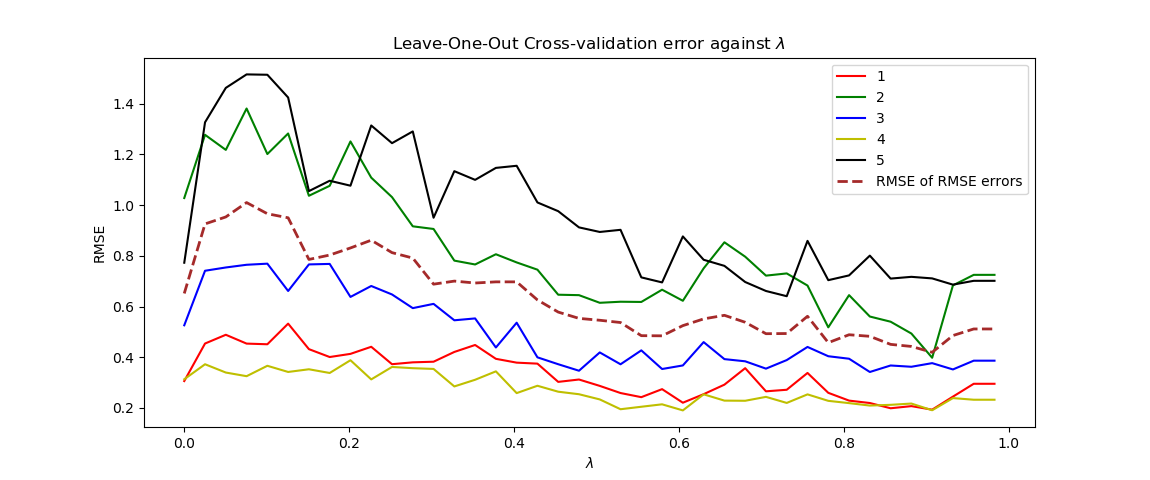
For 0.9 one can find a minimum of the RMSE of the RMSE of each variable. This oservation can be mitigated assuming that only Y variables 1 and 4 are well described by the X dataset. In that context, a discussion with experts, might help to decide the value to give to the parameter.
Classification analysis
Let us produce 1 axis since only one group must be discriminated:
R=1
Start model building and tcheck results with sklearn tools:
mod_0_classif=py_ddspls.model.ddspls(Xs,Y_bin,lambd=lambd,R=R,mode="clas",verbose=True)
Y_est = mod_0_classif.predict(Xtest)
print(sklm.classification_report(Y_est, Y_classif[id_test]=='Class 1'))
- Cross validation can be performed with built tools, the parameter NCORES
permits to use parallellization:
perf_model_class = py_ddspls.model.perf_ddspls(Xs,Y_classif,R=R,kfolds="loo",n_lambd=40,NCORES=7,mode="classif")
print(perf_model_class)

fig = plt.figure()
ax = fig.add_subplot(1, 1, 1)
ax.plot(perf_model_class[:,1], perf_model_class[:,2])
plt.title('Leave-One-Out Cross-validation error against $\lambda$')
plt.xlabel('$\lambda$')
plt.ylabel('Classification Error')
plt.show()
Which returns this kind of graphics
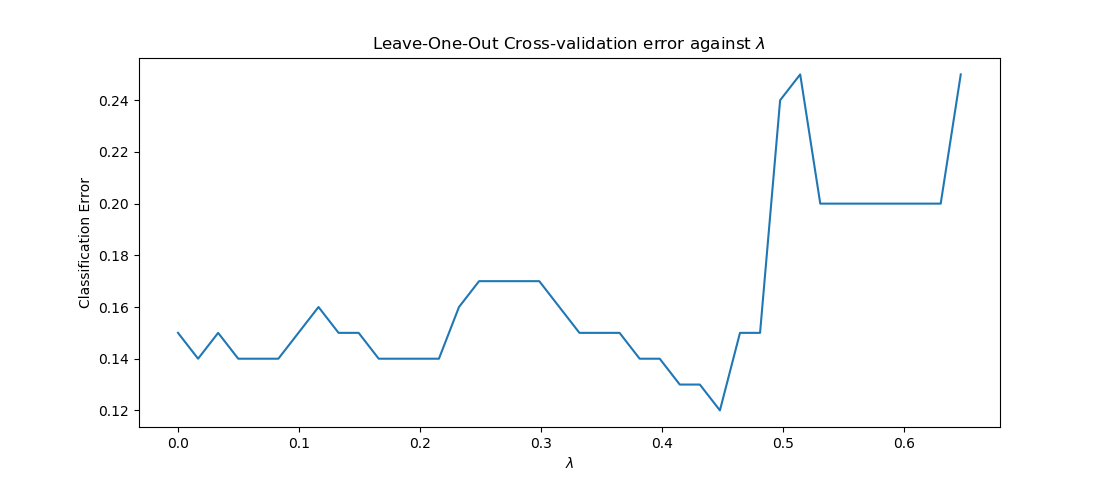
- One that figure one can see that a parameter approximately equal to 0.45 can be
chosen.
Enjoy :)
1 maintainer

Release files for py-ddspls 1.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| py_ddspls-1.1.0-py3.7.egg | Legacy Egg format | - | - | Details |
Release files / py_ddspls-1.1.0-py3.7.egg
| Download URL | py_ddspls-1.1.0-py3.7.egg |
|---|---|
| Size | 23.1 kB |
| Tags | Egg |
|
SHA-256 checksum How to use checksums |
ded27e7cdb22dcabb33f03a722d4d28ec9aaa34888250e9bef070d7ecca3d1fe
|
|
BLAKE2b-256 checksum How to use checksums |
a185948b136d1c002a7cd1f5e232d3788a66542f9bb1b5a07c23cace641decc5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/3.1.1 pkginfo/1.4.2 requests/2.21.0 setuptools/40.6.3 requests-toolbelt/0.9.1 tqdm/4.28.1 CPython/3.7.1
|














