
Pypeln
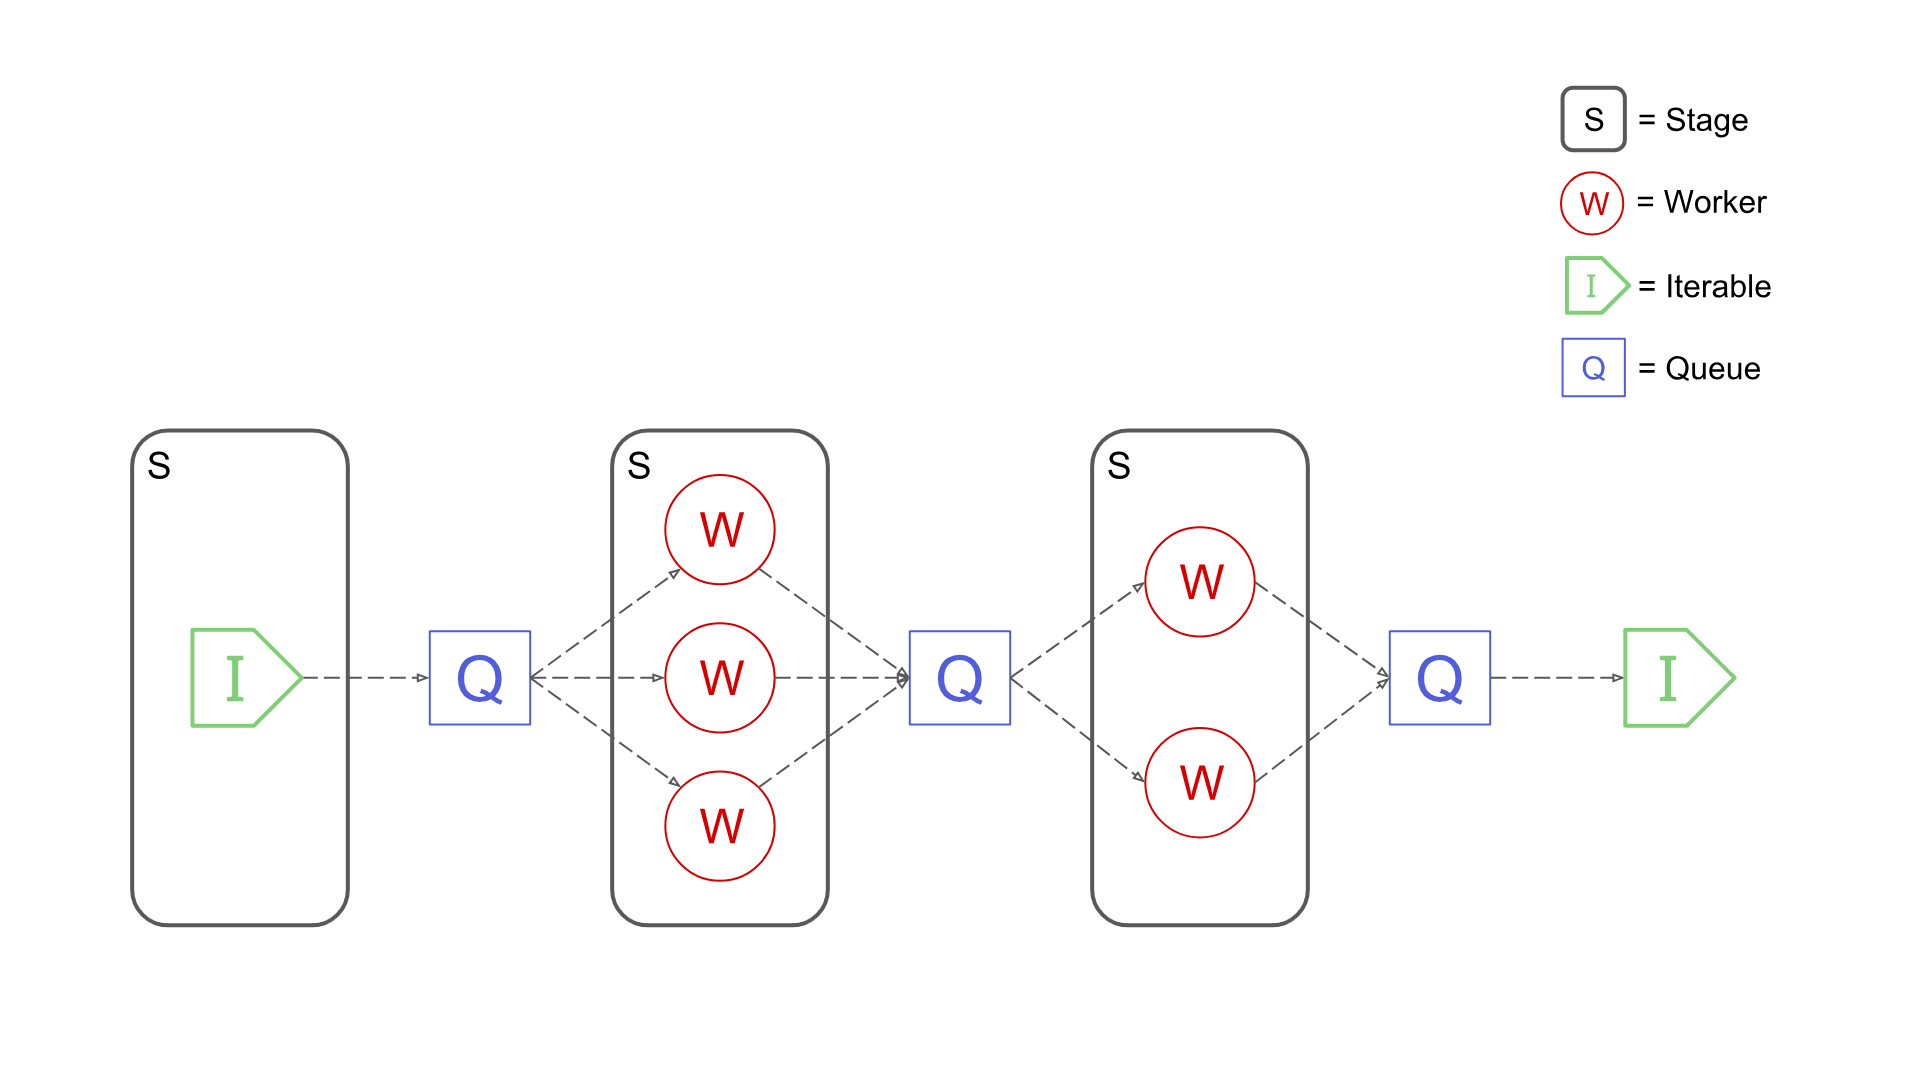
Pypeln (pronounced as "pypeline") is a simple yet powerful Python library for creating concurrent data pipelines.
Main Features
- Simple: Pypeln was designed to solve medium data tasks that require parallelism and concurrency where using frameworks like Spark or Dask feels exaggerated or unnatural.
- Easy-to-use: Pypeln exposes a familiar functional API compatible with regular Python code.
- Flexible: Pypeln enables you to build pipelines using Processes, Threads and asyncio.Tasks via the exact same API.
- Fine-grained Control: Pypeln allows you to have control over the memory and cpu resources used at each stage of your pipelines.
For more information take a look at the Documentation.
Installation
Install Pypeln using pip:
pip install pypeln
Basic Usage
With Pypeln you can easily create multi-stage data pipelines using 3 type of workers:
Processes
You can create a pipeline based on multiprocessing.Process workers by using the process module:
import pypeln as pl
import time
from random import random

def slow_add1(x):
    time.sleep(random()) # <= some slow computation
    return x + 1

def slow_gt3(x):
    time.sleep(random()) # <= some slow computation
    return x > 3

data = range(10) # [0, 1, 2, ..., 9]

stage = pl.process.map(slow_add1, data, workers=3, maxsize=4)
stage = pl.process.filter(slow_gt3, stage, workers=2)

data = list(stage) # e.g. [5, 6, 9, 4, 8, 10, 7]
At each stage the you can specify the numbers of workers. The maxsize parameter limits the maximum amount of elements that the stage can hold simultaneously.
Threads
You can create a pipeline based on threading.Thread workers by using the thread module:
import pypeln as pl
import time
from random import random

def slow_add1(x):
    time.sleep(random()) # <= some slow computation
    return x + 1

def slow_gt3(x):
    time.sleep(random()) # <= some slow computation
    return x > 3

data = range(10) # [0, 1, 2, ..., 9]

stage = pl.thread.map(slow_add1, data, workers=3, maxsize=4)
stage = pl.thread.filter(slow_gt3, stage, workers=2)

data = list(stage) # e.g. [5, 6, 9, 4, 8, 10, 7]
Here we have the exact same situation as in the previous case except that the worker are Threads.
Tasks
You can create a pipeline based on asyncio.Task workers by using the task module:
import pypeln as pl
import asyncio
from random import random

async def slow_add1(x):
    await asyncio.sleep(random()) # <= some slow computation
    return x + 1

async def slow_gt3(x):
    await asyncio.sleep(random()) # <= some slow computation
    return x > 3

data = range(10) # [0, 1, 2, ..., 9]

stage = pl.task.map(slow_add1, data, workers=3, maxsize=4)
stage = pl.task.filter(slow_gt3, stage, workers=2)

data = list(stage) # e.g. [5, 6, 9, 4, 8, 10, 7]
Conceptually similar but everything is running in a single thread and Task workers are created dynamically.
Mixed Pipelines
You can create pipelines using different worker types such that each type is the best for its given task so you can get the maximum performance out of your code:
data = get_iterable()
data = pl.task.map(f1, data, workers=100)
data = pl.thread.flat_map(f2, data, workers=10)
data = filter(f3, data)
data = pl.process.map(f4, data, workers=5, maxsize=200)
Notice that here we even used a regular python filter, since stages are iterables Pypeln integrates smoothly with any python code, just be aware of how each stage behaves.
Pipe Operator
In the spirit of being a true pipeline library, Pypeln also lets you create your pipelines using the pipe | operator:
data = (
    range(10)
    | pl.process.map(slow_add1, workers=3, maxsize=4)
    | pl.process.filter(slow_gt3, workers=2)
    | list
)
Related Stuff
- Making an Unlimited Number of Requests with Python aiohttp + pypeln
- Process Pools
- Making 100 million requests with Python aiohttp
- Python multiprocessing Queue memory management
- joblib
- mpipe
Contributors
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for pypeln 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| pypeln-0.3.0.tar.gz | 27.1 kB | Without provenance | Details for pypeln-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| pypeln-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for pypeln-0.3.0-py3-none-any.whl |
Total release size: 60.7 kB
Release files / pypeln-0.3.0.tar.gz
| Download URL | pypeln-0.3.0.tar.gz |
|---|---|
| Size | 27.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c8eb2a8301422491bdf8fcc8fe550bcb9091cd23f09c5a94475e8cefb6d1abed
|
|
BLAKE2b-256 checksum How to use checksums |
a6f209529816a1adac6889148f96621d69c49f0e9f8cd3f38bf7dac5c32b9bfc
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.0.5 CPython/3.7.6 Linux/5.3.0-7629-generic
|
Release files / pypeln-0.3.0-py3-none-any.whl
| Download URL | pypeln-0.3.0-py3-none-any.whl |
|---|---|
| Size | 33.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
420550c51b9957546b845664e6e6cf7ab3fef2996d92521615751c8634ea3d44
|
|
BLAKE2b-256 checksum How to use checksums |
5bfb6e4b44b3d4e34843c647d539d8fb8e31ebeeee00d4db6f37618ccb5ccf1b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/1.0.5 CPython/3.7.6 Linux/5.3.0-7629-generic
|
Security for pypeln 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














