
QuisperX
QuisperX is a version of Max Bain et al's WhisperX, which adds:
- easy access to two extra models fine-tuned on the QuakeBox corpus of New Zealand English speech:
quisper-mediumandquisper-large-v2
- tweaks to WebVTT output to use certain CHAT
transcription conventions (via
--conventions CLAN):- marking of inter-word pauses:
(.)- short pause (0.2s < duration ≤ 0.7s) -(..)- longer pause (0.7s < duration ≤ 1.4s) -(...)- very long pause (1.4s < duration), and
- transcribing interrupted words with a preceding
&+instead of a trailing ellipsis
- marking of inter-word pauses:
- WebVTT output labels speakers using
voice tags,
i.e instead of using the convention than includes the speaker ID in the text:
[SPEAKER_00]: So please remind us of your earthquake story.
... a<v>...</v>tag is used instead:
<v SPEAKER_00>So please remind us of your earthquake story.</v>
QuakeBox Corpus
The quisper-medium and quisper-large-v2 models are versions of Whisper's
medium and large-v2 models fine-tuned on a 95-hour subset of the
QuakeBox corpus of New Zealand English:
@article{CLARK201613,
  title = {{"Kia ora. This is my earthquake story". Multiple applications of a sociolinguistic corpus}},
  journal = {Ampersand},
  volume = {3},
  pages = {13-20},
  year = {2016},
  issn = {2215-0390},
  doi = {https://doi.org/10.1016/j.amper.2016.01.001},
  url = {https://www.sciencedirect.com/science/article/pii/S2215039016300066},
  author = {Lynn Clark and Helen MacGougan and Jennifer Hay and Liam Walsh},
  keywords = {Applied sociolinguistics, Corpus, Monologues}
}
Both models perform better (for NZE sociolinguistic purposes) than the standard Whisper models:
- Many more filler words are included in transcripts.
- Numeric expressions are generally spelled out as words instead of using digits.
- Initialisms like "EQC" are generally split into separate words ("E Q C").
- New Zealand specific place names are transcribed with fewer spelling errors.
- New Zealand rather than US spelling conventions are generally followed.
- Other error rates are lower.
See DOI 10.26021/canterburynz.32736570 for more information.
Installation of Quisper
You can install QuisperX directly from GitHub:
uvx git+https://github.com/nzilbb/quisperX.git
The original WhisperX README continues below...
WhisperX
Recall.ai - Meeting Transcription API
If you’re looking for a transcription API for meetings, consider checking out Recall.ai's Meeting Transcription API, an API that works with Zoom, Google Meet, Microsoft Teams, and more. Recall.ai diarizes by pulling the speaker data and separate audio streams from the meeting platforms, which means 100% accurate speaker diarization with actual speaker names.


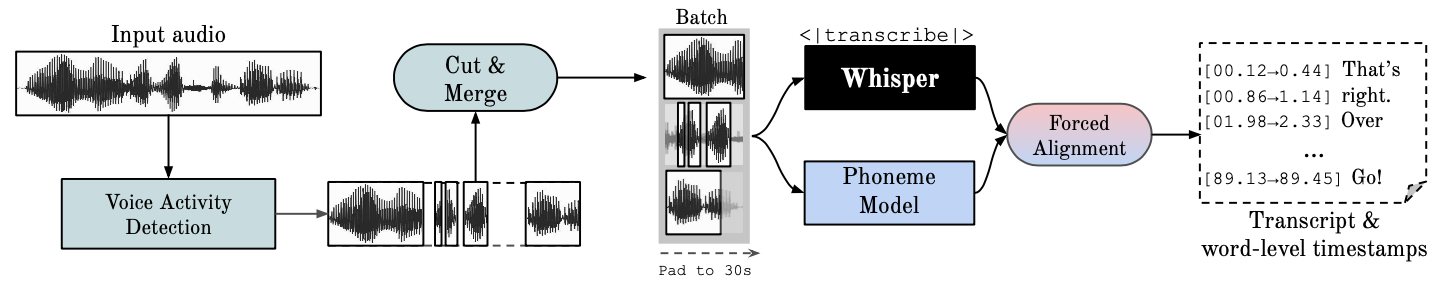
This repository provides fast automatic speech recognition (70x realtime with large-v2) with word-level timestamps and speaker diarization.
- ⚡️ Batched inference for 70x realtime transcription using whisper large-v2
- 🪶 faster-whisper backend, requires <8GB gpu memory for large-v2 with beam_size=5
- 🎯 Accurate word-level timestamps using wav2vec2 alignment
- 👯♂️ Multispeaker ASR using speaker diarization from pyannote-audio (speaker ID labels)
- 🗣️ VAD preprocessing, reduces hallucination & batching with no WER degradation
Whisper is an ASR model developed by OpenAI, trained on a large dataset of diverse audio. Whilst it does produces highly accurate transcriptions, the corresponding timestamps are at the utterance-level, not per word, and can be inaccurate by several seconds. OpenAI's whisper does not natively support batching.
Phoneme-Based ASR A suite of models finetuned to recognise the smallest unit of speech distinguishing one word from another, e.g. the element p in "tap". A popular example model is wav2vec2.0.
Forced Alignment refers to the process by which orthographic transcriptions are aligned to audio recordings to automatically generate phone level segmentation.
Voice Activity Detection (VAD) is the detection of the presence or absence of human speech.
Speaker Diarization is the process of partitioning an audio stream containing human speech into homogeneous segments according to the identity of each speaker.
New🚨
- 1st place at Ego4d transcription challenge 🏆
- WhisperX accepted at INTERSPEECH 2023
- v3 released, 70x speed-up open-sourced. Using batched whisper with faster-whisper backend!
- Context-Aware Batching Released 2026: We successfully enable condition_on_previous_context within our batched transcription framework, improving punctuation and proper noun adherence. See our ArXiv preprint.
Setup ⚙️
0. CUDA Installation
To use WhisperX with GPU acceleration, install the CUDA toolkit 12.8 before WhisperX. Skip this step if using only the CPU.
- For Linux users, install the CUDA toolkit 12.8 following this guide: CUDA Installation Guide for Linux.
- For Windows users, download and install the CUDA toolkit 12.8: CUDA Downloads.
1. Simple Installation (Recommended)
The easiest way to install WhisperX is through PyPi:
pip install whisperx
Or if using uvx:
uvx whisperx
2. Advanced Installation Options
These installation methods are for developers or users with specific needs. If you're not sure, stick with the simple installation above.
Option A: Install from GitHub
To install directly from the GitHub repository:
uvx git+https://github.com/m-bain/whisperX.git
Option B: Developer Installation
If you want to modify the code or contribute to the project:
git clone https://github.com/m-bain/whisperX.git
cd whisperX
uv sync --all-extras --dev
Note: The development version may contain experimental features and bugs. Use the stable PyPI release for production environments.
You may also need to install ffmpeg, rust etc. Follow openAI instructions here https://github.com/openai/whisper#setup.
Speaker Diarization
To enable Speaker Diarization, include your Hugging Face access token (read) that you can generate from Here after the --hf_token argument and accept the user agreement for the speaker-diarization-community-1 model.
Usage 💬 (command line)
English
Run whisper on example segment (using default params, whisper small) add --highlight_words True to visualise word timings in the .srt file.
whisperx path/to/audio.wav
Result using WhisperX with forced alignment to wav2vec2.0 large:
Compare this to original whisper out the box, where many transcriptions are out of sync:
For increased timestamp accuracy, at the cost of higher gpu mem, use bigger models (bigger alignment model not found to be that helpful, see paper) e.g.
whisperx path/to/audio.wav --model large-v2 --align_model WAV2VEC2_ASR_LARGE_LV60K_960H --batch_size 4
To label the transcript with speaker ID's (set number of speakers if known e.g. --min_speakers 2 --max_speakers 2):
whisperx path/to/audio.wav --model large-v2 --diarize --highlight_words True
To maintain continuous context (ideal for technical language / punctuation), set interleaved_context=True:
whisperx path/to/audio.wav --model large-v2 --interleaved_context
To run on CPU instead of GPU (and for running on Mac OS X):
whisperx path/to/audio.wav --compute_type int8 --device cpu
For conditioning on previous context (This allows context to be passed from the previous segment, leading to better results on long audio):
whisperx path/to/audio.wav --model large-v2 --interleaved_context
Other languages
The phoneme ASR alignment model is language-specific, for tested languages these models are automatically picked from torchaudio pipelines or huggingface.
Just pass in the --language code, and use the whisper --model large.
Currently default models provided for {en, fr, de, es, it} via torchaudio pipelines and many other languages via Hugging Face. Please find the list of currently supported languages under DEFAULT_ALIGN_MODELS_HF on alignment.py. If the detected language is not in this list, you need to find a phoneme-based ASR model from huggingface model hub and test it on your data.
E.g. German
whisperx --model large-v2 --language de path/to/audio.wav
See more examples in other languages here.
Python usage 🐍
import whisperx
import gc
from whisperx.diarize import DiarizationPipeline

device = "cuda"
audio_file = "audio.mp3"
batch_size = 16 # reduce if low on GPU mem
compute_type = "float16" # change to "int8" if low on GPU mem (may reduce accuracy)

# 1. Transcribe with original whisper (batched)
model = whisperx.load_model("large-v2", device, compute_type=compute_type)

# save model to local path (optional)
# model_dir = "/path/"
# model = whisperx.load_model("large-v2", device, compute_type=compute_type, download_root=model_dir)

audio = whisperx.load_audio(audio_file)

result = model.transcribe(audio, batch_size=batch_size, interleaved_context=True)
print(result["segments"]) # before alignment

# delete model if low on GPU resources
# import gc; import torch; gc.collect(); torch.cuda.empty_cache(); del model

# 2. Align whisper output
model_a, metadata = whisperx.load_align_model(language_code=result["language"], device=device)
result = whisperx.align(result["segments"], model_a, metadata, audio, device, return_char_alignments=False)

print(result["segments"]) # after alignment

# delete model if low on GPU resources
# import gc; import torch; gc.collect(); torch.cuda.empty_cache(); del model_a

# 3. Assign speaker labels
diarize_model = DiarizationPipeline(token=YOUR_HF_TOKEN, device=device)

# add min/max number of speakers if known
diarize_segments = diarize_model(audio)
# diarize_model(audio, min_speakers=min_speakers, max_speakers=max_speakers)

result = whisperx.assign_word_speakers(diarize_segments, result)
print(diarize_segments)
print(result["segments"]) # segments are now assigned speaker IDs
Demos 🚀



If you don't have access to your own GPUs, use the links above to try out WhisperX.
Technical Details 👷♂️
For specific details on the batching and alignment, the effect of VAD, as well as the chosen alignment model, see the preprint paper.
To reduce GPU memory requirements, try any of the following (2. & 3. can affect quality):
- reduce batch size, e.g.
--batch_size 4 - use a smaller ASR model
--model base - Use lighter compute type
--compute_type int8
Transcription differences from openai's whisper:
- Transcription without timestamps. To enable single pass batching, whisper inference is performed
--without_timestamps True, this ensures 1 forward pass per sample in the batch. However, this can cause discrepancies the default whisper output. - VAD-based segment transcription, unlike the buffered transcription of openai's. In the WhisperX paper we show this reduces WER, and enables accurate batched inference
--condition_on_prev_textis set toFalseby default (reduces hallucination)
Limitations ⚠️
- Transcript words which do not contain characters in the alignment models dictionary e.g. "2014." or "£13.60" cannot be aligned and therefore are not given a timing.
- Overlapping speech is not handled particularly well by whisper nor whisperx
- Diarization is far from perfect
- Language specific wav2vec2 model is needed
Contribute 🧑🏫
If you are multilingual, a major way you can contribute to this project is to find phoneme models on huggingface (or train your own) and test them on speech for the target language. If the results look good send a pull request and some examples showing its success.
Bug finding and pull requests are also highly appreciated to keep this project going, since it's already diverging from the original research scope.
TODO 🗓
-
Multilingual init
-
Automatic align model selection based on language detection
-
Python usage
-
Incorporating speaker diarization
-
Model flush, for low gpu mem resources
-
Faster-whisper backend
-
Add max-line etc. see (openai's whisper utils.py)
-
Sentence-level segments (nltk toolbox)
-
Improve alignment logic
-
update examples with diarization and word highlighting
-
Subtitle .ass output <- bring this back (removed in v3)
-
Add benchmarking code (TEDLIUM for spd/WER & word segmentation)
-
Allow silero-vad as alternative VAD option
-
Improve diarization (word level). Harder than first thought...
Contact/Support 📇
Contact maxhbain@gmail.com for queries.
Acknowledgements 🙏
This work, and my PhD, is supported by the VGG (Visual Geometry Group) and the University of Oxford.
Of course, this is builds on openAI's whisper. Borrows important alignment code from PyTorch tutorial on forced alignment And uses the wonderful pyannote VAD / Diarization https://github.com/pyannote/pyannote-audio
Valuable VAD & Diarization Models from:
- pyannote-audio — Speaker diarization powered by the speaker-diarization-community-1 model, licensed under CC-BY-4.0 by pyannoteAI
- silero-vad
Great backend from faster-whisper and CTranslate2
Those who have supported this work financially 🙏
Finally, thanks to the OS contributors of this project, keeping it going and identifying bugs.
Citation
If you use this in your research, please cite the paper:@article{bain2022whisperx,
title={WhisperX: Time-Accurate Speech Transcription of Long-Form Audio},
author={Bain, Max and Huh, Jaesung and Han, Tengda and Zisserman, Andrew},
journal={INTERSPEECH 2023},
year={2023}
}
Please also cite the paper below if you enabled interleaved context:
@article{bain2026context,
  title={Context-Aware Interleaved Batching for WhisperX},
  author={Bain, Carlos and Bain, Max},
  journal={arXiv preprint arXiv:2608.31170v1},
  year={2026}
}
1 maintainer

Metadata
1 maintainer
Release files for quisperx 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| quisperx-0.1.1.tar.gz | 16.5 MB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| quisperx-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 33.0 MB
Release files / quisperx-0.1.1.tar.gz
| Download URL | quisperx-0.1.1.tar.gz |
|---|---|
| Size | 16.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0ca540a5d9679f325f49884e247a23553de6ba8a0941dd721b98148650e60028
|
|
BLAKE2b-256 checksum How to use checksums |
c7437a1ca82cc1a03899473d55cf90d893d179f09e6fa041d5ccf576a9a69610
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.14 {"installer":{"name":"uv","version":"0.11.14","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / quisperx-0.1.1-py3-none-any.whl
| Download URL | quisperx-0.1.1-py3-none-any.whl |
|---|---|
| Size | 16.5 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a542d7c00f53d1e28bfeccef8e3768aca5339fd66bb6565076040df2128efdc4
|
|
BLAKE2b-256 checksum How to use checksums |
94071a1466a440309dd0ce4f0489212c95c9421f118adcbf17ec30633f09e42e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.11.14 {"installer":{"name":"uv","version":"0.11.14","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"Ubuntu","version":"24.04","id":"noble","libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for quisperx 0.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














