
Radogast — Context Drift Monitor
Universal static analyzer for AI agent sessions.
Why Radogast
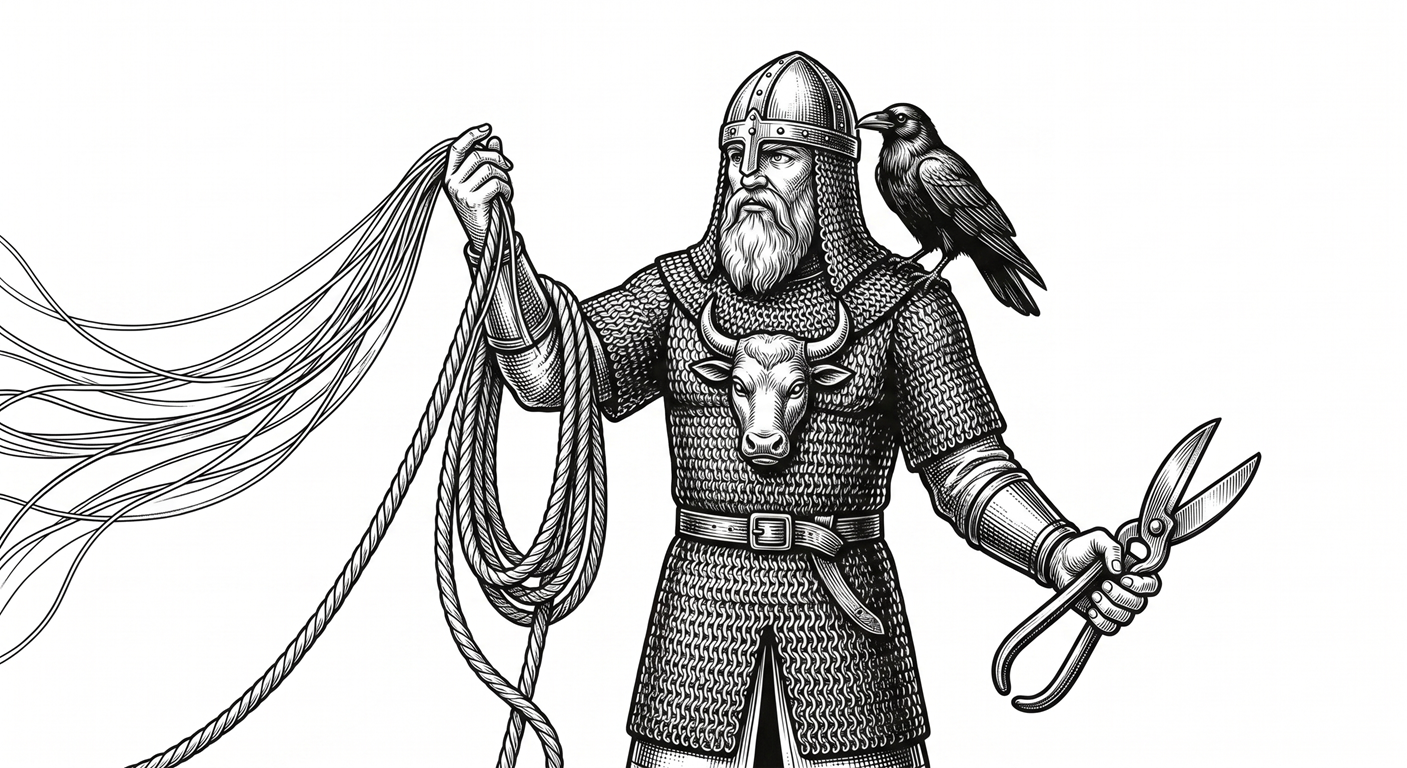
In Slavic mythology, Radogast is the solar deity of the Polabian Slavs — god of hospitality and protection, guardian of travelers and merchants on their journeys. He is depicted in helmet and chainmail, a prophetic bird upon his head, the head of an aurochs on his chest. The prophetic bird watches without sleep; the sun he carries lights the path forward.
We named this tool after him because that is exactly what it does: it illuminates the path of an AI agent through a task. A conversation has a direction — a goal stated at the start. Radogast measures how far the current context has drifted from that origin, whether the key ideas are present and defined, and whether the work is still moving toward the answer. The sun does not bend. If the path has curved away, Radogast will say so.
Universal static analyzer for AI agent sessions. Monitors context drift from a target, measures term coverage, detects process stage via marker words, and warns when a conversation has left the task space.
Works with: 1bcoder, Claude, OpenCode, Codex, aider, Continue.dev, Gemini, pi, nanocoder — any tool that can export message history as JSON.
Install
pip install radogast
# with embedding support (recommended):
pip install "radogast[embed]"
For development:
pip install -e .
pip install -e ".[embed]"
Dependencies
radogast works standalone — the only required dependencies are click, numpy, pyyaml,
and rouge-score. Embedding-based drift detection requires the [embed] extra
(sentence-transformers, ~500 MB); without it, radogast falls back to marker-word analysis only.
If drift detection is unavailable, the output shows the install command directly.
yasna is strongly recommended. Without it, radogast can still analyze sessions — but you have to know the exact path to each session file yourself. Every agent stores sessions in a different place and format. yasna solves this: it indexes sessions from all agents into one searchable store and radogast reads from there automatically.
pip install yasna
Without yasna, radogast is a scalpel. With yasna, it becomes part of a workflow.
Quick start
With yasna (recommended)
# 1. Index sessions from all agents (Claude, 1bcoder, aider, Gemini, opencode, ...)
yasna index

# 2. Define the task you are working on
radogast init

# 3. Watch — yasna index runs automatically before each cycle
radogast watch
radogast will pick up sessions from Claude Code, 1bcoder, aider, Gemini CLI, opencode, Continue.dev, and any other agent yasna supports — no paths needed.
Without yasna
# 1. Define the task
radogast init

# 2. Point radogast at the session file directly
radogast analyze --input ~/.claude/projects/my-project/session.jsonl

# 3. Or watch a specific agent's directory
radogast watch --dir ~/.continue/history/
radogast watch --dir ~/.aider/
radogast watch --dir ~/.1bcoder/autosave/
Target YAML format
goal: "develop REST API for visitor tracking at a café"

key_terms: [REST, API, tracking, session, timestamp, visitor]

milestones:
  - name: domain_understood
    markers: [visitor, establishment, entry, exit, timestamp]
    evidence: "definition of visitor as an entry+exit event pair"
  - name: api_designed
    markers: [endpoint, POST, GET, response]
    evidence: "at least one endpoint with schema"

verification: [visitor, REST, endpoint]

out_of_scope: [authorization, billing, UI]
Config (.radogast.yaml)
windows: [1, 3, 5]           # message window sizes
drift_threshold_deg: 40       # alert above this angle
bias_threshold: 3.0           # term imbalance alert
embedding_model: "BAAI/bge-small-en-v1.5"   # fast, 22MB
hybrid: true                  # marker words + embeddings both
trend_segments: 7             # sparkline bars per term
Plan mode (deepagent_md / deepagent_tree trees)
Everything above analyzes one conversation. Plan mode instead analyzes a whole
generated document tree (index.md + item_*.md, as written by 1bcoder's
/flow deepagent_md, deepagent_tree, or deepagent_tree_md) for cross-branch
redundancy, out-of-scope drift, and key-term coverage across every node at once.
# 1. Seed a target from index.md (wizard: key terms, out-of-scope, mandatory terms)
radogast plan init plan1
# <plan_dir> can be a bare plan name (resolved against ./.1bcoder/planMD/<name>
# if cwd has a .1bcoder/ directory), a relative path, or an absolute path.

# 2. Analyze
radogast plan analyze plan1 --threshold 0.9
Per-node columns in the text report:
| Column | Meaning |
|---|---|
cov=NN% |
key-term coverage for THIS node alone (terms formally defined, not just mentioned) |
cum=NN% |
running coverage: union of terms defined by this node or any earlier one, in tree order -- a term counts once; should approach 100% by the last node, a cum that never climbs is the real gap signal |
oos=N |
out-of-scope term hits found in this node's own content |
cl=N |
which DUPLICATE CLUSTER this node belongs to, or - if none |
~id (0.NN) |
nearest OTHER node by embedding similarity, and its score |
--format:
| Format | Contains |
|---|---|
text (default) |
colored console report -- summary line, legend, KEY TERM FIRST APPEARANCE table, DUPLICATE CLUSTERS breakdown, per-node table |
json |
the full report structure (summary counts, clusters, term_appearances, every node's fields) -- for scripts |
csv |
only the main per-node table, header row first (id,title,coverage_ratio,cumulative_coverage,out_of_scope_hits,nearest_id,nearest_score,cluster_id) -- no clusters breakdown, no term-appearance table, no legend |
--threshold (cosine similarity, default 0.85) is not pre-calibrated -- it depends on
the embedding model and how narrow the plan's own domain is. Run once, read the printed
~id (score) nearest-neighbor column on nodes you already know are/aren't duplicates,
and pick a cutoff from that instead of trusting the default blindly.
MCP tools
| Tool | Description |
|---|---|
analyze_context(messages_json, target_yaml) |
Full report as JSON |
get_drift_score(messages_json, goal, key_terms) |
Quick angle check |
suggest_refocus(messages_json, target_yaml) |
Actionable suggestions |
Output example
[radogast] target: develop REST API for visitor tracking

DRIFT:     23.4°  on_track
STAGE:     api_designed  votes={'api_designed': 3}

TERM COVERAGE  (4/6 defined)  ROUGE-1=0.71
  ✓ REST                  ████████████  defined
  ✓ API                   ██████████░░  defined
  ~ visitor               ████░░░░░░░░  mentioned
  ✗ average time          ░░░░░░░░░░░░  absent
  ✓ timestamp             ██████░░░░░░  defined
  ✓ session               ████████░░░░  defined

BALANCE:  bias=2.1x toward 'REST'

GLOSSARY (3/6 terms):
  REST: architectural style for web services using HTTP...
  session: pair of entry and exit events for one visitor...
  timestamp: Unix epoch in milliseconds, recorded at device level

SUGGESTED:
  → missing from context: average time — add definitions or examples
  → mentioned but not defined: visitor — add explicit definitions
Part of the SIMARGL toolkit
radogast is one of ten tools that together form an intellectual development support system:
| Tool | Role |
|---|---|
| simargl | Task-to-code retrieval — given a task description, finds which files and modules are likely affected, using semantic similarity over git history |
| svitovyd | Project map — scans any codebase and produces a structural map of definitions and cross-file dependencies; queried from the CLI, a web UI with a layered map, or an MCP server |
| 1bcoder | AI coding assistant for small local models — surgical context management, agents, parallel inference, proc scripts |
| yasna | Session memory — indexes conversations from all AI agents so you can find what was discussed, when, and where |
| radogast | Context drift monitor — measures how far an AI agent's conversation has drifted from the original task |
| vyrii | Local AI web UI — chat, translate, web research, RAG and file management in the browser (Flask; Gradio optional); powered by Ollama or any OpenAI-compatible backend |
| syryn | Bluetooth identity beacon for headless devices — the device's IP is its Bluetooth name; hostname, mDNS and network interfaces on request |
| alkonost | Browser cockpit for 1bcoder's flows — the deepagent_* spec pipeline (plan tree → specs → task board) and the glossary (build, browse, search), tuned for small local models |
| gamayun | Statistical ontology without an LLM — builds triples of terms, identifiers, files and modules from task history or a folder of documents and code; every triple carries its significance test |
| mokosh | Dataset gathering — commits of a git repository and the tasks of its tracker (Jira, GitHub, GitLab, YouTrack) in one SQLite database that the other tools read |
- simargl finds the code related to a task by vector search over the task history (embeddings).
- svitovyd answers: how is the code structured and what depends on what?
- 1bcoder answers: how do I work with local models efficiently?
- yasna answers: where did I already discuss this?
- radogast answers: is the AI agent still on track toward the goal?
- vyrii answers: how do I access all of this through a browser?
- syryn answers: what is the address of this headless device?
- alkonost answers: how do I turn one task description into a reviewed, working plan — and see the project's glossary — without a big model or a big context window?
- gamayun finds the code related to a task through an ontology of significant links between words, files and modules (no LLM).
- mokosh prepares the initial dataset from version control and the issue tracker.
Together they cover the full development loop: understand the codebase, find relevant history, work with AI locally, remember what was decided, and verify the context stays on target.
About
(c) 2026 Stanislav Zholobetskyi, Oleh Andriichuk
Institute for Information Recording, National Academy of Sciences of Ukraine, Kyiv
PhD research: «Intelligent Technology for Software Development and Maintenance Support»
1 maintainer

Metadata
1 maintainer
Release files for radogast 0.1.10
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| radogast-0.1.10.tar.gz | 43.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| radogast-0.1.10-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 88.4 kB
Release files / radogast-0.1.10.tar.gz
| Download URL | radogast-0.1.10.tar.gz |
|---|---|
| Size | 43.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
aef99e1ee71a1fffbba8f254193f1005983b5885dfcf642de30d8d12268a90c6
|
|
BLAKE2b-256 checksum How to use checksums |
426ef7efc3735ea55bd7e0afc43263148acfeae6bec852dbc81d26fc589e2f15
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.9
|
Release files / radogast-0.1.10-py3-none-any.whl
| Download URL | radogast-0.1.10-py3-none-any.whl |
|---|---|
| Size | 44.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e01571b6ee57cdbd2b043b7c2f5fae394cb506c0495ab9fdc9aa4efd80af8c27
|
|
BLAKE2b-256 checksum How to use checksums |
61eca7a019a0417383dec1d7a218f2461be692f2955fd92a9c6ef138727c1d47
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.9
|














