
RAFT: Retrieval-Augmented Fine-Tuning
Note from @lumpenspace:
This technique is something ive been working last summer/fall, originally planning to get a paper out of it. Then it seemed obvious so i didn't, and instead used pieces of this repo for other projects and abandoned this repo.
I discovered not without horror that some of the tech is still cutting edge, so i might as well share it.
In this old version, the main simulee was Gary Marcus; the idea was to make a model that could pass as him in a conversation and demonstrate how stochastic parrots are still plenty capable to mimic the deterministic ones, but there's a couple interesting tidbits that i've moved to more decent repos but, given my pretty annoying habit of not sharing subpar code, you might as well start here.
Scroll to usage and functionality for cli options, what you can do (apart from what's described below) is automagically fetch, chunk, embed, story, and query a db starting from a substack url.
Not guaranteeing anything works, but it's a good starting point for a lot of things and includes a couple of new ideas.
OH GOSH
ok then, a friend asked so now it is more lenient with the version number and uses poetry for the dependencies. It's still a mess, but it's a more runnable mess.
(2.1: poetry is gone — it's uv + hatchling now, like the other repos in this constellation.)
2.5
Start a persona project with raft init my-persona, then cd my-persona
and raft interactive. Commands inside the project no longer need a dataset
name. Existing raft <action> <name> datasets still work.
At the beginning, select all the sources you have: tweets (X / Bluesky), Substack, blogs / RSS, web pages, PDFs, local files, or chat logs. You can select multiple sources, including several of the same kind. For each, choose conversations or grounding documents before importing. Tweets also support an automatic split: replies become conversations and other posts become grounding. Conversation sources must contain actual exchanges; an essay is not turned into invented dialogue. Extracting unstructured conversations uses the configured LLM.
Grounding is optional. With conversations alone, prep skips chunking and embedding and creates training examples without retrieved memories.
Projects store raft.json alongside fetch/, blobs/, metadata/,
conversations/, and corpus/. Model state and source choices live in
metadata/state.json.
2.3
raft interactive grew into a five-phase session, resumable per dataset —
what exists on disk (plus data/{name}_meta.json) tells it where you left
off, and it suggests the next phase:
- gather — documents and conversations, one source at a time, combined
into one dataset. New document sources beside substack / tweets / local
files: any RSS/Atom feed (a plain site URL works too — raft follows its
rel=alternatefeed link, and teaser-only entries get their linked page fetched in full), single URLs, and PDFs (pip install 'raft-ft[pdf]'). Re-adding a source only imports what is new (deduplicated by link). - prep — chunk + embed, then generate the finetune examples. Retrieval
now only surfaces the target's earlier writings: chunks carry a
comparable
date_num, and each exchange's memory query is filtered to documents dated before the interview; unknown-dated documents stay retrievable. A collection embedded before 2.3 has nodate_num, so raft warns and skips the filter — re-runningraft embed(embedding is now an upsert) backfills it and turns the filter on. - train — pick the venue (the OpenAI finetuning API, or a huggingface model on a GPU pod via opbdh) and the model. While the job runs, raft collects test questions, showing for each which documents and tweets retrieval will put in the persona's context; the finetuned model id (or adapter path) is recorded in the dataset meta.
- eval — generate the benchmark files (when a benchmark transcript exists) and run the stored test questions against the finetuned model, retrieval context shown alongside each answer.
- serve — also standalone as
raft serve <name>: chat with the persona, retrieval-augmented, every turn showing what landed in context (answers on stdout, chrome on stderr, so it pipes). OpenAI finetunes are served directly; for a LoRA adapter raft prints a serving recipe instead.
2.0
New major version. Substack is no longer the only way in:
-
raft interactive— guided end-to-end session. Asks who the target is, collects text sources (substack / tweets / local files) and conversation examples. Structured inputs (raft transcripts, chat-message JSON, grounding jsonl) are recognised and imported as-is; unstructured ones (raw chat logs, podcast transcripts, whatever) are converted into transcript datasets with an LLM (RAFT_LLM_MODEL, defaultgpt-4o). Then chunk/embed/ft:gen/ft:run, each step optional. -
raft tweets— tweet mode. First asks which network(s) to draw from — X / Twitter, Bluesky, or both, merged into one dataset — then calls ariadne's Python API to reconstruct reply branches and imports them: thread texts become grounding documents, reply branches become q/a transcripts. The target's own posts become the answers, whoever they were replying to becomes the questioner. For X you choose the source (archive export, CSV/JSON dump, or a public handle) and can add the Community Archive (community-archive.org — no key, and it completes reply threads whose parents were authored by other people) and/or a twitterapi.io key. Bluesky needs nothing but a handle. Needs ariadne (≥ 0.4), published on PyPI as ariadne-x (the bare name is taken by the GraphQL library):pip install ariadne-x. -
raft ft:run <name> --model <model>— model routing. OpenAI-finetunable ids (gpt-4o-mini and friends) go through the OpenAI finetuning API as before. Any other model — i.e. a huggingfaceorg/nameid — is trained on a rented GPU pod via opbdh's native finetuning facility (≥ 1.10.0). RAFT imports the generated examples into a resumable recipe; opbdh creates the SFT runner, estimates resources per GPU, launches training, and retrieves the adapter. Choose RunPod or Prime Intellect's multi-cloud GPU marketplace: there are many GPU and cloud options beyond RunPod, through these two provider backends.pip install -U 'raft-ft[hf]' opbdh config wizard raft ft:run garymarcus --model Qwen/Qwen2.5-7B-Instruct --provider primeintellect --method qlora --max-spend 5
Native recipe options include
--epochs,--learning-rate,--max-length,--batch-size,--gradient-accumulation, and--recipe. GPU options include--gpu-count,--vram-gb, and--max-dollars-per-hour; a project-rootopbdh.jsonworks too.--dry-runpreviews the launch without renting compute or recording a trained model. RAFT supports LoRA and QLoRA adapters. The command prints the native recipe directory, whereopbdh ftcan resume the workflow, and returns the syncedmodel/adapter directory after training.
Both integrations go through the two tools' Python APIs rather than shelling out, so raft gets the reconstructed threads and the run result as data — and surfaces their errors (spend guard tripped, remote job failed) directly.
RAFT / RATF
RAFT, or Retrieval-Augmented Fine-Tuning, is a method comprising of a fine-tuning and a RAG-based retrieval phase. It is particularly suited for the creation of agents that realistically emulate a specific human target.
RATF, or Replica Agent Testing Framework, is a framework for evaluating the performance of dialogue agents emulating real-world targets.
Abstract
The emulation of specific humans in conversational agents presents unique challenges and opportunities for contextual understanding, theory of mind and personalization. In this paper, we introduce the Retrieval-Augmented Fine-Tuning (RAFT) methodology, designed explicitly for simulating individual humans.
RAFT employs a dual-phase process:
In the Retrieval-Augmented Fine-Tuning phase proper, combines interview transcripts featuring the human target with appropriately selected, rephrased and evaluated "memories" from the author's past output to give the model a sense of the way the target human combines past writings with the current context to generate responses.
In the generation phase, these memories augment the language model's responses to create a nuanced and personalized dialogue.
We demonstrate the efficacy of RAFT through a unique evaluation metric, RATF (Replica Agent Testing Framework) that compares model-generated responses with original human responses in an interview setting. Our findings highlight RAFT's potential to significantly advance the field of personalized, context-sensitive conversational agents.
Process
Retrieval-Augmented Fine-Tuning
Two datasets are required for the fine-tuning phase:
- A dataset of interview transcripts featuring the target human
- A dataset of the target's past written output (tweets, essays, etc.)
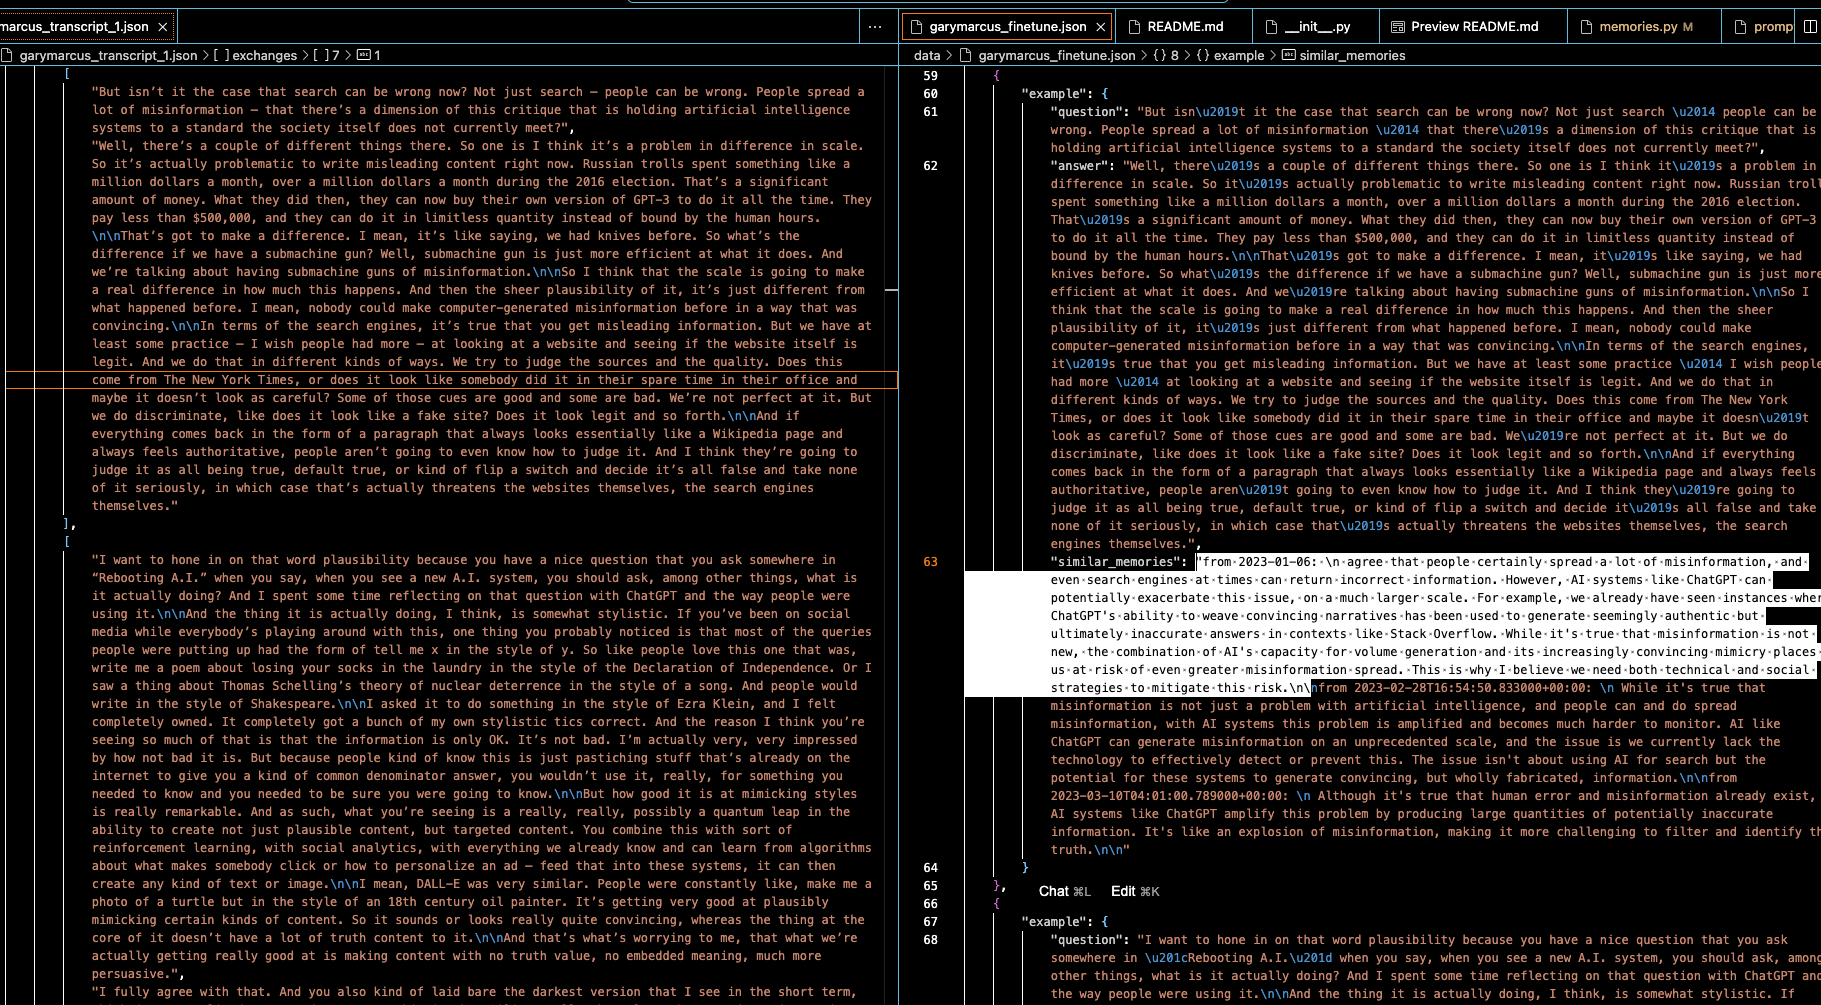
The interview transcripts used within a RAG-inspired process retreiving "memories" from the target's written output for each of the interviewer's questions. These memories are then rephrased and evaluated in the context of the target user's answer and, if found useful, they are interpolated between question and answer for the fine-tuning phase.
The steps to reproduce this process are as follows:
- Create a dataset of interview transcripts featuring the target human. Each interview is a separate
data/{name}_transcript_{i}.jsonfile holding{"participants": {"q": ..., "a": ...}, "date": ..., "url": ..., "exchanges": [[question, answer], ...]}. As of 2.0 you don't have to write these by hand:raft interactivetakes chat-message JSON, ariadne output or plain unstructured transcripts and produces them for you. - Create a dataset of the author's past written output —
data/{name}.jsonl, one{"title", "link", "date", "content"}object per line.raft fetchbuilds this from a substack;raft tweetsfrom a tweet archive;raft interactivefrom arbitrary local files. - Split the past output dataset in chunks of a size suitable for the chosen embedding model (8192 tokens for Openai's text-embedding-ada-002), and collect metadata and embeddings for each chunk.
- Store the resulting metadata and embeddings in a vector database (we use ChromaDB).
Then, in order to generate a fine-tuning dataset:
- For each interview, run the RAG process to retrieve memories from the author's past output for each of the interviewer's questions.
- Ask the model to rephrase each memory in the context of the interviewer's question. The same model and prompt will be used in the generation phase.
- Evaluate the resulting memory by the question only first, and discard it if it is not considered useful by the model. We apply this first pass separately because, at inference time, we will not have access to the target human's answer.
- Save the resulting context including question, memory and as many of the previous [question, memory and answers] tuples as possible, up to the maximum context size the finetune allows, as a new finetune sample.
Before/after pics (interview/ ft dataset)
Generation
The fine-tuned model is then used to generate responses to the interviewer's questions. The model is prompted with the question and the rephrased memories, and the resulting response is evaluated using the RATF framework.
Usage and Functionality
Installation
The distribution is named raft-ft (raft was taken on PyPI); the import and the
CLI are still raft. Until the first raft-ft release lands on PyPI, install from
git:
pip install git+https://github.com/lumpenspace/raft
Once released:
pip install raft-ft
For development, uv manages the environment:
uv sync --extra dev --extra hf
uv run pytest
uv run ruff check .
Usage
raft -h
The following actions are available:

- interactive: Guided end-to-end session: sources, conversations, finetune.
- tweets: Build a dataset from tweets via ariadne interactive.
- fetch: Fetch the blog from Substack and store it in the data directory.
- chunk: Chunk the blog into 4096 token pieces and store them in the data directory.
- embed: Create embeddings for the chunks and store them.
- ft:gen: Generate finetune files for the blog.
- ft:run: Run the finetune job (OpenAI, or huggingface via opbdh).
- bench:setup: Setup the benchmark for the blog.
- ask: Ask a question about the blog content.
Licence
MIT
1 maintainer

Release files for raft-ft 2.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| raft_ft-2.6.0.tar.gz | 56.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| raft_ft-2.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size:113.6 kB
Release files / raft_ft-2.6.0.tar.gz
| Download URL | raft_ft-2.6.0.tar.gz |
|---|---|
| Size | 56.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
57bae600bf7c16f62b9413ce5b3028731588c152b7d632ab00b6f6038da2fd58
|
|
BLAKE2b-256 checksum How to use checksums |
5b0879d4666d57d1d27b22e00e31e6895d8912c1073b955220f8ac193953ae52
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency logRelease files / raft_ft-2.6.0-py3-none-any.whl
| Download URL | raft_ft-2.6.0-py3-none-any.whl |
|---|---|
| Size | 57.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c1ad062747fa59db821ff4ad489c53a0a16d702222400f5355b686ac1d96b6cb
|
|
BLAKE2b-256 checksum How to use checksums |
61d19464e26b9b46f561531c7bab077eb50ae5e02493b6367bfd22d446be03a3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 11, 2026.
Transparency log













