
hawk
Write per-sample kernels in Python, with derivatives. Part of the RAPTOR family.
hawk: one kernel, two machines, and its derivatives
Write a numerical kernel for one sample as a plain Python function. hawk compiles it for the GPU or the CPU and derives its gradient (reverse mode) and tangent (forward mode).


aether · hawk · eagle · raptor · the family
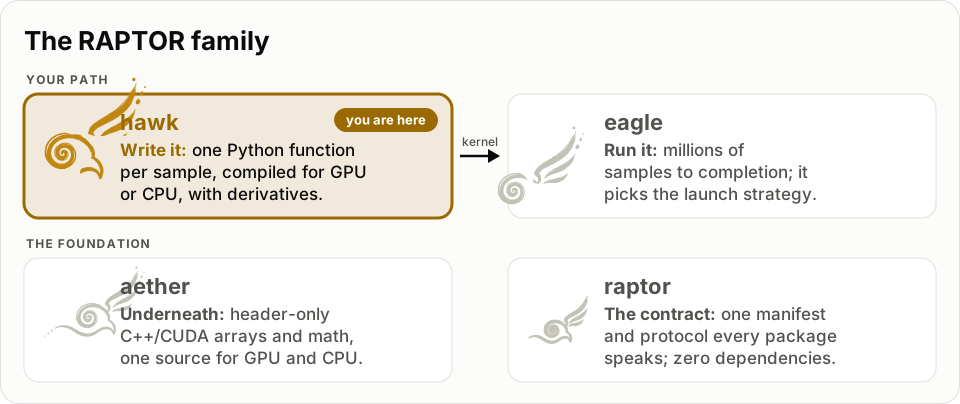
hawk is the kernel-authoring layer of the RAPTOR family: write a kernel once at the level of your application, and hawk derives its forward- and reverse-mode derivatives and compiles it for host or device through eagle. See where RAPTOR fits for the full four-part story.
Read the documentation — installation, a five-minute quickstart, tutorials, examples and the full Python API reference.
Write a kernel, get its gradient
import pathlib, tempfile

import hawk
from hawk import Kernel, Mutable, Scalar, Vector
from hawk.diff import vjp
from hawk.math import dot

@hawk.kernel
def energy(v: Vector[3], out: Mutable[Scalar]):
    out = 0.5 * dot(v, v)

energy_vjp = Kernel("energy_vjp", vjp(energy, wrt=("v",)))
work = pathlib.Path(tempfile.mkdtemp())
bundle = hawk.build([energy, energy_vjp], work, targets=("host",))
import numpy as np

v = np.array([[1.0, 2.0, 3.0, 4.0], [0.0, 1.0, 0.0, 1.0], [0.0, 0.0, 1.0, 1.0]])
e = np.zeros(4)
hawk.run(hawk.load(work, "energy"), v=v, out=e)
print("energy:", e)
# energy: [0.5 2.5 5.  9. ]
bar_out = np.ones(4)             # seed: d(loss)/d(energy) = 1 for every sample
bar_v = np.zeros((3, 4))
hawk.run(hawk.load(work, "energy_vjp"), v=v, bar_out=bar_out, bar_v=bar_v)
print("gradient d(energy)/dv:")
print(bar_v)
# [[1. 2. 3. 4.]
#  [0. 1. 0. 1.]
#  [0. 0. 1. 1.]]
energy = 0.5 |v|^2, so d(energy)/dv = v exactly — the printed gradient above is the input v. Output above
is the notebook's own: docs/content/tutorials/04_gradients_backward.ipynb. hawk.diff.jvp derives the forward-mode (tangent) twin the same way.
Five-minute quickstart · install: pip install raptor-hawk (CPU route; it brings aether-dsc along), or pip install "raptor-hawk[cuda12]" "raptor-eagle[cuda12]" for the GPU route
Writing kernels
A kernel is a plain Python function decorated @hawk.kernel, one sample at a
time; its parameters are its declared planes (Scalar, Vector[3], Mutable,
...) and its body writes ordinary arithmetic:
import hawk
from hawk import Mutable, Scalar, Terminated, Vector
from hawk.math import maximum, norm

@hawk.kernel
def running_apogee(position: Vector[3], terminated: Terminated,
                    r_max: Mutable[Scalar]):
    r_max = maximum(r_max, norm(position))
Running statistics: read it before you write it
A Mutable parameter such as r_max is an ordinary local variable: read
it before you assign it and you get the value it held when THIS launch
began, which is how a running statistic is written — a launch reads what
an earlier launch left behind, and writes a new value on top of it. Your
buffer remembers; the kernel reads what it remembered. The host owns that
memory: it must initialise r_max before the first launch and preserve it
between launches — hawk never zeroes or scratch-allocates a plane a kernel
reads from. That memory is not differentiable: a launch-start read is a
recurrence across launches, and hawk keeps no tape across them, so
hawk.diff.vjp/jvp refuse a kernel that reads one — differentiate the
per-launch term on its own instead.
Kernel kinds and returned outputs
A kernel may commit through several sinks — the places a kernel's
result goes: declared Mutable/Accum parameters (Output.named(...)),
a return <expr> committed into a synthesised slot (a result sink
hawk creates for you rather than one you declared as a parameter;
Output.returned(ttype, slot=...) names it), or both together — a
returned acceleration alongside an ordinary diagnostic Mutable the body
also writes:
from hawk import Param
from hawk.ext import Kind, Output

ACCEL = Kind("drag", output=Output.returned(Vector[3], slot="acc"))

@ACCEL
def drag(velocity: Vector[3], k: Param, speed: Mutable[Scalar]):
    speed = norm(velocity)          # an ordinary named sink
    return (-k * norm(velocity)) * velocity   # the returned slot, "acc"
Kind(...) also has a class-form spelling — sugar over the same object, one
kernel-authoring style closer to a plugin author's own vocabulary: an
annotated class attribute is a vocabulary entry, a plain-assigned one sets
one of Kind's own fields (output, sink, guard, ...), and anything
else refuses.
from hawk.ext import KernelKind, Output

class Accel(KernelKind, slug="drag"):
    output = Output.returned(Vector[3], slot="acc")

@Accel
def drag(velocity: Vector[3], k: Param):
    return (-k * norm(velocity)) * velocity
Install
pip install raptor-hawk                                     # CPU only: no GPU, driver or CUDA packages needed
pip install "raptor-hawk[cuda12]" "raptor-eagle[cuda12]"    # GPU: hawk compiles, eagle runs; [cuda13] on both for CUDA 13
Linux x86_64, CPython 3.10-3.13, and a host g++ 11 or newer. raptor-hawk pulls aether-dsc (the sealed C++
headers hawk compiles against) automatically. No nvcc or CUDA toolkit is needed. Tested with CUDA 12.6 and
CUDA 13.0 (CUDA 12.6 or newer).
NVIDIA packages come only through the extras.
raptor-hawk[cuda12]pullscuda-bindings12,nvidia-cuda-nvrtc-cu12andnvidia-cuda-cccl-cu12;raptor-hawk[cuda13]pullscuda-bindings13,nvidia-cuda-nvrtc13 andnvidia-cuda-cccl13 (CUDA 13's wheels have no-cu13suffix);raptor-eagle[cuda12]/[cuda13]pull CuPy (cupy-cuda12x/cupy-cuda13x, with the CUDA headers CuPy compiles against). Without an extra pip installs no NVIDIA package: you get the CPU route, or the GPU route through a CUDA setup you already have. Pick the extra matching the CUDA version your driver reports (nvidia-smi, top right).
Platforms: built and tested on Linux x86_64 only so far (CPython 3.10–3.13), on NVIDIA GPUs from Pascal (Quadro P2000) and Turing (Tesla T4). There are no wheels for macOS, Windows or ARM yet, and WSL2 is untested. raptor-core and aether-dsc are pure Python and install anywhere.
See installation for the CPU-only route (no GPU, driver or NVRTC needed at all) and every other detail.
Performance
Every number in this section is read from eagle's committed cards (benchmarks/perf_card/card_quadro-p2000.md, benchmarks/rk78_card/card_quadro-p2000.md).
Kernels authored with hawk are what eagle's performance card times: hawk + eagle (eagle.simulate) is
3.9×–47× faster than NVIDIA Warp (3.9×), JAX (8.7×), CuPy and PyTorch (47×) at 1,000,000 RK4
oscillators finishing at different times — 156 ms on a
Quadro P2000, using 3.8×–5.2× less GPU memory than CuPy and PyTorch (a million samples in 50 MiB, 1.31× the
bare minimum state; CuPy 5.1×, PyTorch 6.9×; NVIDIA Warp 64 MiB, 1.7×) — and the same hawk kernel, unmodified, integrates 1,000,000 adaptive
RK7(8) orbits in 13.0 s on the GPU or 7.15 s on 8 CPU threads alone. This is the regime hawk + eagle's
compaction targets (many samples stopping at different times); in other regimes the other tools hold their own — on a
dense workload where nothing finishes early Warp ties it (693 ms vs 699 ms at N = 1,000,000) and is level at
N = 10,000 (7.22 ms vs 7.22 ms), and on this FP64-weak development card the CPU arm is the faster one there. See
eagle's performance page for every number, every arm,
including the ones where it doesn't win.
Going deeper
The pip-only device compile, directly
The device compile hawk.artifact.build/build_bundle use when no nvcc
is on $PATH goes through hawk.compile.device/hawk.compile.cubin; the
same entry points are usable directly, for an ad hoc CUDA C++ source
string that was never authored as a traced hawk kernel at all:
from hawk.compile import cubin, cubin_available

if cubin_available():
    image = cubin(source)          # DeviceImage(image=<SASS bytes>, target="cubin", arch="sm_XX")
cubin_available() never raises; device(source, target="ptx") is the
alternative when PTX (the portable intermediate form NVRTC can also emit)
is what a caller needs, guarded against a driver too old to JIT a newer
NVRTC's PTX (target="cubin" needs no such guard — it is already SASS,
the GPU's own machine code). Headers come from aether_dsc's sealed
payload — a copy of the headers hawk's device compiler reads from
directly, bundled into the wheel — never from disk.
Build and test from a source checkout (development)
Clone aether and eagle next to this checkout (so ../aether
and ../eagle sit beside hawk/), then install aether's sealed header
payload before hawk itself:
pip install ../aether/dsc
pip install -e .[test]
pytest -m "not gpu"
The compiled half (hawk._core) is a nanobind extension built through
scikit-build-core; pip install -e . builds it via CMakeLists.txt,
resolving the aether/eagle C++ header roots from those sibling checkouts
(or $HAWK_AETHER_INCLUDE/$HAWK_EAGLE_INCLUDE). -m "not gpu" deselects
the tests that need a CUDA GPU and cupy; most of the rest additionally
need eagle installed as a Python package to execute traced kernels on host
or device (see the "Python package" section of
eagle's README).
hawk write it (this repo) · eagle run it · aether the numerics core · raptor the shared contracts — the RAPTOR family
Apache-2.0 (see LICENSE and
NOTICE) · cite via "Cite this repository"
(CITATION.cff; each tagged release is archived on Zenodo with its own DOI once the first one exists) · built to
make GPU computing accessible on modest hardware, for research and education. Collaboration is the point, and a
citation is the currency — get in touch.
1 maintainer

Metadata
1 maintainer
Release files for raptor-hawk 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| raptor_hawk-0.3.0.tar.gz | 1.4 MB | Details |
Built distributions (wheels)
| File | Reset | |||
|---|---|---|---|---|
| raptor_hawk-0.3.0-cp313-cp313-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl | CPython 3.13 | CPython 3.13 | Linux glibc 2.28+ x86-64, Linux glibc 2.26+ x86-64 | Details |
| raptor_hawk-0.3.0-cp312-cp312-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl | CPython 3.12 | CPython 3.12 | Linux glibc 2.26+ x86-64, Linux glibc 2.28+ x86-64 | Details |
| raptor_hawk-0.3.0-cp311-cp311-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl | CPython 3.11 | CPython 3.11 | Linux glibc 2.26+ x86-64, Linux glibc 2.28+ x86-64 | Details |
| raptor_hawk-0.3.0-cp310-cp310-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl | CPython 3.10 | CPython 3.10 | Linux glibc 2.26+ x86-64, Linux glibc 2.28+ x86-64 | Details |
Total release size: 3.3 MB
Release files / raptor_hawk-0.3.0.tar.gz
| Download URL | raptor_hawk-0.3.0.tar.gz |
|---|---|
| Size | 1.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
920554ff50b35a64b310dce8fa3e32816baea2514aef34349524ae40f9bdca3e
|
|
BLAKE2b-256 checksum How to use checksums |
ccd7d5c12a19d4996587c035eb3625ed259705e83a32920ec363ee71b8b05b57
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / raptor_hawk-0.3.0-cp313-cp313-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl
| Download URL | raptor_hawk-0.3.0-cp313-cp313-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl |
|---|---|
| Size | 484.1 kB |
| Tags | CPython 3.13 Linux glibc 2.26+ x86-64 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
a301b217b209820ba05624e30c2d63e9aab7a75fb2218cd4ea05cf173b965906
|
|
BLAKE2b-256 checksum How to use checksums |
74ed4883be33ec0b2b7ca2634e3b9cd49a206750198036b45670346d09e065ca
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / raptor_hawk-0.3.0-cp312-cp312-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl
| Download URL | raptor_hawk-0.3.0-cp312-cp312-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl |
|---|---|
| Size | 484.2 kB |
| Tags | CPython 3.12 Linux glibc 2.26+ x86-64 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
4e7995777e6fc3c8c6184caf178c7d6ecf528045907571b5f6db2e6b2421aa89
|
|
BLAKE2b-256 checksum How to use checksums |
4998cb7988a8ed505d20864b186a297adfd8f337935daf5169d7c16bc6e65e69
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / raptor_hawk-0.3.0-cp311-cp311-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl
| Download URL | raptor_hawk-0.3.0-cp311-cp311-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl |
|---|---|
| Size | 484.6 kB |
| Tags | CPython 3.11 Linux glibc 2.26+ x86-64 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
233d4e41fa822a36e24d8a6b15caaf1d92b784dfc801d784ebedc7f5829ad1c0
|
|
BLAKE2b-256 checksum How to use checksums |
c197af301b4f42983c1ff5a01e598c17ae83a4f6fb44acad1e47b7f283d4e9bf
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / raptor_hawk-0.3.0-cp310-cp310-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl
| Download URL | raptor_hawk-0.3.0-cp310-cp310-manylinux_2_26_x86_64.manylinux_2_28_x86_64.whl |
|---|---|
| Size | 485.0 kB |
| Tags | CPython 3.10 Linux glibc 2.26+ x86-64 Linux glibc 2.28+ x86-64 |
|
SHA-256 checksum How to use checksums |
338a37a08a05f98dd4321f1a2efacaa4555e1fbd3187294e998ef666ba6d094f
|
|
BLAKE2b-256 checksum How to use checksums |
8e39f39f4c5e090c10c054cecbbd13499d627672737e0bf331ade393fa9ecbd8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency log













