
Reddrix — An open-source, blazing-fast Reddit Scraper for Python (No Login or API Key)
A powerful, async-first Reddit scraper (with built-in proxy support) for posts and comments with detailed metrics (no login or API key). Scrape subreddits, profiles, and specific posts, or search Reddit site-wide by keywords. Collect rich, structured data including authors, scores, timestamps, post flairs, comment threads, and more (24+ fields).


If this Python package is useful to you or saved you time, consider starring the GitHub repository ⭐ to support me and help other find it and have an easier time scraping Reddit ❤️.
Installation • Quickstart • Features • Output Dataset • Reddrix Arguments Options
Installation
pip install -U reddrix
reddrix install # Mandatory for installing the Camoufox browser.
Quickstart
Using Async Context Manager:
from reddrix import Reddrix
import asyncio

async def main():
    async with Reddrix(
        mode="standard",
        subreddit_urls=[
            "https://www.reddit.com/r/webscraping",
            # URLs of specific subreddits to include when scraping posts and comments
            # Add as many as you want
        ],
        profile_urls=[], # URLs of specific profiles to include when scraping posts and comments; add as many as you want. Only public data is scraped
        post_urls=[], # URLs of specific posts to include in the scraping; add as many as you like
        sort="new",
        include_comments=True,
        max_results=500,
        max_posts_per_collection=500,
        verbose=True
    ) as reddrix:
        scrape_count = 0
        async for item in reddrix.get_items():
            # item is a Python dictionary with more than 24 keys.
            scrape_count += 1
            print(scrape_count, item["submissionType"], item["submissionUrl"])

if __name__ == "__main__":
    asyncio.run(main())
Without the context manager:
from reddrix import Reddrix
import asyncio

async def main():
    reddrix = Reddrix(
        mode="standard",
        subreddit_urls=["https://www.reddit.com/r/webscraping"],
        sort="new",
        include_comments=True,
        max_results=500,
        max_posts_per_collection=500,
        verbose=True
    )
    await reddrix.start()

    scrape_count = 0
    async for item in reddrix.get_items():
        # item is a Python dictionary with more than 24 keys.
        scrape_count += 1
        print(scrape_count, item["submissionType"], item["submissionUrl"])

    await reddrix.stop()


if __name__ == "__main__":
    asyncio.run(main())
Scraping Posts and Comments Based on Keywords (uses Reddit's current shreddit search engine):
from reddrix import Reddrix
import asyncio

async def main():
    async with Reddrix(
        mode="keyword_search",
        sort="new", # The sort option is ignored for this mode
        query="how to scrape reddit",
        include_comments=True,
        max_results=500,
        max_posts_per_collection=500,
        verbose=True
    ) as reddrix:
        scrape_count = 0
        async for item in reddrix.get_items():
            # item is a Python dictionary with more than 24 keys.
            scrape_count += 1
            print(scrape_count, item["submissionType"], item["submissionUrl"])

if __name__ == "__main__":
    asyncio.run(main())
Using Reddrix as a standalone Reddit http client for your custom scraping setup (random jitter between requests does not apply when using the get method directly, so you'll need to use your own logic here, or use the preset scraping setup shown above):
from reddrix import Reddrix
import asyncio

async def main():
    async with Reddrix() as reddrix:
        html_content = await reddrix.get(url="https://www.reddit.com/search?q=how+to+scrape+reddit") # Only HTML/XML is supported
        print(html_content)

if __name__ == "__main__":
    asyncio.run(main())
Using Reddrix with Proxies:
from reddrix import Reddrix
import asyncio

async def main():
    async with Reddrix(
        # Your normal arguments above ...,
        proxies=[
            "scheme://user:pass@hostname:port",
            "scheme://user2:pass2@hostname2:port2",
            # Add as many as you want, and Reddrix automatically rotates between them...
        ]
    ) as reddrix:
        scrape_count = 0
        async for item in reddrix.get_items():
            # item is a Python dictionary with more than 24 keys.
            scrape_count += 1
            print(scrape_count, item["submissionType"], item["submissionUrl"])

if __name__ == "__main__":
    asyncio.run(main())
Features
- 🚀 Async-First: High-performance asynchronous scraping with
asyncioand an async iterator for streaming results. - 🔑 No Login or API Key: Scrape Reddit seamlessly without logging in or providing an API key.
- 🔍 Multiple Search Modes: Scrape subreddits, user profiles, and specific posts, or search Reddit by keywords.
- 💬 Comprehensive Data Extraction: Collect posts and comments with 24+ structured fields, including authors, scores, timestamps, flairs, media URLs, and comment thread metadata.
- 🛡️ Resilient Scraping: Built-in retries, cookie renewal, request jittering, and configurable proxies.
- ⚙️ Fine-Grained Control: Configure sorting, time frames, result limits, comment depth, and comment counts.
- 🧩 Standalone HTTP Client: Use Reddrix's asynchronous
get()method in your own custom scraping workflows. - 🐍 Pythonic API: Manage scraper resources with an async context manager or explicit
start()andstop()methods.
Output Dataset
If you use the preset scraping setup from async for item reddrix.get_items(), each item is a Python dictionary with 24 keys.
Example Reddit Post Output:
{
  "submissionId": "1w1gc8p",
  "submissionIdPrefixed": "t3_1w1gc8p",
  "submissionType": "post",
  "submissionUrl": "https://www.reddit.com/r/Sat/comments/1w1gc8p/is_this_good_improvement_for_10_hours_of/",
  "submittedAt": "2026-08-29T07:53:42+00:00",
  "parentId": None,
  "parentPostId": None,
  "parentPostUrl": None,
  "postType": "image",
  "crosspostParentId": None,
  "crosspostParentUrl": None,
  "title": "Is this good improvement for 10 hours of dedicated study + need help for rw section",
  "bodyText": "math significantly improved but reading writing is too tough for me (international student)\n\nplease help, i have to give the sat in two months, will reading novels improve my rw score?",
  "author": "stcer",
  "depth": None,
  "postFlair": None,
  "tags": [],
  "subreddit": "r/Sat",
  "score": 32,
  "upvoteRatio": 0.98,
  "numComments": 29,
  "numCrossposts": 0,
  "externalUrl": "https://i.redd.it/cjhezz5bs9mh1.jpeg",
  "galleryImagesUrls": []
}
Example Comment Output:
{
  "submissionId": "p6lwobb",
  "submissionIdPrefixed": "t1_p6lwobb",
  "submissionType": "comment",
  "submissionUrl": "https://www.reddit.com/r/Sat/comments/1w1gc8p/is_this_good_improvement_for_10_hours_of/p6lwobb/",
  "submittedAt": "2026-08-29T13:41:52+00:00",
  "parentId": "t3_1w1gc8p",
  "parentPostId": "t3_1w1gc8p",
  "parentPostUrl": "https://www.reddit.com/r/Sat/comments/1w1gc8p",
  "postType": None,
  "crosspostParentId": None,
  "crosspostParentUrl": None,
  "title": None,
  "bodyText": "How did you do that in 10 hours? Can you please give me the sources that you used? I also need help in rw section and I’ll take the sat in 2 weeks",
  "author": "AnalysisStill4932",
  "depth": 0,
  "postFlair": None,
  "tags": [],
  "subreddit": "r/Sat",
  "score": 9,
  "upvoteRatio": None,
  "numComments": None,
  "externalUrl": None,
  "thumbnailUrl": None,
  "galleryImagesUrls": []
}
Output Fields Explanation:
submissionId— [string] The ID of the post or comment.submissionIdPrefixed— [string] The prefixed ID of the post or comment.submissionType— [string] Whether the submission is apostorcomment.submissionUrl— [string] The URL for the submission.submittedAt— [string] The date and time the post or comment was submitted in UTC timezone and ISO format.parentId— [string,None] The ID of the direct parent post or comment.parentPostId— [string,None] The ID of the parent post. For posts, this field will always beNonesince posts have no parent.parentPostUrl— [string,None] The URL of the parent post. For posts, this field will always beNonesince posts have no parent.postType— [string,None] The post type. Can be any oftext,poll,link,image,gallery, orvideo. For comments, this field will always beNone.crosspostParentId— [string,None] The ID of the parent of the crosspost (for posts that are not crossposts, will beNone).crosspostParentUrl— [string,None] The URL of the parent of the crosspost (for posts that are not crossposts, will beNone).title— [string,None] The post title (will always beNonefor comments).bodyText— [string,None] The main text content of a post or comment.author— [string] The author of the post or comment.depth— [integer,None] The comment depth (top-level comments have a depth of0and posts have a depth ofNone).postFlair— [string,None] The post flair (will beNonefor comments).tags— [list] A list of the tags for the post (always empty for comments).subreddit— [string,None] The subreddit in which the post or comment was submitted.score— [integer,None] The vote score of the post or comment.upvoteRatio— [float,None] The ratio of upvotes to total number of votes of a post (alwaysNonefor comments).numComments— [integer,None] The number of comments in a post (alwaysNonefor comments).externalUrl— [string,None] The external URL in a post. For comments, this field will beNonebecause external URLs will be included in thebodyTextanyway.thumbnailUrl— [string,None] The thumbnail image URL forvideo,image, andgallerypost types (alwaysNonefor any other submission).galleryImagesUrls— [list] A list of URLs for all images in a gallery (always empty for any submission other thangalleryposts).
Reddrix Arguments Options
mode(string) — Eitherstandardorkeyword_search. Default isstandard.max_results(integer) — The maximum total number of items (posts and comments combined) to return across all sources. Default is999999.max_posts_per_collection(integer) — The maximum number of posts to scrape from each collection. A collection is a single subreddit, profile, keyword search, or domain. Default is999999.sort(string) — One ofdefault,new,hot,top_all_time,top_past_hour,top_today,top_past_week,top_past_month, andtop_past_year. Applies to subreddits and profiles. This option is ignored inkeyword_searchmode, which always uses Reddit's relevance sorting. Default isdefault.subreddit_urls(list of strings) — Subreddit URLs to scrape, e.g.["https://www.reddit.com/r/webscraping"]. Used instandardmode only. URLs that are not valid subreddit URLs are skipped. Default is[].post_urls(list of strings) — Specific post URLs to scrape, e.g.["https://www.reddit.com/r/webscraping/comments/abc123/post_title/"]. Used instandardmode only. URLs that are not valid post URLs are skipped. Default is[].profile_urls(list of strings) — User profile URLs to scrape the submitted posts of, e.g.["https://www.reddit.com/user/username"]. Both/user/and/u/URLs are supported. Used instandardmode only. URLs that are not valid profile URLs, or those of profiles that are deleted, banned, or hiding their content, are skipped. Default is[].query(string) — The search keywords to look up site-wide on Reddit. Used inkeyword_searchmode only. Default isNone.include_comments(boolean) — Whether to scrape the comments of each post in addition to the post itself. Comments are returned as separate items withsubmissionTypeset tocomment. Default isFalse.max_comments_depth(integer) — The maximum comment depth to scrape. Top-level comments have a depth of0, their replies have a depth of1, and so on. Only applies ifinclude_commentsisTrue. Default is10.max_comments_per_post(integer) — The maximum total number of comments (top-level comments and replies) to scrape per post. Only applies ifinclude_commentsisTrue. Default is999999.max_top_comments_per_post(integer) — The maximum number of top-level comments (depth0) to scrape per post. Only applies ifinclude_commentsisTrue. Default is999999.proxies(list of strings) — A list of proxy URLs in the formatscheme://user:pass@hostname:port. Reddrix rotates through them automatically, picking an unused proxy first and reusing proxies only after the whole list has been used. Default is[](no proxy).verbose(boolean) — Whether to print timestamped log messages (initialization, retries, etc.) to the console. Default isFalse.
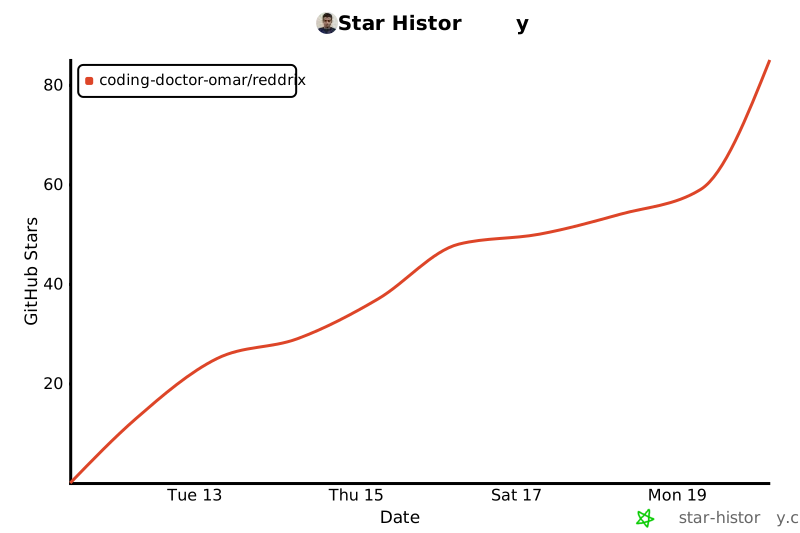
Star History
1 maintainer

Metadata
1 maintainer
Release files for reddrix 1.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| reddrix-1.1.1.tar.gz | 18.4 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| reddrix-1.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 33.2 kB
Release files / reddrix-1.1.1.tar.gz
| Download URL | reddrix-1.1.1.tar.gz |
|---|---|
| Size | 18.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0ab0cd32a76c952526d271d431ebf5062d466f83e04a4f47a548536c4ba51eb6
|
|
BLAKE2b-256 checksum How to use checksums |
bb4831c509c09df9182988ee096d4fc95c858cff6a315edce91975e0ba2d41cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.1
|
Release files / reddrix-1.1.1-py3-none-any.whl
| Download URL | reddrix-1.1.1-py3-none-any.whl |
|---|---|
| Size | 14.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
b944c20a0e703ec7f094ab4fa409d6a1f75ab20c4cf335d8dec9f42f7df2b9e6
|
|
BLAKE2b-256 checksum How to use checksums |
6d2b7d2f2548af9a35c77f82e16f5bf7ad72b419603aa5ca0ec4c723bcad7a79
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.1
|
Security for reddrix 1.1.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














