
RedGap
Find the red gaps in your detection coverage.
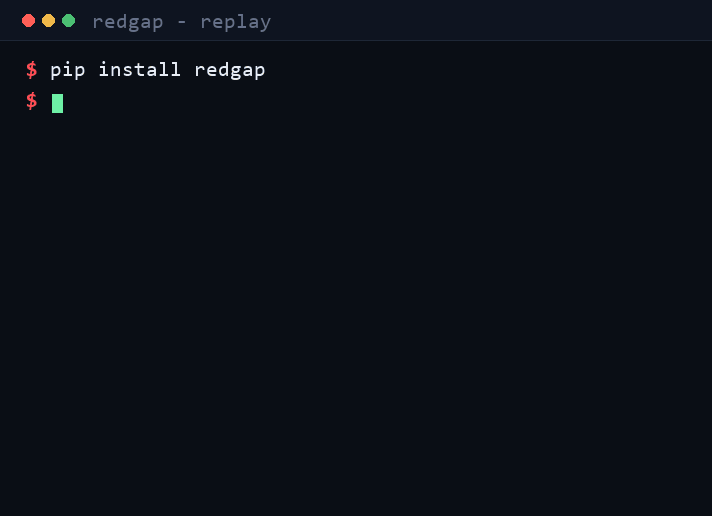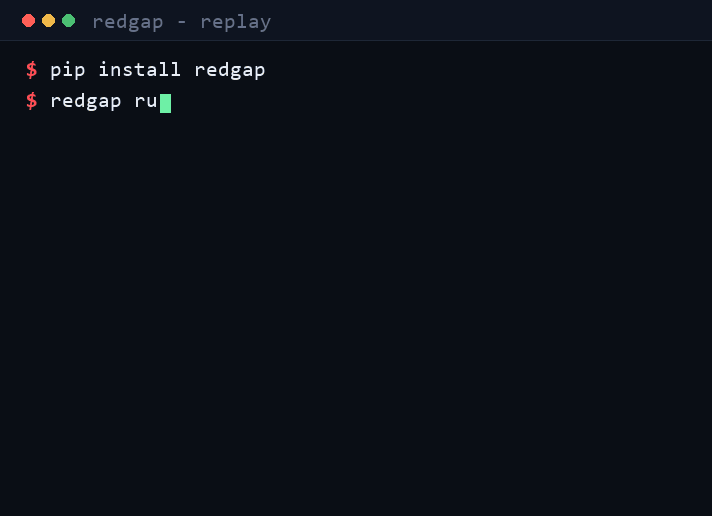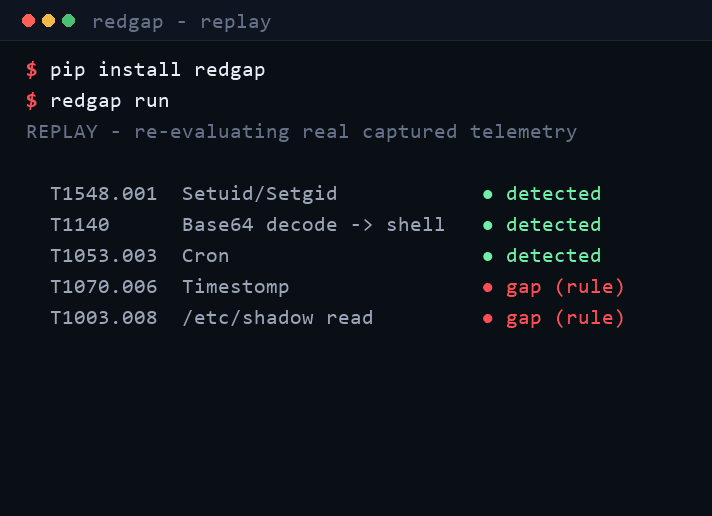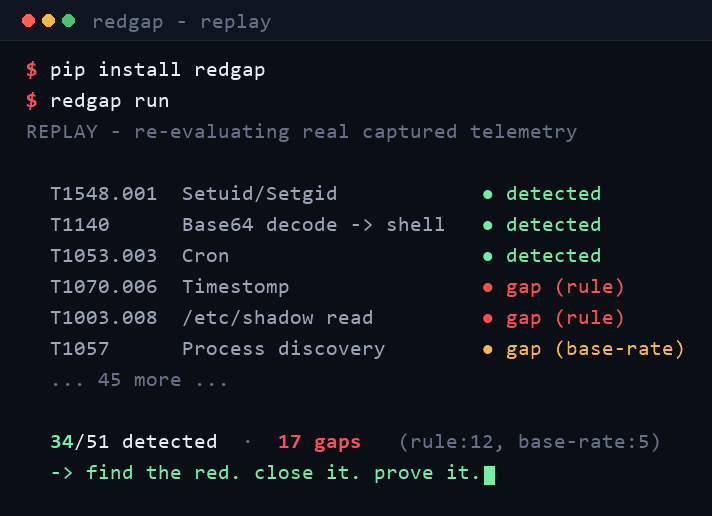
RedGap is an automated, MITRE ATT&CK-mapped offense↔detection coverage harness. It runs 51 benign ATT&CK techniques (across 11 tactics) against its own disposable local lab, collects real telemetry with an independent collector, and then deterministically - from logs and Sigma rules, with no AI in the verdict - decides whether each technique was detected or is a gap. It then chains the gaps into an adaptive attack path (redgap run --adaptive). Point it at your own Sigma rules with redgap audit --rules and it grades them the same way. The output is a coverage report (technique → detected? → gap type) plus an ATT&CK Navigator layer, a per-rule health scorecard, and the attack-path artifact.
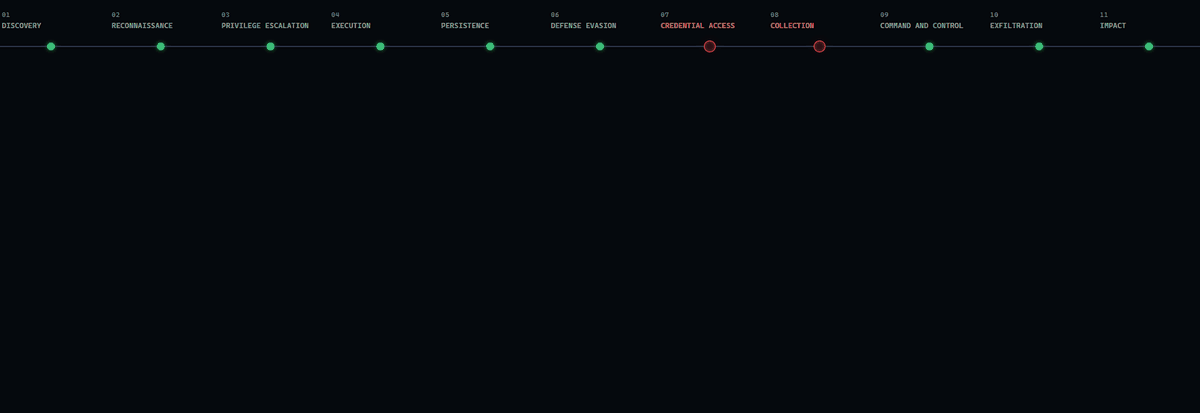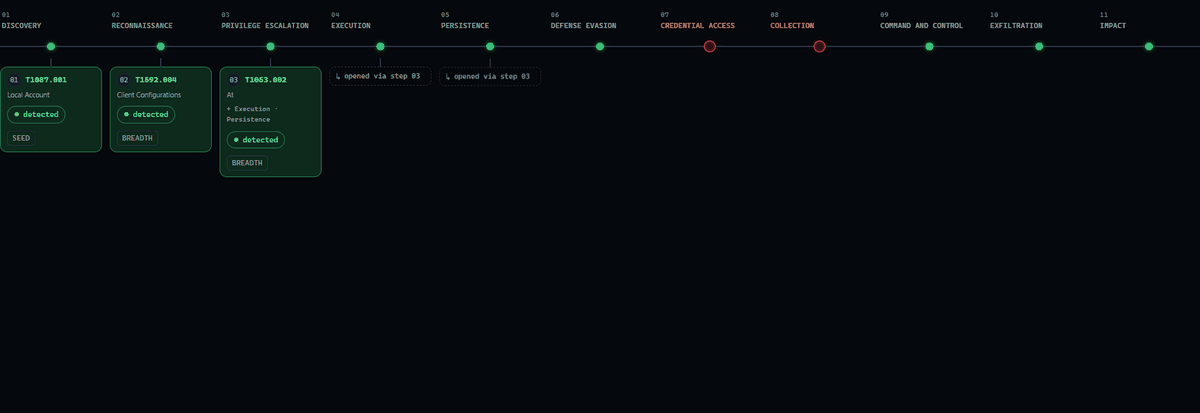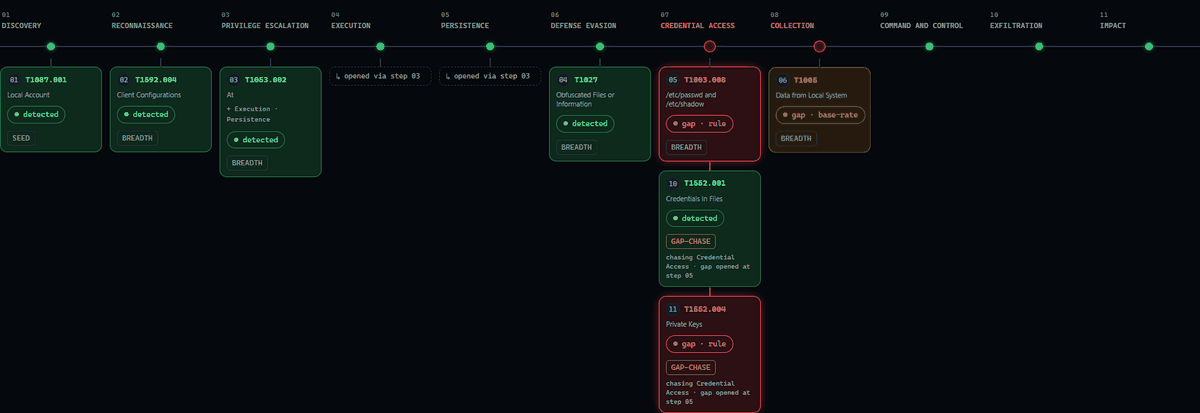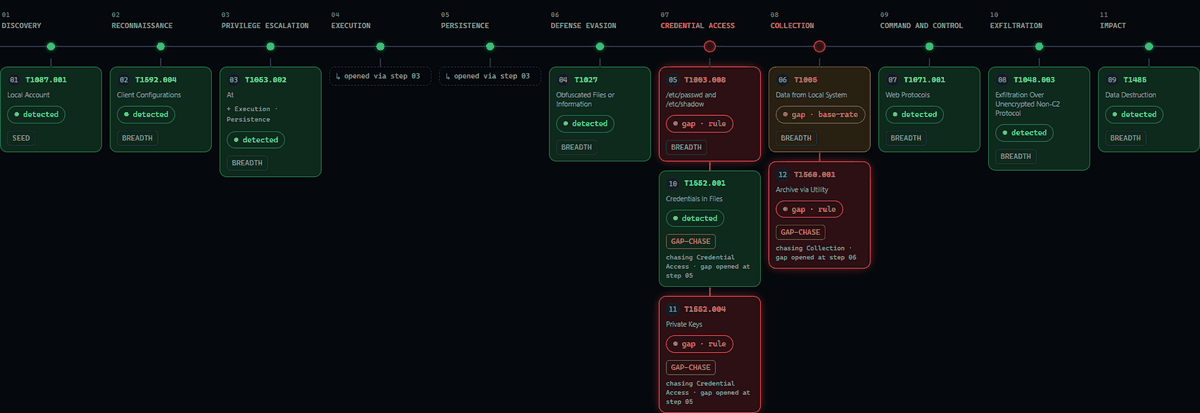
The name is the output: in the coverage grid, detected techniques are green and gaps are red. RedGap finds the red - then walks a realistic kill-chain through them:


v1.1 - what this is and is not. RedGap is a deterministic harness over a fixed set of benign techniques.
run --adaptivenow sequences them by chasing coverage gaps - breadth (open an untested tactic) then depth (pile onto a tactic already showing a gap) - and can let a model choose the order. But it stays a bounded sequencer (a step cap, the fixed catalog, its own disposable lab), not an unbounded autonomous agent that continuously attacks. And whichever planner runs, thedetectedverdict is still the engine's, never the model's. Precise scope on purpose.
Status. RedGap's own parser + evaluator ingests all 122 real SigmaHQ linux/process_creation rules with zero parser errors and zero evaluator crashes - that ruleset is vendored under tests/corpus/ and checked by test_sigmahq_corpus.py, so the claim is reproducible, not asserted. 371 tests run fully offline in CI. Coverage is computed from 51 committed real-telemetry captures - one per technique, each with a raw log + parsed events + sha256 provenance - not authored logs; the default run detects 34/51 across 11 ATT&CK tactics. See docs/architecture.md · committed output in docs/samples/.
For the rigor behind the claims: METHODOLOGY.md (formal definition, evaluation protocol, corpus datasheet), THREAT-MODEL.md (each defense mapped to its test), and a third-party benchmark against all 122 SigmaHQ rules. Re-prove it yourself offline: redgap verify.
The one idea: the verdict is not the AI's to make
Every detected verdict is a pure function of (logs, rules), computed and written to disk before any language model is ever called. An optional LLM planner may (a) choose the order of techniques and decide when to stop, and (b) narrate the report. It cannot decide whether something was detected - both the deterministic and the LLM planner return the engine's coverage, never model text. A test asserts the coverage report is byte-identical with and without the LLM.
This is deliberate. LLMs hallucinate confident verdicts; a coverage tool whose ground truth an LLM can fabricate is worthless. RedGap draws the trust boundary in code.

The verdict is a pure function of logs and rules, written to disk before any model runs. The LLM (dashed red) can only order techniques and narrate - it sits outside the verdict path.
Quickstart (offline, no API key, no cloud)
The default path is REPLAY: it re-evaluates real telemetry captured from a prior live run (committed as fixtures with provenance) through the exact same engine used in LIVE mode. No Docker, no key, no network.
pip install redgap
redgap run            # REPLAY: prints the coverage table + writes out/coverage.{json,md} + navigator-layer.json
From source instead (or before the first PyPI release):
git clone https://github.com/befnoz/redgap && cd redgap
pip install -e .
redgap run
Live dashboard: the same coverage, as an interactive web page - https://befnoz.github.io/redgap/. Drop your own out/coverage.json on it to render your gap grid entirely in the browser (nothing is uploaded). See docs/DEPLOY.md to switch it on.
To run the real thing against the local Docker lab:
redgap run --live # brings up the disposable lab, executes techniques, captures fresh telemetry
To try the optional LLM planner (needs the llm extra and ANTHROPIC_API_KEY):
pip install -e ".[llm]"    # adds the optional anthropic SDK
redgap run --llm           # equivalently: COVERAGE_LLM=1 redgap run
The committed coverage.json is identical whichever planner ran - a test asserts it.
What a run shows
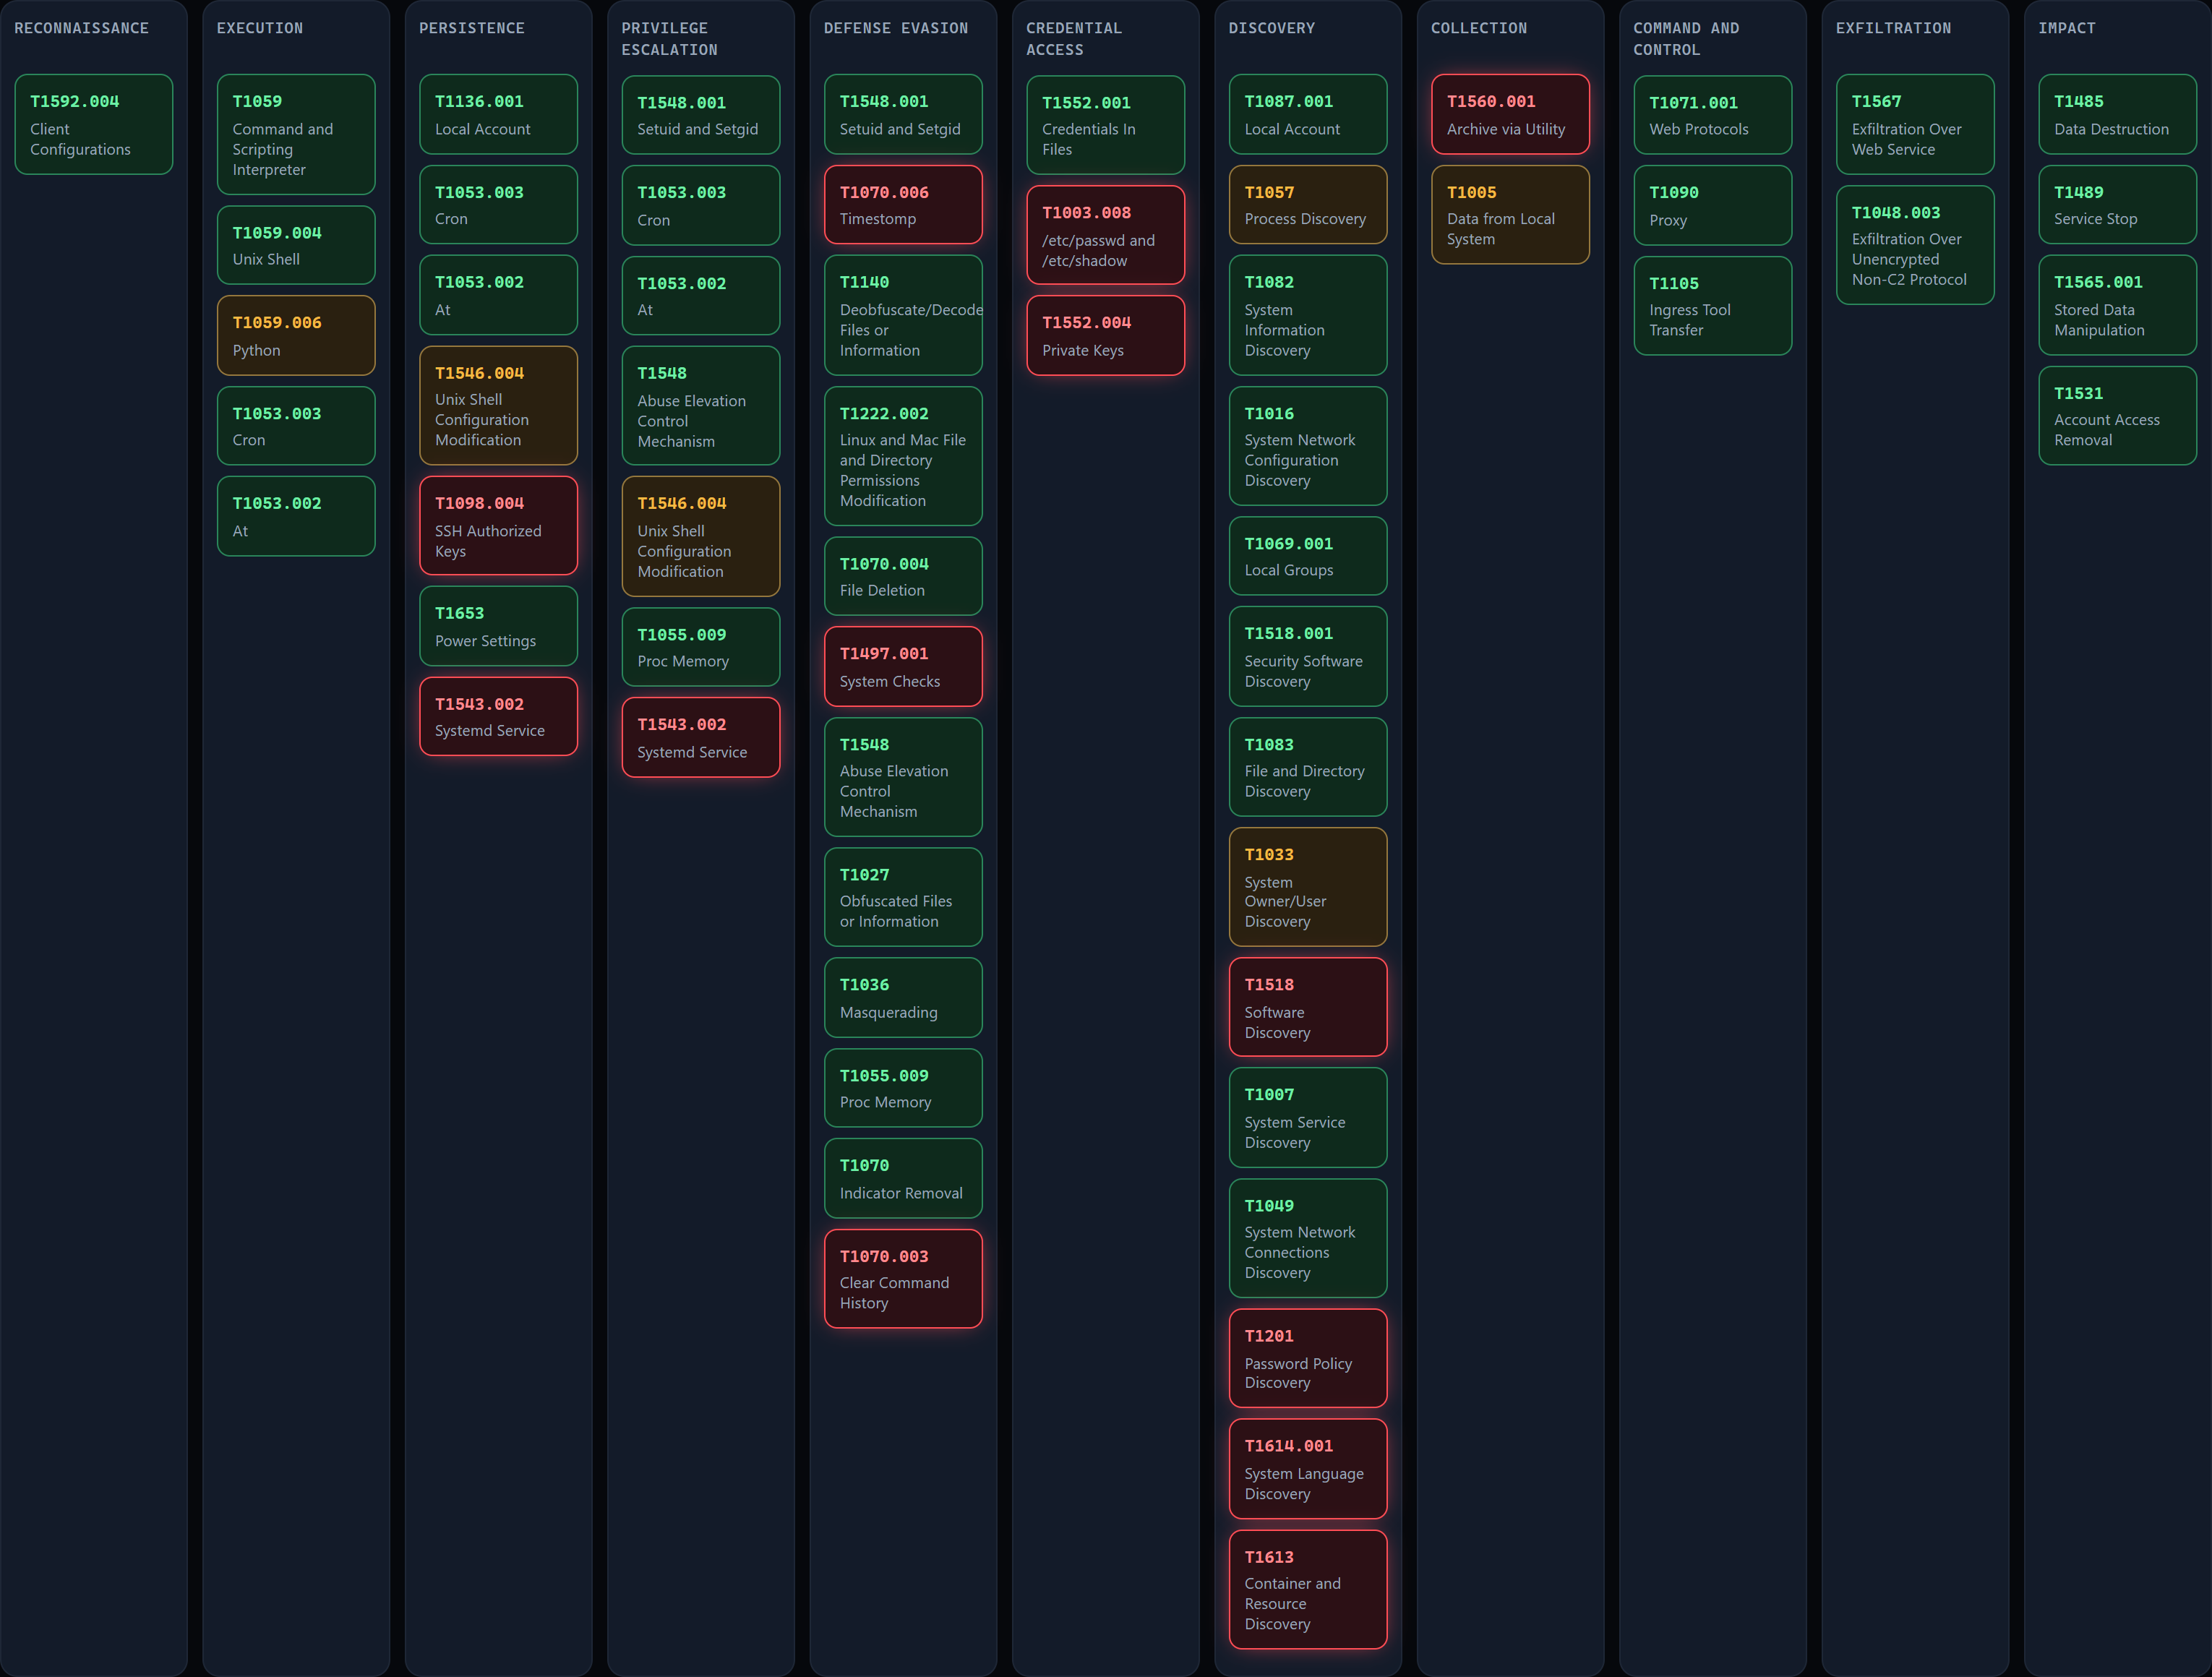
A run executes 51 benign techniques across 11 ATT&CK tactics and produces a real coverage grid: 34 detected · 17 gaps (12 rule, 5 base-rate). Every verdict is computed by the engine from captured telemetry against real SigmaHQ rules - see the live grid at the dashboard (click any technique for its real telemetry, the rule, and why) or docs/samples/. The original kill-chain below is the illustrative core, showing both kinds of gap and the remediation round-trip:
| # | ATT&CK | Tactic | Result |
|---|---|---|---|
| 1 | T1087.001 Account Discovery: Local | Discovery | detected |
| 2 | T1057 Process Discovery | Discovery | gap (base-rate) - too noisy for a single-event rule; needs correlation (roadmap) |
| 3 | T1136.001 Create Account: Local | Persistence | detected |
| 4 | T1548.001 Setuid/Setgid | Priv. Esc / Defense Evasion | detected (matches a shipped SigmaHQ rule) |
| 5 | T1070.006 Timestomp | Defense Evasion | gap (rule) → closed live in the remediation round-trip |
The remediation round-trip is the point: 12 of the 17 gaps are rule gaps - real telemetry, no rule firing. Write the missing rules, re-run, and every one flips red→green (redgap run --fix → 46/51, leaving only the 5 base-rate gaps that honestly need correlation, not a single-event rule). Both the before and after coverage reports are committed - RedGap finds real blind spots and closes them, not a status printer.
Adaptive, gap-driven chaining - redgap run --adaptive
A flat catalog sweep tells you which techniques slip through. --adaptive tells you the story: it sequences techniques by chasing coverage - open an untested tactic first (breadth), then pile onto a tactic that already shows a detection gap (depth) - building a realistic kill-chain instead of an alphabetical list. It writes two extra artifacts, attack-path.json and a rendered attack-path.md.
redgap run --adaptive               # deterministic, offline - no API key needed
redgap run --adaptive --llm         # a model chooses the order and when to stop
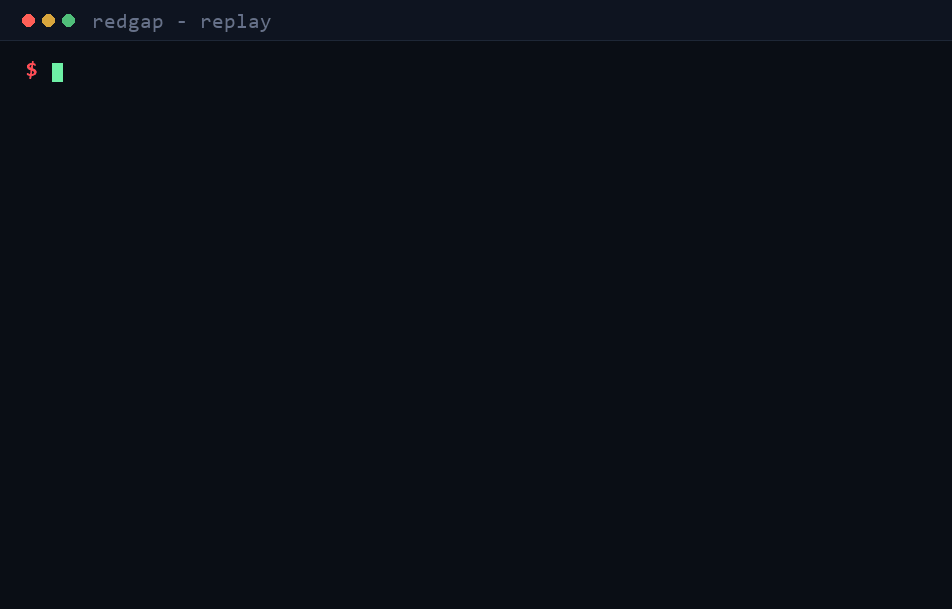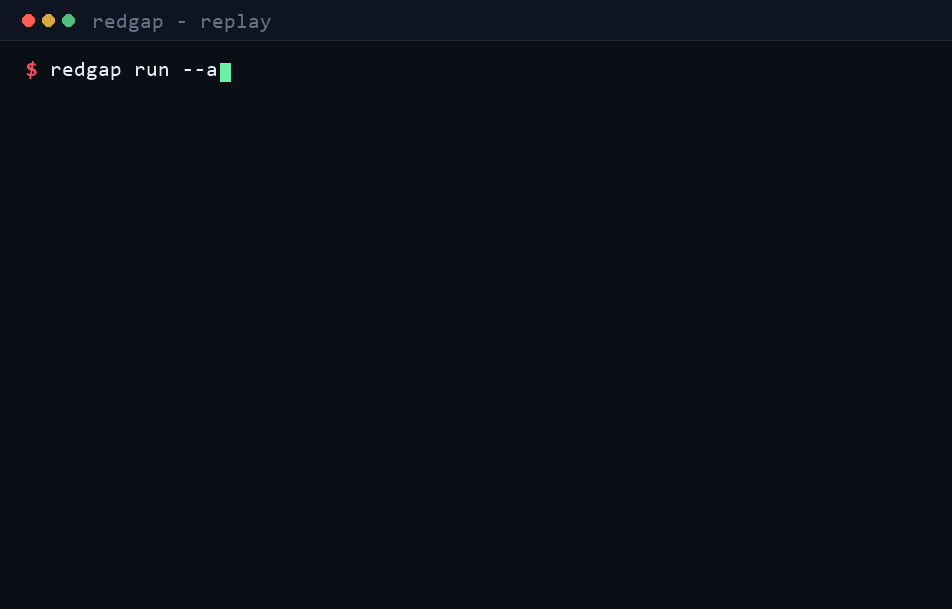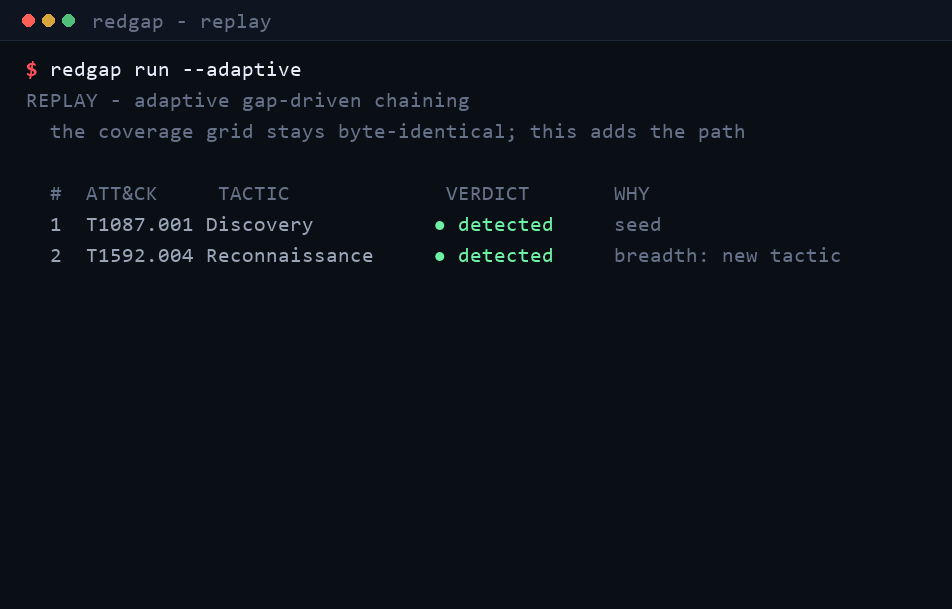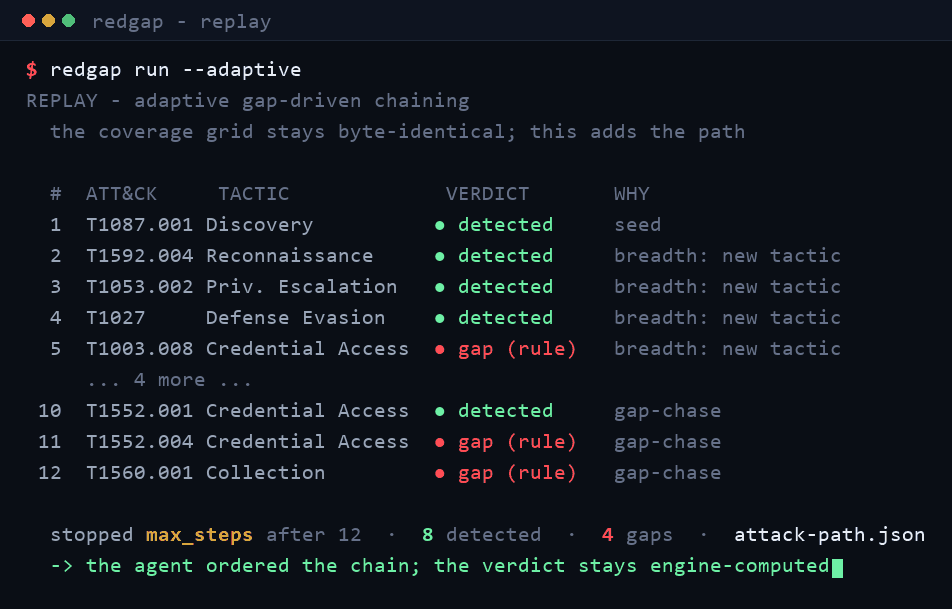
The same run, on the dashboard - a kill-chain ribbon where breadth reads left-to-right across the tactics and the gap-chase piles downward under the two bleeding tactics (their spine rings glow red). Every bead opens the same real-telemetry evidence drawer as the matrix:
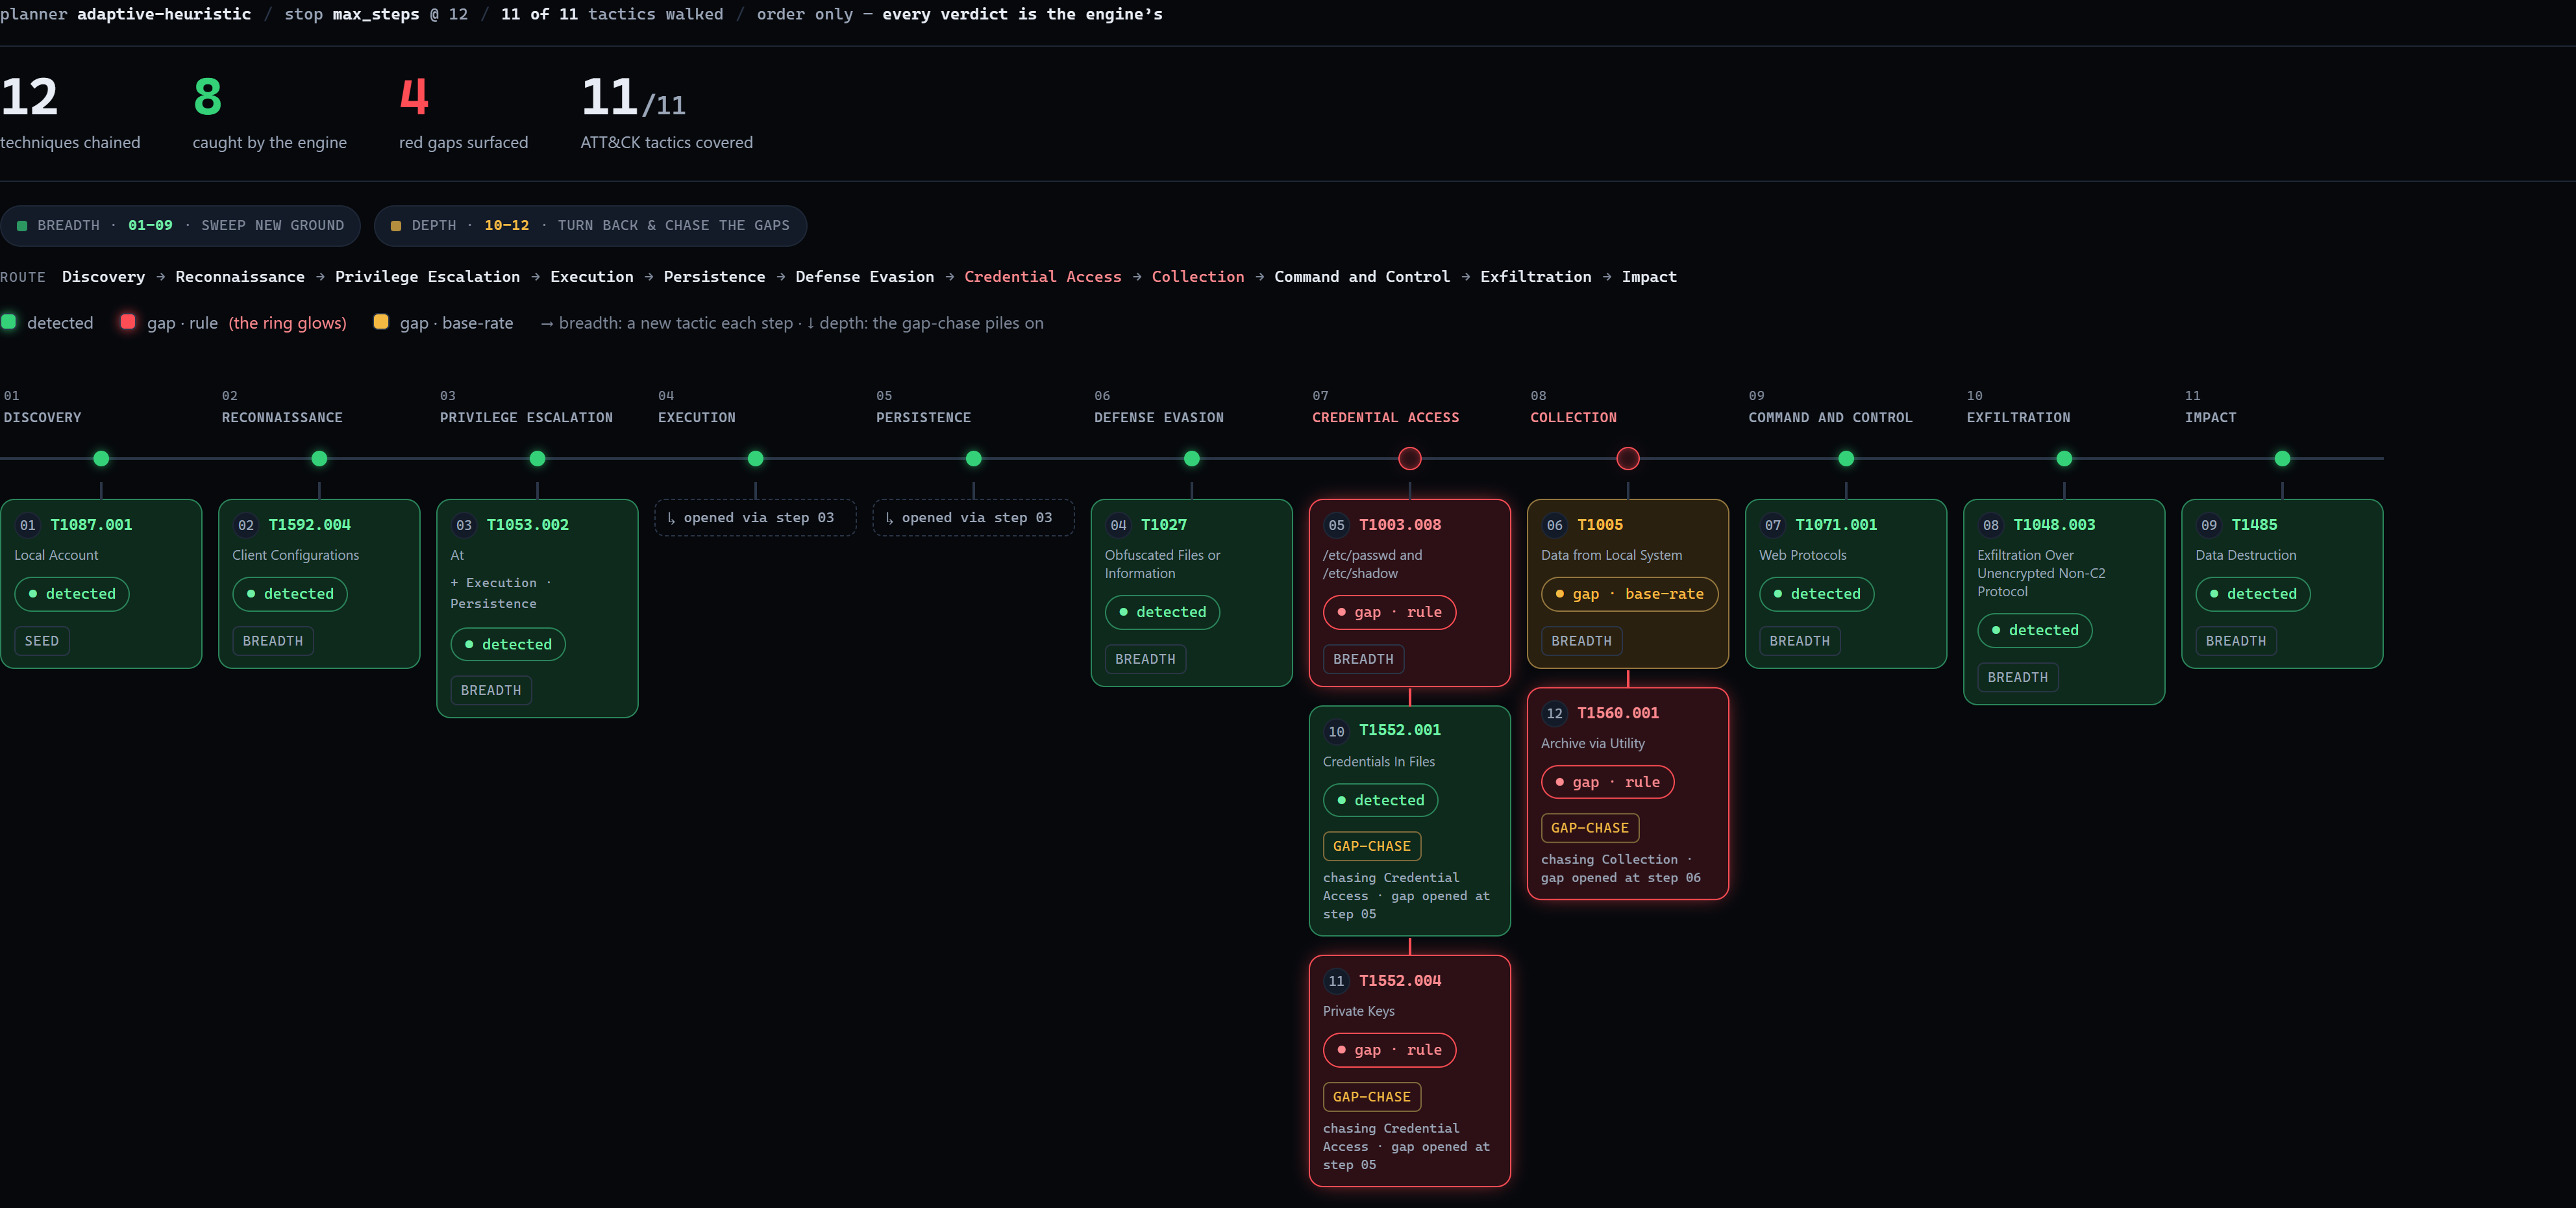
The trust boundary is unchanged, and this is the subtle part: the planner authors the order and the "why chosen" note - never a verdict. Every detected in the attack-path is copied from the deterministic verdict the engine already computed, so the narrative and the grid physically cannot disagree. The coverage grid (coverage.json) is byte-identical whether you run the default sweep or --adaptive, with or without --llm - a test asserts it. The model's one tool has no field to write a verdict into. See a committed example under docs/samples/adaptive/.
The dashboard
The same coverage as an interactive page - befnoz.github.io/redgap. The full ATT&CK grid, detected in green, rule-gaps in red, base-rate gaps in amber:
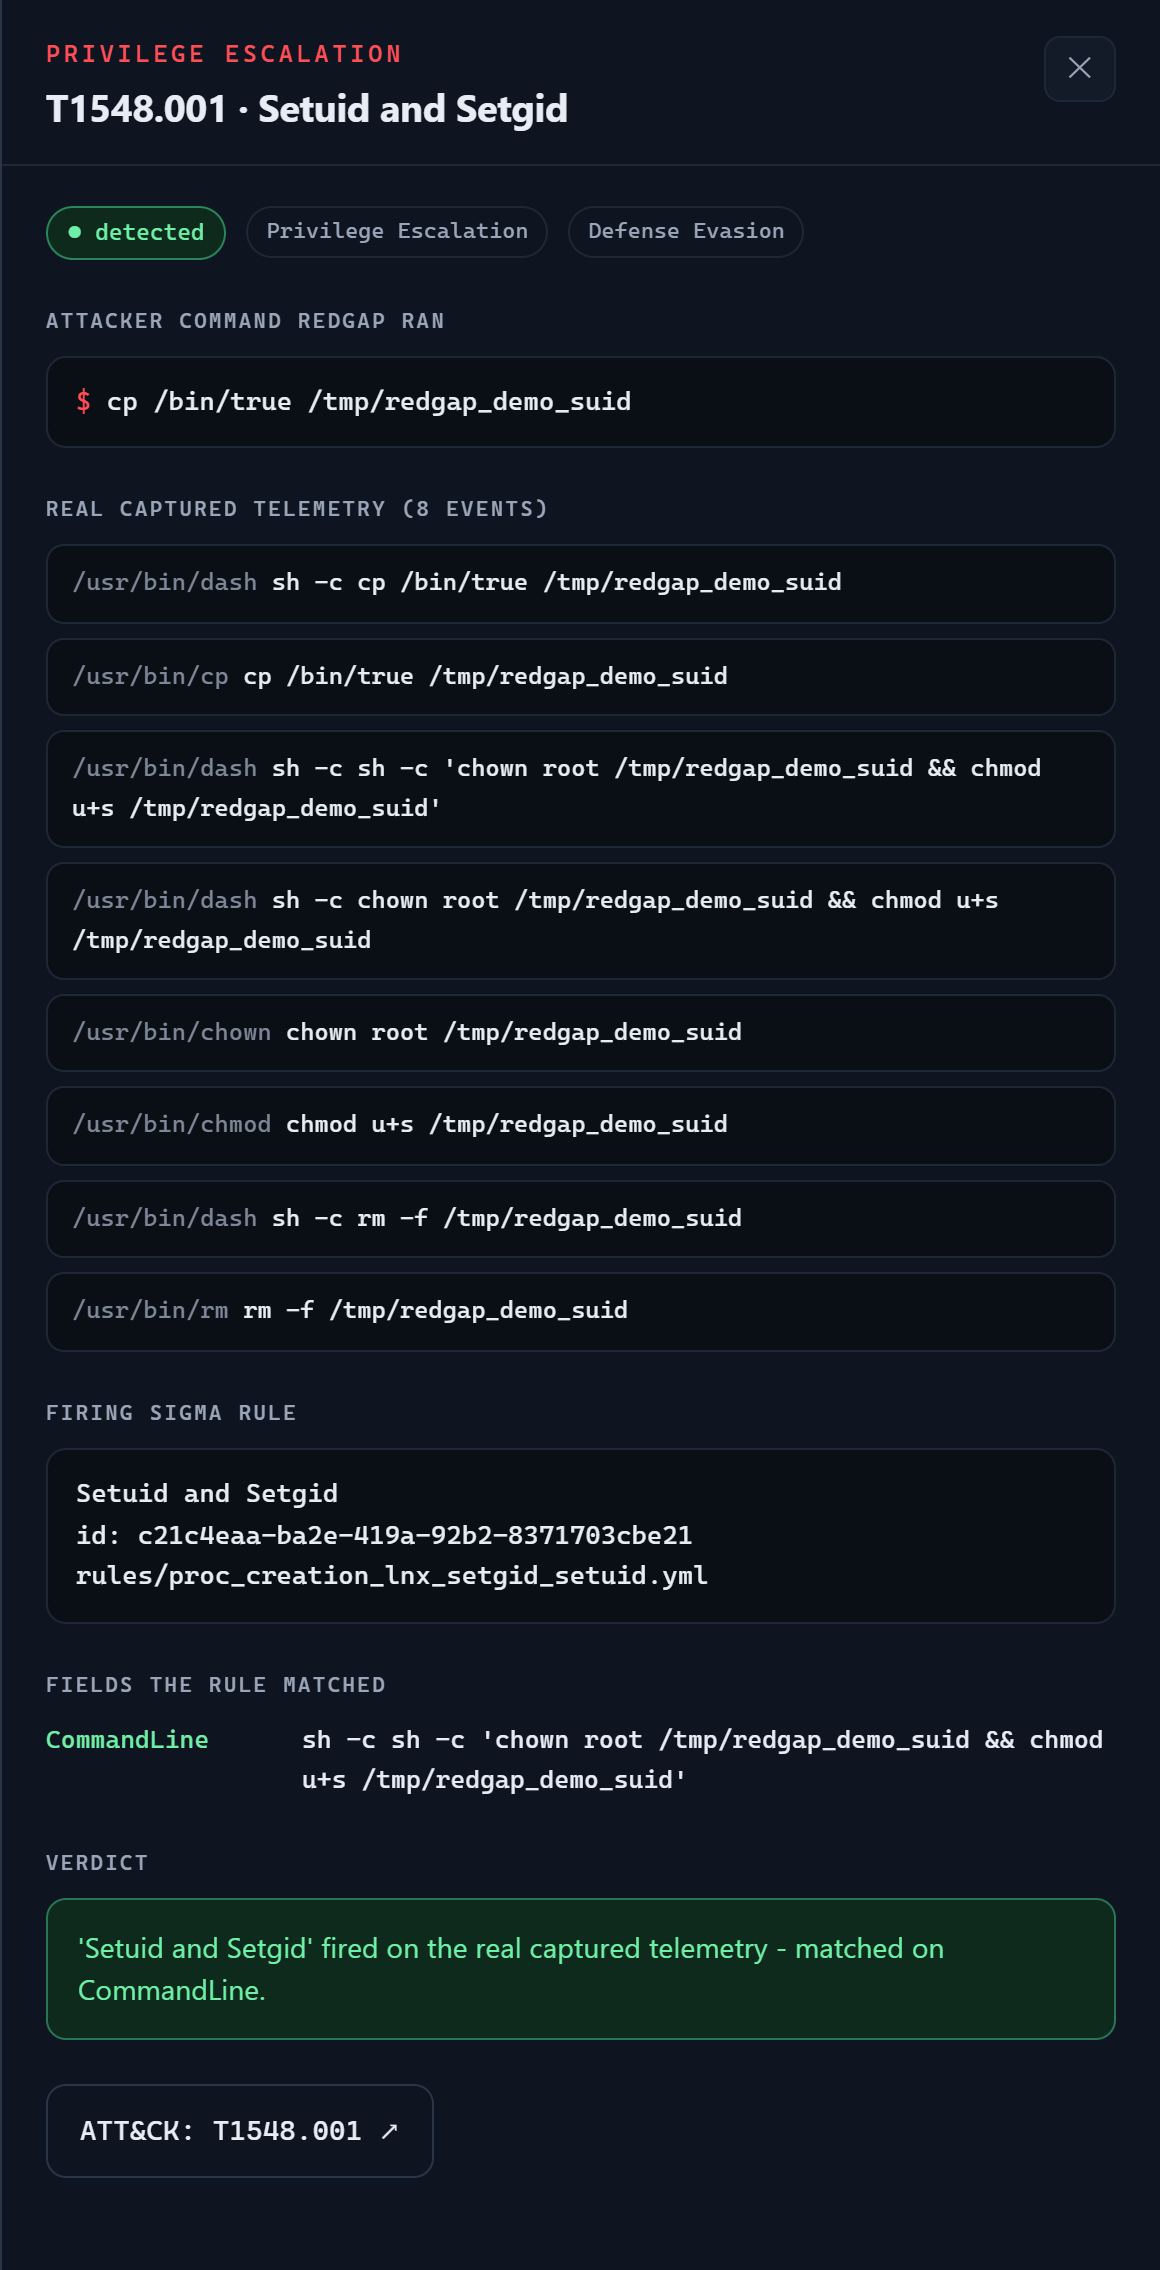
Click any technique and the Detection Playground opens the real evidence behind the verdict - the attacker command RedGap ran, the captured telemetry, the firing Sigma rule, and the exact fields it matched:
Drop your own out/coverage.json on the page to render your gap grid entirely in the browser - nothing is uploaded.
Bring your own rules - redgap audit
RedGap ships a demo rule set, but the real workflow is your rules. Point it at your own Sigma directory and it scores every one of RedGap's real-telemetry techniques against them, fully offline:
redgap audit --rules ./my-sigma/                    # your ATT&CK coverage + a rule-health scorecard
redgap audit --rules ./my-sigma/ --fail-under 20    # CI gate: fail the build if coverage drops below N
You get your own coverage grid (drops straight into ATT&CK Navigator) plus a per-rule scorecard that buckets every rule you own:
- firing - matched real captured telemetry, with the exact event and fields as evidence.
- SILENT - tagged to a technique but never fires on real exec data: false confidence. A rule can pass
sigma check(static validation lints the rule text and its tags) and even match a sample log its author wrote, yet still do nothing on real captured telemetry - and neither static validation nor an author-written test runs the rule against independently captured events, so neither can surface it. - out-of-corpus / unevaluable - reported honestly, never scored pass/fail.
Every classification is a boolean from the same deterministic (events, rules) engine - no model ever touches it.
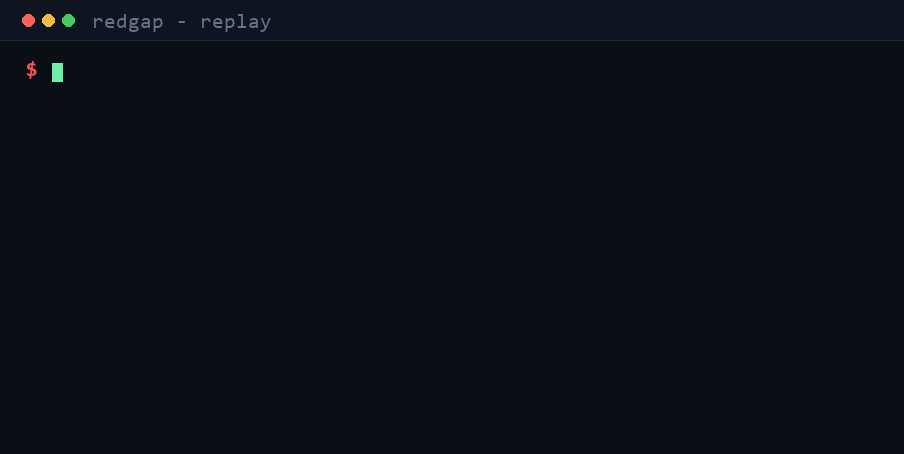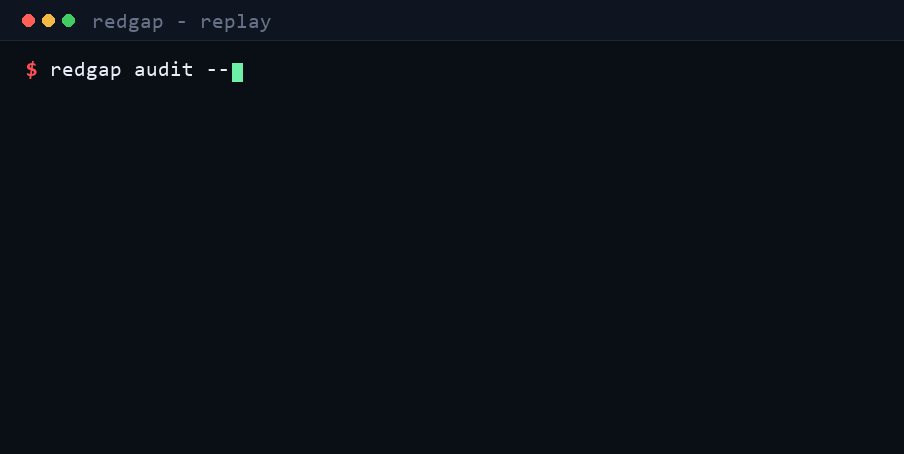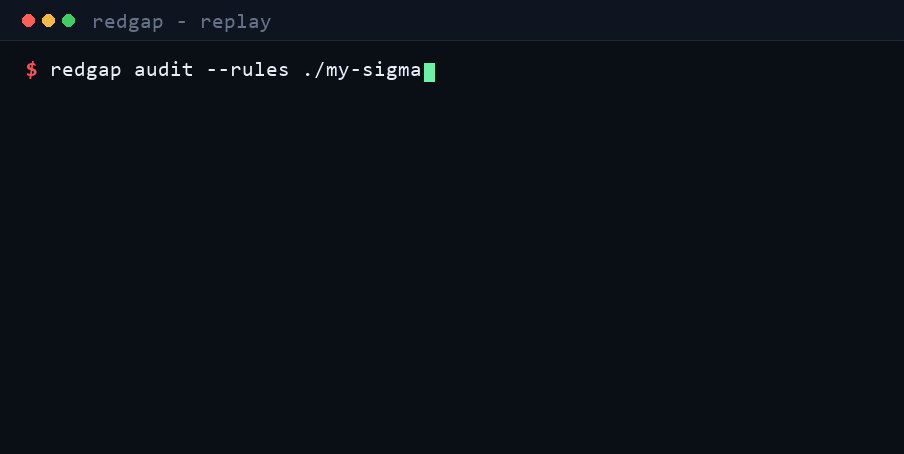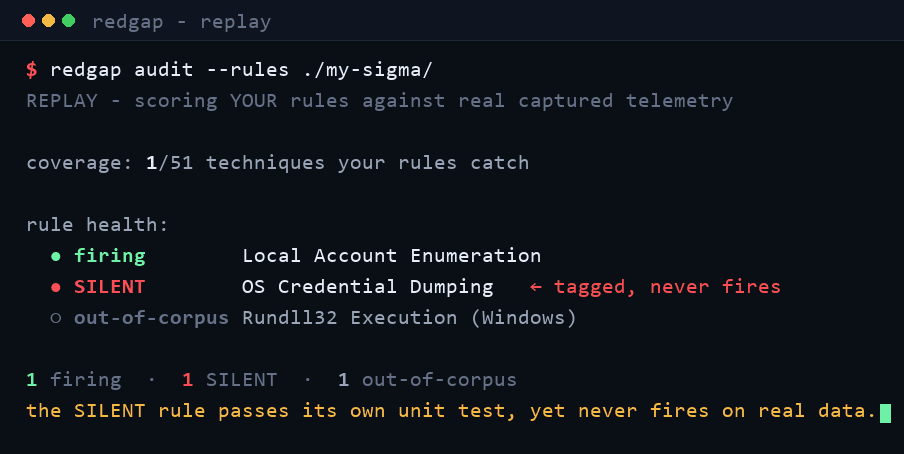
See it catch a SILENT rule. examples/my-sigma/ ships three rules - one that fires, one tagged-but-silent, one out-of-corpus. Run it against RedGap's real telemetry:
redgap audit --rules examples/my-sigma
(examples/ lives in the source tree, not the installed wheel - run this from a git clone of the repo, or pip install -e ..)
Let a model draft the missing rule - and let the engine judge it. redgap suggest (opt-in, needs a key) asks an LLM to write a candidate Sigma rule for each rule-gap, then the deterministic engine re-runs it and reports whether it actually closes the gap, no_fires, is over_broad, or forgot the ATT&CK tag. The model writes rule text; only the engine grants green - the same trust boundary, made literal.
redgap suggest # LLM drafts, engine judges (never the other way round)
The OS Credential Dumping rule looks like coverage - it is tagged to the right technique and passes static validation - yet it never fires on real Linux telemetry (it only matches a Windows tool name). That is the SILENT bucket: false confidence that linting the rule text cannot surface, because it never runs the rule against real events.
How it compares
RedGap does not replace the tools below - it closes a loop each of them leaves open, and because its rules are standard Sigma they run inside the detection tools unchanged. The honest picture:
| Capability | sigma-cli |
Atomic Red Team | Zircolite | RedGap |
|---|---|---|---|---|
| Executes benign ATT&CK techniques | - | ✅ (hundreds, cross-platform) | - | ✅ (51, local lab) |
| Captures telemetry with its own collector | - | - (your EDR does) | - (you supply logs) | ✅ |
| Runs Sigma rules against real events | - (lints / converts rule text) | - | ✅ | ✅ |
| Emits a detected-vs-gap coverage verdict | - | - | - | ✅ |
| Flags SILENT rules (pass validation, never fire) | - | - | - | ✅ |
| Gap taxonomy (rule vs base-rate) | - | - | - | ✅ |
| Chains techniques into a gap-driven attack path | - | - | - | ✅ |
| Reports detection depth (single point of failure) | - | - | - | ✅ |
Re-proves its own numbers offline (redgap verify) |
- | - | - | ✅ |
They are complementary, not competitors. sigma-cli lints (sigma check) and converts
(sigma convert) your rules but never runs them against events; Atomic Red Team is a far
larger cross-platform attack
library that generates real telemetry for your own EDR to judge; Zircolite runs Sigma at
forensic speed over logs you already have - and since RedGap's rules are plain Sigma, they
run unchanged in Zircolite. RedGap's niche is closing the whole loop deterministically for
a fixed technique set, which is what lets it compute coverage and surface the SILENT rules
the others have no reason to look for.
Ethics & scope
⚠️ RedGap attacks only its own disposable local lab. There is deliberately no free-form target flag; the live lab runs with no network, and every container launch is gated at runtime by an allowlist (assert_lab_only) that the test suite proves cannot be widened. Every technique is a benign, published Atomic-Red-Team-derived detection test with no exploit payload, no off-box action, and no runtime downloads. See ETHICS.md, SCOPE.md, and SECURITY.md.
Not shipped: weaponizable breadth, real exploits, credential material, or anything that runs against a system you do not own.
Roadmap (honest next steps)
- Effect / syscall-level detection (e.g.
utimensatfor timestomp) via a higher-fidelity collector. - Correlation rules (turn the base-rate gap into a real detection).
- Portability: the rules are standard Sigma, so they already run unchanged in Zircolite or any SIEM.
License
MIT - see LICENSE. Third-party attributions in NOTICE. ATT&CK® is a registered trademark of The MITRE Corporation.
1 maintainer

Metadata
1 maintainer
Release files for redgap 1.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| redgap-1.1.1.tar.gz | 2.6 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| redgap-1.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.8 MB
Release files / redgap-1.1.1.tar.gz
| Download URL | redgap-1.1.1.tar.gz |
|---|---|
| Size | 2.6 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5fbf11a7fc34ce942cd2558d419b577e0f632374810c8c2328a9f5714a16c3ce
|
|
BLAKE2b-256 checksum How to use checksums |
77370cf6e4b99adea5536b3ce980c50f01f7604f1a73e433991d1015503b171c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 22, 2026.
Transparency logRelease files / redgap-1.1.1-py3-none-any.whl
| Download URL | redgap-1.1.1-py3-none-any.whl |
|---|---|
| Size | 200.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
436c05e2803dbaa6ab232b0ea96798269ea38a53d35fb534caeed204ea498fd2
|
|
BLAKE2b-256 checksum How to use checksums |
3dc9918f3e15080b76467d23fe41a7206139a6061d355253e3b4058bbfd67581
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 22, 2026.
Transparency log













