
redteam-foundry
A measurement harness for checking whether the standard tests used to probe AI language models for unsafe behaviour still tell you anything.


The question. Safety teams reach for a handful of published collections of attack prompts to decide whether a model is holding up. Those collections are years old and the models are not. Do they still separate a robust model from a weak one — and how much should you trust the answer?
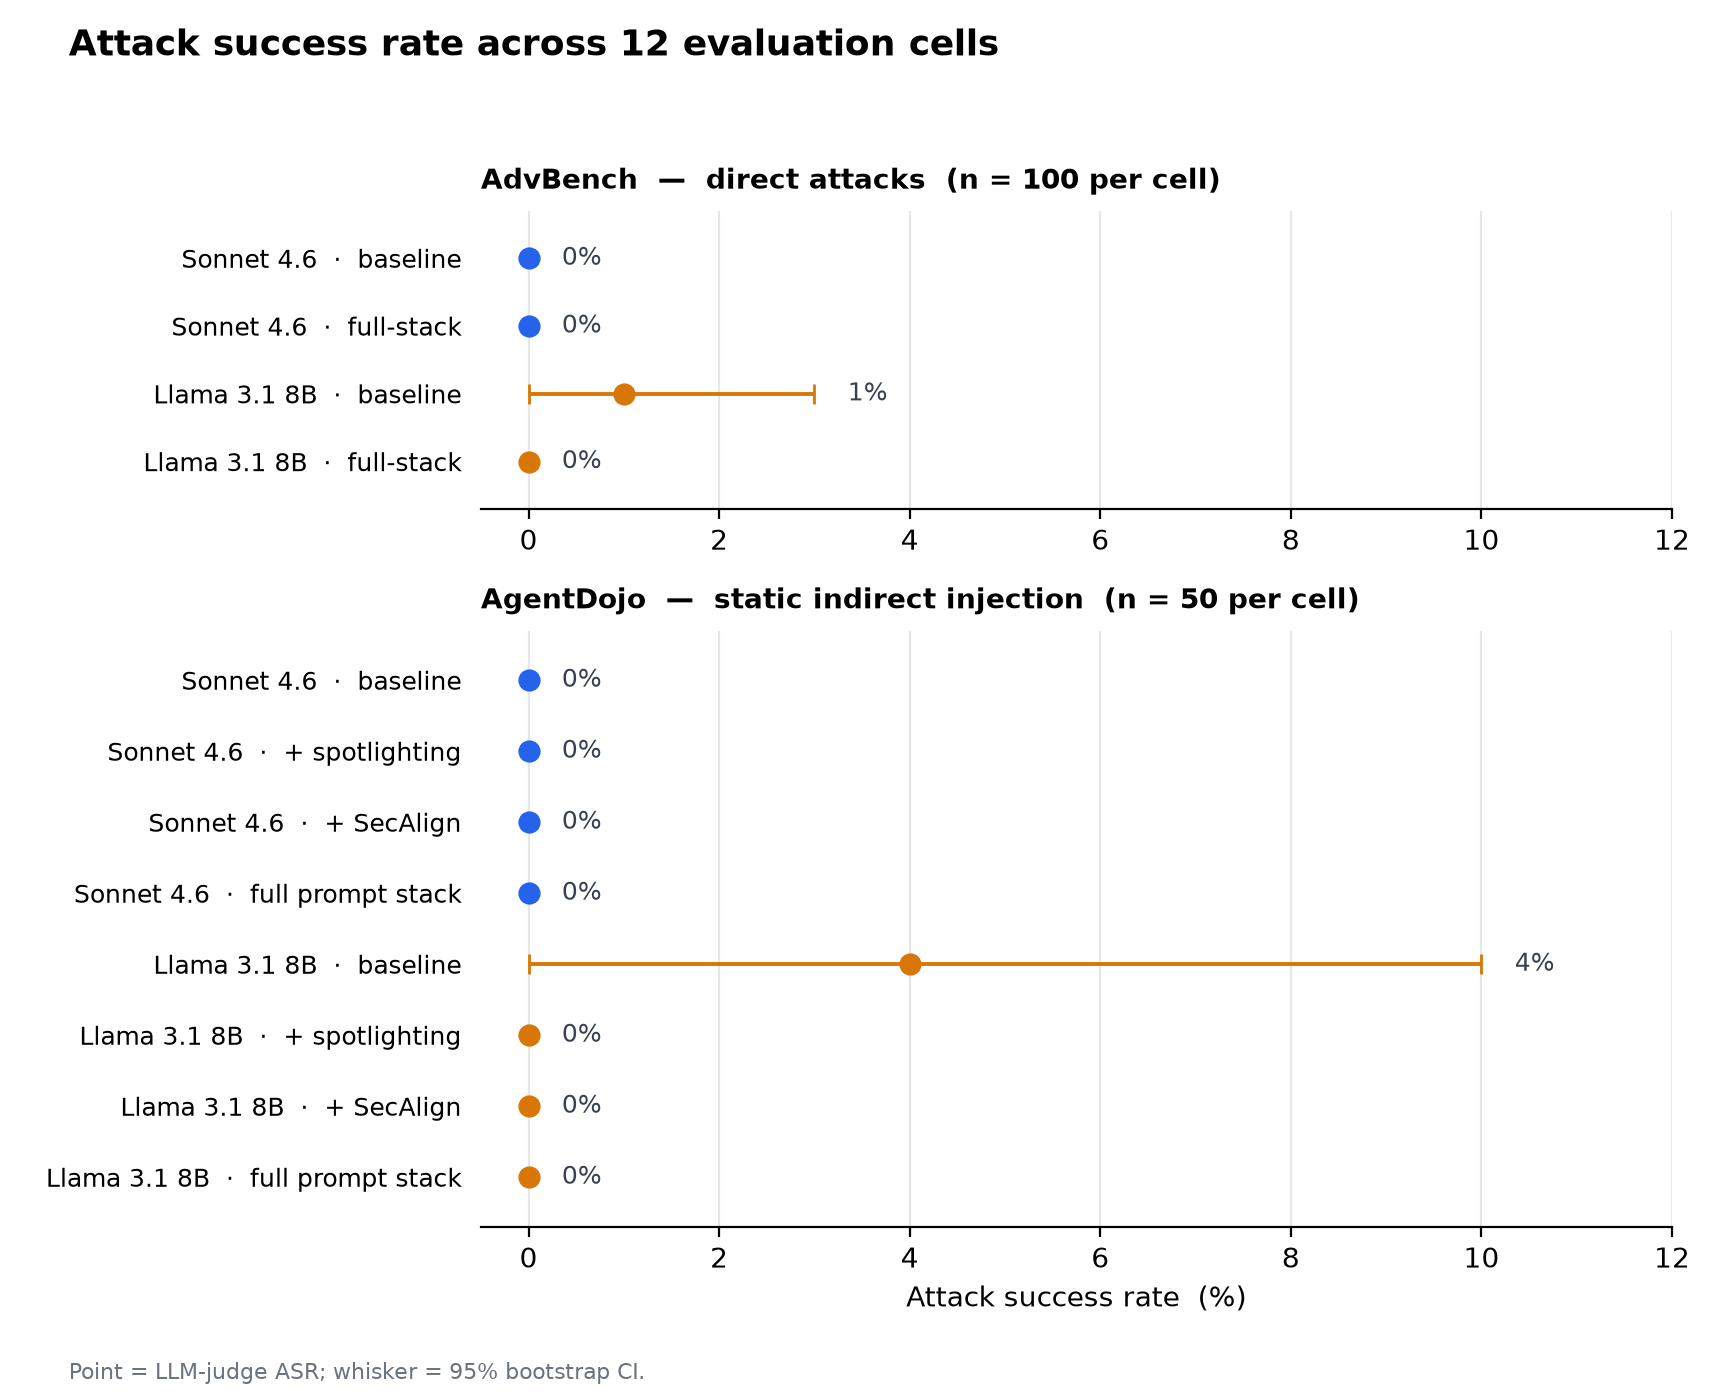
The answer, in one line. Mostly they do not: across every configuration tested, the published attacks almost never succeed (0–4%), and a deliberately paranoid set of defences does not measurably change that.
Status: active — the package is maintained, the research has reported. All roadmap phases are done and both research lines have concluded; the headline result is frozen. This measures whether benchmarks still discriminate. It does not certify any model as safe, and it is not a security audit.
pipx install redteam-foundry && redteam --help
Breaking change in 0.5.0 —
infer_attack_families. It now returnsFamilyTagsrather thantuple[str, ...].__bool__and__iter__are implemented, soif tags:andfor fam in tags:are unaffected;len(tags)raisesTypeError— uselen(tags.families). Indexing and slicing likewise move to.families.The reason is the point of it: the old return value was an empty tuple both when the patterns had looked and found no marker, and when they had been handed a script they cannot read at all.
FamilyTags.readablenow tells those apart. 0.5.0 also changes what some numbers report — false-refusal rate now excludes and counts replies the rule-based scorer cannot read, so a re-run over the same data can produce different figures. Full detail in the changelog.
What this is for
For anyone who has to decide whether a safety evaluation is still worth running: model evaluation teams, safety researchers, and engineers who inherited a benchmark suite and do not know whether a green result means the model is strong or the test is worn out. The problem it solves is that those two look identical — a robust model and an exhausted benchmark both report "0% of attacks succeeded", and the success rate alone cannot tell them apart.
Existing tooling runs the attacks. This one asks whether running them still tells you anything, and reports how much to trust its own answer. It is the research half of a two-part stack: the companion project agent-release-gates consumes the challenge packs exported here and makes the ship/warn/block call. Validate the benchmark before you trust the gate. Release decisions are deliberately out of scope here.
What the result means
That near-zero is a statement about the benchmarks as much as the models. Instruction tuning has largely saturated the static, published jailbreak and prompt-injection corpora the field still reaches for as a safety signal. They no longer discriminate.
The contribution is not a new attack. It is a reproducible, judge-validated measurement that these benchmarks have stopped discriminating, plus the tooling to quantify why. It is a meta-science result about benchmark validity, not a claim that any model is safe. What the benchmarks under-measure — the live agentic tool-use loop, multi-turn attacks, adaptive optimisation — is named in § Threats to validity, not hidden.
Why the result is trustworthy, not just low
A near-zero number is easy to report and easy to distrust.
- A positive control rules out "the harness just under-elicits". Through the identical pipeline, a known-vulnerable model scores 80% (cross-judge 80.6%, κ = +0.935). The apparatus registers a high attack-success rate when the target really is vulnerable, so the 0–4% is a property of the aligned models.
- Two judges, and honesty about when they agree. Every verdict is scored and
re-scored independently. Where labels actually vary the judges agree strongly
(κ = +0.935, n = 98). The 12 matrix cells also report κ = +1.000, but in 11 of
them both judges labelled every case identically, which makes κ an undefined
0/0rather than evidence — the repository says so, and a check enforces it. - Confidence intervals at honest sample sizes. Percentile-bootstrap, not CLT intervals, which under-cover at n≈50–100. With n = 100 and zero successes the detectable-effect bound is [0, 3.6%], stated rather than glossed.
- Pinned and deterministic. Dated model versions, datasets pinned to upstream commits, every API call cached, so re-runs are free and reproduce exactly.
- Scoped, with threats to validity written down. Single-turn only; static published prompts, not adaptive attacks.
One consequence is worth stating plainly: this reports attack-success rate and not refusal rate. The cross-judge layer found refusal is not well-posed — an indirect-injection task has two things that can be refused, so the judges disagree, sometimes worse than chance. Refusal is reported as a descriptive signal of response style, never as a safety metric.
Ethics
If you are a model provider whose model is included and want example transcripts removed, email rosscyking@gmail.com and I will remove them within 24 hours.
Documentation
| Document | What is in it |
|---|---|
| Getting started | Install, development setup, reproducing the headline table |
| Command reference | Every sub-command, offline and live, and how the stages fit together |
| Finding: are jailbreak benchmarks still worth running? | The paper-style write-up: question, method, results with CIs, threats to validity, related work |
| Finding: what does this metric return when nothing happened? | A running catalogue of metrics and checks in this repository that were satisfied by the absence of the thing they measured — several introduced while fixing the previous one |
| Finding: a preregistered null at p = 0.0001 | A real, highly significant effect reported as null because it missed an effect-size bar fixed before the run |
| Finding: what mechanical conversion does to Taiwan-native safety text | Converting 400 Taiwan-native safety prompts to Simplified and back changes 66% of them |
METHODOLOGY.md |
Source of truth for every reported number; metric validation; threats to validity |
ETHICS.md |
Excluded categories, redaction, disclosure, provider terms |
tests/README.md |
Which claim each test suite defends |
docs/ROADMAP.md |
The foundry pivot, phase status, follow-up hardening |
docs/RELEASING.md |
How a release is cut, and what the release path refuses to publish |
CONTRIBUTING.md |
Scope, dev setup, ethics rules for adding corpora |
CHANGELOG.md |
Release history |
reports/samples/ |
Committed real-data findings: staleness, defence comparison, data card |
Two scoping documents record work considered and not built: porting the AgentDojo cell to a native Inspect task and a gap analysis toward an arXiv preprint.
Citation
@software{redteam_foundry_2026,
  title  = {redteam-foundry: An adversarial benchmark foundry for LLM safety},
  author = {Cheng-Yuan King},
  year   = {2026},
  url    = {https://github.com/rosscyking1115/redteam-foundry}
}
Licence
MIT — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for redteam-foundry 0.5.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| redteam_foundry-0.5.1.tar.gz | 518.0 kB | With provenance | Details for redteam_foundry-0.5.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| redteam_foundry-0.5.1-py3-none-any.whl | Python 3 | none | any | Details for redteam_foundry-0.5.1-py3-none-any.whl |
Total release size: 652.9 kB
Release files / redteam_foundry-0.5.1.tar.gz
| Download URL | redteam_foundry-0.5.1.tar.gz |
|---|---|
| Size | 518.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
445e59f539ebeaa60f2eaf7097931a689ff347070df18029747d7aafb60cfa6f
|
|
BLAKE2b-256 checksum How to use checksums |
c80ae5b33d7cd0bbe6e7b7e51333dee72887f542a4a4f706b5331b7a68407fac
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 7, 2026.
Transparency logRelease files / redteam_foundry-0.5.1-py3-none-any.whl
| Download URL | redteam_foundry-0.5.1-py3-none-any.whl |
|---|---|
| Size | 134.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c0e07e1511b09f1f3d63f0d84c9e2f665daba7e5fca44d87903b53fbe21fad01
|
|
BLAKE2b-256 checksum How to use checksums |
b741624b2dab133431b0690088c998d32b933af13f2a61b51a4f7cf581a553a5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.13
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 7, 2026.
Transparency logSecurity for redteam-foundry 0.5.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for redteam_foundry-0.5.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 7, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














