




regeval
pytest, but for LLM prompts.
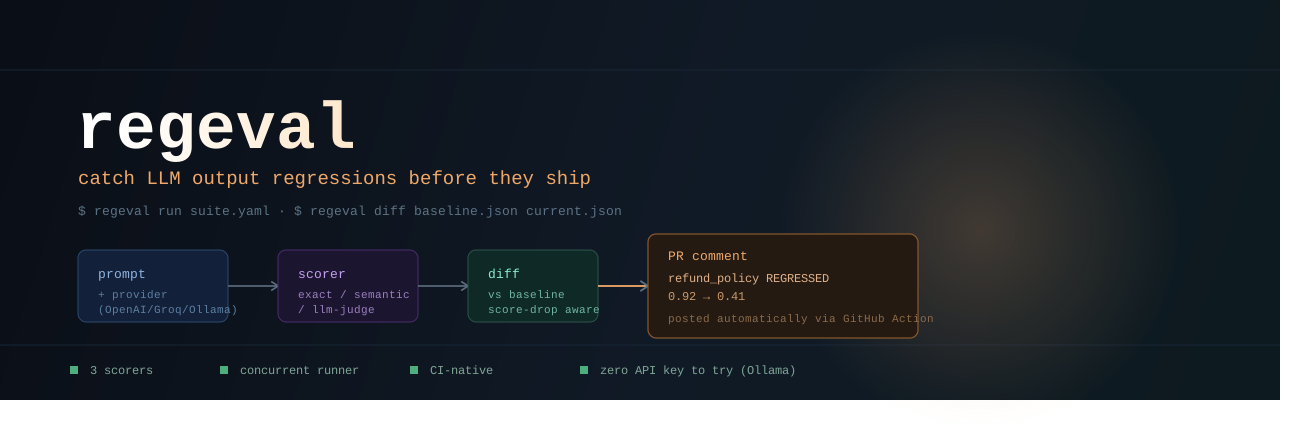
Catch LLM output regressions before they ship. Write down what "correct" looks like once, then automatically check it every time a prompt, model, or pipeline changes — locally, or as a comment on every pull request.
Table of contents
- The problem
- Quickstart (zero API key needed)
- Real example output
- How it works
- Three scorers, three use cases
- GitHub Action
- Installation
- Roadmap
- Contributing
- Security
- Support
- License
The problem
You tweak a system prompt to handle a new case. It works for that case. Did it silently break something else? Right now, almost nobody actually checks — they ship it and find out from a confused customer or a Slack message. regeval turns "did I break anything" from a guess into an actual, automated answer.
Quickstart (zero API key needed)
regeval works against any OpenAI-compatible API — including Ollama running locally, so you can try the entire tool for free, with no signup:
pip install regeval
ollama pull llama3

regeval init
regeval run regeval.suite.yaml
     Example suite — 2/2 passed
┏━━━━━━━━━┳━━━━━━━━┳━━━━━━━┳━━━━━━━┓
┃ Case    ┃ Status ┃ Score ┃  Time ┃
┡━━━━━━━━━╇━━━━━━━━╇━━━━━━━╇━━━━━━━┩
│ math    │  PASS  │  1.00 │ 0.35s │
│ capital │  PASS  │  1.00 │ 0.60s │
└─────────┴────────┴───────┴───────┘
All cases passed.
Real example output
Not a mockup — actual output from examples/semantic_similarity_suite.yaml run against a local llama3 model. Notice the model's phrasing doesn't match the expected text word-for-word, and the scorer correctly recognizes it's still right:
expected: "Gravity is the invisible force that pulls things toward
           each other, like what keeps your feet on the ground."

actual:   "Gravity is a magic force that pulls everything towards each
           other, like a big hug from the Earth, and it's what keeps
           you from floating off into space when you're playing outside!"

score: 0.879   →   PASS (threshold 0.75)
exact_match would have failed this outright. semantic_similarity correctly recognized the meaning matches even though not a single sentence is shared.
For genuinely nuanced cases, llm_judge gives you reasoning, not just a score:
case: explain_tradeoff
score: 0.80
reasoning: "The actual response accurately captures the main tradeoff
            between hash tables and sorted arrays, but does not exactly
            match the expected result in terms of the specific lookup
            times mentioned."
How it works
- Write a YAML suite: prompts, expected results, which scorer to use.
regeval run suite.yamlcalls your provider concurrently for every case (real thread pool, bounded, not sequential), scores each result, and shows a live progress bar.- Save the result as your baseline:
--output baseline.json. - Change your prompt. Run again:
--output current.json. regeval diff baseline.json current.json— flags anything that regressed, including cases that are still technically passing but whose score quietly dropped.- Wire the included GitHub Action into your CI so this happens automatically on every pull request, with the report posted as a comment.
Three scorers, three use cases
| Scorer | Best for | How it works |
|---|---|---|
exact_match |
Answers that should be identical every time (support email, fixed facts) | String equality, optional case/whitespace normalization |
semantic_similarity |
Answers where wording varies but meaning shouldn't (policy explanations) | Embedding cosine similarity via your provider's /embeddings endpoint |
llm_judge |
Nuanced quality judgments (tone, completeness, correctness of reasoning) | A second model call grades the output 0-10 with a one-sentence reason |
GitHub Action
Included in this repo at .github/actions/regeval-action — runs your suite, diffs against a stored baseline, and posts the result as a PR comment automatically:
- uses: raoamogh/regeval/.github/actions/regeval-action@main
  with:
    suite: evals/support_bot.suite.yaml
    baseline: evals/baseline.json
    api-key: ${{ secrets.OPENAI_API_KEY }}
Full example: examples/github-workflow-example.yml.
Installation
pip install regeval                # core
pip install regeval[caching]       # + flightlock integration, dedupes identical prompts across reruns
Roadmap
- Provider interface (OpenAI-compatible: OpenAI, Groq, OpenRouter, Ollama)
- Three scorers: exact match, semantic similarity, LLM-as-judge
- Suite YAML loading with actionable validation errors
- Concurrent execution engine
- Regression diff with score-drop-threshold detection
- Rich terminal reporting
- CLI (
init,run,diff) - GitHub Action for automated PR comments
- flightlock-backed call caching (in progress)
- Publish to PyPI
- Async provider support
Contributing
See CONTRIBUTING.md.
Security
See SECURITY.md.
Support
See SUPPORT.md.
AI-assisted development
See AI_POLICY.md for how AI pair-programming was used in building this project, and what's expected of contributors.
License
MIT — see LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for regeval 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| regeval-0.1.0.tar.gz | 33.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| regeval-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 55.8 kB
Release files / regeval-0.1.0.tar.gz
| Download URL | regeval-0.1.0.tar.gz |
|---|---|
| Size | 33.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cf2366a551f5dff899c5fe0505dcb983948cb4df71858661ab5e5f80021e9625
|
|
BLAKE2b-256 checksum How to use checksums |
668af9a98f9161d02715b4152edf6cdc2b5d3dd4c9e3f2ec93a4a4900d11ff7c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|
Release files / regeval-0.1.0-py3-none-any.whl
| Download URL | regeval-0.1.0-py3-none-any.whl |
|---|---|
| Size | 21.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
98962eef7ec9ee002f99df764c9417bf047761adee24cc0d25027000ca783094
|
|
BLAKE2b-256 checksum How to use checksums |
a926b24a5498f5354fce72e06a688cbf3372da9a798d25d984957bc43a033cc9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|













