
This release is a pre-release and may not be stable for production use.

Lightweight vector index extension for the open lakehouse stack.


Quick Start | Why Relify | Compute Engines | Benchmarks | Documentation
Relify is an open-source Python and Rust library for indexing and searching lakehouse data with the compute engines you already use. It stores vector indexes as open Parquet or Iceberg tables, allowing DataFusion, StarRocks, and Spark to query them directly with SQL while source data stays where it is.
Relify targets analytical and offline vector workloads such as large-k retrieval, similarity joins, and vector search composed with analytical queries. Dedicated vector databases remain the better fit for latency-sensitive, high-concurrency online serving.
Quick Start
Relify supports standard CPython 3.11 through 3.14 on Linux x86_64 and macOS arm64. Install the embedded DataFusion and Parquet path:
python -m pip install relify
Spark and StarRocks are optional integrations with separate setup; see Compute Engines.
From a new working directory, build an IVF-Flat index over the dataset included in the package and run a filtered vector query:
import relify

session = relify.connect("./relify-data")
session.register_parquet("documents", relify.datasets.uri("documents"))
documents = session.table("documents")

documents.create_index(
    "documents_embedding",
    column="embedding",
    key=["document_id"],
    config=relify.IVF(nlist=3),
)
documents.wait_for_index("documents_embedding")

query = (
    documents.search([0.2, 0.0], column="embedding")
    .where("tenant_id = 42 AND status = 'published'")
    .nprobes(3)
    .limit(3)
    .select(["document_id", "title", "category"])
)

print(session.collect(query).to_pylist())
Vector search remains a relation rather than a terminal service call. Keep the query lazy, register it as a DataFusion view, and continue with SQL in the same execution context:
session.register_parquet(
    "document_stats",
    relify.datasets.uri("document_stats"),
)
session.register_view("vector_hits", session.to_dataframe(query))

summary = session.sql("""
    SELECT
        h.category,
        COUNT(*) AS matches,
        AVG(h._distance) AS avg_distance,
        MAX(s.popularity) AS max_popularity
    FROM vector_hits AS h
    JOIN document_stats AS s USING (document_id)
    GROUP BY h.category
    ORDER BY h.category
""")
print(summary.to_pydict())
The packaged dataset makes this example self-contained. The getting-started guide covers persistent tables, existing indexes, query inspection, and source schema requirements.
Why Relify
- Zero ETL into a vector database. Source vectors stay in their existing lakehouse tables; Relify writes only index data and metadata.
- One open vector index. IVF centroids and postings are ordinary relational data, published as Parquet datasets or Iceberg tables rather than an engine-owned binary artifact.
- Across compute engines. Engine-specific backends consume the same index model and query contract instead of maintaining a separate copy per runtime.
- SQL-native execution. Cluster pruning, source filtering, joins, distance computation, and top-k remain inside the host engine's relational plan.
Compute Engines
| Engine | Model | Current capability | Status |
|---|---|---|---|
| DataFusion | Embedded | Build and query Parquet indexes in one Python process | Supported |
| Spark Classic | Batch | Build Iceberg indexes; query Parquet and Iceberg | Experimental |
| StarRocks | OLAP | Query Spark-built Iceberg indexes over Arrow Flight SQL | Experimental |
DataFusion is the default backend. Spark and StarRocks live under
relify.experimental and require caller-managed engines and catalog
configuration. All three use the same query model and open index metadata.
See the local, Spark, and StarRocks guides for installation and configuration.
How It Works

Source rows remain in their original Parquet or Iceberg table. Building an IVF-Flat index writes only portable metadata, centroids, and postings as open table data.
At query time, an engine-specific adapter binds the source and index to DataFusion, StarRocks, or Spark. The engine performs candidate pruning, source filtering, distance calculation, top-k, and subsequent analytical SQL in its own runtime.
The open index specification defines the shared schema and query semantics; the architecture guide describes the implementation boundaries.
Benchmarks
The current reproducible benchmark compares persisted, single-node IVF-Flat construction and memory-resident large-k search on one million 128-dimensional vectors. It ran on a 10-core Apple M4 with 16 GB of unified memory.
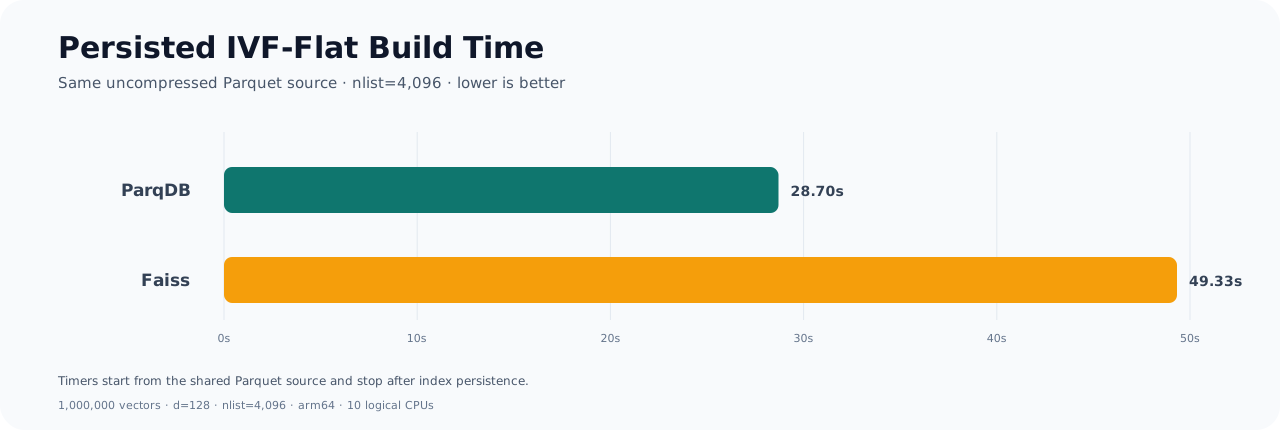
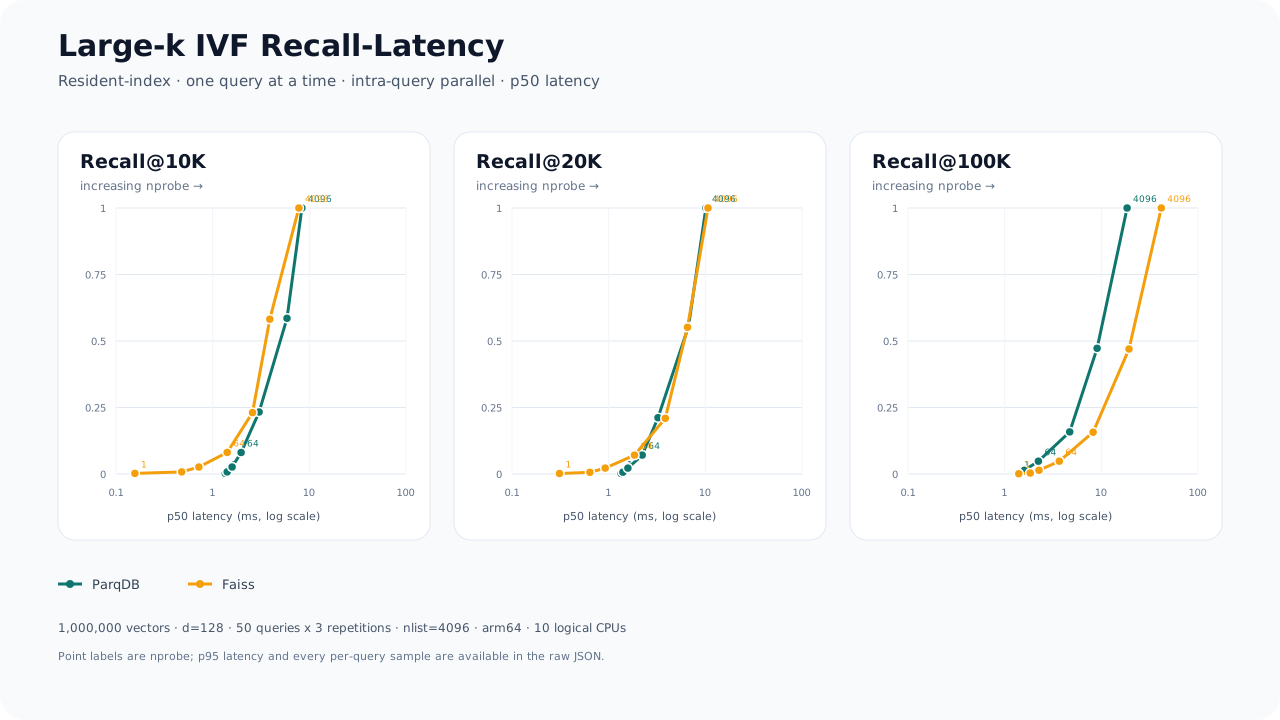
Both implementations start from the same uncompressed Parquet source. Query
measurements use one query at a time, nlist=4,096, increasing nprobe, and
k=10,000, 20,000, and 100,000. See the
methodology and raw results
for complete measurements.
Documentation
- Getting started and Python examples
- Core concepts, architecture, and open index specification
- Python API and configuration
- Current limitations, troubleshooting, and roadmap
TEngineDB-V
Relify began as the open-source research prototype behind TEngineDB-V. The project now develops those ideas into a general-purpose vector extension for the open lakehouse stack.
Development
Relify uses uv, Maturin, Cargo, and a small Makefile orchestration layer:
make sync
make develop
make check
See CONTRIBUTING.md for quality gates, fixtures, benchmarks, and contribution guidelines.
License
Relify's original code is available under the MIT License. Wheels include the vendored DataFusion Python binding under Apache-2.0; see the third-party notices.
Relify builds on work from LanceDB, DataFusion, DuckDB, StarRocks, Apache Spark, and Apache Iceberg, with gratitude to their contributors and communities.
1 maintainer

Metadata
1 maintainer
Release files for relify 0.1.0rc2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Built distributions (wheels)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| relify-0.1.0rc2-cp310-abi3-manylinux_2_28_x86_64.whl | CPython 3.10 | abi3 | Linux glibc 2.28+ x86-64 | Details |
| relify-0.1.0rc2-cp310-abi3-macosx_11_0_arm64.whl | CPython 3.10 | abi3 | macOS 11.0+ ARM64 | Details |
Total release size: 131.2 MB
Release files / relify-0.1.0rc2-cp310-abi3-manylinux_2_28_x86_64.whl
| Download URL | relify-0.1.0rc2-cp310-abi3-manylinux_2_28_x86_64.whl |
|---|---|
| Size | 68.7 MB |
| Tags | CPython 3.10 Linux glibc 2.28+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
e86e6b0518b6220fcd7a6e1ff818590de5bb2553b3bbbf959567c58ff9539343
|
|
BLAKE2b-256 checksum How to use checksums |
65d6fb1caeaad68db2ce5e3376864e623a2dceca8a51ca206d44281e3eb5cb25
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 4, 2026.
Transparency logRelease files / relify-0.1.0rc2-cp310-abi3-macosx_11_0_arm64.whl
| Download URL | relify-0.1.0rc2-cp310-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 62.6 MB |
| Tags | CPython 3.10 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
0935f536de06744076893b7a6da55690a7906cb2c757974895c4185af028d464
|
|
BLAKE2b-256 checksum How to use checksums |
90f00a50142251404c53cac6b0d94ef88c27c69be388371526b8db4b63616918
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 4, 2026.
Transparency log













