
Re:Max / Re:Dr
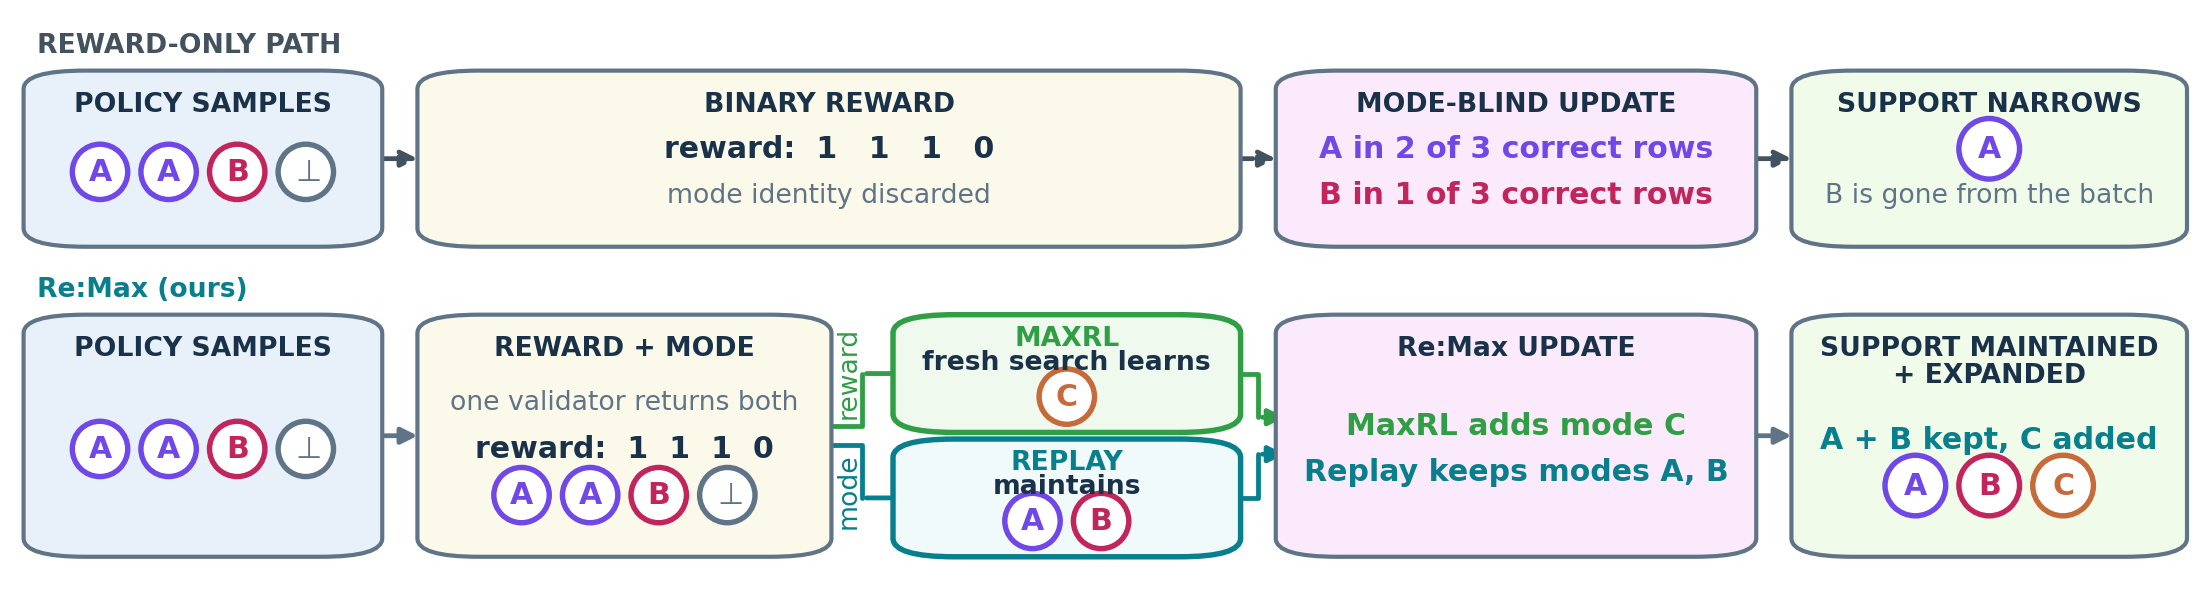
Retain and rehearse the correct solution modes a policy discovers. Re:Dr adds verified replay to Dr.GRPO; Re:Max adds it to MaxRL. A prompt-local bank stores verified exemplars discovered during training and rehearses their modes uniformly.
Performance · Install · Train and resume · API · Results · Contributing · Citation
ModeBench separately supplies datasets, validators, and canonical mode identities. This repository provides the replay method, training integration, 20 Level-1 recipes, and reproducible saved-key analyses.
Performance on ModeBench
Qwen2.5-0.5B-Instruct, Level 1, final recorded step 3072, seeds 43–47, 128 held-out prompts per domain and four groups of eight responses. Each entry is pass@8 / PCMD [eligible PCMD seeds]. Larger values mean more tasks solved / more diversity among correct responses.
| Domain | GRPO | Dr.GRPO | Re:Dr | MaxRL | Re:Max |
|---|---|---|---|---|---|
| Graph | 0.361 / 0.009 [5] | 0.323 / 0.001 [5] | 0.969 / 0.560 [5] | 0.537 / 0.087 [5] | 0.945 / 0.526 [5] |
| Countdown | 0.639 / 0.008 [5] | 0.480 / 0.007 [5] | 0.672 / 0.487 [5] | 0.582 / 0.022 [5] | 0.666 / 0.511 [5] |
| Python | 0.172 / — [0] | 0.172 / — [0] | 0.528 / 0.000 [2] | 0.172 / — [0] | 0.681 / 0.312 [4] |
| MathIR | 0.460 / 0.002 [5] | 0.512 / 0.001 [5] | 0.796 / 0.018 [5] | 0.445 / 0.000 [5] | 0.789 / 0.006 [5] |
| PantryPlan | 0.545 / 0.000 [5] | 0.522 / 0.000 [5] | 0.729 / 0.334 [5] | 0.531 / 0.000 [5] | 0.721 / 0.317 [5] |
This preview covers all five domains, with five terminal seeds per method. PCMD includes only seeds with at least 30 eligible prompts; it pools the 32 responses within each prompt, then averages eligible prompts and seeds. Seed populations can differ, so these are descriptive endpoints, not paired treatment-effect estimates. A dash means insufficient support, not zero diversity. The JSON comparison output lists the exact seeds used for each metric. GRPO is a retained historical comparator; the maintained training recipes cover Dr.GRPO, Re:Dr, MaxRL and Re:Max.
# Print all five domains, including missing results and PCMD support.
remax results compare --level level1 --scale qwen05b --reproduce
# Other retained comparisons; --json includes exact values and seed identities.
remax results compare --level level1 --scale falcon1b --reproduce
remax results compare --level level1 --scale qwen3b --reproduce
remax results compare --level level2 --scale qwen05b --reproduce --json
These commands recompute the saved-key analysis on CPU. They do not regenerate responses or retrain models. ModeBench's level tables also include untrained models and retained Level-3 summaries, with their different evaluation protocols stated explicitly.
| Comparison | How to run or inspect it | Available scope |
|---|---|---|
| Dr.GRPO / Re:Dr / MaxRL / Re:Max | Follow Train and resume, selecting the corresponding bundled recipe | Maintained Level-1 Qwen-0.5B training; historical score equivalence is not established |
| GRPO; Falcon-1B; Qwen-3B; Level-2 Qwen-0.5B | remax results compare above; remax results show ID for bindings |
Saved-key numerical reproduction |
| Matched Re:Dr | remax results show snapshot/matched_redr_20260924 |
Summary only |
| Online RLEP | remax results show snapshot/online_rlep_20260927 |
Summary only |
| Tuned controls | remax results show snapshot/tuned_control_stage2_20260927 and snapshot/tuned_control_sweep_20260927 |
Summary only |
| Replay mechanism ablations | remax results show snapshot/replay_mechanism_ladder_20260924 |
Summary only |
| Level 3 | remax results show snapshot/level3_comparison_20260917 |
Summary only |
remax results list gives all exact IDs. Summary snapshots expose their gaps; reproduce refuses them. The repository does not provide verified end-to-end launch recipes for these summary-only comparisons. To check the preview table from a checkout, run python ops/summarize_performance.py --check.
Install
For the core API on Linux x86_64 with Python 3.10–3.12:
git clone https://github.com/liv-daliberti/remax.git
cd remax
python3.10 -m venv .venv-cpu
source .venv-cpu/bin/activate
python -m pip install --upgrade pip
python -m pip install 'torch==2.6.0+cpu' --index-url https://download.pytorch.org/whl/cpu
python -m pip install 'modebench==0.4.0' --find-links \
  https://github.com/liv-daliberti/modeBench/releases/download/v0.4.0/modebench-0.4.0-py3-none-any.whl
python -m pip install .
remax walkthrough
remax recipes
remax walkthrough grades three saved Countdown responses, retains two verified modes, applies a CPU replay update, and restores bank state. Expect two correct responses, one incorrect, zero prompt tokens scored, and parameters_updated / bank_restored both true. It needs no model weights or GPU. remax demo is a smaller score-gradient example.
The core requires PyTorch 2.6.x, NumPy >=1.26.4,<3, and the qualified modebench==0.4.0 package. Training preflight checks its code and resource hashes, so altered packages fail even when their version matches. The install command also accepts the tested ModeBench GitHub release while PyPI publication is pending. Commands work outside the checkout without PYTHONPATH. To build wheel and sdist artifacts, install build and run python -m build; the release workflow publishes the exact tested artifacts to GitHub Releases and PyPI. Once version 0.1.1 is published, python -m pip install remax-rl==0.1.1 installs the core; install the CPU PyTorch wheel first when using the CPU walkthrough.
Train and resume
Use a separate training environment. The qualified configuration is Linux x86_64, Python 3.10, CUDA 12.4, one 48 GB RTX A6000, eight CPU cores and 64 GB RAM. Allow about 60 GB of disk for dependencies, weights and checkpoints. Run the following from the checkout, with training commands inside a GPU allocation.
Prepare the environment and inputs
PYTHON=python3.10 bash ops/setup_gpu_environment.sh .venv-train
source .venv-train/bin/activate
remax environment --training

git clone https://github.com/liv-daliberti/modeBench.git ../modeBench
git -C ../modeBench checkout 33cfc3fd1732bd500fe13f13555419557aa248e2
python ../modeBench/ops/verify_data.py
python ../modeBench/ops/materialize_training_data.py \
  --config level1_pantry_plan --output outputs/data/pantry_plan
The setup script installs the GPU dependency lock. The data materializer creates all 384 training and 128 evaluation rows; keep the full splits even when a short recipe selects fewer training rows. The launcher authenticates their contents independently.
Download the recipe's pinned Qwen2.5-0.5B-Instruct snapshot:
python - <<'PY'
import json
from pathlib import Path
from huggingface_hub import snapshot_download
recipe = json.loads(Path("configs/remax_pantry_plan_05b.json").read_text())
model = snapshot_download(repo_id=recipe["model_id"], revision=recipe["model_revision"])
Path("outputs/model-path.txt").write_text(model + "\n")
PY
model_path="$(cat outputs/model-path.txt)"
Run a short example
This recipe uses three training prompts for two passes, saves checkpoints every two updates, and evaluates the full held-out split with K=2 and one sampled draw. It demonstrates execution, not paper-level performance.
python examples/prepare_training_walkthrough.py outputs/walkthrough.json
remax-run outputs/walkthrough.json --data-root outputs/data/pantry_plan \
  --model "$model_path" --output outputs/preflight --validate-only
remax-run outputs/walkthrough.json --data-root outputs/data/pantry_plan \
  --model "$model_path" --output outputs/train --execute
Preflight resolves the complete configuration before creating models or workers. Use a fresh output directory for each attempt. --render-only offers an explicitly unverified preview on CPU. Wrong inputs, incompatible settings, unknown recipe fields and conflicting inherited environment variables fail before training. Put changes in the recipe JSON.
Run the four maintained methods
After preparing the same Pantry inputs above, this runs full-budget recipes sequentially on the allocated GPU. It is substantially longer than the six-update walkthrough. All four use the same seed, inputs and evaluation settings, and each gets a fresh output directory:
for method in drgrpo redr maxrl remax; do
  remax-run "${method}_pantry_plan_05b" --data-root outputs/data/pantry_plan \
    --model "$model_path" --seed 43 --output "outputs/comparison/${method}-s43" --execute
done
Repeat with seeds 44–47 for five runs per method. Other domains use their corresponding materialized data directory and recipe name, listed by remax recipes. These are new runs of the maintained methods; the historical endpoints above remain separately identified.
Resume explicitly
To demonstrate recovery, even after the first run finishes, continue from its committed step-2 checkpoint in a fresh process:
checkpoint_path="$(python - <<'PY'
from pathlib import Path
matches = list(Path("outputs/train").glob("*/checkpoints/step_00002"))
assert len(matches) == 1, matches
print(matches[0])
PY
)"
remax-run outputs/walkthrough.json --data-root outputs/data/pantry_plan \
  --model "$model_path" --output outputs/resumed \
  --resume "$checkpoint_path" --execute
Keep the original recipe, total horizon, seed, installed source, dependencies, hardware and input bytes. Checkpoints restore model, optimizer, scheduler, RNG, data position, bank, replay cursor and evaluation cadence. Never use an incomplete .pending-* directory, a latest symlink, or an untrusted checkpoint. There is no automatic resume discovery. Source edits—including formatting—change resume identity, so retain the old environment for existing runs.
Read the evaluation
Greedy and sampled evaluation run automatically during training. Inspect the saved summaries:
python - <<'PY'
import json
from pathlib import Path
root = Path("outputs/train")
assert not any(p.stat().st_size for p in root.rglob("evaluation_failures.jsonl")), "Evaluation failed"
logs = list(root.rglob("train_metrics.jsonl"))
assert len(logs) == 1, logs
fields = ["misc/policy_sgd_step", "eval/multi_answer/accuracy",
          "eval/multi_answer/sampled_any_correct_at_2",
          "eval/multi_answer/sampled_distinct_correct_at_2"]
with logs[0].open() as stream:
    for line in stream:
        row = json.loads(line)
        if "eval/multi_answer/accuracy" in row:
            print({key: row.get(key) for key in fields})
PY
These fields mean optimizer step, greedy correctness, pass@2, and mean distinct verified modes among two samples. Missing evaluations are not zero scores. Keep launch_request.json, effective_config.json, checkpoints and eval_mode_coverage_draws.jsonl with each result. When joining resumed attempts, use the original prefix through the checkpoint and the resumed suffix; do not count duplicate evaluations.
Verifier timeouts or broken workers raise EvaluationFailure. Preserve diagnostics and reject partial scores. For dependency errors, check the active environment; for cache quota errors, set XDG_CACHE_HOME to writable scratch space; for input mismatches, restore the pinned inputs instead of changing expected hashes.
Public API
| Method | Fresh objective | Replay |
|---|---|---|
drgrpo |
Dr.GRPO | Executes with exactly zero applied gradient |
redr |
Dr.GRPO | Uniform verified replay |
maxrl |
Binary MaxRL | Executes with exactly zero applied gradient |
remax |
Binary MaxRL | Uniform verified replay |
The 20 recipes cover all five Level-1 domains. Full recipes use 384 prompts, eight passes and 16 fresh samples; the walkthrough deliberately reduces the budget. Controls preserve bank bookkeeping and replay computation. Evaluation answers never initialize the bank.
The executable API example uses remax.benchmark.grade_task, then these remax.core interfaces:
OnlineCanonicalBank.score_and_update(...)admits active, verified discoveries.bank.scheduled_global_replay_groups(min_modes=1)selects retained banks deterministically.materialize_canonical_replay_batch(...)creates causal response masks excluding prompt/padding tokens.canonical_replay_uniform_verified_likelihood_loss(...)averages negative response-token-normalized log scores over modes, then banks. Singletons participate.bank.state_dict()/load_state_dict(...)restore the bank; full training recovery also needs the other learner state.
The OAT adapter combines fresh RL loss with replay coefficient and accumulation scaling. Start in src/remax/core; training plumbing lives in integrations/oat, with historical comparators isolated in experiments.
Reproduce results
remax results list
remax results show level2/qwen05b/countdown/replay_maxrl
remax results reproduce level2/qwen05b/countdown/replay_maxrl
remax results verify
The installed result catalog contains 95 runnable saved-key analysis arms and six labeled summary snapshots. Numerical reproduction checks 473 included seed records across 95 arms; the catalog also records the two excluded cells. verify checks integrity and bindings only. Neither command retrains models, regrades all original responses, or validates the numbers in summary-only snapshots. Missing historical training evidence is recorded explicitly.
Current GPU qualification covers bounded Pantry training/resume for all four methods and Countdown sampling continuity. Full-budget historical scores, other hardware and distributed GPU recovery remain unqualified. To reproduce the full-state comparison, run python ops/resume_gpu.py run --workdir outputs/resume-proof --data-root outputs/data/pantry_plan --model "$model_path"; it runs both trajectories and audits automatically. GPU tolerances are atol=1e-6, rtol=1e-6 for model tensors and atol=1e-8, rtol=1e-5 for optimizer tensors, with exact bank, RNG, scheduling and evaluation decisions.
Contributing
Repository steward: Liv G. d'Aliberti, also listed in CODEOWNERS. Use issues with the commit, recipe, environment and minimal reproduction. Code is Apache-2.0; ModeBench owns benchmark semantics and dataset terms.
From the checkout in the CPU environment, install .[dev], then run make quality and make check. Focused checks are make conformance boundary resume scaling. Reinstall after code/asset changes. CI tests wheel and sdist installations outside the checkout on Python 3.10–3.12. Ruff covers all maintained core modules; strict mypy initially covers the six numerical/type/scoring/execution modules listed in pyproject.toml, not bank mixins or checkpoint dictionaries.
Preserve frozen fixtures, input registries and result identities. Changes to rewards, canonicalization, admission, normalization, replay weighting, sampling, evaluation or exclusions require an explicit scientific compatibility explanation and a new versioned identity. Benchmark changes belong in ModeBench first. Never turn evaluator failures into incorrect answers or change expected results merely to pass a test. Record exact commits, input hashes, recipe, runtime, seeds and exclusions when reporting results.
Citation
The paper is accepted at MATH-AI 2026 and under review at ICLR 2027. Please cite the paper and record the exact Re:Max/ModeBench commits and input identities used. Machine-readable metadata is in CITATION.cff.
@inproceedings{dAliberti:etal:ModeCollapse:2027,
  author    = {d'Aliberti, Liv G. and Abdulhai, Marwa and Druchyna, Sofiia and Henderson, Peter and Horta Ribeiro, Manoel},
  title     = {Measuring and Mitigating Solution Mode Collapse in {RLVR}},
  booktitle = {International Conference on Learning Representations ({ICLR})},
  year      = {2027},
  note      = {Under review at {ICLR} 2027},
}
1 maintainer

Metadata
1 maintainer
Release files for remax-rl 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| remax_rl-0.1.1.tar.gz | 8.4 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| remax_rl-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 16.7 MB
Release files / remax_rl-0.1.1.tar.gz
| Download URL | remax_rl-0.1.1.tar.gz |
|---|---|
| Size | 8.4 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fae7f30821b0974a2de67f232ad73731a4493a350638f7fe2e88d8273d3f72d8
|
|
BLAKE2b-256 checksum How to use checksums |
8bc9c0a153aea6cc90f640e823ef10c81532f7273a7faf0acaf1da44add08fc2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency logRelease files / remax_rl-0.1.1-py3-none-any.whl
| Download URL | remax_rl-0.1.1-py3-none-any.whl |
|---|---|
| Size | 8.2 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3f6bfe5021dadf8ee3c97d6f2581c87b1ad692a5dd362dcc2a99b9393307e67e
|
|
BLAKE2b-256 checksum How to use checksums |
8193d472ddb762340c7ef2868de5f09be4463d6a7f3a3763230efc6da662fdec
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 1, 2026.
Transparency log












