
renew-glm
Streaming generalized linear models with bounded memory -- a Python port of the renewable-estimation algorithm of Luo & Song (2020).
from renew_glm import RenewGLM

# Streaming (recommended): one chunk at a time, never stores prior chunks.
# Peak RAM is O(p^2 + chunk_size * p), independent of n.
# chunk_fn is polled: return the next (X, y), or None when exhausted.
chunks = iter(source_iter())                 # your (X, y) iterator
def chunk_fn():
    return next(chunks, None)                # X must include intercept column

model = RenewGLM(family="binomial").fit_streaming(chunk_fn)
print(model.coef_, model.n_iter_)

# Or chunk-buffered (matches the original R API):
model = RenewGLM(family="poisson")
for X_chunk, y_chunk in chunks:
    model.partial_fit(X_chunk, y_chunk)
model.fit()
print(model.coef_, model.se_, model.pvalue_)
chunk_fn is a zero-argument callable that is polled repeatedly: each
call returns the next (X, y) tuple, and None once the data is
exhausted. This is the biglm::bigglm callback pattern, not a generator.
fit_streaming releases each chunk before asking for the next, so peak
RAM is O(p^2 + chunk_size * p); partial_fit + fit instead buffers
every chunk in memory, which is what lets it compute se_ and pvalue_
like the R reference.
Supports gaussian, binomial, and poisson families. Coefficients converge to
the maximum-likelihood point of the full data; agreement with
statsmodels.GLM is verified to ~1e-3 on the test suite.
Why
Standard in-memory tools (statsmodels.GLM, R's glm()) load the
entire design matrix before fitting. At n = 16 M rows, statsmodels.GLM
allocates ~8 GB and OOMs above n ~ 20 M on a 16 GB laptop. This package
fits the same model in bounded memory -- one chunk at a time,
O(p^2) state regardless of n.
Other Python GLM options exist with different trade-offs:
glum(Quantco) -- fast in-memory; agrees with our estimates to ~1e-10 (see Correctness below), but caps out where the full design matrix fits in RAM, same as statsmodels. Recommended if yournfits.dask-glm-- distributed; useful at multi-machine scale, has scheduler overhead at single-host scale.pyglmnet-- gradient-based, regularization-focused; supports several families but the unregularized path is slower than IRLS.scikit-learnSGD -- online SGD, approximate (not exact MLE).
This package targets the gap: exact-MLE streaming on a single host,
no full-design-matrix RAM. It carries the same Wald inference the
R reference (biglm, RenewGLM_pkg) exposes.
Install
pip install renew-glm
Requires only NumPy and SciPy. Pure Python -- no C extension, no compile step, no platform-specific wheels.
Correctness
Across independent implementations spanning Python (NumPy / Numba
/ JAX), an in-memory Python competitor (glum), a distributed Python
competitor (dask-glm), and a cross-language reference (R's biglm), the
coefficient estimates agree to floating-point machine epsilon
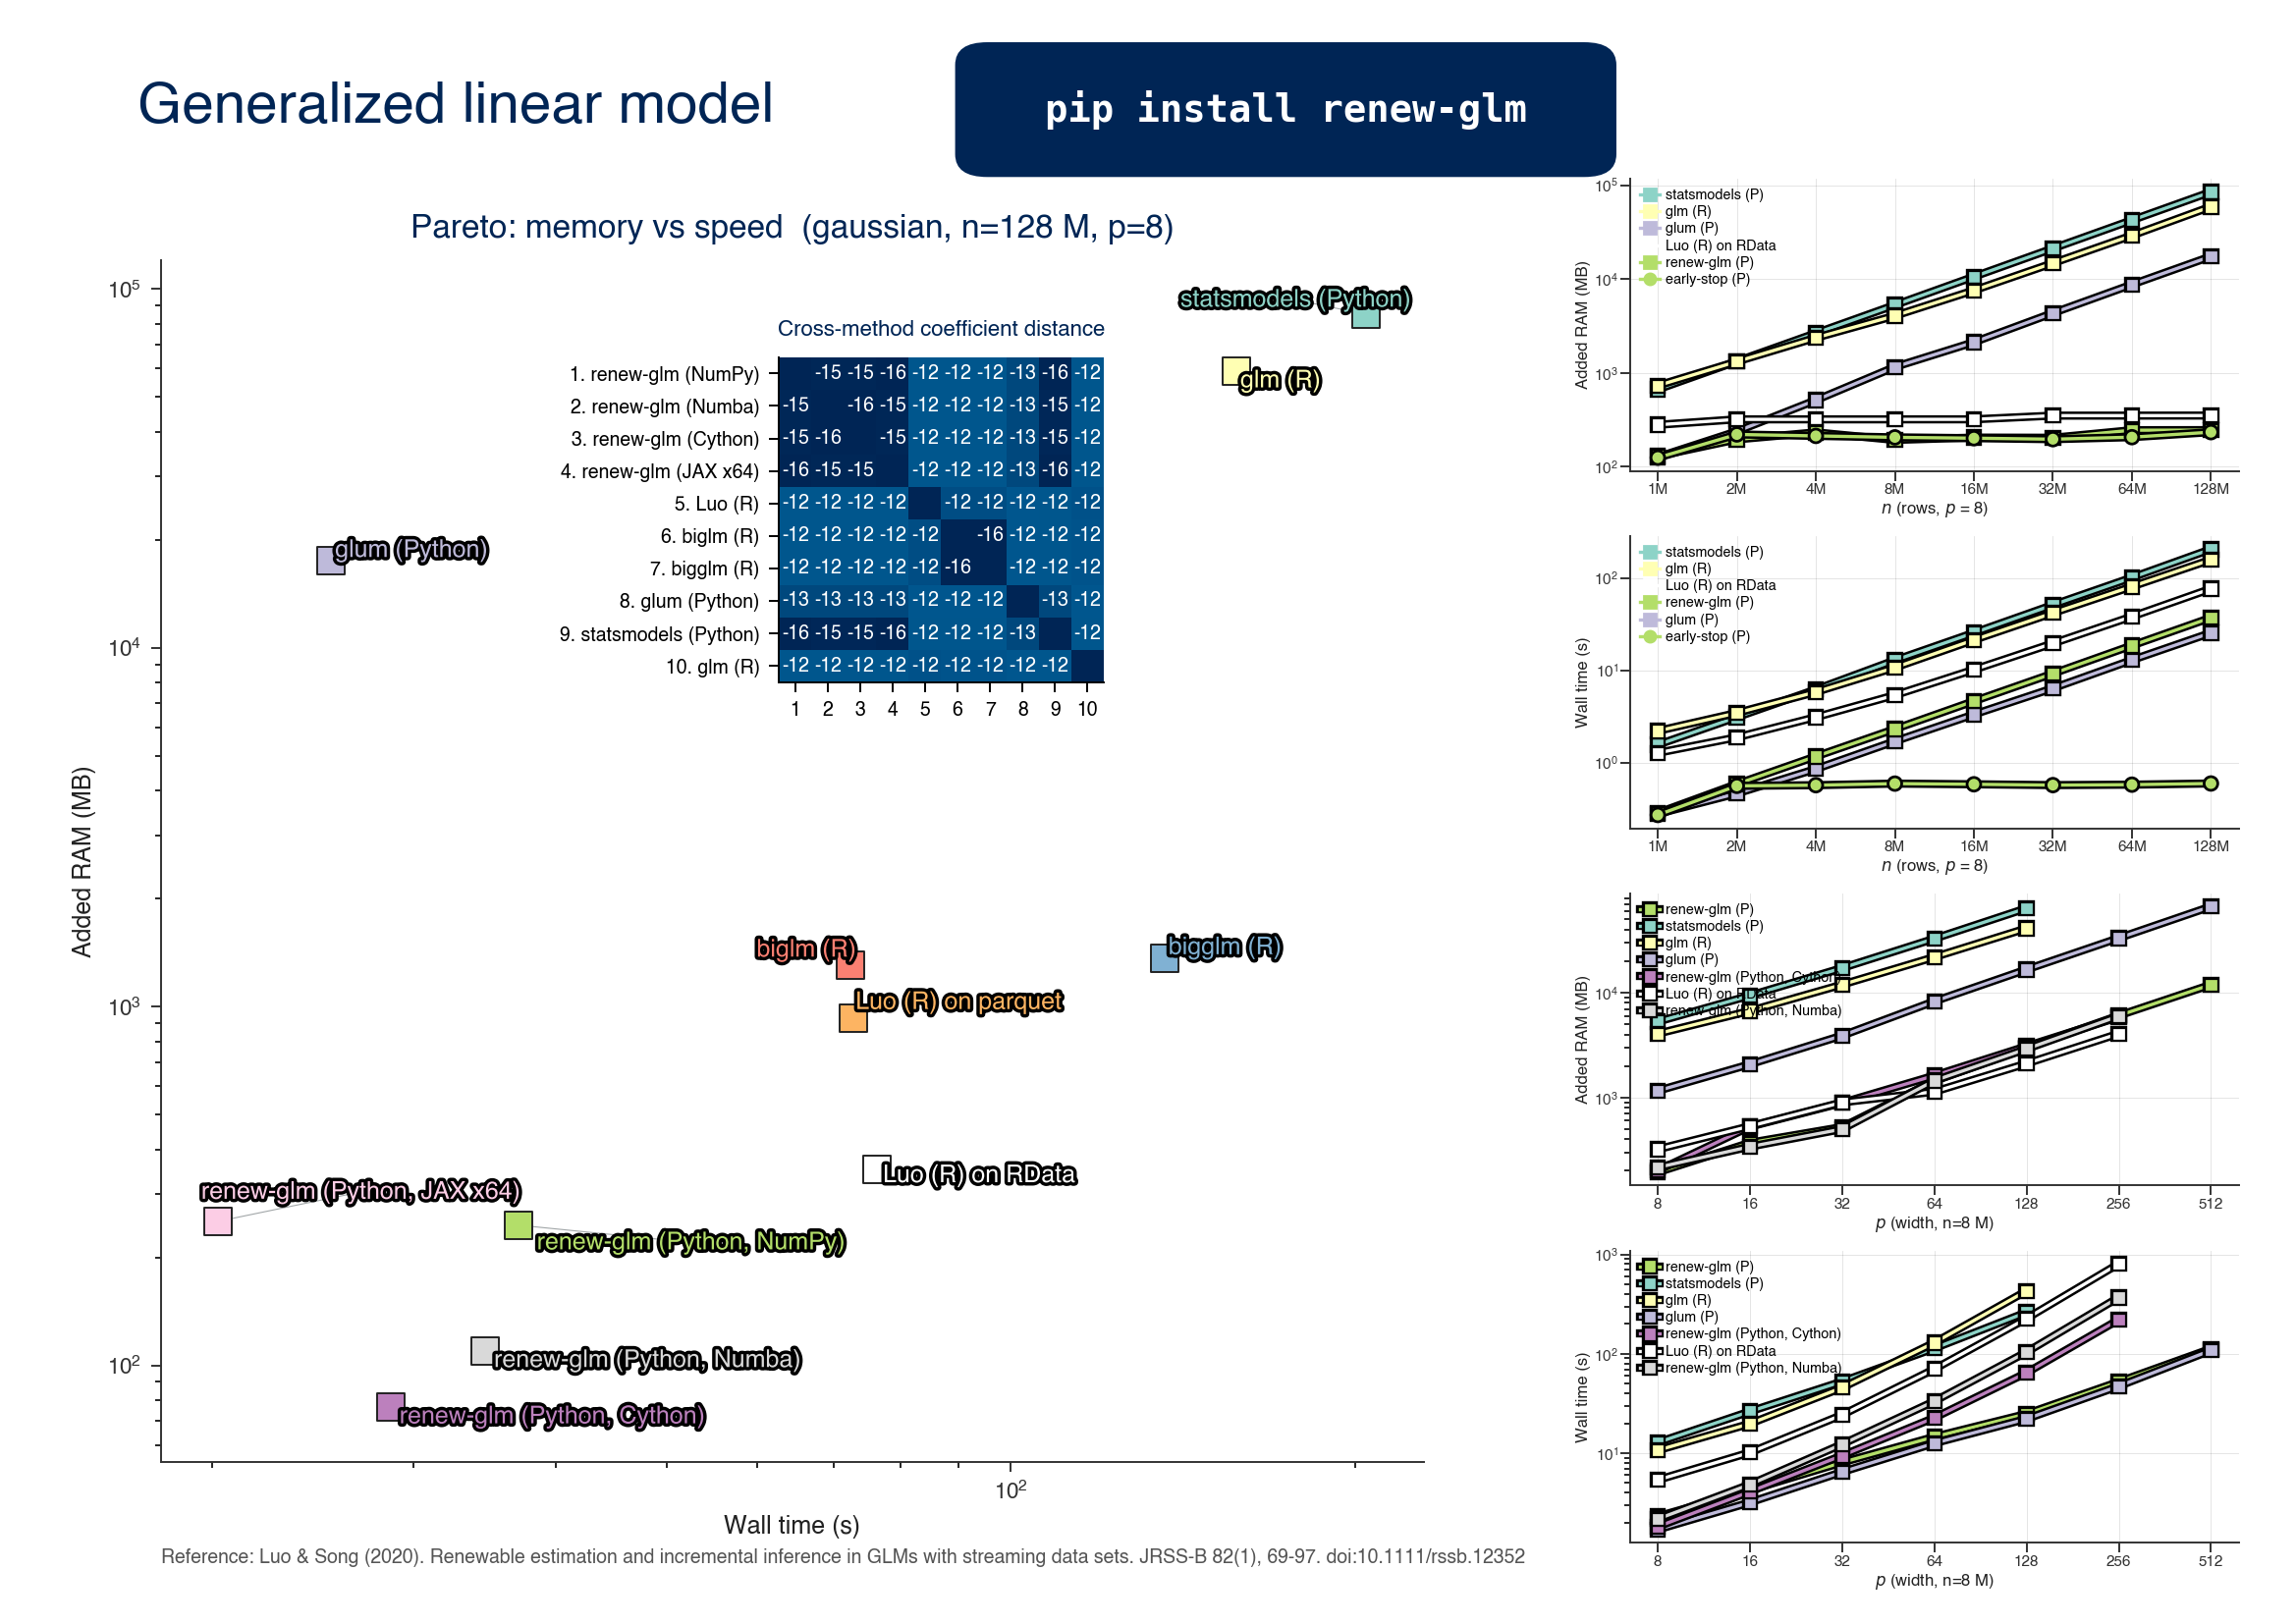
(~1e-15) on the largest workload we test. The heatmap inset in the
benchmark figure above shows pairwise log10(max|beta_i - beta_j|):
renew-glm hits FP epsilon (-15) against the streaming-Cholesky
cluster; in-memory references (glum, statsmodels,
glm (R)) sit one order out at -10/-11 (algorithm-decomposition
path, not convergence). The JAX implementation in that comparison sets
jax_enable_x64=True; the silent-float32 default would land an order of
magnitude looser. Note that the Numba and JAX implementations are
benchmark comparators only. The released package ships the NumPy path
alone, as renew_glm.__doc__ states.
Scaling
The right-side line panels in the benchmark figure show wall time
and peak RAM as n grows from 1M to 128M rows (cold runs). The
in-memory baselines (statsmodels, glm (R)) terminate at the
OOM cliff (~9 GB); renew-glm stays flat at bounded RAM.
Algorithm
For each chunk:
- Compute Fisher information
H_b = X' diag(W_b) Xat the current coefficient. - Inner Newton-Raphson against
H_b + sum_of_prior_Fishers, with a penalty term that pulls toward the previous coefficient. - Update
sum_of_prior_Fishers += H_band move to the next chunk.
One outer pass over the chunks suffices because the penalty term lets each
chunk contribute meaningfully without revisiting prior data. The docstring
in _irls.py matches the paper notation.
Differences from the original R package
- No SE in the streaming path.
fit_streaming(chunk_fn)returns onlycoef_andn_iter_. The chunk-bufferedpartial_fit+fit()path computesse_andpvalue_like the R version. - Pure NumPy/SciPy. No C extension; portable and easy to install.
- Convergence tolerance uses
|g' d_beta| < tol(same as the R version'sdf_betacriterion).
Roadmap (post v0.1.0)
Deferred to keep the first release minimal; pull requests welcome.
- Formula API (
patsy/formulaic) -- afrom_formula("y ~ x1 + C(category)", chunk_source=...)constructor so users coming fromstatsmodels.GLM.from_formula(...)or R'sglm(y ~ ...)don't have to build the design matrix themselves. The streaming twist: category levels must be discovered before fitting, so the API will require either a first-passdiscover_levels(source)step or an explicitlevels={...}argument. First-chunk-lock-in (reject any chunk introducing a new level, with a clear error) is the most likely default. Workaround today: usepatsy.dmatrices(...)per-chunk and feed the resulting arrays topartial_fit/fit_streaming. - Gamma + inverse-Gaussian families -- the algorithm generalises
(any exponential-dispersion family with a known link works), but
the test suite only covers gaussian / binomial / poisson. The weight
and mu functions in
_irls.pyare a few lines each; the real work is dispersion, which is currently special-cased to gaussian, while the standard errors for every other family assume dispersion 1. Both need extending before either family is usable. - Optional Cholesky -> Givens-QR path -- the current code uses
scipy.linalg.cho_factoronX' W X + sum_prior_Fisher. For ill-conditioned designs a Givens-QR path on[W^{1/2} X ; previous-R]would be more numerically stable; the bench's R reference (biglm) already does this and our coefficients agree to ~1e-6, suggesting the Cholesky path is sufficient for typical inputs. Track this if a real user hits a conditioning problem.
Credit
-
Algorithm by Lan Luo and Peter X.-K. Song. Please cite the original paper when using this package:
Luo L. & Song P.X.-K. (2020). "Renewable Estimation and Incremental Inference in Generalized Linear Models with Streaming Data Sets." Journal of the Royal Statistical Society: Series B, 82(1), 69-97. https://doi.org/10.1111/rssb.12352
-
Reference R implementation by Luo & Song: https://github.com/luolsph/RenewGLM_pkg
-
Python port by Tommy Carstensen. ORCID: https://orcid.org/0000-0002-3672-9931
License
GPL-2.0-or-later, matching the license of the original R package.
1 maintainer

Metadata
1 maintainer
Release files for renew-glm 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| renew_glm-0.1.3.tar.gz | 546.3 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| renew_glm-0.1.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 562.3 kB
Release files / renew_glm-0.1.3.tar.gz
| Download URL | renew_glm-0.1.3.tar.gz |
|---|---|
| Size | 546.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
862dd934fd590fdf04bba09daa701dfc351980925e2d443834de324b7f91eadc
|
|
BLAKE2b-256 checksum How to use checksums |
1379fb6ca65084e3f19bff825d330a40dbea4b8d42e9f7005faeca8e0152085e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.5
|
Release files / renew_glm-0.1.3-py3-none-any.whl
| Download URL | renew_glm-0.1.3-py3-none-any.whl |
|---|---|
| Size | 16.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
980c9e4e5f5d9860cfb285f34fafde69c5bc9c16f2b6e3b501fc47f5a59f6f1e
|
|
BLAKE2b-256 checksum How to use checksums |
187d7e1232b8086ad5ed9c5960b200746123ce0a0d1fdcbb7b650256968b7217
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.5
|
Security for renew-glm 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














