
Restruct




Extract structured JSON from single-column resumes.
PDF (OCR) · DOCX · PNG · JPEG
Runs on your machine. No resume upload and no API key.
Restruct is built for flat, single-column resumes with one top-to-bottom reading order. It finds the document's sections and extracts names, contact details, jobs, dates, schools and skills.
The output follows one published JSON schema. A missing section does not become a missing key, and a layout the parser cannot read reliably is reported instead of silently rearranged.
- Inputs: PDF, including scanned PDFs through OCR; DOCX; PNG; and JPEG.
- Layout scope: one content column. Sidebars, multiple columns, text inside graphics and nested tables are detected as unsupported layouts rather than repaired by guesswork.
- Local processing: after the model files are installed, resume extraction makes no network request.
- Stable output: sixteen sections in a fixed order, validated against
resume.schema.json. - Inspectable results: reconstruct the extracted JSON or draw the detected fields on the source page.
Why Restruct exists
Restruct grew out of my work on Open LinkedOut, a lightweight, local-first job scraping and matching system. I initially experimented with small open-weight language models, such as Qwen3 4B, running locally. Even at that scale, they consumed enough RAM and disk space that they could not run comfortably on my laptop, while still being prone to hallucinating resume details.
Restruct therefore uses document structure and explicit patterns first. Smaller, task-specific NLP models from Hugging Face are used only when the document itself does not settle the meaning of a span.
Built with





Install
uv add restruct-cv
uv run restruct --install-models
About those two commands
- The distribution is
restruct-cv; the command it installs isrestruct. The unqualified name was already taken on PyPI by an unrelated project. --install-modelsdownloads the two models Restruct uses: 352 MB, once. They are ordinary local files, verified by checksum as they arrive.- It is the only command that touches the network. Everything after it works offline.
Scanned PDFs, PNG files and JPEG files contain pixels rather than readable text, so they also need Tesseract. A native-text PDF or DOCX does not. Each PNG or JPEG is treated as one resume page, with its original proportions and camera-orientation metadata preserved.
brew install tesseract                 # macOS
apt-get install tesseract-ocr          # Debian / Ubuntu
Use it
uv run restruct resume.pdf -o .
That writes resume.json next to you, and prints nothing.
-o takes a file or a directory:
| You write | You get |
|---|---|
-o out.json |
exactly that file |
-o . |
resume.json in the current directory |
-o results/ |
resume.json inside results/ |
A directory gets <resume>.json, named after the input, so extracting several resumes into
one place doesn't have each one overwrite the last.
See what was understood
uv run restruct resume.pdf -o . --reconstruct
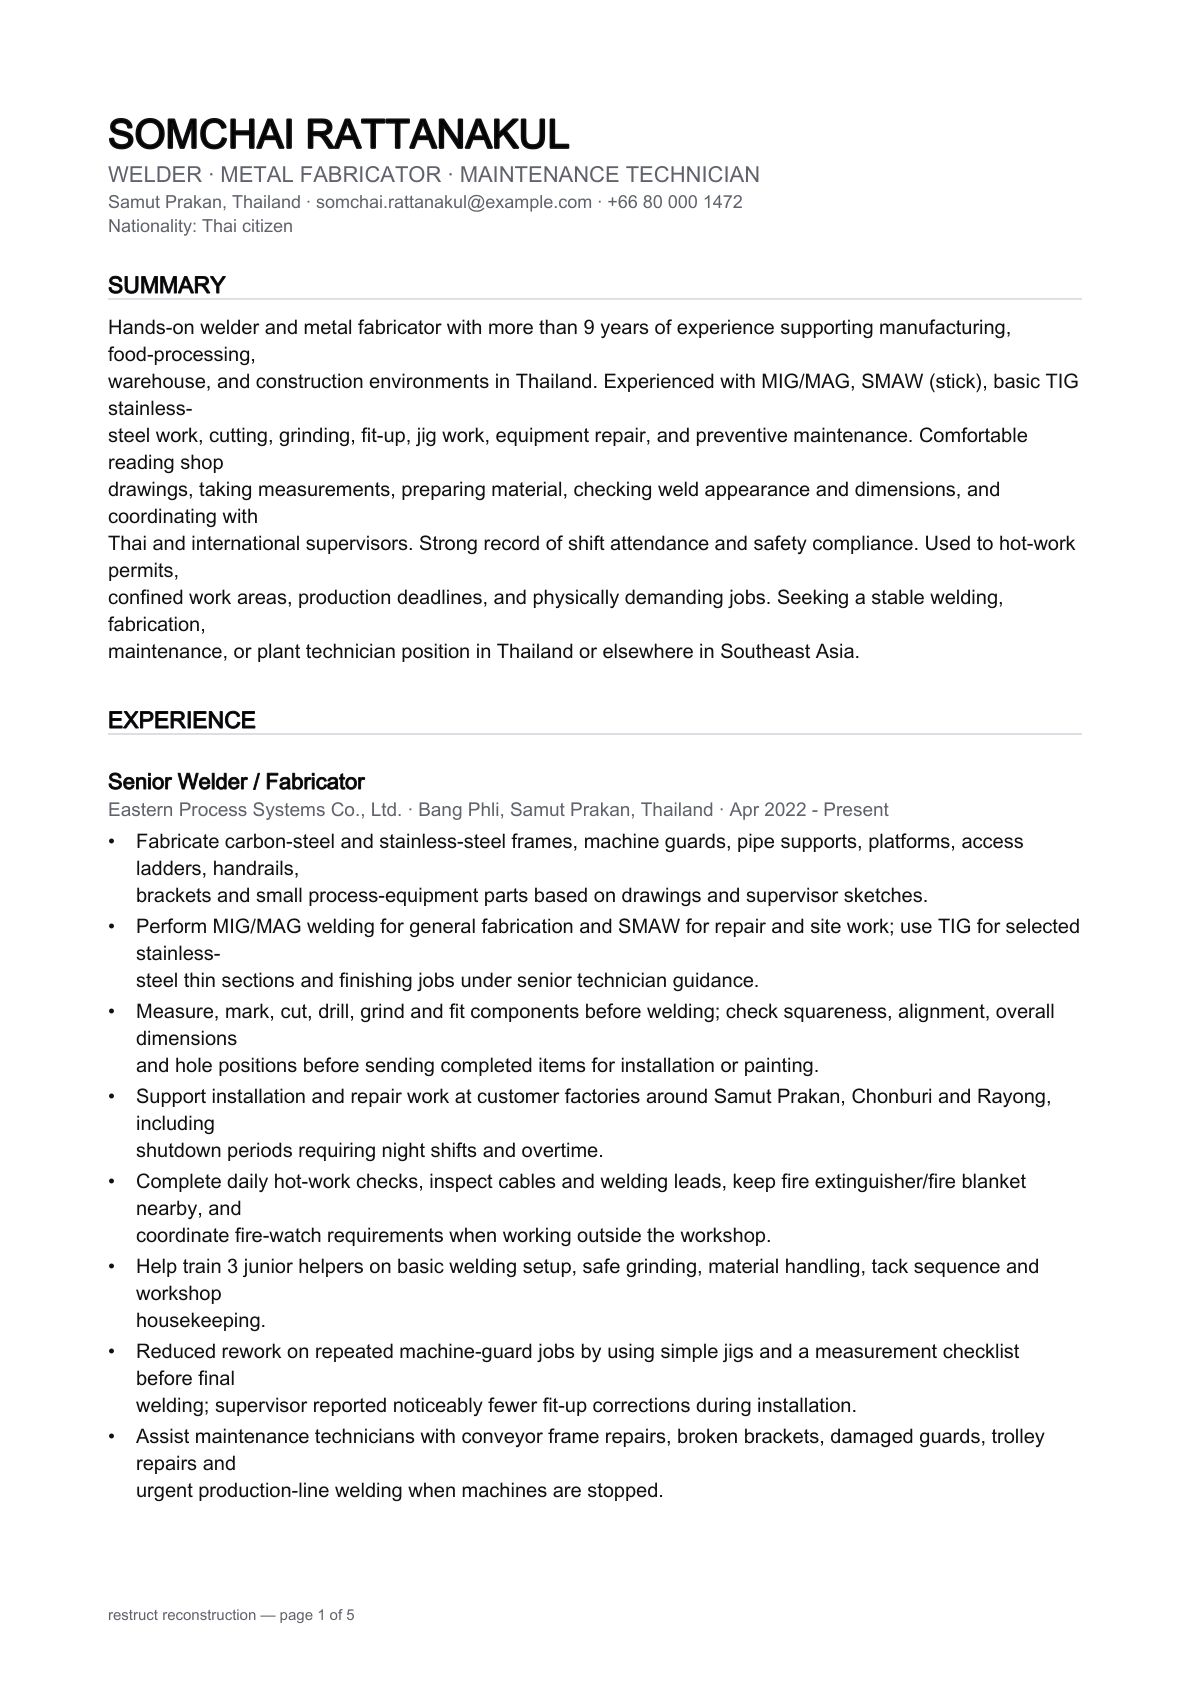
This draws the extracted result back out as a readable page, reconstruction.pdf plus a PNG
per page, built only from what was extracted, with the original layout thrown away.
That's the whole point:
- A bullet filed under the wrong section is obvious at a glance here, and invisible in a wall of JSON.
- A date read as a job title shows up in the wrong line of the header.
- Anything Restruct could not place is drawn in red under
UNPLACED, rather than quietly dropped.
It is deliberately not a facsimile. Imitating the original layout would hide the very errors it exists to reveal.
You can also draw a result you already have, without re-extracting anything:
uv run restruct resume.json --reconstruct
Check it is ATS-friendly
uv run restruct resume.pdf -o . --ats
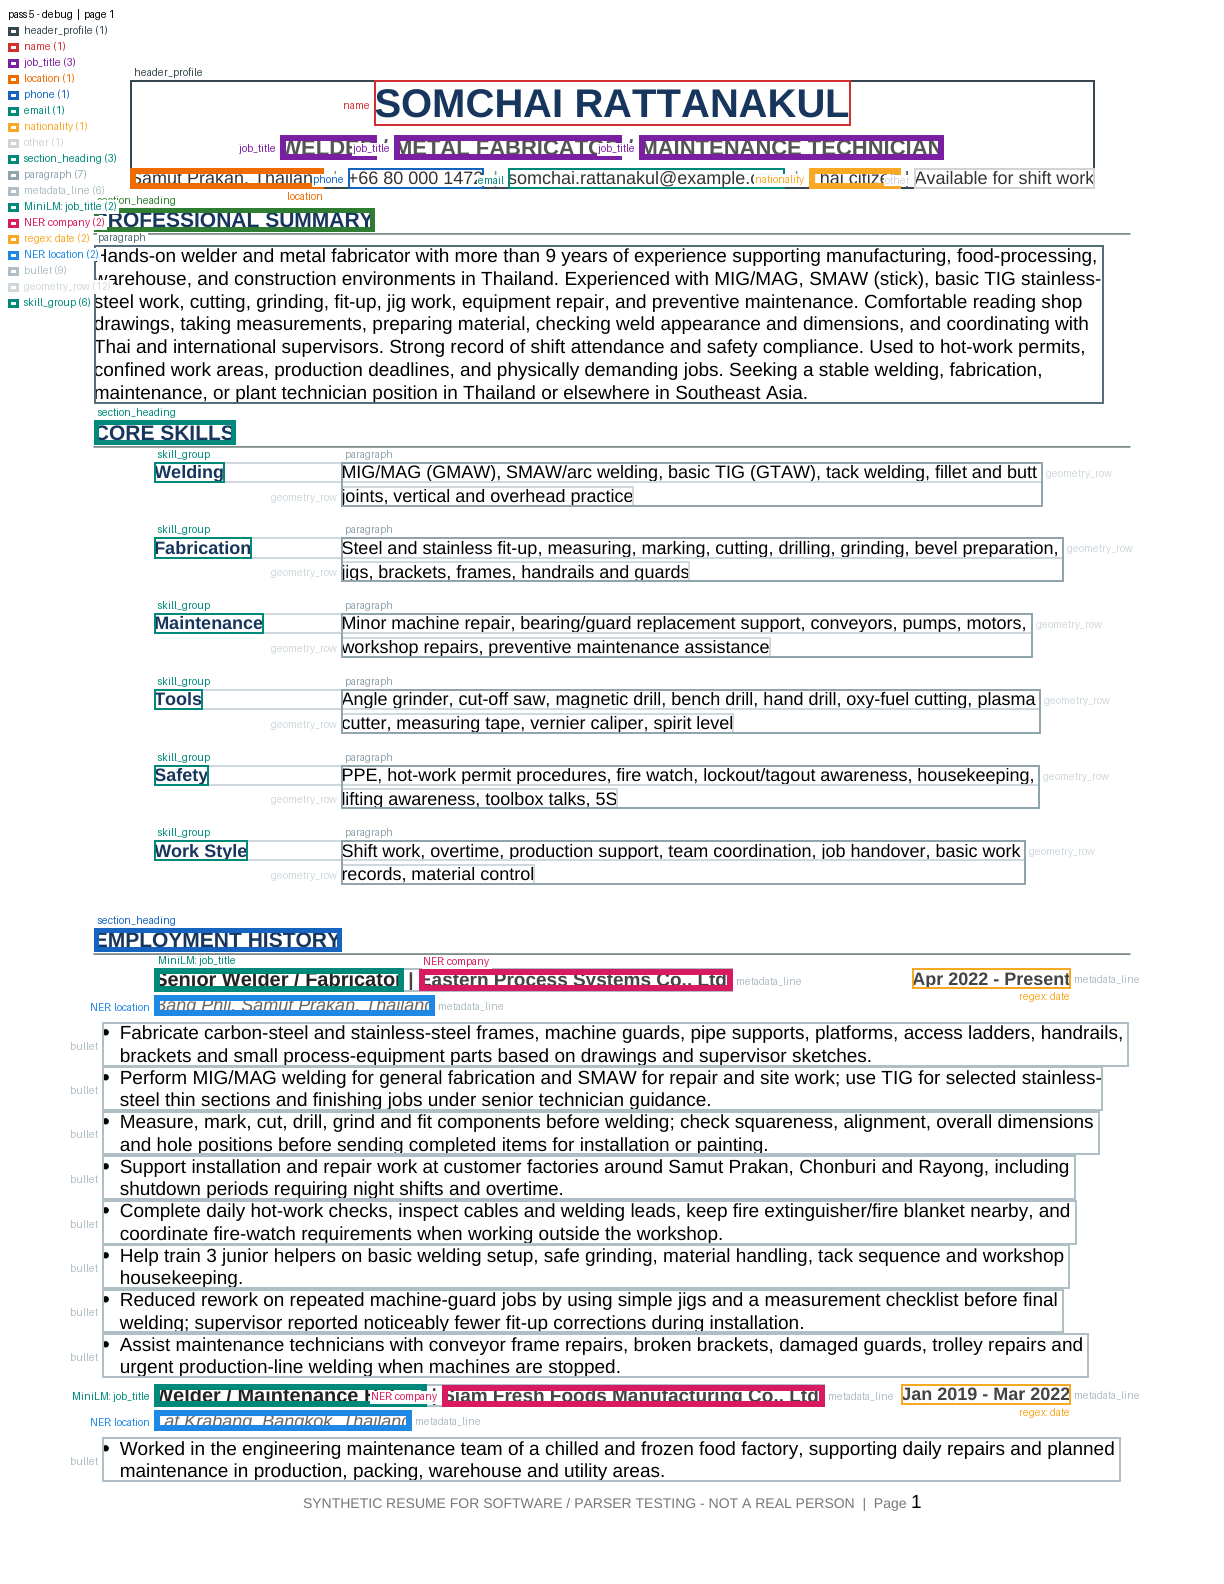
Alongside the JSON you get an overlay of every page, showing exactly what a parser could read and where it thought each section began and ended.
- Boxes in the wrong places, or missing, are the layouts machines choke on: side-by-side columns, text inside a graphic, a table nested in a table.
- Each box is labelled with the field it became:
name,job_title,bullet,skill_group. - Heavier boxes are model conclusions. Lighter ones are things the document stated outright, so you can tell a guess from a fact.
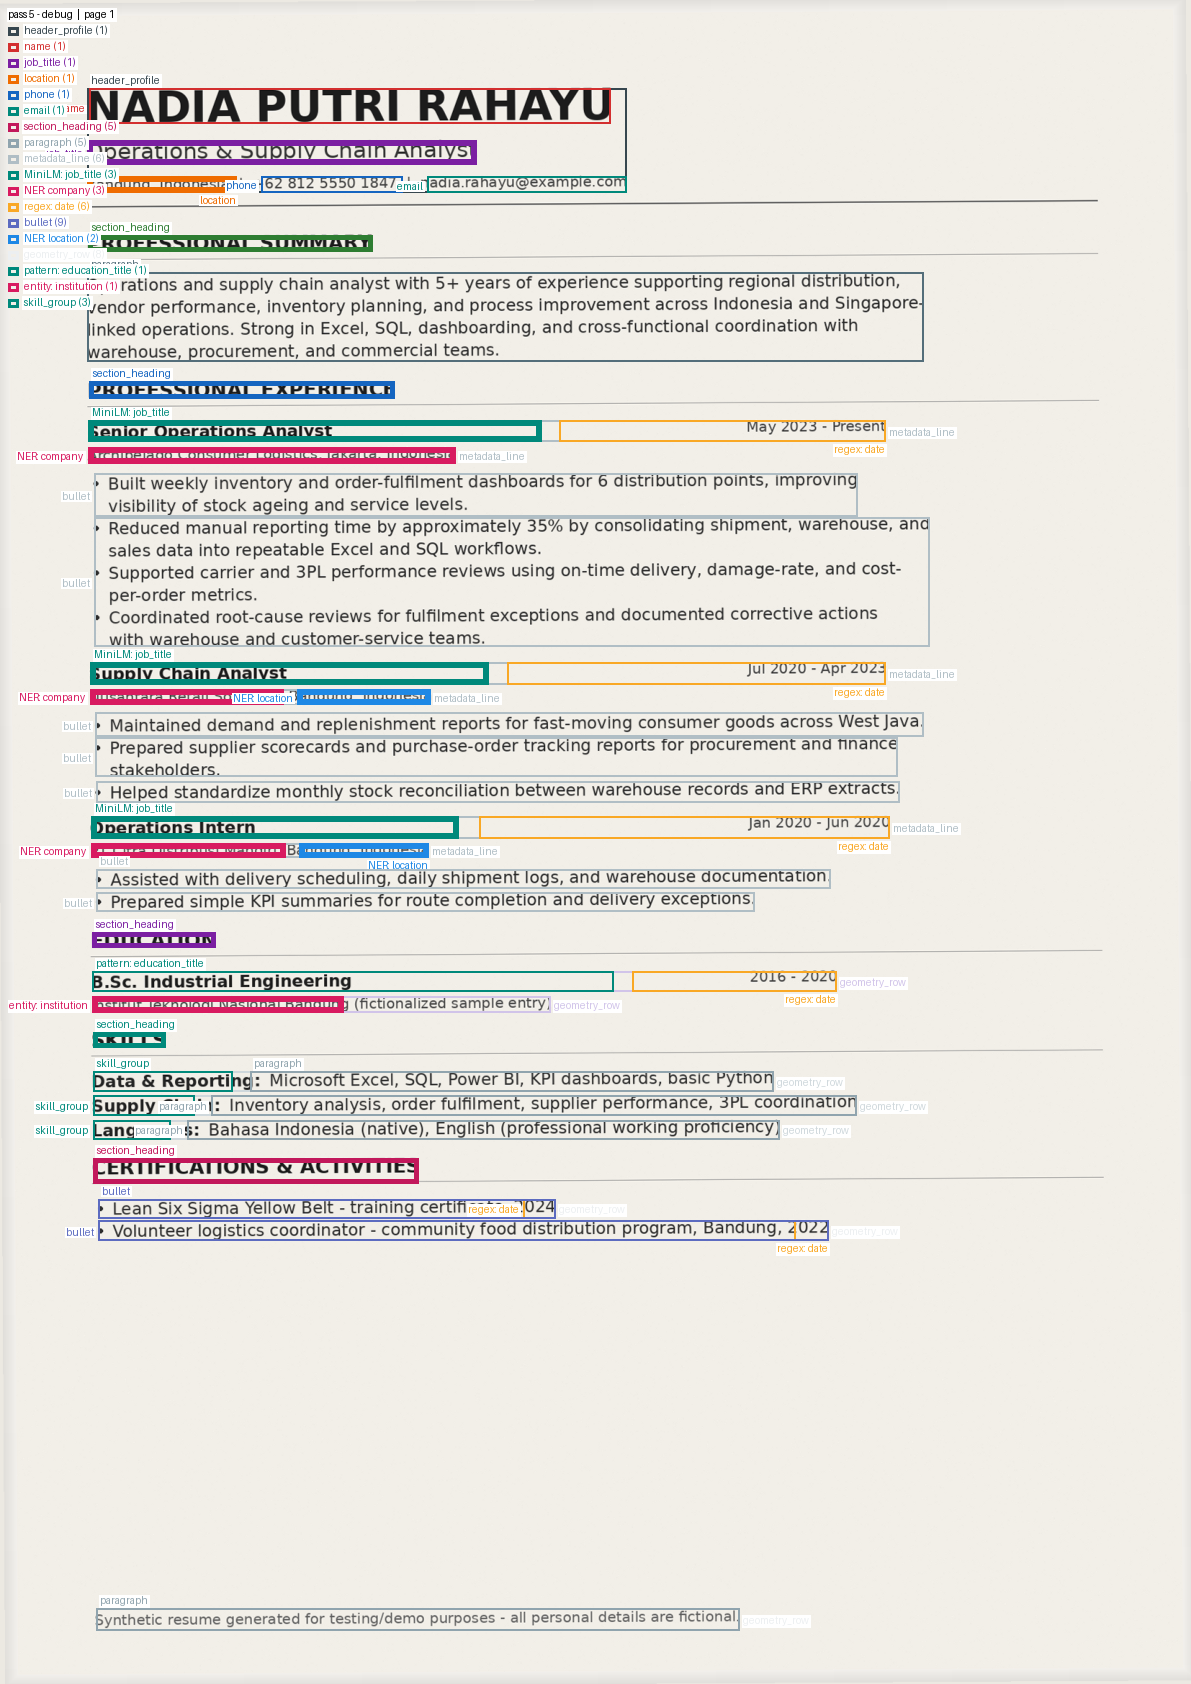
Scans and photographs go through the same path. A PNG or JPEG is placed on a page of its own proportions and read as a scan, and OCR is rebuilt into the same geometry a native PDF produces, so a photographed page gets an overlay that looks like any other:
What you get back
resume.json is plain data: no bounding boxes, no model names, no confidence scores.
{
  "schema_version": "1.0",
  "header_profile": { "name": "…", "emails": ["…"], "phones": ["…"] },
  "summary": null,
  "experience": [{ "job_titles": ["…"], "companies": ["…"], "bullets": ["…"] }],
  "education": [],
  "…": "…",
  "others": []
}
- Sixteen sections, always present, always in the same order.
nullwhen the resume has none,[]when the section exists but yielded nothing, never absent.resume.schema.jsonis the published contract, and every release is validated against it.- A section Restruct isn't confident about goes to
others, with its original heading kept, rather than being guessed into the wrong place.
Restruct is deliberately careful about what it claims. v1 targets single-column resumes, and a layout whose reading order can't be recovered is recorded as such, never silently repaired into something that reads plausibly and is wrong.
How accuracy is measured
A parser's failures matter more than its average. Restruct is scored per field, not with a single headline number that hides which fields to trust.
uv run tools/dev.py scorecard
This currently reports field-level precision, recall and F1 (name, dates, job titles, ...) and
section-routing accuracy - the percent of content assigned to the right one of 16 fixed sections
versus landing in others. Scored against 10 hand-labeled resumes in tests/labels/: enough to
catch regressions, not enough to claim broad accuracy yet.
Next release: strict exact-match accuracy (no containment leniency) and OCR character/word error rate, once the labeled corpus is large enough to make those numbers meaningful rather than noisy.
From Python
from restruct import extract_resume
Failures are raised as typed exceptions, so embedding Restruct in a service doesn't cost you your process. The command-line tool turns those into exit codes instead, grouped by decade:
| Code | Meaning |
|---|---|
0 |
success |
1x |
input: not found, unsupported format, unreadable document |
2x |
environment: models missing, Tesseract missing, download failed |
3x |
extraction |
4x |
output |
Examples
Three extracted resumes are committed under examples/, one per kind of input:
| Example | Source | What's in it |
|---|---|---|
7.anomaly/ |
native PDF, 3 pages | JSON and a page overlay per page |
9.ocr/ |
scanned PDF | the same shapes, recovered by OCR |
11/ |
DOCX | JSON only, because a DOCX has no page to draw on |
Worth a look before installing anything.
Contributing
Contributions are welcome. See CONTRIBUTING.md for the setup, the test
suite and the accuracy scorecard, and CLAUDE.md for the design decisions behind each module.
⚠️ Please do not submit real resumes, or labels derived from them. The fixtures in
resumes-synthetic/are synthetic and safe to commit.
License
1 maintainer

Metadata
1 maintainer
Release files for restruct-cv 0.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| restruct_cv-0.3.1.tar.gz | 126.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| restruct_cv-0.3.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 283.8 kB
Release files / restruct_cv-0.3.1.tar.gz
| Download URL | restruct_cv-0.3.1.tar.gz |
|---|---|
| Size | 126.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c4fddf890a142a3094f0ec8ae218cb353be24529168487285539b48e79e884e5
|
|
BLAKE2b-256 checksum How to use checksums |
8501fc8242b82965bf7093eb04a89001be64c3f03ccfc6349f32c9f6917ce286
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.11 {"installer":{"name":"uv","version":"0.12.11","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / restruct_cv-0.3.1-py3-none-any.whl
| Download URL | restruct_cv-0.3.1-py3-none-any.whl |
|---|---|
| Size | 157.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2a7b98e33ae29f39388728057a13886bf56fe591f5ea0a8b7ba8577ce7e3790f
|
|
BLAKE2b-256 checksum How to use checksums |
d8ec22df7949effa055f711f372927d4a8aa4003e0eff1b1ee2e0a30a86a0754
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.11 {"installer":{"name":"uv","version":"0.12.11","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














