

Result Companion


Turn your Robot Framework test failures into instant, actionable insights with AI.
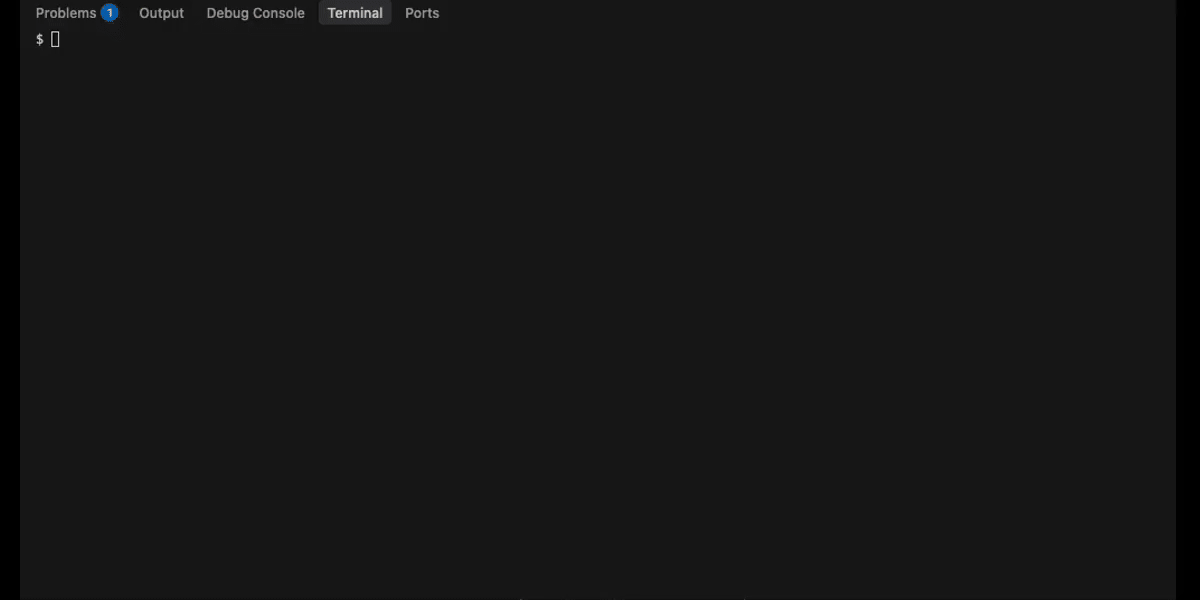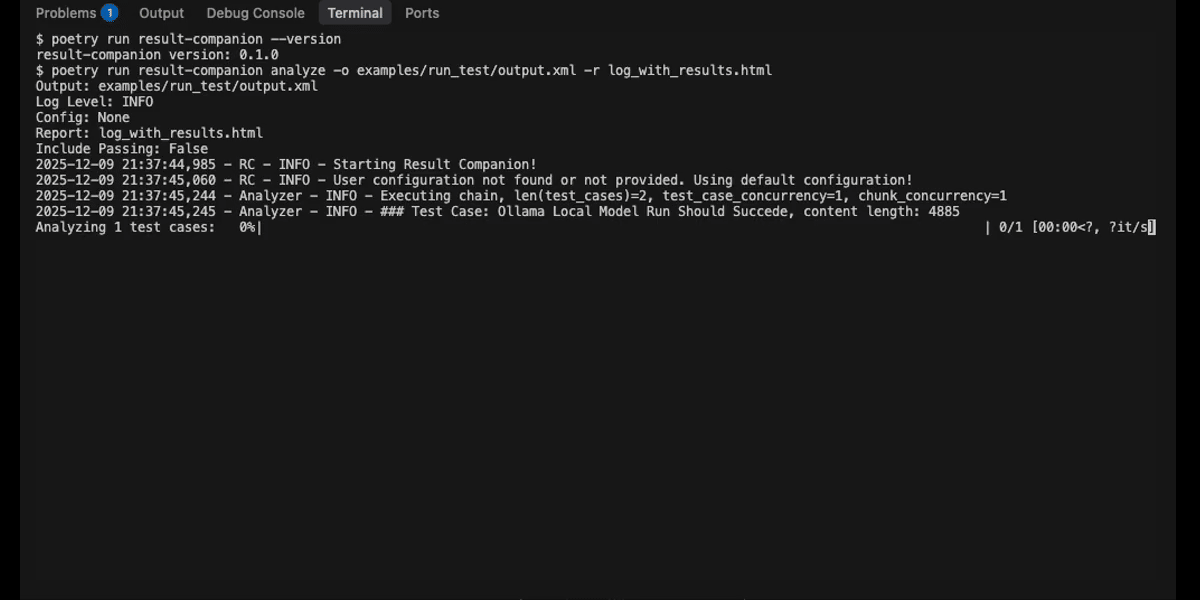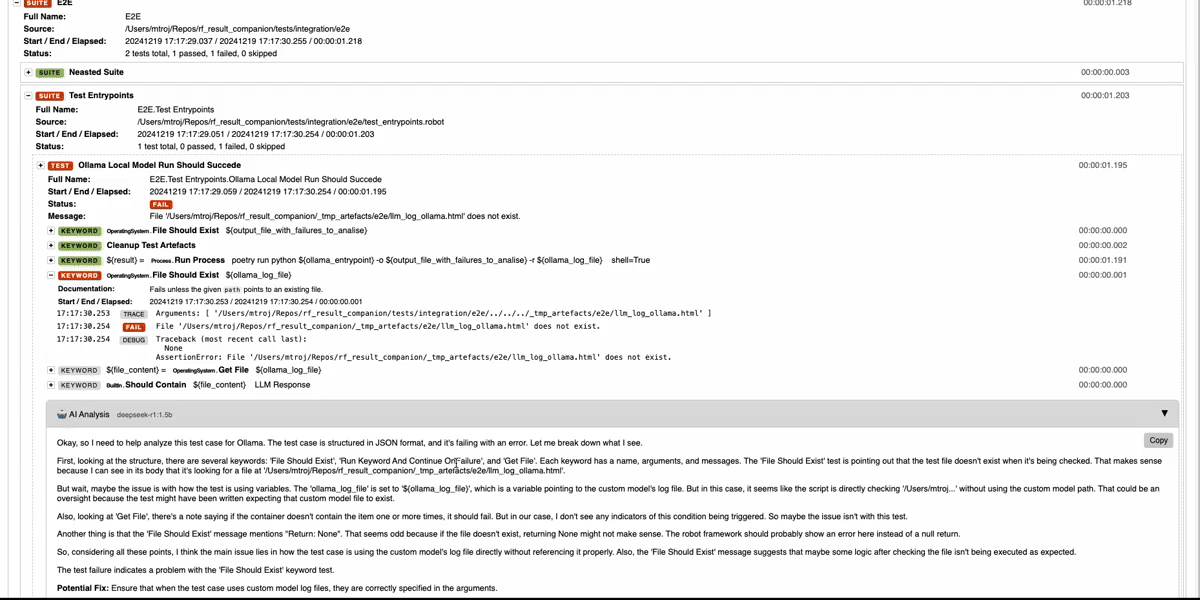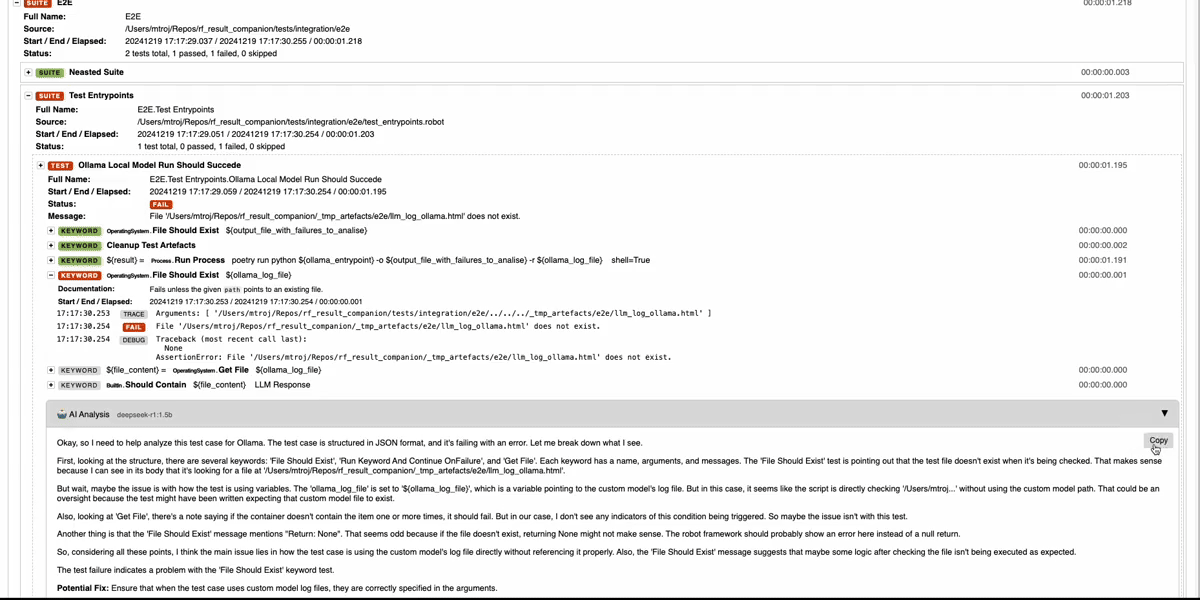
Why Result Companion?
Every QA engineer knows the pain: A test fails. You dig through logs. You trace keywords. You hunt for that one error message buried in thousands of lines. Hours wasted.
Result Companion changes that. It reads your output.xml, understands the entire test flow, and tells you exactly what went wrong and how to fix it—in seconds, not hours.
What It Does
# Before: Manual debugging for hours
robot tests/                     # Test fails
# Now: Where did it fail? Why? What's the root cause?

# After: Instant AI analysis
result-companion analyze -o output.xml   # Get answers in seconds
Your enhanced log.html now includes:
- Root Cause Analysis: Pinpoints the exact keyword and reason for failure
- Test Flow Summary: Understand what happened at a glance
- Actionable Fixes: Specific suggestions to resolve the issue
For CI logs and pipelines, use text output. An overall failure synthesis is run by default and added to both rc_log.html and text output. Disable with --no-overall-summary:
result-companion analyze -o output.xml --text-report rc_summary.txt
result-companion analyze -o output.xml --print-text-report
result-companion analyze -o output.xml --no-overall-summary
To inspect every prompt sent to the LLM and its response, use --debug-log. See Debugging Prompts for details.
Copilot Review Agent
Replaces the manual "which commit broke this test?" investigation. AI cross-references Robot Framework failures with PR code changes via GitHub Copilot and posts the verdict as a PR comment:
result-companion analyze -o output.xml --json-report rc_summary.json
result-companion review -s rc_summary.json --repo owner/repo --pr 65

# Save to file for review/editing before posting
result-companion review -s rc_summary.json --repo owner/repo --pr 65 --preview -o review.md
See examples/PR_REVIEW.md for setup, flow diagram, flags, and GitHub Actions usage.
Example generated PR comment — PR #65
🔍 result-companion: Test Failure Analysis
Root cause: unclear — investigate further
- Location:
poc_pr_review.py:6— file docstring and example usage reference interactivegh auth loginwhich, if executed in CI without a token, can trigger GitHub 403/forbidden responses - Location:
poc_pr_review.py:35— the prompt/action builder constructs shell commands that would rungh pr commentwithout using a non-interactive token, risking authentication failures in CI
💡 Suggested Fix
Replace interactive GH auth and posting with a token-based non-interactive command:
action = (
    "Print the review comment body only — do NOT run gh pr comment."
    if preview
    else (
        f'echo "$GITHUB_TOKEN" | gh auth login --with-token && '
        f'gh pr comment {pr_number} --repo {repo_name} --body "<review text>"'
    )
)
Ensure CI provides GITHUB_TOKEN secret and keep preview=True by default in CI invocation.
For AI Agents
Generate compact, portable context for coding agents:
result-companion analyze -o output.xml --text-report rc_summary.txt --no-html-report
result-companion analyze -o output.xml --json-report rc_summary.json
Then pass the report to your agent:
Read rc_summary.txt and rank failures by confidence and impact. Propose fix order.
Agent guidance lives in AGENTS.md. Skill-aware tools can use .agents/skills/result-companion/SKILL.md.
Quick Start
Option 1: GitHub Copilot (Easiest for Users With Copilot)
Already have GitHub Copilot? Use it directly—no API keys needed.
pip install result-companion

# One-time setup
brew install copilot-cli   # or: npm install -g @github/copilot
copilot -i "/login"            # Login when prompted, then /exit

# Analyze your tests
result-companion analyze -o output.xml -c examples/configs/copilot_config.yaml
See Copilot setup guide.
Option 2: Local AI (Free, Private)
pip install result-companion

# Auto-setup local AI model
result-companion setup ollama
result-companion setup model deepseek-r1:1.5b

# Analyze your tests
result-companion analyze -o output.xml -c examples/configs/ollama_config.yaml
Option 3: Cloud AI (OpenAI, Azure, Google)
pip install result-companion

# Configure and run
export OPENAI_API_KEY="your-key"
result-companion analyze -o output.xml -c examples/configs/openai_config.yaml
Supports 100+ LLM providers via LiteLLM.
Real Example
Your test fails with:
Login Test Suite
└── Login With Valid Credentials [FAIL]
Result Companion tells you:
**Flow**
- Open browser to login page ✓
- Enter username "testuser" ✓
- Enter password ✓
- Click login button ✓
- Wait for dashboard [FAILED after 10s timeout]

**Failure Root Cause**
The keyword "Wait Until Page Contains Element" failed because
element 'id=dashboard' was not found. Server returned 503 error
in network logs at timestamp 14:23:45.

**Potential Fixes**
- Check if backend service is running and healthy
- Verify dashboard element selector hasn't changed
- Increase timeout if service startup is slow
Beyond Error Analysis
Customize prompts for any use case:
# security_audit.yaml
llm_config:
  question_prompt: |
    Find security issues: hardcoded passwords,
    exposed tokens, insecure configurations...
# performance_review.yaml
llm_config:
  question_prompt: |
    Identify slow operations, unnecessary waits,
    inefficient loops...
See Custom Analysis examples for security audits, performance reviews, and more. The llm_config section also supports chunking prompts for large test suites.
Configuration Examples
Check examples/configs/ for ready-to-use configs:
- GitHub Copilot (easiest for users with copilot)
- Local Ollama setup
- OpenAI, Azure, Google Cloud
- Custom endpoints (Databricks, self-hosted)
- Prompt customization for security, performance, quality reviews
Filter Tests by Tags
Analyze only the tests you care about:
# Analyze smoke tests only
result-companion analyze -o output.xml --include "smoke*"

# Exclude work-in-progress tests
result-companion analyze -o output.xml --exclude "wip,draft*"

# Analyze critical tests (including passes)
result-companion analyze -o output.xml --include "critical*" -i
Or use config file:
test_filter:
  include_tags: ["smoke", "critical*"]
  exclude_tags: ["wip", "flaky"]
  include_passing: false  # Analyze failures only
See tag_filtering_config.yaml for details.
Token Efficiency
Before sending a test case to the LLM, result-companion keeps context compact and useful:
1. Field filtering — exclude RF fields irrelevant to your analysis via rendering.exclude_fields:
rendering:
  exclude_fields: [elapsed_time, lineno, owner, assign]
See field reference in EXAMPLES.md for the full list and common presets.
2. Consecutive line deduplication — repeated log lines are collapsed:
# Before
    DeprecationWarning: Call to deprecated create function FieldDescriptor().
    DeprecationWarning: Call to deprecated create function FieldDescriptor().
    DeprecationWarning: Call to deprecated create function FieldDescriptor().

# After
    DeprecationWarning: Call to deprecated create function FieldDescriptor(). (repeats ×3)
3. Context-aware chunking — tests that exceed the token budget are split into self-contained chunks. Each chunk repeats the suite → test → keyword ancestor chain so the LLM can interpret it without prior context:
Suite: Outer Suite - FAIL
    Suite: Inner Suite - FAIL
        Test: Example workflow - FAIL
            Keyword: Run job and wait - PASS
                {...}                          ← continuation marker
                Keyword: Log - PASS
4. Screenshot context — embedded Robot screenshots become [SCREENSHOT] placeholders. Enable local OCR with result-companion[ocr] and --ocr to add [SCREENSHOT_OCR] text near the keyword that captured it.
OCR text is sent to your configured LLM with the rest of the test context, so use a local model or disable OCR for sensitive screenshots. See Robot Screenshot OCR for setup and supported formats.
Limitations
- Embedded screenshots are represented by placeholders; optional OCR can extract screenshot text. Videos and file-based screenshots are not supported.
- Large test suites processed in chunks
- Local models: Need 4-8GB RAM + GPU/NPU for good performance (Apple Silicon, NVIDIA, AMD)
Contributing
Contributions welcome! See CONTRIBUTING.md for guidelines.
For bugs or feature requests, open an issue on GitHub.
Development Setup
make install                # install with dev dependencies
poetry run pre-commit install  # one-time: install pre-commit hooks

make test-unit              # unit tests only
make test-integration      # integration tests (e2e skipped automatically)
make test-e2e              # e2e only (requires Copilot CLI / Ollama locally)
make test-integration-all  # all integration tests including e2e
License
Apache 2.0 - See LICENSE
Disclaimer
Cloud AI providers may process your test data. Local models (Ollama) keep everything private on your machine.
You are responsible for data privacy. The creator takes no responsibility for data exposure, intellectual property leakage, or security issues. By using Result Companion, you accept all risks and ensure compliance with your organization's data policies.
1 maintainer

Metadata
1 maintainer
Release files for result-companion 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| result_companion-0.1.0.tar.gz | 60.0 kB | Without provenance | Details for result_companion-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| result_companion-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for result_companion-0.1.0-py3-none-any.whl |
Total release size: 132.9 kB
Release files / result_companion-0.1.0.tar.gz
| Download URL | result_companion-0.1.0.tar.gz |
|---|---|
| Size | 60.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7f064513819dae58e3c293ca6df29ca14819157a91eac74dbca2fdb696255d7d
|
|
BLAKE2b-256 checksum How to use checksums |
d69d19d2f3becce0e619c845ce771a29ddaf52ab670c953d098e0c90a62bff79
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.4.1 CPython/3.12.13 Linux/6.17.0-1020-azure
|
Release files / result_companion-0.1.0-py3-none-any.whl
| Download URL | result_companion-0.1.0-py3-none-any.whl |
|---|---|
| Size | 72.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
541e5a7510b49d852c352a40bbc26b50a6587f9462c2668aa13c5c05f8f77501
|
|
BLAKE2b-256 checksum How to use checksums |
acdbd67fabdf9ff1ddf3510c3e2767b5ffc55f7214729ee6d1da29bce66153d0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
poetry/2.4.1 CPython/3.12.13 Linux/6.17.0-1020-azure
|
Security for result-companion 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














