
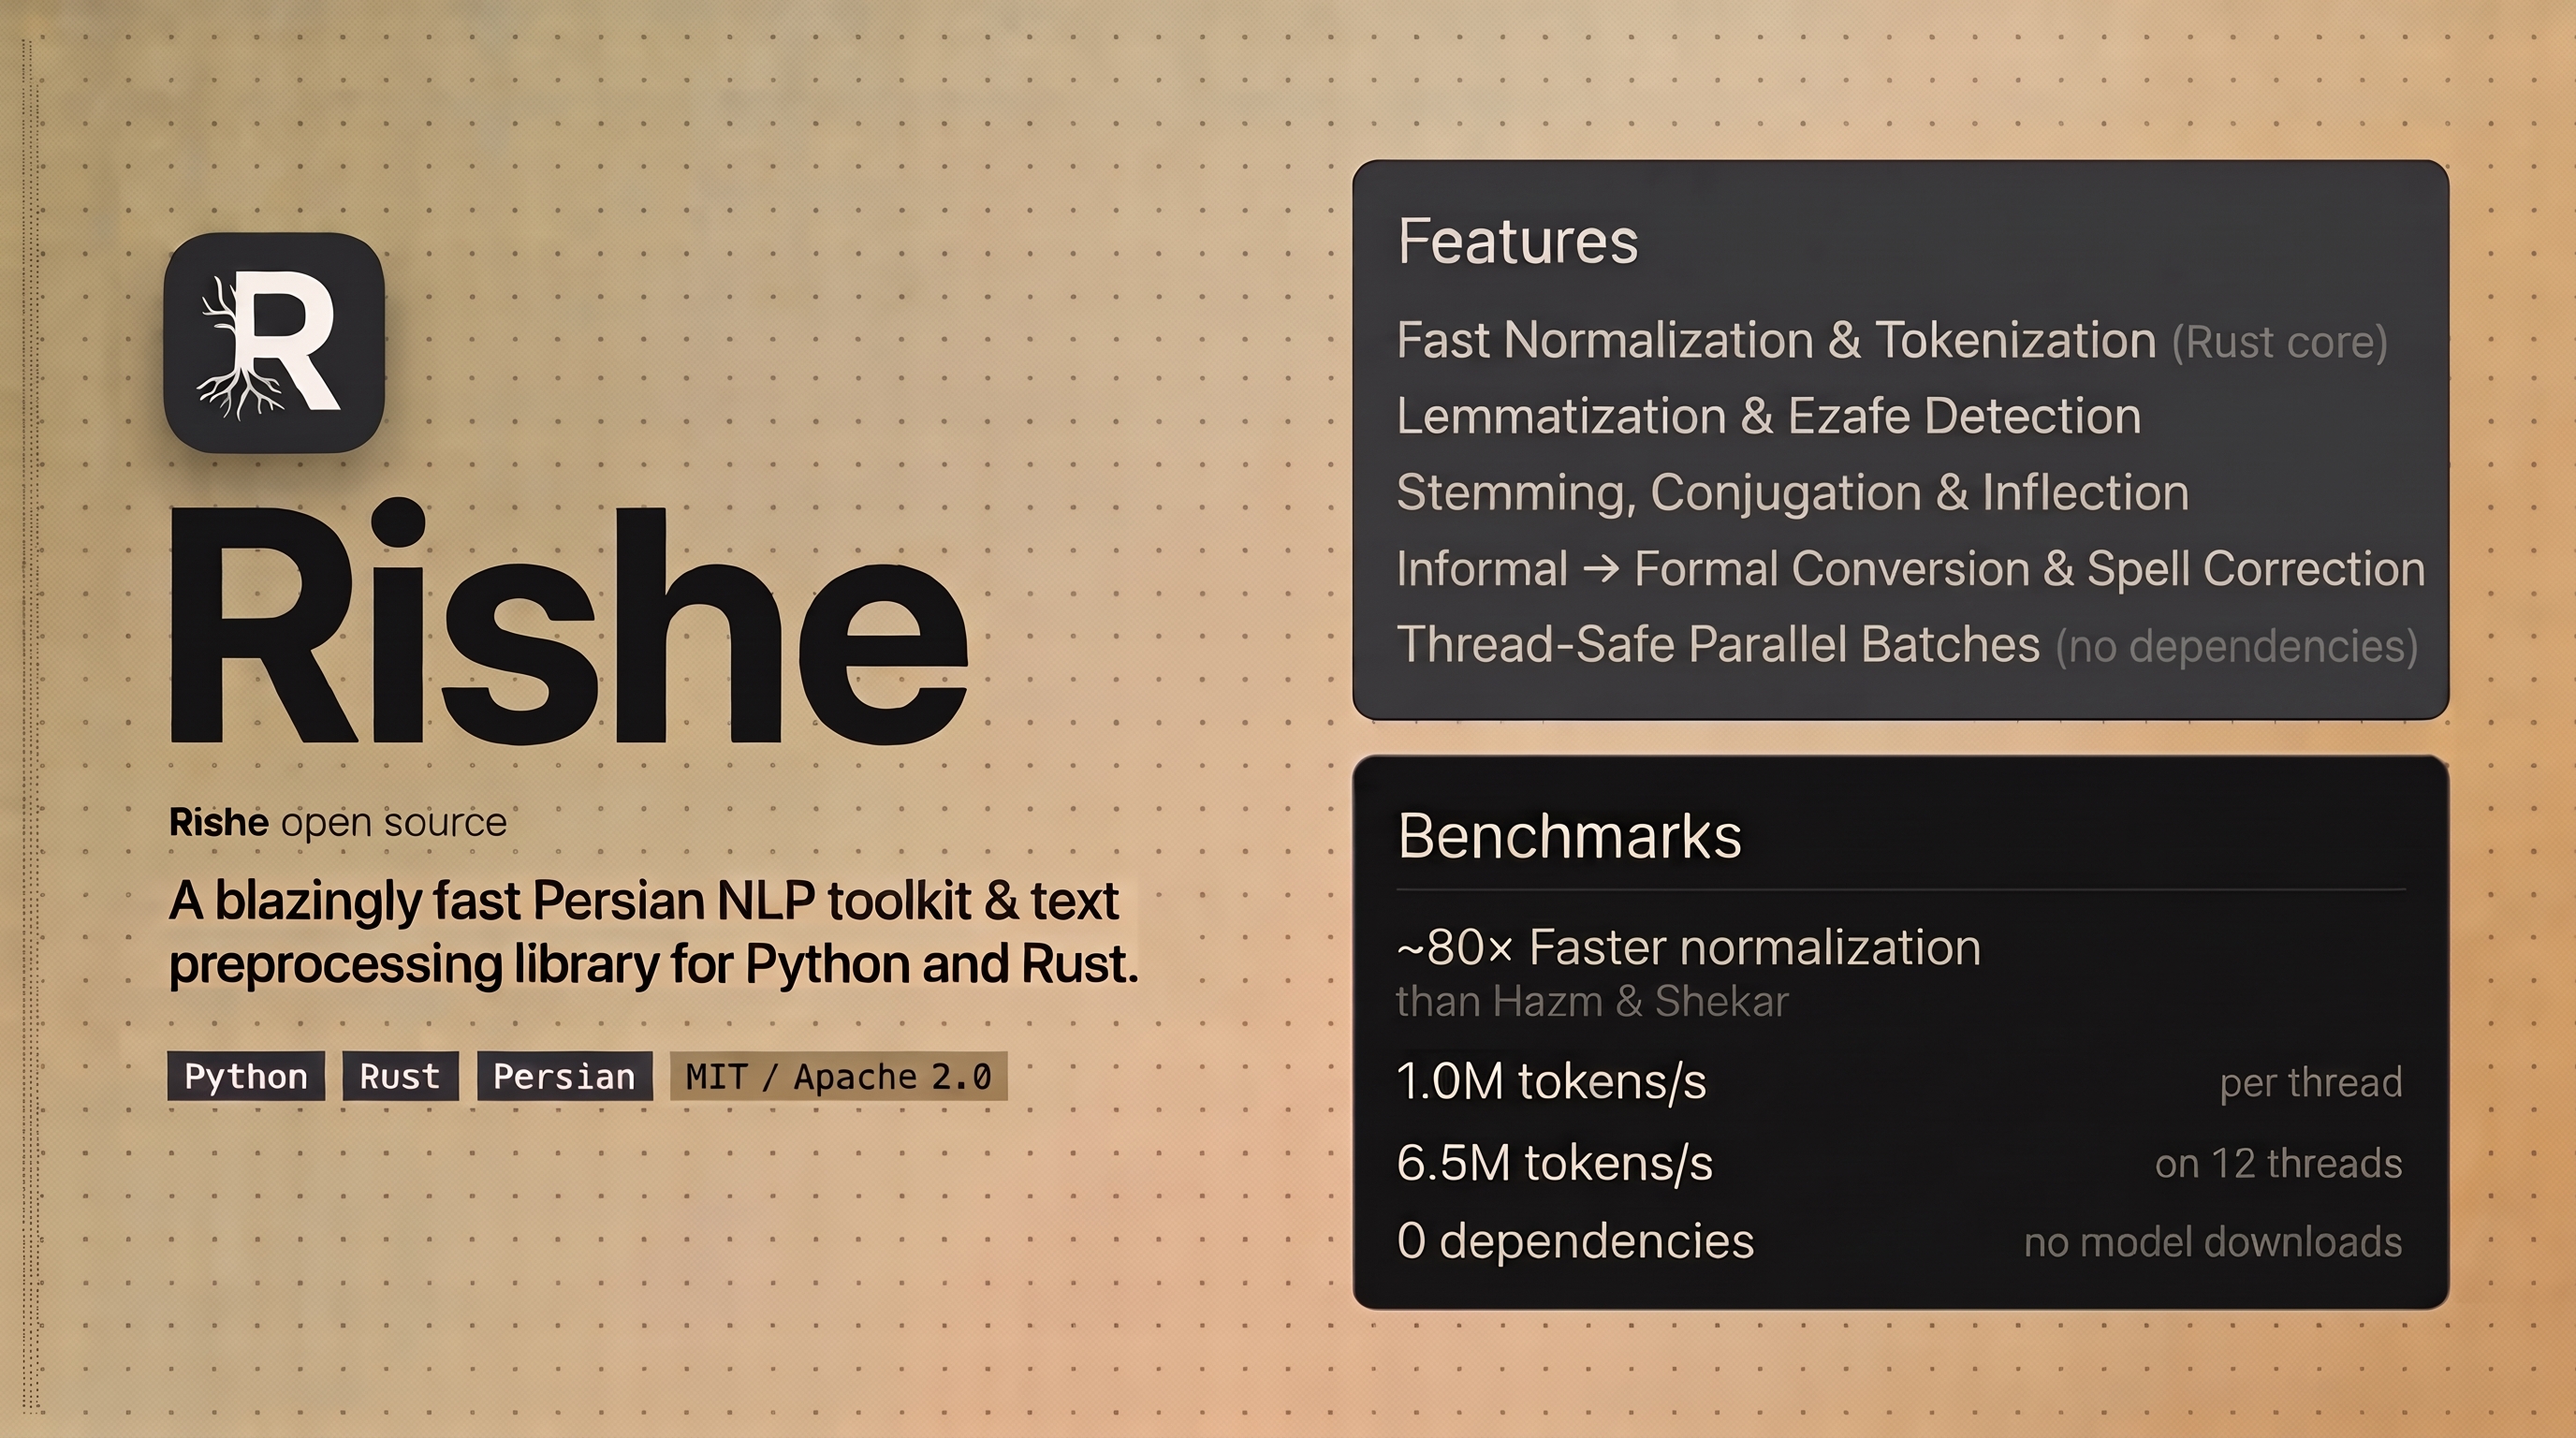
Rishe (ریشه)
Fast Persian NLP and morphology, built in Rust.
Rishe (root in Persian) turns raw Persian text into clean, structured data in one call: normalized text, tokens, lemmas, sentences, ezafe markers, and a formal rewrite of colloquial writing. It also ships the morphology utilities that usually live in a separate library: stemming, verb conjugation, inflection, token splitting, spell correction, and stopword removal.
The core is Rust. You get it as a pip install with prebuilt wheels, no
runtime dependencies, and the same engine as a Rust crate. The base pipeline
needs no model downloads; optional POS/NER/ezafe packs are separate.
from rishe import Pipeline
pipe = Pipeline()
doc = pipe("اون داره تو خونه کتاب میخونه، چیه؟")
doc.tokens # ['آن', 'دارد', 'تو', 'خانه', 'کتاب', 'میخواند', '،', 'چیست', '؟']
doc.lemmas # ['آن', 'داشت', 'تو', 'خانه', 'کتاب', 'خواند', '،', 'چیست', '؟']
doc.formal_text # 'آن دارد تو خانه کتاب میخواند، چیست؟'
Why Rishe
- Normalization about 80× faster than Hazm and Shekar: 1.2 µs per sentence against 96 µs and 104 µs.
- Best tokenization and lemmatization in this comparison. Token F1 of 1.0000 on UD-Seraji, 0.9989 on UD-PerDT and 0.9028 on PEYMA; lemma accuracy of 0.9209 and 0.9316, ahead of Hazm (0.9048 / 0.9009) and Shekar (0.81 / 0.82).
- Morphology in the same core. Stemming, conjugation, inflection, token splitting, spell correction and stopwords — no second library, no extra runtime. On the UD lemma proxy, stemming is 89.2% / 89.5% exact against Hazm (66.4% / 64.4%) and Shekar (76.1% / 72.0%).
- Spell correction that is fast enough to stay in the loop. 80.8% top-1 and 96.2% top-5 on synthetic 1-edit typos, at 0.16 ms per word; Shekar's statistical checker is 60.8% / 77.6% at 94 ms per word on the same set.
- Embeddings without a Python runtime. A 2.3 GB fastText
.vecloads in 5.9 s (Hazm/gensim: 176 s) with bit-identical vectors; sentence pooling is 2.5× faster, nearest neighbours match Hazm's top-10, and batch calls release the GIL. - POS, NER and ezafe without a Python ML stack. Three compact task packs
load through
ModelPackinto the pure-Rust ONNX runtime; no ONNX Runtime, transformers or torch install, and inference releases the GIL. - Millions of tokens per second. 1.0M tokens/s on one thread;
pipe()runs batches in parallel with the GIL released and reaches 6.5M tokens/s on 12 threads. - Everything in one call. Normalization, informal → formal conversion,
tokenization, lemmatization, sentence splitting and ezafe detection from one
Pipelineobject, in about 16 µs per sentence. - Informal Persian handled. Colloquial forms (
اون,خونه,داره,میخوام,چیه) are rewritten to their formal spelling, and fused clitics such asبهشandازشare split intoبه+اوandاز+او. - Nothing to set up. Compiled-in lexicons (190k nouns, 1.2k verb stems, word frequencies, stopwords), no Python dependencies, and no network access for the base pipeline. Optional task packs are separate downloads.
- Wheels for every major platform. Linux (glibc and musl, x86_64 and aarch64), macOS (Intel and Apple Silicon) and Windows, for Python 3.9+ (abi3). The same core is available as a Rust crate.
- Thread-safe. One
Pipelinecan be shared across threads.
Benchmarks
Measured against Hazm and Shekar on the full UD Persian-Seraji, UD Persian-PerDT and PEYMA test sets. Every library is built once and reused.
Core speed (per sentence, single thread)
| Rishe | Hazm | Shekar | |
|---|---|---|---|
| Normalize | 1.2 µs | 96 µs | 104 µs |
| Tokenize | 4.1 µs | 5.7 µs | 4.4 µs |
| Full pipeline | 16.3 µs | — | — |
Core accuracy
| Task | Dataset | Rishe | Compared with |
|---|---|---|---|
| Token F1 | UD-Seraji | 1.0000 | Shekar 0.9992, Hazm 0.9810 |
| Token F1 | UD-PerDT | 0.9989 | Shekar 0.9976, Hazm 0.9609 |
| Token F1 | PEYMA | 0.9028 | Shekar 0.9018, Hazm 0.8901 |
| Lemma accuracy | UD-Seraji | 0.9209 | Hazm 0.9048, Shekar 0.8058 |
| Lemma accuracy | UD-PerDT | 0.9316 | Hazm 0.9009, Shekar 0.8170 |
New feature highlights
| Feature | Metric | Rishe | Hazm | Shekar |
|---|---|---|---|---|
| Stemming | exact UD-lemma proxy (Seraji / PerDT) | 89.2% / 89.5% | 66.4% / 64.4% | 76.1% / 72.0% |
| Conjugation | hand-written spot-check (29 forms) | 29/29 | 28/29 | 29/29 |
| Conjugation | ms/verb | 0.010 | 0.152 | 0.080 |
| Inflection | comparative / superlative / plural | 100% | N/A | 100% |
| Token splitting | ms/token | 0.0006 | 12.05 | N/A |
| Spell correction | top-1 / top-5 on 1-edit typos | 80.8% / 96.2% | N/A | 60.8% / 77.6% |
| Stopwords | list size | 389 | 389 | 301 |
Static embeddings (same 2.3 GB fastText .vec: 884,790 words × 300 dims;
Hazm loads it through gensim 4.4.0)
| Rishe | Hazm/gensim | |
|---|---|---|
| Load | 5.9 s | 176 s |
| Word vectors | identical (max component Δ 0.0) | — |
| Sentence embedding, mean pooling (UD-Seraji) | 0.015 ms | 0.037 ms |
| Word → Python list | 5.9 µs | 5.1 µs |
| Top-10 nearest neighbours | 100% overlap | — |
Rishe loads the same model 30× faster and pools sentences 2.5× faster, with bit-identical word vectors. Word lookup is at parity: both paths build a Python list, which dominates the cost.
The normalizer operators are 1.5–6× faster than Shekar's per operator (the
exception is ya, 0.7×) with exact output agreement of 100% on 8 of 11
operators and 99.04% on verbal spacing. normalize_stages is opt-in; the default
normalize path is unchanged.
The full core tables, batch scaling and method are in docs/BENCHMARKS.md. The feature tables, proxy metrics and caveats are in docs/FEATURE_BENCHMARKS.md.
Reproduce:
python scripts/benchmark.py             # core token/lemma/speed
python scripts/benchmark_features.py   # stemming, conjugation, splitting, spelling
python scripts/benchmark_normalizer.py # 11 normalizer operators vs Shekar/Hazm
python scripts/benchmark_maskers.py    # 12 maskers vs Shekar
python scripts/benchmark_embeddings.py # static embeddings vs Hazm/gensim
Install
pip install rishe # Python >= 3.9
or, from Rust (Cargo.toml): rishe = "0.4".
The base install has no Python dependencies and no model downloads. Optional models are pulled explicitly and nothing touches the network at runtime.
Usage
from rishe import Pipeline
pipe = Pipeline() # unify digits, strip diacritics, fix ZWNJ
doc = pipe("کتابهای خوب را به دوستانم میدهم.")
doc.normalized_text, doc.formal_text, doc.sentences
doc.tokens, doc.lemmas, doc.ezafe_markers
docs = pipe.pipe(texts) # parallel batch -> list[ProcessedDoc]
pipe.normalize("مي كنم 2026") # 'میکنم ۲۰۲۶'
pipe.tokenize("سلام، دنیا!") # raw tokenization, no normalization
pipe.word_tokenize("سلام، دنیا!") # normalize + tokenize
pipe.sent_tokenize(text) # sentence splitting only
pipe.lemmatize("میروم") # 'رفت' (past-stem lemmas, UD style)
pipe.lemma_full("میروم") # ('رفت', 'رو') (past + present stem)
pipe(text) also rewrites colloquial words to formal ones, so its tokens can
differ from the surface text; word_tokenize tokenizes without rewriting.
tokenize is the fast raw path used for the tokenization benchmarks.
Morphology and utilities
pipe.stem("کتابها") # 'کتاب'
pipe.conjugate("رفت")["present"][:3] # ['میروم', 'میروی', 'میرود']
pipe.comparative("بزرگ") # 'بزرگتر'
pipe.superlative("بزرگ") # 'بزرگترین'
pipe.plural("کتاب") # 'کتابها'
pipe.possessive("خانه", 0) # 'خانهام'
pipe.split_token("بهش") # ['به', 'او']
pipe.spell_suggest("سسلام") # ['سلام', 'اسلام', ...]
pipe.spell_correct("سسلام بر ششما") # 'سلام بر شما'
pipe.tokenize_spans("سلام دنیا") # [('سلام', 0, 4), ('دنیا', 5, 9)] (char offsets)
pipe.remove_stopwords(tokens) # drop Persian stopwords
pipe.process_stages(text, ["normalize", "sentences"]) # choose pipeline stages
Normalizer operators
normalize_stages applies the P1 normalizer operators in the order you list them:
alphabet, arabic_unicode, ya, ya_joda, digits, punctuation,
repeated_letters, orthographic_spacing, punctuation_spacing, word_spacing,
verbal_spacing, and spacing (all four spacing operators).
pipe.normalize_stages("﷽ 1𝟮3٤٥⓺", ["arabic_unicode", "digits"])
# 'بسم الله الرحمن الرحیم ۱۲۳۴۵۶'
pipe.normalize_stages("سلام(دنیا) ! می روم", ["punctuation_spacing", "verbal_spacing"])
# 'سلام (دنیا)! میروم'
word_spacing and verbal_spacing validate against the compiled lexicons, so they
only join forms the engine knows (کتاب ها → کتابها, رفته ام → رفتهام).
Unknown stage names raise ValueError.
Masking
mask_stages removes or masks URLs, emails, mentions, hashtags, emoji, HTML
tags, non-Persian letters, stopwords, offensive words, digits, diacritics and
punctuation. Stage names are url, email, mention, hashtag, emoji,
html, non_persian, stopwords, offensive, digits, diacritics and
punctuation.
pipe.mask_stages("سلام @user، به https://rishe.dev یا info@rishe.dev بنویس.",
                 ["url", "email", "mention"])
# 'سلام   به <URL> یا <EMAIL> بنویس.'

pipe.mask_stages("این کتاب است", ["stopwords"], mask_token="[MASK]")
# '[MASK] کتاب [MASK]'
Defaults are <URL> for URLs, <EMAIL> for emails, a space for mentions,
hashtags and HTML tags, and removal for everything else. Pass mask_token to
override all stages. Masking keeps the spaces left behind; run
normalize_stages(..., ["spacing"]) afterwards to collapse them. Unknown stage
names raise ValueError.
Spell correction uses a 190k-word frequency lexicon and edit-distance 1; typos with two or more edits are left unchanged.
Utilities
pipe.number_to_words(1404)                    # 'یک هزار و چهارصد و چهار'
pipe.number_to_words("3.14")                  # 'سه ممیز چهارده'
pipe.ngrams("این یک متن", 1, 2)                # ['این', 'یک', 'متن', 'این یک', 'یک متن']
pipe.persianize("فایل را با کامپیوتر باز کن")   # 'پرونده را با رایانه باز کن'
pipe.persianize_suggest("فایل")               # [('فایل', ['پرونده'], 0, 4)]
flatten(["الف", ["ب", "پ"]])                  # 'الف', 'ب', 'پ'
persianize uses a built-in curated loanword map; persianize_suggest returns
the alternatives and character spans.
Augmentation
keyboard_noise, ocr_noise and whitespace_noise simulate typing, OCR and
spacing errors. Pass seed= for reproducible output.
pipe.keyboard_noise(text, seed=42)
pipe.ocr_noise(text, seed=42)
pipe.whitespace_noise(text, seed=42)
Keywords and transliteration
pipe.rake(text, top_n=5)
pipe.textrank(text, top_n=5)
pipe.to_tajik("خانه")      # 'хона'
pipe.to_persian("хона")    # 'خانه'
Transliteration is a rule-based script mapping; it preserves the consonant skeleton and is not a phonetic translation.
Tokenizer options
pipe.word_tokenize_with("رفته است", join_verb_parts=True)   # ['رفته_است']
pipe.word_tokenize_with("info@a.co", replace_emails=True)   # ['EMAIL']
Options: join_verb_parts, join_abbreviations, separate_emoji,
replace_links, replace_ids, replace_emails, replace_numbers,
replace_hashtags. All are off by default, so plain word_tokenize is
unchanged.
Embeddings
Static fastText/word2vec vectors load from a .vec file into the Rust core and
stay there: lookups and sentence pooling run without Python objects, numpy or
gensim, and the model is shared read-only across threads. Downloads are
explicit and checksum-verified:
rishe hub pull hazm-fasttext-300 # 2.3 GB, cached in ~/.cache/rishe/models
from rishe import Embeddings, hub

emb = Embeddings(hub.path("hazm-fasttext-300"))
emb.dim, len(emb)                     # vector size, vocabulary size
emb.vector("کتاب")                    # list[float] or None
emb.similarity("کتاب", "دفتر")         # cosine or None
emb.sentence_vector("این کتاب خوب است") # mean of in-vocab token vectors
emb.sentence_vectors(["یک متن", "متن دیگر"])  # parallel, GIL released
emb.most_similar("کتاب", 5)           # [(word, cosine), ...]
Out-of-vocabulary tokens are skipped in sentence vectors; vector() and
similarity() return None. RISHE_HOME overrides the cache root, and
rishe.hub.pull(url, sha256=...) pulls a custom model. Only .vec text files
are supported: fastText .bin and GloVe files are not.
Model packs
POS tagging, NER and ezafe detection ship as three compact task packs. Each pack is a separate, checksum-verified download (under 50 MB; the model is 45 MB and the tokenizer adds 2.4 MB); the base install stays free of Python ML dependencies. The packs run on the pure-Rust runtime inside Rishe, so there is no ONNX Runtime install and no Python tokenizer stack.
rishe hub pull pos-compact # also: ner-compact, ezafe-compact
from rishe import ModelPack, hub
pos = ModelPack(hub.path_pack("pos-compact"))
pos.tag("کتابهای خوب را به دوستانم میدهم.")
# [('کتابهای', 'NOUN'), ('خوب', 'ADJ'), ('را', 'ADP'), ('به', 'ADP'),
# ('دوستانم', 'NOUN'), ('میدهم', 'VERB'), ('.', 'PUNCT')]
pos.tag_words(["کتابهای", "خوب"]) # pre-tokenized input
ner = ModelPack(hub.pull_pack("ner-compact"))
ner.tag("سرلشگر فیروزآبادی به پادشاه عربستان گفت.")
# [..., ('فیروزآبادی', 'B_PER'), ..., ('عربستان', 'B_LOC'), ...]
ezafe = ModelPack(hub.pull_pack("ezafe-compact"))
ezafe.tag_words(["کتابخانه", "مرکزی", "دانشگاه", "شریف"])
# [('کتابخانه', 'EZAFE'), ('مرکزی', 'EZAFE'), ('دانشگاه', 'EZAFE'),
# ('شریف', 'NO_EZAFE')]
ModelPack releases the GIL during inference. hub.pull_pack(name) downloads
and returns the directory; hub.path_pack(name) returns an existing cache entry
and raises if it is not there. From Rust, enable the models feature (this
optional feature needs Rust 1.91; the default crate still builds on 1.75) and
call rishe::models::ModelPack::load(path)?.tag_text(text)?.
Corpora
from rishe import ConlluReader, PeymaReader, PlainTextReader

for sentence in ConlluReader("data/corpora/fa_perdt-ud-test.conllu"):
    print(sentence.text, sentence.tokens[0].lemma)
ConlluReader parses UD/CoNLL-U, PeymaReader parses the PEYMA test format,
and PlainTextReader reads one sentence per line. Other corpus-specific formats
can be added as needed.
CLI
rishe normalize "مي كنم"
rishe tokenize "سلام دنیا" --json
rishe mask "info@a.co" --stages email
printf '%s\n' '{"command":"tokenize","text":"سلام دنیا"}' | rishe serve
Convenience classes
Module-level helpers have object-style counterparts when you want a long-lived instance instead of building one per call:
from rishe import Lemmatizer, Normalizer, WordTokenizer, Stemmer
normalizer = Normalizer()
normalizer.normalize("مي كنم") # 'میکنم'
lemmatizer = Lemmatizer()
lemmatizer.lemmatize("میروم") # 'رفت#رو' (past#present)
WordTokenizer().tokenize("رفته است") # ['رفته_است']
Normalizer, WordTokenizer, SentenceTokenizer, Lemmatizer, Stemmer and
TokenSplitter are all available this way, plus the module-level
word_tokenize and sent_tokenize. They take no lexicon paths: Rishe compiles
its lexicons in.
Rust
use rishe::Pipeline;
let pipe = Pipeline::create(true, true, true);
let doc = pipe.process("کتابهای خوب را به دوستانم میدهم.");
println!("{:?}", doc.tokens);
println!("{}", pipe.stem("کتابها"));
Scope
Rishe is a text-preprocessing and morphology engine: normalization, tokenization, sentence splitting, lemmatization, stemming, verb conjugation, inflection, token splitting, spell correction, stopword removal, ezafe detection, informal → formal conversion and static word/sentence embeddings.
Optional model packs add POS tagging, NER and a learned ezafe tagger. They are
separate downloads from the Hugging Face Hub, so the base install stays
zero-dependency and fast. The 0.5.0 engine loads the packs directly with
ModelPack; no ONNX Runtime install is needed.
Dependency parsing, chunking, contextual embeddings and text classification are not in the base yet.
Building from source
cargo test
maturin develop --release     # Python extension into the current venv
python scripts/benchmark.py   # needs: hazm shekar conllu
python scripts/benchmark_features.py
scripts/extract_lexicons.py regenerates data/*.tsv and
data/word_freq.tsv from Hazm's data files; build.rs compiles them into FSTs.
License
Dual-licensed under Apache-2.0 or MIT, at your option. The bundled lexicons, stopwords and word frequencies are derived from Hazm data (MIT); see NOTICE.md.
1 maintainer

Metadata
1 maintainer
Release files for rishe 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| rishe-0.5.0.tar.gz | 1.8 MB | With provenance | Details |
Built distributions (wheels)
| File | Reset | |||
|---|---|---|---|---|
| rishe-0.5.0-cp39-abi3-win_amd64.whl | CPython 3.9 | abi3 | Windows x86-64 | Details |
| rishe-0.5.0-cp39-abi3-musllinux_1_2_x86_64.whl | CPython 3.9 | abi3 | Linux musl 1.2+ x86-64 | Details |
| rishe-0.5.0-cp39-abi3-musllinux_1_2_aarch64.whl | CPython 3.9 | abi3 | Linux musl 1.2+ ARM64 | Details |
| rishe-0.5.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl | CPython 3.9 | abi3 | Linux glibc 2.17+ x86-64 | Details |
| rishe-0.5.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl | CPython 3.9 | abi3 | Linux glibc 2.17+ ARM64 | Details |
| rishe-0.5.0-cp39-abi3-macosx_11_0_arm64.whl | CPython 3.9 | abi3 | macOS 11.0+ ARM64 | Details |
| rishe-0.5.0-cp39-abi3-macosx_10_12_x86_64.whl | CPython 3.9 | abi3 | macOS 10.12+ x86-64 | Details |
Total release size: 81.4 MB
Release files / rishe-0.5.0.tar.gz
| Download URL | rishe-0.5.0.tar.gz |
|---|---|
| Size | 1.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1a4f2218a6d371bcf5c739d96a3f498af4df9bee3ffaf2d3d2071352ad4636f4
|
|
BLAKE2b-256 checksum How to use checksums |
2987bda33d2c4c13c4c2ea8067466d5e7fe4c2c3ca649f2f365e94d5f54ebb15
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-win_amd64.whl
| Download URL | rishe-0.5.0-cp39-abi3-win_amd64.whl |
|---|---|
| Size | 10.4 MB |
| Tags | CPython 3.9 Windows x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
d424ad985ba0ab734af0a7d9abf8255f5ecc832991c9201e9b1ed0ea1060523d
|
|
BLAKE2b-256 checksum How to use checksums |
100cb12310b67fec0d171b6de5973ae9e8af3f9d0fd53d62fb950e1a90a03c08
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-musllinux_1_2_x86_64.whl
| Download URL | rishe-0.5.0-cp39-abi3-musllinux_1_2_x86_64.whl |
|---|---|
| Size | 12.8 MB |
| Tags | CPython 3.9 Linux musl 1.2+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
178ba6201a2d993073848ae0e21afda53a0e0ba3fa80ad42f3556b2d35bf560a
|
|
BLAKE2b-256 checksum How to use checksums |
a7c96271f56b18c9d9b432d1130476a1302d48f81eacd410fa64a8c923b24c1e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-musllinux_1_2_aarch64.whl
| Download URL | rishe-0.5.0-cp39-abi3-musllinux_1_2_aarch64.whl |
|---|---|
| Size | 11.8 MB |
| Tags | CPython 3.9 Linux musl 1.2+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
7c7a782baf6596f780a28e68e0e2934dbf238f4eb779b9ba86d4321c0accfdda
|
|
BLAKE2b-256 checksum How to use checksums |
3257ad2d890f7cb40fb766e5662fa7915a21ebe73a5648c5673155c98d664ef3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl
| Download URL | rishe-0.5.0-cp39-abi3-manylinux_2_17_x86_64.manylinux2014_x86_64.whl |
|---|---|
| Size | 11.8 MB |
| Tags | CPython 3.9 Linux glibc 2.17+ x86-64 abi3 |
|
SHA-256 checksum How to use checksums |
c09e7040e00566af5be94e91edb647a1b9c5aff9c4ec74e5a34cb8f6a28ad7f8
|
|
BLAKE2b-256 checksum How to use checksums |
3dcb40be5c1ab27f761e5523a6ada6a369bf19d206d3d1b2be56b8572c122e83
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl
| Download URL | rishe-0.5.0-cp39-abi3-manylinux_2_17_aarch64.manylinux2014_aarch64.whl |
|---|---|
| Size | 11.6 MB |
| Tags | CPython 3.9 Linux glibc 2.17+ ARM64 abi3 |
|
SHA-256 checksum How to use checksums |
d73aed6267a004ae28418428daaedc8f8e9e0f1b350353e0e3e0bdb9e84518a3
|
|
BLAKE2b-256 checksum How to use checksums |
b76cc3fd3c48d91e856dd01505fdc447be374dbe9fa93000d3cd7fd116980965
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-macosx_11_0_arm64.whl
| Download URL | rishe-0.5.0-cp39-abi3-macosx_11_0_arm64.whl |
|---|---|
| Size | 10.2 MB |
| Tags | CPython 3.9 abi3 macOS 11.0+ ARM64 |
|
SHA-256 checksum How to use checksums |
e050067b8216eee6a91e838a96dd9fa8471794b1d9f167804af51ae4693c5bbb
|
|
BLAKE2b-256 checksum How to use checksums |
72c7df9da6c95c11a841ec639c1ee8049d7acfba34d0a4e7ed1bd43955bc15f2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logRelease files / rishe-0.5.0-cp39-abi3-macosx_10_12_x86_64.whl
| Download URL | rishe-0.5.0-cp39-abi3-macosx_10_12_x86_64.whl |
|---|---|
| Size | 11.0 MB |
| Tags | CPython 3.9 abi3 macOS 10.12+ x86-64 |
|
SHA-256 checksum How to use checksums |
31ec58f415869d6d32982e0db959665138b794aa6581ae92e79ae308bbc3a4a9
|
|
BLAKE2b-256 checksum How to use checksums |
be7d8e0b72249b046ee2a9666d4e4310e5558997512f84ba113712922e19945b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logSecurity for rishe 0.5.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 8 files in this release have been uploaded with provenance metadata.
Attestation for rishe-0.5.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 25, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














