
scale-forecasting
Enterprise time-series forecasting on Google Cloud — from 10 series on a laptop to 100,000+ in BigQuery, with one JSON configuration and no idle compute.


37 models · 5 families · 21 evaluation metrics · 7 Google Cloud runtimes · 5 Analytical SQL Views · validated at 100k series
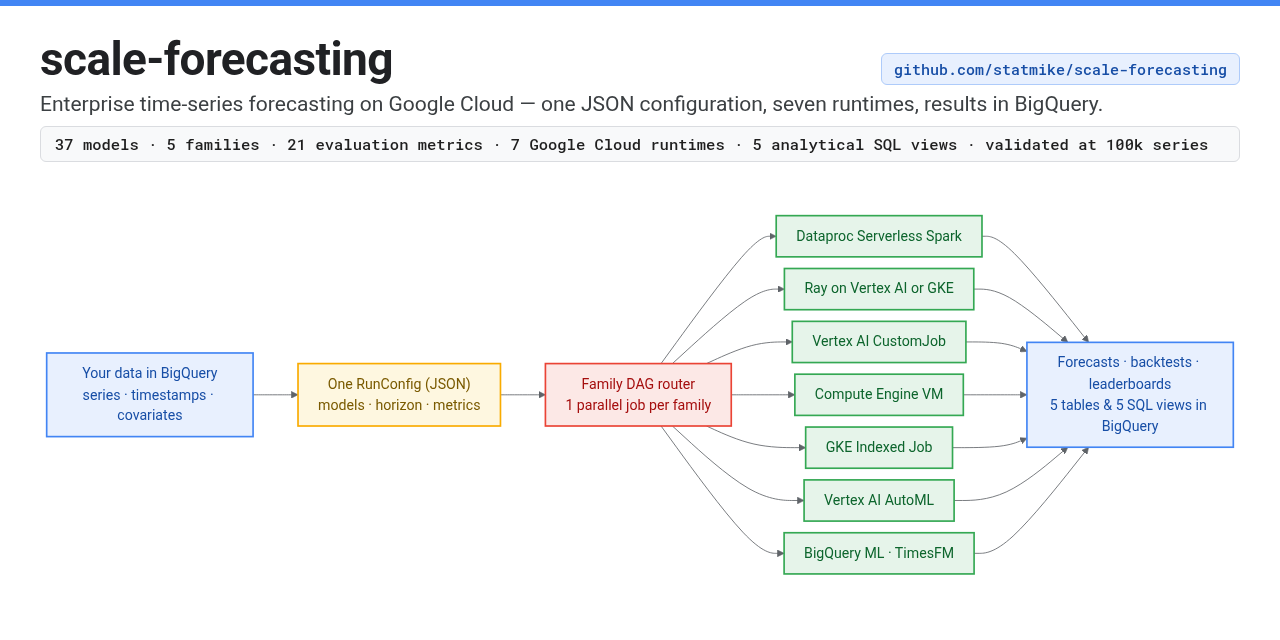
What you just found
You describe what to forecast in one JSON file — the BigQuery table, the horizon, the models, the covariates, and the evaluation metrics. scale-forecasting decides how: it splits active models into up to five family jobs, dispatches each family in parallel to the Google Cloud runtime you chose for it, scores every model with rolling-origin backtesting and conformal prediction intervals, blends the winners into ensembles, reconciles hierarchical trees, and streams forecasts, leaderboards, and feature attributions back to BigQuery. When the run ends, the compute is gone.
- Use
scale-forecastingwhen you want to evaluate or operate multiple model families (statistical, gradient-boosted trees, PyTorch deep learning & open-weight foundation models, Vertex AI AutoML, and BigQuery ML) under one schema, one backtest contract, and one BigQuery leaderboard — from a handful of series to 100,000+. - Use a simpler path when a single SQL query (
AI.FORECASTorARIMA_PLUSdirectly in BigQuery) already answers the question; you can still adoptscale-forecastinglater to benchmark that SQL baseline against 35 Python and AutoML models on the same holdout folds.
Three ways to start
Journey 1 — Try it locally in 5 minutes (no cloud, no credentials)
Install the pure offline package (or clone the repo and run uv sync) to fit models, run backtests, and inspect metrics in memory on your machine:
pip install scale-forecasting
python -m scale_forecasting.playground --list
python -m scale_forecasting.playground --model theta --backtest --horizon 14
import scale_forecasting as sf
from scale_forecasting import playground

result = playground.run_one(model="theta", horizon=14, backtest=True)
plan = sf.Forecaster.from_file("configs/ensemble_demo.json").dry_run()
print(result.metrics["wape"], plan.run_id)
Continue in notebooks/00_model_playground.ipynb or Getting started (docs/getting_started.md).
Journey 2 — Deploy to your Google Cloud project in 15 minutes
Provision the BigQuery dataset, Cloud Storage buckets, least-privilege service accounts, VPC networking, container image, Colab Enterprise runtime template, and 100,000-series seed dataset with two Terraform stages:
cd terraform/bootstrap && terraform init
terraform apply -var="project_id=YOUR_PROJECT_ID" -var="billing_account=YOUR_BILLING_ID"

cd ../main && terraform init
terraform apply -var="project_id=YOUR_PROJECT_ID"
Estimated cost & ongoing services: One-time provisioning (Cloud Build image build + Dataproc Serverless 100k seed batch) costs an estimated ~$0.15–$0.50. At rest, datasets, buckets, VPC networking, and service accounts have no running compute cost (only standard Cloud Storage and BigQuery storage rates for stored bytes). Forecast runs bill only while batches, VMs, pods, or queries execute. Always-on disclosure: Cloud Composer 3 (
create_composer = falseby default) and standing GKE clusters incur continuous hourly charges while provisioned. Seedocs/deploying_on_gcp.mdandterraform/README.md.
Journey 3 — Run 100,000+ series on Google Cloud
Launch any declarative configuration from the CLI, Python SDK, or a generated Cloud Composer 3 DAG:
# Run directly from the CLI or stage native gcloud / kubectl / bq / ray commands
python -m scale_forecasting.main --config configs/ensemble_demo.json
python -m scale_forecasting.main --config configs/spark_serverless_100k.json --emit-airflow dags/sf_100k.py
Full operator loop: Running and reviewing (docs/running_and_reviewing.md) and Platform overview (docs/overview.md).
AI agents, portable skills & built-in MCP server
scale-forecasting is ready out of the box for Google Antigravity (agy CLI & IDE), Claude Code, Cursor, VS Code Copilot, and Windsurf — shipping a portable SKILL.md (auto-discovered via .agents/skills.json), an Antigravity plugin.json + mcp_config.json, a built-in MCP server (python -m scale_forecasting.mcp), a Draft 2020-12 RunConfig JSON Schema, and llms.txt / llms-full.txt compiled directly from code (make agent-surfaces):
# Probe installed extras, available models, and SF_* readiness:
python -m scale_forecasting.agent_surfaces --probe-env

# Launch Google Antigravity CLI (auto-discovers .agents/skills/ & AGENTS.md) or register MCP:
agy
claude mcp add scale-forecasting -- python3 -m scale_forecasting.mcp
Full setup and architectural guide: AI Agents, Portable Skills & Built-in MCP Server (docs/agent_and_mcp_guide.md).
One configuration, every engine
Every run is a validated RunConfig (such as configs/ensemble_demo.json). To move a model family between Dataproc Serverless, Ray, Vertex AI CustomJob, Compute Engine, or GKE, change compute.families.<family>.runtime — nothing else:
{
  "run_name": "hybrid_stacked_ensemble",
  "data": {"source_table": "source_series_iceberg", "series_limit": 100, "horizon": 14},
  "models": ["theta", "holtwinters", "xgboost", "arima_plus"],
  "compute": {
    "families": {
      "statistical": {"runtime": "spark"},
      "ml": {"runtime": "spark"}
    }
  },
  "backtest": {"enabled": true, "scheme": "expanding", "n_folds": 3, "decision_metric": "wape"},
  "ensemble": {"enabled": true, "strategies": ["mean", "inverse_error", "nnls", "xgb"]}
}
Why Google Cloud for forecasting at any scale
| Pillar | What it means for you | Proof in this repository |
|---|---|---|
| Data stays in BigQuery | Workers read source tables via the BigQuery Storage Read API with contiguous per-worker [start_id, end_id] pushdown and stream results back through the Storage Write API. |
docs/reading_source_data.md · docs/writing_results.md |
| Compute only while it runs | Active model families launch in parallel (dag.py); fast CPU families tear down immediately while GPU families finish; single-VM GCE enforces triple-redundant self-deletion. |
docs/runtimes_reference.md · docs/architecture.md |
| Seven runtimes, one contract | Run spark, ray, vertex, gce, gke, vertex_automl, and bigquery concurrently under one run_id across CPU and NVIDIA T4, L4, A100, A100_80GB GPUs. |
docs/runtimes_reference.md · docs/validation.md |
| Managed and open models on one leaderboard | Benchmark BigQuery ML (ARIMA_PLUS, AI.FORECAST / timesfm / bq_timesfm) and Vertex AI AutoML alongside 31 open-source statistical, tree, deep learning, and foundation models (chronos_bolt, chronos2, timesfm_torch) on identical folds. |
docs/models_reference.md · docs/output_schemas.md |
| Governed by construction | Content-addressed run_id, snapshot-pinned reads, 5 registry tables, 5 analytical SQL views, surgical cell repair (retry_run), and 42 live-validated smoke configurations. |
docs/output_schemas.md · docs/operations.md · docs/validation.md |
| Modular install & 1-file extensibility | pip install scale-forecasting has zero Google Cloud dependencies; [gcp], [spark], [ray], [models], and [all] are opt-in extras; new models ship in 1 file with no image rebuild. |
docs/runtime_dependencies.md · docs/adding_a_model.md |
What's inside
| Family | Models (37 total) |
Runtimes | Highlights |
|---|---|---|---|
statistical (18) |
theta, auto_theta, holtwinters, autoets, auto_arima, sarimax, tbats, auto_ces, stl_bagging, ucm, kalman, prophet, croston, fft, naive_mean, naive_seasonal, naive_drift, naive_moving_average |
spark, ray, vertex, gce, gke |
Fast local baselines, state-space, intermittent demand, and harmonic decomposition. |
ml (5) |
lightgbm, xgboost, catboost, random_forest, regression_lags |
spark, ray, vertex, gce, gke |
Lag/calendar/exogenous features plus Tier 1 & Tier 2 TreeSHAP / linear / deviation attributions. |
deep_learning (8) |
tide, tft, tsmixer, patchtst, neuralprophet, chronos_bolt, chronos2, timesfm_torch |
spark, ray, vertex, gce, gke |
Trained PyTorch ([models-dl]) and open-weight zero-shot foundation ([models-foundation]) models across local, global, and hybrid regimes on CPU or GPU. |
automl (4) |
vertex_l2l, vertex_tide, vertex_tft, vertex_seq2seq |
vertex_automl |
Managed Vertex AI Tabular Workflows & AutoML training jobs with Stage-1 HPO reuse and baseline attributions. |
native (2) |
arima_plus (ARIMA_PLUS / ARIMA_PLUS_XREG), timesfm / bq_timesfm (AI.FORECAST) |
bigquery |
Pure BigQuery SQL execution with future covariates (ARIMA_PLUS_XREG), ML.EXPLAIN_FORECAST attributions, and zero cluster provisioning. |
- Evaluation, quantiles & calibration: 21 evaluation metrics (16 point + 5 interval:
wape,smape,mape,maape,ope,mae,rmse,mse,rmsle,bias,mase,mase_seasonal,rmsse,msse,r2,cv,coverage,pinball,interval_score,interval_width,msis), empirical conformal prediction intervals, monotone multi-percentile fans (output.quantileswith Chernozhukov rearrangement), and Newsvendor asymmetric cost targets (underage_cost/overage_cost) (docs/metrics_reference.md). - Hierarchy, smart ensembles & explainability: All 8 Hyndman FPP3 reconciliation methods (including active-set non-negative
"mint_nonneg"alongsidemint_shrink,wls_var,wls_struct,ols,bottom_up,top_down,middle_out), 8 ensemble strategies (mean,median,inverse_error,champion,horizon_specialist,nnls,ridge,xgb) withtop_k&parsimony_marginpruning and calibrated ensemble intervals, physical bounds (floor,cap,cumulative_round), and two-tier feature attributions (attributions_df/plot_attributions). - Forecaster workbench, econometrics, inventory policy & executive reports: Pre-fit data hygiene & SBC demand regime routing (
smooth,erratic,intermittent,lumpy), Forecast Value Added (compute_fva) with Harvey–Leybourne–Newbold (1997) modified Diebold–Mariano $p$-values, lead-time horizon decay, Trigg tracking-signal bias audits, AR(1)-aware time rollups (rollup_time) and replenishment policy translators (compute_inventory_policy/inventory_policy_dffor $(s, S)$, $(R, S)$, Fill Rate, and Newsvendor safety stock, reorder point, and EOQ), counterfactual promo/price scenario simulation (simulate_scenarios), live drift & whipsaw stability scoring, Top-$N$ exception triage (exceptions_df), and self-contained interactive HTML/JSON reports (python -m scale_forecasting.report) (docs/forecaster_workbench.md).
Learn by doing (11 notebooks across 4 tracks)
All notebooks in notebooks/ include committed outputs and one-click Colab Enterprise launch links:
- Track 1 — Local sandbox & plugins (no GCP setup):
00_model_playground.ipynb·09_custom_models_and_metrics.ipynb - Track 2 — Cloud runtimes:
01_bigquery_native_sql.ipynb·02_vertex_and_gce_vms.ipynb·03_spark_serverless_and_connect.ipynb·04_ray_on_vertex_gpu.ipynb - Track 3 — Covariates, hierarchy, HPO & ensembles:
05_covariates_and_global_models.ipynb·06_hierarchical_reconciliation.ipynb·07_hpo_backtesting_and_ensembles.ipynb - Track 4 — Master multi-engine DAG & operations:
08_multi_engine_master_workflow.ipynb·10_registry_operations_and_scale.ipynb - Team lab: Hands-on workshop guide (
docs/workshop.md)
Where next
- Start here: Getting started · Platform overview · Forecaster workbench · AI agents, skills & MCP · Choosing a runtime · Cost estimates & controls · Why Google Cloud · FAQ · Glossary · Documentation map
- Reference: Compute runtimes · Configuration · Models & ensembles · Evaluation metrics · Output schemas & views
- Operate & extend: Python SDK (
Forecaster) · Running & reviewing · Operations & repair · Quota & 100k scale · System validation ledger · API reference
License
Apache-2.0 — see LICENSE.
This is not an officially supported Google product. It is built on Google products and is neither endorsed nor supported by Google.
1 maintainer

Metadata
1 maintainer
Release files for scale-forecasting 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| scale_forecasting-1.2.0.tar.gz | 1.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| scale_forecasting-1.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.2 MB
Release files / scale_forecasting-1.2.0.tar.gz
| Download URL | scale_forecasting-1.2.0.tar.gz |
|---|---|
| Size | 1.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
12afa9b3c7bc3e27233e92418af20662e95da130d4ae47559e6310289269b115
|
|
BLAKE2b-256 checksum How to use checksums |
18def7e40f0511cea89a48127b93562a93d43c49303a31b689a46bef3fa1c4f5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / scale_forecasting-1.2.0-py3-none-any.whl
| Download URL | scale_forecasting-1.2.0-py3-none-any.whl |
|---|---|
| Size | 1.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ec2e359e9f6def86ca16c5485723944143bc6ba48e126d7c19ccf4fed8734177
|
|
BLAKE2b-256 checksum How to use checksums |
8532d7a930e4502c7318dc253c863ca639965b7ffd427ff8b8776ff1b478e203
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log













