
searchts
A keyless web unlocker and reader for AI agents. (Off the record: "search this shit".)
It reads the page, or it tells your agent plainly that it can't.
When Claude, Cursor, Codex or another agent fetches a URL, it regularly comes back with junk: a 403 bot wall, an empty JavaScript shell, a truncated AI-chat share link, or a login screen that the model happily summarizes as if it were the article. searchts is the reader your agent calls instead. It is open source (MIT), free, needs no API key, refuses paid residential proxies by default, and runs as an MCP server, a CLI or a Python library.




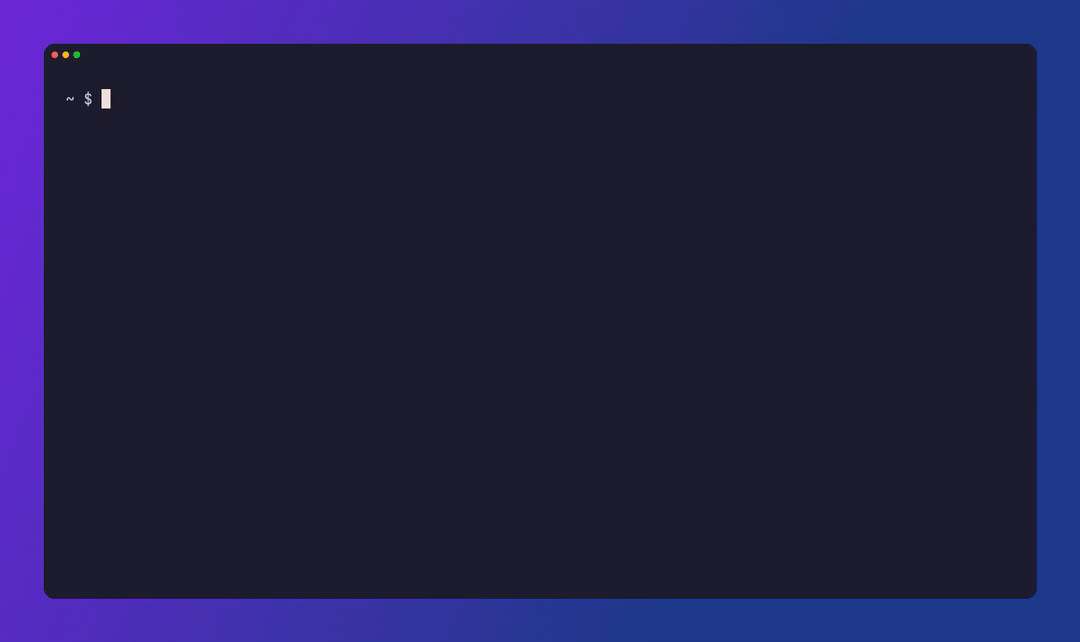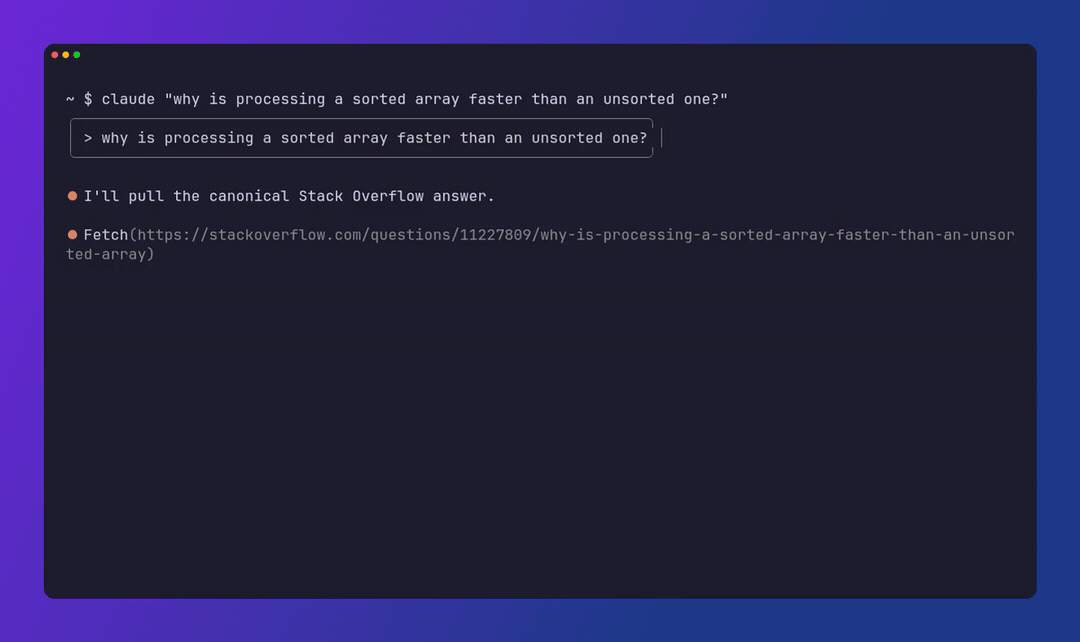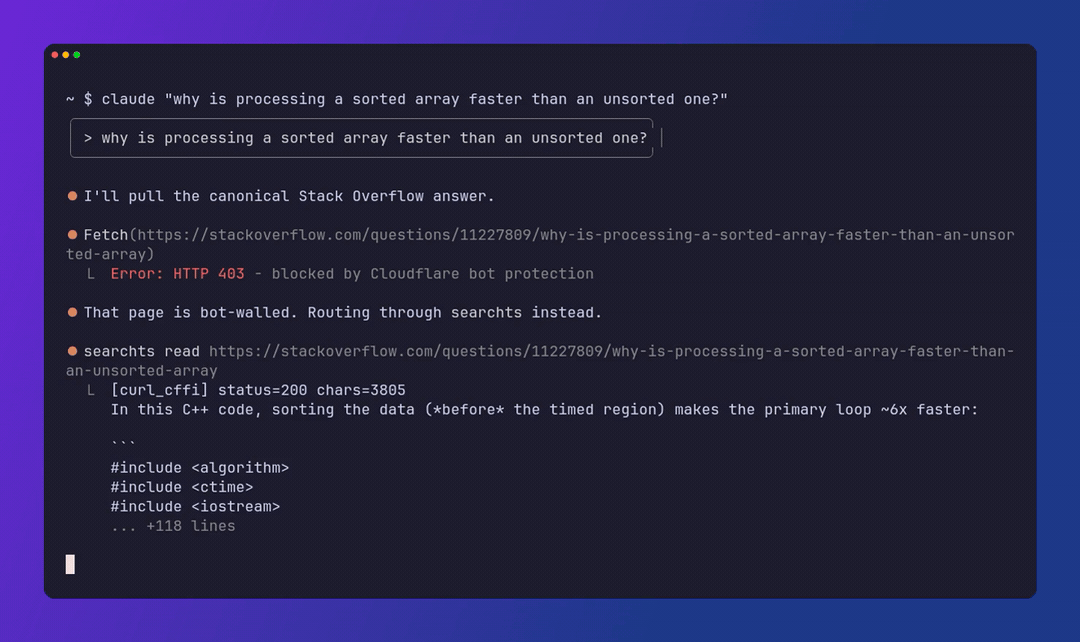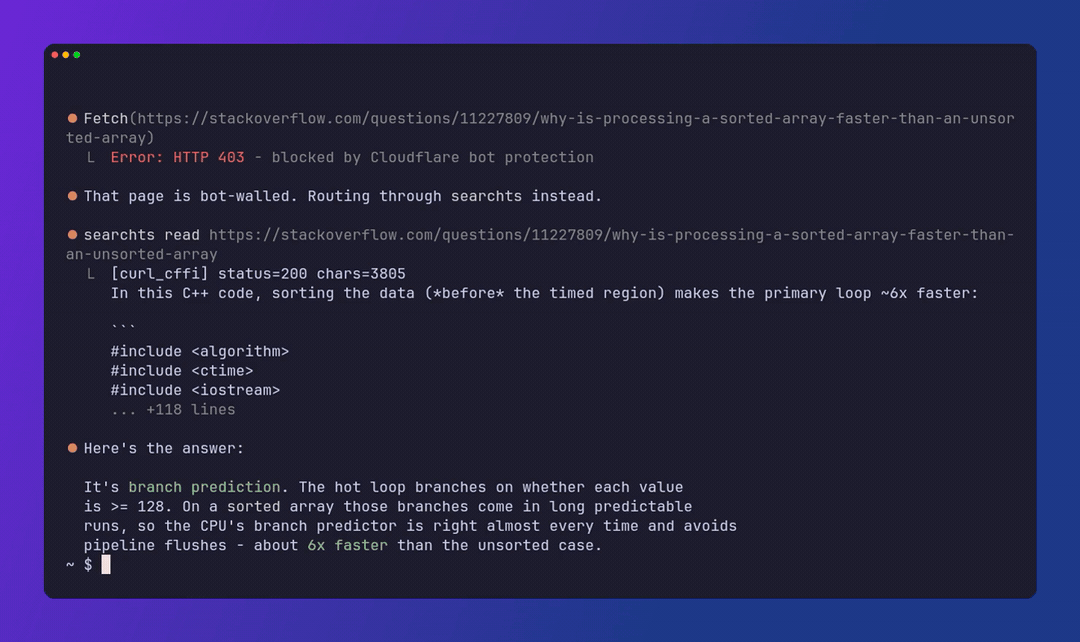
▶ Watch the full 1-minute demo
One-line agent install
Add searchts to Claude Code, Cursor or any MCP client in one command. No API key:
claude mcp add searchts -- uvx --from "searchts[mcp]" searchts mcp serve
Keep it globally and add the stealth browser, which the hardest rungs use:
pipx install "searchts[mcp]" && searchts install --browser
claude mcp add searchts -- searchts mcp serve
Install covers uvx, pipx, venv and the browser extra. The CLI, the MCP server and the Python library all call the same read path.
Three things your agent's built-in fetch can't do
1. Decode full ChatGPT, Claude, Gemini, Grok, Poe, DeepSeek, Perplexity and Copilot share links
A shared conversation never sits in the initial page HTML as plain text. A raw fetch gets a JavaScript shell; a renderer can still cut the chat off mid-thread. searchts read recognizes share URLs and decodes each provider's own data channel into complete, role-labeled Markdown, keyless and without logging in:
searchts read https://chatgpt.com/share/...        # turbo-stream payload in the page (no browser)
searchts read https://claude.ai/share/...          # keyless snapshot API behind Cloudflare (no browser)
searchts read https://gemini.google.com/share/...  # keyless batchexecute RPC (no browser)
searchts read https://chat.deepseek.com/share/...  # stealth render, auto-scrolls past list virtualization
Eight providers: ChatGPT (both /share/<uuid> and the newer /s/<prefix>_<id> short links), Claude, Gemini, Grok, Poe, DeepSeek, Perplexity and Copilot. The first five need no browser. The last three reuse the stealth tier, scroll until the page height stops changing, open the folds, then read.
2. Escalate past bot walls, or fail loudly instead of hallucinating on a login screen
Every searchts read walks a three-tier open-source unlocker and remembers which rung worked per domain:
curl_cffiimpersonates a real Chrome TLS/JA3 and HTTP/2 fingerprint. Fast, local, private.- Jina Reader (
r.jina.ai) renders JavaScript when the page only fills in after it runs. Default on;SEARCHTS_NO_JINA=1keeps the URL off Jina's servers. patchrightis a lazy stealth Chromium, started only when the cheaper tiers fail.--humanopens a real browser when only a person can clear the page.
searchts read https://some-js-heavy-or-fingerprinted-site.com --scrub
# Tier 1 (curl_cffi) -> 403 | Tier 2 (Jina) -> clean Markdown returned, injection scrubbed

searchts read https://www.linkedin.com/in/someone/
# Fails loudly: reports the exact tier and login-wall reason. stdout stays empty.
--scrub strips invisible and bidi characters and flags prompt-injection indicators before untrusted text reaches your model.
A login you hand over is different from a login searchts guesses. In 0.15.0, local reuse is opt-in and fenced to the one host in the command: --cookies-from-browser <browser> --yes, --cookies <path>, or --cdp-port <port>. Without one of those, a wall is an error, not an article.
3. Transcribe videos and grab fingerprint-gated design assets
searchts transcribe https://youtu.be/...                     # YouTube, TikTok, Instagram Reels, Reddit
searchts transcribe https://www.instagram.com/reel/... --cookies-from-browser chrome
searchts grab https://stripe.com --kinds images,fonts,svg --read --out ./stripe-kit
Transcription is subtitles-first, then yt-dlp audio plus Whisper when there are no captions. grab extracts a page's images, icons, CSS, fonts, SVGs and color palette through the same unlocker, so it works on fingerprint-gated CDNs, not just open ones.
Why it exists
I built searchts because Claude kept running into walls when I asked it to read the web for me. The trigger was a Devpost hackathon page and its terms: the page wasn't even walled, and Claude still couldn't read it.
The first versions, which I built with Claude, failed the other way. When they couldn't get a page, they handed back whatever they got, and the agent summarised a loading screen as if it were the article. So searchts has one rule above the rest: return the real page, or fail loudly and say why. It never hands your agent a fake read.
How searchts compares
searchts grew out of Agent-Reach's channel/doctor scaffolding, then replaced the read/search core with an escalating unlocker, share-link decoders and an MCP server.
| Capability | Built-in WebFetch / curl |
Agent-Reach | Hosted scrapers (Firecrawl, Jina Pro) | searchts |
|---|---|---|---|---|
| Architecture | Naive HTTP fetch | Installer and per-platform routers for third-party CLIs (yt-dlp, OpenCLI, Jina) |
Hosted fetch + scraper fleet | Local escalating unlocker + MCP server + CLI |
| Bot / JS escalation | None | One Jina Reader hop for the web | Hosted proxies and rendering | curl_cffi (TLS/JA3) → Jina → patchright stealth + --human |
| Login or block | Hands 200 OK login HTML to the model, or errors | Depends on the upstream CLI and its session | Credits, limits, or partial HTML | Fails loudly with the tier and reason; local login reuse is opt-in |
| AI-chat share links | Empty JS shell or truncated | No share-link decoder; depends on Jina | Renderer can cut long chats | Native decoders + auto-scroll stealth render (8 providers) |
| Web search | None | Exa via mcporter |
Paid search endpoint | Keyless DuckDuckGo + RRF across SearXNG / Exa / Brave / Tavily |
| Prompt-injection scrubbing | None | — | — | Built-in (--scrub) |
| Benchmark | None | None | Marketing pass rates | Reproducible two-suite scorecard (Smoke vs Walled) |
| Default cost | Free | Free, plus the CLIs it installs | API key and per-page credits | Free, MIT, keyless (no paid residential proxy by default) |
What it does
- Reads pages your agent's own fetch can't: browser-fingerprint checks, JavaScript-only pages and some bot walls
- Fails loudly when the read is not the real page (a login the user did not hand over, a puzzle that needs a person, a block that is the address) and says which tier failed and why
- Reads complete ChatGPT / Claude / Gemini / Grok / Poe / DeepSeek / Perplexity / Copilot shared conversations
- Works with Claude, Codex, and MCP agents
- Extracts clean Markdown, ready to feed a model
- Says when a page has more than it returned (a next page, a feed, folded text) and rebuilds search results and feeds the extractor mangles
- Searches the web without API keys
- Downloads a page's assets (images, fonts, palette)
- Transcribes videos, subtitles-first
Why the package is free
The package you install is free and keyless. The fetch and the browser run on your machine, from your connection. It does not bundle a residential proxy. Jina Reader, the one hosted rung, is free and can be turned off. That is not a promise that every hard page is free forever. A read that needs an exit we operate is a different product, not a default of this package. The scorecard is what this build actually read, not a list of walls that can never be passed.
The unlocker
searchts reads any URL through an escalating ladder and stops at the first tier that returns real content:
- curl_cffi: a fetch that impersonates a real Chrome's TLS/JA3 and HTTP2 fingerprint. Beats user-agent and fingerprint filters. Fast, local, private.
- Jina Reader: a JavaScript-rendering relay (
r.jina.ai), for pages that only fill in content after running JS. Default on — the target URL is sent to Jina's servers on this rung. Opt out withSEARCHTS_NO_JINA=1or configjina: false(local curl + stealth only). - stealth browser: an undetected headless Chromium (patchright), launched lazily only when the cheaper tiers fail, for live JS / Cloudflare managed challenges.
If no tier comes back with real content, an optional human-in-the-loop step opens a real browser so you can clear the page once and continue. That covers interactive CAPTCHAs and soft walls alike: a login page served as HTTP 200 is not a challenge, but it is still a page only a human gets past. Block detection is phrase-based (not vendor-name based), so legitimate pages that merely embed a bot-sensor script are not falsely rejected. Content is extracted to clean Markdown with trafilatura.
What it won't do. It will not pretend a wall page is the article. A login the user did not hand over still fails, with the reason. Local reuse shipped in 0.15.0, only when you hand searchts a session for the one site in the command (--cookies-from-browser <browser> --yes, --cookies <path>, or --cdp-port <port>). A Chrome cookie file that App-Bound Encryption locks is never decrypted; start Chrome with a debugger port instead. Signing in on a remote browser is not built (F27). A DataDome device-check is not a permanent failure: the stealth browser is supposed to let that script finish, and to take a simple click (continue, a checkbox, a press-and-hold that is one action). A puzzle that asks a person to recognize images still stops. The package will not route you through a paid residential proxy by default. A release never claims a site reads until it does. datadome.co is still a fail on the current scorecard. That is a measurement, not a rule.
AI-chat share links
Share links from AI chat apps are a special kind of hard: the conversation never appears in the page HTML as extractable text, so a raw fetch returns an empty shell, and a renderer can still cut it off mid-chat. searchts read recognizes these URLs and decodes each provider's own data channel instead, returning the complete conversation as role-labeled Markdown — keyless, no login:
| Provider | Share URL | How it's read |
|---|---|---|
| ChatGPT | chatgpt.com/share/…, chatgpt.com/s/… |
turbo-stream payload embedded in the page |
| Claude | claude.ai/share/… |
keyless snapshot API (behind Cloudflare) |
| Gemini | gemini.google.com/share/… |
keyless batchexecute RPC |
| Grok | grok.com/share/…, x.com/i/grok/share/… |
keyless share-links API |
| Poe | poe.com/s/… |
__NEXT_DATA__ payload embedded in the page |
| DeepSeek | chat.deepseek.com/share/… |
stealth render, scrolled to the end |
| Perplexity | perplexity.ai/search/…, perplexity.ai/page/… |
stealth render, scrolled to the end |
| Copilot | copilot.microsoft.com/shares/…, …/shares/pages/… |
stealth render, scrolled to the end |
The first five need no browser. The last three are JavaScript shells with nothing in the initial HTML, so those reuse the stealth tier: wait for the conversation to render, auto-scroll until the page height stops changing (list virtualization will otherwise truncate a long chat), then expand the collapsed sections before reading. The benchmark currently covers the five that read without a browser; the three that need one are not in it yet.
ChatGPT issues two shapes: /share/<uuid> for a whole conversation, and the
newer /s/<prefix>_<id> short links for a single shared turn (t_ thread,
m_ message, dr_ deep research, cd_ Codex). Both are read.
Each provider is a drop-in plugin module (searchts/share_extractors/); if a provider changes its format, extraction falls back to the normal unlocker ladder instead of failing.
Does it actually work?
Rather than take our word for it, searchts ships a reproducible two-suite benchmark: it runs the unlocker over two page sets and reports how many it read — keyless — and which tier carried each.
- Smoke — a small public page set (control, open docs, AI-chat share links). A regression canary, not evidence about hard bot-walls.
- Walled — real vendors that restrict bots (Reddit, LinkedIn login wall, a Cloudflare/DataDome-class site, X, Booking). A short body under the unlocker's minimum-content threshold is a fail, not a pass; expected walled failures are reported honestly, not papered over with 100%.
The last committed run read 12/12 Smoke and 2/7 Walled. The walled number is the point: five real walls are reported as failures instead of hidden behind a fake 100%.
These two are reported separately on purpose — the smoke number is not "does it work on walls." See benchmarks/README.md.
python -m benchmarks.run                       # both suites, print a scorecard
python -m benchmarks.run --suite walled       # the real walled pass rate only
python -m benchmarks.run --out docs/          # write docs/scorecard.md + results.json
Latest run: docs/scorecard.md. Add your own targets — see benchmarks/README.md.
The numbers only mean something from a residential connection: a datacenter IP (or a VPN that reshapes your TLS fingerprint) blocks the fast curl_cffi tier more than a real user sees.
Install
Keep it (global isolated CLI, MCP extra included):
pipx install "searchts[mcp]"
Try it without installing (one-shot, copy-paste):
uvx --from "searchts[mcp]" searchts <verb>
venv / packaging only (not the recommended path for the CLI):
python -m venv .venv
source .venv/bin/activate   # Windows: .venv\Scripts\activate
pip install "searchts[mcp]"
Stealth browser (installs into the same env as the running CLI). With uvx or uv tool, put browser in the spec itself, for example uvx --from "searchts[mcp,browser]", in every command you use, the MCP one included. Only Chromium is shared between environments:
searchts install --browser
Quickstart
searchts read https://en.wikipedia.org/wiki/Ada_Lovelace   # fetch a page as clean Markdown
searchts search "open source vector db"    # multi-provider web search (keyless by default)
searchts transcribe https://youtu.be/...   # transcript of a YouTube/TikTok/Instagram/Reddit video
searchts grab https://example.com          # download a page's assets + extract palette/fonts
searchts get https://example.com/logo.png  # download one asset (image/PDF/font/file)
searchts doctor                            # see what is configured and working
read flags: --json, --backend <tier>, --human (hand off a CAPTCHA or login wall to a real browser), --scrub (redact injection), --pages <n> (follow the next page, curl only, max 5), --items <n> (keep following until this many list rows, and scroll the feed when that is the only way it grows), --expand (open the folds: closed <details> and buttons labelled read/show/see more; never a link, a form or a sign-in, and a "continue reading" paywall is named rather than opened), --proxy <url> (route through a proxy; --proxy-trusted lets a remote proxy operator see the Cookie header). Logged-in reads, all opt-in and for the one site in the command: --cookies-from-browser <browser> with --yes (copy that site's cookies for this session), --cookies <path> (a searchts-owned cookie file), --cdp-port <port> (cookies from your localhost debugger port).
Asking for more is capped by your ceilings, and searchts cannot ask past them: SEARCHTS_MAX_PAGES (default 5), SEARCHTS_MAX_ITEMS (default 300), SEARCHTS_MAX_EXPAND_CLICKS (default 8). Set them in the environment or in a more: block in ~/.searchts/config.yaml (env wins). A request above the ceiling is clamped, not silently reduced, and the note lands on the text you read: [items: asked for 900, the ceiling is 300]. --expand stays a yes/no; how far it goes is your ceiling, not a flag. Lists that only grow by scrolling and folds that need JavaScript both need the browser: searchts install --browser. The scroll opens its own browser, which carries no proxy and no cookies, so a read that carries either does not scroll and says so. Those three ceilings are also every cap on a Reddit read: a post card, a comment and a search result are all rows, so SEARCHTS_MAX_ITEMS is the only number that decides how many come back, and anything left out is printed as a number rather than dropped.
login verbs: searchts login signin <url> (sign in once in a browser searchts opens; add --yes to keep it), login keep <url>, login kill <url> (delete searchts's copy; your own browser is untouched unless you pass --also-browser), login list, login purge-scratch.
search flags: -n <count>, --json, --provider <name>. Content goes to stdout (pipeable); status to stderr.
grab flags: --out <dir>, --kinds <images,icons,css,fonts,svg,inline_svg>, --scripts, --read (also save page.md), --max <n>, --json.
Use it from your AI agent
Add searchts to your agent in one line - as an MCP server, or as a Claude Code slash command:
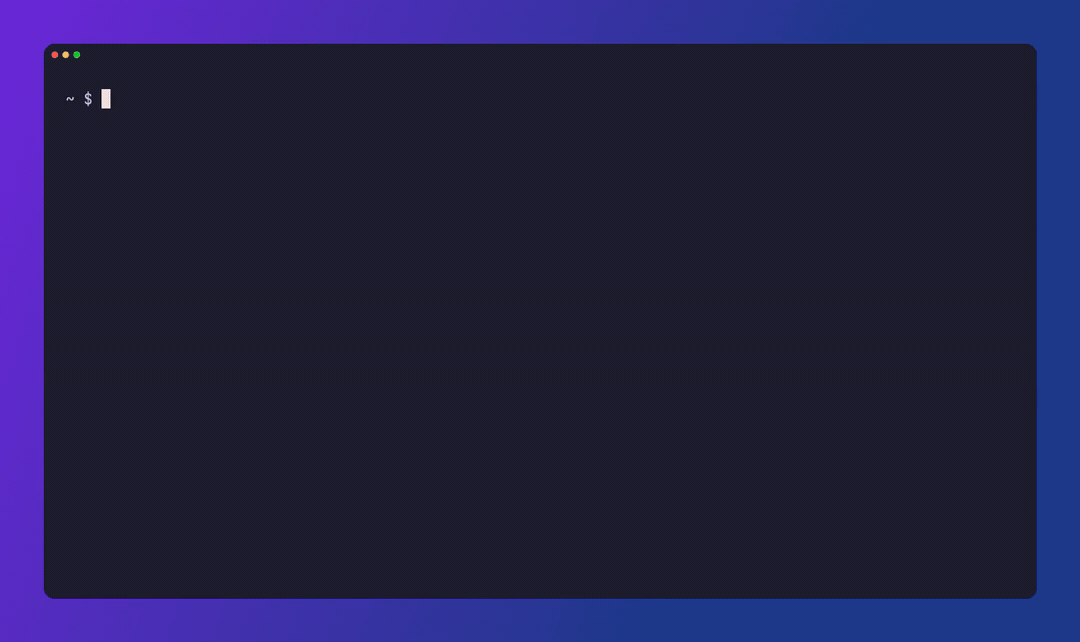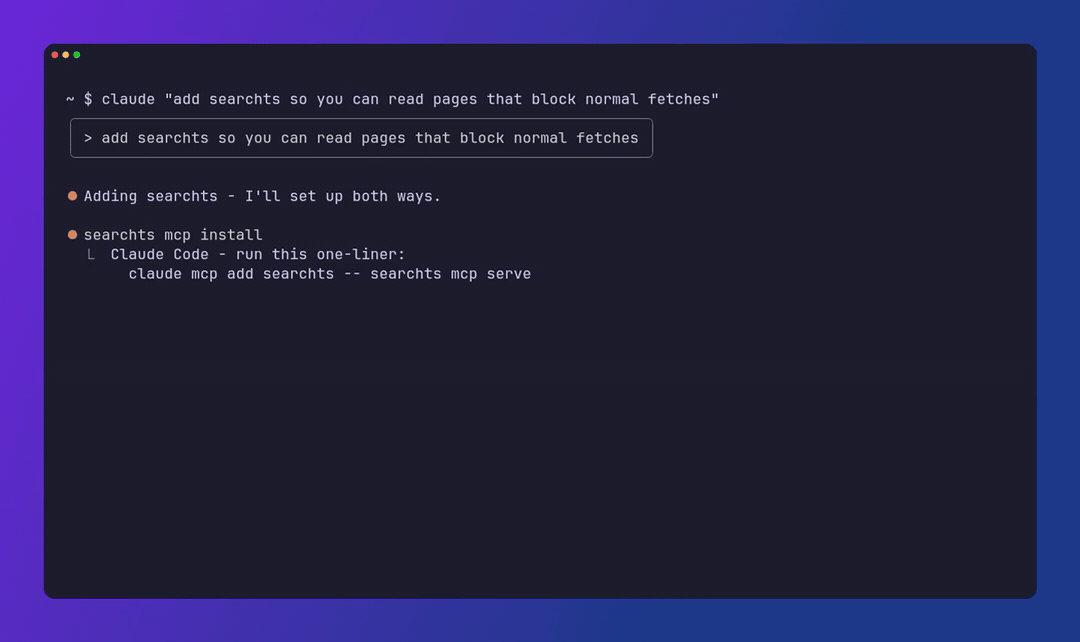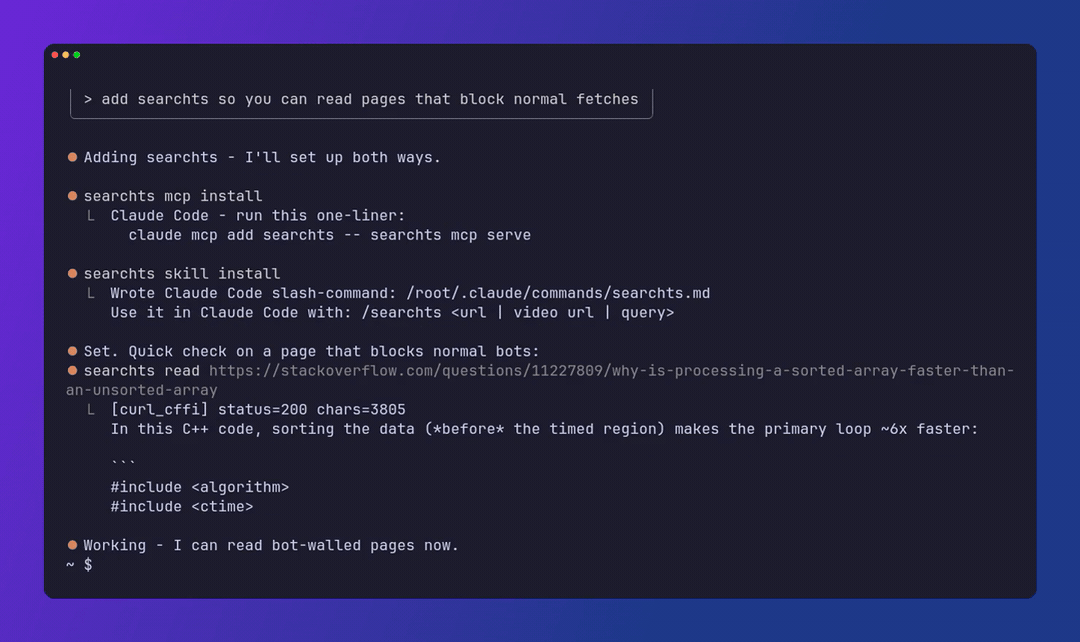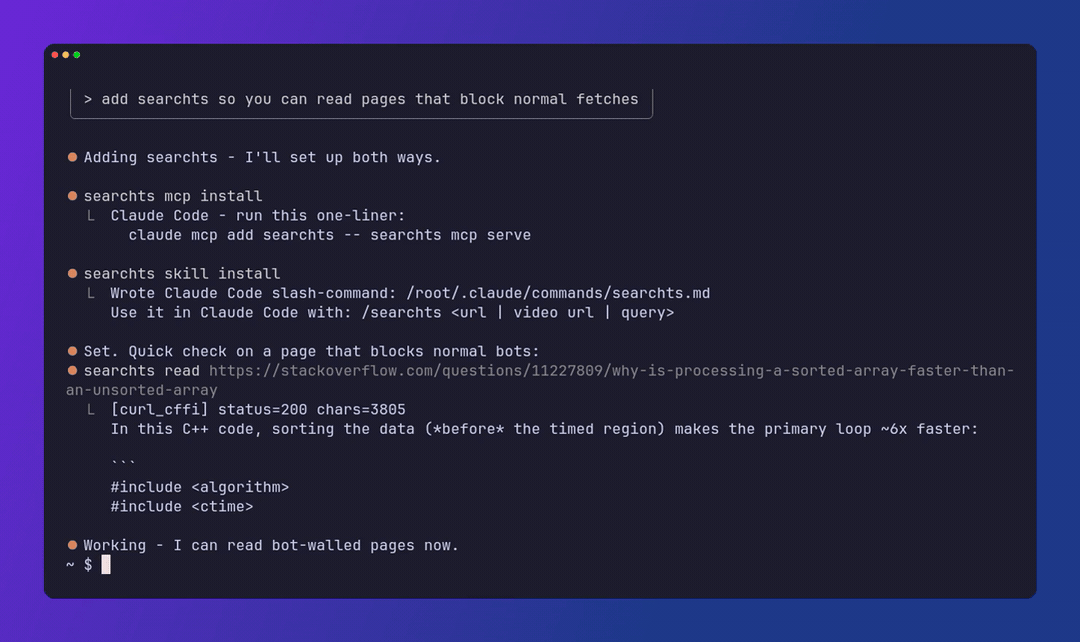
Two ways, both one command:
# 1) MCP: always-on read_url + web_search + fetch_asset + grab_site + get_status + transcribe + login_status / login_signin / login_kill
# Try / no install / Claude cannot see PATH:
claude mcp add searchts -- uvx --from "searchts[mcp]" searchts mcp serve
# Keep (after pipx install "searchts[mcp]"):
#   claude mcp add searchts -- searchts mcp serve
# Desktop / Cursor JSON: `searchts mcp install`  (or uvx the same serve command)
# First read: Wikipedia shows more than example.com, which is one short paragraph.

# 2) Slash command: type /searchts <url-or-query> in Claude Code
searchts skill install        # writes ~/.claude/commands/searchts.md
See the MCP server reference for all nine tools (read_url, web_search, fetch_asset, grab_site, get_status, transcribe, login_status, login_signin, login_kill), their inputs and outputs, and when to use each.
Features
- Escalating open-source unlocker: curl_cffi, then Jina Reader, then a stealth browser.
- Multi-provider search with rank fusion: DuckDuckGo (keyless default), plus SearXNG, Exa, Brave, and Tavily when configured; results merged with reciprocal rank fusion and de-duplicated.
- Video transcription: yt-dlp audio plus Whisper for YouTube, TikTok, Instagram, and Reddit videos.
- Asset + design grabber:
searchts grab <url>downloads a page's images/icons/css/fonts and extracts a color palette plus the fonts in use;searchts get <url>pulls a single asset. Both go through the same escalating unlock ladder, so they work on fingerprint-gated CDNs, not just open ones. - Prompt-injection scrubbing: strips invisible/bidi characters, flags injection indicators, optional redaction, so untrusted page content is safer to feed a model.
- Per-domain backend memory: remembers which tier worked per domain and tries it first (
SEARCHTS_NO_MEMORY=1to disable). - Jina opt-out: the JS-render relay is on by default;
SEARCHTS_NO_JINA=1(orjina: falsein~/.searchtsconfig) skips it so URLs never hitr.jina.ai. - Surfaces: a CLI, an MCP server (
read_url,web_search,fetch_asset,grab_site,get_status,transcribe,login_status,login_signin,login_kill), and a Python library.
Use as a library
from searchts import unlocker
r = unlocker.fetch("https://example.com")
print(r.backend, r.status, r.text)

from searchts.search import search
for hit in search("open source vector db", max_results=5):
    print(hit.title, hit.url)
How it works, and its limits
- The free package runs from your own connection at personal volume. It does not ship a proxy pool.
- A script check, including one simple click, is work for the stealth browser. A puzzle that needs a person, and a login the user did not hand over, still stop.
--humanis for those. A block that is only the address is a separate layer. It is not this fix, and it is not a reason to call DataDome impossible. - Reddit is one known-host file on the same ring, not a bypass. Listings, threads, profiles and search read as cards;
--itemsfollows Reddit's own next-post cursor and--expandopens its "more replies" controls, so the browser tier stays required and there is still no claim that every Reddit URL reads. Which rung answers at all depends on the browser profile: Reddit decides whether to serve its "Prove your humanity" check from the profile's standing, not from the address, so a freshly created profile is challenged page after page while a warm one (the persistent~/.searchts/browser-profile) is not — on this box the first runs of a new profile were refused on every tier and the same commands read a few minutes later. A scratchHOMEthrows that profile away, so a throwaway CI or test box measures only the cold answer. When a page is a wall it says which one: private, banned, quarantined, over-18, gone, archived, rather than handing back the nav bar. - Some platforms (notably Instagram, and YouTube in 2026) may need your browser cookies or fail intermittently; that is platform-side.
- Anti-bot systems evolve; this is an arms race and the techniques may need occasional updates. Respect each site's terms of service and use responsibly.
Configuration
Search works with no keys (DuckDuckGo). Everything else is optional, via searchts configure or a .env (see .env.example):
- Search providers: Exa, Brave, Tavily API keys, or a self-hosted
SEARXNG_URL, for more and better results. - Transcription: a Groq or OpenAI (Whisper) key, plus
ffmpegandyt-dlp. Login-gated video:searchts transcribe URL --cookies-from-browser chrome(opt-in;readhas its own opt-ins, see thereadflags above). - GitHub token for higher rate limits.
Run searchts doctor to check what is configured and working.
Optional integrations
The core is read / search / transcribe. Every searchts read goes through
unlocker.fetch — there is no per-platform router. searchts doctor only probes
whether optional CLIs (gh, twitter-cli, opencli, mcporter) are on PATH
and authenticated. Presence is not a claim that searchts reads those sites
through those CLIs.
Roadmap
The open work is PLAN.md. ROADMAP.md is the direction, not the task list. What already shipped is docs/plan-shipped.md.
Credits
searchts builds on and extends Agent-Reach (MIT), reusing its channel, installer, and diagnostics architecture. The escalating open-source unlocker, multi-provider search with rank fusion, prompt-injection scrubbing, per-domain backend memory, the human-in-the-loop CAPTCHA flow, the video transcript channels, the read_url / web_search MCP tools, and the read / search CLI commands are additions in searchts. Thanks to the original authors.
License
MIT. See LICENSE. Original portions Copyright (c) 2025 Agent Eyes; modifications and additions Copyright (c) 2026 capad-xyz.
Built by capad. Questions or feedback: open an issue or email oss@capad.fyi.
Fun fact: "searchts" doesn't officially abbreviate anything. Off the record, it stands for "search this shit".
1 maintainer

Metadata
1 maintainer
Release files for searchts 0.16.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| searchts-0.16.0.tar.gz | 3.1 MB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| searchts-0.16.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 3.4 MB
Release files / searchts-0.16.0.tar.gz
| Download URL | searchts-0.16.0.tar.gz |
|---|---|
| Size | 3.1 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
8d7253534854c8cee6faa201f3c177123b5e32b5bd00f8dd7e8cd4be584fea42
|
|
BLAKE2b-256 checksum How to use checksums |
42614839c89f1f90ba6284be66fa16db1fc3d47c2cfa387e4c8c26d7bac55add
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logRelease files / searchts-0.16.0-py3-none-any.whl
| Download URL | searchts-0.16.0-py3-none-any.whl |
|---|---|
| Size | 358.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
95c2920c644b643a078a514e0bd553fecf3f730c62168973c48e341b4edac588
|
|
BLAKE2b-256 checksum How to use checksums |
02ba05ed41f9482e2b1abf8c151a0644af915184a6ec961e2c5a21d8cf027494
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logSecurity for searchts 0.16.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for searchts-0.16.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 20, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














