
SEO Desk
Your site ranks on Google. Does ChatGPT cite it?
Open-source SEO, AEO and GEO audits that tell you what to fix first,
from your terminal, your CI, Claude Code or any MCP client.
Quick start · Use it your way · Dashboard · AI visibility · Compare · FAQ




Quick start
uvx seo-desk audit yoursite.com
No account, no API key, nothing to configure. (No uv? pip install seo-desk, then seodesk audit yoursite.com.)
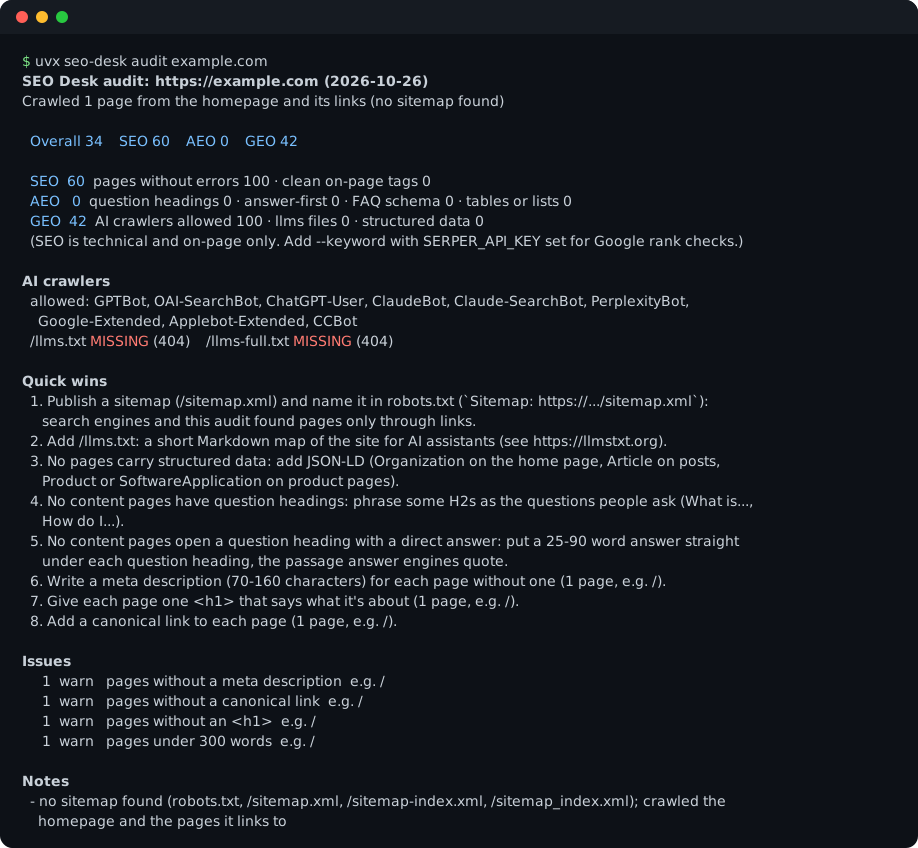
A real run against example.com, October 2026.
Want to see the dashboard first? uvx seo-desk demo opens it on eight weeks of sample data.
Why SEO Desk
AI assistants answer the question and cite a handful of sources. Ranking on Google doesn't make you one of them; being readable, quotable and known does. SEO Desk checks all three, every day if you like:
- Can AI crawlers read you? robots.txt read the way GPTBot, ClaudeBot and Google read it (RFC 9309 wildcards and
longest match, which Python's own robots parser gets wrong), plus
llms.txtandllms-full.txt. - Is each page quotable? Question headings, a 25-90 word answer straight under them, FAQ schema, tables, structured data, and every classic on-page check.
- Do AI models name you? Ask ChatGPT, Perplexity, Gemini or Claude what your customers ask and see who they cite instead, and whether they repeat something false about you.
- What should you do first? Rule-based quick wins on every audit; with a model key, an AI analyst reads the evidence and writes a prioritised to-do list that doesn't repeat itself day after day.
What it checks
| Measures | Checks | |
|---|---|---|
| SEO | Ranking in Google | Every sitemap page: status, title and description length, canonical, noindex, H1s, thin pages, alt text, duplicate titles, slow pages, broken or retired JSON-LD. Google positions for your keywords (Serper); search volumes and every keyword you rank for (DataForSEO). |
| AEO | Being the quoted answer: snippets, AI Overviews, People also ask | Question headings, answer-first paragraphs, FAQPage schema, tables and lists. |
| GEO | Being named by AI assistants | Which AI crawlers robots.txt lets in, llms.txt and llms-full.txt, structured data, claims your site must never make, and what AI models actually answer. |
Pages are read without running JavaScript, as most AI crawlers read them: a page that only renders in the browser shows up thin here, and that's worth knowing.
Use it your way
| Get it | Then | |
|---|---|---|
| Terminal | uvx seo-desk or pip install seo-desk |
seodesk audit yoursite.com |
| Claude Code plugin | /plugin marketplace add Anas660/claude-seo-desk |
"audit my site for AI search", and it fixes what it finds |
| MCP server | claude mcp add seo-desk -- uvx --python ">=3.10" --from "seo-desk[mcp]" seodesk mcp |
Claude, Cursor or any MCP client calls the tools |
| GitHub Action | uses: Anas660/claude-seo-desk@v0.1.0 |
A score on every deploy, in the job summary |
| Daily agent | seodesk init |
History, trends, AI analyst, dashboard, many sites |
Terminal
seodesk audit https://www.example.com                       # text report
seodesk audit example.com --format markdown -o report.md     # or json
seodesk audit example.com --keyword "invoice template"       # + Google rank (SERPER_API_KEY)
seodesk audit example.com --brief                            # + the AI analyst's actions (LLM_API_KEY)
seodesk audit example.com --fail-under 70                    # exit 1 under 70, for CI
seodesk llms-txt example.com -o llms.txt                     # draft an llms.txt from the site's pages
All audit options
| Option | |
|---|---|
--format text|markdown|json, -o FILE |
Report format and where to write it; --json FILE also writes the full JSON |
--max-pages 50 |
Sitemap pages to crawl |
--keyword K (repeat), --country us, --language en |
Google rank checks, needs SERPER_API_KEY |
--brief, --model, --base-url, --max-usd 0.25 |
The AI analyst's brief, needs LLM_API_KEY |
--fail-under N |
Exit with 1 when the overall score is under N |
--ignore-robots |
Crawl pages robots.txt disallows for SEODesk (only on a site you run) |
Claude Code plugin
/plugin marketplace add Anas660/claude-seo-desk
/plugin install seo-desk@seo-desk
Then ask "audit www.example.com for AI search" or run /seo-desk:audit https://www.example.com. Claude runs the
audit, explains the scores, and, when you're in the site's repo, finds where robots.txt, titles, structured data and
llms.txt come from and fixes them with you, then checks the result. /seo-desk:llms-txt writes the site's llms.txt
from its real pages. The bundled MCP server needs uv.
MCP server
Four read-only tools for any MCP client: Claude Code, Claude Desktop, Cursor, Windsurf, VS Code.
| Tool | Does |
|---|---|
audit_site(url, max_pages, keywords) |
The whole audit, sized for a model's context |
inspect_page(url) |
One page in detail, for checking a fix |
check_ai_access(url) |
Which AI crawlers robots.txt lets in; llms.txt files |
draft_llms_txt(url) |
A starting llms.txt from the site's pages |
claude mcp add seo-desk -- uvx --python ">=3.10" --from "seo-desk[mcp]" seodesk mcp
Claude Desktop, Cursor and other clients
{
  "mcpServers": {
    "seo-desk": {
      "command": "uvx",
      "args": ["--python", ">=3.10", "--from", "seo-desk[mcp]", "seodesk", "mcp"]
    }
  }
}
Or pip install "seo-desk[mcp]" (Python 3.10+) and use "command": "seodesk", "args": ["mcp"].
GitHub Action
# .github/workflows/seo.yml
on:
  push:
    branches: [main]
jobs:
  seo:
    runs-on: ubuntu-latest
    steps:
      - uses: Anas660/claude-seo-desk@v0.1.0
        with:
          url: https://www.example.com
          fail-under: 60          # optional: fail the job under this overall score
          # keywords: |           # optional: needs SERPER_API_KEY in env
          #   invoice template
The report lands in the job summary. Outputs: overall, seo, aeo, geo and report (the JSON file).
Daily agent
mkdir my-seo && cd my-seo
seodesk init                    # config.yaml, sites/example.yaml, .env.example
# put your site in sites/example.yaml; copy .env.example to .env and add the keys you have
seodesk check                   # keys, and each site's sitemap
seodesk run                     # crawl, check, score, brief: every site in config.yaml
seodesk dashboard --no-password # http://127.0.0.1:5380, this machine only
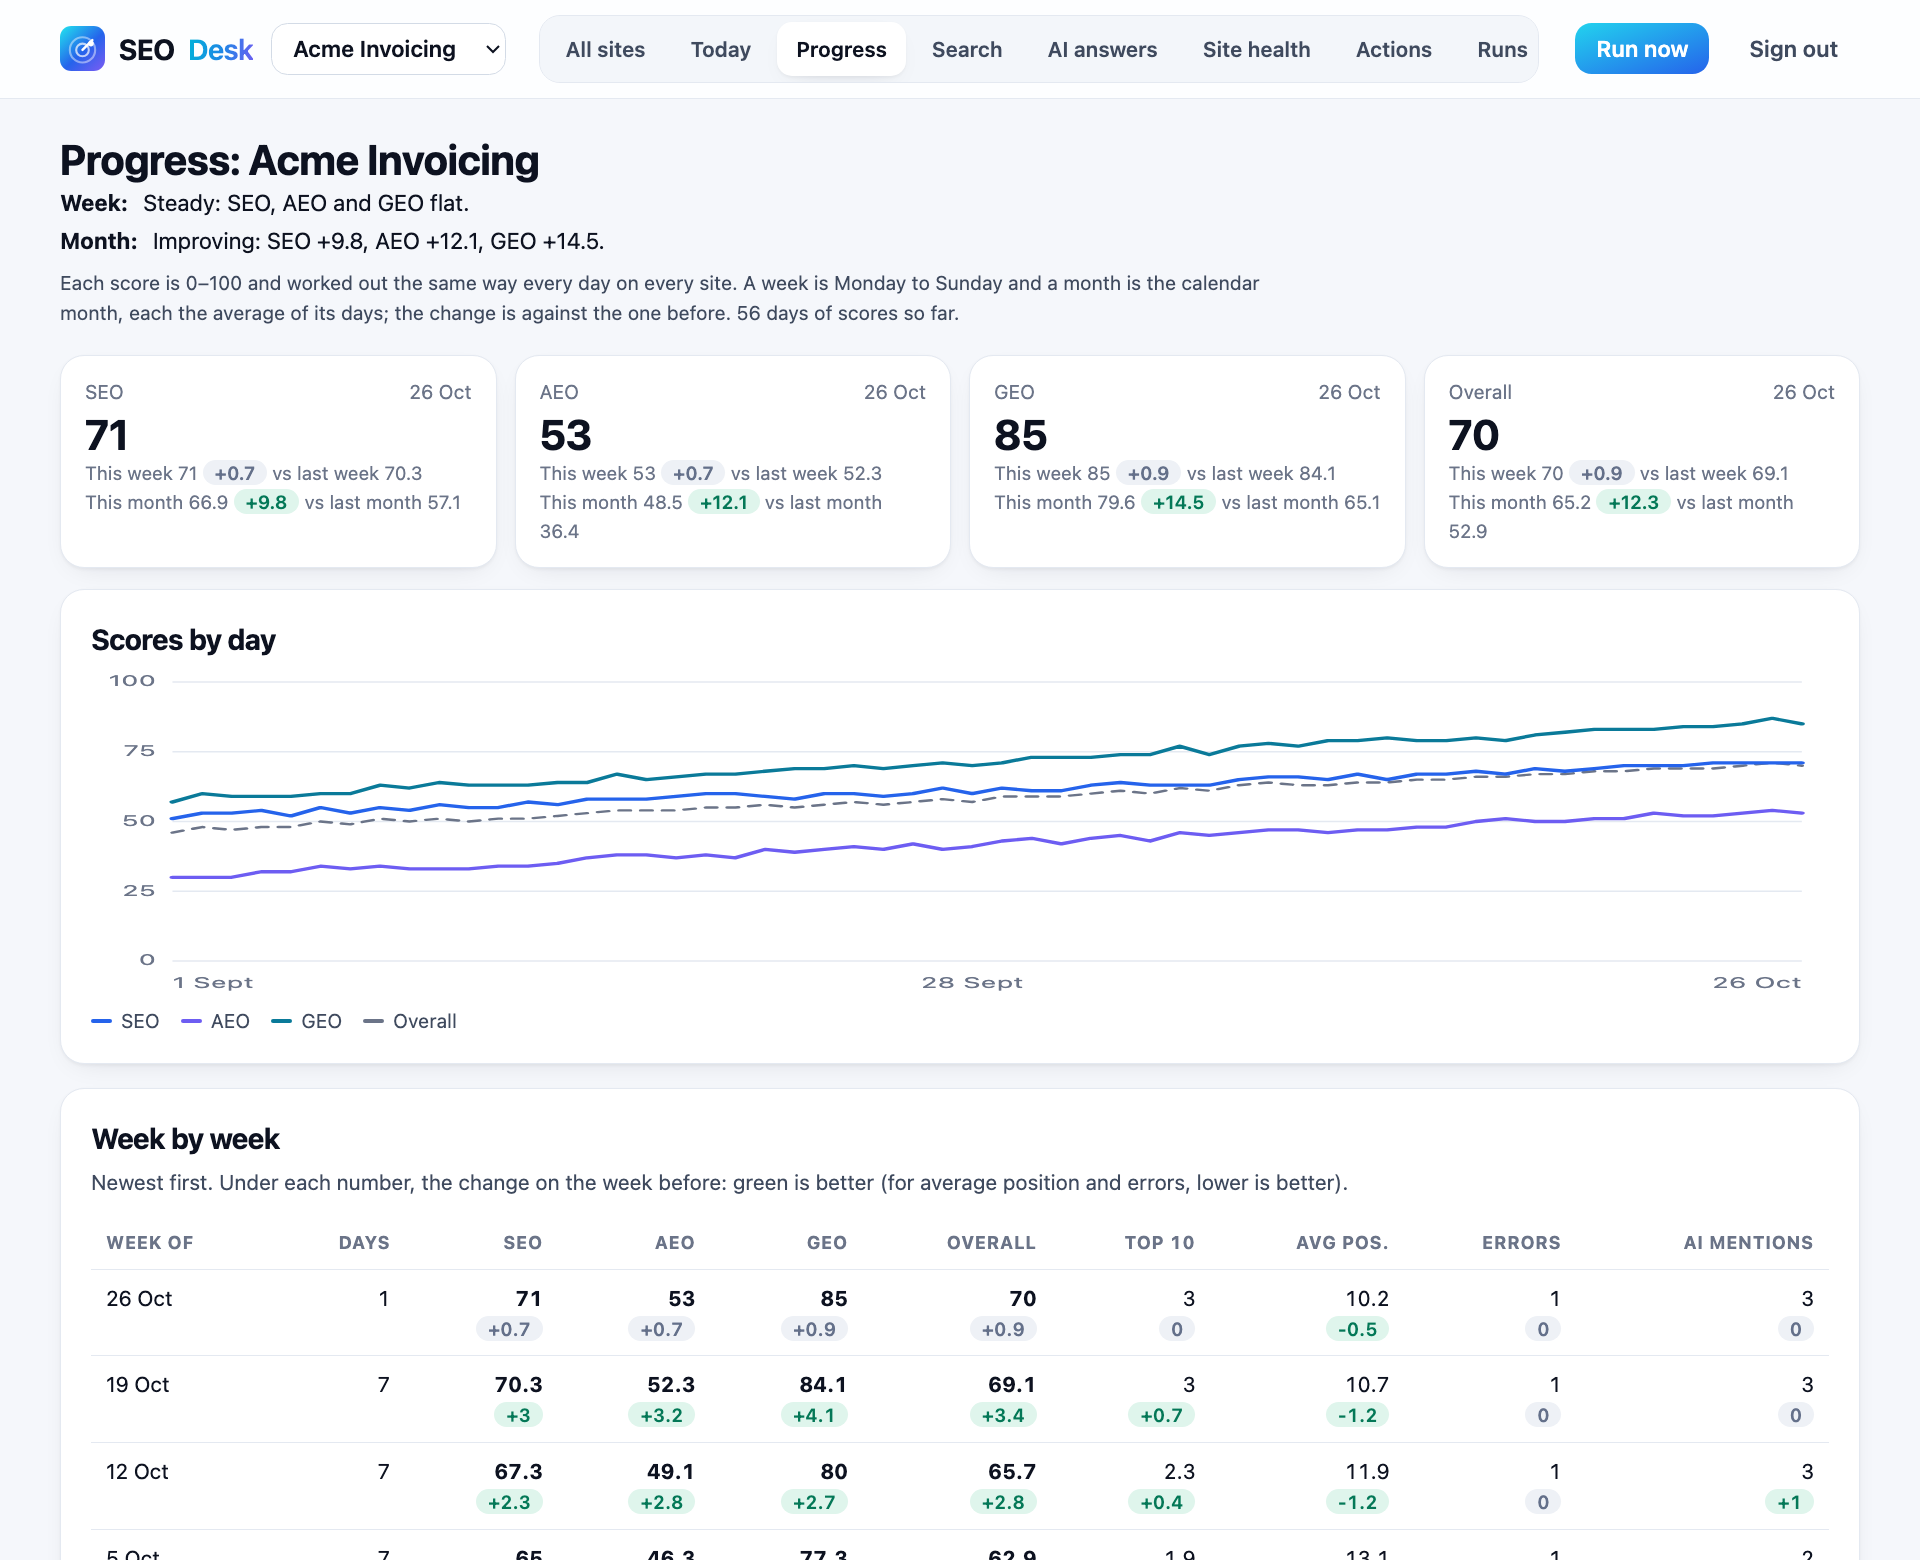
Each run lands in data/seo.db (SQLite) and compares each week and each month with the one before. The AI analyst
reads the day's evidence, can read pages and run a few live Google checks, and returns 3-8 specific actions, each
with the numbers it rests on. An action suggested again tomorrow updates its row instead of piling up; one you mark
done or dismissed stays that way.
Schedule it with cron (0 7 * * * cd /path/to/my-seo && seodesk run) or the systemd units in deploy/. To
reach the dashboard from elsewhere, set a password (seodesk password) and put HTTPS (Caddy, nginx) in front of it.
Keys (all optional) and what they cost
Key in .env |
Adds | Cost |
|---|---|---|
| none | Crawl, GEO checks, scores, history, dashboard | $0 |
LLM_API_KEY |
The AI analyst's brief, AI visibility | A brief is about a cent with the default model |
SERPER_API_KEY |
Google ranks for your keywords, People also ask, live checks for the analyst | About $1 per 1,000 searches |
DATAFORSEO_LOGIN, DATAFORSEO_PASSWORD |
Real search volumes, and every keyword Google ranks you for | A few cents a site a month |
LLM_API_KEY is an OpenRouter key by default (one key, hundreds of models; the default is
deepseek/deepseek-v4.1-flash). Any OpenAI-compatible API works: set llm.base_url and llm.model in config.yaml
(OpenAI, a local Ollama or LM Studio, your company's gateway). Spending caps stop paid steps per run, per site per
month and for every site per month, and every cent is recorded and shown on the dashboard.
The dashboard
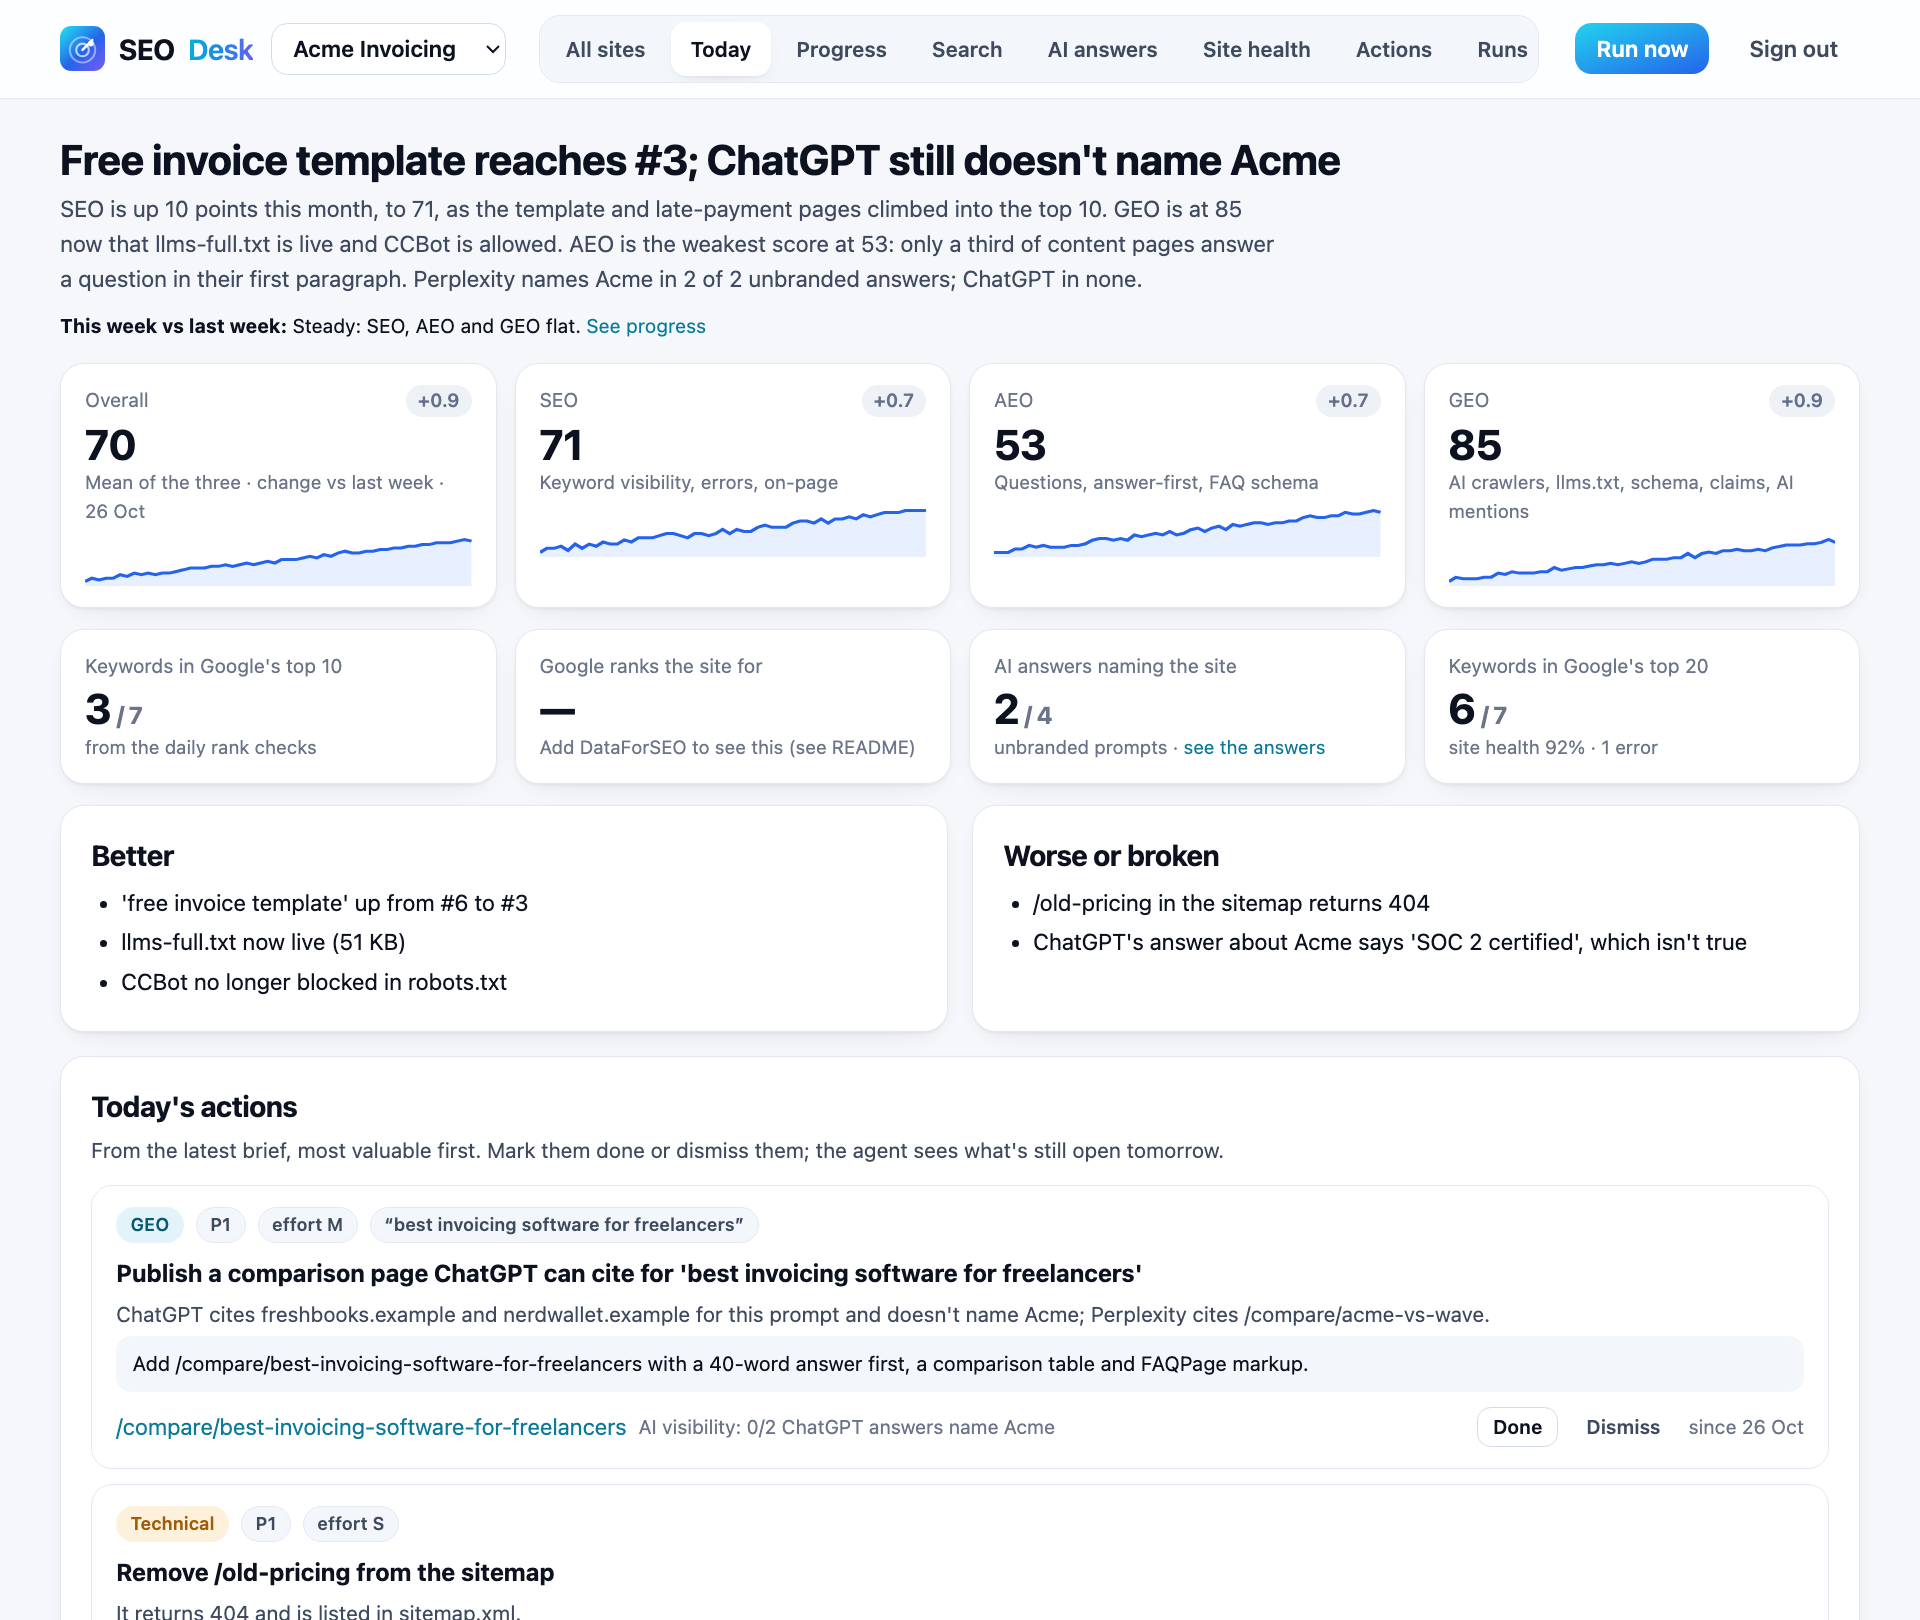
| Progress, week by week and month by month | What AI models answer |
|---|---|
 |
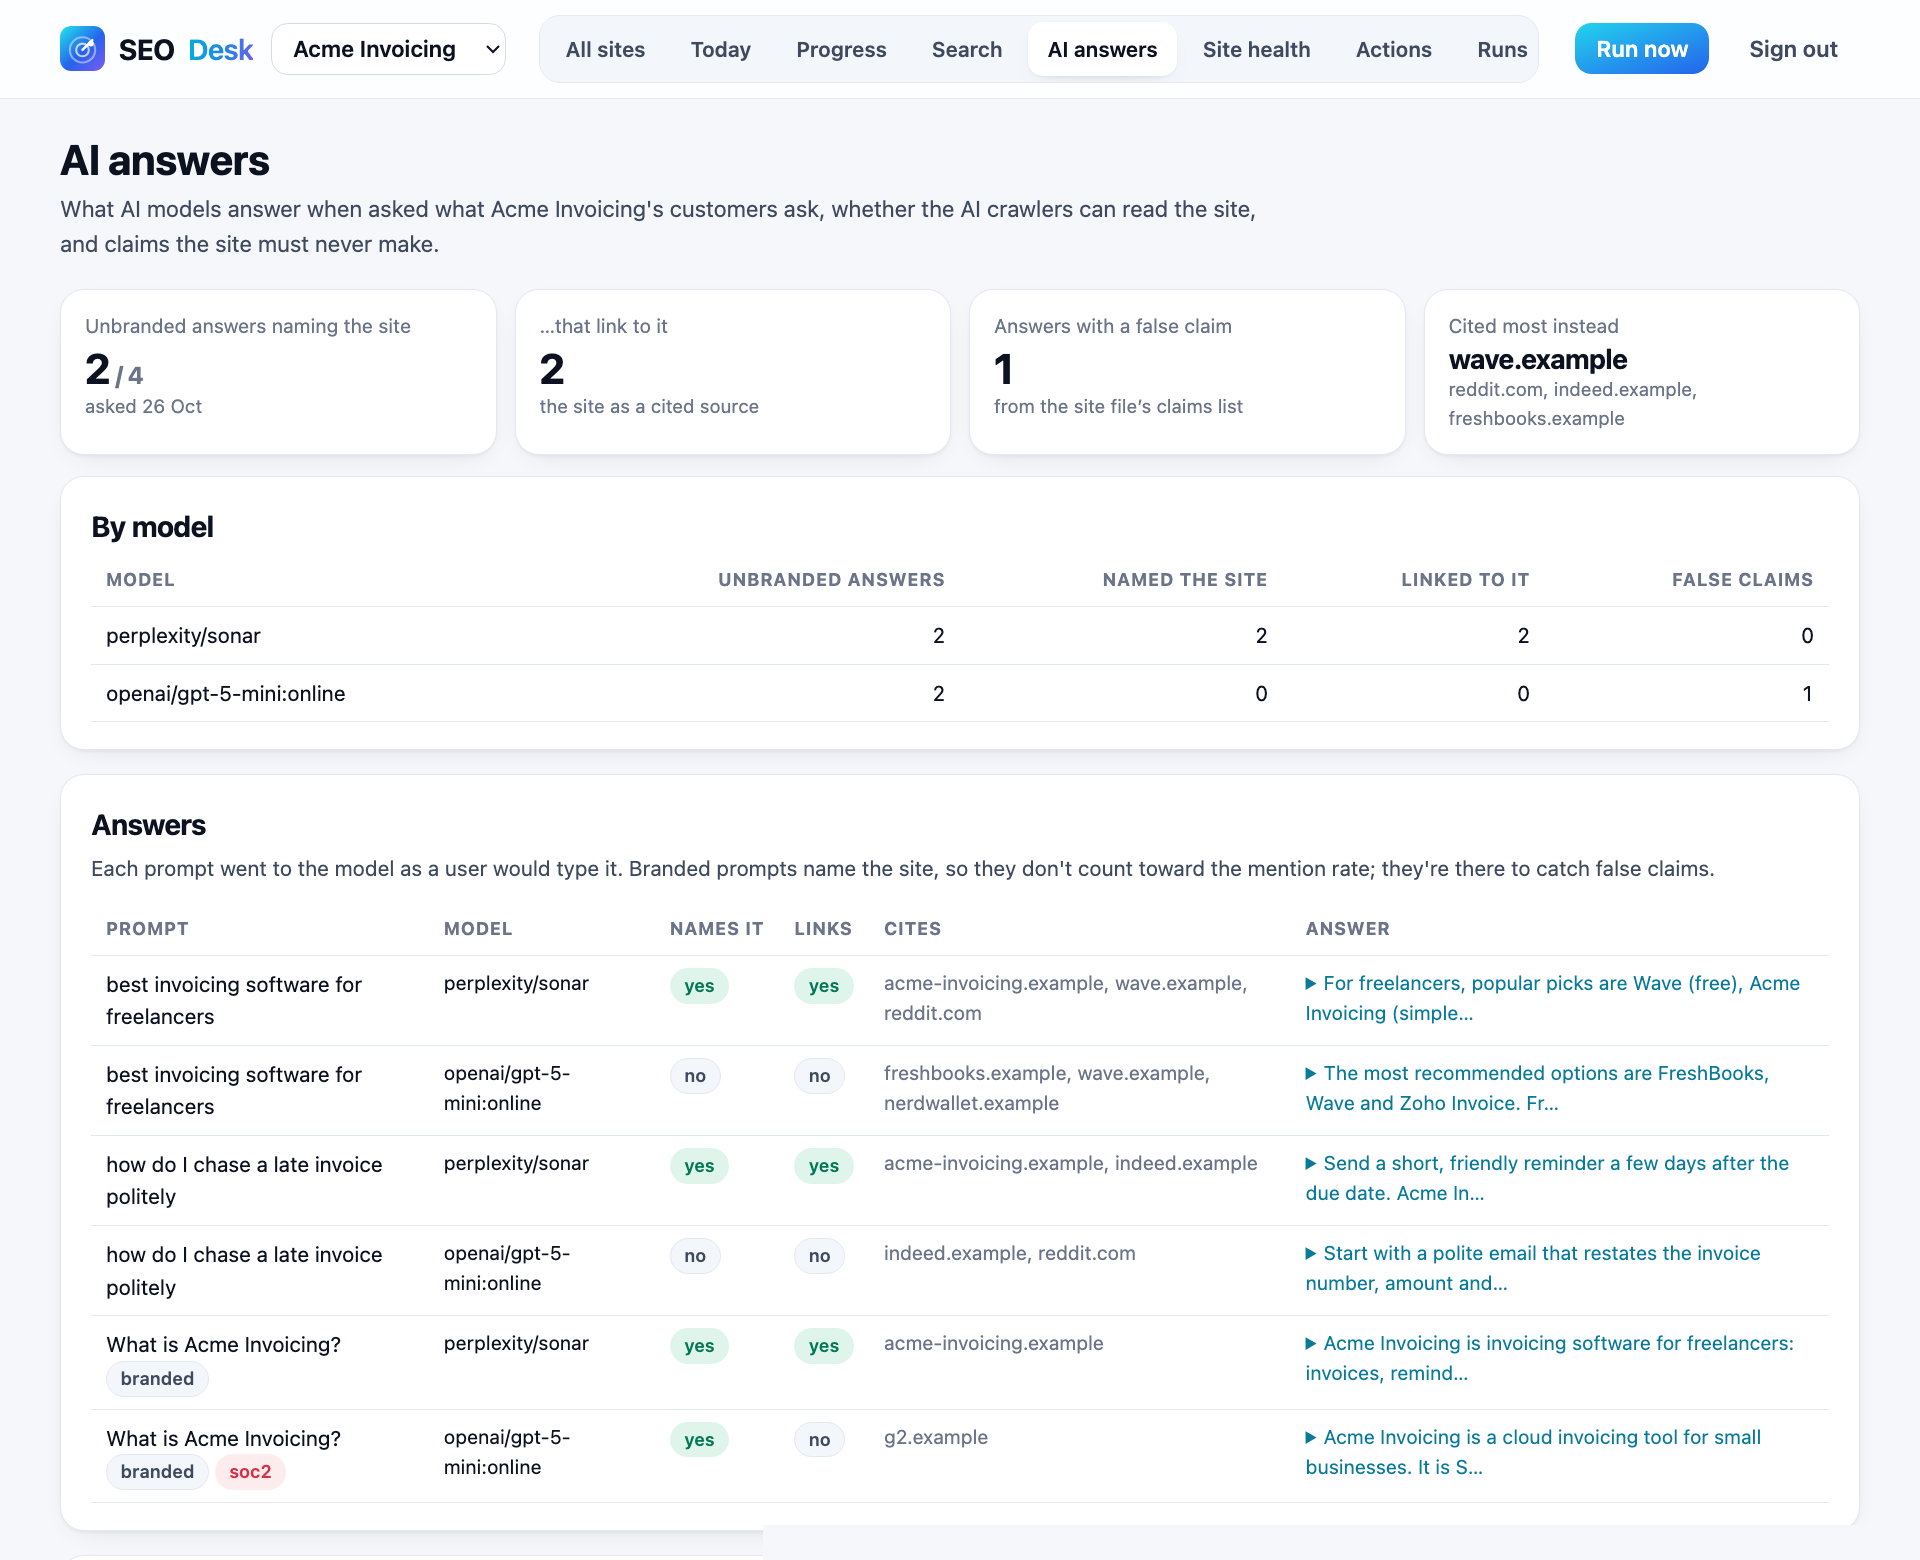 |
Sample data from seodesk demo: two fictional sites on the reserved .example domain.
AI visibility
Ask AI models the questions your customers ask, the way they ask them:
# sites/example.yaml
ai_visibility:
  models: [perplexity/sonar, openai/gpt-5-mini:online]   # OpenRouter names; ":online" adds web search
  prompts:
    - best invoicing software for freelancers
    - how do I make an invoice as a freelancer
    - {prompt: "What is Example invoicing?", branded: true}
  every_days: 7
For every answer: does it name you, does it link to you, which sites it cites instead, and does it repeat a false claim from your claims list. The share of unbranded answers that name you feeds the GEO score; branded prompts catch what AI gets wrong about you. Each prompt goes to the model with no system prompt and nothing that hints at your site.
Claims your site must never make
List what isn't true ("SOC 2 certified", an old price, a dropped feature). SEO Desk scans every live page, both llms files and the AI answers for it. Rules can count only sentences about you and skip sentences that deny the claim, so "we have no SOC 2 report" and "insist on SOC 2 from any vendor" don't trip them:
claims:
  - {id: soc2, pattern: '\bSOC[\s-]?2\b', about_us: true, unless: '\bno\b|\bnot\b', why: there is no SOC 2 report}
How the scores work
Each score is 0-100, the same formula every day on every site (progress.py). A part with no data is left out and the others count for more.
- SEO = keyword visibility 50% (#1 100 points, #2 90, #3 80, #4-5 65, #6-10 50, #11-15 25, #16-20 15) + pages without errors 30% + pages with clean on-page tags 20%. Without rank checks, SEO is the last two.
- AEO = content pages with question headings 30% + an answer-first paragraph 30% + FAQPage schema 20% + tables or lists 20%.
- GEO = AI crawlers allowed 25% + llms.txt (60) and llms-full.txt (40) 15% + pages with structured data 20% + no false claims 15% + AI models naming you in unbranded answers 25% (a quarter of answers or more scores 100).
- Overall = the mean of the three. Change the formula, then
seodesk rescorerecomputes every stored run.
How it compares
| Typical one-off GEO checker | Paid AI-visibility tracker | SEO Desk | |
|---|---|---|---|
| Price | Free | Monthly subscription | Free (MIT); you pay only for API calls you turn on |
| Runs on | Your machine | Their cloud | Your machine or server, one SQLite file |
| AI crawler and llms.txt checks | ✅ | Some | ✅, robots.txt read per RFC 9309 |
| On-page SEO and AEO checks | Some | Some | ✅ |
| What AI models answer about you | ❌ | ✅ | ✅, with the models you choose |
| History and week/month trends | ❌ | ✅ | ✅ |
| What to do next | Rule-based | Varies | Quick wins, plus an AI analyst that cites its evidence |
| CI, Claude Code and MCP | Some | Rarely | ✅ all three |
A polite crawler
- One identifiable user agent,
SEODesk/<version> (+https://github.com/Anas660/claude-seo-desk), four pages at a time. - It skips pages robots.txt disallows for
SEODesk(or*). On your own site you can turn that off. - Google results come from Serper's API, never by scraping Google.
FAQ
What are SEO, AEO and GEO?
SEO (search engine optimisation) is ranking in Google's links. AEO (answer engine optimisation) is being the passage quoted in featured snippets, AI Overviews and People also ask. GEO (generative engine optimisation) is being named and cited by AI assistants like ChatGPT, Perplexity, Gemini and Claude. They overlap: a crawlable, well-structured page with a direct answer helps all three.
Do I need API keys?
No. Without keys SEO Desk crawls, runs every GEO and AEO check, scores the site, keeps history and serves the dashboard. Keys add Google rank checks (Serper), search volumes (DataForSEO), the AI analyst and AI visibility (any OpenAI-compatible model API).
Should I block GPTBot and the other AI crawlers?
That's your call, and SEO Desk only reports it. Know the split: search and answer crawlers (OAI-SearchBot, ChatGPT-User, Claude-SearchBot, PerplexityBot) decide whether AI answers can cite you; training crawlers (GPTBot, ClaudeBot, CCBot, Google-Extended, Applebot-Extended) decide whether your pages train future models. Blocking the first group usually costs visibility.
Is llms.txt worth it?
It's a proposal (llmstxt.org), not a standard. Google has said it doesn't use it; some AI tools
and agents do read it. It's cheap to publish and keep current, so SEO Desk checks it and counts it for 15% of GEO, and
seodesk llms-txt drafts one from your pages.
Does it render JavaScript?
No, on purpose: most AI crawlers don't either. If a page you care about scores thin, it probably renders on the client; server-side rendering or prerendering fixes that for every crawler.
Can I audit a site I don't own?
Yes, politely: SEO Desk identifies itself, fetches four pages at a time and skips what robots.txt disallows for it.
Where does my data go?
Nowhere you didn't choose. Everything is stored in a SQLite file on your machine; page text goes only to the model API you configure, and only when you turn on the brief or AI visibility.
Contributing
git clone https://github.com/Anas660/claude-seo-desk && cd claude-seo-desk
python -m venv .venv && .venv/bin/pip install -e ".[dev]"
.venv/bin/pytest -q          # offline, a few seconds: every network call is faked
Ideas that would help most: a Google Search Console connection, optional JavaScript rendering, more answer-engine
checks, and a native Anthropic API client. See CONTRIBUTING.md; issues labelled
good first issue are a good place to start.
Project layout
| Module | Does |
|---|---|
crawl.py |
Sitemap discovery, the page checks, AEO signals |
geo.py |
AI crawler access (RFC 9309 robots.txt), llms.txt, the claims scan |
probes.py |
AI visibility |
audit.py, llmstxt.py |
seodesk audit and its reports; the llms.txt draft |
mcp_server.py |
The MCP server |
serp.py, dataforseo.py, stores.py |
Google ranks, search volumes, WordPress.org and Shopify listings |
progress.py |
The scores, and week and month comparisons |
agent.py, llm.py |
The AI analyst and the chat-model client |
pipeline.py, db.py |
One daily run of one site; the SQLite store |
dashboard/ |
The dashboard (standard-library HTTP server, one HTML page) |
skills/, .claude-plugin/ |
The Claude Code plugin |
If SEO Desk saved you an afternoon, a ⭐ helps other people find it.
Star history
License
MIT © Syed Anas
SEO Desk is an independent open-source project. It isn't made or endorsed by Anthropic; Claude and Claude Code are Anthropic's trademarks, named here because SEO Desk works with them.
1 maintainer

Metadata
1 maintainer
Release files for seo-desk 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| seo_desk-0.1.0.tar.gz | 119.4 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| seo_desk-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 230.1 kB
Release files / seo_desk-0.1.0.tar.gz
| Download URL | seo_desk-0.1.0.tar.gz |
|---|---|
| Size | 119.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c6ba8e9650d3132bb40c3aafa4a2353e265b52a249f52ef103ed820a4bd26b23
|
|
BLAKE2b-256 checksum How to use checksums |
fbf6b78dca6442a3987f5de49c7e5f348bbaa4a5919be90d08d93bc1599d2cfd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|
Release files / seo_desk-0.1.0-py3-none-any.whl
| Download URL | seo_desk-0.1.0-py3-none-any.whl |
|---|---|
| Size | 110.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e2f46362db87ae1b4b8fc49fa3aef74bc6dd13f429995b7e0f9cab5a221edb33
|
|
BLAKE2b-256 checksum How to use checksums |
8c11f646a680b14f04a0b151848488de3c91e66fc620099e72d6ac86b95277b4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.14
|
Security for seo-desk 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














