
Université de Toulon · LIS · CNRS · ILLS · pyannoteAI
📄 Paper · 🌐 Website · 🤗 Hugging Face · 💻 GitHub
🗣️ This framework is intended to provide an easy, ready-to-use and strong SepRQ feature extractor for 🍸 cocktail-party 🍸 and multi-talker conversational scenarios 🔀 👥, while also facilitating the use of other feature extractors from the literature. We also release a BEST-RQ model trained at 50 Hz as a valuable contribution to the community.
SepRQ features are pulled from 🤗
SevKod/SepRQ; a call returns the 12
Conformer layer features usable for training or cocktail-party representation analysis. Requires PyTorch and upstream speechbrain>=1.0.3;
runs on CPU or GPU.
👉 Please visit https://sevkod.github.io/SepRQ/ for the full usage and demo.
Install
pip install seprq
Usage (frozen ❄️ or fine-tuned 🔥)
from seprq import SepRQEncoder

wav = "hf.co/SepRQ/SepRQ/blob/main/ex/mix.wav"
# wav = torchaudio.load("path/to/audio.wav")

# "SepRQ" — see "Available models" for every name
encoder = SepRQEncoder("SepRQ", streams=2)

# ❄️ frozen feature extraction
encoder.requires_grad_(False).eval()  # or True for 🔥 fine-tuning

features = encoder(wav)
It accepts a file path (any format/rate — decoded, mono, resampled to 16 kHz)
or a waveform tensor [num_samples], [batch, num_samples] or
[batch, channel, num_samples].
SepRQ ships in variants trained to separate a different number of speakers —
select one with streams (default 2):
encoder = SepRQEncoder("SepRQ", streams=3)
# 3-speaker variant
Available models
| name | layers | dim |
|---|---|---|
⭐ SepRQ ⭐ |
12 | 576 |
BestRQ_50Hz |
12 | 576 |
HuBERT_BASE |
12 | 768 |
WavLM_BASE |
12 | 768 |
WavLM_BASE_PLUS |
12 | 768 |
WavLM_LARGE |
24 | 1024 |
The SepRQ / BEST-RQ weights come from the Hub (private — authenticate once with
huggingface-cli login or HF_TOKEN); the HuBERT / WavLM baselines are fetched
from the torchaudio pipelines, nothing extra to host.
Run a task
SUPERB separation, diarization, and enhancement, plus target-speaker
extraction, personalized speech extraction, personalized VAD,
target-speaker ASR, and DIHARD 3 diarization (local segmentation).
The head is chosen from the upstream. Published for
SepRQ (streams=2, and streams=3 on DIHARD 3), HuBERT_BASE,
WavLM_BASE, and WavLM_BASE_PLUS.
Target-speaker tasks take an enrollment utterance.
from seprq import SepRQPipeline

# Separation
pipe = SepRQPipeline("separation", upstream="SepRQ", streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/SS/mix1.wav"

save_to = "./output"

sources = pipe(mixture, save_to=save_to)
# [num_speakers, num_samples]

# ./output/source1.wav
# ./output/source2.wav

# Diarization
pipe = SepRQPipeline("diarization", upstream="SepRQ", streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/SD/mix1.wav"

save_to = "./output"

activations = pipe(mixture, save_to=save_to)
# [time, num_speakers]

# ./output/activations.rttm

# Enhancement
pipe = SepRQPipeline("enhancement", upstream="SepRQ", streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/SE/mix1.wav"

save_to = "./output"

clean = pipe(mixture, save_to=save_to)
# [num_samples]

# ./output/cleaned.wav

# Target speaker extraction
pipe = SepRQPipeline("target-speaker-extraction",
                     upstream="SepRQ",
                     streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/TSE/mix1.wav"
enrollment = "hf.co/SepRQ/SepRQ/blob/main/ex/TSE/enroll1.wav"

save_to = "./output"

target = pipe(mixture, enrollment=enrollment, save_to=save_to)
# [num_samples]

# ./output/extracted_audio.wav

# Personalized speech extraction
pipe = SepRQPipeline("personalized-extraction",
                     upstream="SepRQ",
                     streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/PSE/mix1.wav"
enrollment = "hf.co/SepRQ/SepRQ/blob/main/ex/PSE/enroll1.wav"

save_to = "./output"

target = pipe(mixture, enrollment=enrollment, save_to=save_to)
# [num_samples]

# ./output/extracted_audio.wav

# Personalized VAD
pipe = SepRQPipeline("personalized-vad", upstream="SepRQ", streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/PVAD/mix1.wav"
enrollment = "hf.co/SepRQ/SepRQ/blob/main/ex/PVAD/enroll1.wav"

save_to = "./output"

activations = pipe(mixture, enrollment=enrollment, save_to=save_to)
# [time]

# ./output/activations.rttm

# Target-speaker ASR
pipe = SepRQPipeline("target-speaker-asr",
                     upstream="SepRQ",
                     streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/TS-ASR/mix1.wav"
enrollment = "hf.co/SepRQ/SepRQ/blob/main/ex/TS-ASR/enroll1.wav"

save_to = "./output"

text = pipe(mixture, enrollment=enrollment, save_to=save_to)

# ./output/extracted_transcript.txt

# DIHARD 3 diarization
pipe = SepRQPipeline("diarization-dihard3",
                     upstream="SepRQ",
                     streams=2)

# Input mixture - [num_samples]
mixture = "hf.co/SepRQ/SepRQ/blob/main/ex/DH3/mix1.wav"

save_to = "./output"

activations = pipe(mixture, save_to=save_to)
# [time, num_speakers]

# ./output/activations.rttm
# Local segmentation only (EEND).
# Not intended for long file recordings without clustering.
🔀 SepRQ — separation as the pretext task
SepRQ swaps masked prediction for pseudo source separation. It predicts one stream of discrete units per speaker in the mixture, at several temporal resolutions.
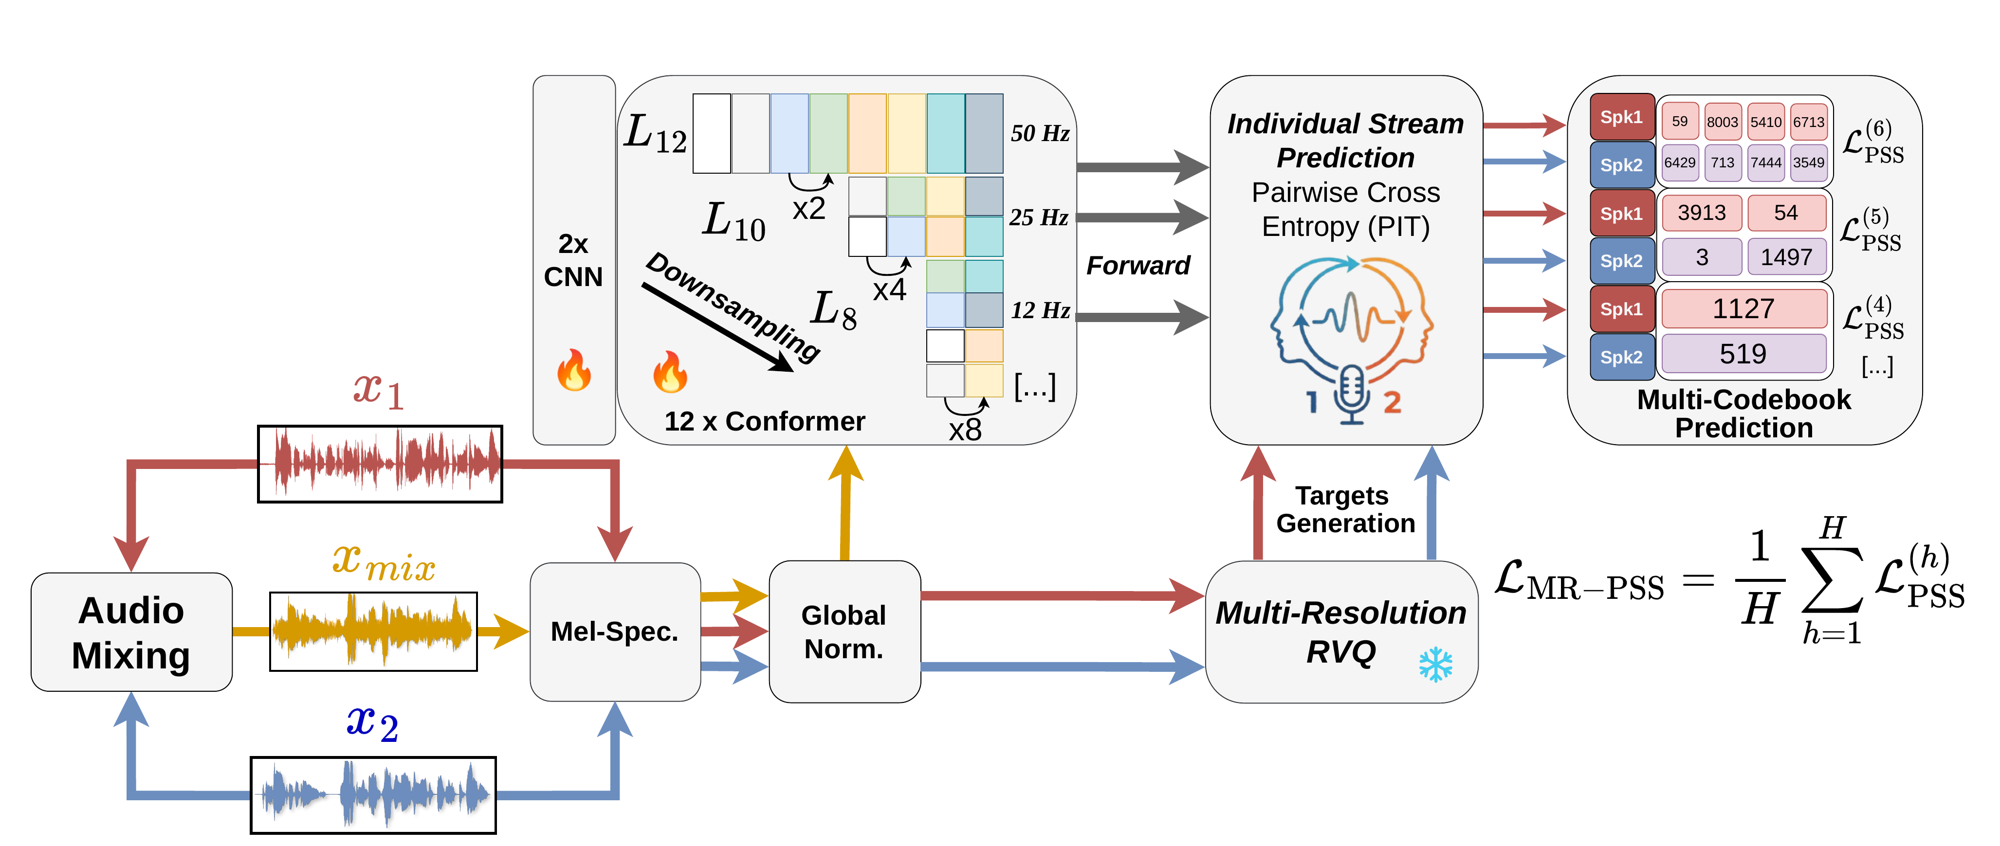
Fig. 1. SepRQ performs pseudo source separation in the discrete space. Random vector quantizers (RVQs) give speaker-specific discrete labels at several resolutions.
- Pseudo source separation — each separation head predicts the frozen BEST-RQ codewords of one clean speaker from the mixture. Utterance-level PIT resolves speaker order.
- Mask-free — masking can hide exactly the content needed to disentangle a mixture. SepRQ predicts units over the full utterance, which uses every frame for training.
- Multi-resolution — a separation objective follows every two Conformer layers, with frame folding going from 20 ms to 320 ms and one codebook per scale.
👥 Results
Frozen upstreams with SUPERB / TS-SUPERB downstream heads.
Multi-speaker SUPERB
Speaker diarization (SD), speech separation (SS) and speech enhancement (SE). LS = LibriSpeech, LL = Libri-Light, Mix = LL-60k + GigaSpeech-10k + VoxPopuli-24k.
| Model | Class | #Param (M) | Data (h) | SD | SS | SE | |
|---|---|---|---|---|---|---|---|
| DER ↓ | SI-SDRi ↑ | PESQ ↑ | STOI ↑ | ||||
| Generic SSLs | |||||||
| HuBERT Base | Base | 94.68 | LS-960 | 5.88 | 9.36 | 2.58 | 93.9 |
| WavLM Base | Base | 94.70 | LS-960 | 4.55 | 10.37 | 2.58 | 94.0 |
| WavLM Base+ | Base | 94.70 | Mix-94k | 3.50 | 10.85 | 2.63 | 94.3 |
| HuBERT Large | Large | 316.62 | LL-60k | 5.75 | 10.45 | 2.64 | 94.2 |
| WavLM Large | Large | 316.62 | Mix-94k | 3.24 | 11.19 | 2.70 | 94.5 |
| Cocktail-party SSLs | |||||||
| C-HuBERT Base | Base | 96.00 | LS-960 | 2.77 | 11.08 | 2.63 | 94.0 |
| C-HuBERT Large | Large | 318.00 | LL-60k | 2.65 | 11.24 | 2.65 | 94.3 |
| ⭐ SepRQ ⭐ | Base | 85.68 | LS-960 | 2.08 | 12.10 | 2.67 | 94.4 |
TS-SUPERB
Target speaker extraction (TSE), personalized speech extraction (PSE), personalized VAD (PVAD), target-speaker ASR (TS-ASR).
| Upstream | #Param (M) | TSE | PSE | PVAD mAP ↑ |
TS-ASR | |||
|---|---|---|---|---|---|---|---|---|
| SI-SDRi ↑ | STOI ↑ | SI-SDRi ↑ | STOI ↑ | WER ↓ | ||||
| (w/o LM) | (w/ LM) | |||||||
| HuBERT Base | 94.68 | 9.64 | 87.30 | 8.61 | 79.92 | 94.60 | 36.86 | 30.52 |
| WavLM Base | 94.70 | 10.26 | 88.40 | 9.65 | 81.57 | 94.40 | 27.82 | 22.68 |
| WavLM Base+ | 94.70 | 10.69 | 89.00 | 10.01 | 82.67 | 95.00 | 24.75 | 20.06 |
| ⭐ SepRQ ⭐ | 85.68 | 12.53 | 91.45 | 11.18 | 85.60 | 96.61 | 22.26 | 16.78 |
Out-of-domain
EEND diarization on DIHARD 3 and ConvTasNet separation on WSJ0-2/3mix.
| Upstream | Diarization | Separation | ||
|---|---|---|---|---|
| DIHARD 3 | WSJ0-2mix | WSJ0-3mix | ||
| FA / MD / SC ↓ | DER ↓ | SDRi ↑ | SDRi ↑ | |
| w/o SSL features | 6.1 / 8.1 / 4.9 | 19.3 | 16.4 | 13.1 |
| HuBERT Base | 4.3 / 8.6 / 4.7 | 17.7 | 17.0 | 12.7 |
| WavLM Base | 4.4 / 8.3 / 4.5 | 17.3 | 17.5 | 13.2 |
| WavLM Base+ | 4.8 / 7.6 / 4.2 | 16.6 | 18.2 | 13.4 |
| ⭐ SepRQ (2 src) ⭐ | 4.9 / 7.4 / 3.8 | 16.1 | 19.8 | 14.5 |
| ⭐ SepRQ (3 src) ⭐ | 5.0 / 7.3 / 4.1 | 16.4 | 19.4 | 17.2 |
Citation
If SepRQ helps your research, please cite the paper: arXiv:2610.04690.
@misc{baroudi2026seprqselfsupervisedspeech,
  title         = {SepRQ : Self-Supervised Speech Mixture Representation Learning
                   via Mask-Free, Multi-Scale Source Separation},
  author        = {Séverin Baroudi and Hervé Bredin and Ricard Marxer},
  year          = {2026},
  eprint        = {2610.04690},
  archivePrefix = {arXiv},
  primaryClass  = {eess.AS},
  url           = {https://arxiv.org/abs/2610.04690}
}
1 maintainer

Metadata
1 maintainer
Release files for seprq 0.4.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| seprq-0.4.6.tar.gz | 20.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| seprq-0.4.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 38.1 kB
Release files / seprq-0.4.6.tar.gz
| Download URL | seprq-0.4.6.tar.gz |
|---|---|
| Size | 20.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0fd808cc35f27209aacd395594f13f3e93a81a443eeaff1dcf1dde73dc16fc21
|
|
BLAKE2b-256 checksum How to use checksums |
9c5fbe319ff21973b0f028a3927516bbb2e38ad488623199a5cfc233bf4277ab
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency logRelease files / seprq-0.4.6-py3-none-any.whl
| Download URL | seprq-0.4.6-py3-none-any.whl |
|---|---|
| Size | 17.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7787bbc614dc5746846d4a102a50ee5b442aafb4464267b9501262694dfd058c
|
|
BLAKE2b-256 checksum How to use checksums |
37a58f6bb178b617df960d43e59b38b743daf092cdaf9953c889183c78aabfc4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 7, 2026.
Transparency log













