
ServeX Guard
Production quality gate for RAG & LLM systems.
Measure quality · Flag PII leaks · Flag prompt injection · Track query drift.
One command. In your CI/CD. Before it reaches production.


Website · Quick Start · CI/CD · Config · Roadmap
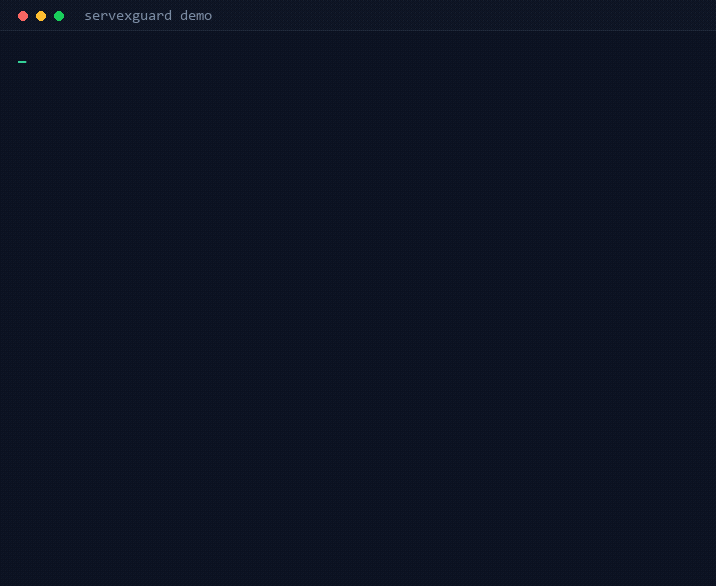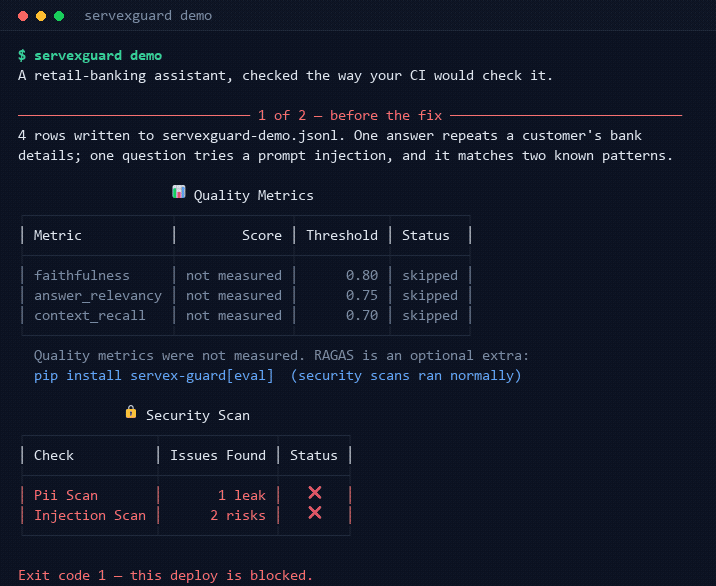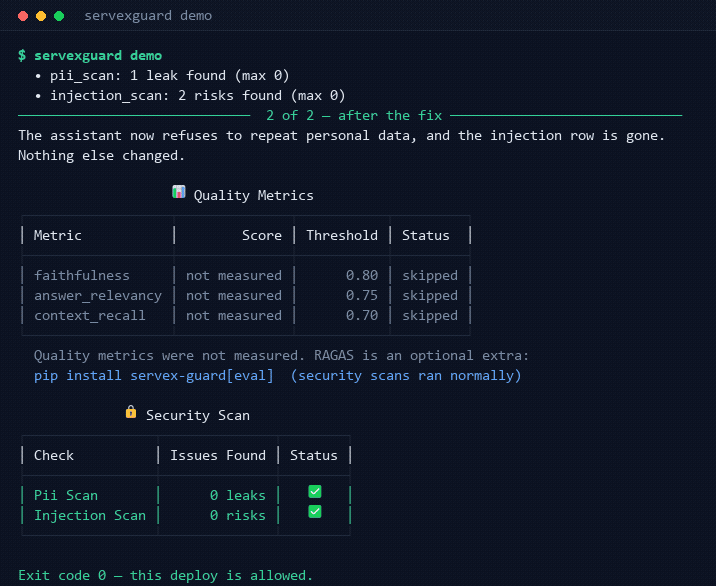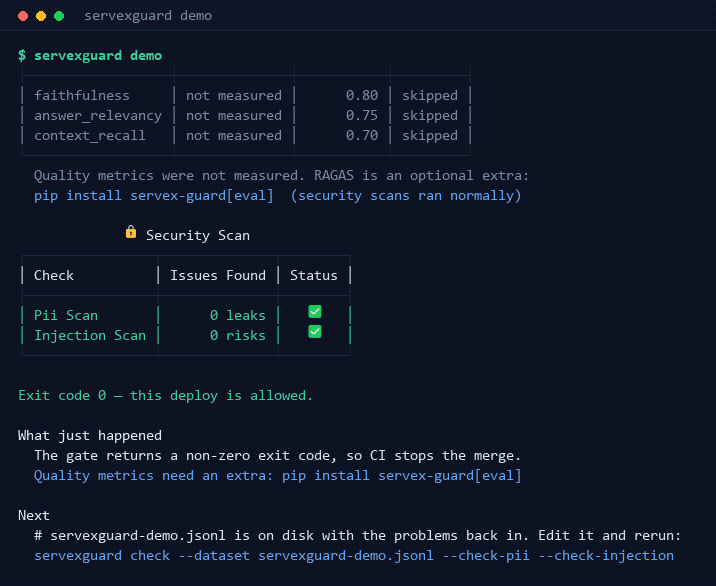
Try it yourself, no dataset and no account:
pip install servex-guard && servexguard demo
The Problem
You deployed a RAG system. It worked great in dev.
Then in production:
- The LLM hallucinated on a financial document → wrong advice to a customer
- A prompt injection leaked internal data through the response
- A regulatory update wasn't indexed → the system drifted silently for 2 weeks
- PII (national IDs, IBANs, emails) passed through to the LLM and got logged
Nobody noticed until the client complained.
The Solution
ServeX Guard is a single CLI command that checks your RAG system before deployment:
pip install "servex-guard[all]"

servexguard check \
  --dataset golden_dataset.jsonl \
  --llm-model mistral-small3.2 \
  --llm-base-url http://localhost:11434/v1 \
  --llm-embedding-model bge-m3 \
  --check-pii --pii-preset ma \
  --check-injection --llm-injection
📊 Quality Metrics
   faithfulness      0.870  ✅  (min 0.80)
   answer_relevancy  0.820  ✅  (min 0.75)
   context_recall    0.790  ✅  (min 0.70)

🔒 Security Scan
   Pii Scan          0 leaks  ✅
   Injection Scan    0 risks  ✅
   Injection Judge   0 risks  ✅

✅ QUALITY GATE PASSED
Illustrative output. For a real run, see examples/sample-report.md.
| Exit code | Meaning | CI |
|---|---|---|
0 |
Everything requested was measured and passed | continues |
1 |
A check failed | stops |
3 |
A requested check could not be measured | stops |
A broken install or an unreachable model is never reported as a pass. To accept a
gap on purpose, set that metric's threshold to 0 or pass --allow-unmeasured.
Quick Start
Install
pip install servex-guard
See it work first
Before writing anything, run the bundled example. It needs no dataset, no account and no API key, and it runs the gate twice: once against a dataset carrying a leaked IBAN and a prompt injection, once after both are fixed.
servexguard demo
It leaves servexguard-demo.jsonl in the current directory with the problems
back in, so you can edit it and rerun.
The demo covers the security scans only. Quality metrics (faithfulness, relevancy, context recall) need
pip install servex-guard[eval]and a model to judge with. Without them,checkreports not measured and exits3.
Choose who judges quality
Faithfulness and the other metrics are computed by an LLM you name, on any
OpenAI-compatible endpoint. Nothing is sent anywhere until you name one, even
if OPENAI_API_KEY is set.
# servexguard.yaml
llm:
  model: mistral-small3.2
  base_url: http://localhost:11434/v1   # Ollama, vLLM, Azure OpenAI... local if you like
  embedding_model: bge-m3               # needed for answer_relevancy
  api_key_env: OPENAI_API_KEY           # the variable's name, never the key
Models are examples: pick and validate your own. A weak judge produces confident, wrong scores.
Prepare your golden dataset
A JSONL file with reference Q&A pairs your RAG system should answer correctly:
{"question": "What is the deductible?", "ground_truth": "500€", "answer": "The deductible is 500€ as stated in Article 4.", "contexts": ["Article 4: The deductible is fixed at 500€..."]}
{"question": "How do I file a claim?", "ground_truth": "Call 0800-123-456", "answer": "Call 0800-123-456 within 5 business days.", "contexts": ["Claims can be filed via phone at 0800-123-456..."]}
Run
# Security scans only, nothing leaves the machine
servexguard check --dataset golden_dataset.jsonl \
  --min-faithfulness 0 --min-relevancy 0 --min-context-recall 0 \
  --check-pii --pii-preset ma --check-injection

# Everything, judged by a local model, with a report
servexguard check --dataset golden_dataset.jsonl \
  --llm-model mistral-small3.2 --llm-base-url http://localhost:11434/v1 \
  --llm-embedding-model bge-m3 \
  --check-pii --pii-preset ma --check-injection --llm-injection \
  --output report.json
Send results to ServeX Guard Cloud (optional)
--upload posts the computed report to your Cloud dashboard. Everything is still
computed locally. The Cloud receives scores, counts and finding types, with
anything quoted from your dataset removed. The hosted dashboard is available on
request.
export SERVEXGUARD_API_KEY=sxg_...          # from dashboard.servexguard.com → Settings
servexguard check --dataset golden_dataset.jsonl --upload --project my-rag-app
| Flag | Default | Purpose |
|---|---|---|
--upload |
off | Post the report to the Cloud |
--project |
default |
Cloud project name (created on first upload) |
--cloud-url |
https://api.servexguard.com/v1/runs |
Override the ingest endpoint (or SERVEXGUARD_CLOUD_URL) |
An upload failure never fails the run: it prints a warning and keeps the exit code from your quality gate.
Use in Python
from servexguard import ServeXGuard
from servexguard.evaluator import LLMSettings

guard = ServeXGuard(
    min_faithfulness=0.80,
    min_relevancy=0.75,
    check_pii=True,
    pii_presets=["ma"],
    check_injection=True,
    llm=LLMSettings(
        model="mistral-small3.2",
        base_url="http://localhost:11434/v1",
        embedding_model="bge-m3",
    ),
)

result = guard.check("golden_dataset.jsonl")

print(result.verdict)      # passed | failed | not_measured
print(result.failures)     # what failed
print([c.name for c in result.not_measured])  # what could not be measured
Why not just use RAGAS directly?
You can, and for the detection itself you probably should. RAGAS, Presidio and a dozen regexes are open source, and ServeX Guard calls them rather than replacing them. What takes the time is everything around them.
| DIY (RAGAS + Presidio) | Hosted eval platforms | ServeX Guard | |
|---|---|---|---|
| Time to a working gate | Days of glue code | Hours | One command |
| Blocks a deploy by exit code | Build it yourself | Partial | Built in |
| Nothing leaves your machine until you name a model | Depends what you wire up | Mostly cloud | Default |
| Stores your users' conversation text | Your choice | Yes, that is the product | No. Uploads carry scores and counts, no quoted text |
| Injection checks for FR, AR and Darija, Moroccan PII preset | If you build it | English first | Built in, limits measured |
| Keeps working if the vendor disappears | Yes, it is your code | No | Yes, Apache 2.0 |
If you have an engineer with two spare months and no compliance deadline, build it. Most teams do not, and the part nobody budgets for is not the detection but the memory around it: stored history, a nightly comparison, alerting, retention, and the evidence an auditor asks for a year later.
What this is not
It does not block attacks at runtime. It runs beside your pipeline, not in front of your model. If you need a runtime firewall for LLM traffic, buy one, and keep this for proving that what you shipped still behaves the way you validated it.
It is also not a replacement for your own eval set. It runs your golden dataset against your thresholds. A bad dataset produces a confident, useless green tick.
Measured limits
Numbers from tests in this repository, on Windows, with one local model
(qwen3-vl:8b-instruct). The cases were written by the author: treat them as an
indication, not a benchmark, and measure on your own data.
Prompt injection. 80 cases in five language variants, written after the rules and the judge prompt were frozen (cases):
| Attacks caught | Benign questions flagged | |
|---|---|---|
Rules (--check-injection) |
0 / 40 | 0 / 40 |
LLM judge (--llm-injection) |
32 / 40 | 0 / 40 |
| Judge, by language | Attacks caught |
|---|---|
| French | 8 / 8 |
| Arabic | 8 / 8 |
| Darija, Arabic script | 7 / 8 |
| English | 6 / 8 |
| Darija, Latin script | 3 / 8 |
- Rules catch phrasings someone wrote down, and nothing else. They are a cheap first filter.
- The judge can be fooled. A poisoned document telling it to "reply OK" got through in our own end-to-end test. It reads the text it judges, so it can be attacked like any other model.
- Zero risks does not prove a system is safe.
Query drift. Character n-grams, so it sees wording, not meaning: a paraphrase in different words looks like drift. On 200 random splits of 24 public banking questions in five language variants (12 against 12), the default threshold of 0.20 gave 5.4% false alarms and 8.7% missed topic changes. Tune it on your own traffic.
PII. Without a spaCy model, PII detection is regex and cannot see person names;
the report says which detector ran. Arabic has no spaCy model, so Arabic text stays on
regex. The ma preset matches formats, so an unusual format is missed.
Quality metrics come from RAGAS with English prompts, judged by the model you choose. Scores on French, Arabic or Darija depend on that model. Validate them on answers you have graded yourself before trusting a threshold.
CI/CD Integration
GitHub Actions
name: RAG Quality Gate

on: [push, pull_request]

jobs:
  servex-guard:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: actions/setup-python@v5
        with:
          python-version: '3.11'

      - run: pip install "servex-guard[all]"

      - name: ServeX Guard Quality Gate
        run: |
          servexguard check \
            --dataset data/golden_dataset.jsonl \
            --min-faithfulness 0.80 \
            --check-pii \
            --check-injection
        env:
          # Read the model and endpoint from servexguard.yaml, and the key from here.
          OPENAI_API_KEY: ${{ secrets.LLM_API_KEY }}
Azure DevOps
- task: Bash@3
  displayName: 'ServeX Guard Quality Gate'
  inputs:
    targetType: inline
    script: |
      pip install "servex-guard[all]"
      servexguard check \
        --dataset $(Build.SourcesDirectory)/data/golden_dataset.jsonl \
        --min-faithfulness 0.80 \
        --check-pii
What ServeX Guard Checks
Quality metrics (via RAGAS, judged by your LLM)
| Metric | What it measures | Default |
|---|---|---|
| Faithfulness | Answer grounded in retrieved context? | ≥ 0.80 |
| Answer Relevancy | Answer addresses the question? (needs an embedding model) | ≥ 0.75 |
| Context Recall | Retrieval found the right documents? (needs ground_truth) |
≥ 0.70 |
Security scanning
| Check | What it looks for | Needs |
|---|---|---|
| PII Detection | Emails, phones, IBANs, cards, IPs in answers. Person names with a spaCy model | Nothing. [pii] and a spaCy model for names |
Moroccan preset (--pii-preset ma) |
RIB with check key, CIN, phones, ICE, CNSS, also in Arabic-Indic digits | Nothing |
| Injection rules | Known phrasings in EN, FR, AR, Darija, in questions, answers and retrieved contexts | Nothing |
Injection judge (--llm-injection) |
Reworded attacks in questions and retrieved contexts | An LLM |
Your own patterns go in security.custom_entities.
Drift detection
| Check | What it catches |
|---|---|
| Query Drift | Questions moving away from a saved baseline, by wording. Create it with --save-baseline on a known-good dataset |
Configuration
Create a servexguard.yaml in your project root:
quality:
  min_faithfulness: 0.80
  min_relevancy: 0.75
  min_context_recall: 0.70

llm:
  model: mistral-small3.2
  base_url: http://localhost:11434/v1
  embedding_model: bge-m3

security:
  check_pii: true
  pii_presets: [ma]
  language: fr
  check_injection: true
  llm_injection: true

drift:
  enabled: true
  max_query_drift: 0.20
  baseline_file: "data/baseline.npy"

dataset:
  path: "data/golden_dataset.jsonl"

output:
  format: json
  path: "reports/report.json"
Then run:
servexguard check # reads servexguard.yaml automatically
Architecture
Your RAG system
      ↓ golden_dataset.jsonl
┌──────────────────────────────┐
│      ServeX Guard CLI        │
│                              │
│  Evaluator   → RAGAS + LLM   │  Quality scores
│  Security    → regex, Presidio,│  PII + injection
│                optional LLM  │
│  Drift       → n-gram cosine │  Wording shift
│  Reporter    → JSON/MD/CLI   │  Report + exit code
└──────────────────────────────┘
        ↓
  exit 0 ✅   exit 1 ❌   exit 3 ⛔ not measured
        ↓
  CI/CD continues or stops
Who is this for?
- AI Engineers deploying RAG to production and needing a safety net
- MLOps teams who want automated quality checks in their pipelines
- Enterprises in banking, insurance, and healthcare with compliance requirements
- Consultants delivering RAG projects to clients who need audit trails
Roadmap
- Quality evaluation (RAGAS), on an LLM you name
- PII detection (regex, Presidio with an installed spaCy model)
- Moroccan PII preset
- Prompt injection rules in EN, FR, AR, Darija
- Optional LLM injection judge
- Query drift against a saved baseline
- CLI with exit codes for CI/CD, failing closed when nothing was measured
- YAML configuration
- Better Darija detection, in Latin script above all
- Semantic drift on real embeddings
- Quality drift and document drift
- GitHub Action (marketplace)
- Compliance PDF reports (ACAPS / BAM / RGPD)
Contributing
ServeX Guard welcomes contributions! We follow an Issue-first process — please open an Issue before submitting a PR. See CONTRIBUTING.md for details.
git clone https://github.com/Mahdielaimani/ServeX-Guard.git
cd ServeX-Guard
pip install -e ".[dev]"
pytest                # the real RAGAS and Presidio tests skip unless [all] is installed
License
Apache 2.0 — free for commercial use.
Author
El Mahdi El Aimani — Senior AI Engineer · LLMOps Architect · ServeX AI
Built from production experience deploying RAG systems at Crédit Agricole du Maroc and OCP NutriCrops.


Made with care in Morocco 🇲🇦 · by ServeX AI
1 maintainer

Metadata
1 maintainer
Release files for servex-guard 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| servex_guard-0.3.0.tar.gz | 82.6 kB | Without provenance | Details for servex_guard-0.3.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| servex_guard-0.3.0-py3-none-any.whl | Python 3 | none | any | Details for servex_guard-0.3.0-py3-none-any.whl |
Total release size: 134.2 kB
Release files / servex_guard-0.3.0.tar.gz
| Download URL | servex_guard-0.3.0.tar.gz |
|---|---|
| Size | 82.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ec4a8a4fb2ba59d8ffd713b3955e2628c372eb7c8e363543a05522c5105e48e7
|
|
BLAKE2b-256 checksum How to use checksums |
34d8392837a5d50118f7dd468d258c4dce7b9f45167601dd451fe4d11f509a0a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|
Release files / servex_guard-0.3.0-py3-none-any.whl
| Download URL | servex_guard-0.3.0-py3-none-any.whl |
|---|---|
| Size | 51.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
029ca4ac0a89d759a2738489f3bf5c653cd7e4c86a7952684d1e27d746006d07
|
|
BLAKE2b-256 checksum How to use checksums |
5a6e241339da24d20acefe2f41ae437371964482ae1ec5c9325136e268b1798d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.10
|
Security for servex-guard 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














