
SEVAE: Structural Equation–Variational Autoencoder
Interpretable, disentangled latents for tabular data via a theory-driven architecture. SE-VAE mirrors structural-equation modeling (SEM): each construct has its own encoder/decoder block, plus an optional nuisance latent and global cross-talk context.
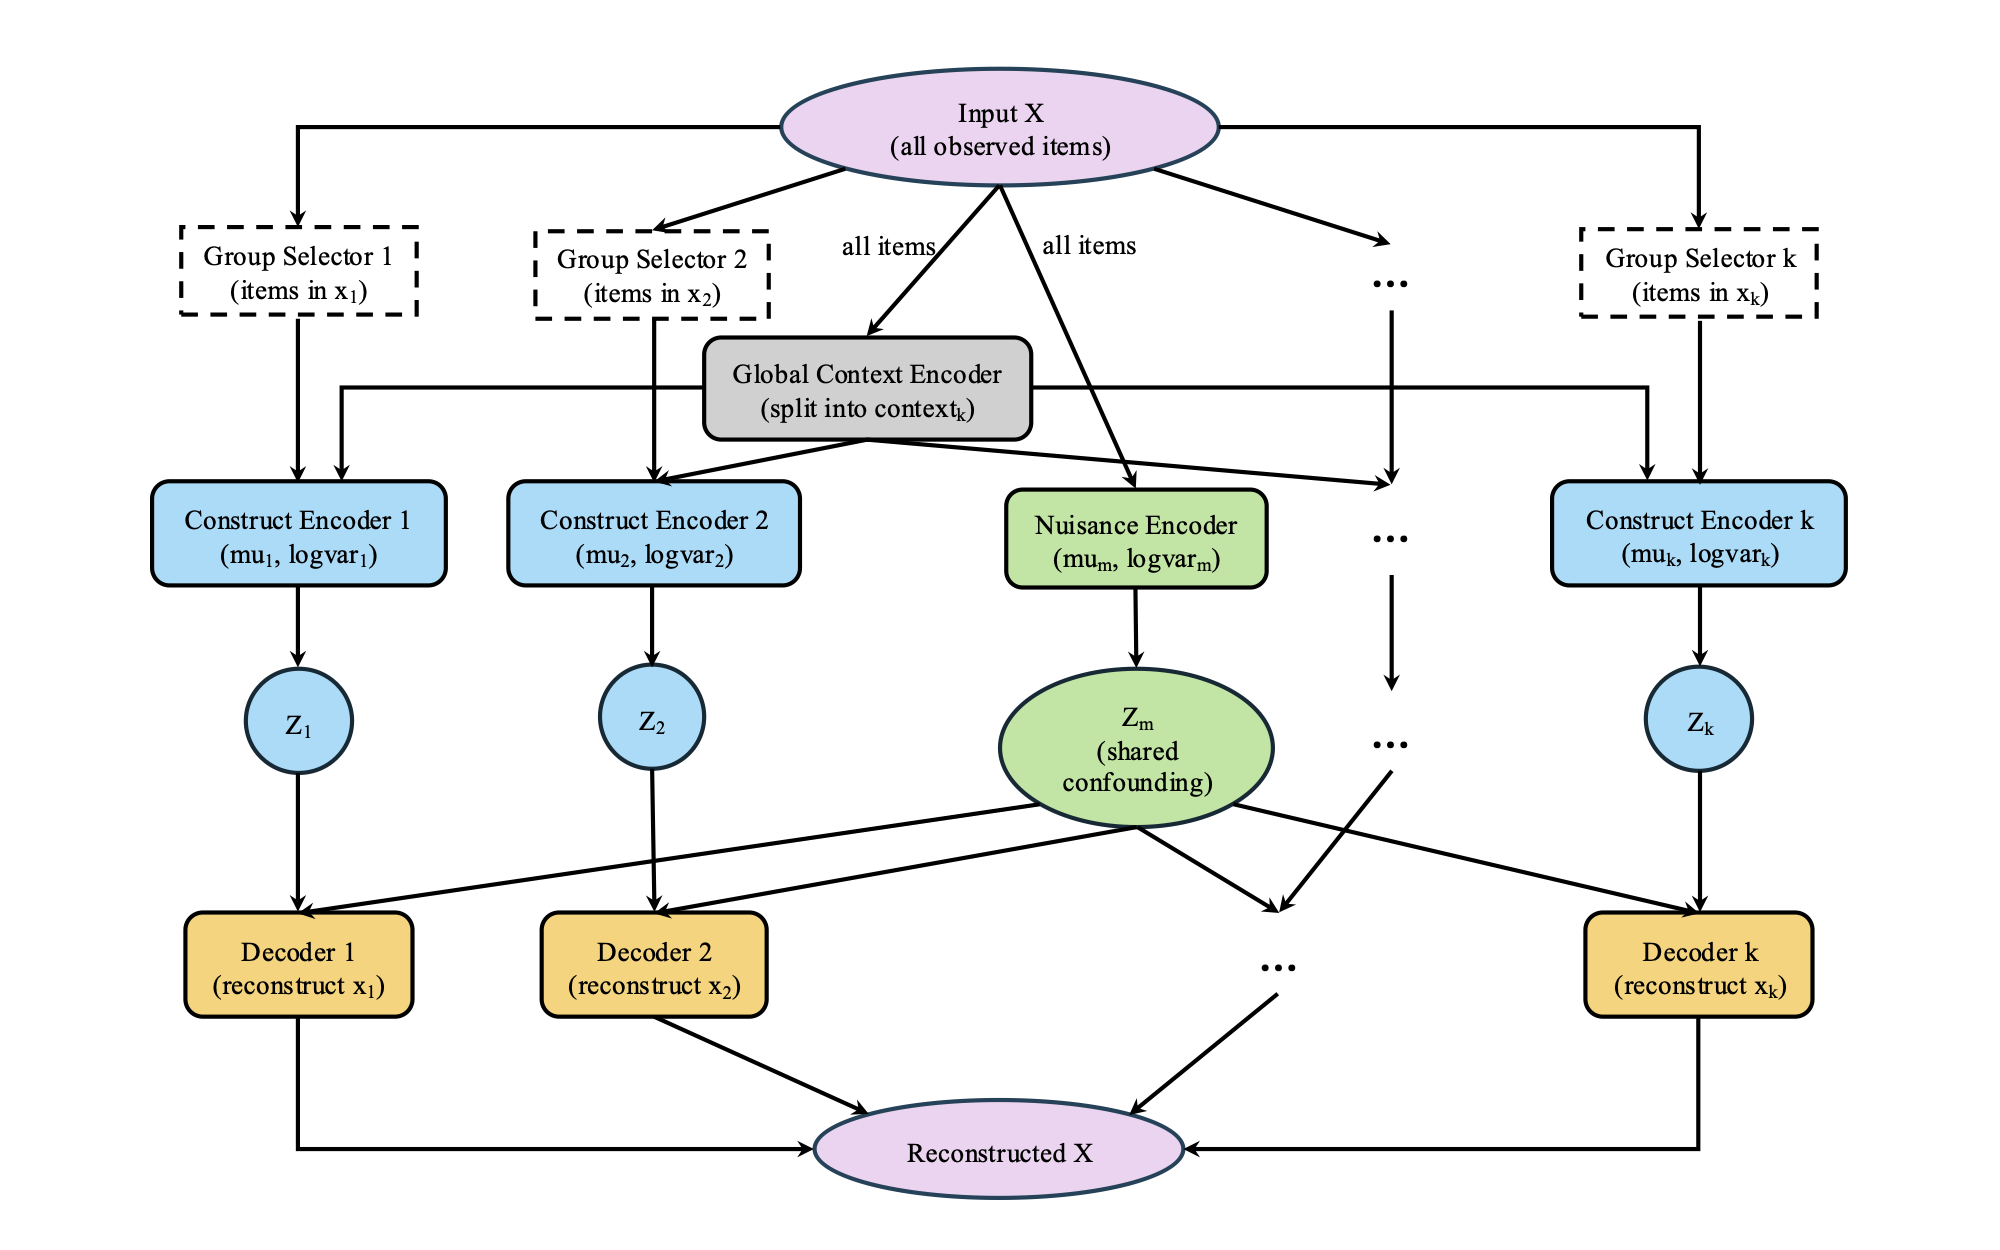
Features
- Per-construct latents (
Kconstructs ×d_per_construct) - Global cross-talk (
context_dim) concatenated to each construct encoder - Nuisance latent(s) over the full input (
n_nuisance_blocks × d_nuisance) - Adversarial leakage penalty (discourages the nuisance latent from reconstructing items alone)
- KL annealing with a single knob (
cfg.kl_weight) you update during training - Flexible column indexing:
- contiguous blocks via
items_per_construct(default), - index lists with
model.bind_column_groups([...]), - name-based with
cfg.feature_name_groups+model.bind_feature_names(names).
- contiguous blocks via
Install
# 1) Install a matching PyTorch build for your platform.
#    CPU (generic):
pip install torch

#    CUDA example (change CUDA version as needed):
pip install torch --index-url https://download.pytorch.org/whl/cu121

#    Apple Silicon (MPS):
pip install torch

# 2) Install SEVAE
pip install sevae
Quickstart
import torch
from sevae import SEVAE, SEVAEConfig

K, J = 6, 8  # constructs, items per construct

cfg = SEVAEConfig(
    n_constructs=K,
    items_per_construct=J,     # contiguous groups: [F1*][F2*]...[FK*]
    d_per_construct=1,
    d_nuisance=1,
    n_nuisance_blocks=1,
    context_dim=1,             # small cross-talk
    hidden=128,
    dropout=0.05,
    # structure losses (tune per dataset)
    tc_weight=6.4,
    ortho_weight=1.0,
    leakage_weight=0.5,
    # KL is annealed during training by updating this field
    kl_weight=0.0
)

model = SEVAE(cfg)

x = torch.randn(64, K * J)     # batch of tabular rows
out = model(x)                 # forward
losses = model.loss(x, out)    # dict with loss_total and components
losses["loss_total"].backward()
Flexible column indexing
A) Contiguous (default) If your columns are already grouped as [F1_Item1..J][F2_Item1..J]...[FK_Item1..J], just set:
cfg = SEVAEConfig(n_constructs=K, items_per_construct=J, ...)
model = SEVAE(cfg)
B) Arbitrary index groups (interleaved columns)
# Example for 48 columns not stored contiguously:
column_groups = [
    [0,  7, 14, 21, 28, 35, 42, 47],  # construct 0 item indices
    [1,  8, 15, 22, 29, 36, 43, 46],  # construct 1
    # ...
]
model.bind_column_groups(column_groups)   # call once before training
C) Name-based groups (with pandas)
# Suppose df is a pandas DataFrame with columns in any order
feature_name_groups = [
    [f"F1_Item{j}" for j in range(1, J+1)],
    [f"F2_Item{j}" for j in range(1, J+1)],
    # ...
]
cfg = SEVAEConfig(
    n_constructs=K,
    items_per_construct=J,
    feature_name_groups=feature_name_groups,
    context_dim=1,
)
model = SEVAE(cfg)
model.bind_feature_names(df.columns.tolist())  # map names → indices once
Training recipe
SEVAE builds its layers lazily on the first forward pass. Create the optimizer after the first tiny forward, and then move the model to the device (or make the model device-aware; see Device tips).
import torch, torch.nn.functional as F
from torch.utils.data import DataLoader, TensorDataset

device = torch.device("cpu")  # or "cuda", or "mps"
x = ...  # (N, K*J) standardized features (e.g., via sklearn StandardScaler)
X_t = torch.tensor(x, dtype=torch.float32)

loader = DataLoader(TensorDataset(X_t), batch_size=512, shuffle=True)

cfg = SEVAEConfig(
    n_constructs=K, items_per_construct=J, d_per_construct=1,
    d_nuisance=1, n_nuisance_blocks=1, context_dim=1, hidden=32, dropout=0.05,
    tc_weight=6.4, ortho_weight=1.0, leakage_weight=0.5,
    tc_on_construct_only=True,          # TC on constructs (recommended)
    adv_include_block_recon=True,       # match original objective
    recon_reduction="sum",              # main recon like the reference script
    kl_weight=0.0                       # will anneal below
)
model = SEVAE(cfg)

# 1) Build lazily with a tiny CPU forward, then move to device
with torch.no_grad():
    _ = model(X_t[:2])
model.to(device)
opt = torch.optim.Adam(model.parameters(), lr=1e-3)

EPOCHS = 100
for epoch in range(1, EPOCHS + 1):
    # KL annealing (linear over first 50% of epochs)
    model.cfg.kl_weight = min(1.0, epoch / (EPOCHS * 0.5))

    model.train()
    total = 0.0
    for (xb,) in loader:
        xb = xb.to(device)
        out = model(xb)
        loss = model.loss(xb, out)["loss_total"]
        opt.zero_grad()
        loss.backward()
        opt.step()
        total += float(loss.item())

    if epoch % 10 == 0:
        print(f"Epoch {epoch}/{EPOCHS} avg loss {total/len(loader):.4f} (β={model.cfg.kl_weight:.2f})")
Device tips (CPU / CUDA / MPS)
Recommended (robust) pattern
- Build on CPU with a tiny batch: with torch.no_grad(): _ = model(X_t[:2])
- Move the model: model.to(device)
- Create the optimizer after moving: opt = torch.optim.Adam(model.parameters(), lr=...)
- Move inputs each step: xb = xb.to(device)
Apple MPS
# Optional: allow CPU fallback for not-yet-supported ops
export PYTORCH_ENABLE_MPS_FALLBACK=1
Non-contiguous groups
If you used bind_column_groups or bind_feature_names, the model stores index tensors. After model.to(device), they are automatically used on the same device. If you subclass or modify the model, ensure those indices are on device.
Citation
If you use this package, please cite:
Zhang, R., Zhao, C., Zhao, X., Nie, L., & Lam, W. F. (2025). Structural Equation-VAE: Disentangled Latent Representations for Tabular Data. arXiv preprint arXiv:2508.06347.
@article{zhang2025structural,
  title={Structural Equation-VAE: Disentangled Latent Representations for Tabular Data},
  author={Zhang, Ruiyu and Zhao, Ce and Zhao, Xin and Nie, Lin and Lam, Wai-Fung},
  journal={arXiv preprint arXiv:2508.06347},
  year={2025}
}
1 maintainer

Metadata
1 maintainer
Release files for sevae 1.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| sevae-1.0.2.tar.gz | 245.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| sevae-1.0.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 255.3 kB
Release files / sevae-1.0.2.tar.gz
| Download URL | sevae-1.0.2.tar.gz |
|---|---|
| Size | 245.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e4be8662a6714f4cceb43ebc7a11410c613706708f4496cfe149c24ffb81470b
|
|
BLAKE2b-256 checksum How to use checksums |
3d66b0e3555e759707915df88467019c409191f9a5898aa49cdeb5a07dfd844a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.19
|
Release files / sevae-1.0.2-py3-none-any.whl
| Download URL | sevae-1.0.2-py3-none-any.whl |
|---|---|
| Size | 9.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2e1e1a50e66564c68b6db911f36a030db7945f60376a9e1f9f23144ba6cf09f5
|
|
BLAKE2b-256 checksum How to use checksums |
86fdff4184b8a11359f695f8f0284784a70e0714b3da833d5a7d3b29c7e768b9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.19
|














