
shap-hypetune
A python package for simultaneous Hyperparameters Tuning and Features Selection for Gradient Boosting Models.
Overview
Hyperparameters tuning and features selection are two common steps in every machine learning pipeline. Most of the time they are computed separately and independently. This may result in suboptimal performances and in a more time expensive process.
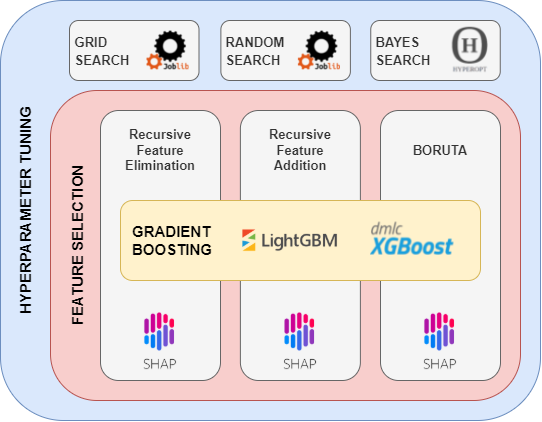
shap-hypetune aims to combine hyperparameters tuning and features selection in a single pipeline optimizing the optimal number of features while searching for the optimal parameters configuration. Hyperparameters Tuning or Features Selection can also be carried out as standalone operations.
shap-hypetune main features:
- designed for gradient boosting models, as LGBModel or XGBModel;
- developed to be integrable with the scikit-learn ecosystem;
- effective in both classification or regression tasks;
- customizable training process, supporting early-stopping and all the other fitting options available in the standard algorithms api;
- ranking feature selection algorithms: Recursive Feature Elimination (RFE); Recursive Feature Addition (RFA); or Boruta;
- classical boosting based feature importances or SHAP feature importances (the later can be computed also on the eval_set);
- apply grid-search, random-search, or bayesian-search (from hyperopt);
- parallelized computations with joblib.
Installation
pip install --upgrade shap-hypetune
lightgbm, xgboost are not needed requirements. The module depends only on NumPy, shap, scikit-learn and hyperopt. Python 3.6 or above is supported.
Media
- SHAP for Feature Selection and HyperParameter Tuning
- Boruta and SHAP for better Feature Selection
- Recursive Feature Selection: Addition or Elimination?
- Boruta SHAP for Temporal Feature Selection
Usage
from shaphypetune import BoostSearch, BoostRFE, BoostRFA, BoostBoruta
Hyperparameters Tuning
BoostSearch(
    estimator,                              # LGBModel or XGBModel
    param_grid=None,                        # parameters to be optimized
    greater_is_better=False,                # minimize or maximize the monitored score
    n_iter=None,                            # number of sampled parameter configurations
    sampling_seed=None,                     # the seed used for parameter sampling
    verbose=1,                              # verbosity mode
    n_jobs=None                             # number of jobs to run in parallel
)
Feature Selection (RFE)
BoostRFE(
    estimator,                              # LGBModel or XGBModel
    min_features_to_select=None,            # the minimum number of features to be selected
    step=1,                                 # number of features to remove at each iteration
    param_grid=None,                        # parameters to be optimized
    greater_is_better=False,                # minimize or maximize the monitored score
    importance_type='feature_importances',  # which importance measure to use: default or shap
    train_importance=True,                  # where to compute the shap feature importance
    n_iter=None,                            # number of sampled parameter configurations
    sampling_seed=None,                     # the seed used for parameter sampling
    verbose=1,                              # verbosity mode
    n_jobs=None                             # number of jobs to run in parallel
)
Feature Selection (BORUTA)
BoostBoruta(
    estimator,                              # LGBModel or XGBModel
    perc=100,                               # threshold used to compare shadow and real features
    alpha=0.05,                             # p-value levels for feature rejection
    max_iter=100,                           # maximum Boruta iterations to perform
    early_stopping_boruta_rounds=None,      # maximum iterations without confirming a feature
    param_grid=None,                        # parameters to be optimized
    greater_is_better=False,                # minimize or maximize the monitored score
    importance_type='feature_importances',  # which importance measure to use: default or shap
    train_importance=True,                  # where to compute the shap feature importance
    n_iter=None,                            # number of sampled parameter configurations
    sampling_seed=None,                     # the seed used for parameter sampling
    verbose=1,                              # verbosity mode
    n_jobs=None                             # number of jobs to run in parallel
)
Feature Selection (RFA)
BoostRFA(
    estimator,                              # LGBModel or XGBModel
    min_features_to_select=None,            # the minimum number of features to be selected
    step=1,                                 # number of features to remove at each iteration
    param_grid=None,                        # parameters to be optimized
    greater_is_better=False,                # minimize or maximize the monitored score
    importance_type='feature_importances',  # which importance measure to use: default or shap
    train_importance=True,                  # where to compute the shap feature importance
    n_iter=None,                            # number of sampled parameter configurations
    sampling_seed=None,                     # the seed used for parameter sampling
    verbose=1,                              # verbosity mode
    n_jobs=None                             # number of jobs to run in parallel
)
Full examples in the notebooks folder.
1 maintainer

Metadata
1 maintainer
Release files for shap-hypetune 0.2.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| shap-hypetune-0.2.7.tar.gz | 15.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| shap_hypetune-0.2.7-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 32.7 kB
Release files / shap-hypetune-0.2.7.tar.gz
| Download URL | shap-hypetune-0.2.7.tar.gz |
|---|---|
| Size | 15.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
53268f19b26f91297f04320d4d2d3009a03fc897dbe339a5521c8ea05ac5d468
|
|
BLAKE2b-256 checksum How to use checksums |
a445d0156b03e18b58174068a69821bca42fadbafa9b78d5e877daaaeb8877ae
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.3
|
Release files / shap_hypetune-0.2.7-py3-none-any.whl
| Download URL | shap_hypetune-0.2.7-py3-none-any.whl |
|---|---|
| Size | 17.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
480d9e74ec10067d16508ef209d1da86a011d4982a44fbb04051c46c4ffa6536
|
|
BLAKE2b-256 checksum How to use checksums |
dd8bd31a106a8065cbda0142e531709df1b2366ae6160ad190f4b8fa463a4aa6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.11.3
|














