
🏭 Skill Factory
Train agent skills like you train weights.
Stop hand-tweaking SKILL.md and hoping. Define what "good" means, and let an
optimizer measurably improve the skill against held-out data.


▶ Full explainer video (61s — silent and narrated cuts) is attached to every release.
Skill Factory treats a SKILL.md as a trainable parameter: you give it a
metric and a dataset, and a pluggable optimizer evolves the skill to maximize the
metric — the same idea behind Microsoft SkillOpt
and DSPy GEPA, under one clean interface, plus a self-contained
optimizer that needs no heavy dependencies.
Optimized skills are emitted in the open npx skills
layout, so they drop straight into Claude Code, Codex, Cursor, Gemini CLI, and more.
Results
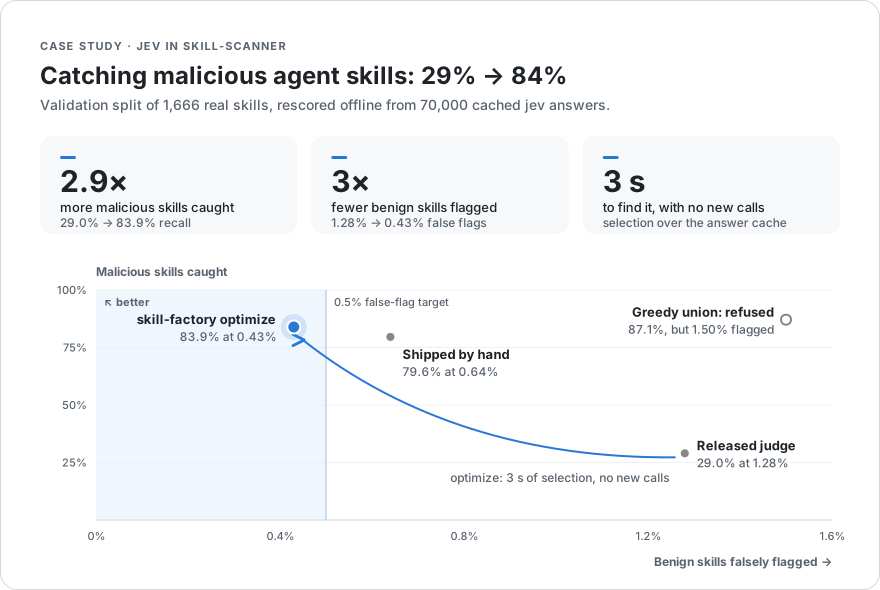
In classifier mode, the optimizer took skill-scanner's real jev judge from the released probes to a better probe set than the one an expert shipped by hand. It found the same structure on its own: five intent questions plus a lure, at a threshold of 0.0755 where the expert chose 0.075.
The numbers behind the chart (training and validation, plus the fine print)
| Probe set | Training | Validation |
|---|---|---|
| Released judge: 4 capability probes at P ≥ 0.85 | 19.0% at 1.52% false flags | 29.0% at 1.28% |
| Shipped by hand: mean of 5 intent questions + a lure, ≥ 0.075 | 78.8% at 0.33% | 79.6% at 0.64% |
| Greedy union of 4 (refused by the gate) | 83.7% at 0.43% | 87.1% at 1.50% |
skill-factory optimize, selection only, ≥ 0.0755 |
81.5% at 0.43% | 83.9% at 0.43% |
Every row was recomputed from skill-scanner's cached lab (1,666 skills, 47 candidate questions, 70k answers) without a single call. The validation number is optimistic, because validation chose among a few candidates. The unbiased check is skill-scanner's sealed splits: 73.2% on the test split and 69.9% on held-out corpora for the shipped set. Full write-up: docs/classifier.md.
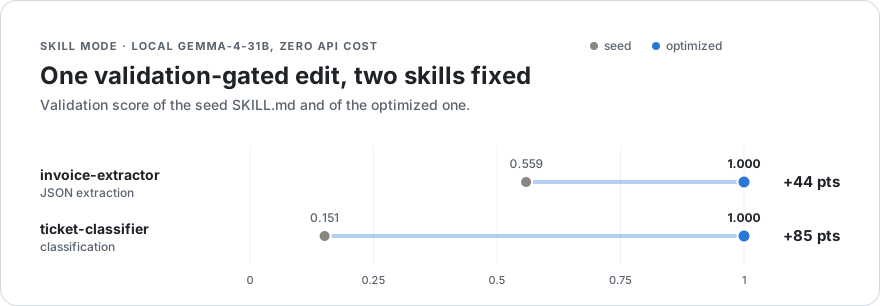
In skill mode, both examples ran end to end against a local gemma-4-31b-it-mlx in
LM Studio, at zero API cost. One validation-gated reflective edit rewrote each vague seed
into a structured skill with a schema, a strict output format and normalization rules.
Reproduce with examples/*/config.lmstudio.yaml. The winning skills and their full
candidate histories are in the skill gallery, ready to install.
Why
Prompt/skill authoring is usually vibes: edit, eyeball a couple of cases, ship. Skill Factory makes it an experiment you can reproduce and defend:
- Measured, not guessed — every candidate is scored on a held-out validation split.
- Validation-gated — an edit is kept only if it beats the current best. No regressions.
- Provider- and harness-agnostic — optimize once, run anywhere.
- Honest by construction — the whole pipeline is verifiable offline with a fake model.
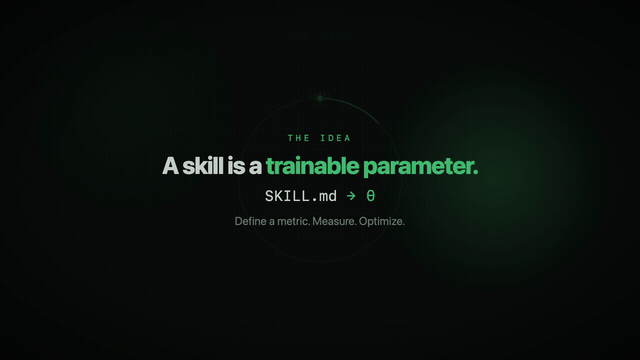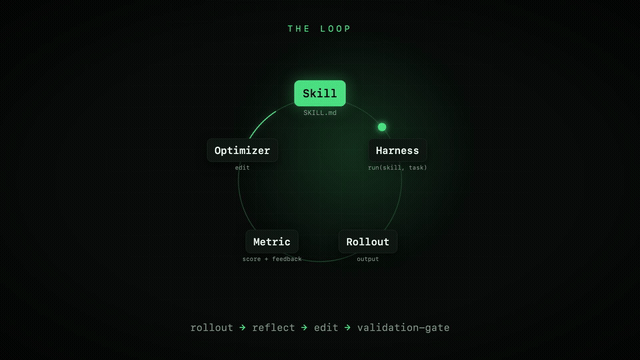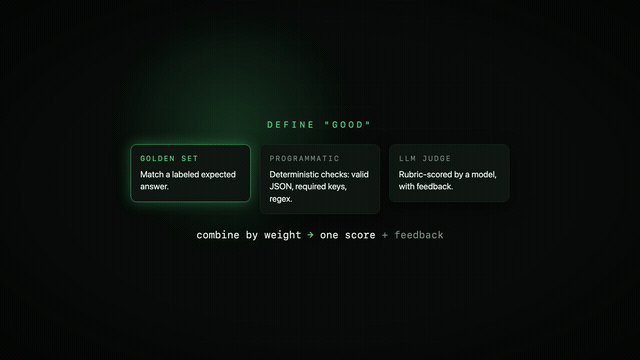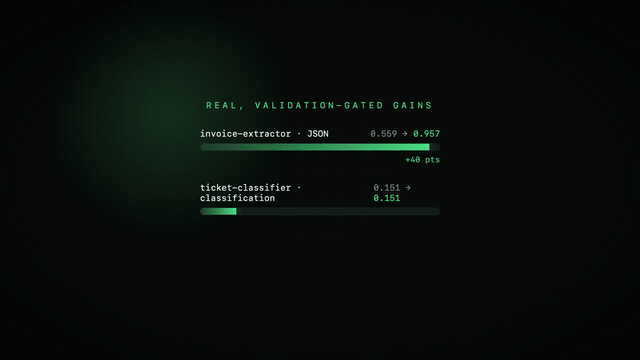
The scientific loop
Every optimizer reduces to the same five primitives and the same loop:
   Skill (SKILL.md, the trainable text)
     │
     ▼
   Harness ─run(skill, task)→ Rollout ─→ Metric ─→ score + feedback
     ▲                                                   │
     └────── Optimizer (reflect on feedback, edit, ──────┘
             keep only if it beats validation)
| Primitive | What it is | Where |
|---|---|---|
Skill |
A SKILL.md document (frontmatter+body) |
core/skill.py |
Dataset |
Tasks with optional gold answers | core/task.py |
Harness |
Runs a skill on a task → Rollout |
harness/ |
Metric |
Scores a rollout + returns feedback | metrics/ |
Optimizer |
Mutates the skill to maximize the metric | optimizers/ |
The textual feedback is load-bearing: reflective optimizers read why a rollout scored low to decide how to edit the skill.
Install
pip install "skill-factory[anthropic]"    # from PyPI (published with each release)
pipx install skill-factory                # or: CLI-only, isolated

# from source:
git clone https://github.com/FrancoisChastel/skill-factory && cd skill-factory
pip install -e ".[anthropic]"
# extras: [openai] [dspy] [skillopt] [dev]  ·  or [all]
Copy .env.example → .env and add your key(s) — or skip keys entirely and run
against a local model (see fully local).
Quickstart
skill-factory optimize -c examples/invoice-extractor/config.yaml   # optimize
cat runs/invoice-extractor/report.md                               # scorecard
npx skills add dist/invoice-extractor                              # install the result
Also: skill-factory evaluate · export · list · ui · lab (classifier mode).
Classifier mode: tune a decision model, not a prompt
Some skills are really classifiers: "is this skill malicious?", "does this PR do what it says?". With a decision model like jev, which answers yes/no questions with calibrated probabilities, the thing to train is a probe set: the questions, their framings, how answers combine, the threshold, and the policy that turns a score into a verdict.
skill-factory optimize -c examples/pr-mismatch/config.yaml    # kind: classifier
skill-factory lab freeze -c examples/pr-mismatch/config.yaml  # then the test split may be read
skill-factory lab report -c examples/pr-mismatch/config.yaml --ask
What it adds around the same reflect, edit, validate loop:
- A lab that caches every answer. One request answers up to 40 questions about an example, so trying 40 ideas costs about what one costs, and every threshold, ensemble and policy is rescored offline for free.
- Dataset-level objectives: recall at a false-positive budget, with constraints such as "no new false blocks" checked against the current best.
- Honest splits: group-aware train/val/test, held-out groups, and a test set that refuses to print until the configuration is frozen.
- Reflection on system causes, not only wording: misses that were never sent (over budget, failed) come first in the digest.
- Selection and ensembling, policy replay, re-ask determinism, recalibration, and exports (JSON, TypeScript, Python) with a byte-for-byte parity check.
On skill-scanner's real jev lab, the optimizer beat the hand-shipped probe set and
refused a greedy union whose false flags tripled on validation
(chart above). Live on examples/pr-mismatch, the capability questions
separated at chance, while a single mismatch question caught every hidden change:
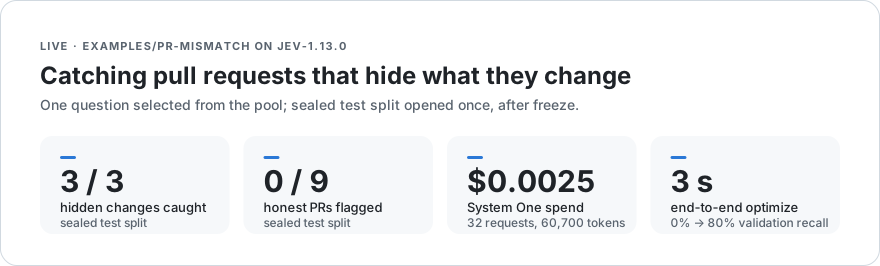
It is a small dataset (3 test positives), so read it as the workflow working end to
end, not as a benchmark. Full guide: docs/classifier.md.
It also works the other way: metric.systemone uses jev as a cheap, cached rubric
judge in skill mode.
Metrics — combine all three
Configured under metric: and merged by weight; a metric that can't apply to a
task is dropped, not penalized.
metric:
  golden:                 # compare to a labeled expected answer
    mode: json_equal      # exact | normalized | token_f1 | json_equal | numeric
    weight: 2.0
  programmatic:           # deterministic checks
    weight: 1.0
    checks: [is_valid_json, {json_has_keys: [vendor, date, total, currency]}]
  judge:                  # rubric-based LLM-as-judge
    weight: 1.0
    criteria:
      - {name: correctness, description: "all fields correct?", weight: 3}
      - {name: format, description: "strict JSON, no prose?", weight: 2}
Optimizers — pluggable backends
Select with optimizer.name.
| Name | Needs | Notes |
|---|---|---|
llm_loop |
just an LLM key | Default. Self-contained reflective, validation-gated loop. |
dspy_gepa |
[dspy] |
DSPy GEPA reflective/evolutionary search. |
skillopt |
your SkillOpt setup | Bridges to Microsoft SkillOpt (best_skill.md). |
All backends report a comparable baseline → best because the final skill is
always scored through the same harness + metric.
Providers — bring any model
Set per role — the target runs the skill, the optimizer proposes edits, the judge scores:
anthropic · openai · azure · openrouter · together · groq ·
deepseek · vllm · lmstudio · ollama (any OpenAI-compatible endpoint).
provider:           {name: anthropic, model: claude-sonnet-5}    # target
optimizer_provider: {name: anthropic, model: claude-opus-4-8}    # proposes edits
judge_provider:     {name: ollama,    model: llama3.1}           # judge (local, free)
Run it free, fully local
Point every role at a local OpenAI-compatible server (LM Studio, Ollama, vLLM)
and optimize at zero cost — the *.lmstudio.yaml configs do exactly this.
Harnesses — optimize in situ
The harness decides where the skill runs during optimization. Skills tuned in the same harness they deploy to transfer best:
harness:
  type: api             # default: skill-as-system-prompt over the provider API

harness:
  type: claude_code     # each rollout runs through the real Claude Code CLI
  model: claude-haiku-4-5   # optional; timeout/executable/extra_args too

harness:
  type: subprocess      # any CLI — Codex, custom agents, eval scripts…
  command: ["my-agent", "--system", "{skill_body}", "--input", "{input_file}"]
  input_via: stdin      # or "arg" with {input}/{input_file} placeholders
claude_code executes claude -p --append-system-prompt <skill> --output-format text
per rollout, piping the task input on stdin. The generic subprocess harness
substitutes {skill_body}, {skill_file}, {input}, {input_file} into your
argv template — non-zero exits, timeouts, and launch failures become failed
rollouts (scored 0) instead of aborting the run.
Optional web UI
A zero-dependency dashboard (Python stdlib) to browse runs, score timelines, and seed↔best skill diffs, and to launch runs:
skill-factory ui --runs runs # → http://127.0.0.1:8765
Architecture
src/skill_factory/
├── core/          skill · task · rollout · result   (dependency-light primitives)
├── metrics/       golden · programmatic · llm_judge · systemone · composite
├── harness/       anthropic_api · callable
├── optimizers/    llm_loop · dspy_gepa · skillopt  (+ lazy registry)
├── classifier/    classifier mode: probe sets, lab, splits, selection, policies, exports
├── llm/           client · openai_compat · factory  (multi-provider)
├── evaluate.py    run a skill across a dataset → Evaluation
├── builder.py     config → live objects → run
├── export.py      emit npx skills-compatible directories
├── persistence.py save/load runs (report.md, best_skill.md, result.json)
├── ui/            optional stdlib web dashboard
├── config.py      declarative YAML run config
└── cli.py         skill-factory <command>
video/             Remotion source for the explainer video
Development
pip install -e ".[dev]"
pytest              # fully offline: fake LLM + callable harness
pytest --cov        # ~80% coverage
Rebuild the README charts (stdlib only; the numbers live at the top of the script):
python docs/media/charts/build_charts.py # → docs/media/charts/*-{light,dark}.svg
Rebuild the explainer video (needs Node + ffmpeg; narration uses macOS say):
cd video && npm install
npm run render            # silent cut      → video/out/explainer.mp4
npm run render:narrated   # narrated cut    → video/out/explainer-narrated.mp4
Roadmap
- Transitions/crossfades + optional narration in the explainer
- More harnesses — Claude Code CLI preset + generic
subprocess(skills optimize in situ) - PyPI packaging + trusted-publishing release workflow (publishes on each GitHub release)
- A gallery of optimized skills with reproducible numbers
- Classifier mode: probe sets for System One decision models (jev), with a cached lab, honest splits and parity-checked exports
- Live-validate the DSPy GEPA adapter against a real run
- Parallel candidate evaluation inside
llm_looprounds - Codex CLI harness preset (works today via
subprocess) - More gallery entries — contributions welcome!
Contributing
PRs welcome — see CONTRIBUTING.md. Keep the core dependency-light and everything testable offline.
Credits
- Microsoft SkillOpt — agent skills as trainable parameters
- Microsoft PromptWizard — feedback-driven prompt optimization
- DSPy / GEPA — reflective/evolutionary program optimization
- npx skills — the open agent-skills format
- Explainer video built with Remotion
License
MIT © 2026 François Chastel
1 maintainer

Metadata
1 maintainer
Release files for skill-factory 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| skill_factory-0.2.0.tar.gz | 122.0 kB | With provenance | Details for skill_factory-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| skill_factory-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for skill_factory-0.2.0-py3-none-any.whl |
Total release size: 254.8 kB
Release files / skill_factory-0.2.0.tar.gz
| Download URL | skill_factory-0.2.0.tar.gz |
|---|---|
| Size | 122.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
7780beacf5d6573846facce1cc988020af0b94a5b3f2b14518d4137926f7862e
|
|
BLAKE2b-256 checksum How to use checksums |
40878fdc29db8321637fe787d74f80ed34ff754c66612db479e6d3d1578277c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / skill_factory-0.2.0-py3-none-any.whl
| Download URL | skill_factory-0.2.0-py3-none-any.whl |
|---|---|
| Size | 132.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c6442e8255eb9156a55fd0ac786a14bd65bd8cf3724228ced4ff8cc106163b3e
|
|
BLAKE2b-256 checksum How to use checksums |
7a31f88afba9a773d1ac3670dfc9a801c491f1b21584256c6df8c21826f3a636
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logSecurity for skill-factory 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for skill_factory-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













