
SkillJab
Your AI writes the analysis. SkillJab makes sure it's right before you spend the six hours finding out.
pipx install skilljab · a Claude Code plugin + CLI · for people who do data analysis with an AI at their side
The problem you already have
You ask Claude to write your pipeline. It writes clean, competent code. You run it on the real data, wait hours, and the result is wrong — because of something that was known: the region where every variant is correlated, the column that was secretly computed from the outcome, the join that doubled half the rows, the spreadsheet that exported 1,234 as text.
The AI knew about all of these. It didn't apply them, because nothing reminded it at the moment it was writing that step. You didn't catch it, because the code looked right. And by the time the mistake was visible, the compute was spent.
SkillJab gives the AI the scars before you pay for them.
What it does for you
SkillJab is a jab — a small controlled hit, like a vaccine shot or a sparring punch — delivered to a miniature of your analysis before the real run. Inside Claude Code, it makes the AI:
- Plan the analysis several ways at once, with different personas (a statistician, a domain veteran, the person who runs the cluster, Reviewer 2), and shows you where the plans disagree — that is where the risk lives.
- Prove the pipeline can recover a truth you planted. It generates a tiny dataset with a known answer and runs the whole pipeline on it. If the answer doesn't come back, the pipeline is wrong before any real data touches it.
- Attack the miniature with "stones" — missing-not-at-random values, a hidden batch, a leaked column, duplicated rows, two units in one column — and report only the silent failures: the result moved and nothing warned you.
- Explain every silent failure, which is the moment the AI says "oh — this is the HLA region" or "that score column is computed from the outcome": the knowledge it had but wasn't using.
- Keep what it learned as a skill. Every explanation becomes a checker, a fix, and a heads-up in a
SKILL.mdthat Claude loads automatically every time it touches that analysis again. Your AI gets better at your pipeline, permanently, with a record of why.
And it hands you a crash-test report so you can see, in one page, where your analysis is strong and where it is fragile.
A real test: the churn model Claude wrote
The kind of prompt people give an AI every day: "Here's a CSV of our customers — tenure, monthly charges, support tickets, contract, plan, churned. Build a churn model and tell me which factors matter." Claude wrote dropna → get_dummies → logistic regression on every column. Clean code. On clean data it recovers every planted effect: AUC 0.73, factors ranked correctly.
Then SkillJab threw ten stones at it, one per round — each one a thing that happens to real customer tables. Eight broke the answer and nothing warned anyone:
| what a real table does | what the AI's pipeline reported |
|---|---|
a churn_score_v1 column from an earlier model |
AUC 1.0; "nothing matters except the score" |
monthly_charges exported as text ('1,234.50') |
get_dummies made 1,400 columns; the price coefficient vanished |
| support history purged for closed accounts | dropna removed the churners; ticket effect 67% too small |
| one billing region in cents | "price doesn't affect churn" |
| one acquisition channel pricier and churnier, unlabelled | every coefficient ~100% off |
| ~50 bills at ±$800 (decimal slip) | price effect 90% off |
| charges + charges-with-tax + annual charges | price effect split three ways, sign unstable |
| tenure derived from a noisy invoice date | tenure effect 70% too small, mis-ranked |
Then the explainer wrote the antibodies. Same ten stones again: six caught, two still silent — and for those two the skill says plainly that the data as delivered cannot reveal them and which columns to ask for. That distinction is the product: not "we catch everything," but "here is what's guarded, here is what isn't, and here is the question to ask before you trust the model."
Full write-up, the pipeline, and a script that replays it in three minutes: examples/churn_ai_pipeline/. The rendered report and the skill it produced: docs/demo/churn/.
The report
One sentence at the top tells you the worst thing it found; everything below shows where and how much. These are from the churn test above.
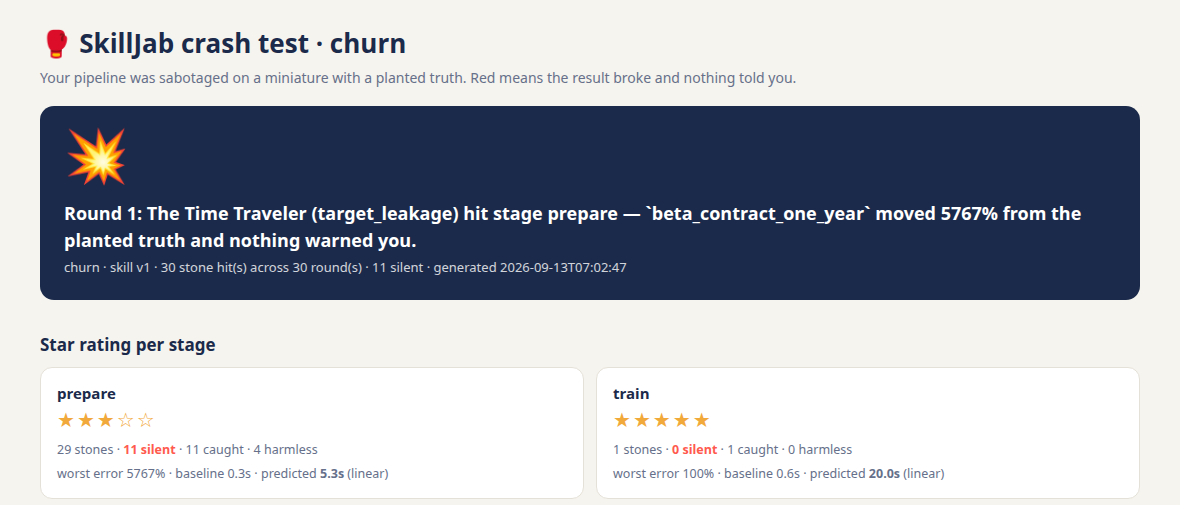
Star rating per stage — which step of your pipeline is weak, in two seconds. A stage loses stars for every stone that broke the result without any check firing.
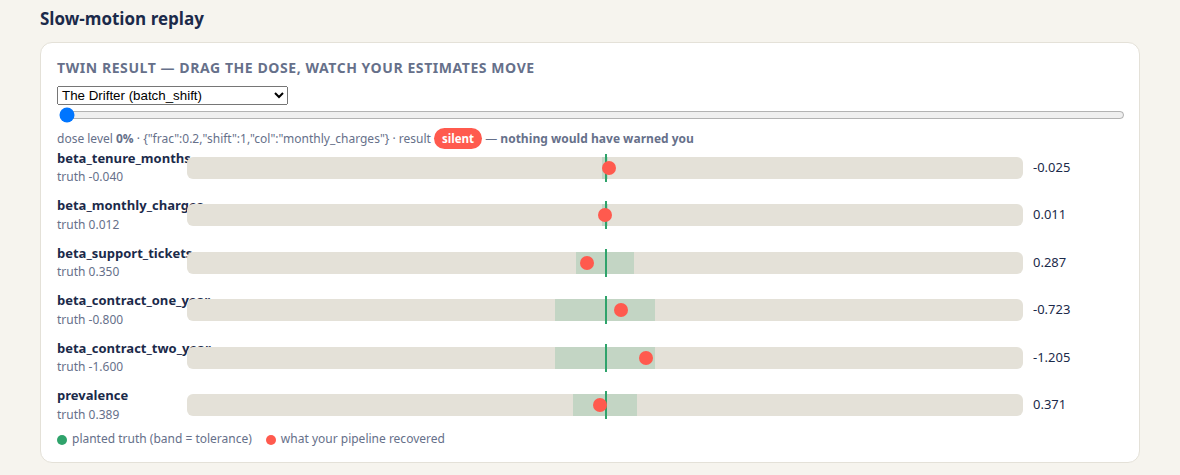
Slow-motion replay — your own estimates against the planted truth, with a slider for the dose. You watch the coefficient leave the green band and see the point where nothing would have told you.
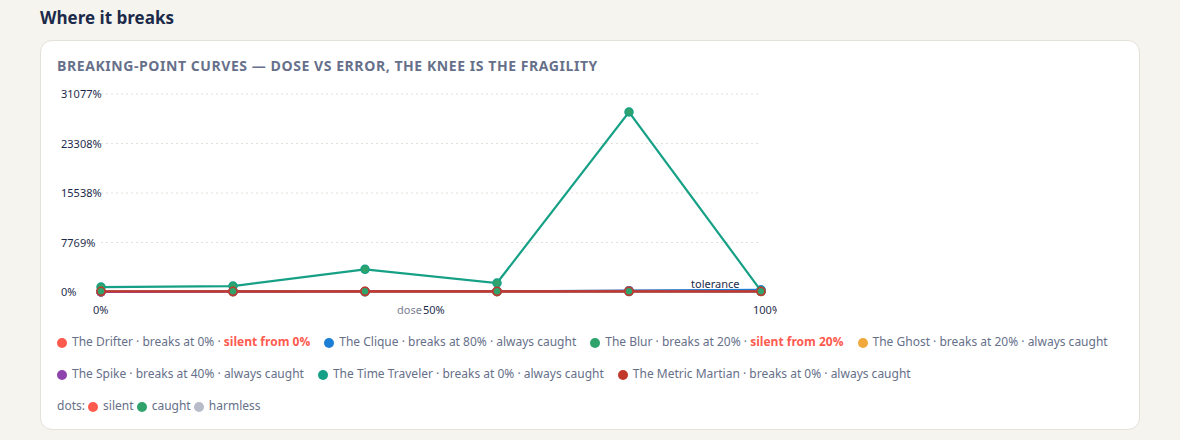
Where it breaks — dose against error for each stone; the knee is the fragility. It answers "how much missingness can I survive?" with a number instead of a warning. After immunization the dots turn green: the checks fire at every dose that breaks the result.
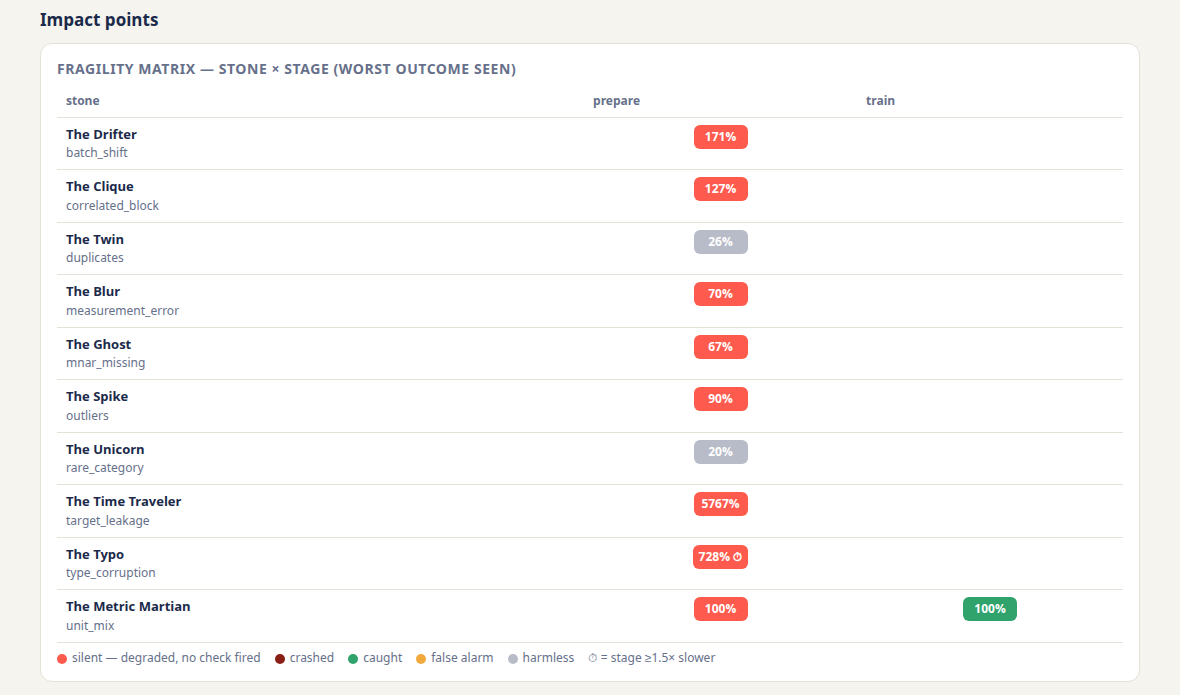
Impact points — stone × stage, colored by the worst outcome ever seen: red is silent, green is caught, grey is harmless. The two reds that remain are the ones the skill says it cannot guard without more columns.
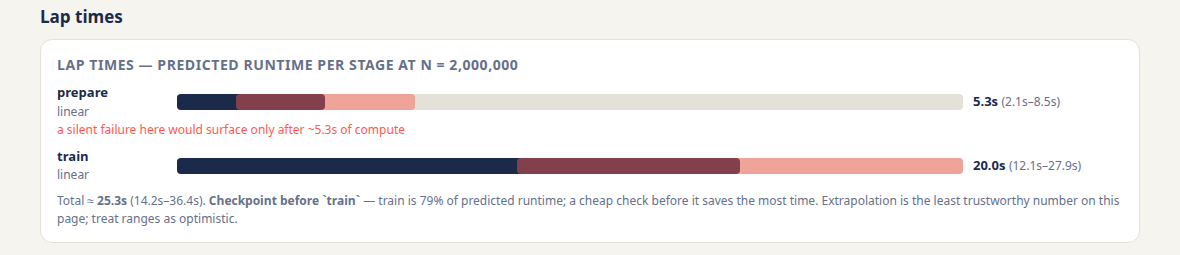
Lap times — predicted runtime per stage at your real N (here 2,000,000 customers), extrapolated from three miniature sizes, with the range, a flag for anything superlinear, and where to put a cheap check so a bad input dies at minute two instead of hour six.
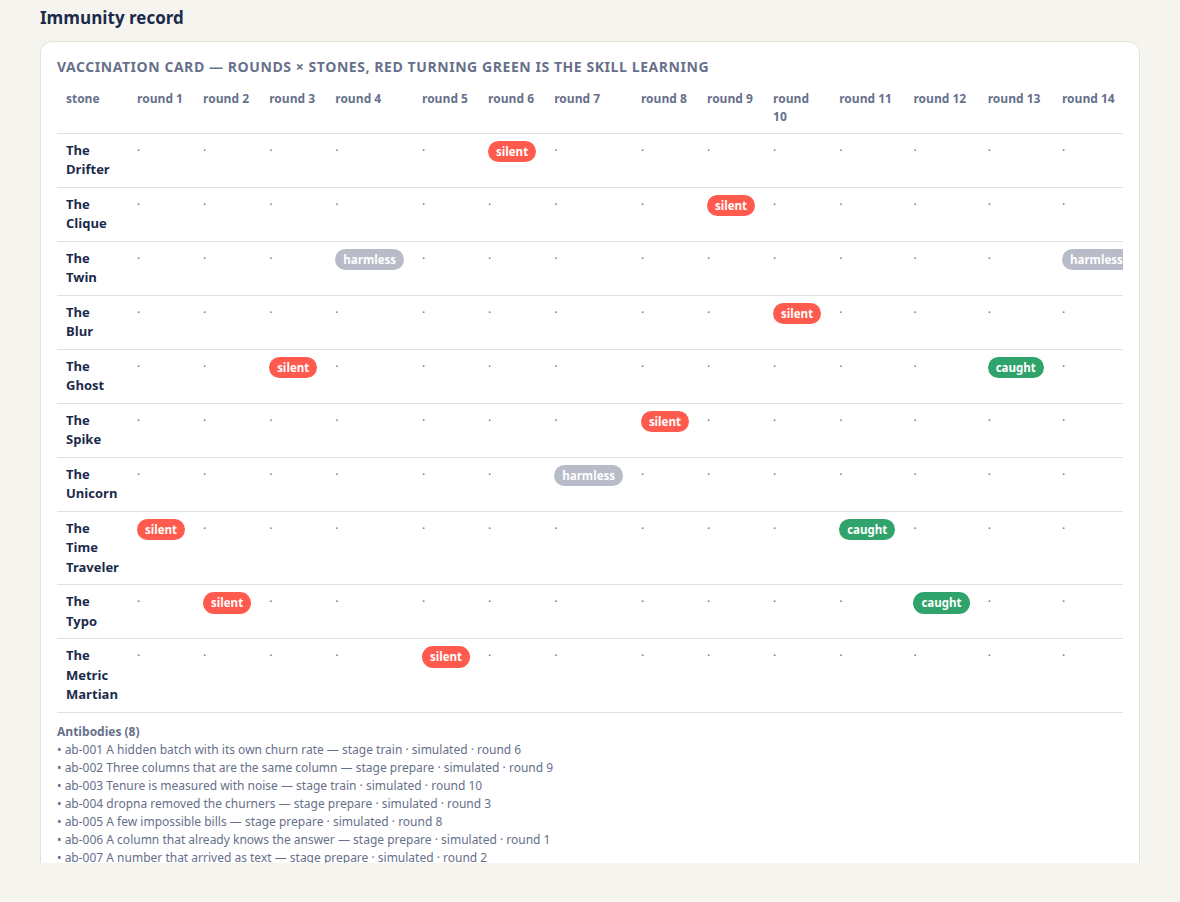
Immunity record — rounds × stones; red turning green is the skill learning. Below it, every antibody with its provenance, and how often the judge picked the right plan in the lineup.
The report is a single self-contained HTML file. No server, no external requests, safe to email.
What you get, in your repo
.claude/skills/<your-pipeline>/
├── SKILL.md            what Claude reads before touching this analysis: heads-ups, fixes, checks
├── antibodies.json     every entry traces to a round, a stone, or something you recognized
├── tree.json           the decisions the planners disagreed on, with the evidence on each branch
├── checks/             the checkers that now run at every stage boundary
└── history/            rounds, sweeps, timing, the report
The skill says why. A heads-up reads like: "stage clean · proven by simulation, round 1, stone target_leakage, worst error 90% — Selecting every x* column swallows any column derived from the outcome. Whitelist predictors explicitly; assert no predictor has |corr| > 0.9 with y before fitting. Check: checks/no_leaky_columns.py." Three evidence classes, kept apart: proven by simulation, reported by you, hypothesis only.
Quick start
pipx install skilljab                                  # the engine (Debian/Ubuntu: sudo apt install pipx first)
git clone https://github.com/AlsammanAlsamman/skilljab
claude --plugin-dir ./skilljab/plugin                  # the Claude Code side
Then, in Claude Code, on any analysis:
/skilljab:build   pipeline.yaml        plans ×N, divergence map, lineup, miniature, clean-recovery proof, SKILL.md v0
/skilljab:test                         one sabotage round; you see only the silent failures
/skilljab:improve                      turn them into antibodies; re-test until the round is clean
/skilljab:jab                          test + improve looped — the whole vaccine in one command
/skilljab:recall                       "describe something odd from a past run, badly" — it lists what it could have been
/skilljab:report                       the crash-test page
Try it on the shipped examples first — examples/churn_ai_pipeline/ (the real test above, ./run_demo.sh) or the minimal examples/toy_regression/:
cd skilljab/examples/toy_regression
skilljab init     --name toy --pipeline pipeline.yaml --spec spec.yaml --skill-dir .claude/skills/toy
skilljab baseline --skill .claude/skills/toy --target-n 200000
skilljab round new    --skill .claude/skills/toy
skilljab round stones --skill .claude/skills/toy target_leakage --level 0.6
skilljab round run    --skill .claude/skills/toy          # → "silent": beta_x1 off by 90%, no check fired
skilljab report --skill .claude/skills/toy                # → history/report.html
How it stays honest
Two halves, and each fact lives in exactly one:
Engine — skilljab CLI (Python, no AI inside) |
Plugin — Claude Code | |
|---|---|---|
| does | plant the truth, inject stones, run stages, grade, sweep doses, diff plans, predict time, render the skill and the report | interview, plan ×N, judge, sabotage, analyze, explain, write antibodies |
| never | decide what a failure means | compute a verdict or grade itself |
Five subagents that cannot see each other's files: planners (one per persona), a judge that runs a lineup — "one of these plans failed; which?" — and is scored against planted culprits so you know how much to trust it, a saboteur that picks stones, a blind analyst that runs the pipeline with the current skill loaded, and an explainer, the only one allowed to see what was planted.
Elicitation proposes; simulation disposes. The AI can suspect anything; only a stone that actually breaks the miniature — or something you recognized yourself — earns a place in the skill.
The stones
Deliberately domain-neutral. A generic stone is enough to make the AI's own knowledge do the specialization.
| character | stone | what it does to the miniature |
|---|---|---|
| The Time Traveler | target_leakage |
adds a feature computed from the outcome |
| The Ghost | mnar_missing |
blanks the top values — missing-not-at-random |
| The Clique | correlated_block |
near-identical copies of a feature |
| The Drifter | batch_shift |
a hidden batch confounded with the outcome |
| The Twin | duplicates |
re-appends rows |
| The Spike | outliers |
a few impossible values |
| The Blur | measurement_error |
noise in a predictor (attenuation) |
| The Metric Martian | unit_mix |
two units in one column |
| The Long Tail | heavy_tails |
Student-t noise |
| The Unicorn | rare_category |
a category level with almost no support |
| The Typo | type_corruption |
'1,234', ' 12 ', 'NA' in a numeric column |
Your pipeline's contract
Stages as shell commands — any language, any tool — and a last stage that writes the estimates:
name: gwas
stages:
  - id: qc      cmd: "plink2 --bfile {in} --geno 0.02 --make-bed --out {out}"   out: qc.csv
  - id: prune   cmd: "Rscript prune.R {in} {out}"                              out: pruned.csv
  - id: fit     cmd: "python fit.py {in} {out}"                                 out: result.json
result.json = {"estimates": {"beta_x1": 0.79, ...}}, with the same names as the planted truth in sim/spec.yaml. Checkers are scripts called at stage boundaries — python3 check.py <stage_output> — that exit 1 or print {"fired": true, "message": "..."}.
Honest limits
- Miniatures can lie. Some failures only appear at scale. The timing page extrapolates and says so; treat ranges as optimistic.
- You need a truth to plant. Quantitative analyses, yes; design and strategy, no — there the simulation is just the AI's own assumptions fed back to itself.
- Three generators ship (
tabular_regression,tabular_classification,two_group_lift). A genotype generator with real LD structure and a counts generator are the next ones. - The graveyard is local. A shared, anonymized graveyard of real past failures is the obvious next step.
Development
git clone https://github.com/AlsammanAlsamman/skilljab && cd skilljab
python3 -m venv .venv && . .venv/bin/activate && pip install -e ".[dev]"
python -m pytest -q                              # 47 tests, ~35 s
claude plugin validate plugin --strict
Design notes and the reasoning behind every choice — the pre-mortem, the recoverability test, why generic stones beat a hand-written pitfall library, the lineup, the tricks for making an AI say "oh yeah, I should have told you" — are in docs/DESIGN.md.
Author
Alsamman M. Alsamman — aalsamman100@gmail.com · github.com/AlsammanAlsamman · MIT
A jab is a vaccine shot and a boxing punch. Both are a small, deliberate hit that makes you stronger before the real fight.
1 maintainer

Release files for skilljab 0.1.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| skilljab-0.1.1.tar.gz | 58.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| skilljab-0.1.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 112.9 kB
Release files / skilljab-0.1.1.tar.gz
| Download URL | skilljab-0.1.1.tar.gz |
|---|---|
| Size | 58.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
301688fee21fa04cef5130cf1578a42e434bbfdc5b0bfc864091c8be1c0579eb
|
|
BLAKE2b-256 checksum How to use checksums |
49d1e6f670ea543f8cd9f8d59b11ba1e5ca579752019398557bd461f1e82fa1c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|
Release files / skilljab-0.1.1-py3-none-any.whl
| Download URL | skilljab-0.1.1-py3-none-any.whl |
|---|---|
| Size | 54.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0e1a53ad13c721ad4e483e97a1bd95dddadc5614c4e9f3a0130294bf79b0e008
|
|
BLAKE2b-256 checksum How to use checksums |
fc90830b4c34776f4ca7e36d56e3f361e92ccf9bfff336861ff342cf6a32a448
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.3
|














