
skillproof
pytest for agent skills: prove your skill actually works.


pip install skillproof
Works with: Claude Code · Codex · any OpenAI-compatible endpoint
Agent skills (SKILL.md folders for Claude Code, Codex, Cursor, Gemini CLI,
OpenCode...) are everywhere, but almost nobody can show that a skill helps. Often
it isn't even loaded: the agent never decides to use it. skillproof runs your
tasks N times with the skill installed and N times without it, then tells
you:
- Trigger rate: did the agent actually load the skill?
- Lift: pass rate with the skill minus pass rate without it, with a 95% confidence interval
- Cost: extra (or saved) tokens, dollars and seconds per run
- A verdict: helps, hurts, no clear effect, or too few runs to say
60-second quickstart
pip install skillproof
export ANTHROPIC_API_KEY=sk-ant-...      # or use your `claude` login

skillproof init ./my-skill                # writes my-skill/evals.yaml
# edit evals.yaml: 2-3 real tasks, how to check them, one task the skill should ignore
skillproof run ./my-skill                 # prints the plan and cost estimate, then runs
uvx skillproof run ./my-skill works too, without installing anything.
Example output
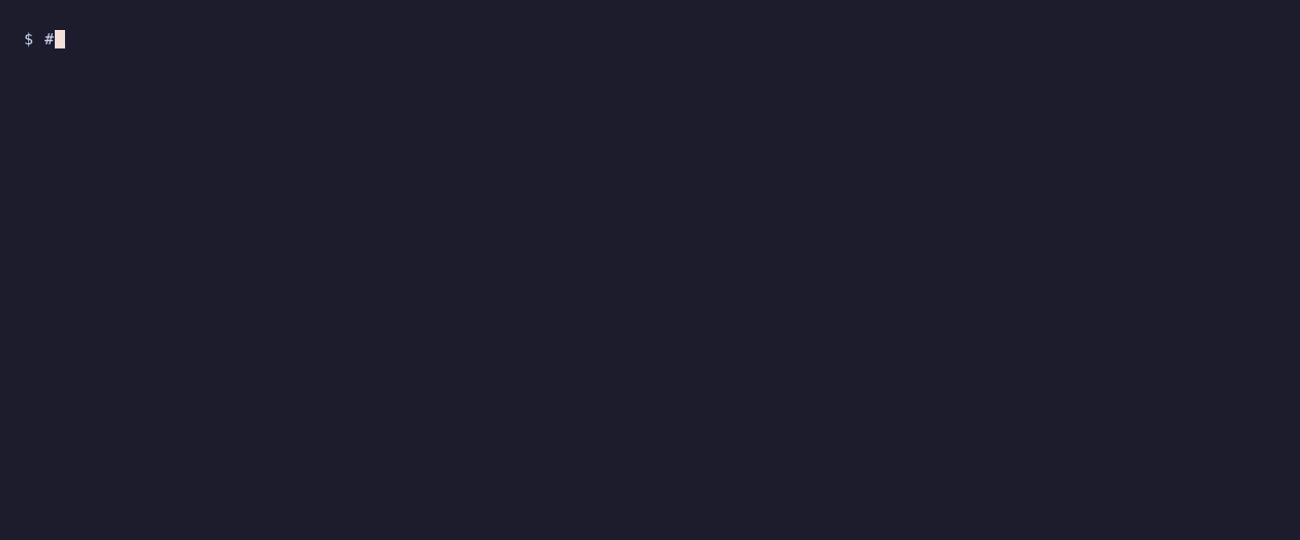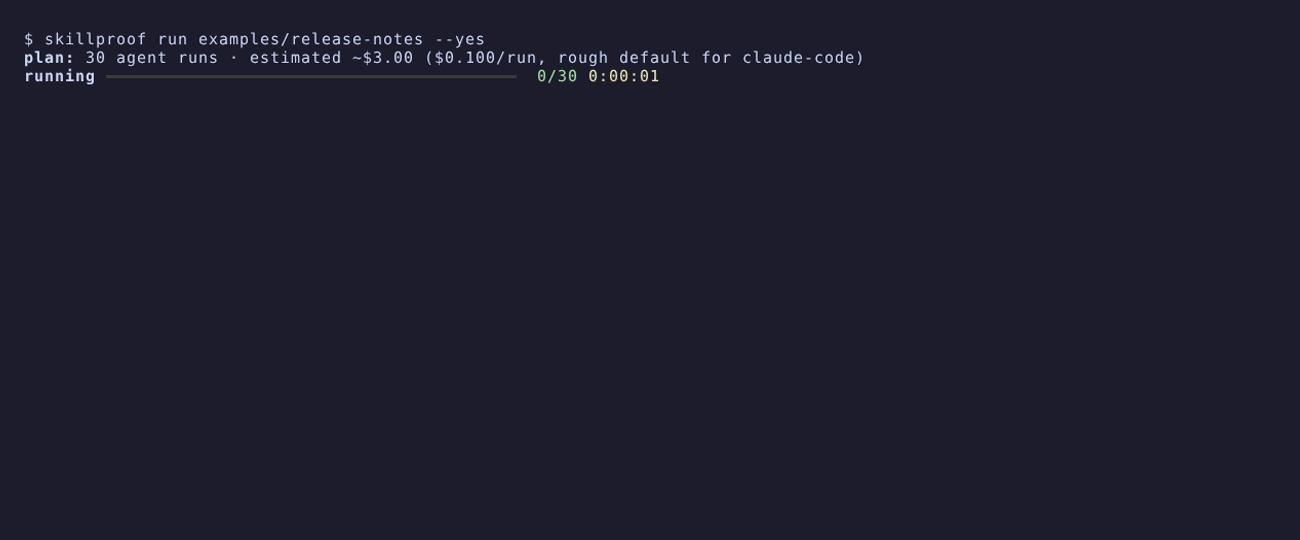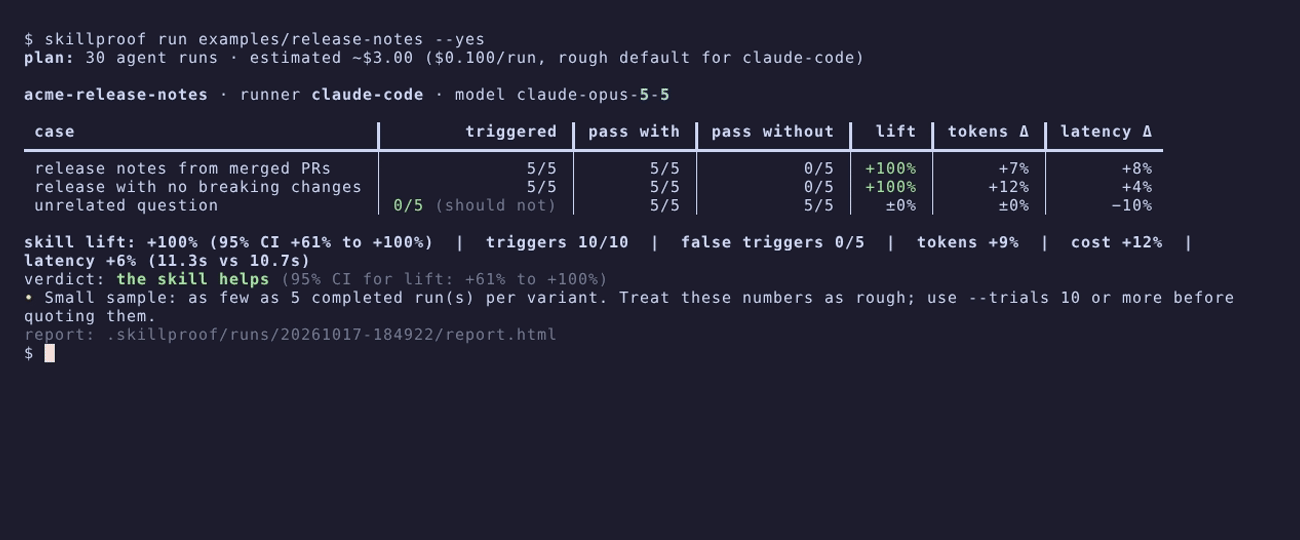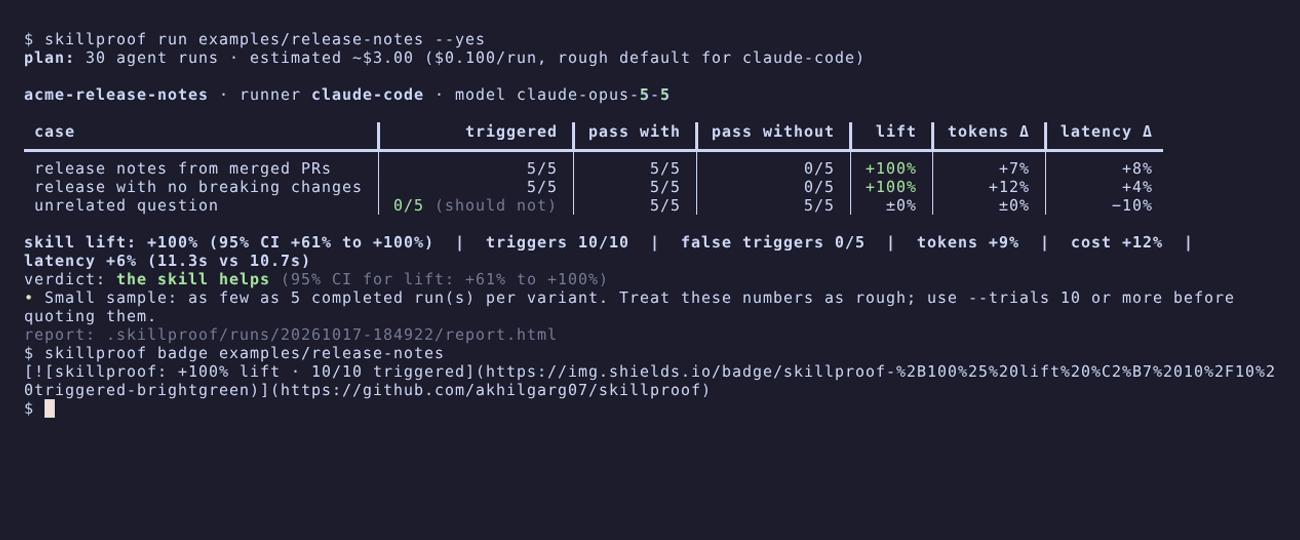
This is a real run of the release-notes example
(Claude Code, 5 trials per variant):
acme-release-notes · runner claude-code · model claude-opus-5-5

 case                             ┃        triggered ┃ pass with ┃ pass without ┃  lift ┃ tokens Δ ┃ latency Δ
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━━━━━━━━╇━━━━━━━━━━━╇━━━━━━━━━━━━━━╇━━━━━━━╇━━━━━━━━━━╇━━━━━━━━━━━
 release notes from merged PRs    │              5/5 │       5/5 │          0/5 │ +100% │      +7% │       −3%
 release with no breaking changes │              5/5 │       5/5 │          0/5 │ +100% │      +7% │       +3%
 unrelated question               │ 0/5 (should not) │       4/5 │          5/5 │  −20% │      ±0% │       −2%

skill lift: +100% (95% CI +61% to +100%)  |  triggers 10/10  |  false triggers 0/5  |  tokens +7%  |  cost +10%
verdict: the skill helps (95% CI for lift: +61% to +100%)
• Small sample: as few as 5 completed run(s) per variant. Treat these numbers as rough; use --trials 10 or more
  before quoting them.
Every run also saves a self-contained HTML report (with each run's checks and
answer), report.md, summary.json and the full transcripts under
.skillproof/runs/<timestamp>/.
examples/ has skills that help, do nothing and hurt, so
you can see all three outcomes.
How it works
for each case in evals.yaml, N trials, interleaved:
    with skill:     fresh temp dir + fixtures + skill installed  ->  agent  ->  checks
    without skill:  fresh temp dir + fixtures, no skill          ->  agent  ->  checks
- Every run gets a fresh temp directory with your fixtures copied in. Your project is never touched.
- Your personal skills, settings and instructions (
~/.claude,~/.codex,~/.agents) are not loaded for either variant, so the only difference is the skill. - The agent can't see your
evals.yamlor its checks. - Transcripts, token usage and tool calls are saved for every run, with API keys redacted.
evals.yaml
skill: ./                 # folder containing SKILL.md
runner: claude-code       # claude-code | codex | openai-compatible
# model: claude-sonnet-5-5  # optional; the agent's default otherwise
trials: 5                 # runs per case, per variant
timeout: 300              # seconds per run

cases:
  - name: "summarizes stack trace"
    prompt: "Here is an error log in error.log. What's wrong?"  # don't name the skill
    fixtures: ./fixtures/case1/     # copied into each run's temp dir
    assert:
      - type: contains
        value: "NullPointerException"
      - type: file_exists
        path: fix.patch
      - type: command               # runs in the temp dir; passes on exit code 0
        run: "python -m pytest -q"
      - type: max_tokens
        value: 20000
      - type: llm_judge             # optional; graded by a model from another vendor
        rubric: "States the root cause in the first sentence."

  - name: "unrelated question"      # catches skills that load when they shouldn't
    prompt: "What's the capital of France?"
    should_trigger: false
    assert:
      - {type: contains, value: "Paris"}
| assertion | passes when |
|---|---|
contains / not_contains |
the final answer contains / doesn't contain value (case-insensitive by default) |
regex |
the final answer matches pattern |
file_exists / file_contains |
a file in the temp dir exists / contains value |
command |
run exits 0 in the temp dir (API keys are removed from its environment) |
max_tokens |
the run used at most value tokens (input + output + cache) |
llm_judge |
a judge model says the answer meets rubric |
Use deterministic checks first. llm_judge defaults to a judge from a different
vendor than the agent (Claude agents are graded by an OpenAI model and vice
versa), so no model grades its own family. Change it with
judge: {provider: anthropic, model: ...}.
Runners
| runner | how it runs | where the skill goes | how a trigger is detected |
|---|---|---|---|
claude-code |
Claude Agent SDK | <temp>/.claude/skills/<name>/ |
a Skill tool call naming the skill |
codex |
codex exec --json |
<temp>/.agents/skills/<name>/ |
a shell command that reads the skill's folder |
openai-compatible |
a small tool-using loop over Chat Completions | SKILL.md pasted into the system prompt | not measured (approximate) |
Keys come from environment variables only: ANTHROPIC_API_KEY (or your claude
login), CODEX_API_KEY / OPENAI_API_KEY (or codex login). Runner settings go
under runner_options:; see each runner's module docstring.
Reports, CI and badges
skillproof run ./my-skill --format md -o report.md    # also: html, json (to stdout)
skillproof report                                      # re-render the latest run
skillproof run ./my-skill --min-lift 0 --min-trigger-rate 80   # exit 1 if not met
skillproof run ./my-skill --dry-run                    # plan + cost estimate only
Cost guard: before every run skillproof prints the number of runs and an
estimate based on your previous runs. Above $5 it asks first; in CI it refuses
unless you pass --yes. If the first runs all fail (bad key, wrong model), it
stops and tells you what to fix.
GitHub Action: comments the results on pull requests and keeps the comment up to date.
# .github/workflows/skillproof.yml (full example: action/example-workflow.yml)
on: pull_request
permissions: {contents: read, pull-requests: write}
jobs:
  skillproof:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
      - uses: akhilgarg07/skillproof@v0
        with: {path: my-skill, trials: "10", min-lift: "0"}
        env: {ANTHROPIC_API_KEY: "${{ secrets.ANTHROPIC_API_KEY }}"}
Badge for your skill's README:
skillproof badge ./my-skill
# [](...)
It is green when the skill helps, red when it hurts and grey when the result is
not significant or comes from fewer than 5 runs per variant. --json prints a
shields.io endpoint file instead, so CI
can keep a badge up to date.
Honest numbers: what this can and can't tell you
- It measures your tasks, not the skill in general. Lift depends on the prompts
and checks you write. Publish your
evals.yamlnext to any number you share. - Small samples are noisy. Every rate comes with a 95% interval (Wilson for pass rates, Newcombe for the lift). Below 5 runs per variant there's no verdict at all, and below 10 the report says the numbers are rough.
- Results depend on the agent and model. Reports record the model that actually
ran. In our runs, Claude Code read a library's source, noticed that a skill's docs
were stale and ignored them (
examples/stale-docs); a weaker model may not. - Trigger detection is per agent and heuristic. Claude Code has an explicit
Skilltool call. Codex reads skills with ordinary shell commands, so a "trigger" there means a command touched the skill's folder. - The
openai-compatiblerunner is an approximation. It pastes SKILL.md into the system prompt instead of letting the agent discover and load it, so it can't measure trigger rate and overstates how often a skill is "used". Reports label it. - Token deltas include cache reads, which are cheap. Look at the cost delta when the agent reports cost (Claude Code does).
llm_judgeis a model's opinion. It's cross-vendor by default, but still noisy; prefer deterministic checks.- Agents run real commands. Runs happen in temp directories, but agents run without permission prompts, so a command could still reach other files on your machine. Test untrusted skills in a container or VM.
Leaderboard
leaderboard/ runs skillproof over a list of public skills (using
evals you write, never the repo's own) and renders a markdown leaderboard.
Contributing
Contributions are very welcome; see CONTRIBUTING.md. Good first issues:
- New runners: Gemini CLI, Cursor (cursor-agent), OpenCode, Aider
- New assertions:
tool_called(the agent used a given tool),json_schema,file_matches(regex on a file),max_cost_usd skillproof compare: two versions of a skill head to head- Windows support and a Docker sandbox option for untrusted skills
- A local judge:
llm_judgeover Chat Completions, for local models (Ollama, vLLM)
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for skillproof 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| skillproof-0.1.0.tar.gz | 342.6 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| skillproof-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 409.2 kB
Release files / skillproof-0.1.0.tar.gz
| Download URL | skillproof-0.1.0.tar.gz |
|---|---|
| Size | 342.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
be3a5d7ef7a31933b58bd7cb370e3fd7fbf26532ed0e2e91785d24aea0994a7b
|
|
BLAKE2b-256 checksum How to use checksums |
27d5fe5783acc5bbea298acd0a828b1d7bc5ea7f5d9d4d951948236ceb05007d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logRelease files / skillproof-0.1.0-py3-none-any.whl
| Download URL | skillproof-0.1.0-py3-none-any.whl |
|---|---|
| Size | 66.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
dc633f366637db43c8b39917a125e156f7549aa4502f9f988486dd0220606f09
|
|
BLAKE2b-256 checksum How to use checksums |
8a5c5f08131816d1da26d19495de63619d15891c6e3688dfa7bdef34907748a2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logSecurity for skillproof 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for skillproof-0.1.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 17, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













